
Why Latency Is The Real Bottleneck In Llm Production Deployment

Why Latency Is the Real Bottleneck in LLM Production Deployment?

Latency Is the Real Bottleneck in AI Systems | by Jayapragash | Apr ...
Memory Bandwidth — The Real Bottleneck in LLM Inference | tutorialQ

3-Part Series: LLM Latency in Production (Part 1)

Reducing LLM Latency in Production - Best Generative AI & Machine ...

The Real Engineering Behind LLM Production

Latency profile of the LLM with the prompt. The hardware here is a ...

The Hidden Bottleneck in AI Inference: Why Healthy GPU Utilization Can ...

The Hidden Cost of LLM Coding Agents: Why Context, Not Code, Is the ...
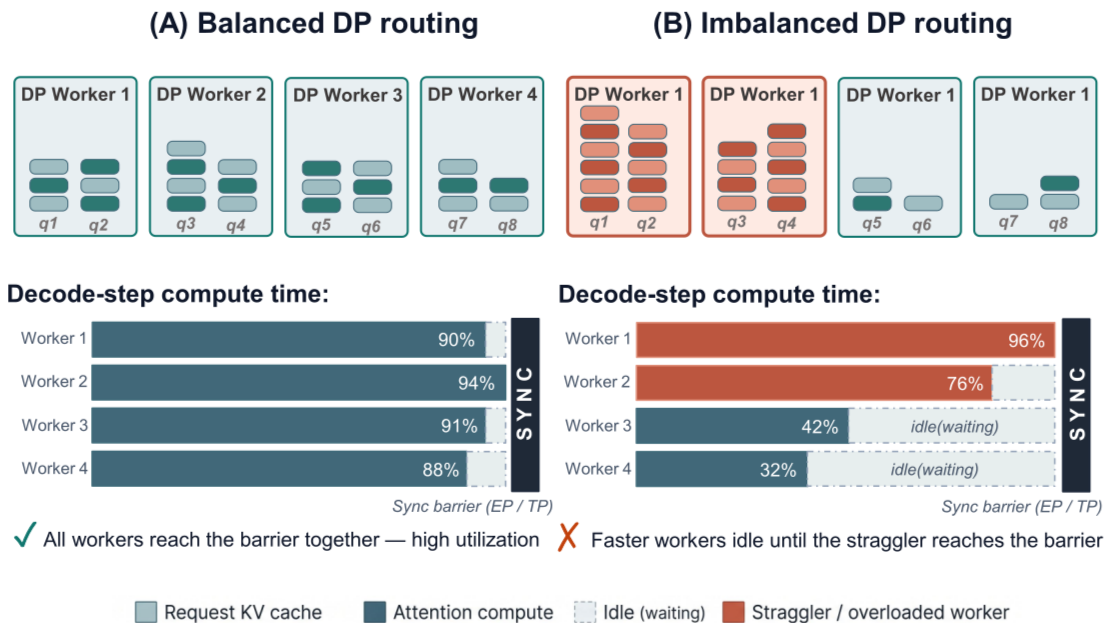
[论文评述] Tackling the Data-Parallel Load Balancing Bottleneck in LLM ...
Advertisement Space (300x250)
Why LLM Deployment is Not Just a Technical Task — It’s Strategic ...

The Real Bottleneck Is Not Execution. It’s Decision Latency.

Techniques to Boost LLM latency in Production | by Himank Jain | Apr ...
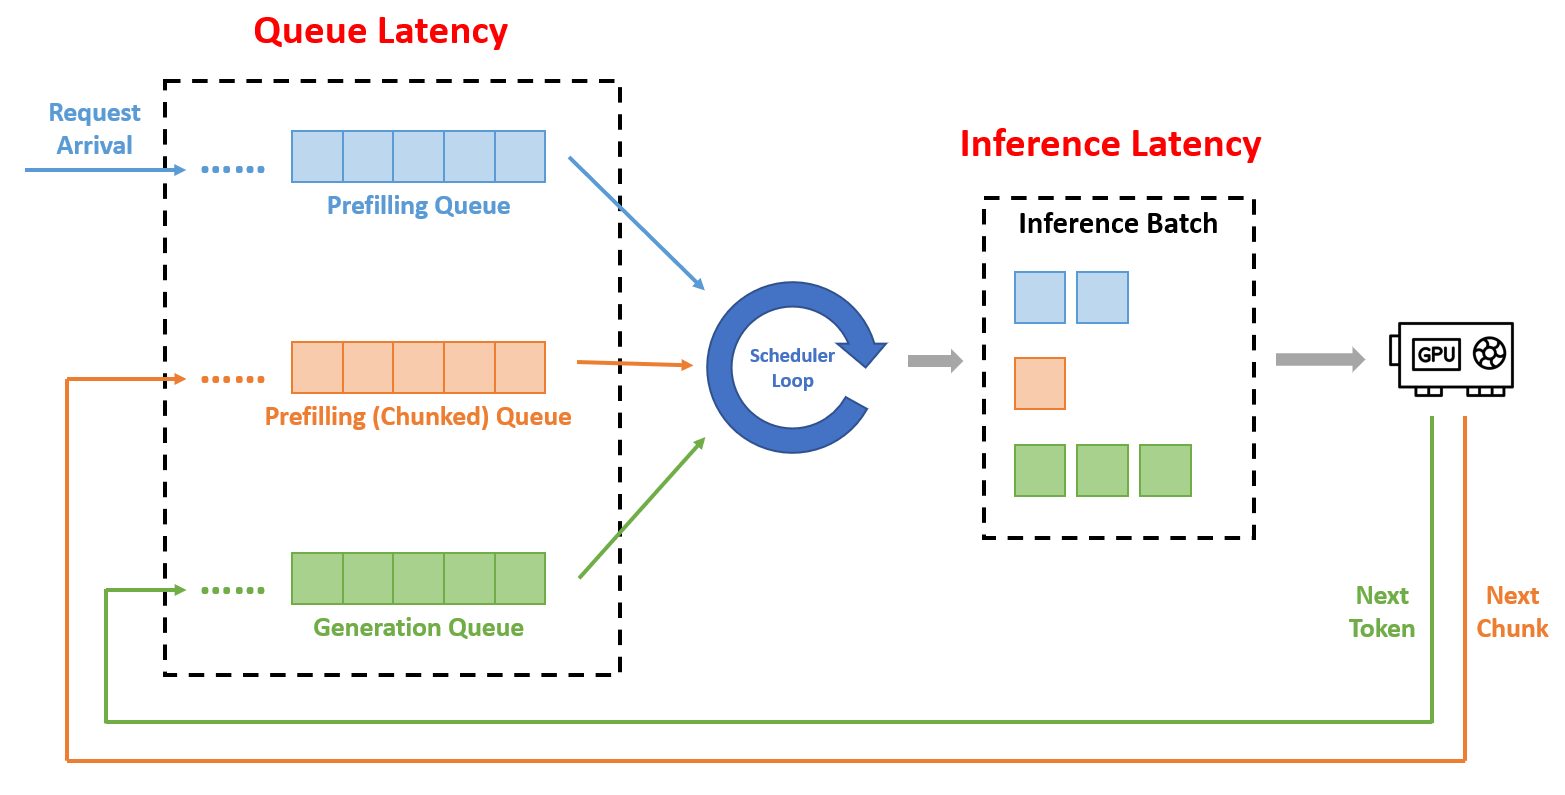
Latency in LLM Serving | Monsoon's Blog

🔍 Optimising LLM Latency: Why Speed matters in Generative AI ⏱️ If you ...
The Business Imperative of LLM Latency Optimization: Winning the Speed ...

8 LLMs in the Backend: FastAPI Patterns for Predictable Latency | by ...
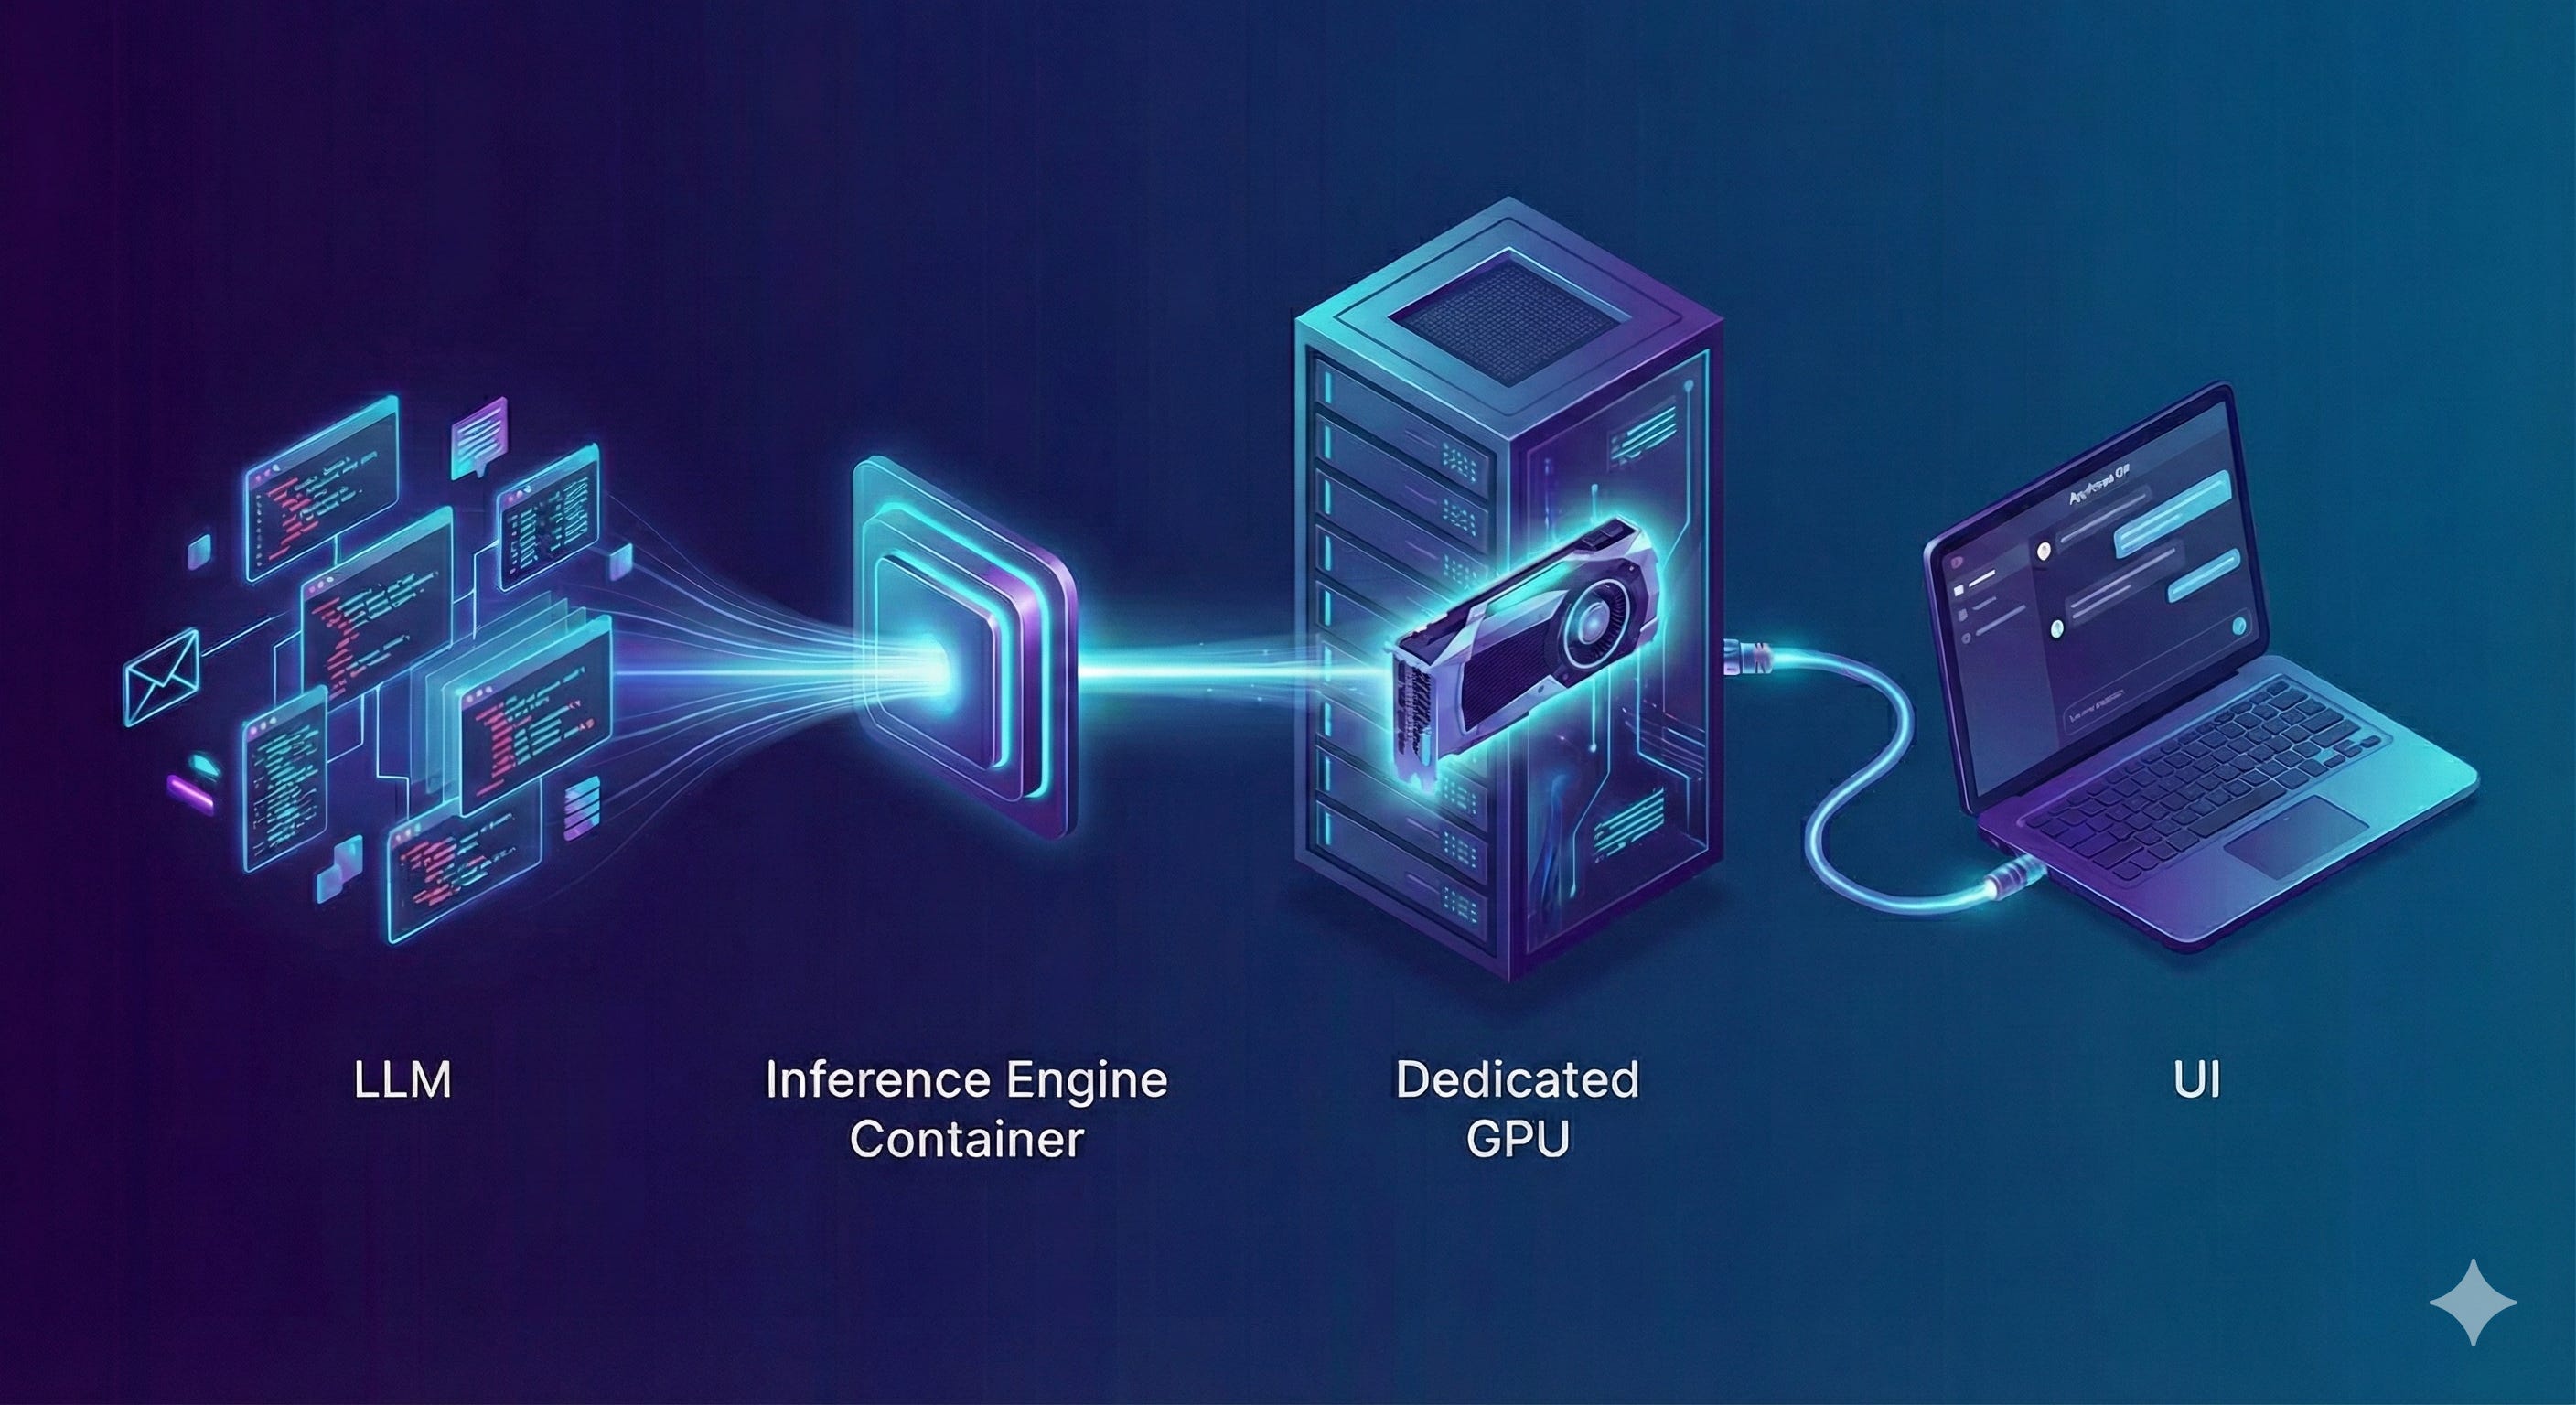
How to Deploy Your LLM in the Cloud - by Benjamin Marie
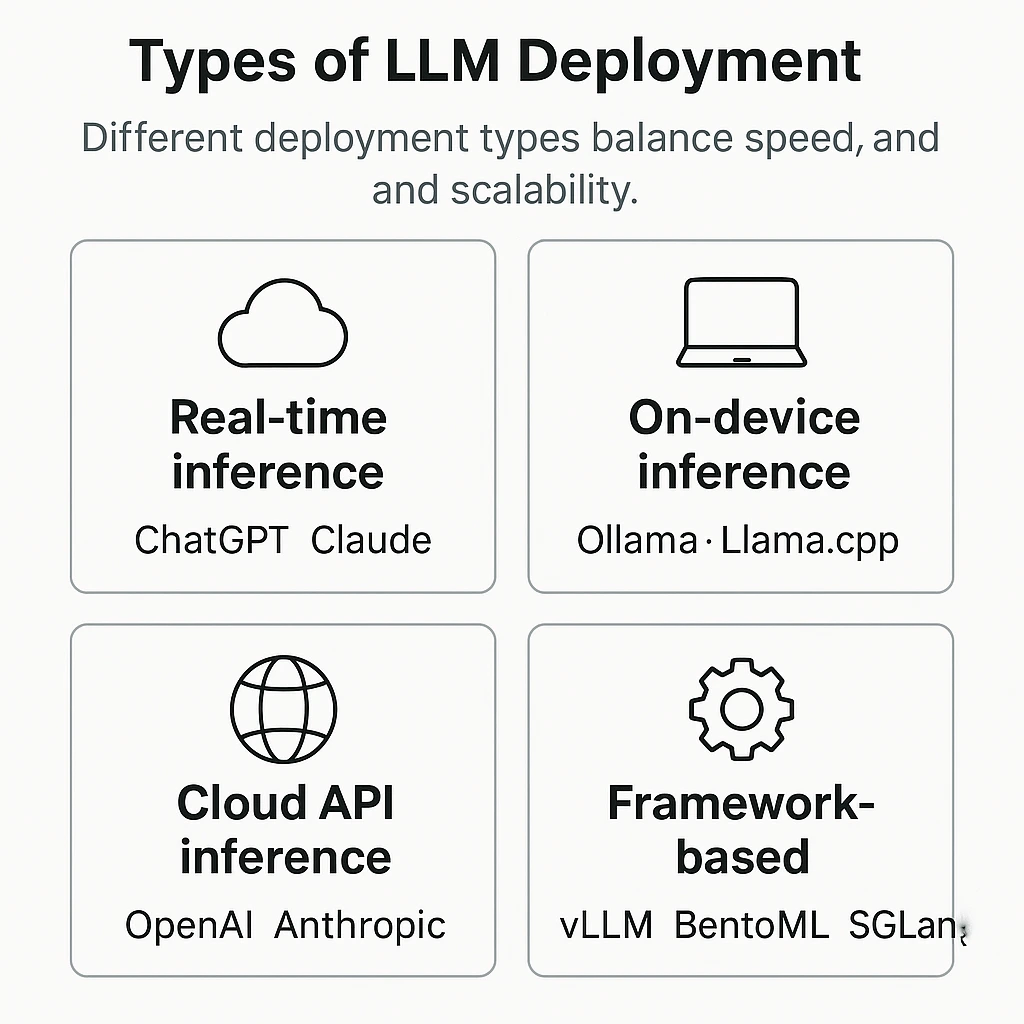
What Is LLM Inference? Process, Latency & Examples Explained (2026)
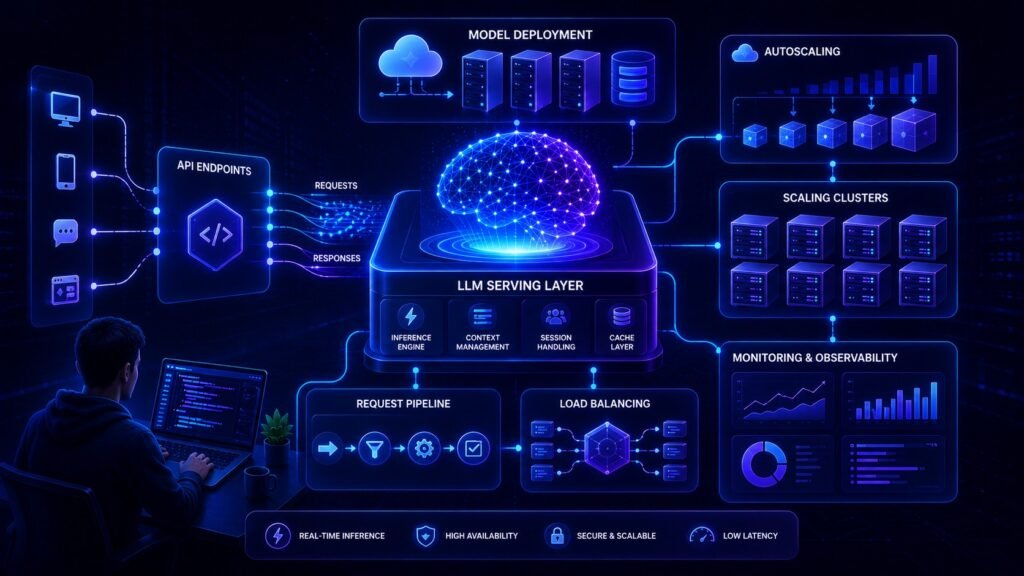
LLM Serving Explained in 2026 (APIs, GPUs, Latency & Scaling) » AIML ...
Advertisement Space (336x280)

REAL data about LLM price and latency - USLUCK
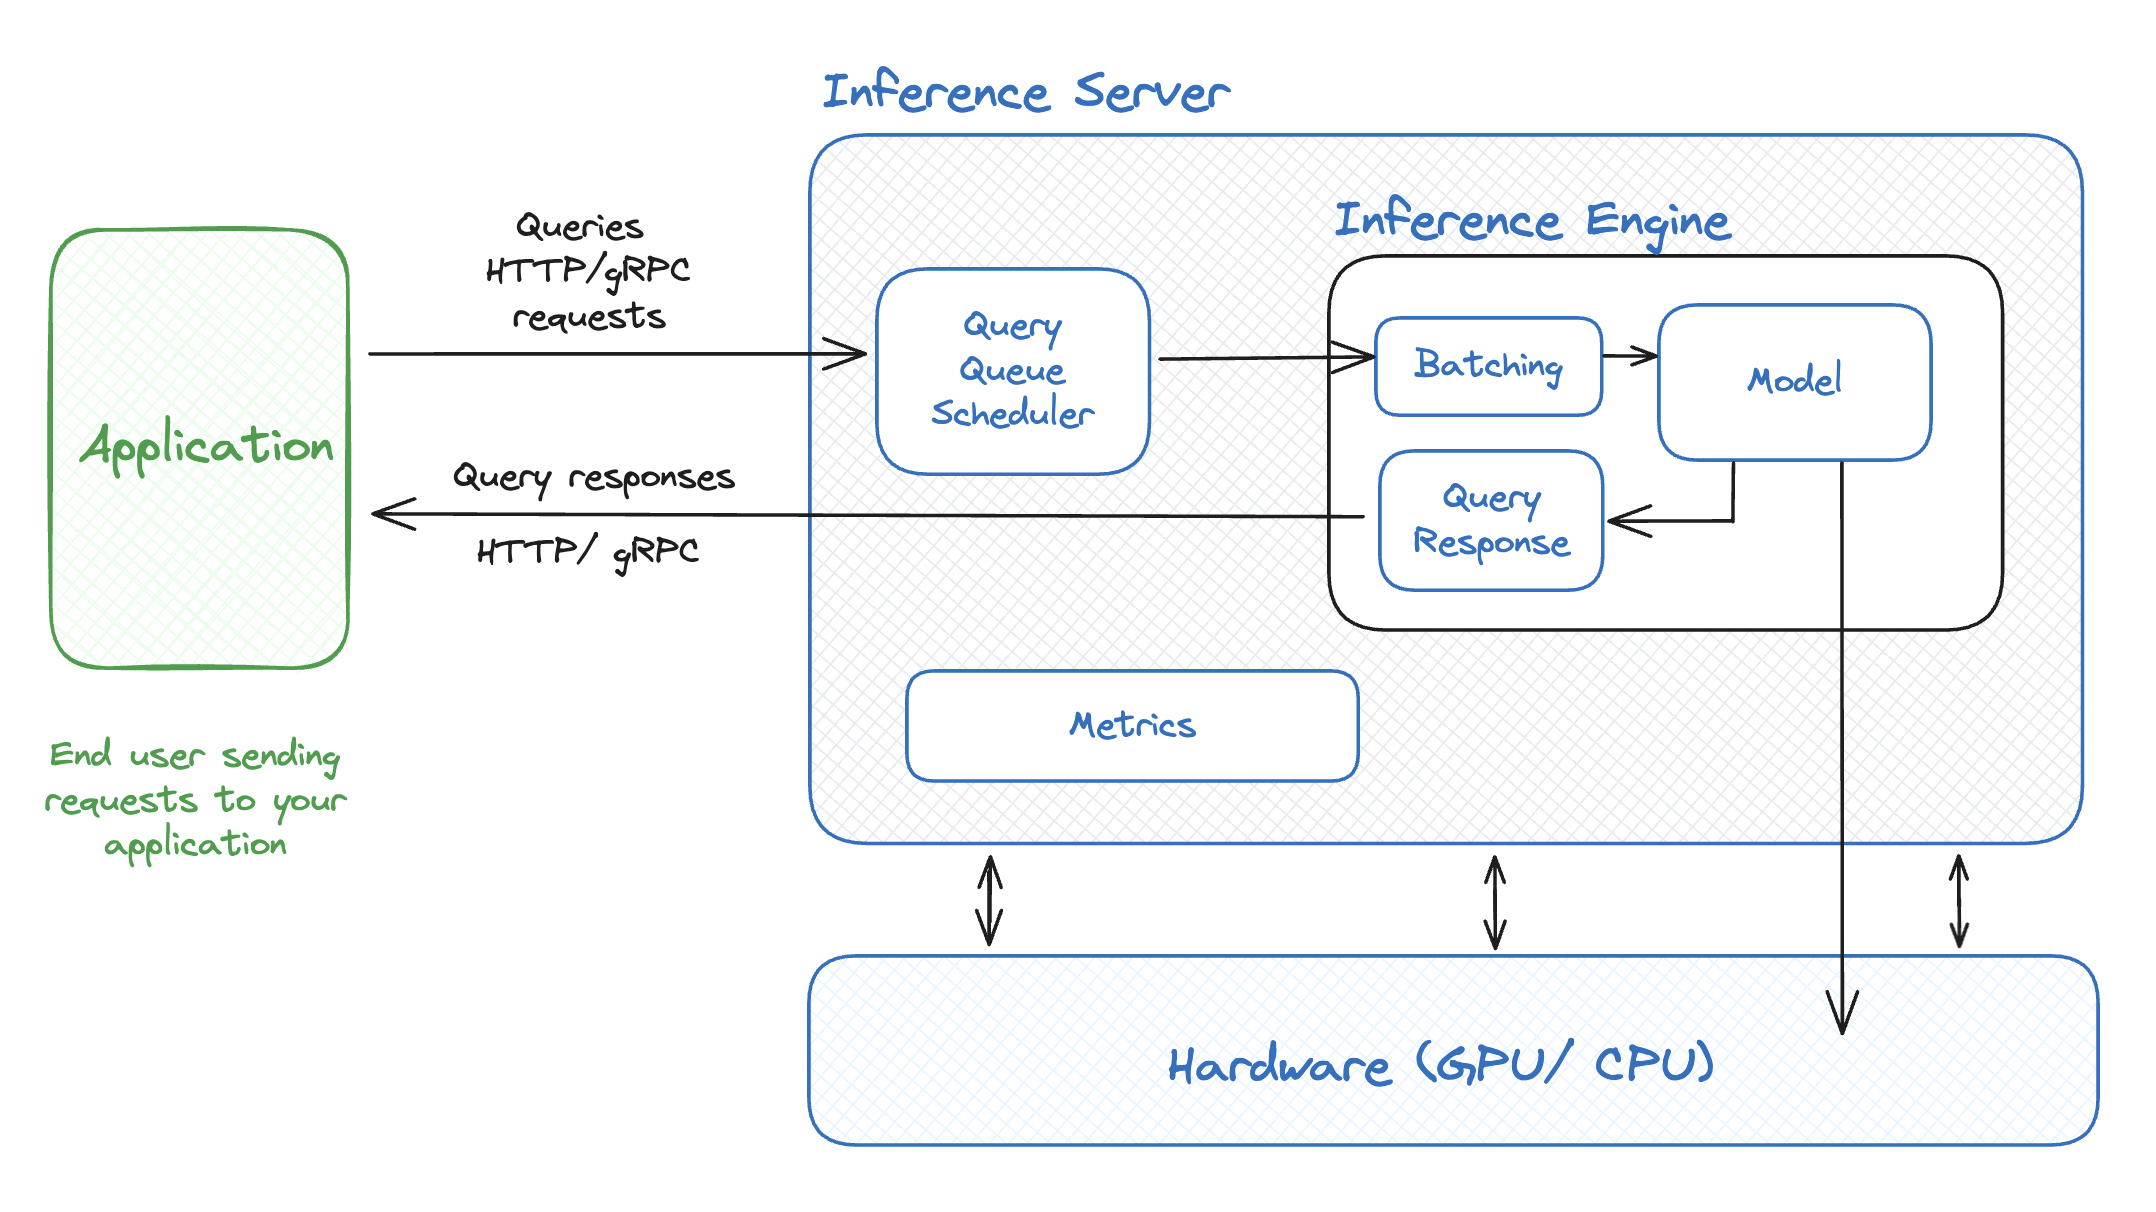
Best LLM Inference Engines and Servers to Deploy LLMs in Production - Koyeb

The Great AI Compression: How LLM Quantization Solves the VRAM Bottleneck
What is LLM monitoring? (Quality, cost, latency, and drift in ...

Top 5 LLM Gateways for Production in 2026 (A Deep, Practical Comparison ...

The New Era of Efficient LLM Deployment - Gradient Flow

Inference Platform: The Missing Layer in On-Prem LLM Deployments
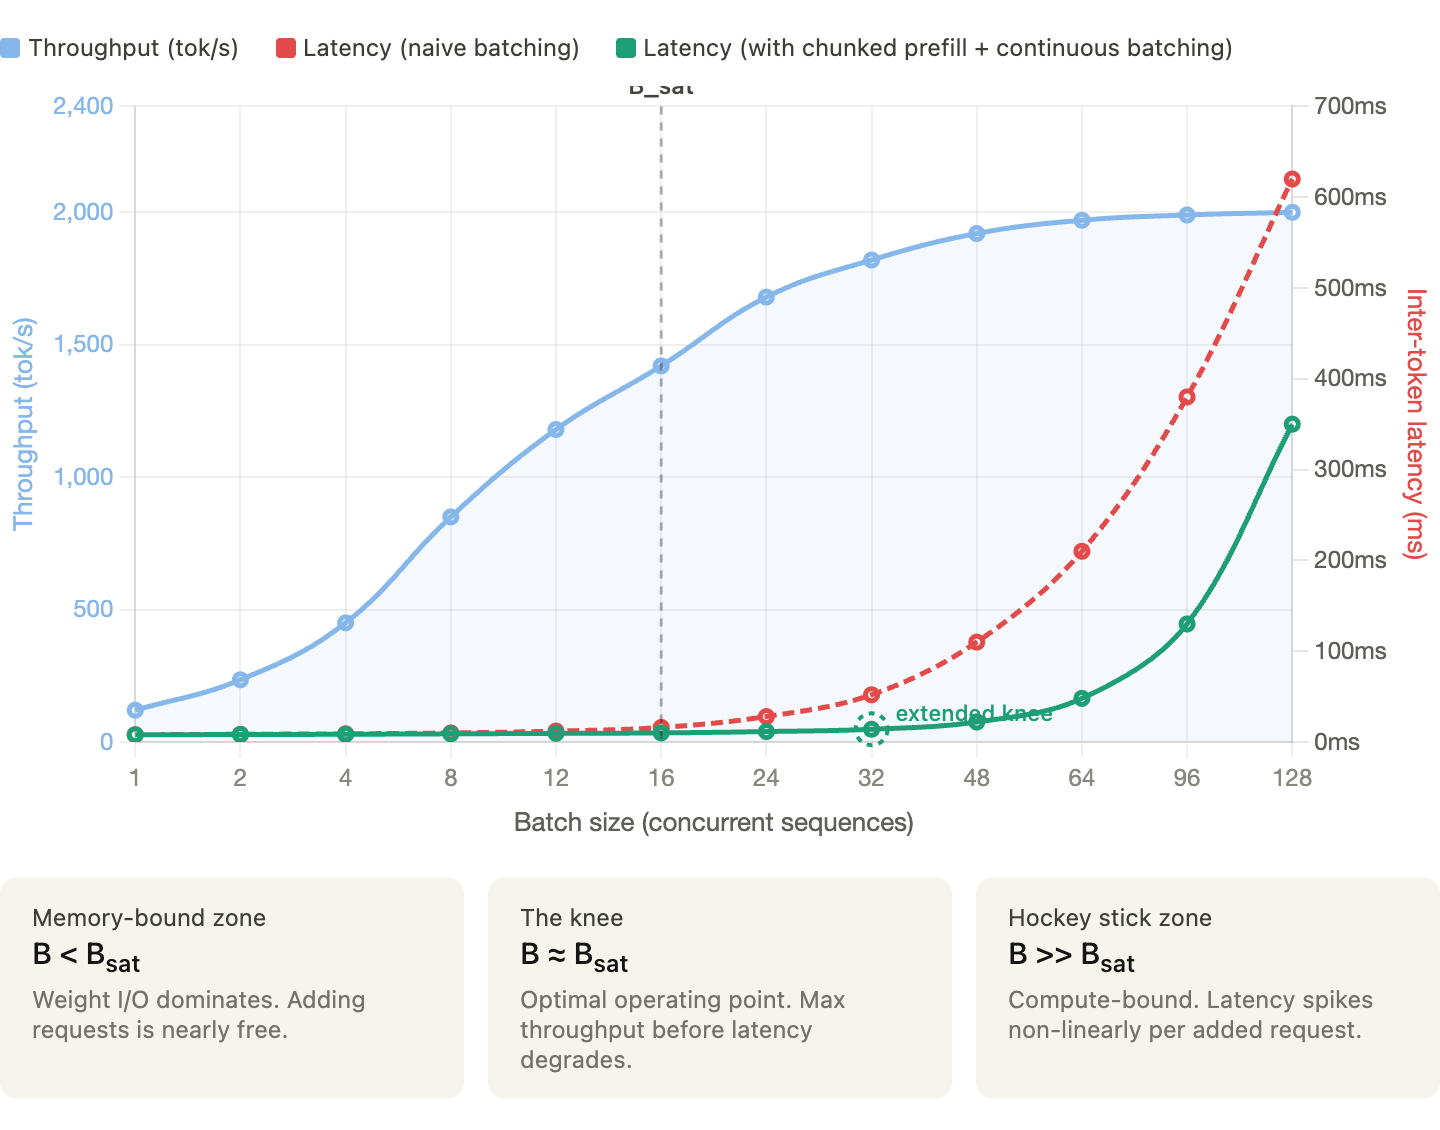
The LLM Inference Trilemma: Throughput, Latency, Cost | DigitalOcean
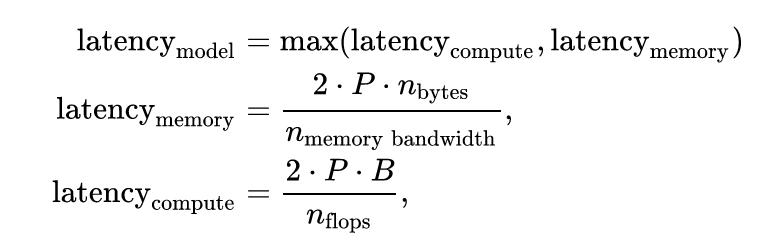
Hardware Design for LLM Inference: Von Neumann Bottleneck - Sasank's Blog

Optimizing AI Performance: A Guide to Efficient LLM Deployment
Advertisement Space (336x280)

How do response time and latency factor into LLM evaluation?

Demystifying LLM Benchmarks: Tokens, Quality, Latency & Throughput | by ...
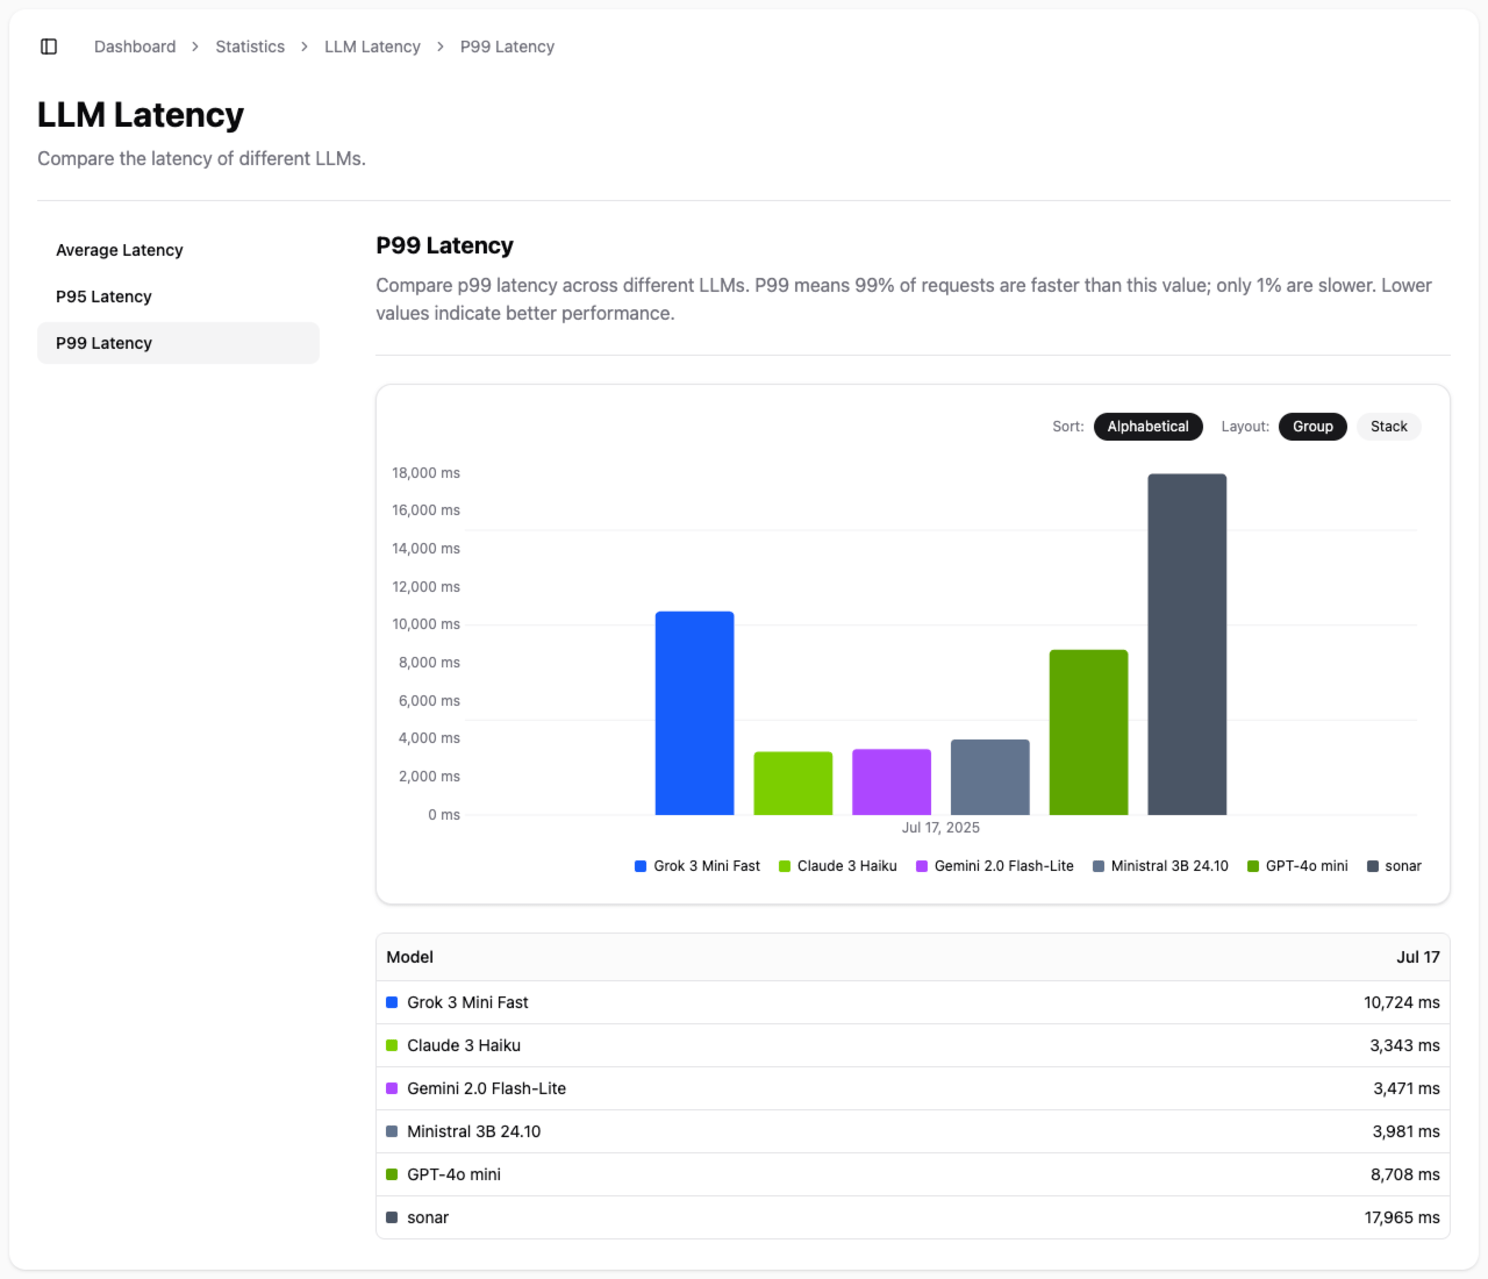
LLM Latency & Performance Monitoring | Nomodo.ai
LLM Deployment Optimization: Latency, Throughput, Cost

Top 7 Performance Bottlenecks in LLM Applications and How to Overcome Them

Boosting LLMs performance in production