
Why Model Size Doesnt Decrease After Int8 Quantization Using Pytorch
Why model size doesn't decrease after INT8 Quantization using pytorch ...
why quantization tool does not decrease model size by 75%? · Issue ...
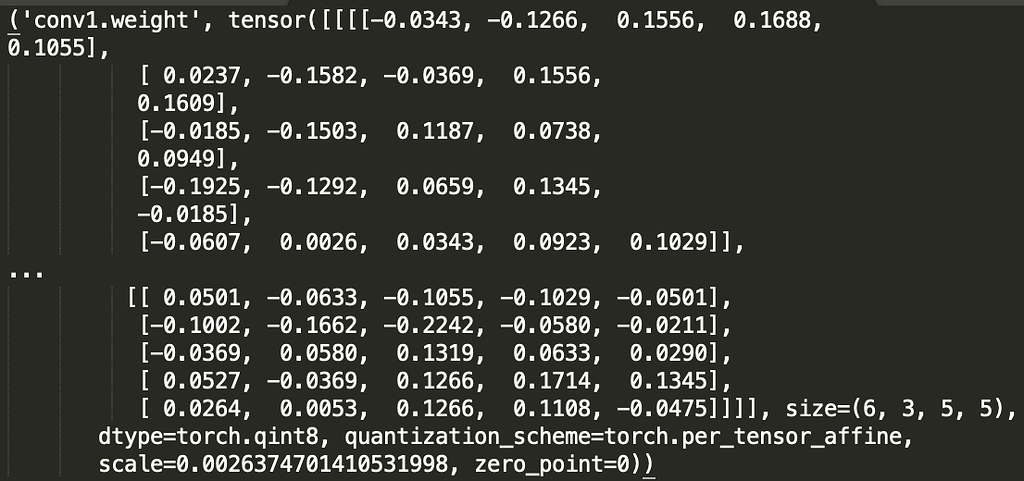
Quantized model parameter after PTQ, INT8? - quantization - PyTorch Forums
The model after INT8 quantization is slower than before and with higher ...
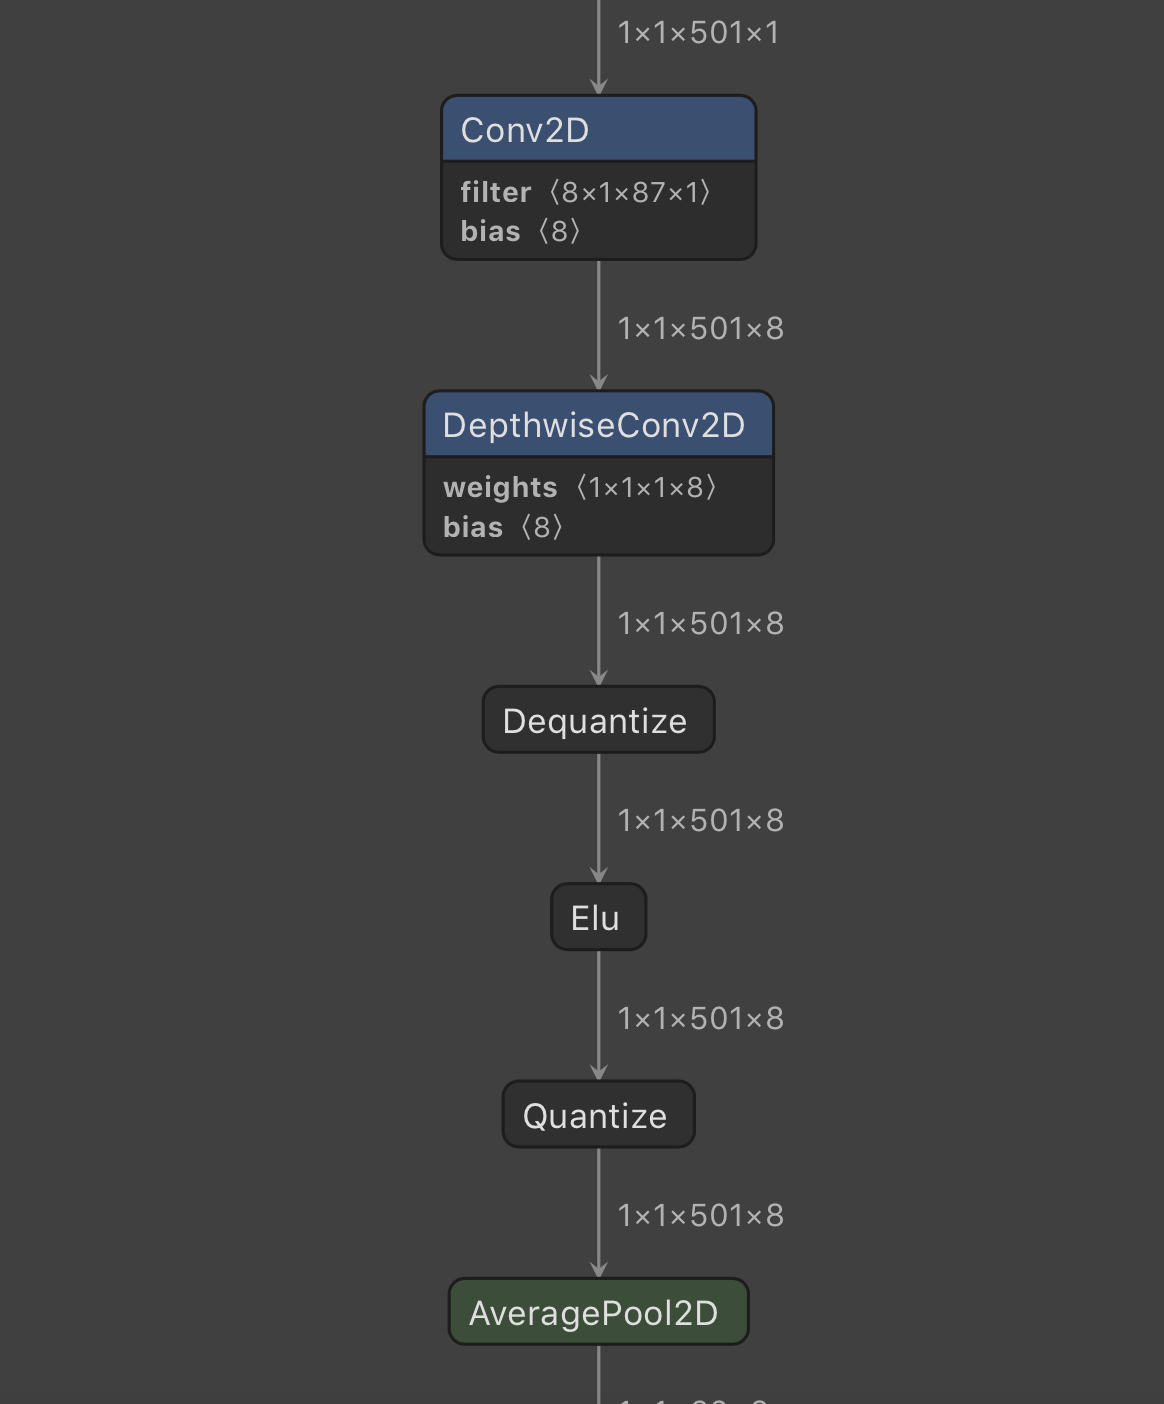
Elu int8 quantization doesn't reduce the size needed by the model on ...
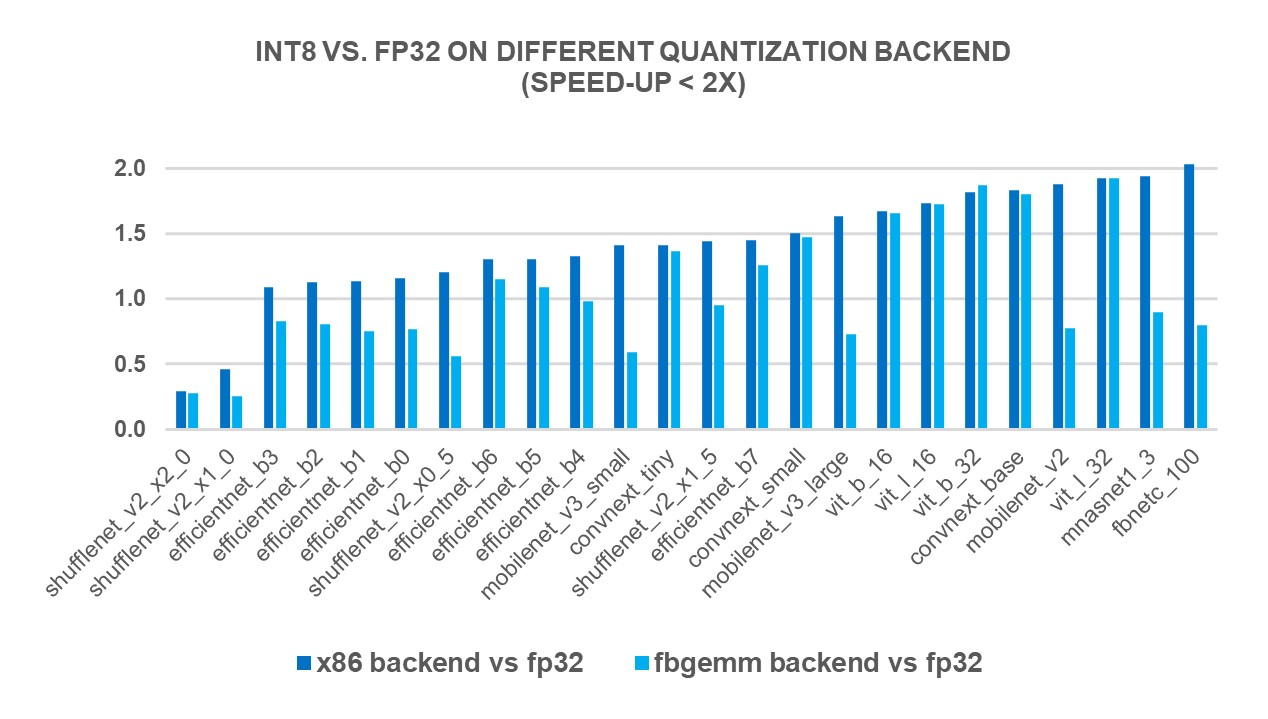
Improve Inference with INT8 Quantization for x86 CPU in PyTorch
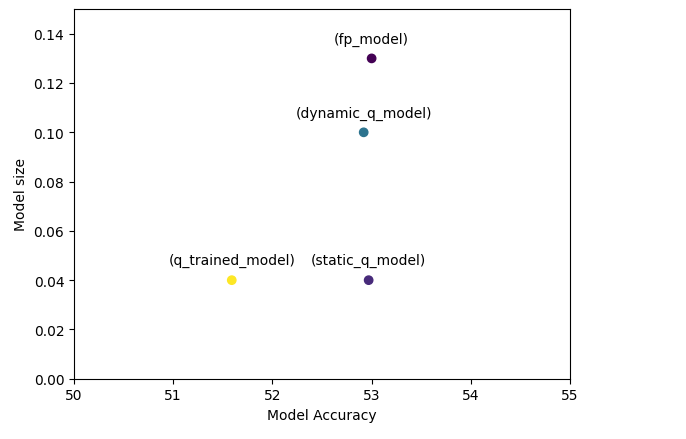
Quantization of custom PyTorch model made easy | by mor40 | Medium
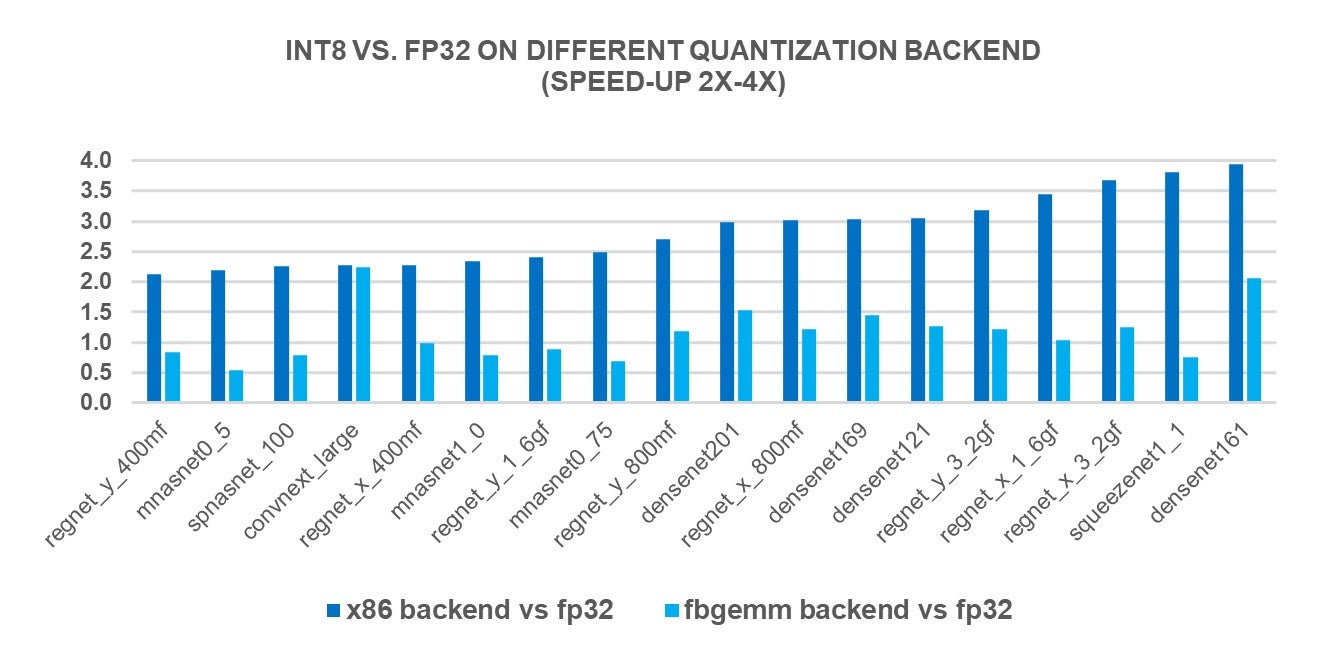
INT8 Quantization for x86 CPU in PyTorch – PyTorch

Model size after quantization, v.s. model accuracy. All layers are ...

GitHub - satya15july/quantization: Model Quantization with Pytorch ...
Advertisement Space (300x250)
Model size after quantization, v.s. accuracy. To compare with ...
LLM Model Size Calculator — How Big is a Model in FP16 / INT8 / INT4 ...
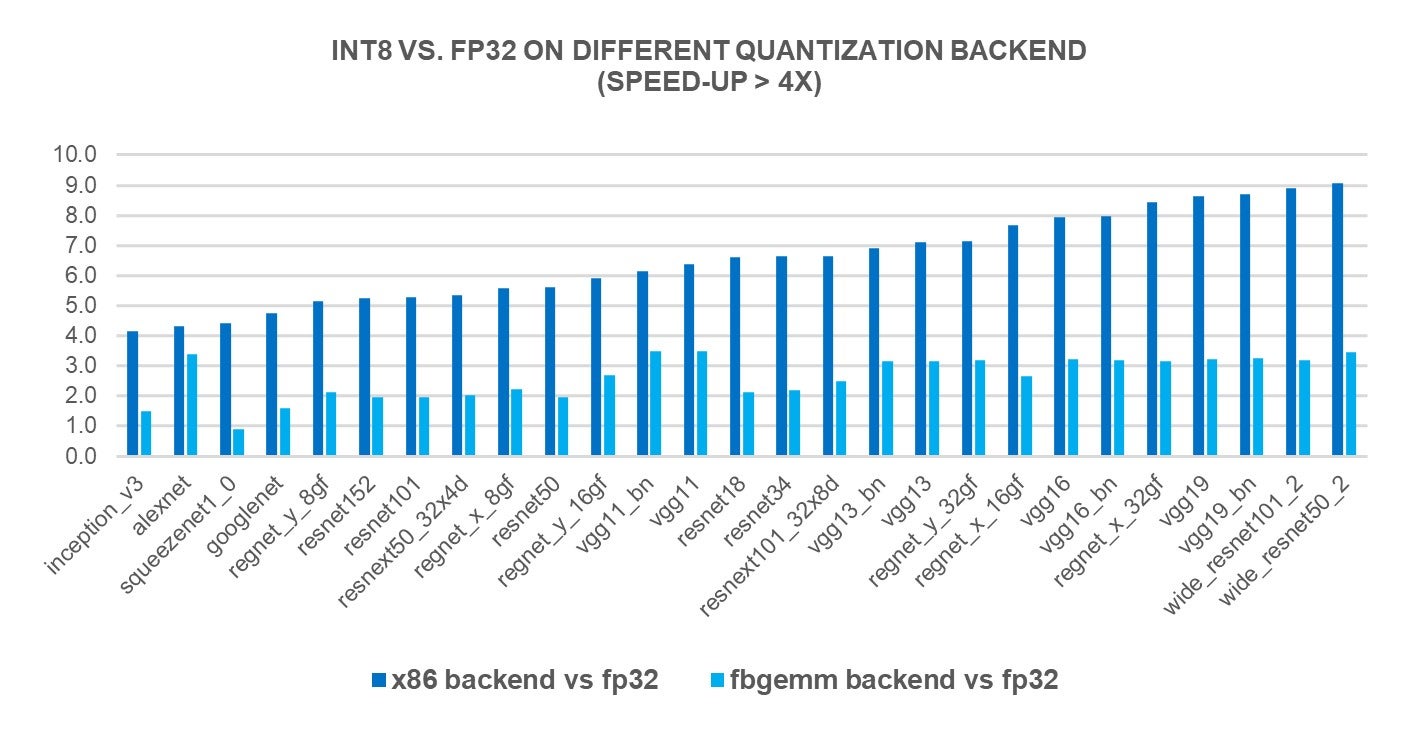
INT8 Quantization for x86 CPU in PyTorch – PyTorch
I use the quantize_static to quantize float32 pytorch model to int8 ...

Achieving FP32 Accuracy for INT8 Inference Using Quantization Aware ...
After quantization aware training, the inference time of the int8 ...

What Is int8 Quantization and Why Is It Popular for Deep Neural ...
INT8 Calibration Reduces Accuracy of PyTorch MNIST Model on Jetson Orin ...

What Is int8 Quantization and Why Is It Popular for Deep Neural ...
Manually load int8 weight from QAT model (quantized with pytorch ...
Advertisement Space (336x280)
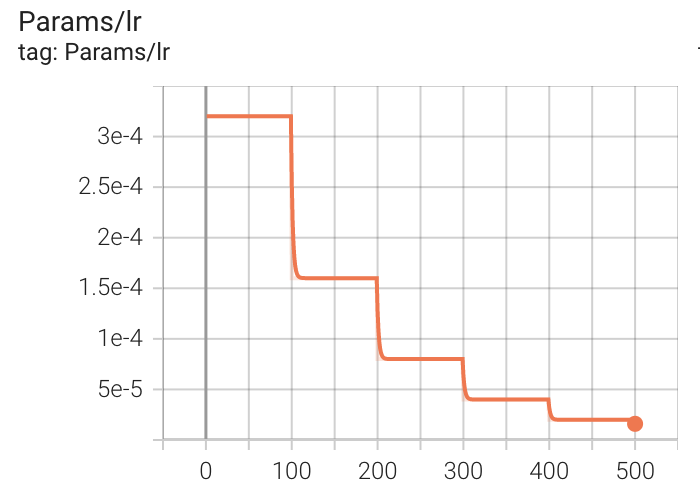
Val loss doesn't decrease after a certain number of epochs - PyTorch Forums
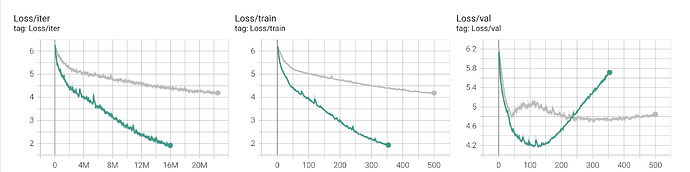
Higher validation loss after using Dropout - PyTorch Forums
Model Quantization for PyTorch (Proposal) · Issue #18318 · pytorch ...
why the yolov8 int8 quant using pytorch_quant is slower than trt --fp16 ...

Qnnpack using activation dtype int8 is not runnable - quantization ...
AI Model Quantization Explained: How FP8, NF4 & INT8 Work in 2026

YOLOv5 Model INT8 Quantization based on OpenVINO™ 2022.1 POT API ...

Perform Model Compression Using Intel® Neural Compressor
Quantization for Large Language Models (LLMs): Reduce AI Model Sizes ...

Curious About Faster ML Models? Discover Model Quantization With ...
Advertisement Space (336x280)
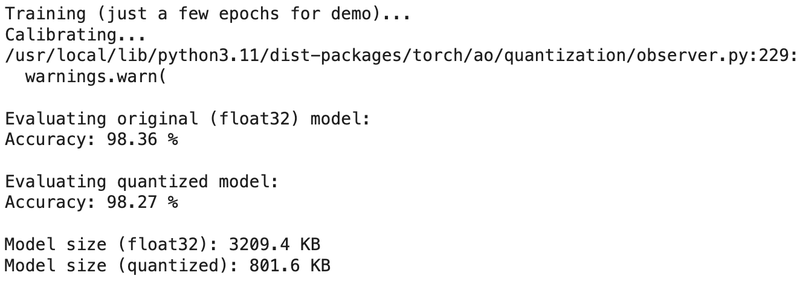
PyTorch Quantization - GeeksforGeeks
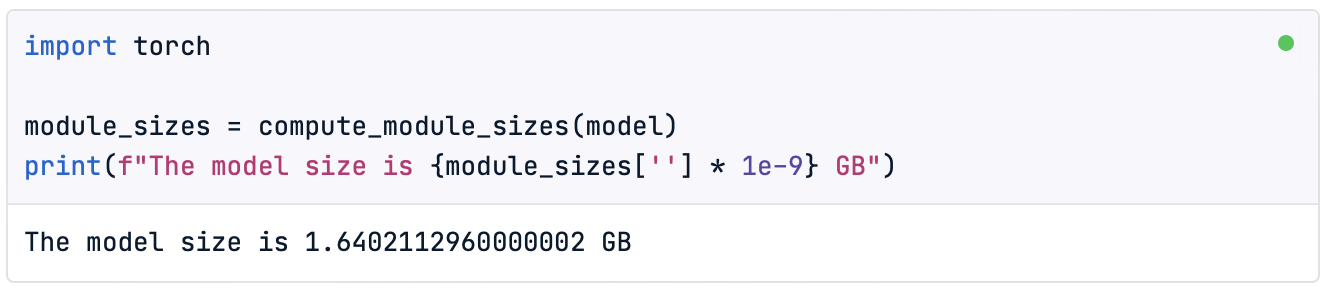
Quantization for Large Language Models (LLMs): Reduce AI Model Sizes ...
Cannot export models to TensorRT with int8 quantization · Issue #82463 ...
Model Quantization | pipecat-ai/smart-turn | DeepWiki
PyTorch Quantization | What is PyTorch Quantization? | How to works?

Quantized Model Pytorch at Brayden Woodd blog