
Will Input Be Quantified In Tensorrt Int8 Mode Issue 2927 Nvidia
will input be quantified in tensorrt int8 mode · Issue #2927 · NVIDIA ...
How does TensorRT implements the `Add` in INT8 mode ? · Issue #1144 ...
Failed to convert ONNX model to TensorRT in int8 mode · Issue #2606 ...

How does TensorRT implements the `Add` in INT8 mode ? · Issue #1144 ...

How does TensorRT implements the `Add` in INT8 mode ? · Issue #1144 ...
TensorRT QAT not support resize op in int8 ? · Issue #2976 · NVIDIA ...

When will the int8 mode will be supported in DINO - TAO Toolkit ...
TensorRT Deconvolution in INT8 mode gives obviously wrong result ...

DCNV2 plugin tensorrt 8.5 arm int8 convert error · Issue #2698 · NVIDIA ...
TensorRT 5 INT8 calibration sample failing · Issue #389 · NVIDIA ...
Advertisement Space (300x250)
Int8 Inference in C++ TensorRT API without Onnx Model · Issue #659 ...
fail to quantize model : Operator `Equal` in INT8 mode · Issue #1092 ...
For any input TensorRT model output is all zero · Issue #2151 · NVIDIA ...
DCNV2 plugin tensorrt 8.5 arm int8 convert error · Issue #2698 · NVIDIA ...
operator "Or" in int8 mode · Issue #499 · NVIDIA/TensorRT · GitHub
3D layers show no speedup in INT8 on cuda cores · Issue #1176 · NVIDIA ...
Convert ONNX model with INT8 mode failed. · Issue #344 · NVIDIA ...
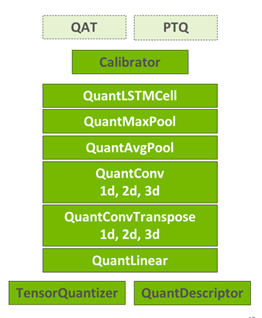
利用 NVIDIA TensorRT 量化感知训练实现 INT8 推理的 FP32 精度 - NVIDIA 技术博客

Quantization to int8 still confusing - TensorRT - NVIDIA Developer Forums
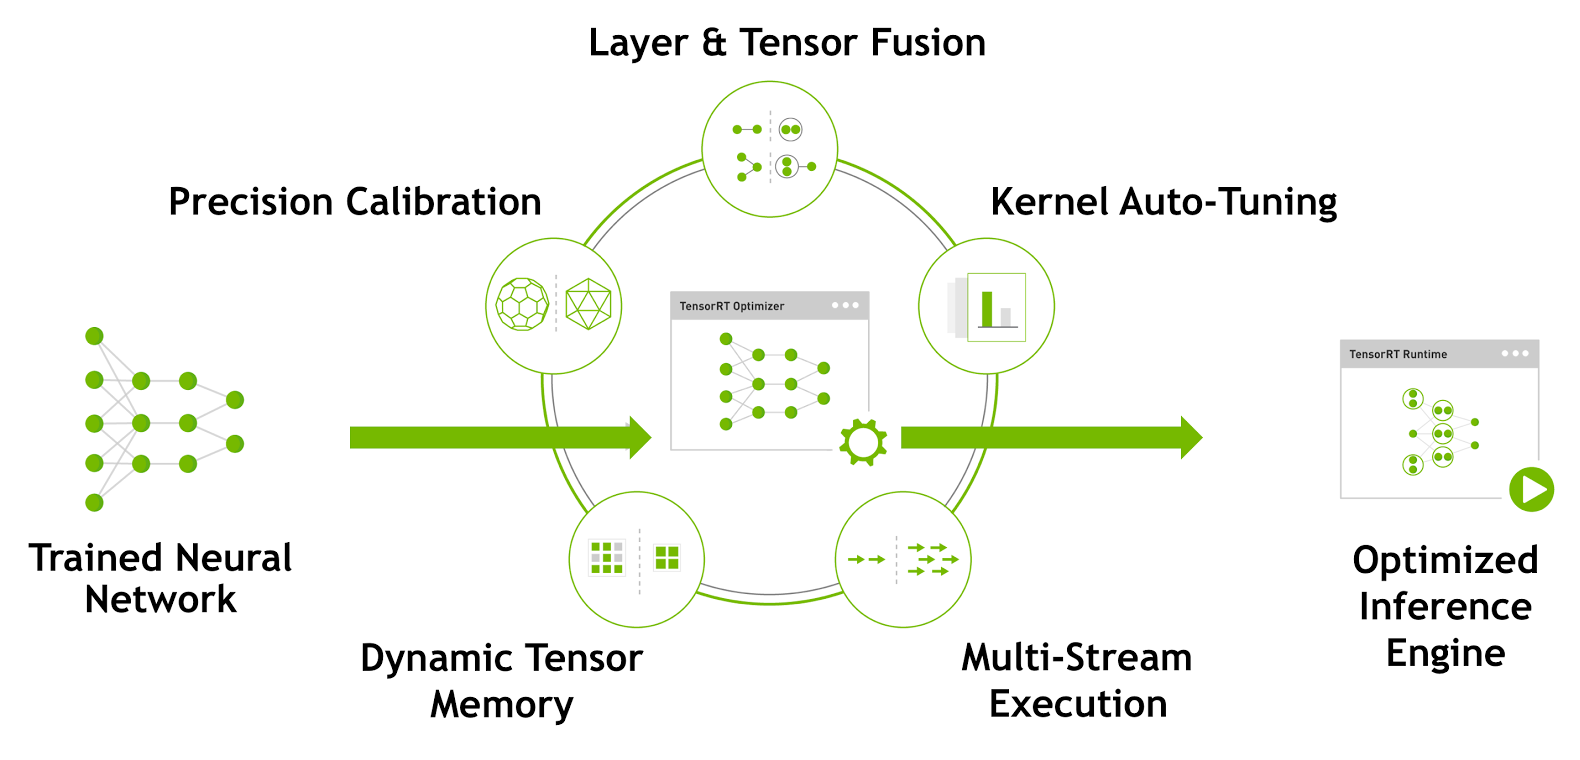
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...
Advertisement Space (336x280)
Int8 mode is slower than fp16 · Issue #993 · NVIDIA/TensorRT · GitHub
INT8 mode layer fusion · Issue #887 · NVIDIA/TensorRT · GitHub
ONNX -> TensorRT FP32 model with INT8 input produces error: Calibration ...
Driver error when upgrade TensorRT 6 to TensorRT 7 using YoloV4 in INT8 ...
Inconsistent result of INT8 inferencing in TensorRT 8.6 when running ...
TensorRT 8.6.1.6 can't build engine with INT8 ONNX on NVIDIA GeForce ...
int8 mode only 5-10% faster than fp16 · Issue #585 · NVIDIA/TensorRT ...
TensorRT INT8 calibration python API · Issue #2322 · NVIDIA/TensorRT ...

Can I write a plugin that only support INT8 implementation in TensorRT ...
Build engine file failed with INT8 calibration mode · Issue #2109 ...
Advertisement Space (336x280)
When I use the TensorRT to infer MoblieNet in the INT8 mode,I meet the ...
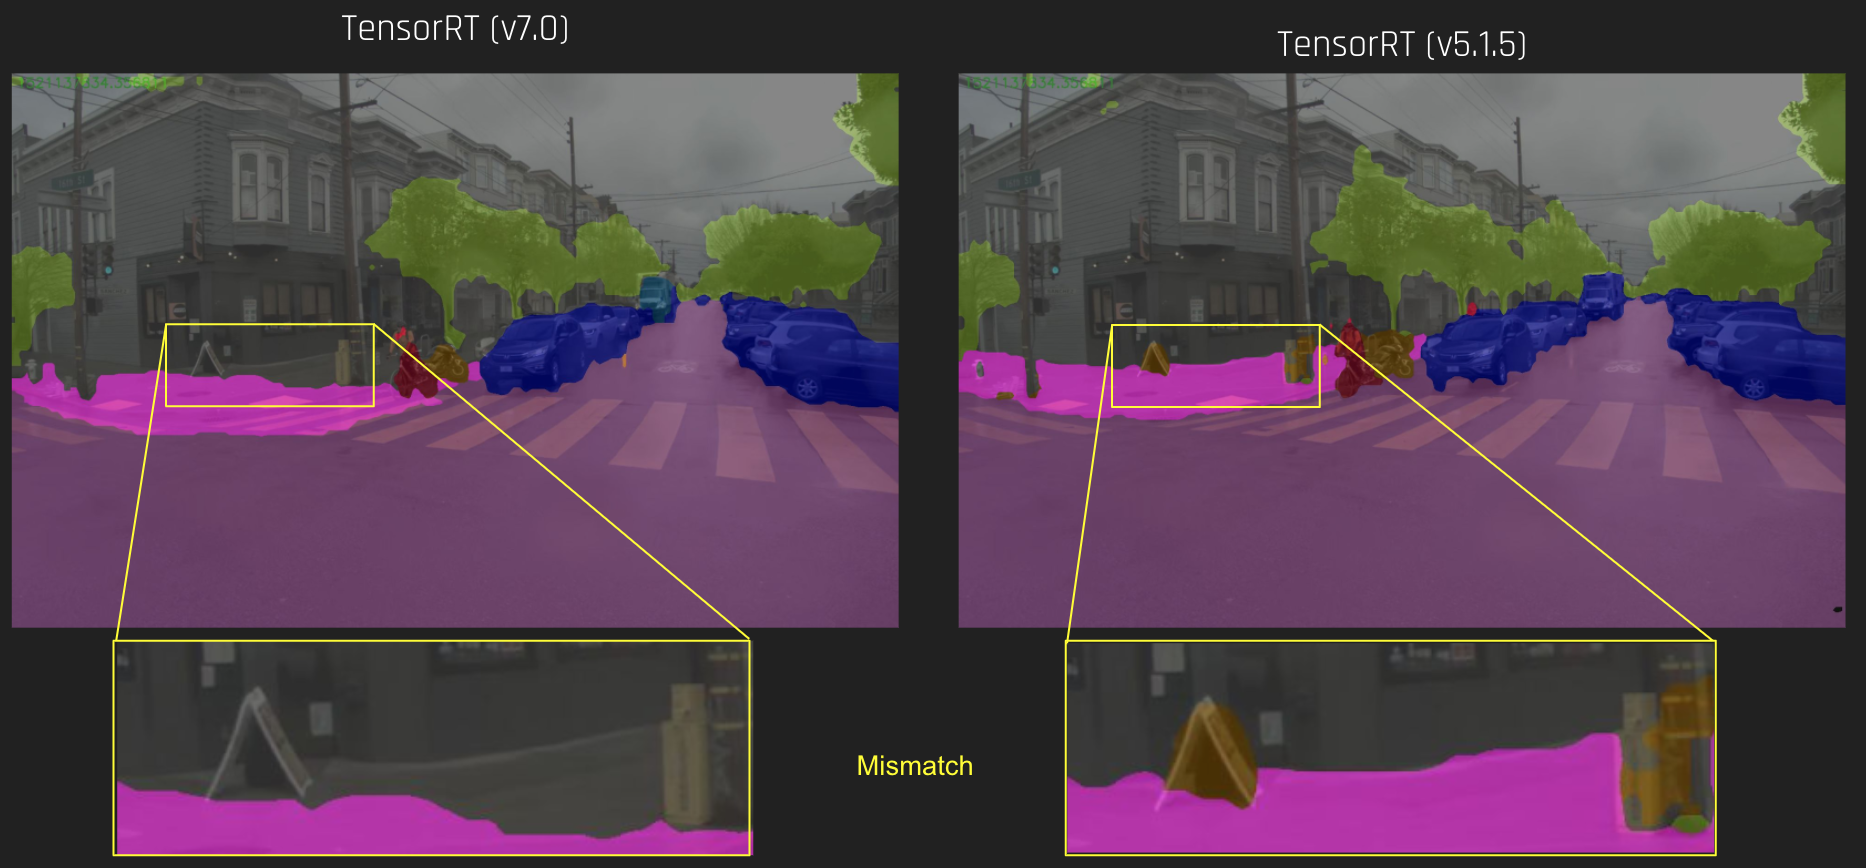
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...

Driver error when upgrade TensorRT 6 to TensorRT 7 using YoloV4 in INT8 ...
How to get INT8 calibration cache format in TensorRT? · Issue #625 ...
The issue of GPU usage in tensorrt dla inference models · Issue #2711 ...
build yolov8 QAT model int8 engine failed · Issue #4532 · NVIDIA ...