
3dvla Enhancing Vision Language Action Models Via 3d Spatial
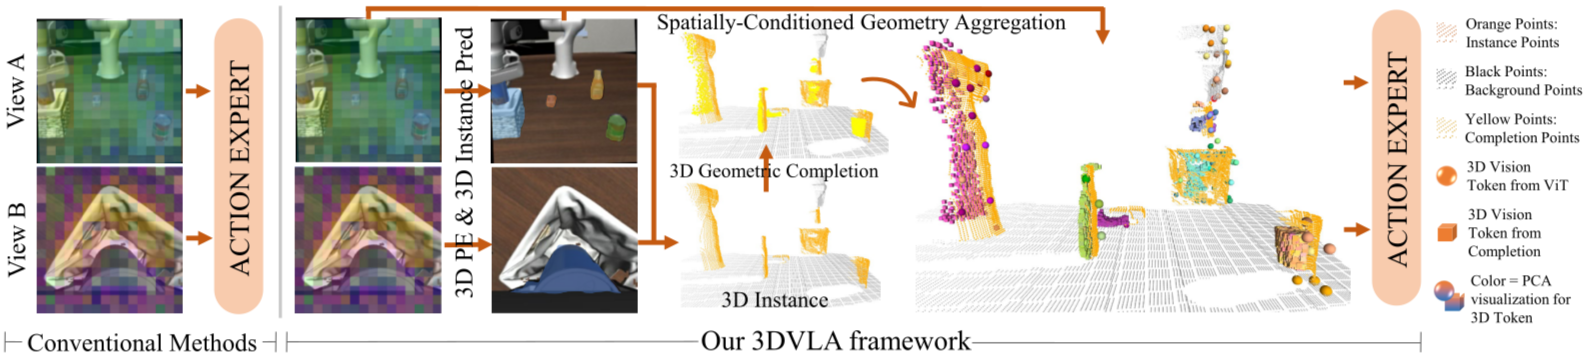
[論文レビュー] 3DVLA: Enhancing Vision-Language-Action Models via 3D Spatial ...

3DVLA: Enhancing Vision-Language-Action Models via 3D Spatial and ...

3DVLA: Enhancing Vision-Language-Action Models via 3D Spatial and ...

(PDF) OG-VLA: 3D-Aware Vision Language Action Model via Orthographic ...

Vision Language Action Models - OpenVLA, π0, RT-2, Gemini Robotics ...

GST-VLA: Structured Gaussian Spatial Tokens for 3D Depth-Aware Vision ...

[论文评述] MoLe-VLA: Dynamic Layer-skipping Vision Language Action Model ...

(PDF) I Know About "Up"! Enhancing Spatial Reasoning in Visual Language ...

3D Vision and Language Pretraining with Large-Scale Synthetic Data
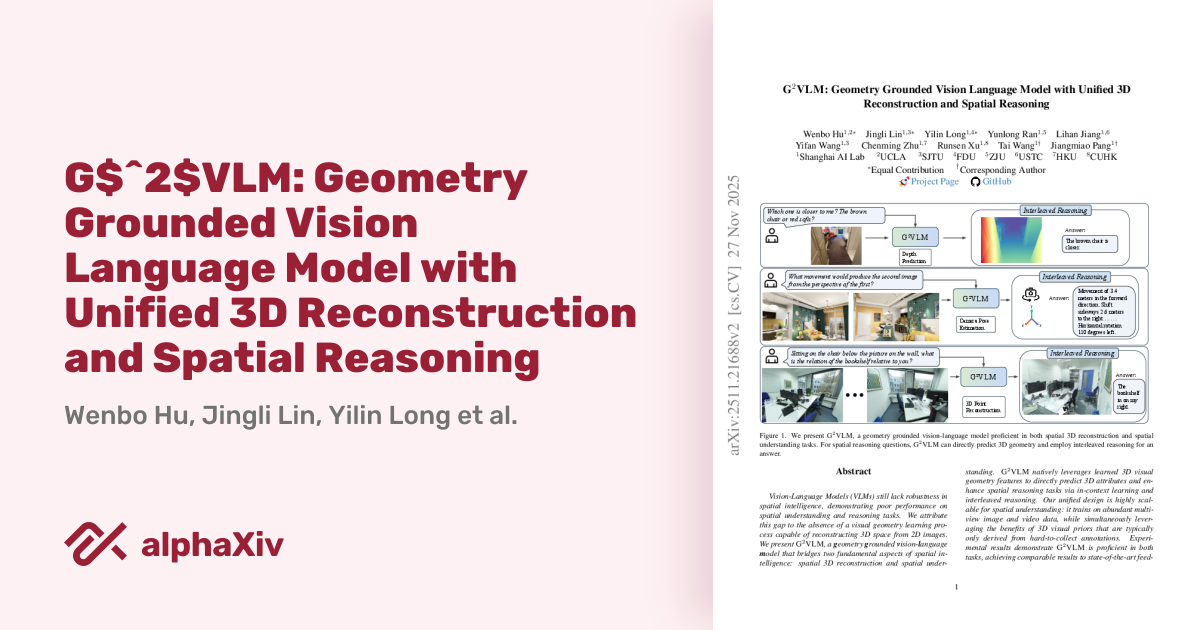
G$^2$VLM: Geometry Grounded Vision Language Model with Unified 3D ...
Advertisement Space (300x250)

[논문 리뷰] DepthVLA: Enhancing Vision-Language-Action Models with Depth ...

[논문 리뷰] PointVLA: Injecting the 3D World into Vision-Language-Action Models

GitHub - UMass-Embodied-AGI/3D-VLA: [ICML 2024] 3D-VLA: A 3D Vision ...

Paper page - DepthVLA: Enhancing Vision-Language-Action Models with ...

DepthVLA: Enhancing Vision-Language-Action Models with Depth-Aware ...

SPATIAL FORCING: IMPLICIT SPATIAL REPRESENTATION ALIGNMENT FOR VISION ...

PointVLA: Injecting the 3D World into Vision-Language-Action Models
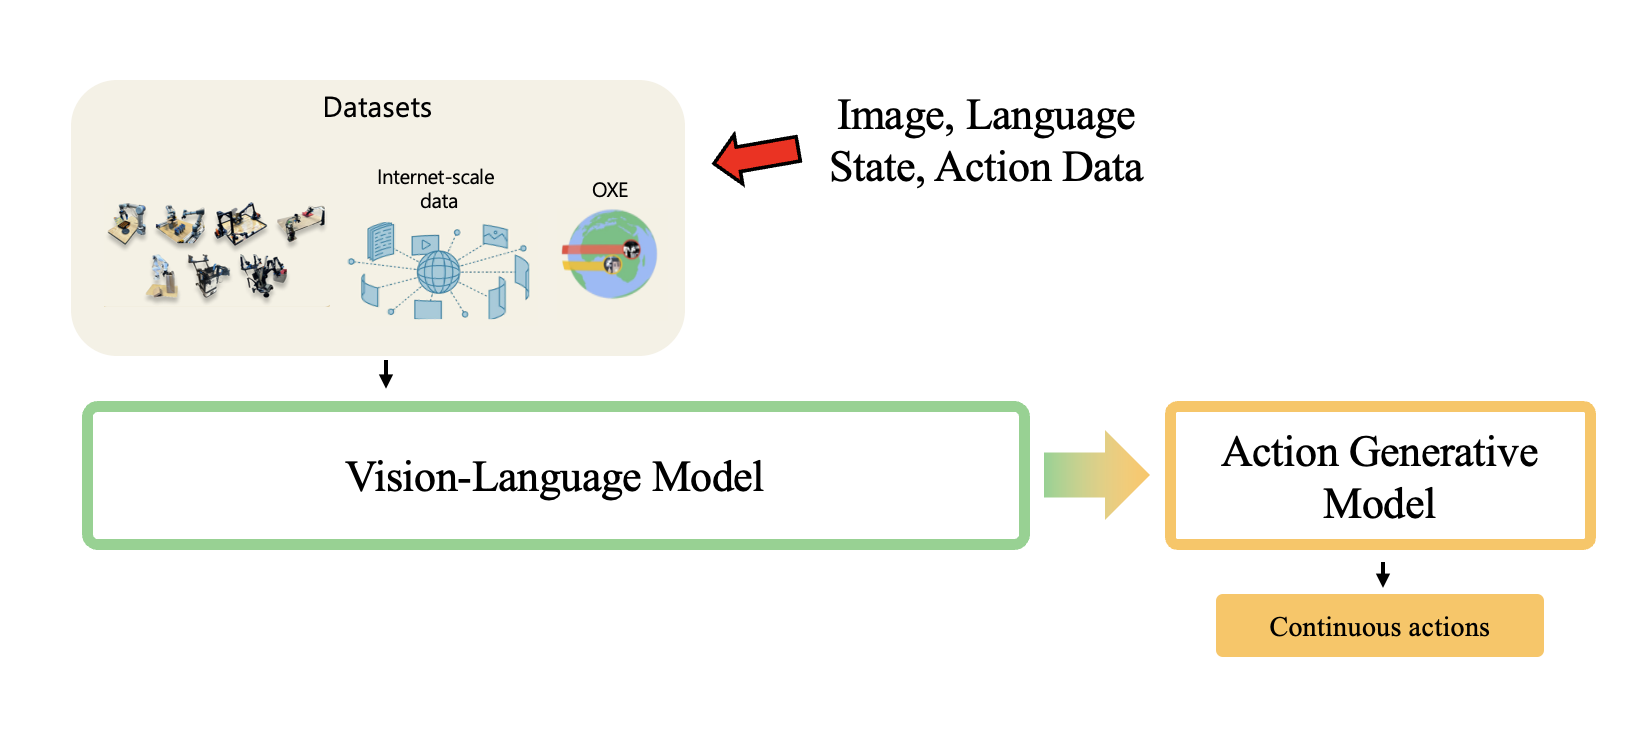
VLA (Vision Language Action model)란?

Geo3DVQA: Evaluating Vision-Language Models for 3D Geospatial Reasoning ...

VLM-3R: Vision-Language Models Augmented with Instruction-Aligned 3D ...
Advertisement Space (336x280)
GitHub - UMass-Embodied-AGI/3D-VLA: [ICML 2024] 3D-VLA: A 3D Vision ...

Vision-Language Models as Differentiable Semantic and Spatial Rewards ...

3D-GENERALIST: Vision-Language-Action Models for Crafting 3D Worlds-CSDN博客

Robust Vision-Language-Action Models via Object-Centric Learning and ...

(PDF) PointVLA: Injecting the 3D World into Vision-Language-Action Models

Paper page - StereoVLA: Enhancing Vision-Language-Action Models with ...
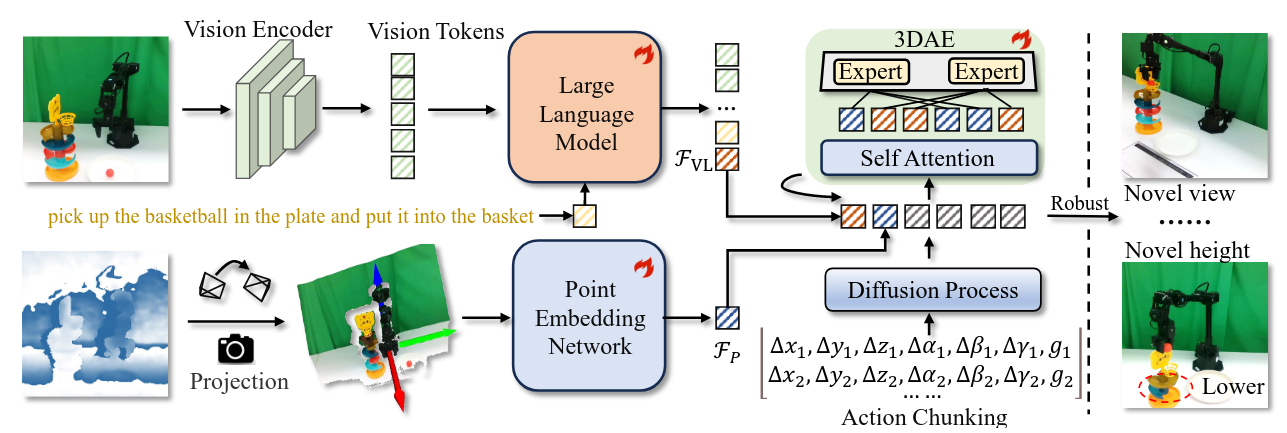
GeoVLA: Empowering 3D Representations in Vision-Language-Action Models
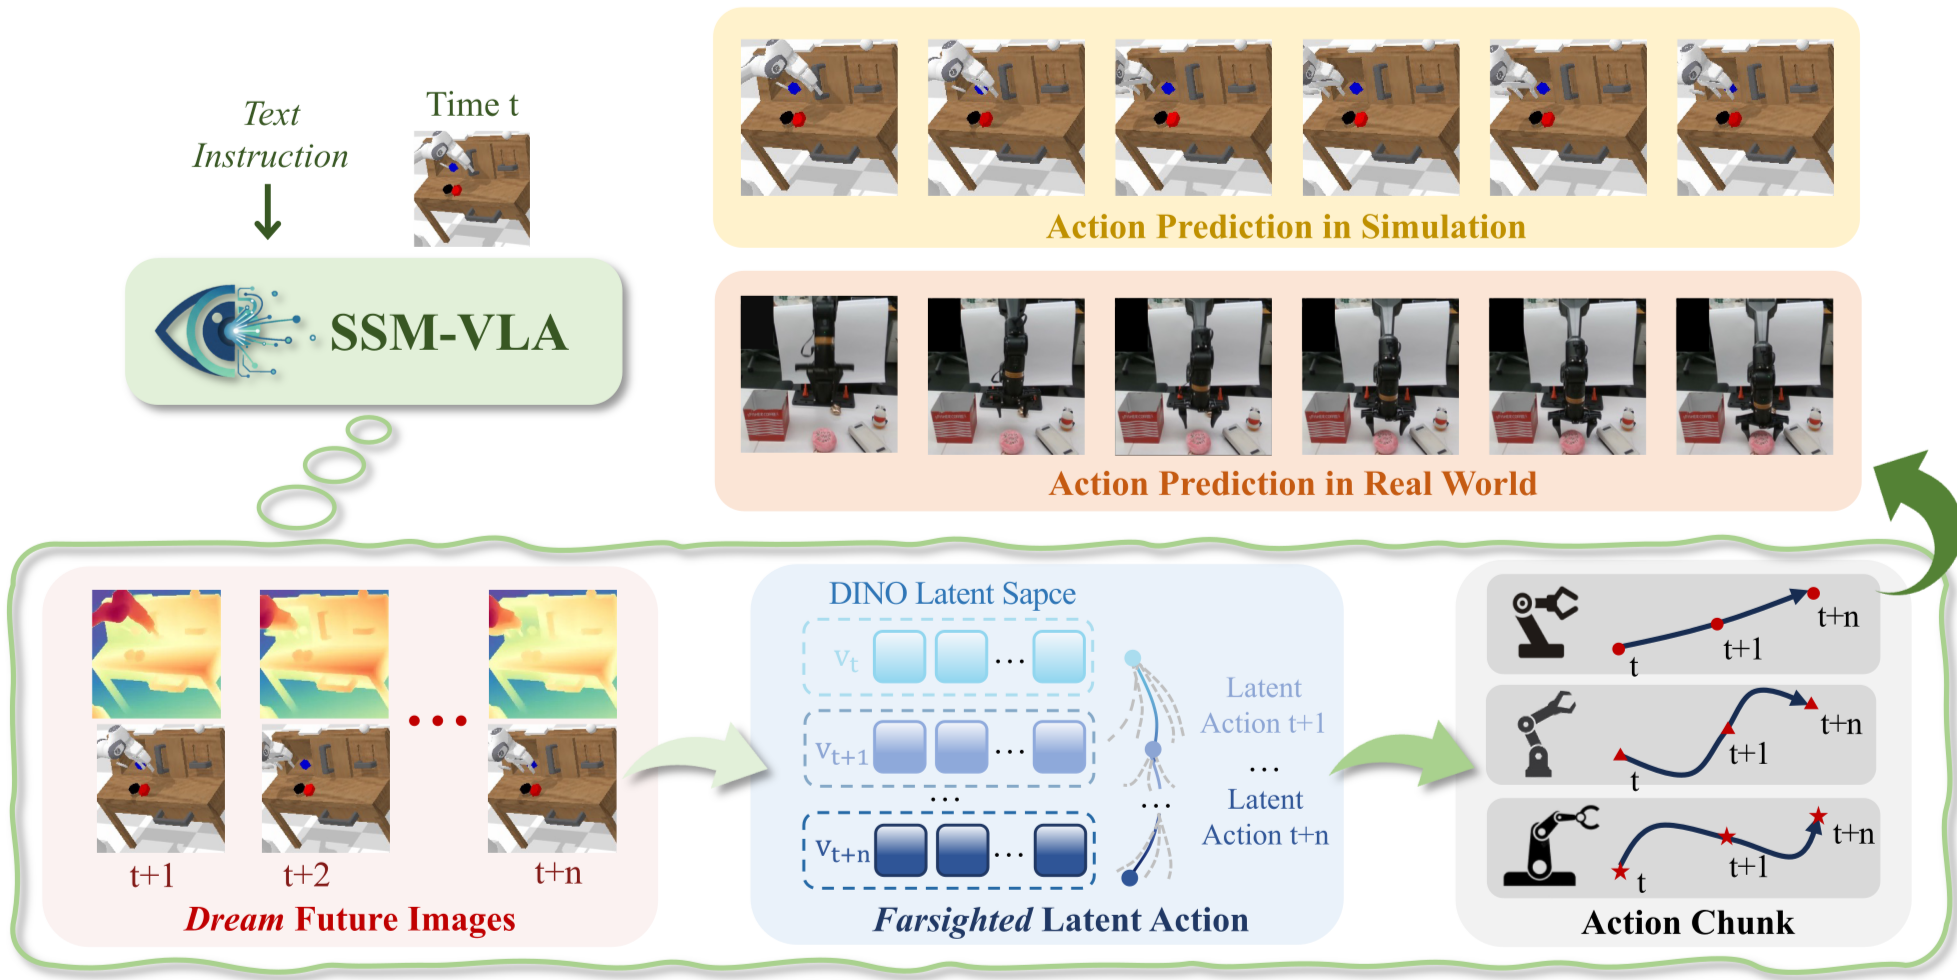
[论文评述] Seeing Space and Motion: Enhancing Latent Actions with Spatial ...
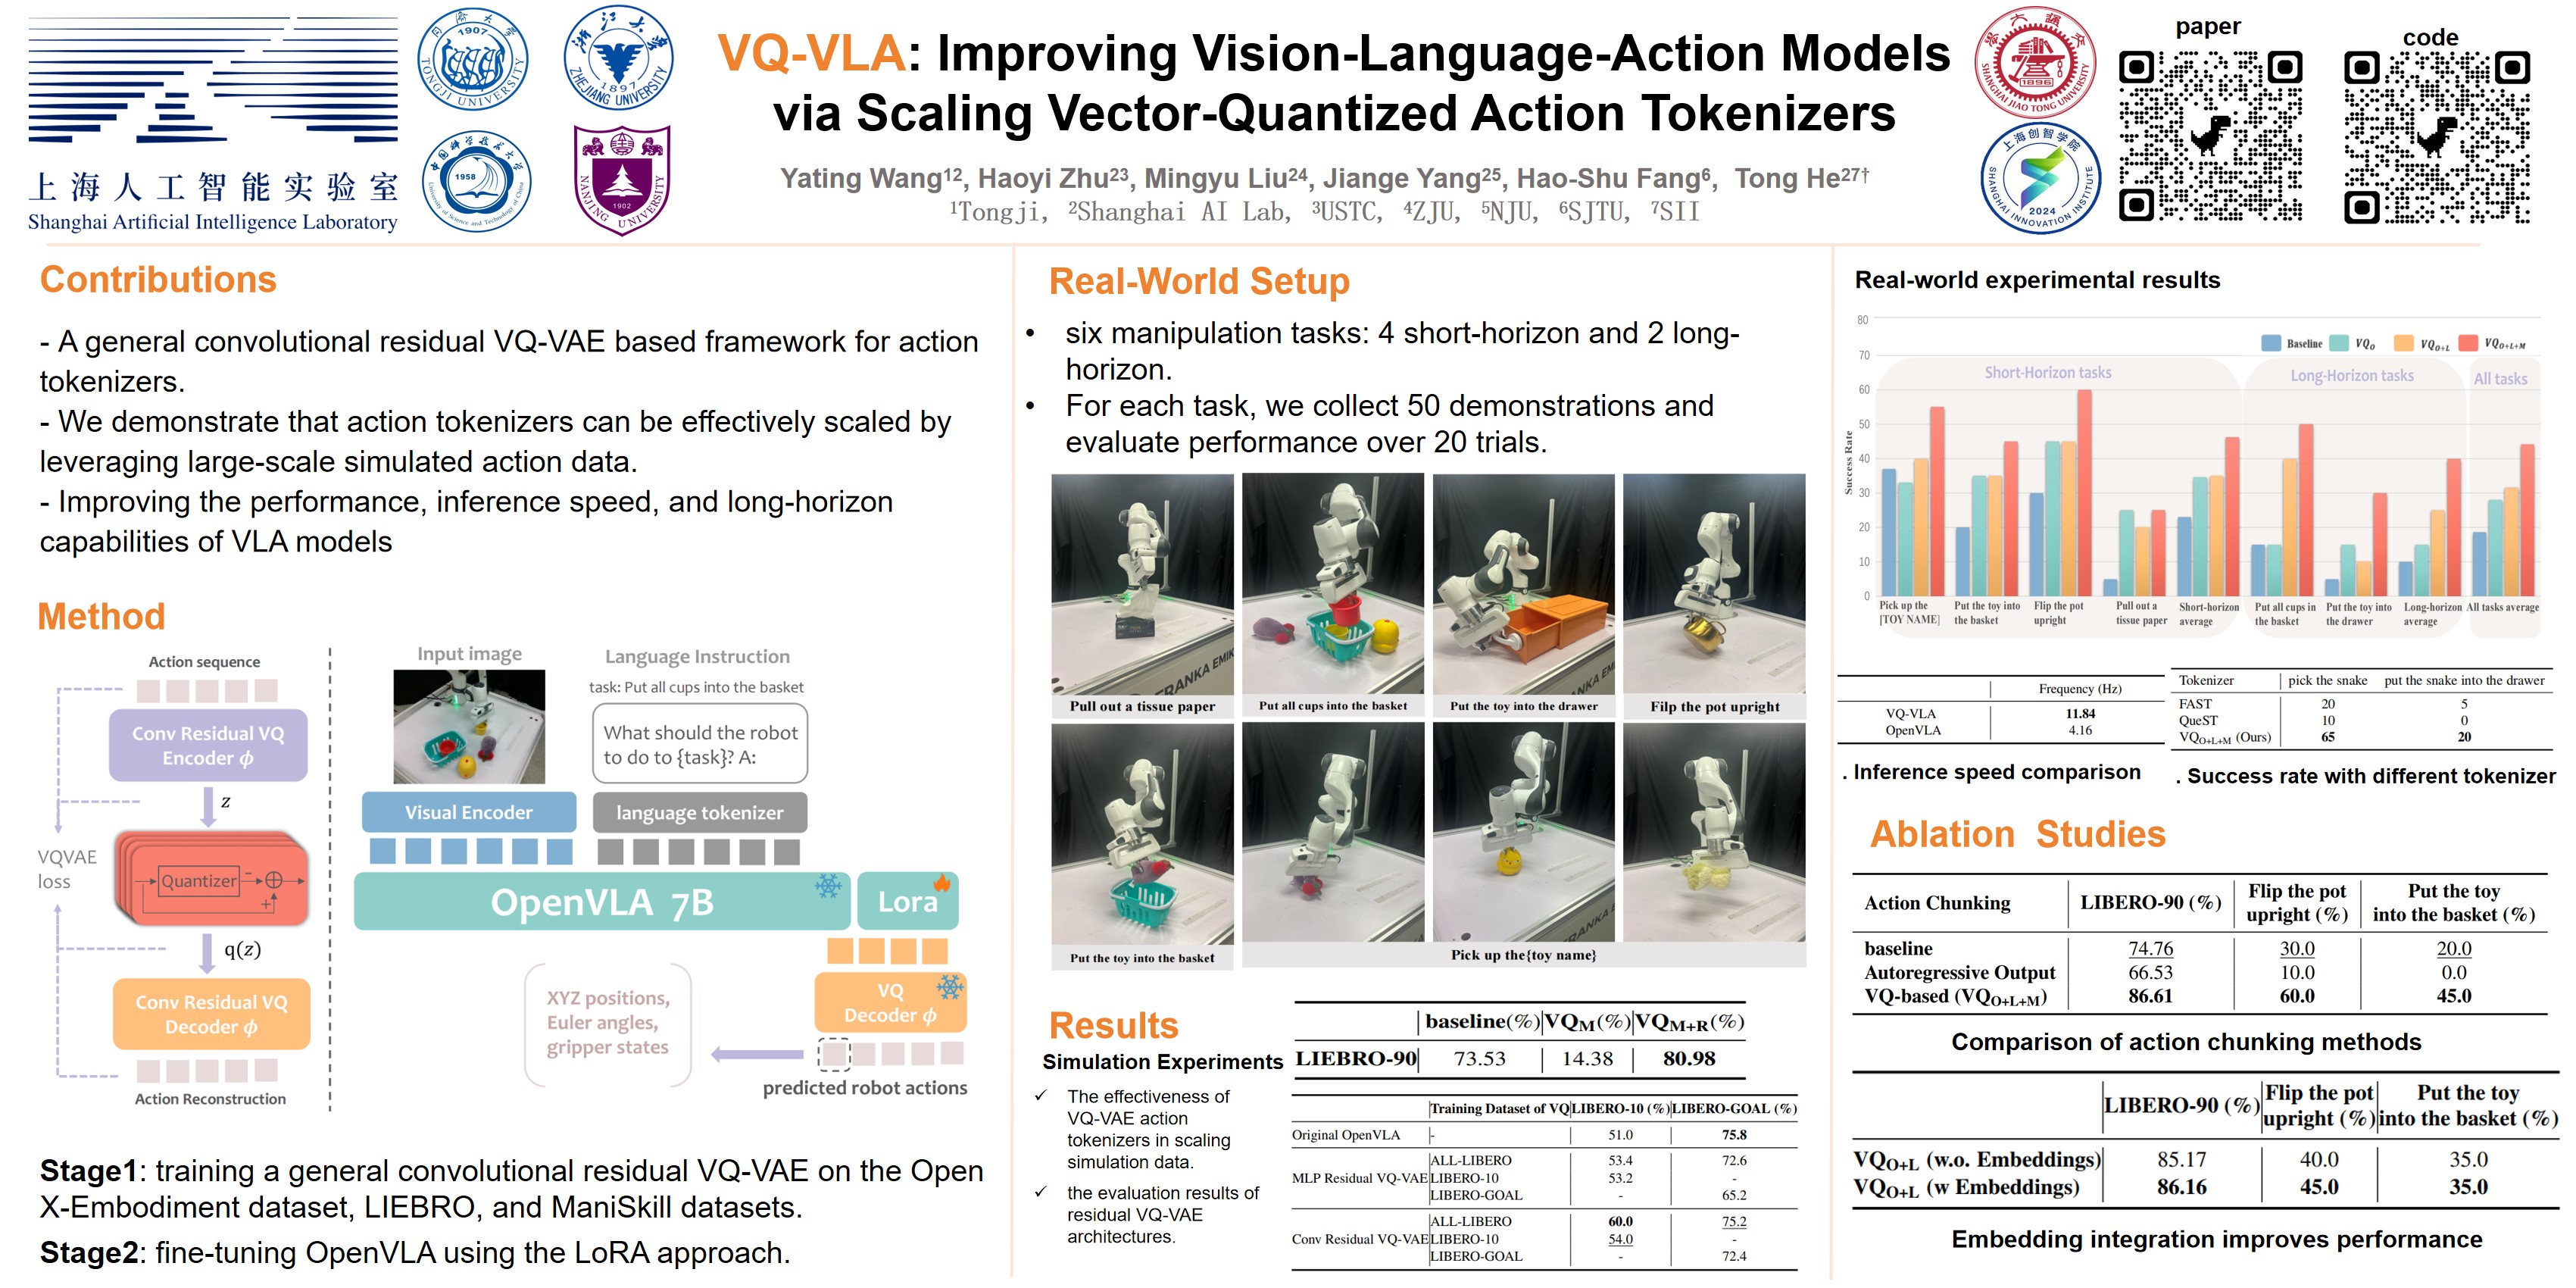
ICCV Poster VQ-VLA: Improving Vision-Language-Action Models via Scaling ...
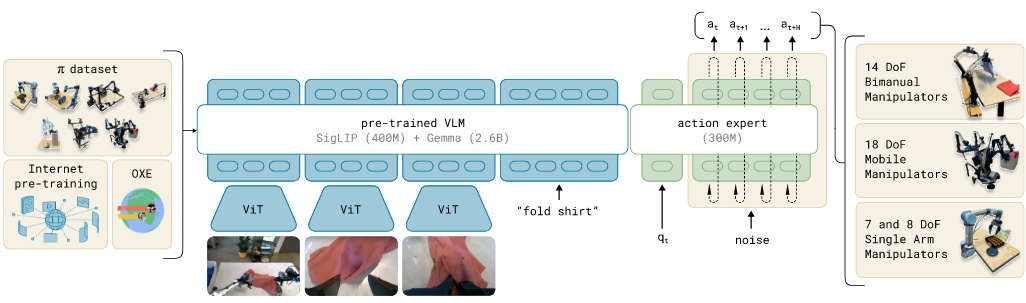
VLA (Vision Language Action model)란?
Advertisement Space (336x280)

Paper page - VLA-R1: Enhancing Reasoning in Vision-Language-Action Models

PointVLA: Injecting the 3D World into Vision-Language-Action Models

Look Before Acting: Enhancing Vision Foundation Representations for ...

(PDF) Improving Vision-Language-Action Models via Chain-of-Affordance

[논문 리뷰] Improving Vision-Language-Action Models via Chain-of-Affordance

(PDF) LEO-VL: Towards 3D Vision-Language Generalists via Data Scaling ...