
Accelerate Large Scale Llm Inference And Kv Cache Offload With Cpu Gpu
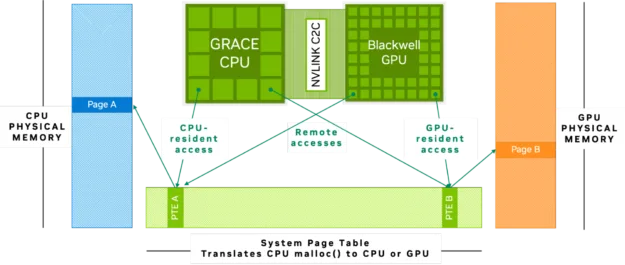
Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...
Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...
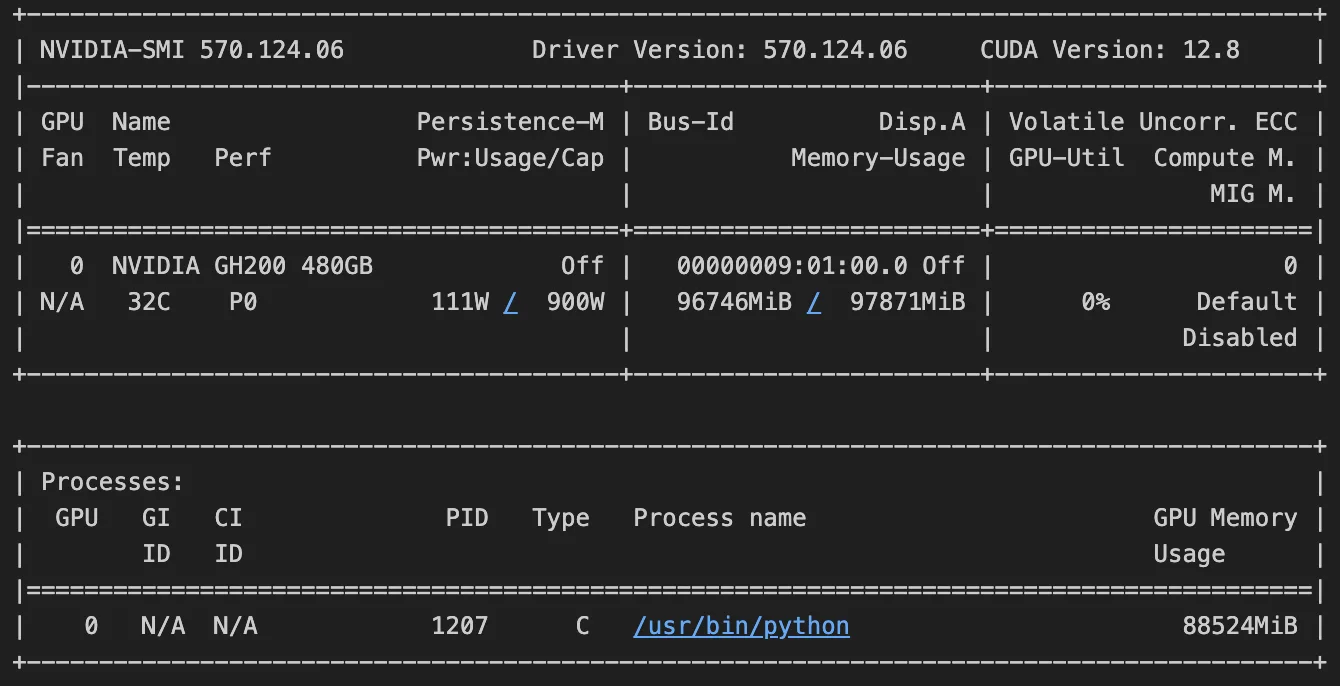
Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...

Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...
Advertisement Space (300x250)

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...

KV Cache Offload Accelerates LLM Inference - NADDOD Blog
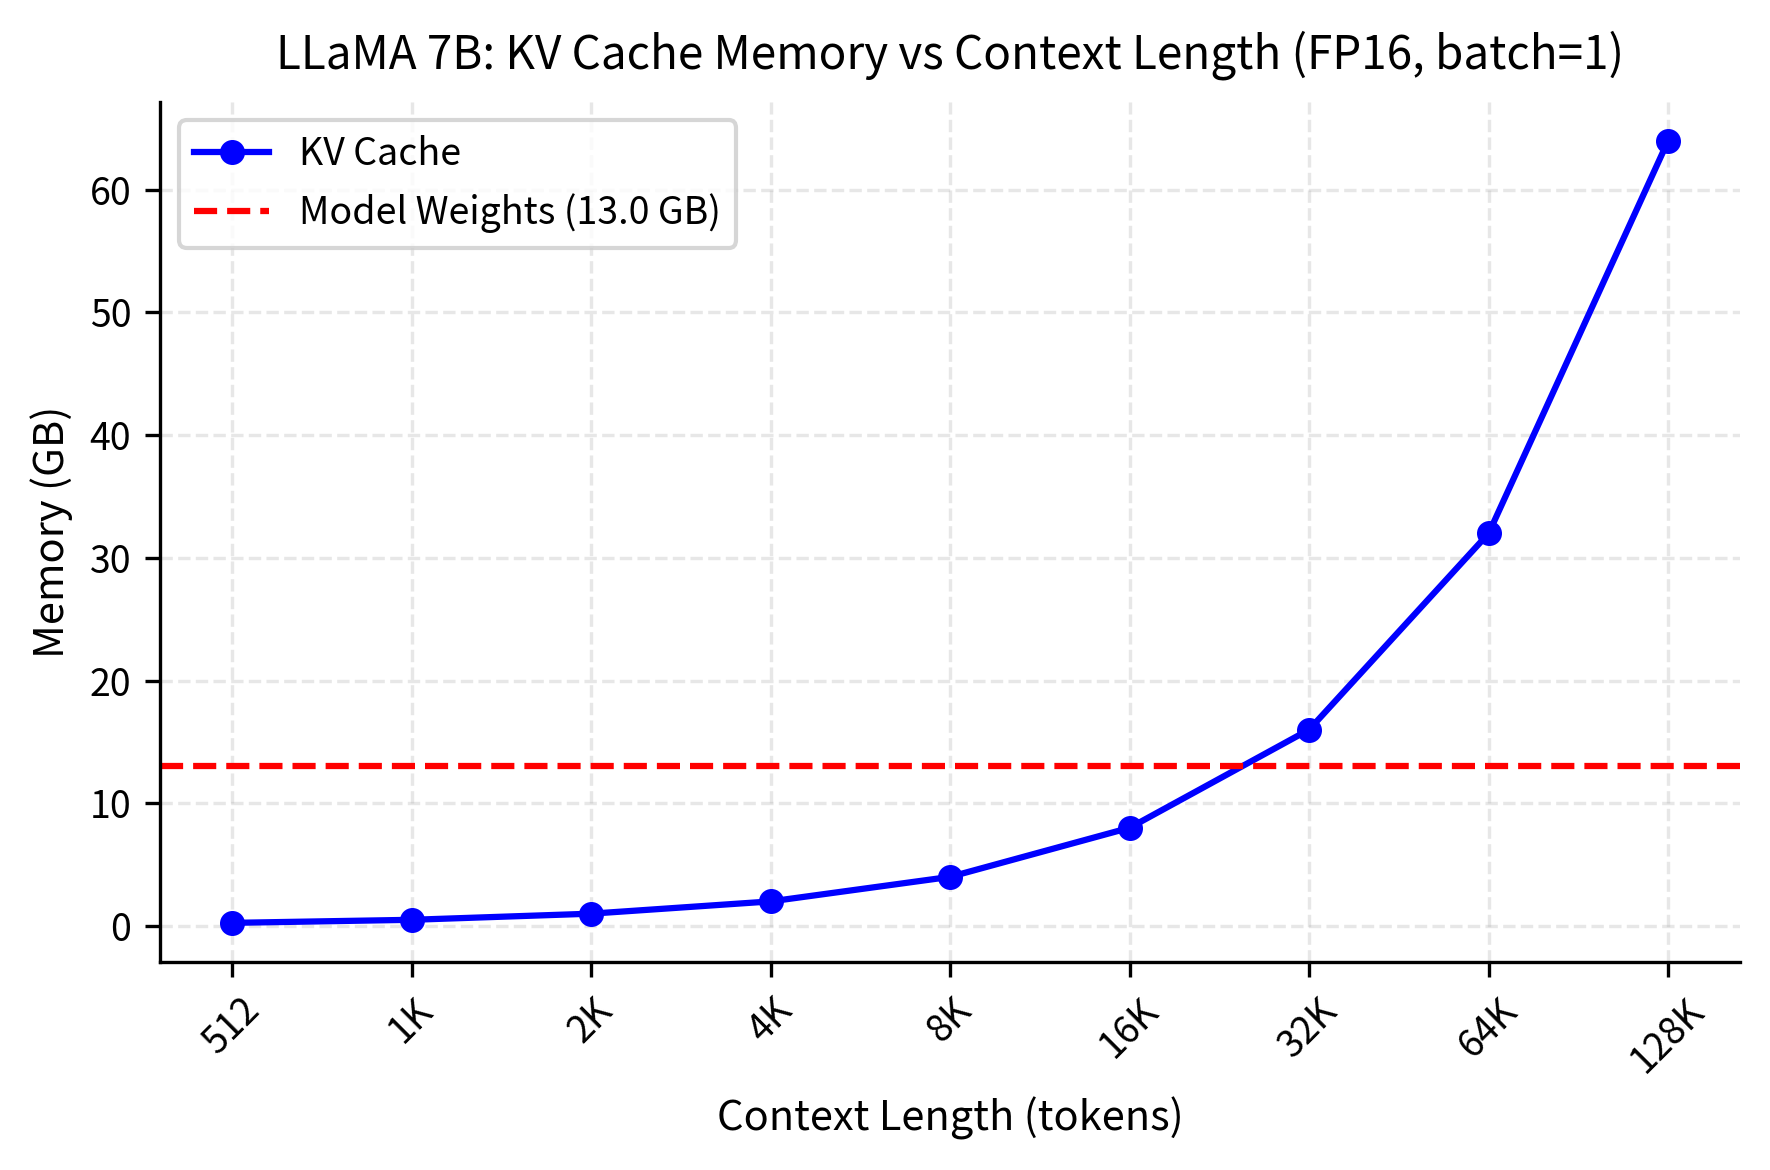
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

Enabling inference at massive scale with hybrid storage for KV cache ...
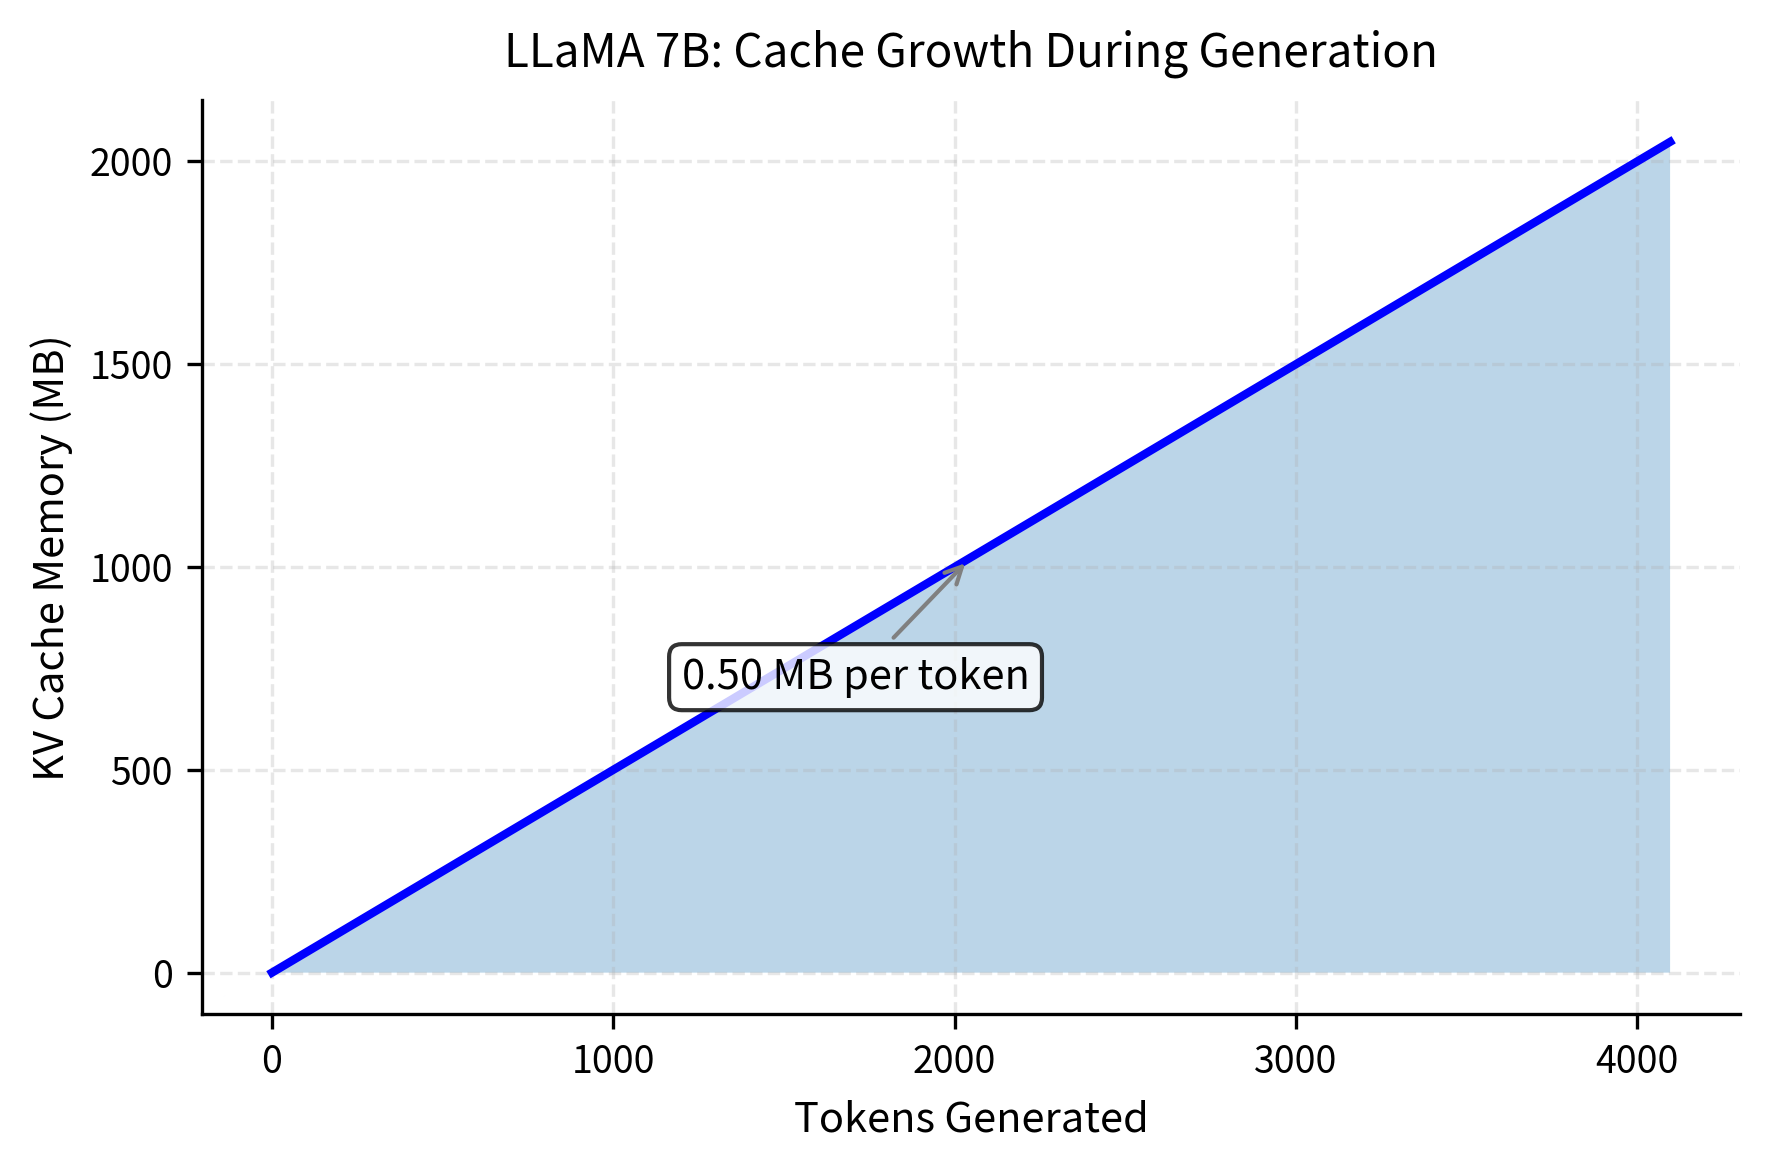
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
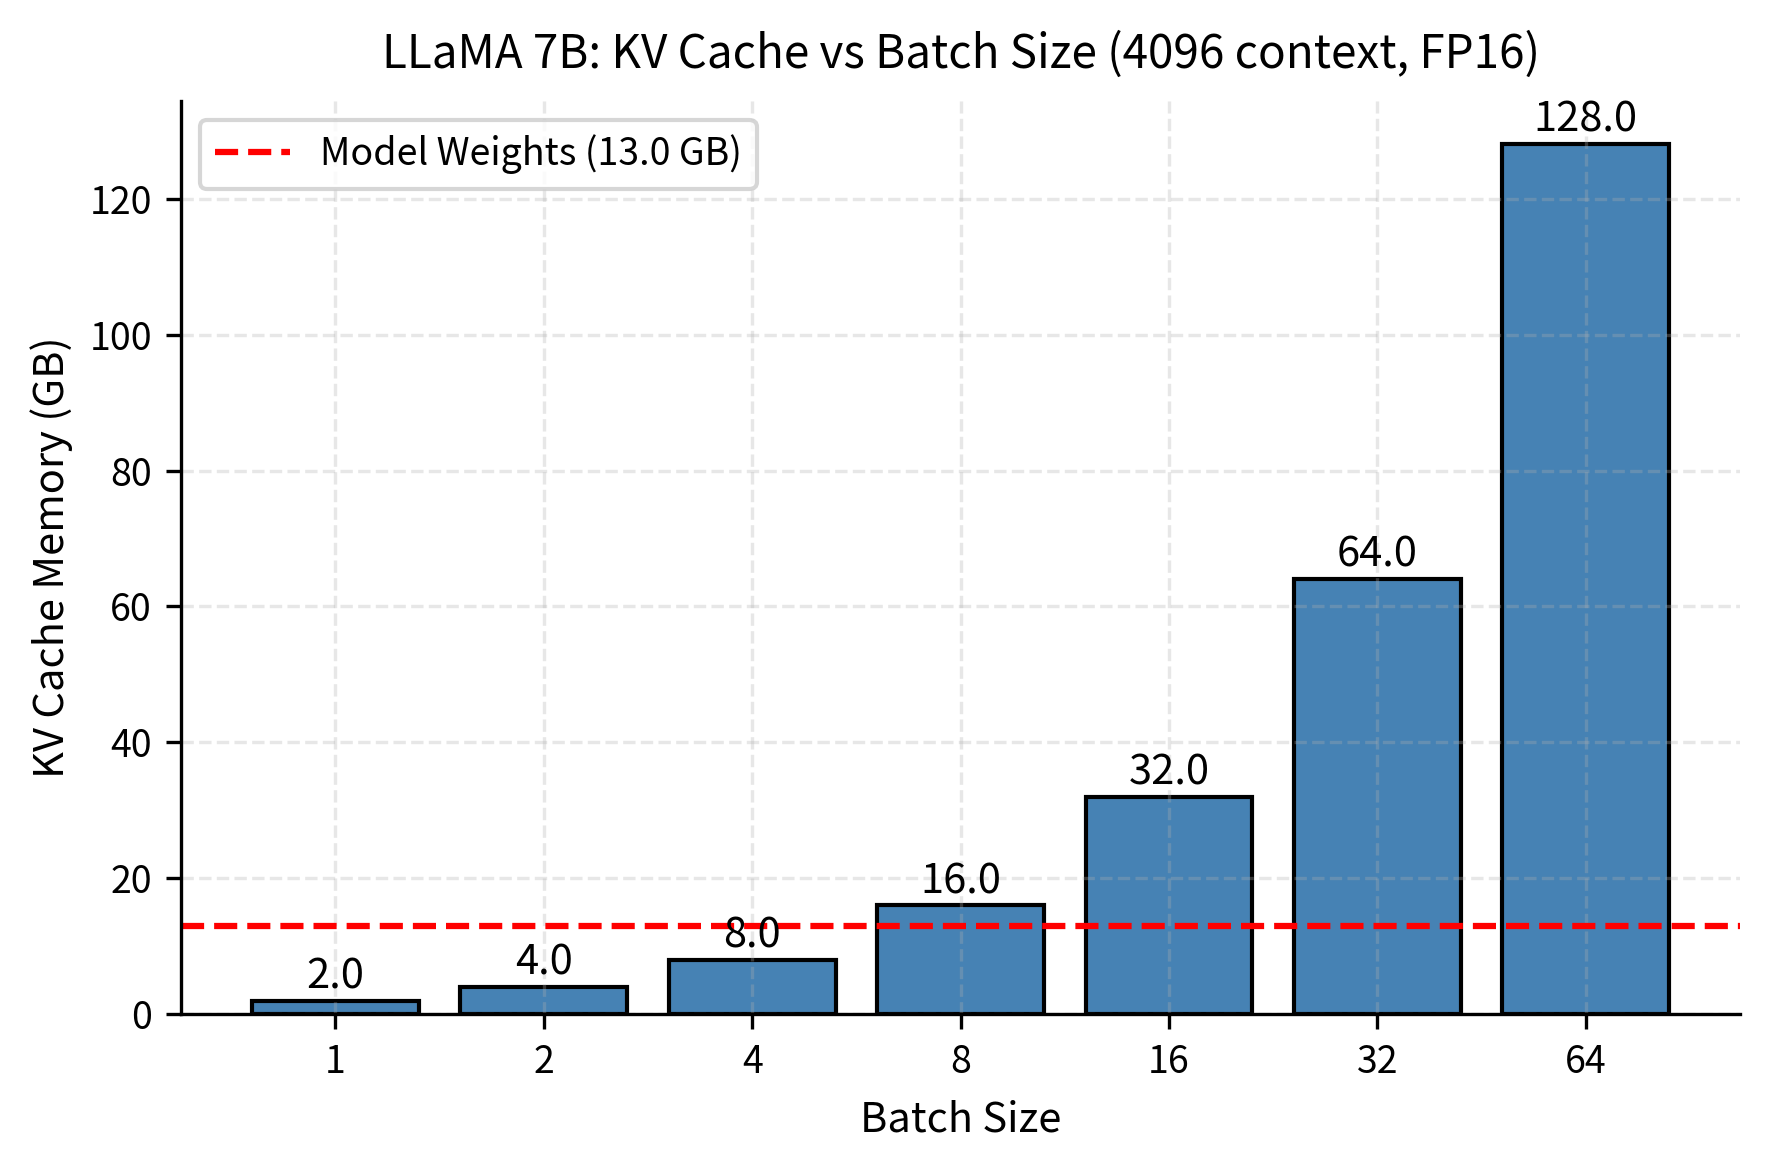
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference

Enabling inference at massive scale with hybrid storage for KV cache ...
Advertisement Space (336x280)

Turbocharging AI Inference with KV Cache Offload

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference

LLM Inference: Accelerating Long Context Generation with KV Cache ...
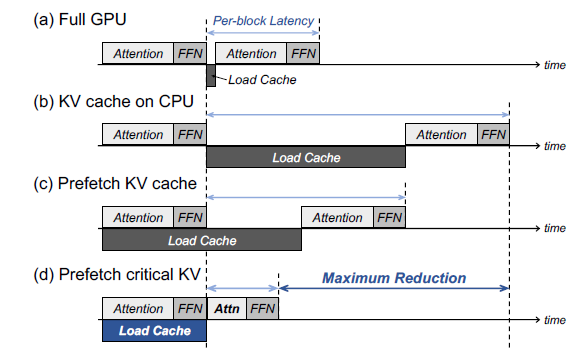
LLM Inference: Accelerating Long Context Generation with KV Cache ...
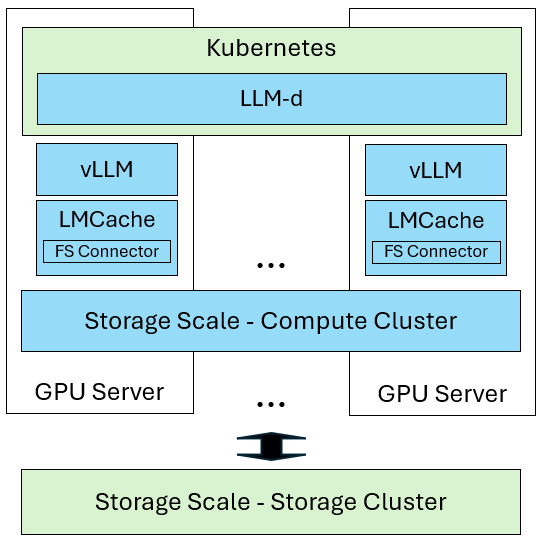
Deploying Distributed LLM Inference Service with IBM Storage Scale for ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
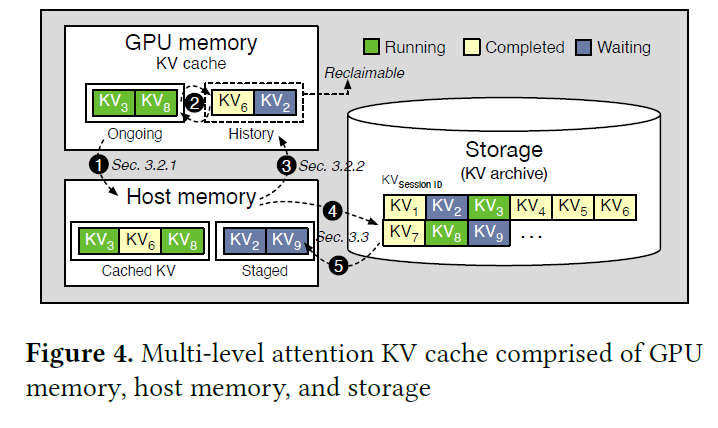
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...

Optimizing Inference for Long Context and Large Batch Sizes with NVFP4 ...
Advertisement Space (336x280)

LLM Inference: Accelerating Long Context Generation with KV Cache ...
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

Optimizing Inference for Long Context and Large Batch Sizes with NVFP4 ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

KV Cache Offloading in LLM Inference | PDF | Cache (Computing ...

What Happens Inside an LLM During Inference: Tokens, KV Cache, and GPU ...