
Accelerate Llm Inference With Speculative Decoding Charles Xu
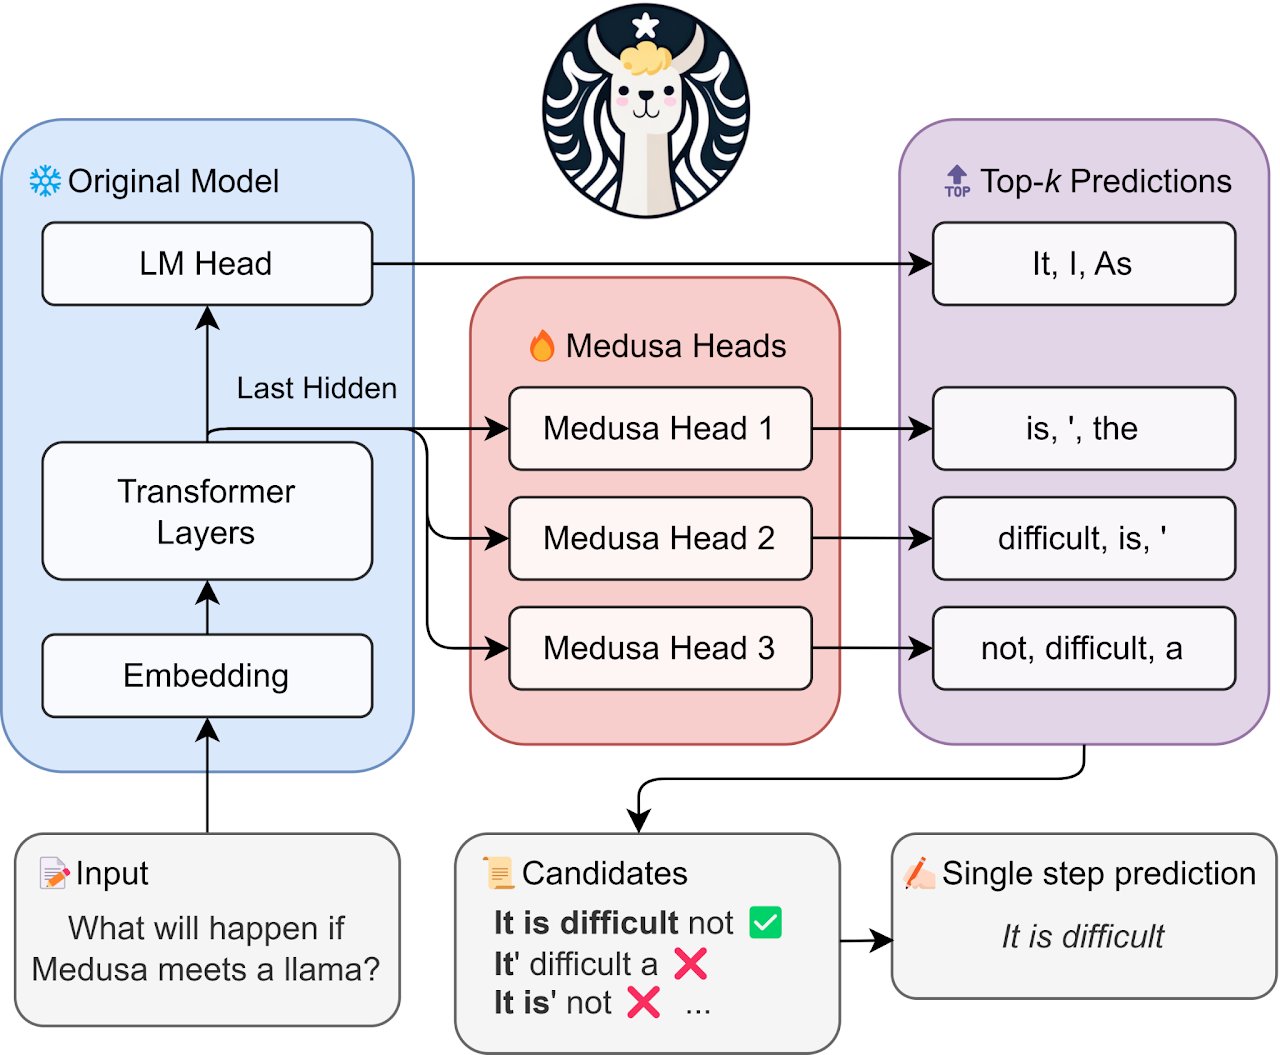
Accelerate LLM Inference with Speculative Decoding | Charles Xu
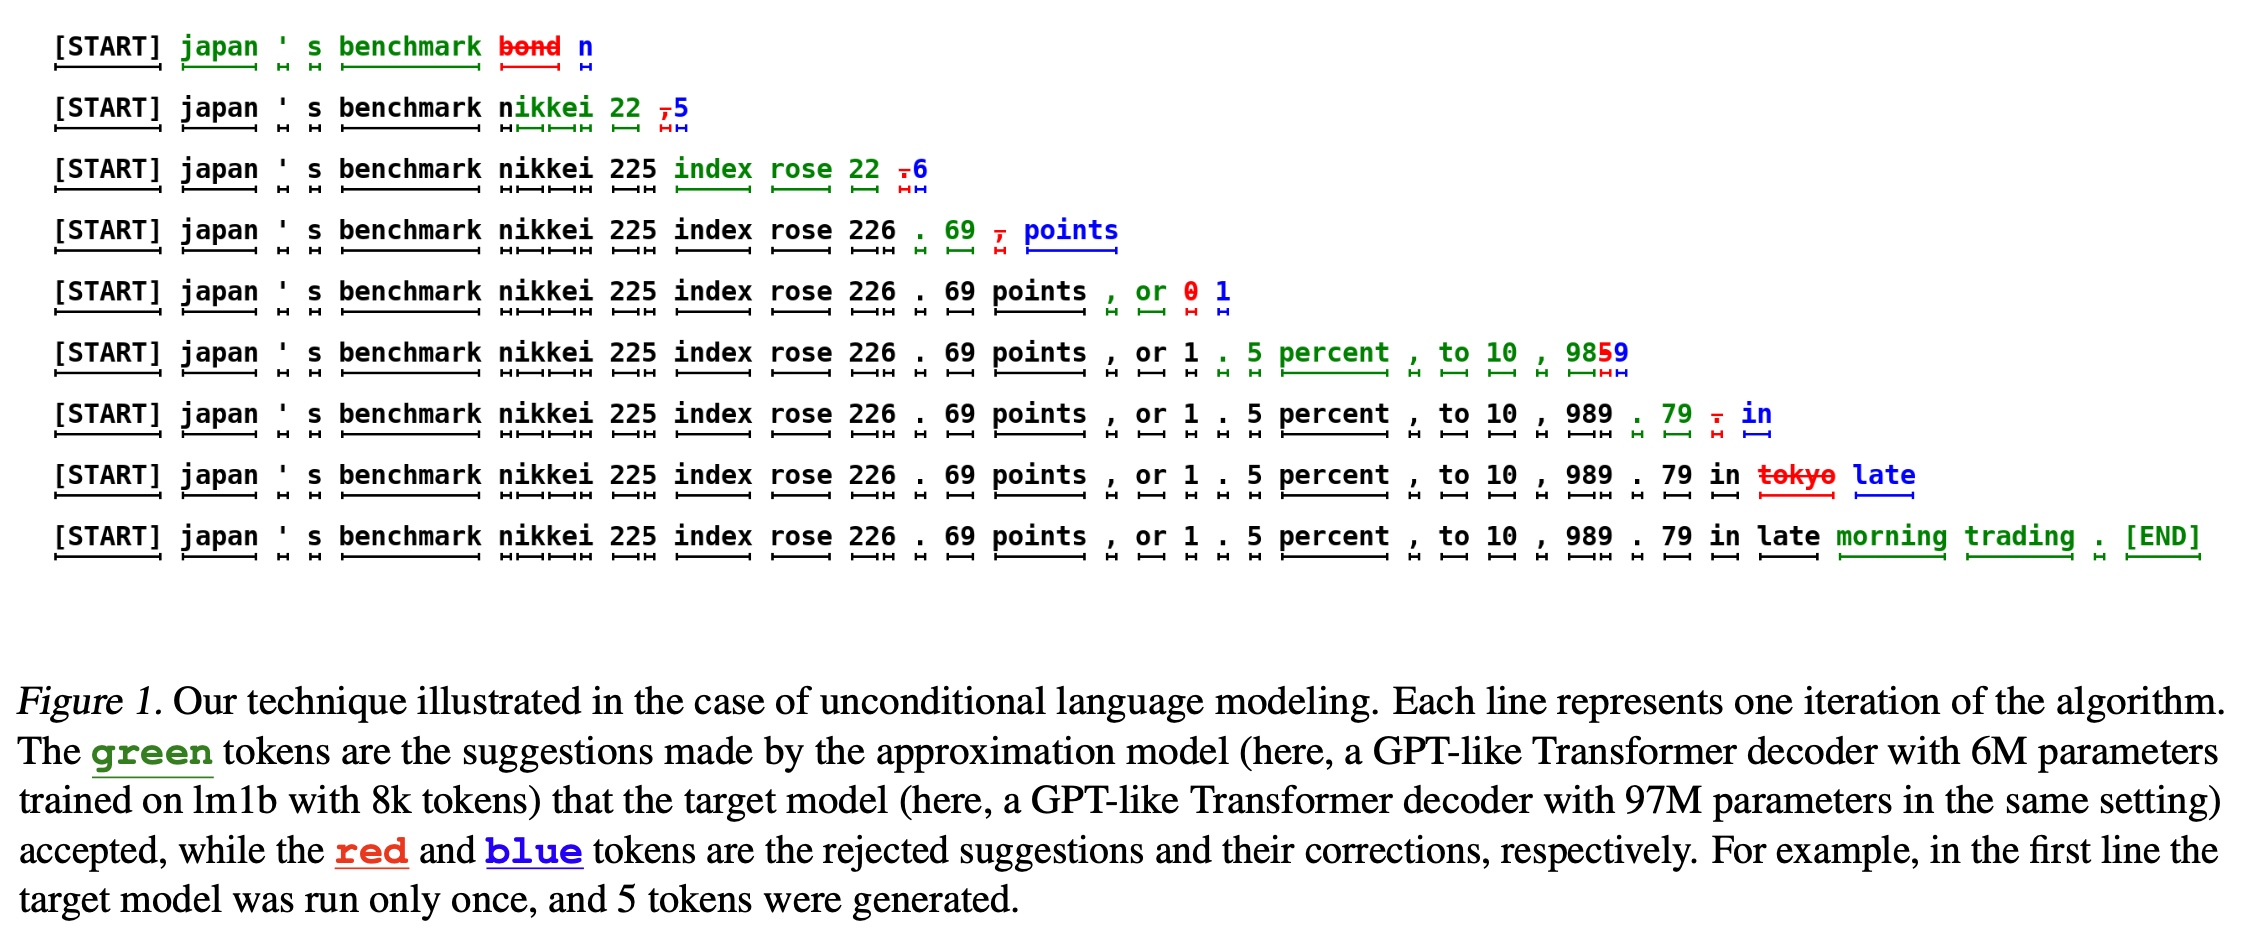
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Speculative Decoding with CTC-based Draft Model for LLM Inference ...
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube

Paper page - Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Staged Speculative Decoding

(PDF) Accelerating LLM Inference with Lossless Speculative Decoding ...
Accelerating LLM Inference with Staged Speculative Decoding - Paper Details
Accelerating LLM Inference with Speculative Decoding - LinkedIn ...
Advertisement Space (300x250)
What is Speculative Decoding and How Does it Accelerate LLM Inference ...
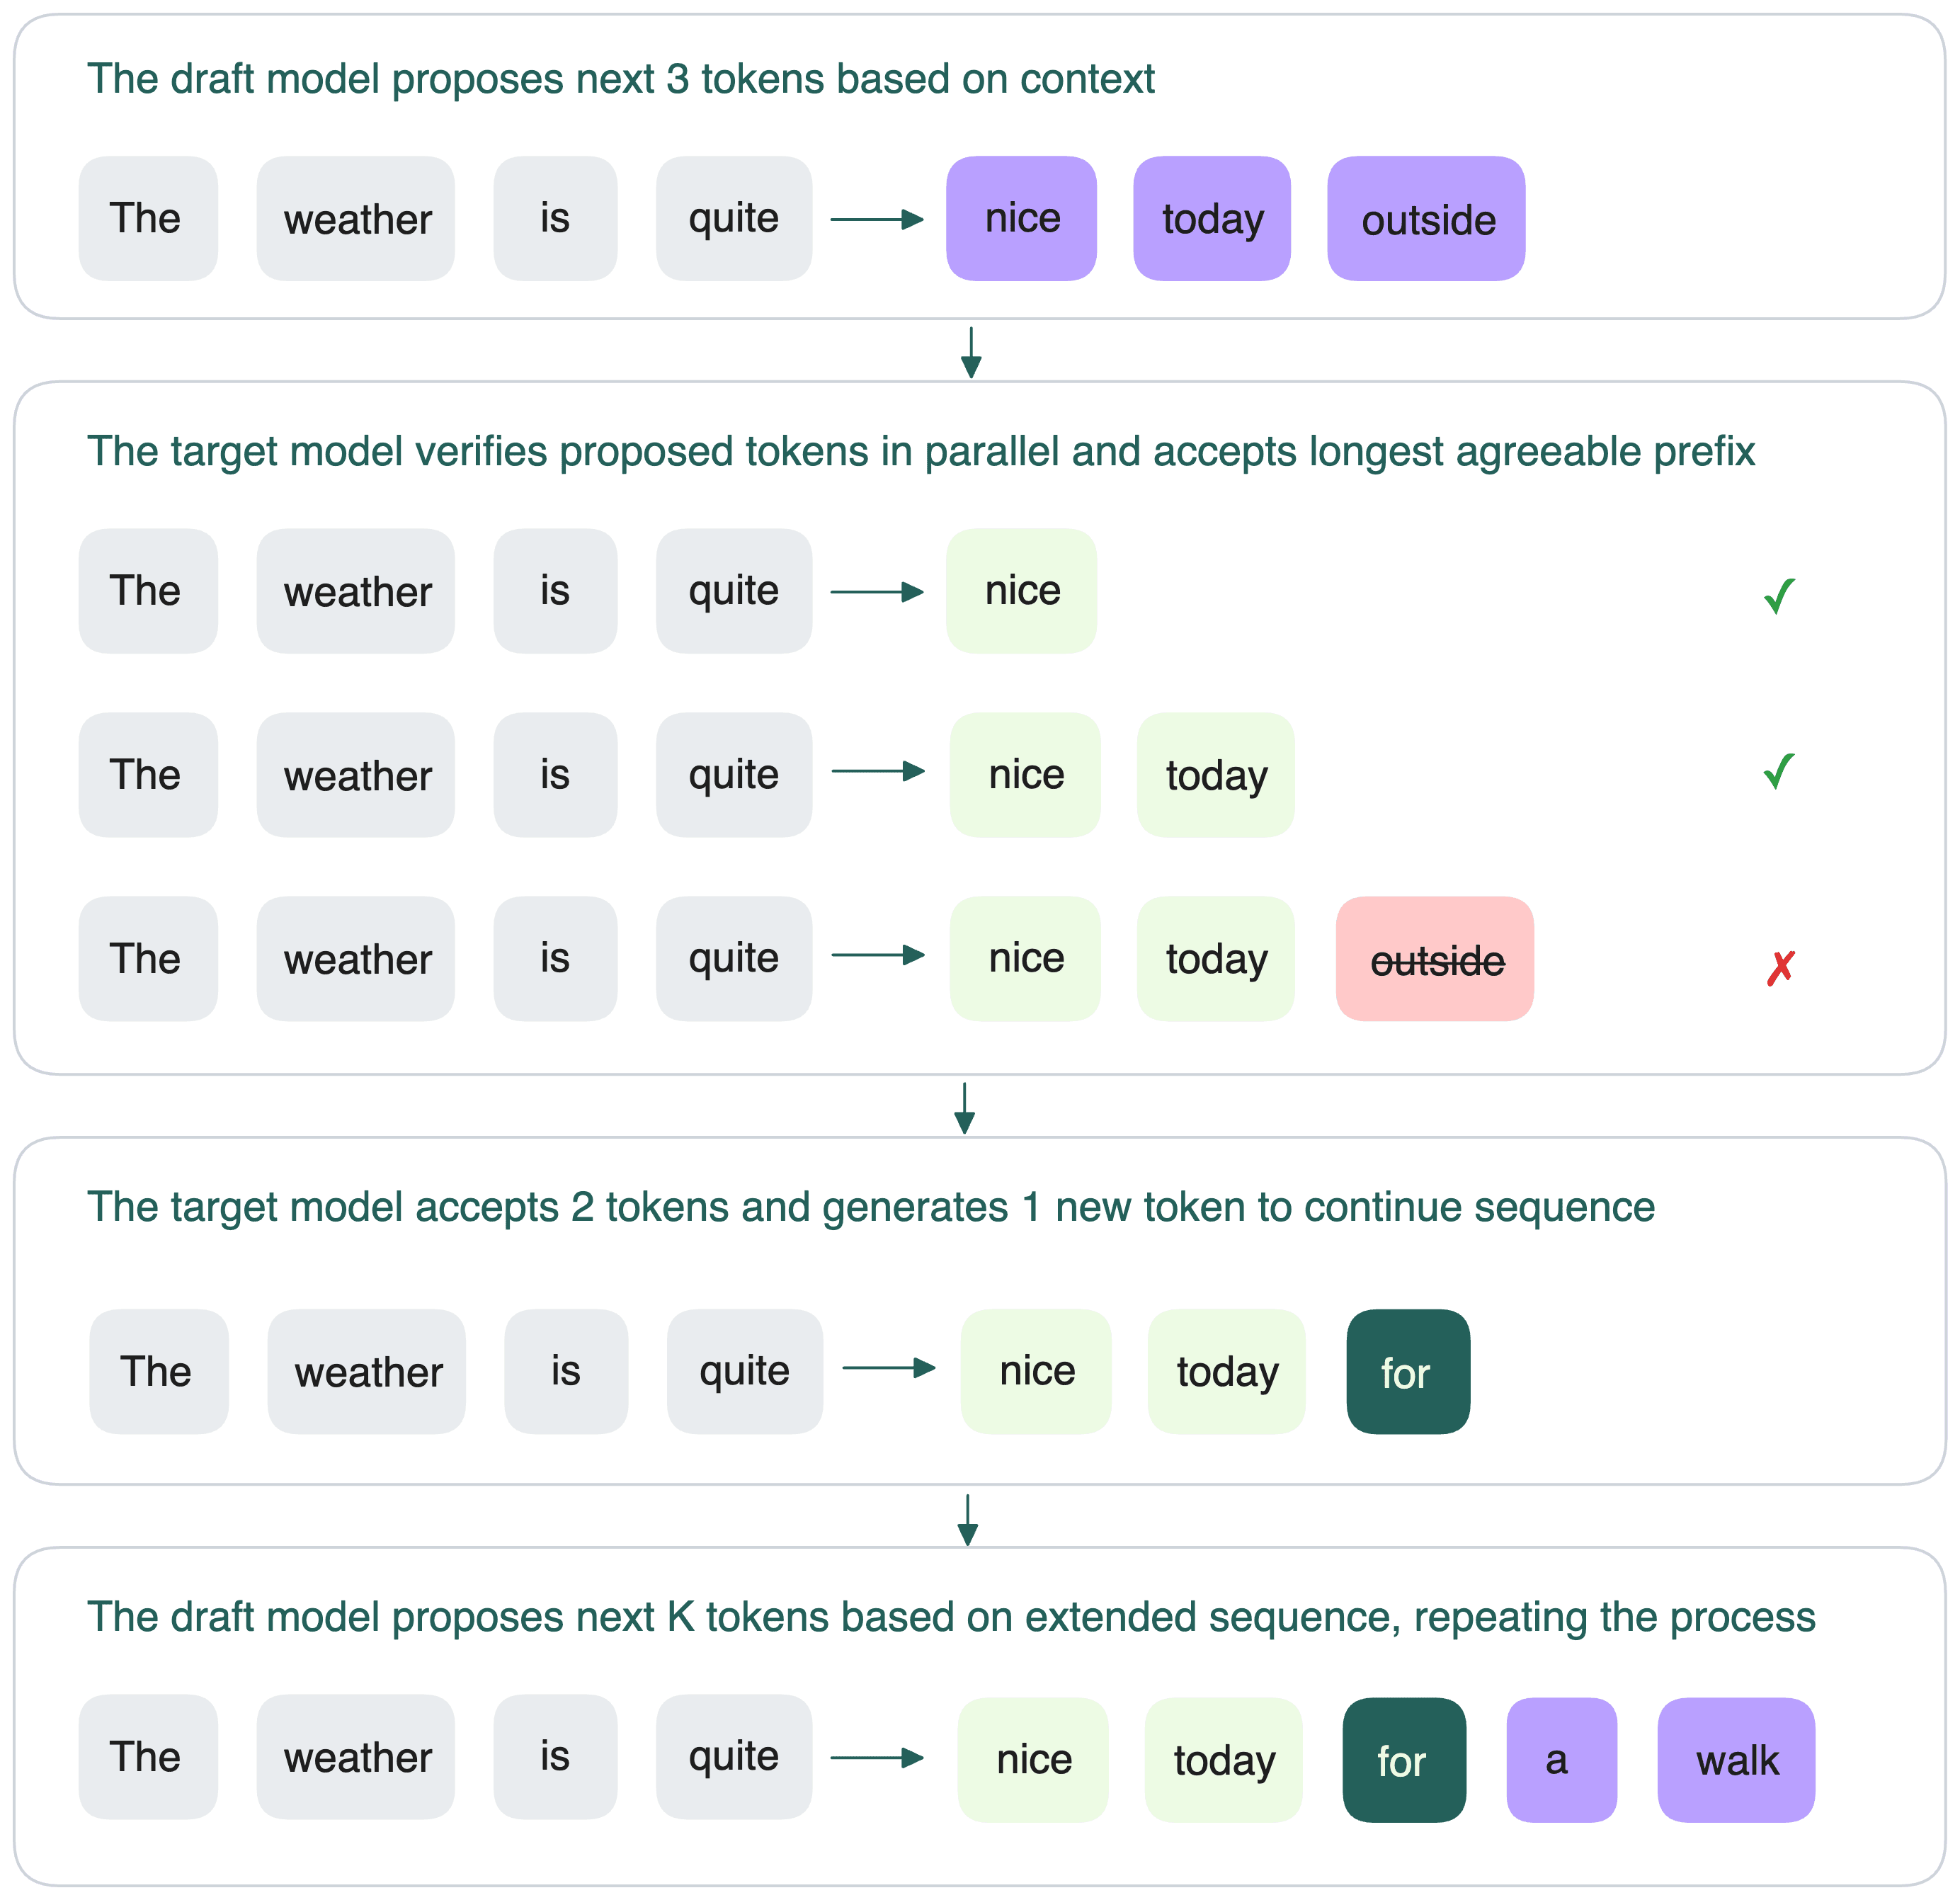
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Accelerating LLM Inference with Speculative Decoding using LMStudio ...
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...
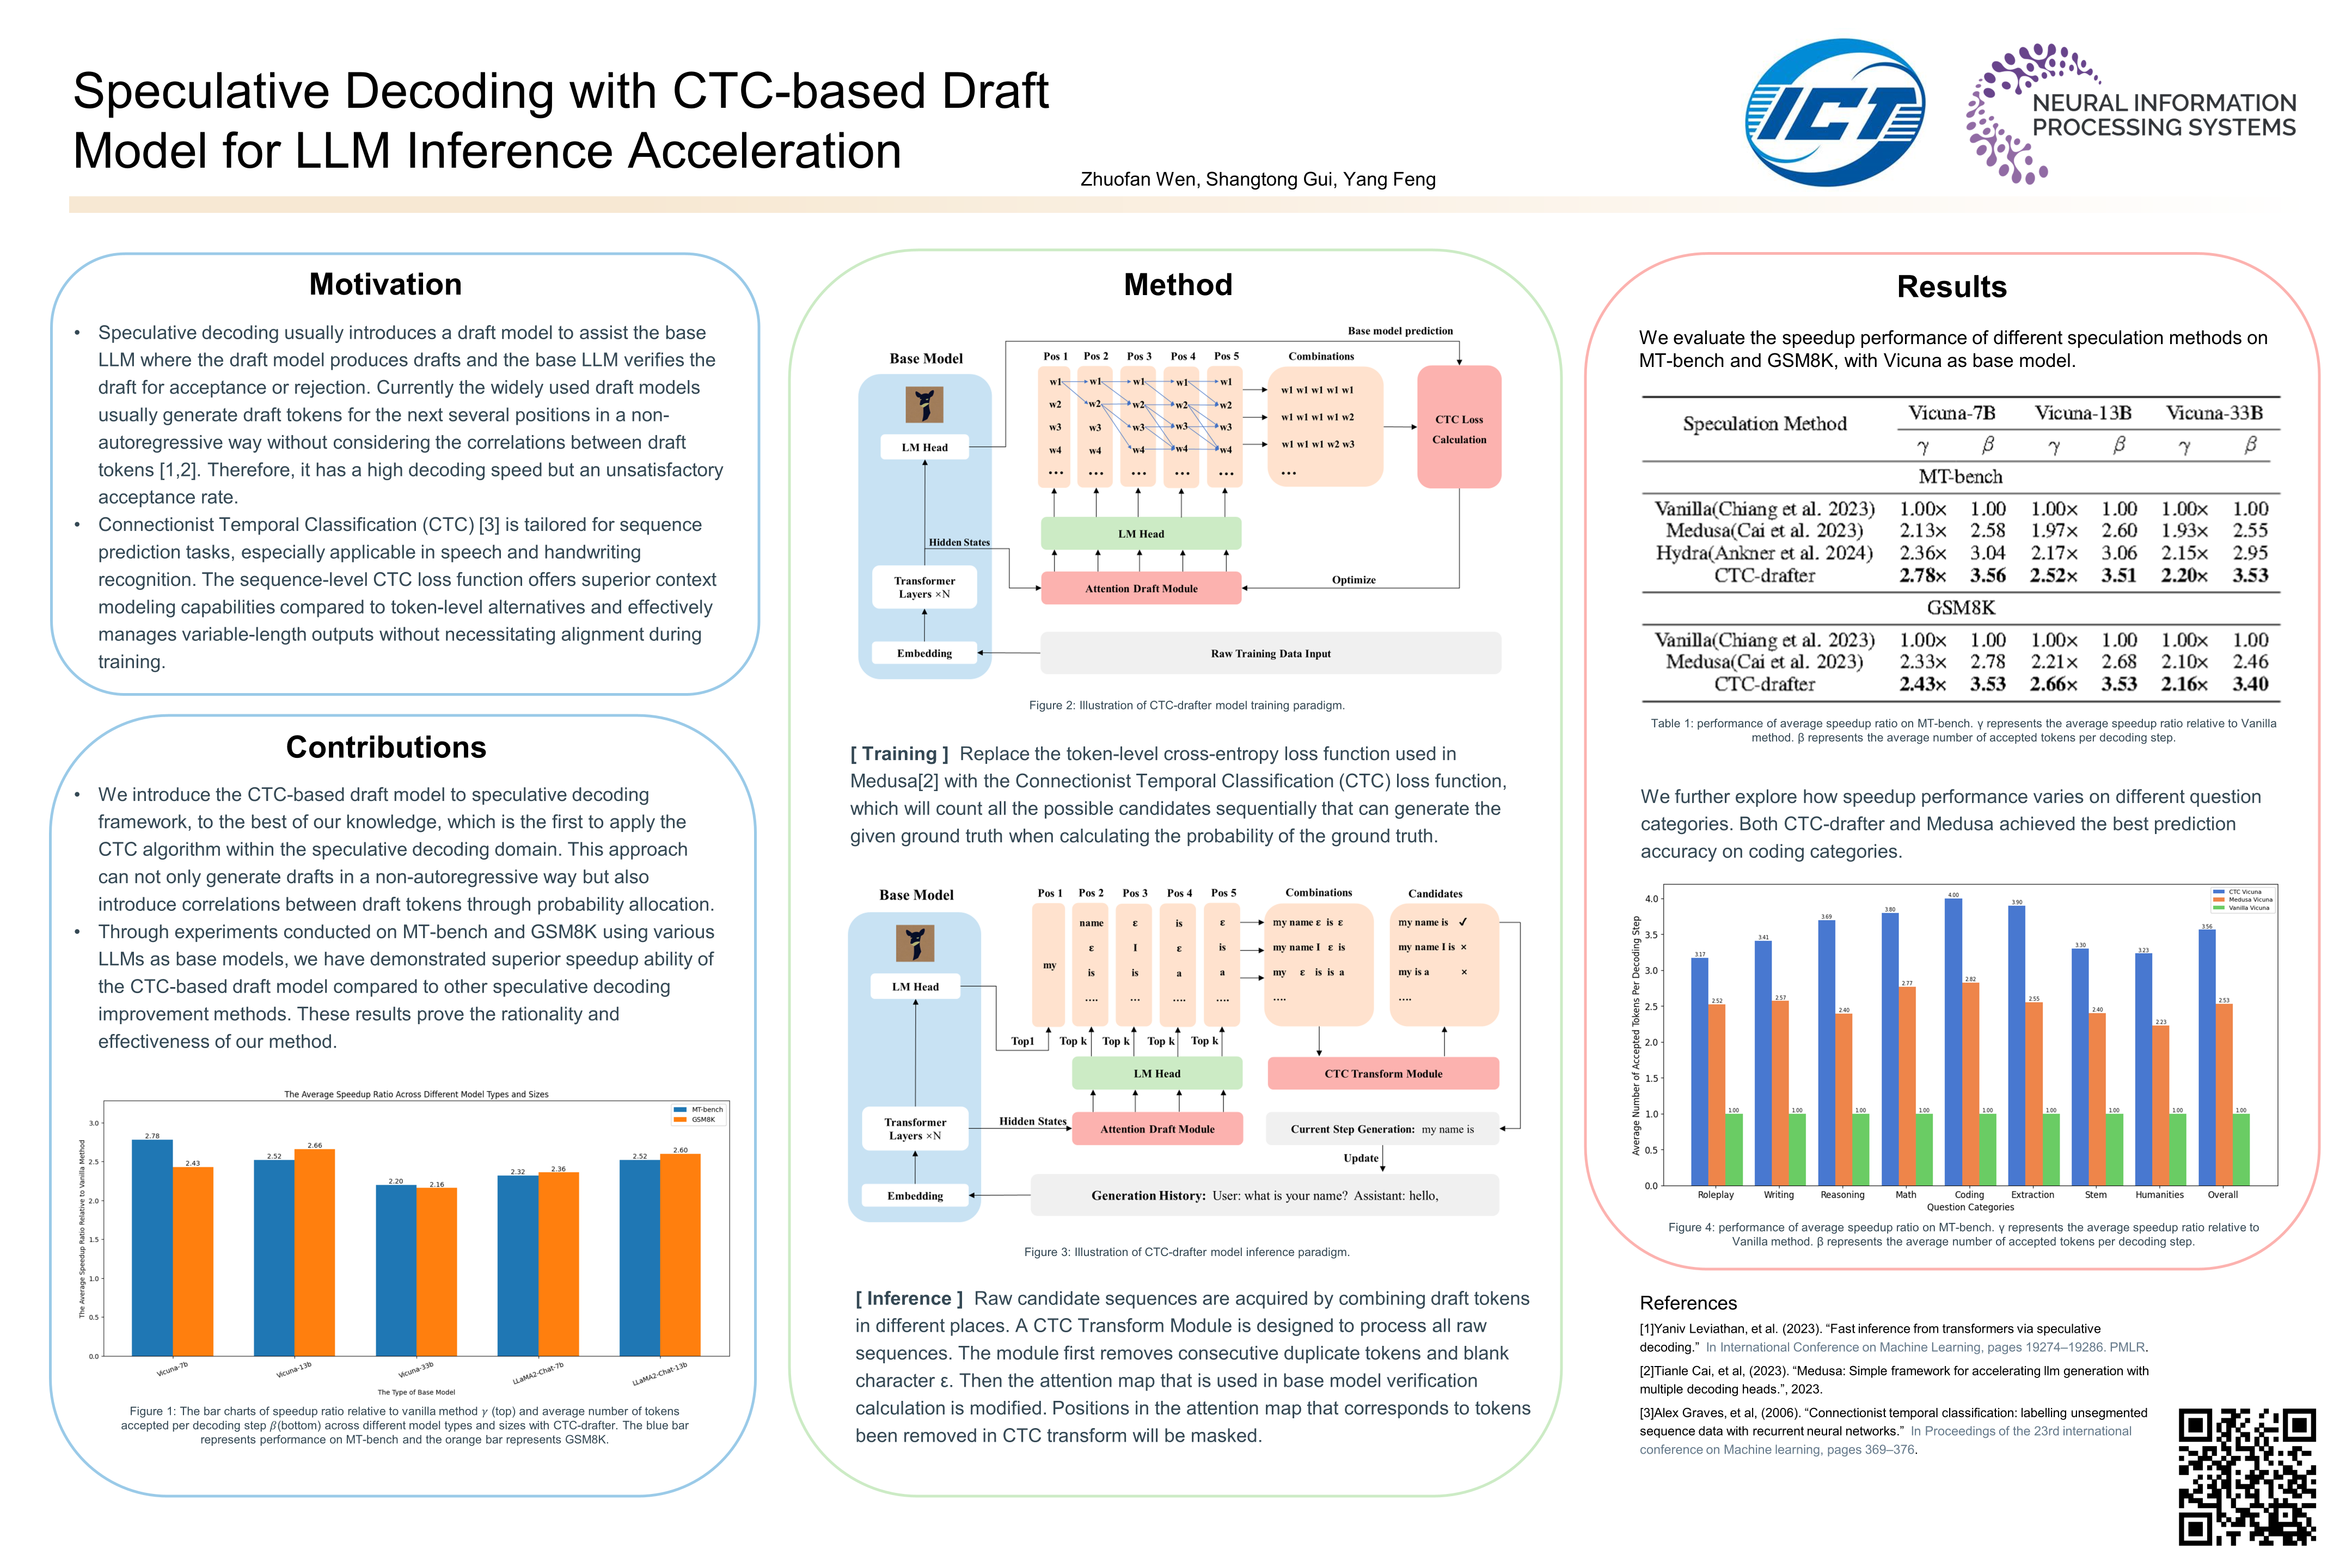
NeurIPS Poster Speculative Decoding with CTC-based Draft Model for LLM ...
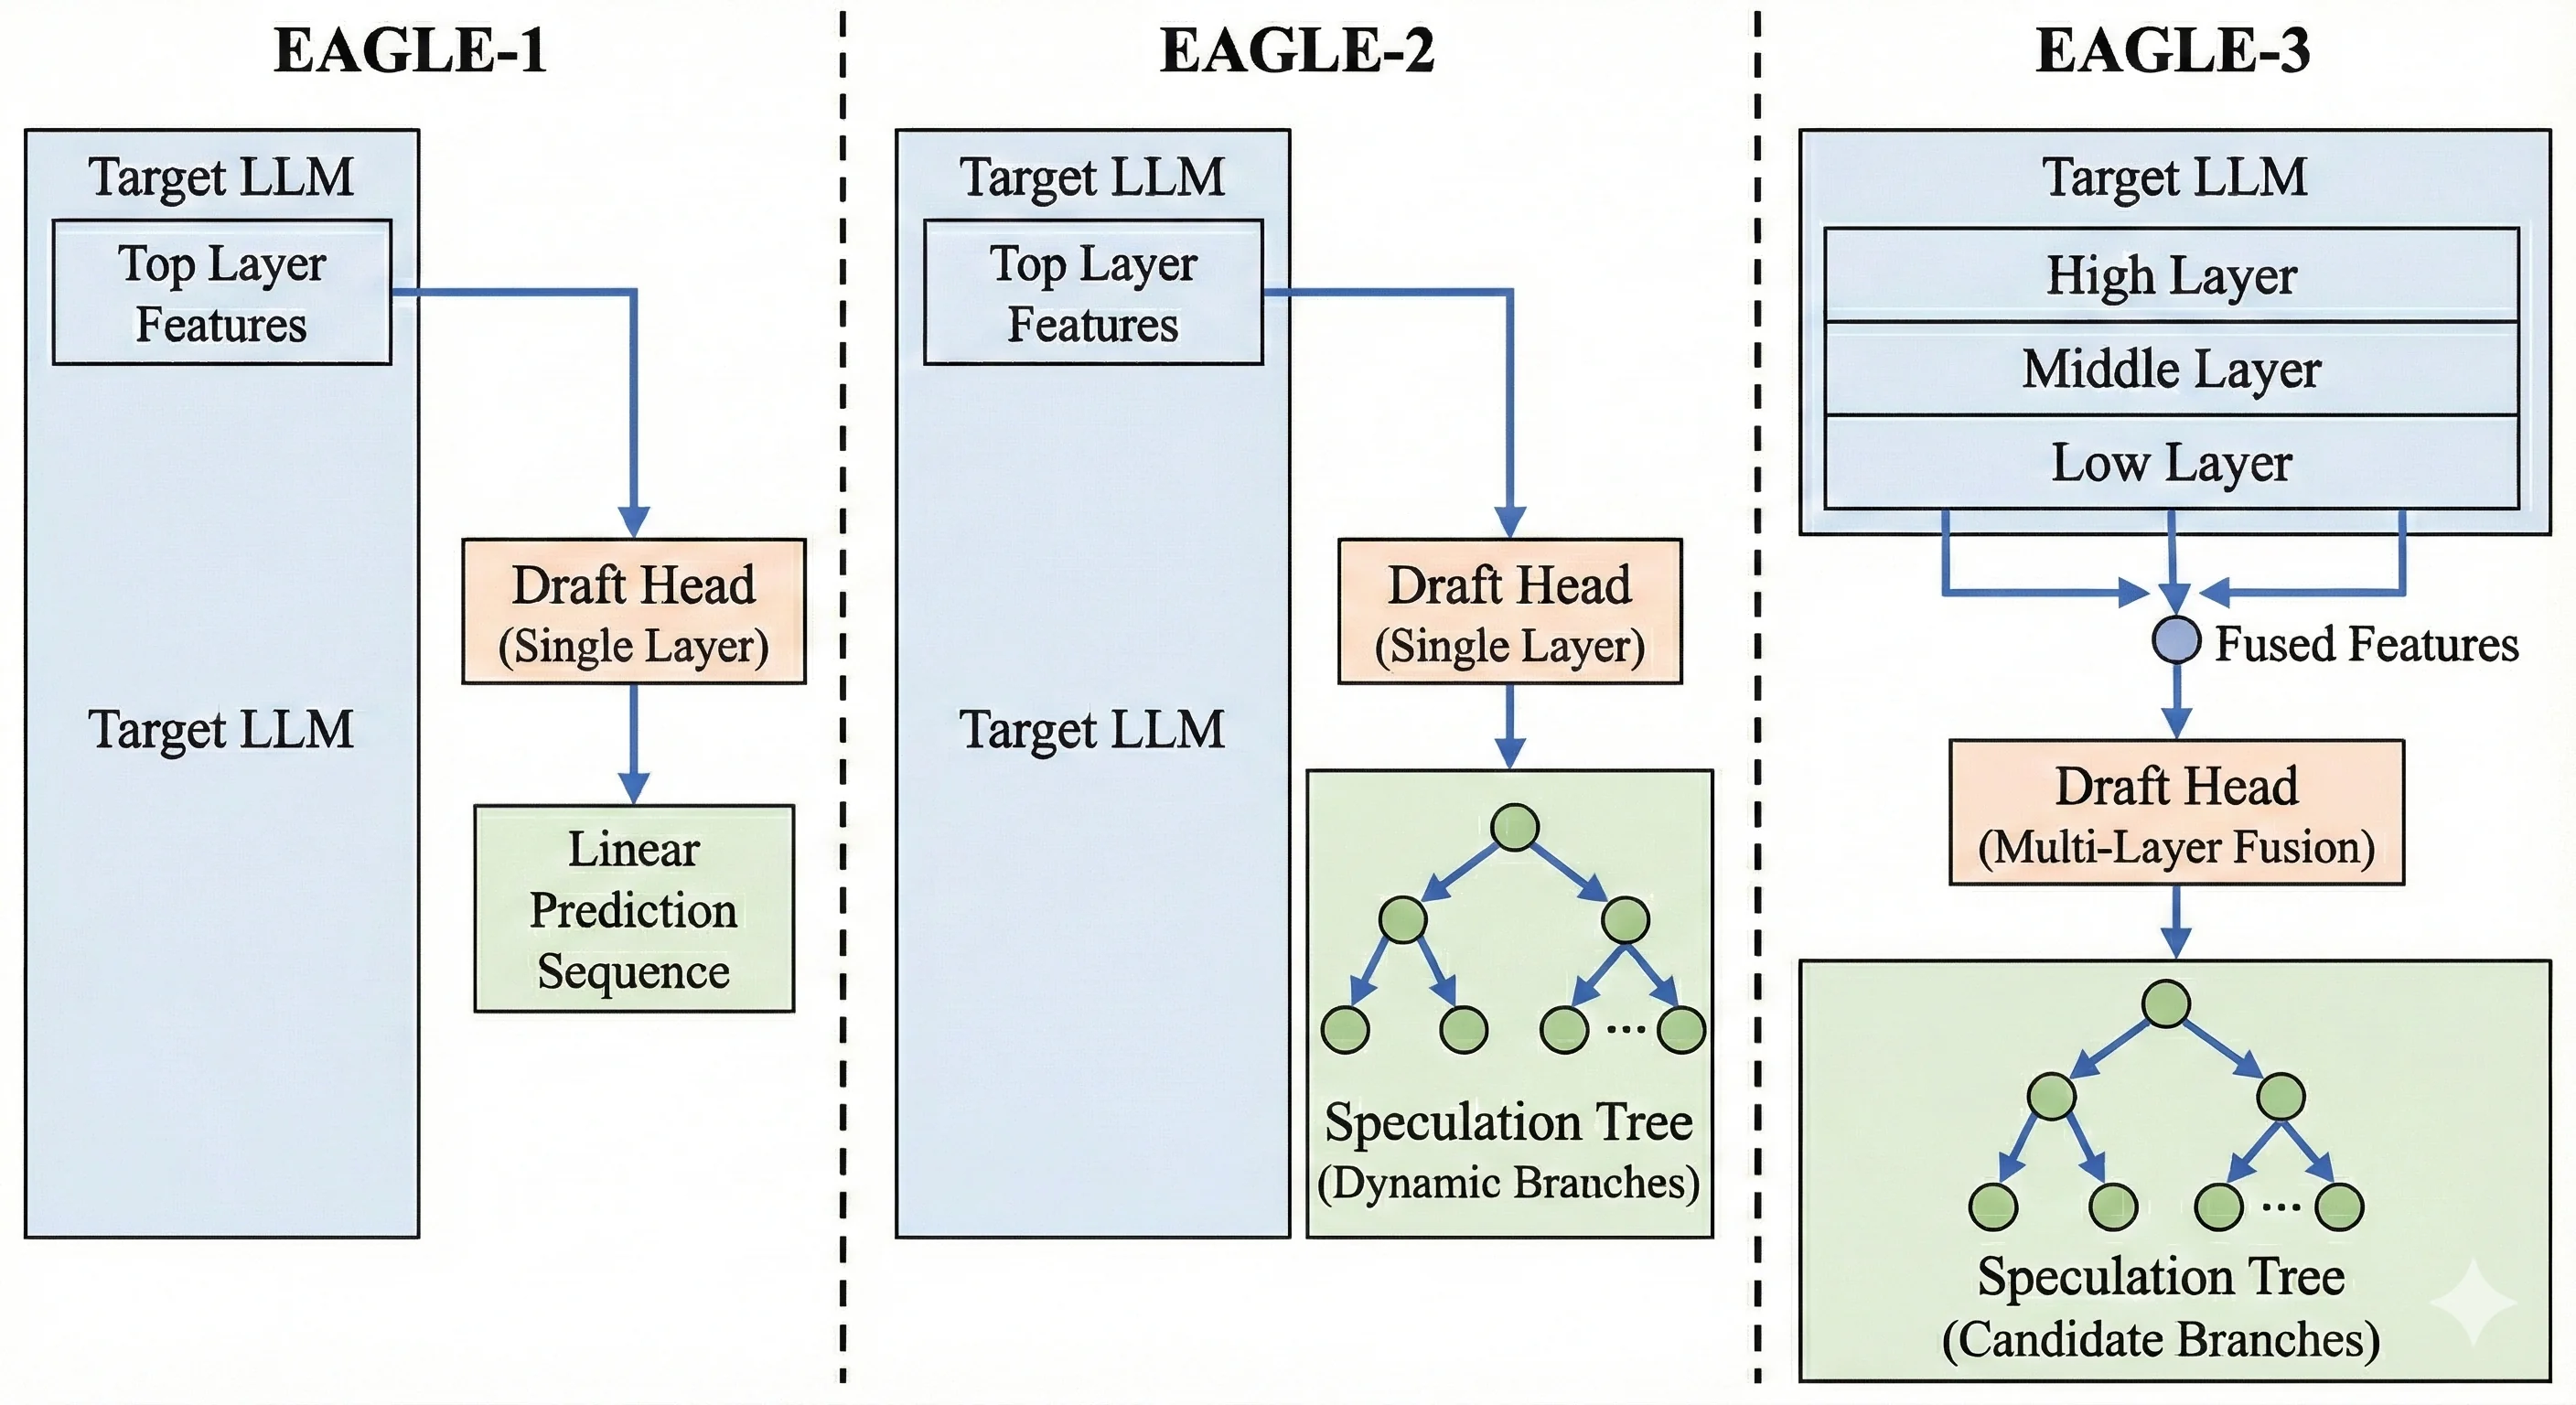
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
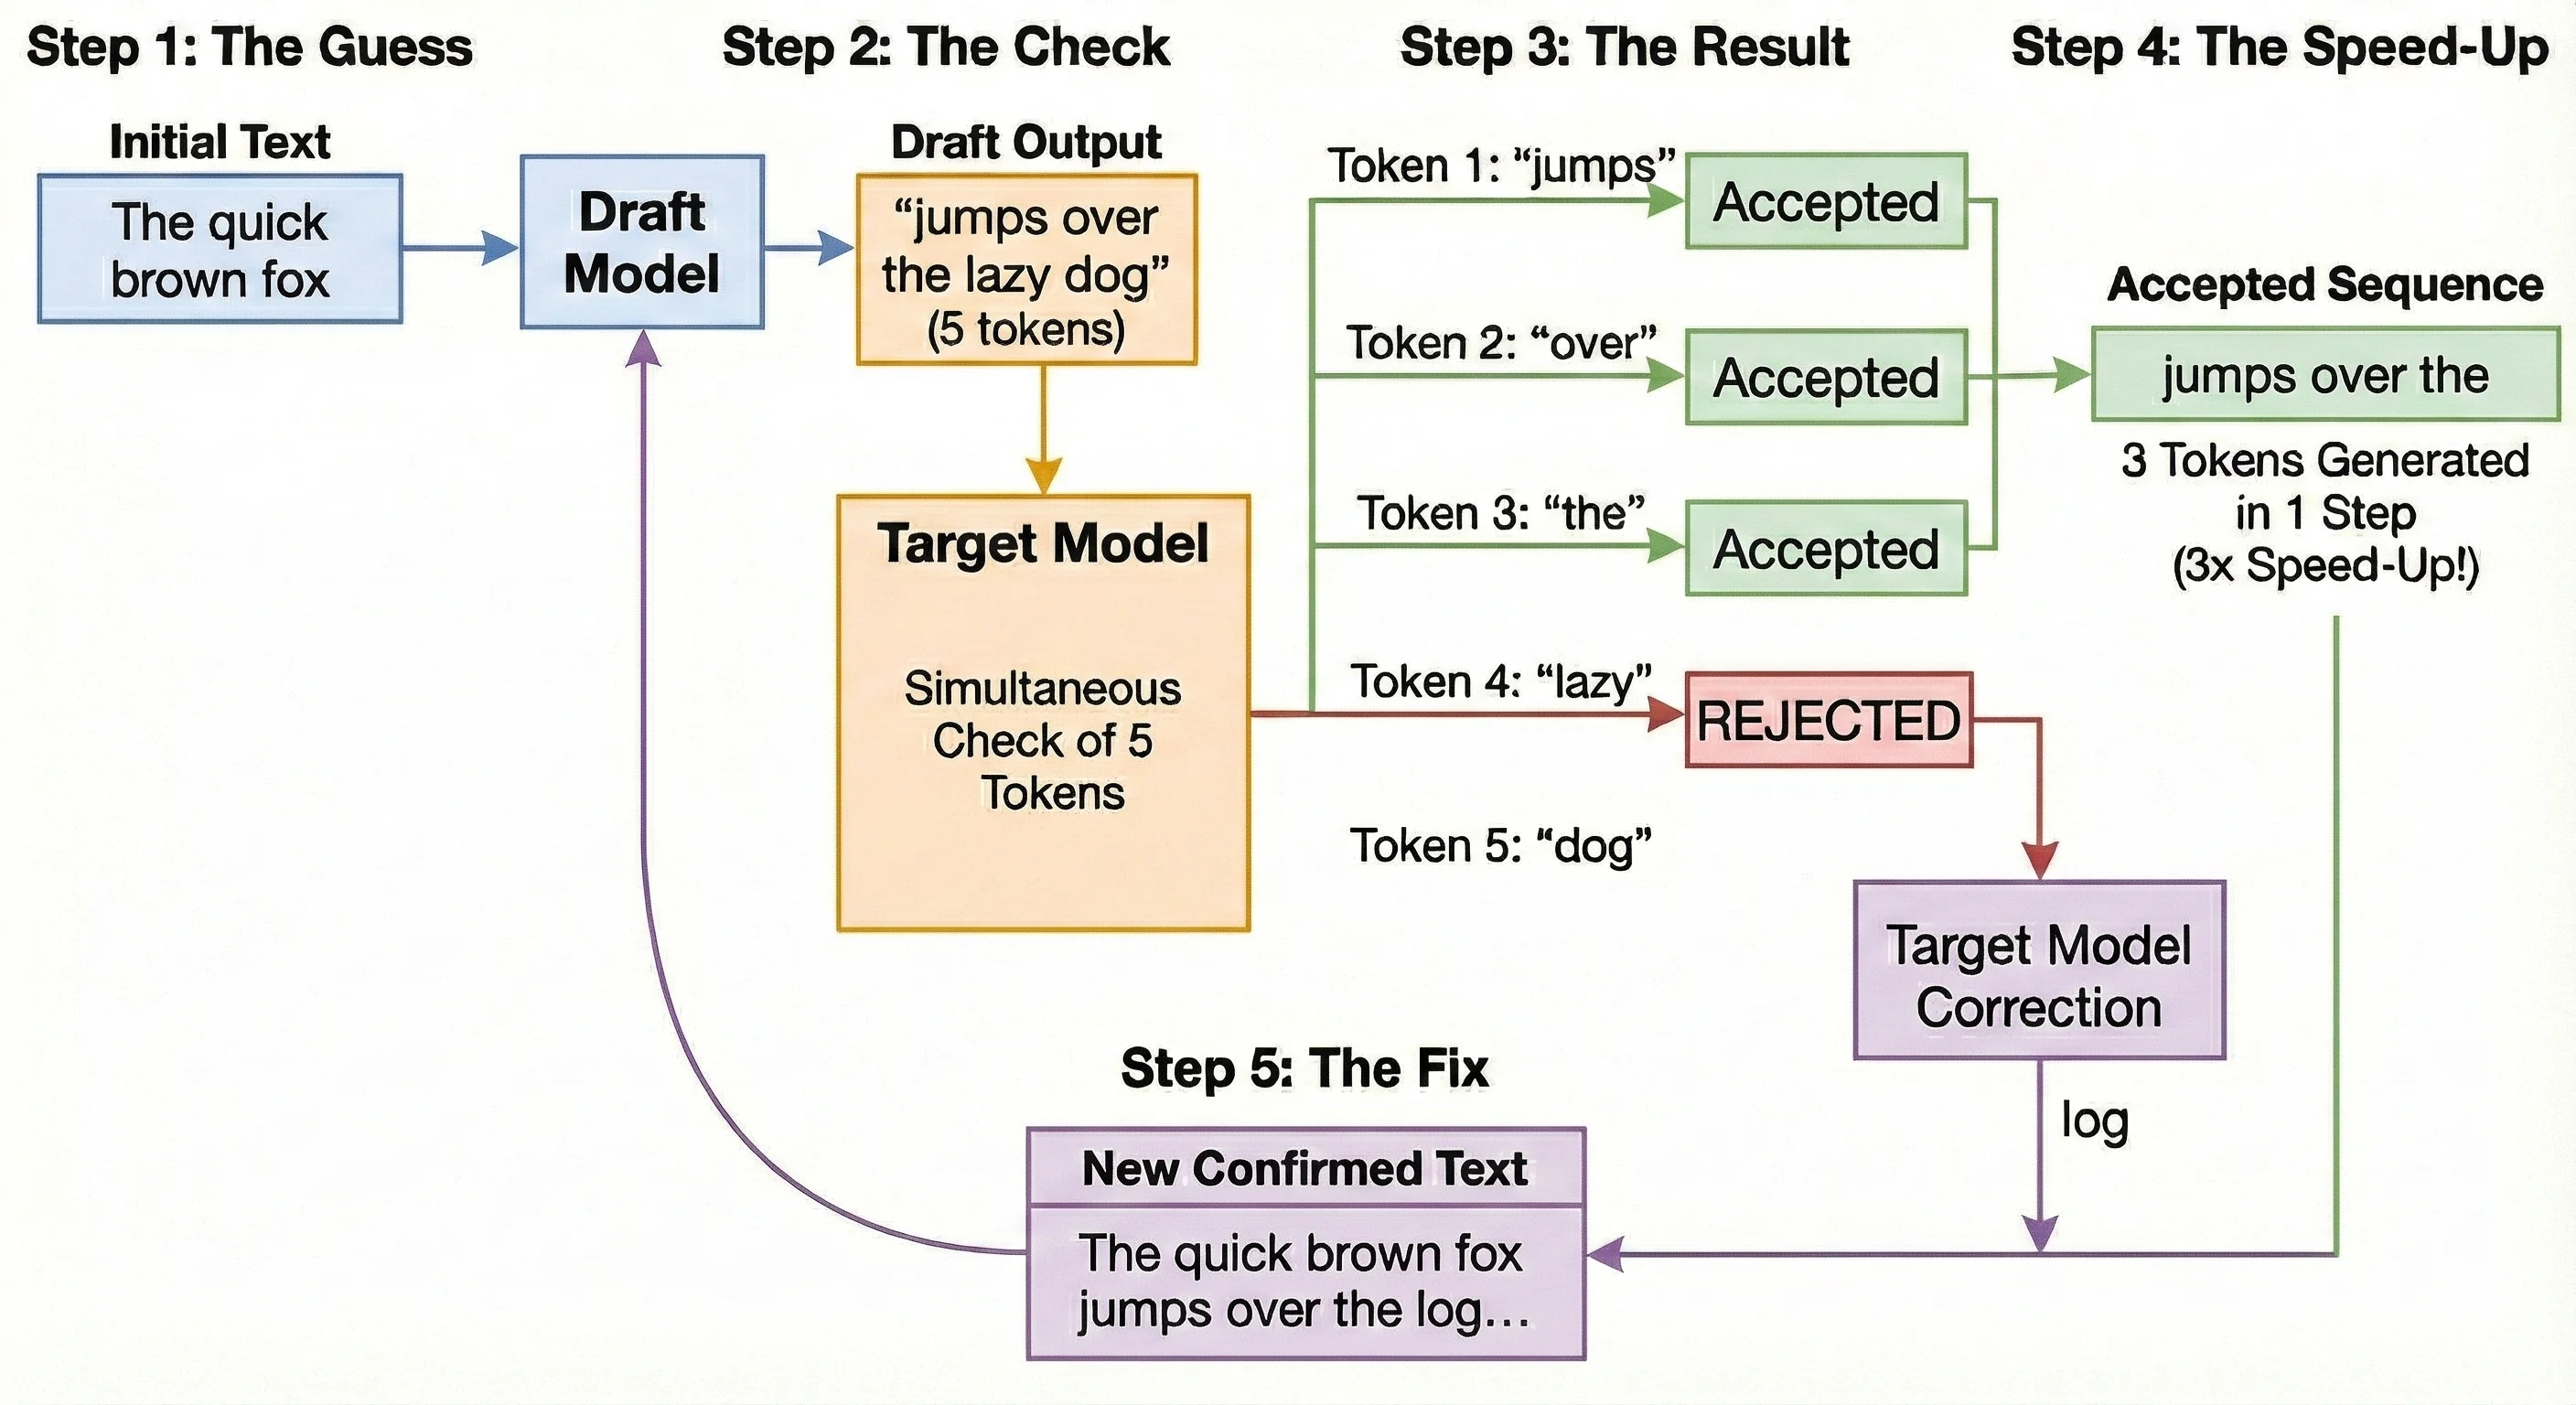
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
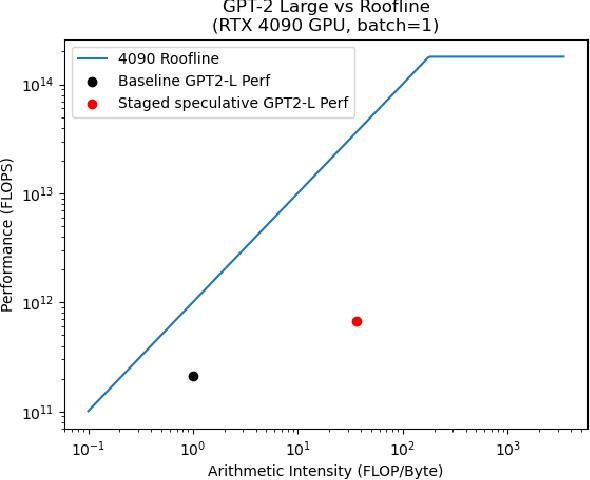
Figure 1 from Accelerating LLM Inference with Staged Speculative ...

Accelerating LLM Inference with Staged Speculative Decoding: Paper and ...
Advertisement Space (336x280)

[논문 리뷰] SDSAT: Accelerating LLM Inference through Speculative Decoding ...

Speeding Up LLM Output with Speculative Decoding — Arabian Post
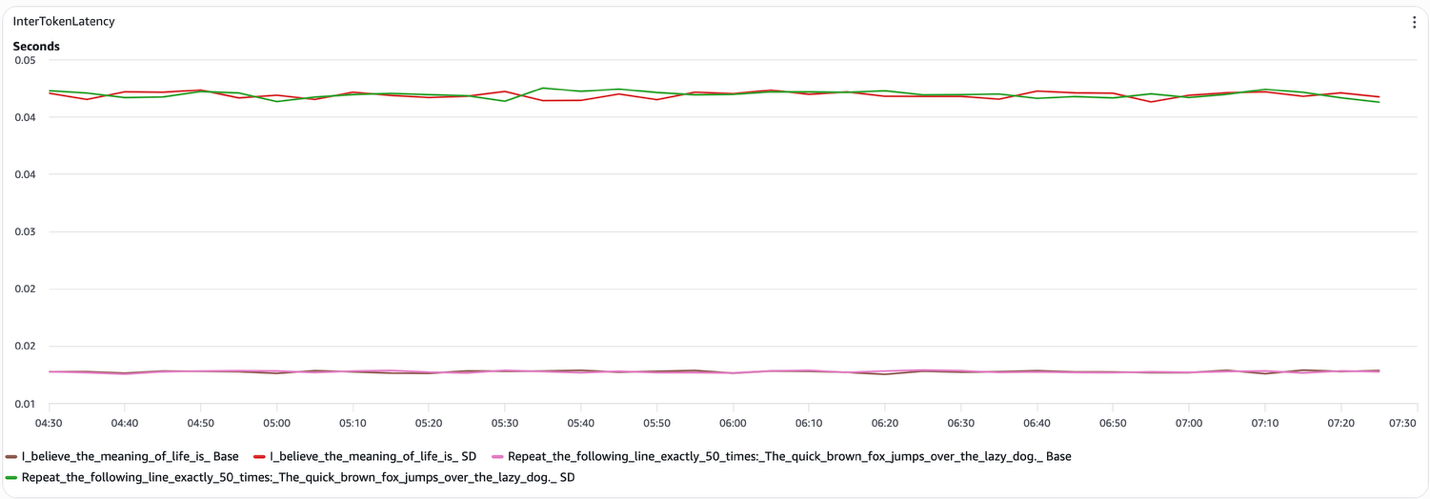
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec
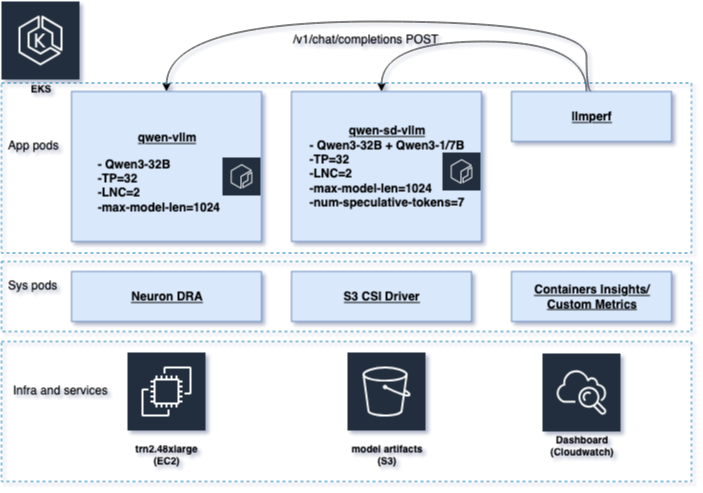
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec

Audio Overview: Accelerating LLM Inference with Lossless Speculative ...
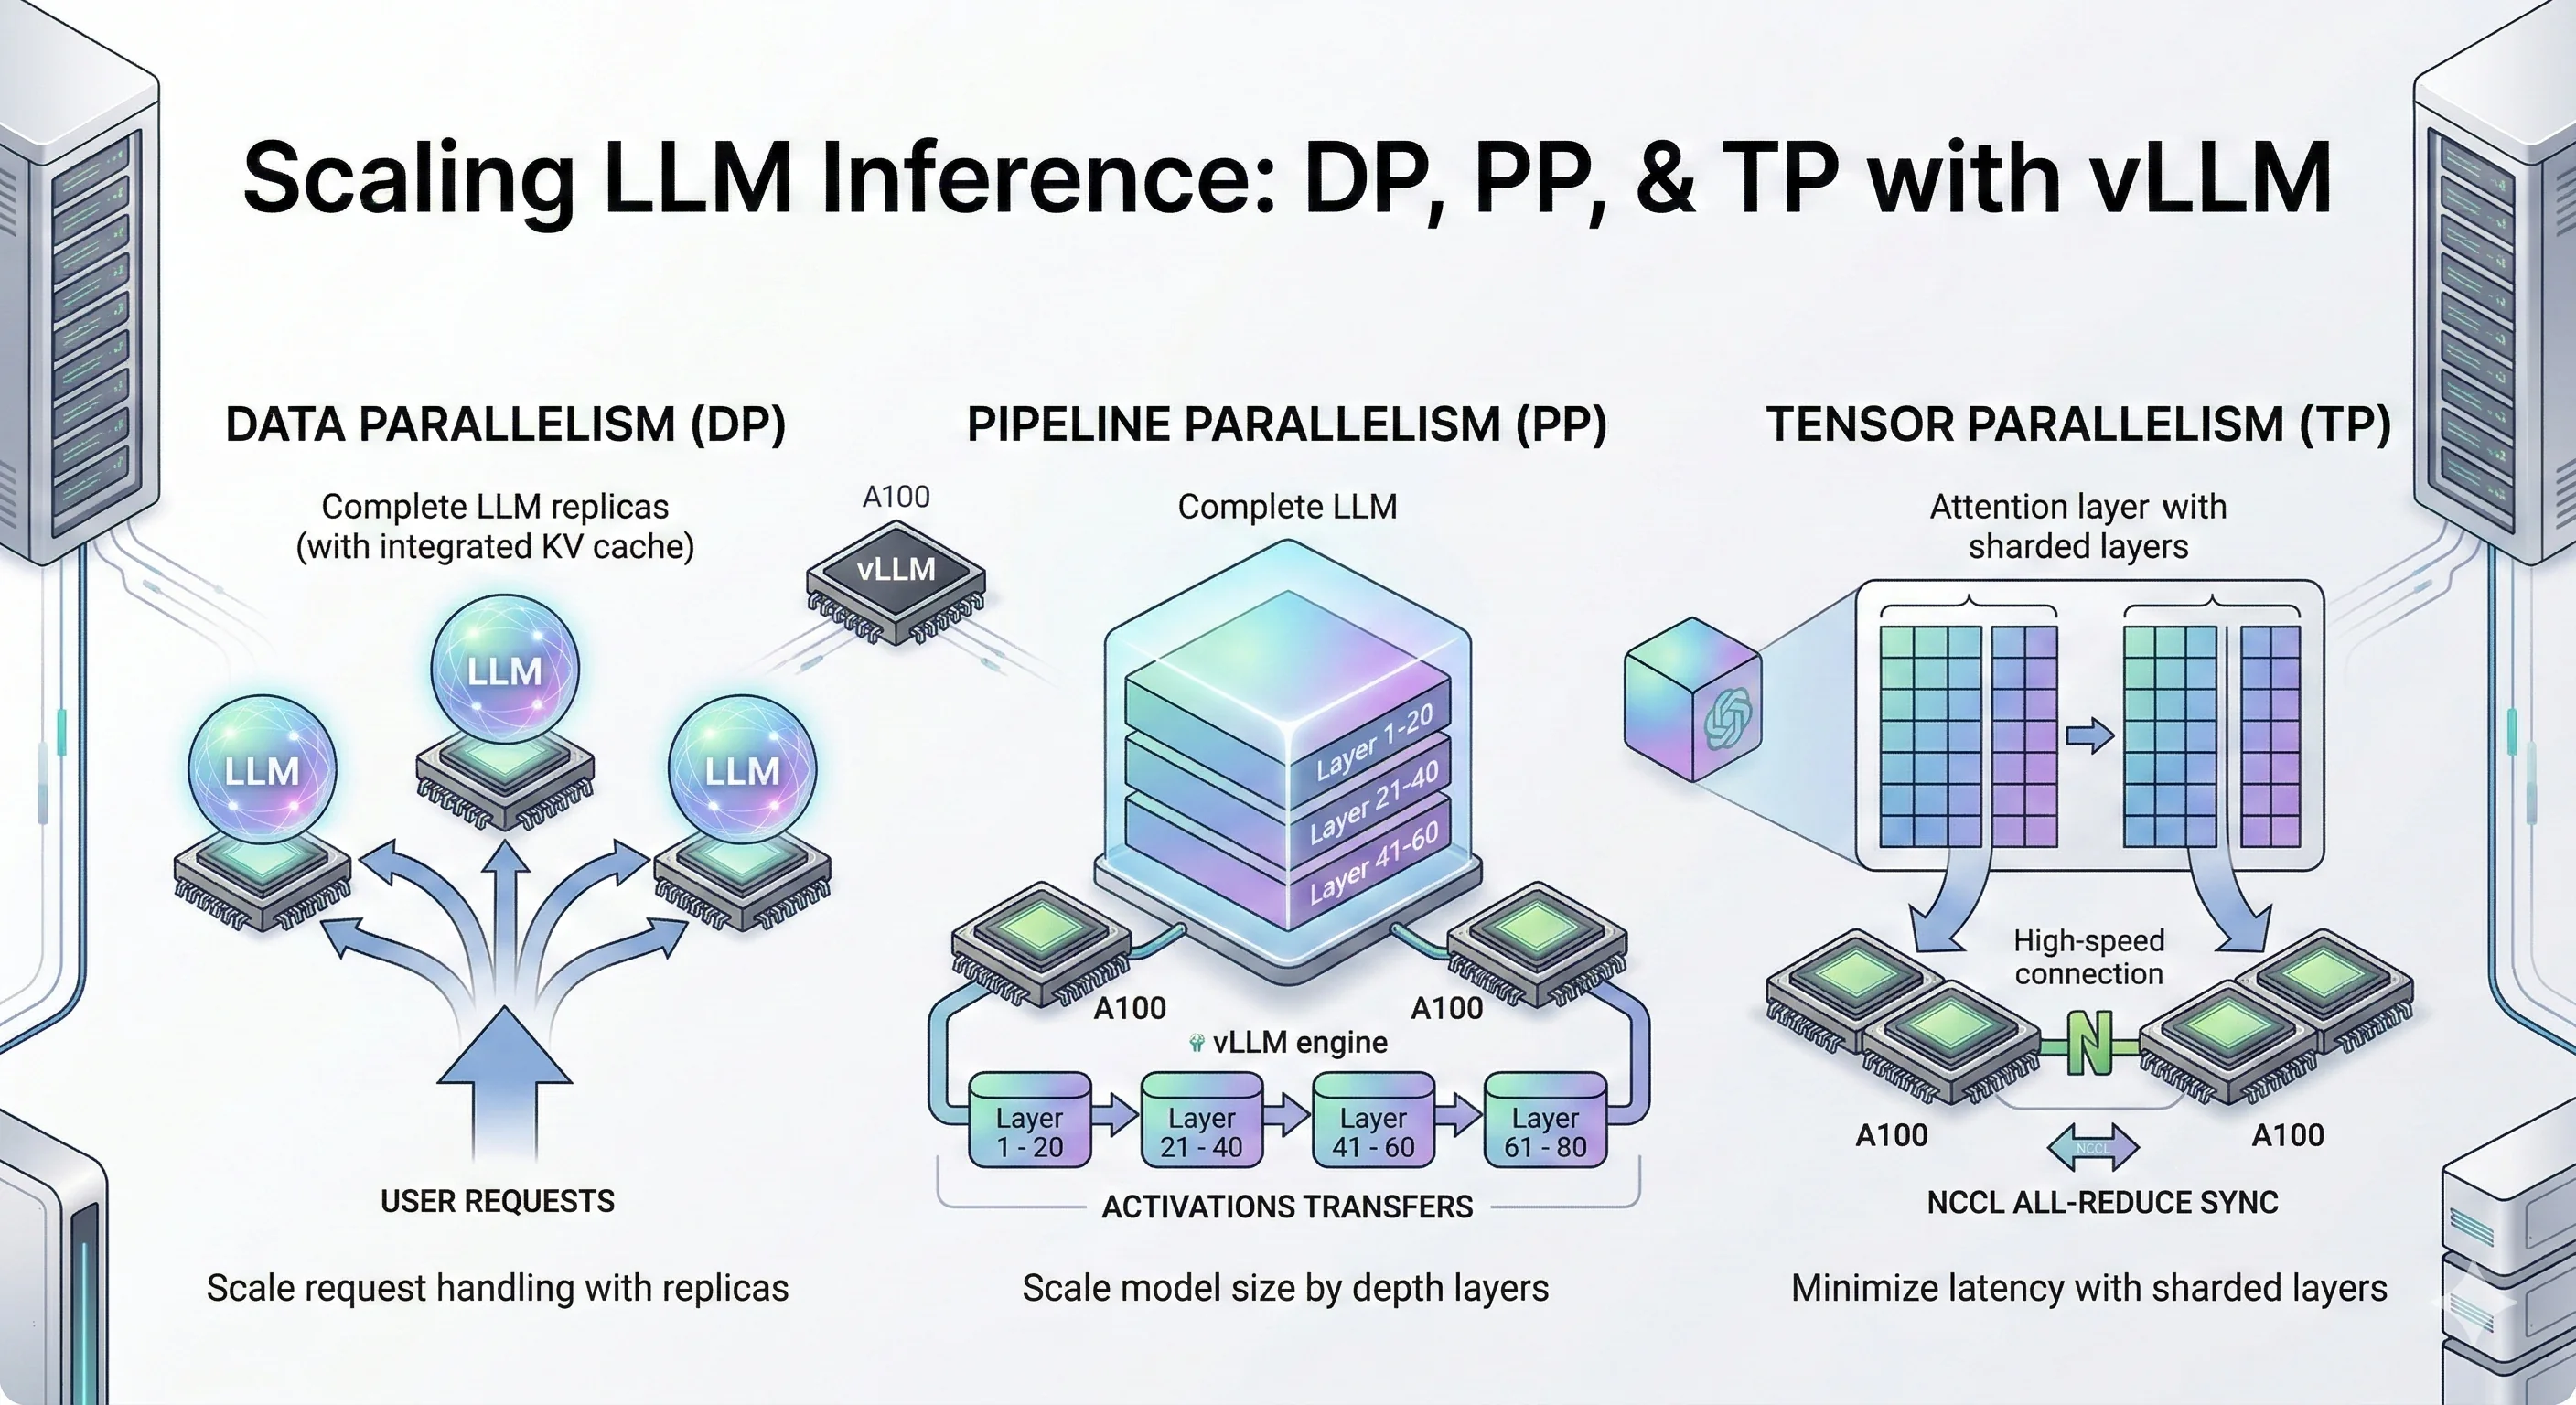
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

How parallel decoding algorithms accelerate LLM inference at the cost ...
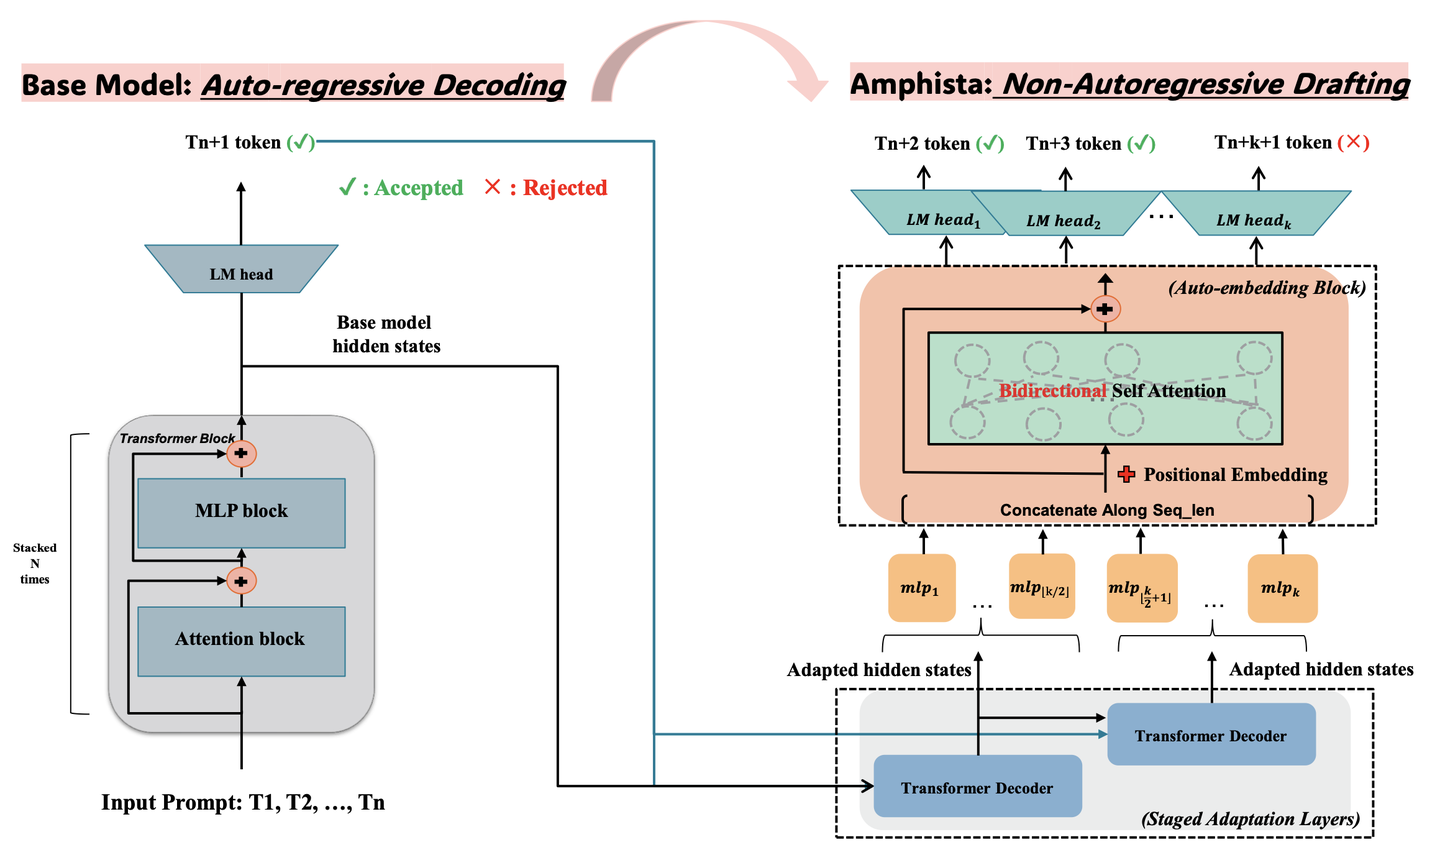
Amphista: Accelerate LLM Inference with Bi-directional Multiple ...

Speculative Decoding and Efficient LLM Inference | TWIML - The Voice of ...

Table 2 from Accelerating LLM Inference with Staged Speculative ...
Advertisement Space (336x280)

(PDF) Accelerate Speculative Decoding with Sparse Computation in ...

[2503.10325] Collaborative Speculative Inference for Efficient LLM ...

SpecInfer: Accelerating Generative LLM Serving with Speculative ...
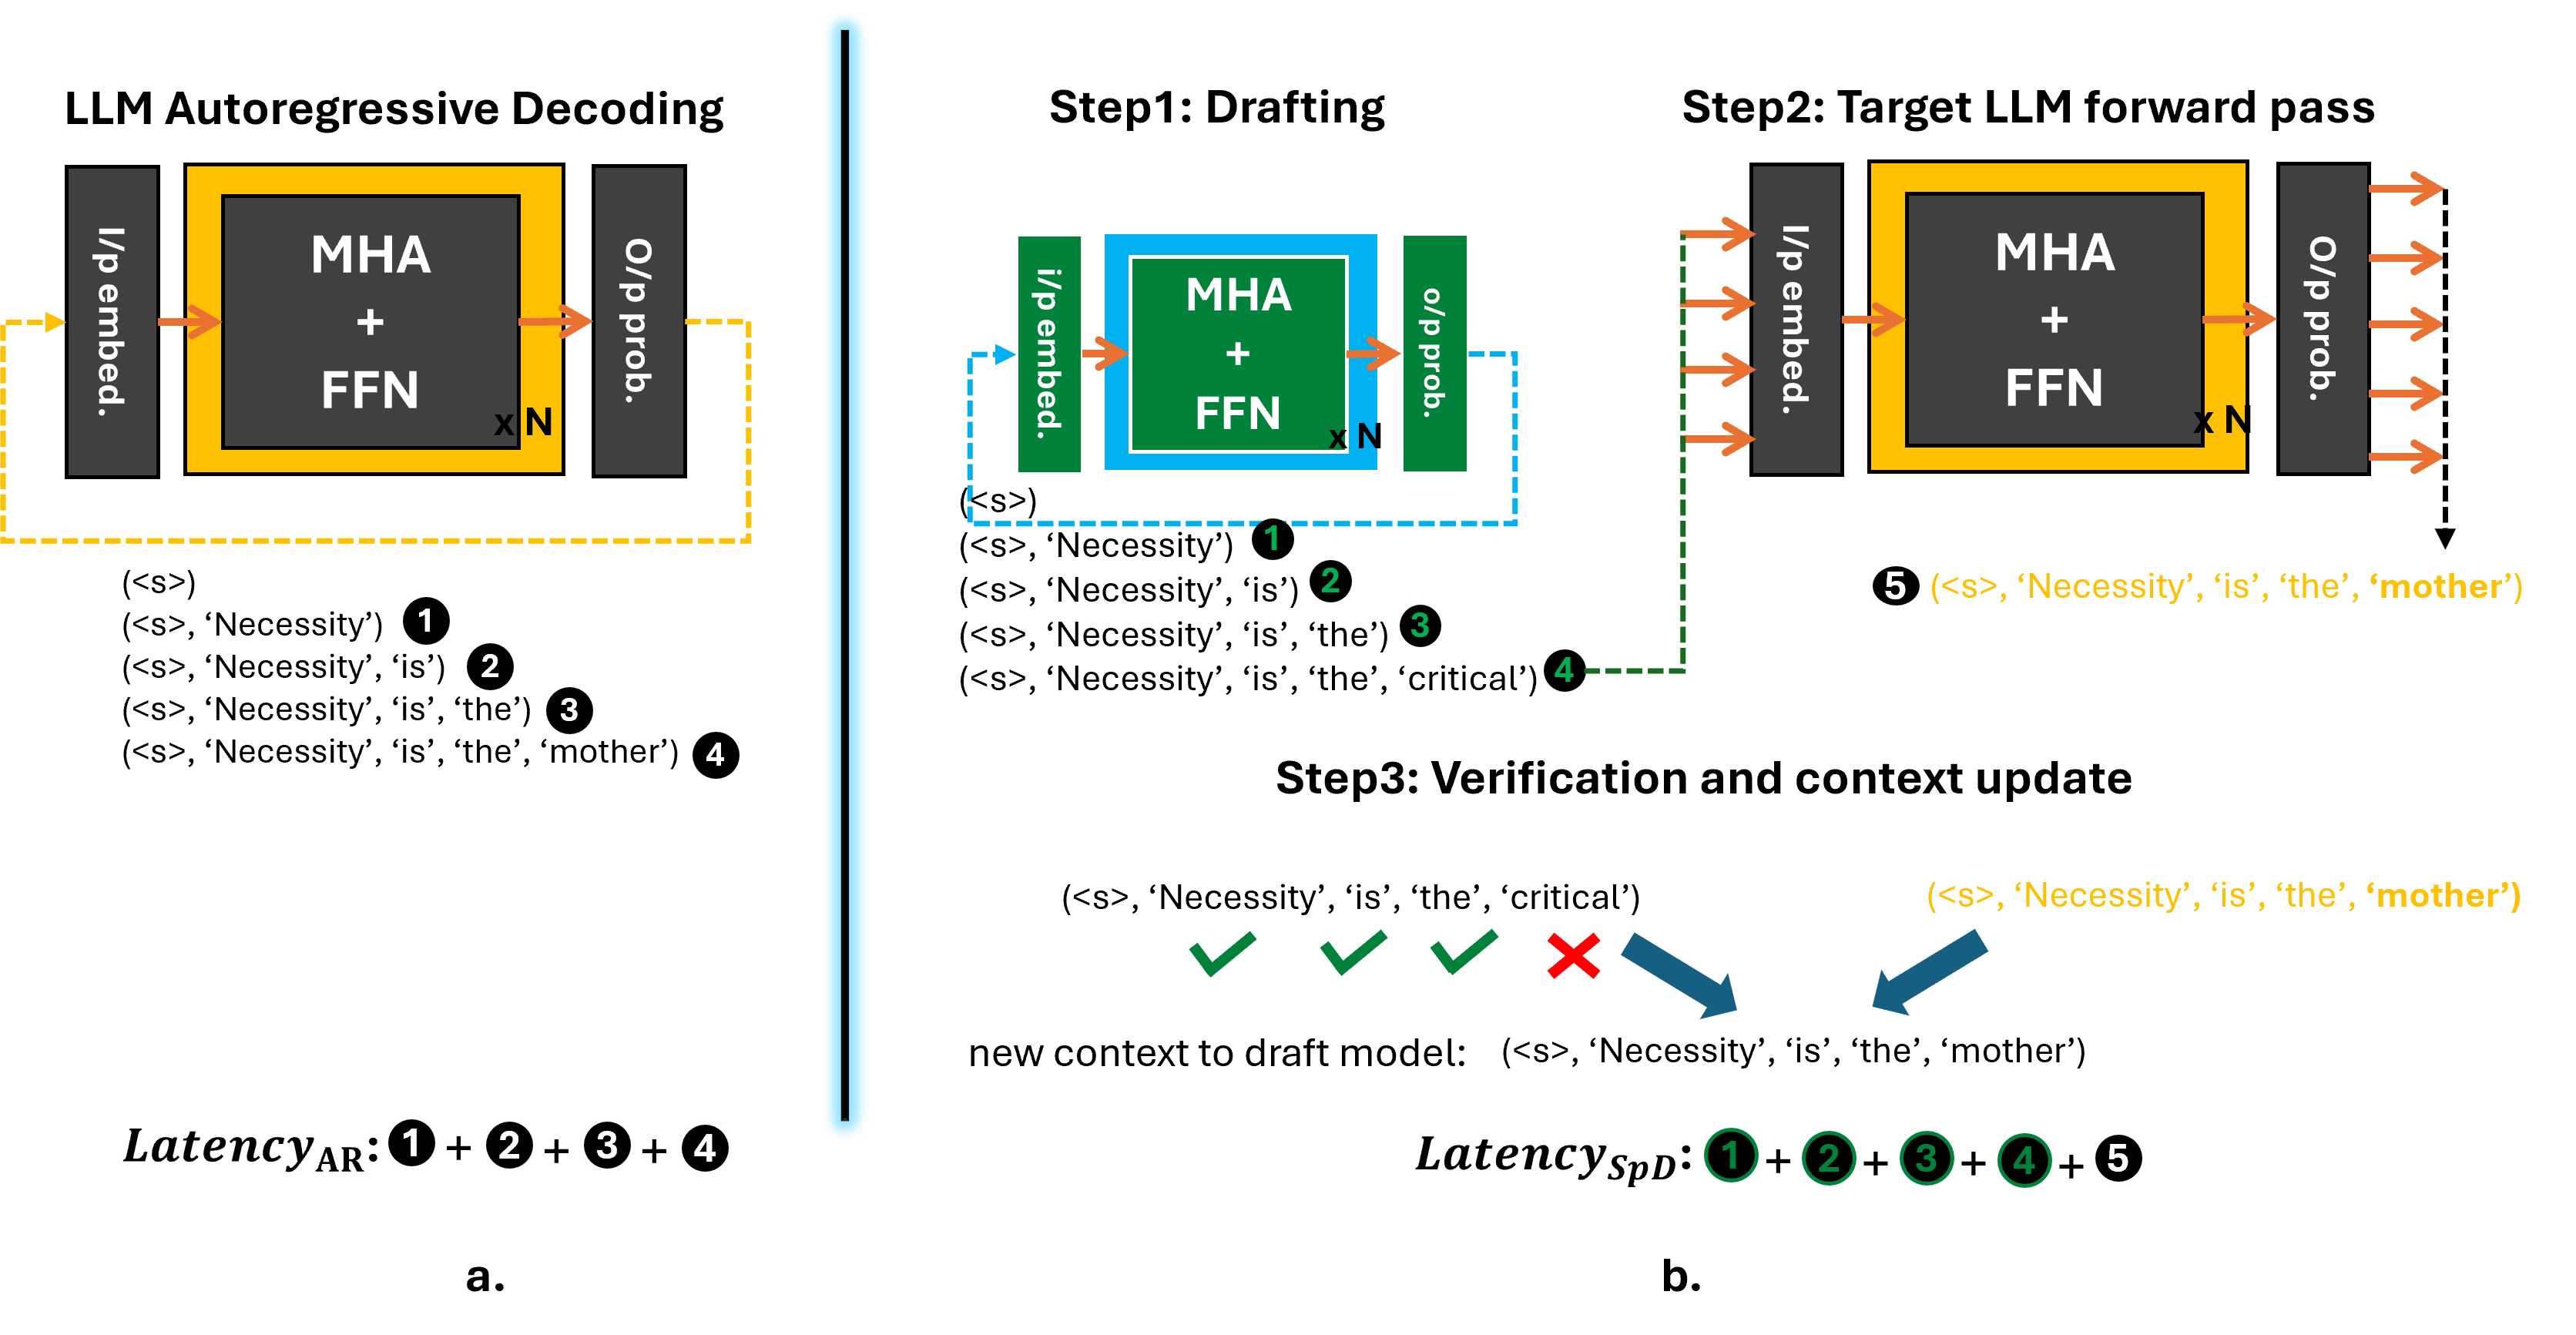
Accelerating LLM Inference: Up to 3x Speedup on MI300X with Speculative ...

SpecEE: Accelerating Large Language Model Inference with Speculative ...