
Accelerating Llm Inference With Speculative Decoding Using Lmstudio

Accelerating LLM Inference with Speculative Decoding using LMStudio ...
Accelerating LLM Inference with Speculative Decoding using LMStudio ...

Accelerating LLM Inference with Speculative Decoding using LMStudio ...

Accelerating LLM Inference with Speculative Decoding using LMStudio ...

Accelerating LLM Inference with Speculative Decoding using LMStudio ...

Paper page - Accelerating LLM Inference with Staged Speculative Decoding
Accelerating LLM Inference with Speculative Decoding - LinkedIn ...

(PDF) Accelerating LLM Inference with Lossless Speculative Decoding ...

(PDF) Accelerating LLM Inference with Staged Speculative Decoding
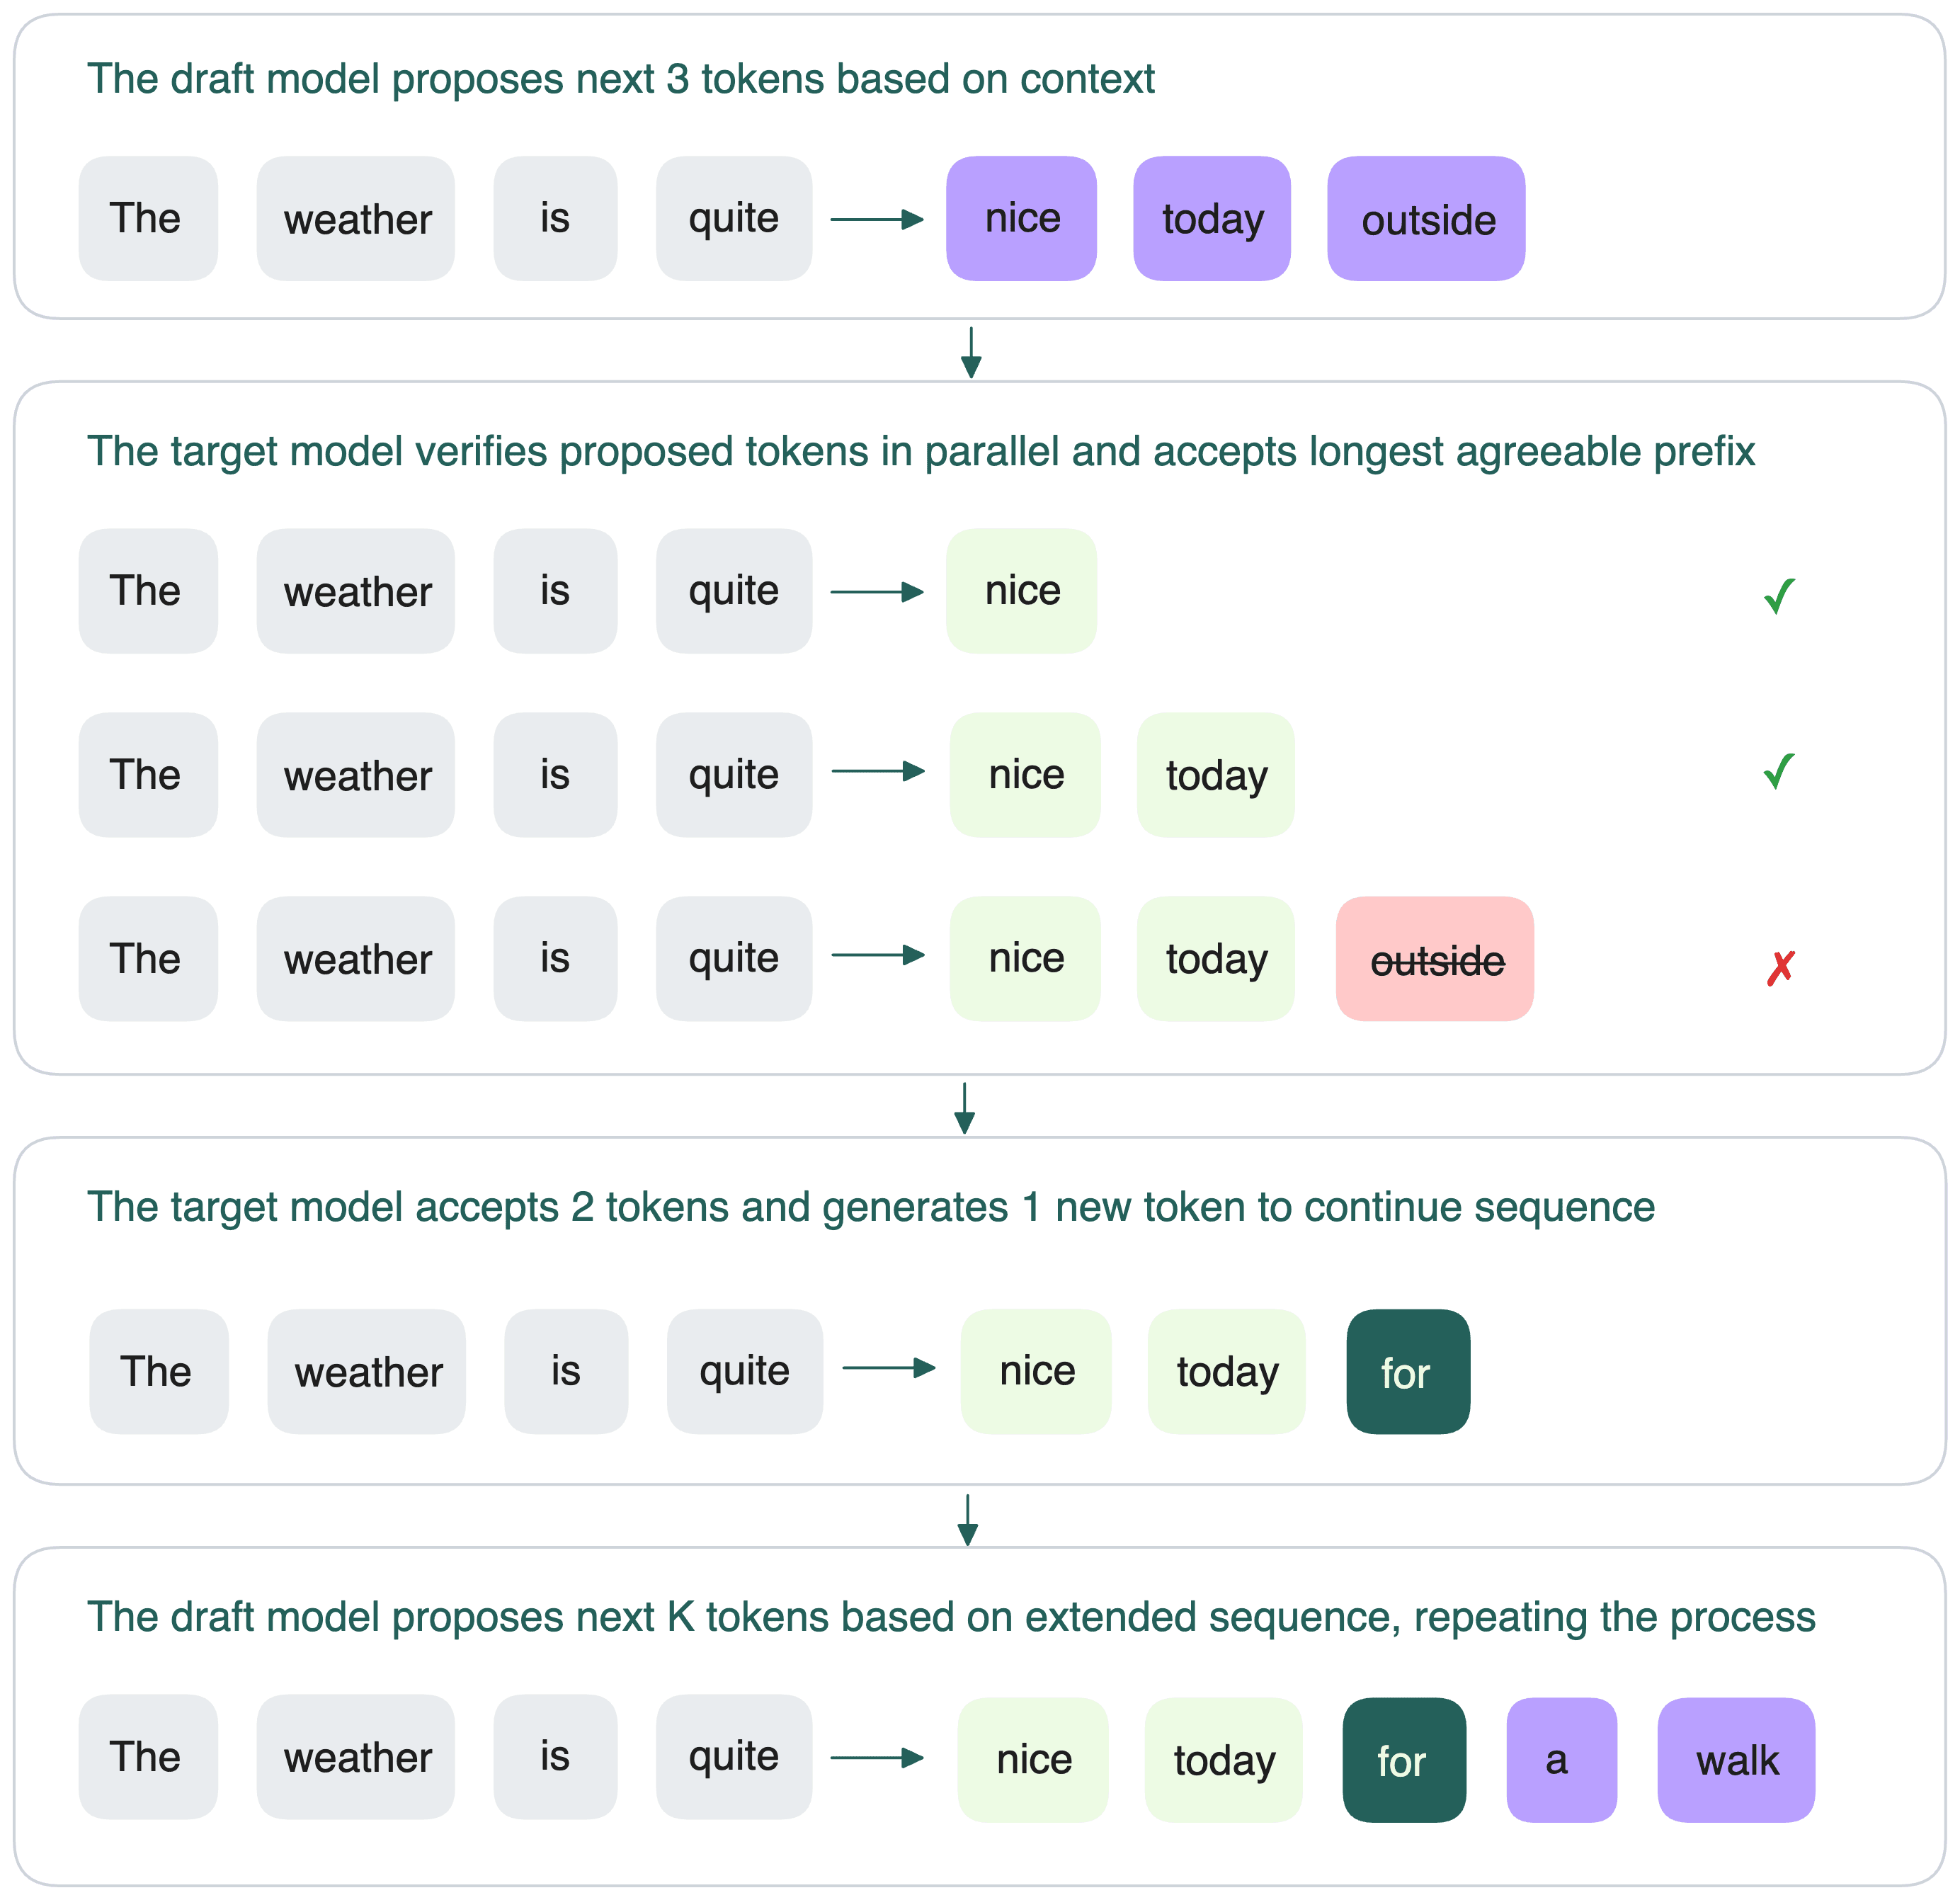
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
Advertisement Space (300x250)
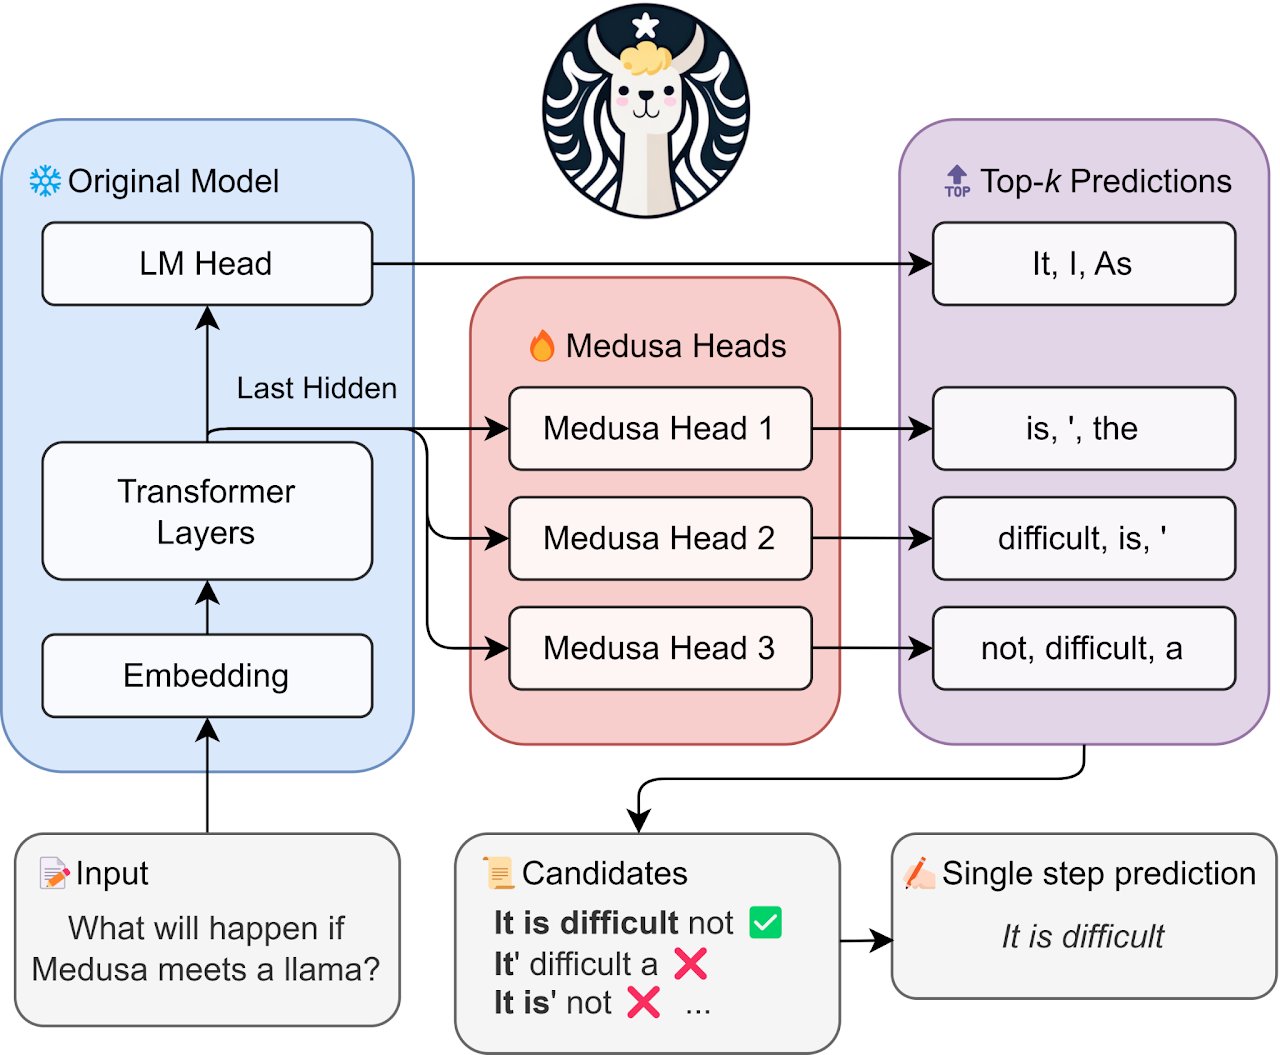
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Speculative Decoding with CTC-based Draft Model for LLM Inference ...
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
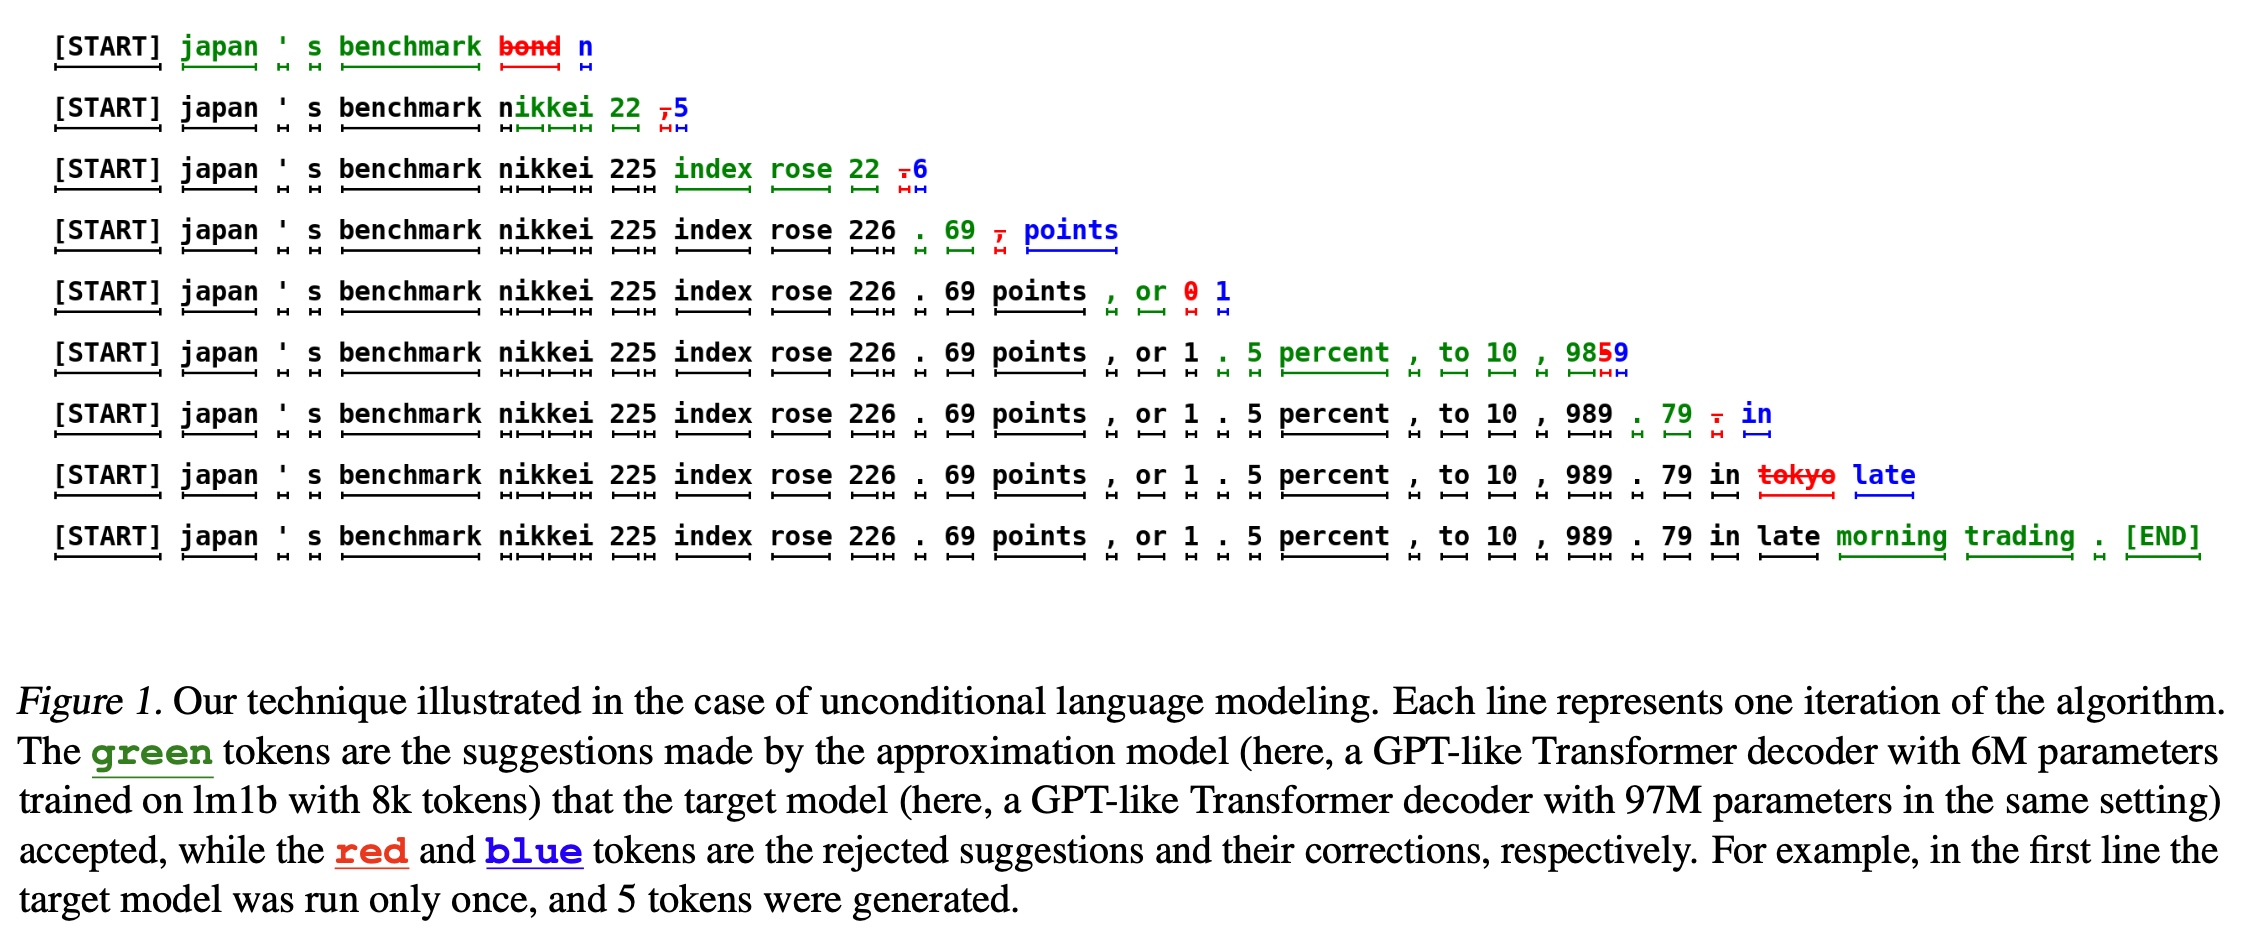
Accelerate LLM Inference with Speculative Decoding | Charles Xu
P-EAGLE: Accelerating LLM Inference via Parallel Speculative Decoding ...
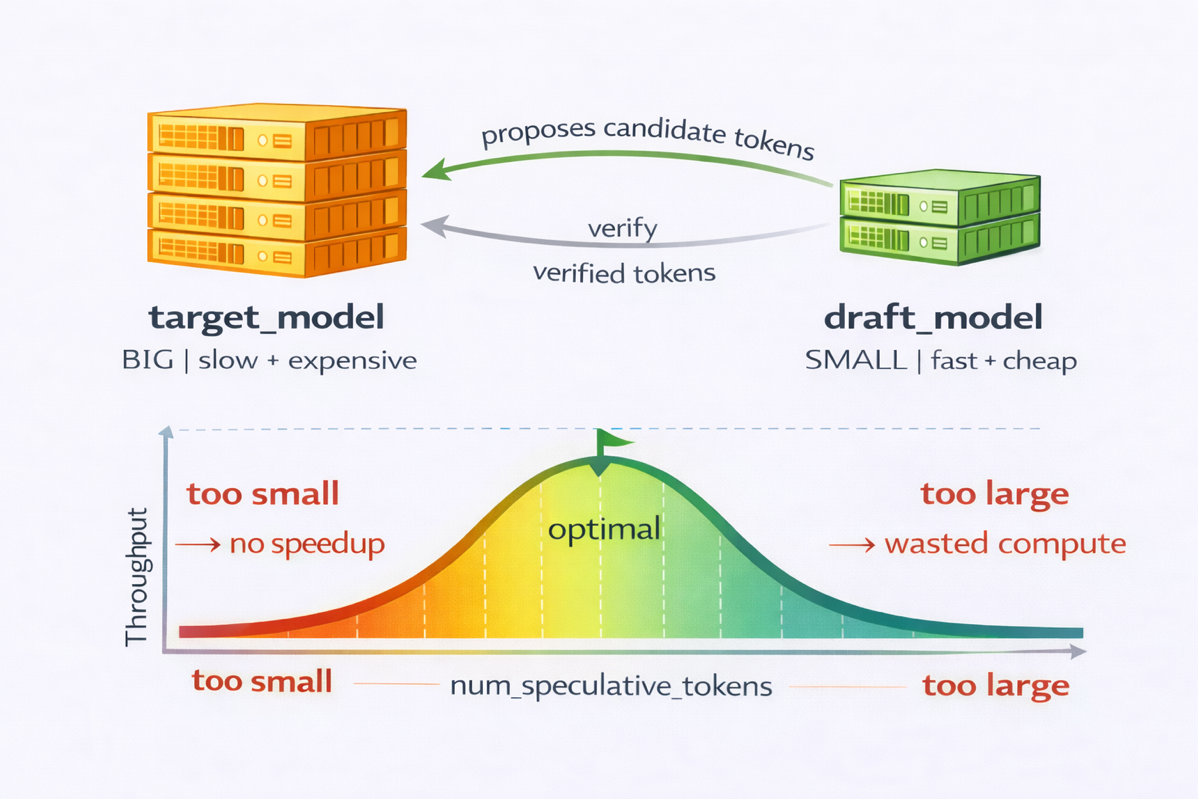
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec

Accelerating LLM Inference with Staged Speculative Decoding: Paper and ...
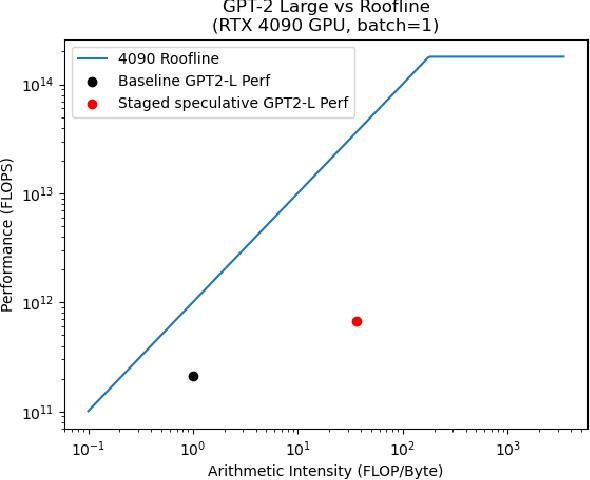
Figure 1 from Accelerating LLM Inference with Staged Speculative ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
Advertisement Space (336x280)
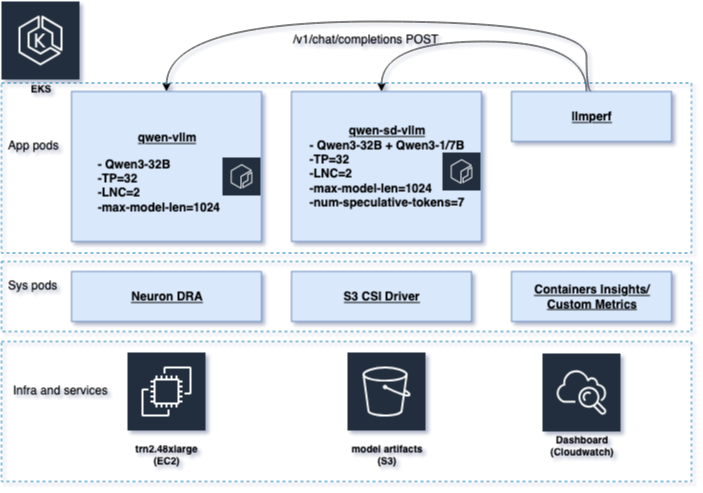
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec

SpecInfer: Accelerating Generative LLM Serving with Speculative ...
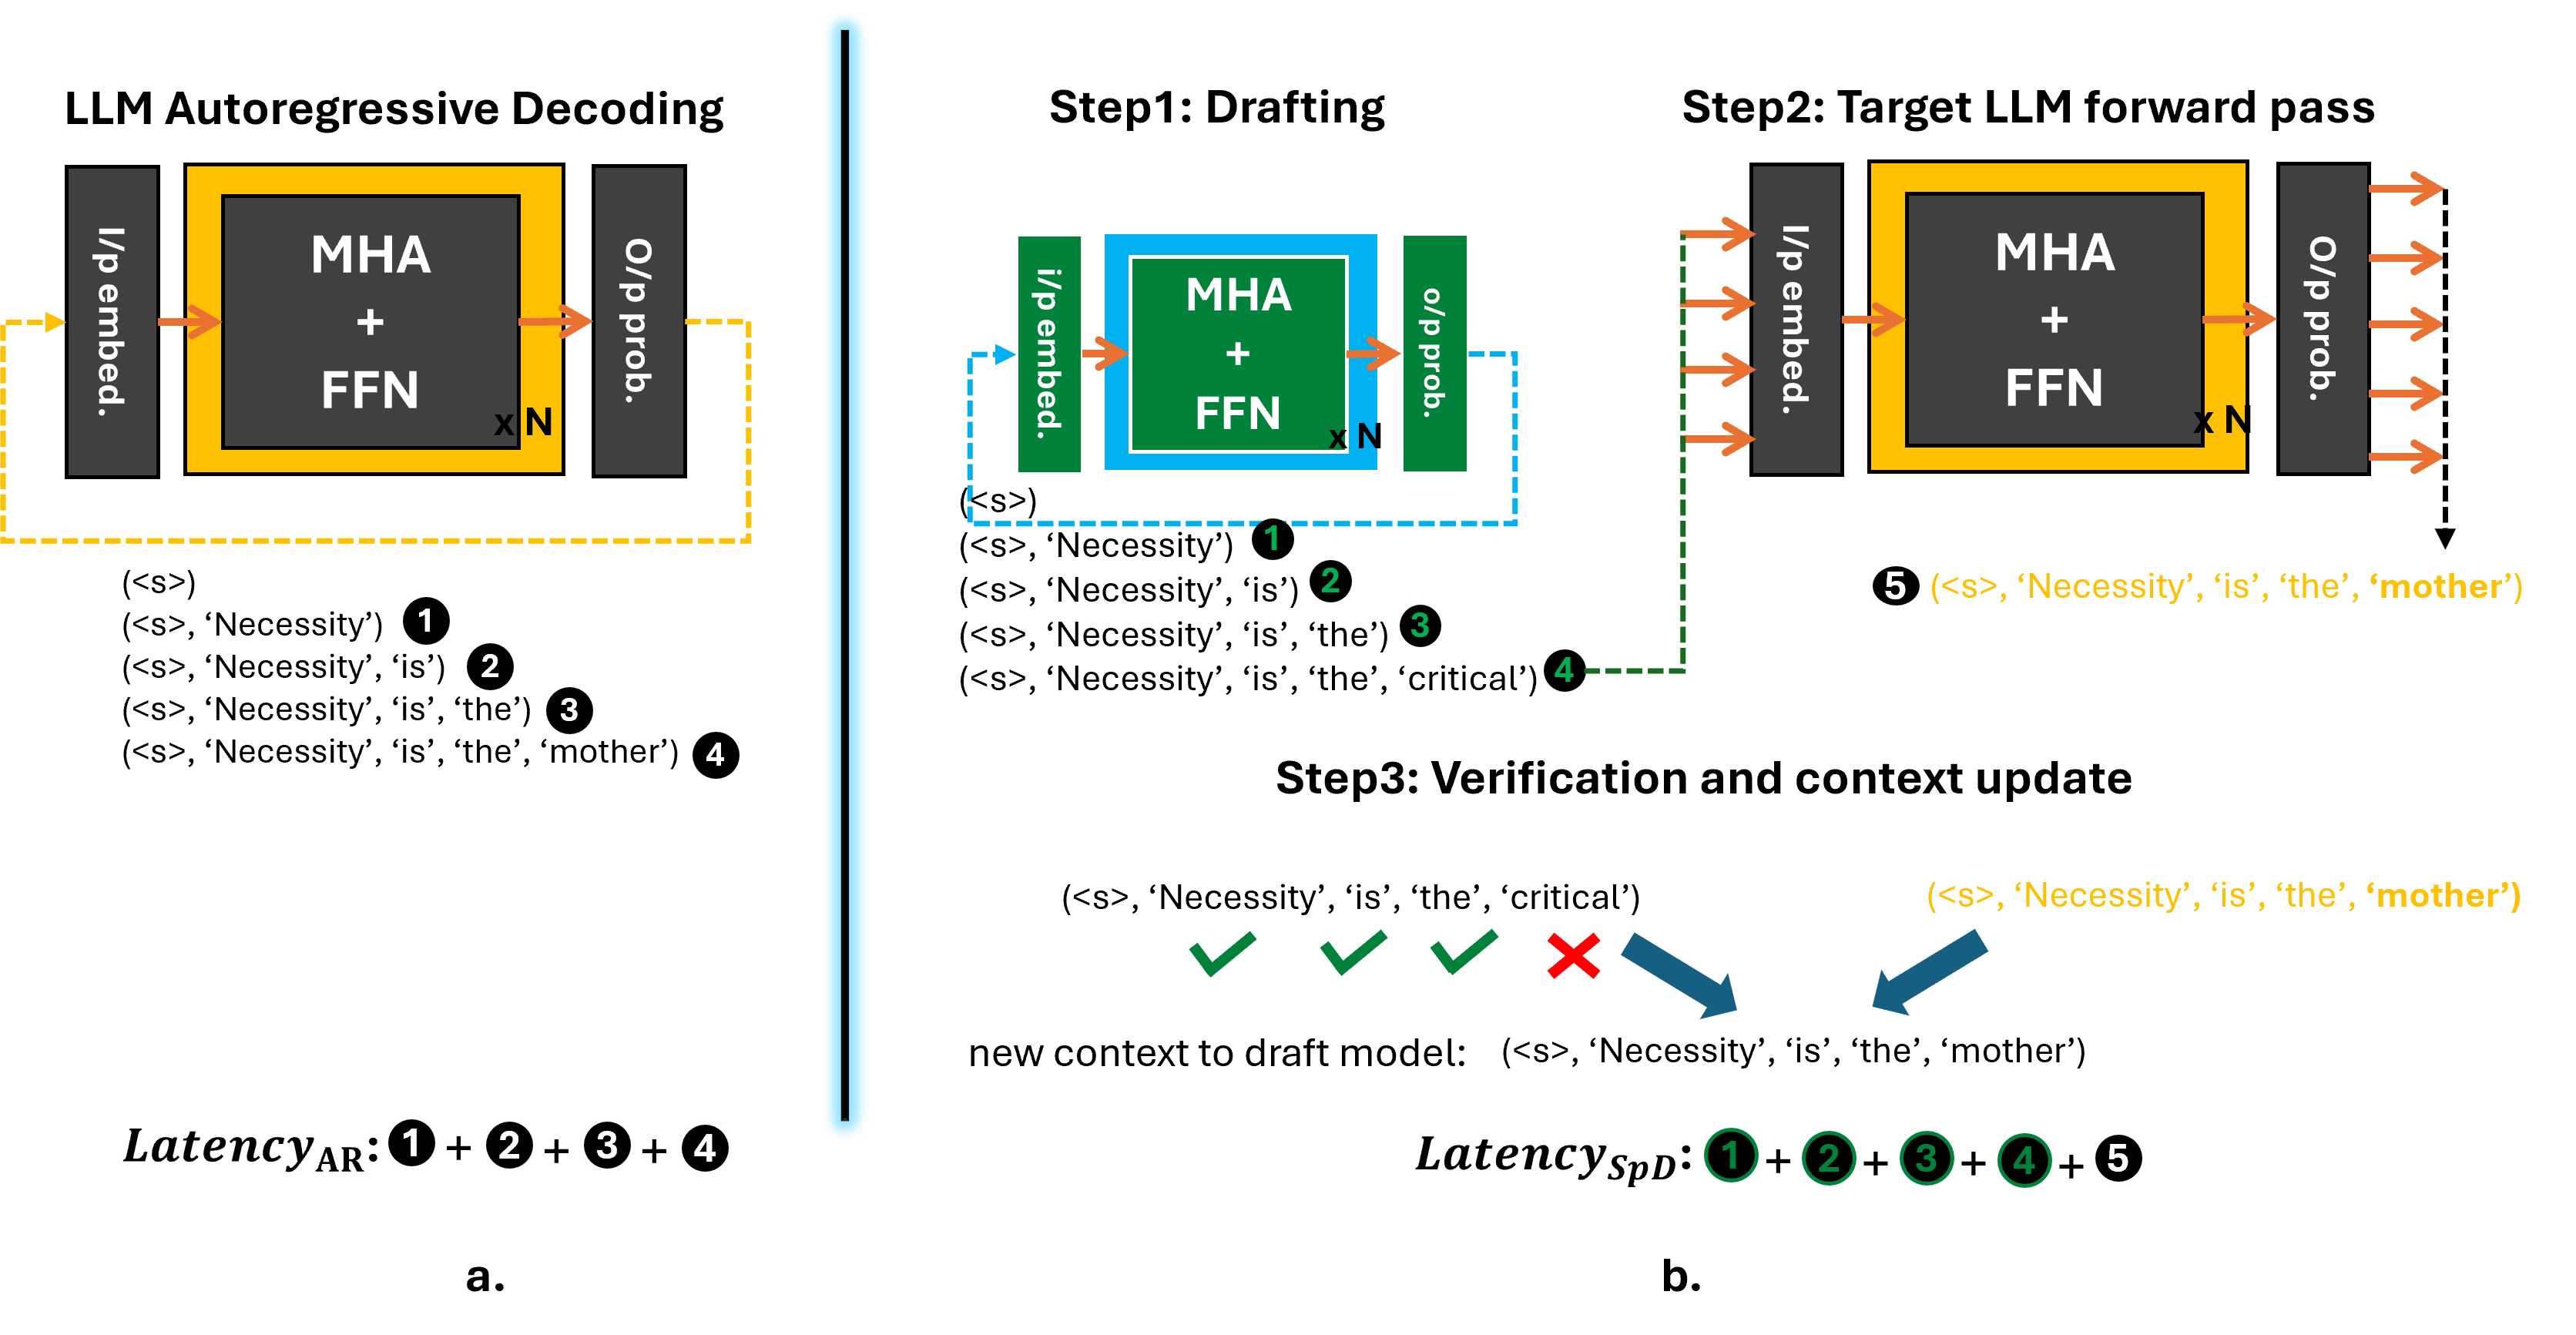
Accelerating LLM Inference: Up to 3x Speedup on MI300X with Speculative ...

SpecEE: Accelerating Large Language Model Inference with Speculative ...
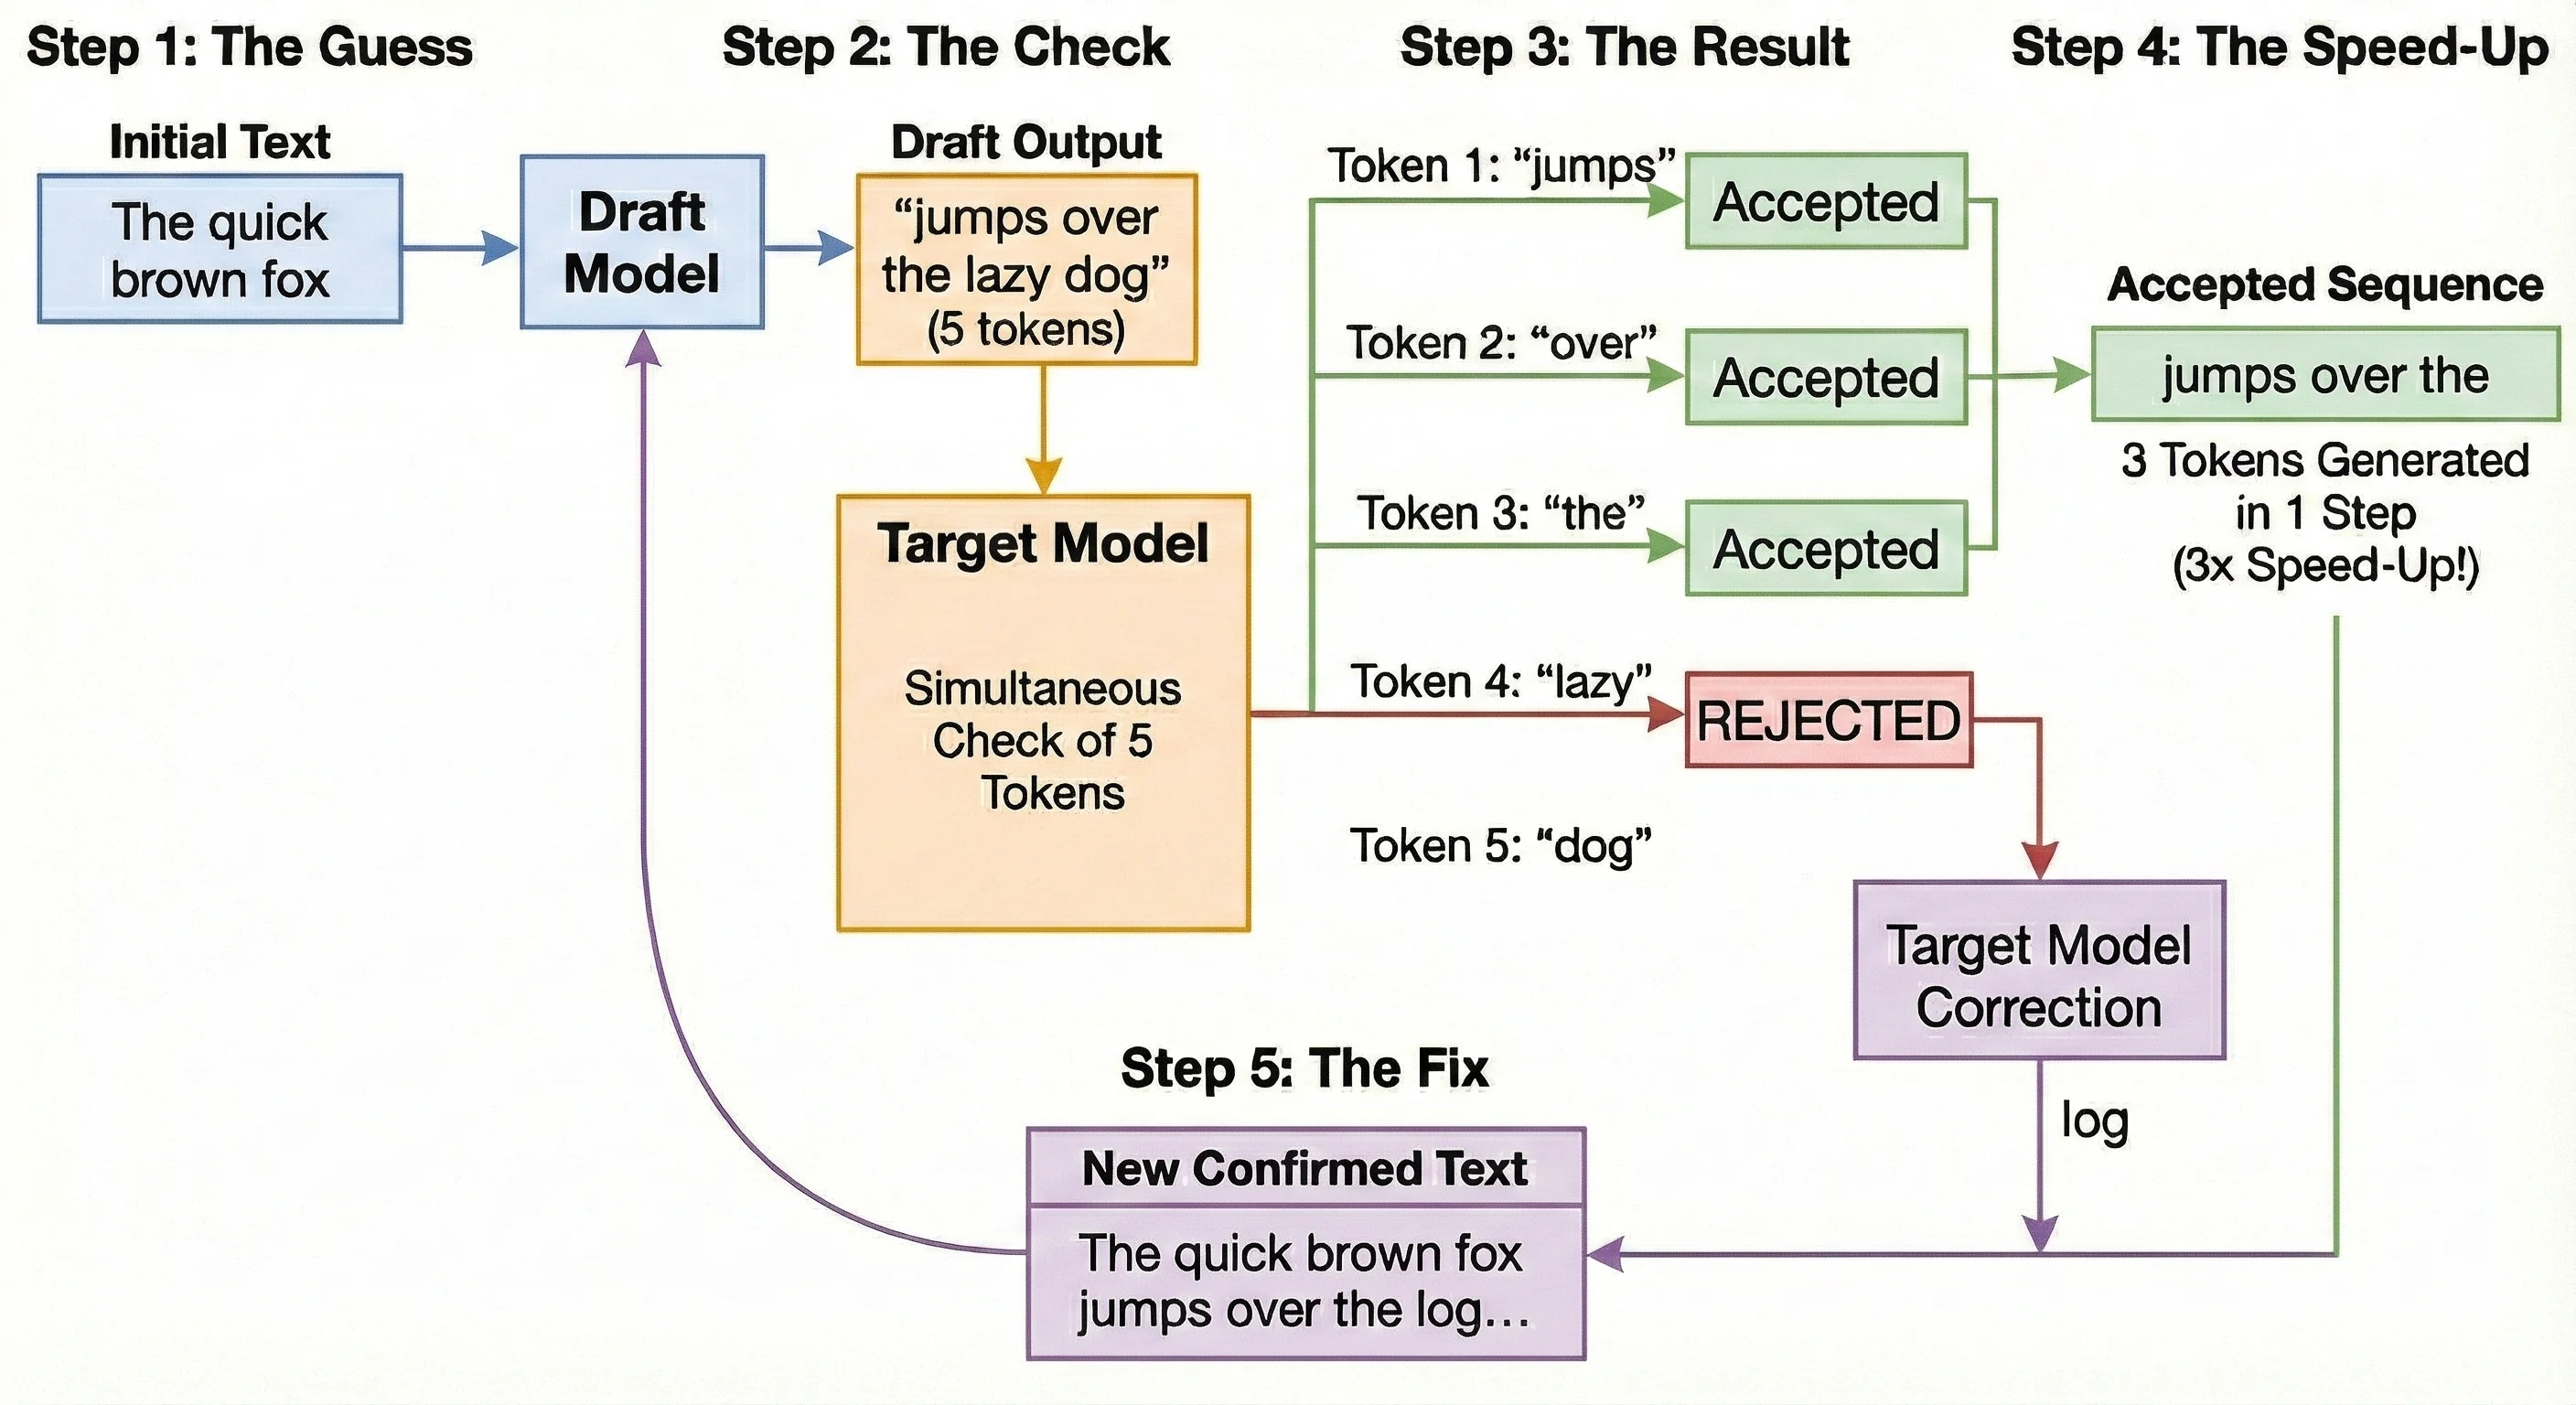
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
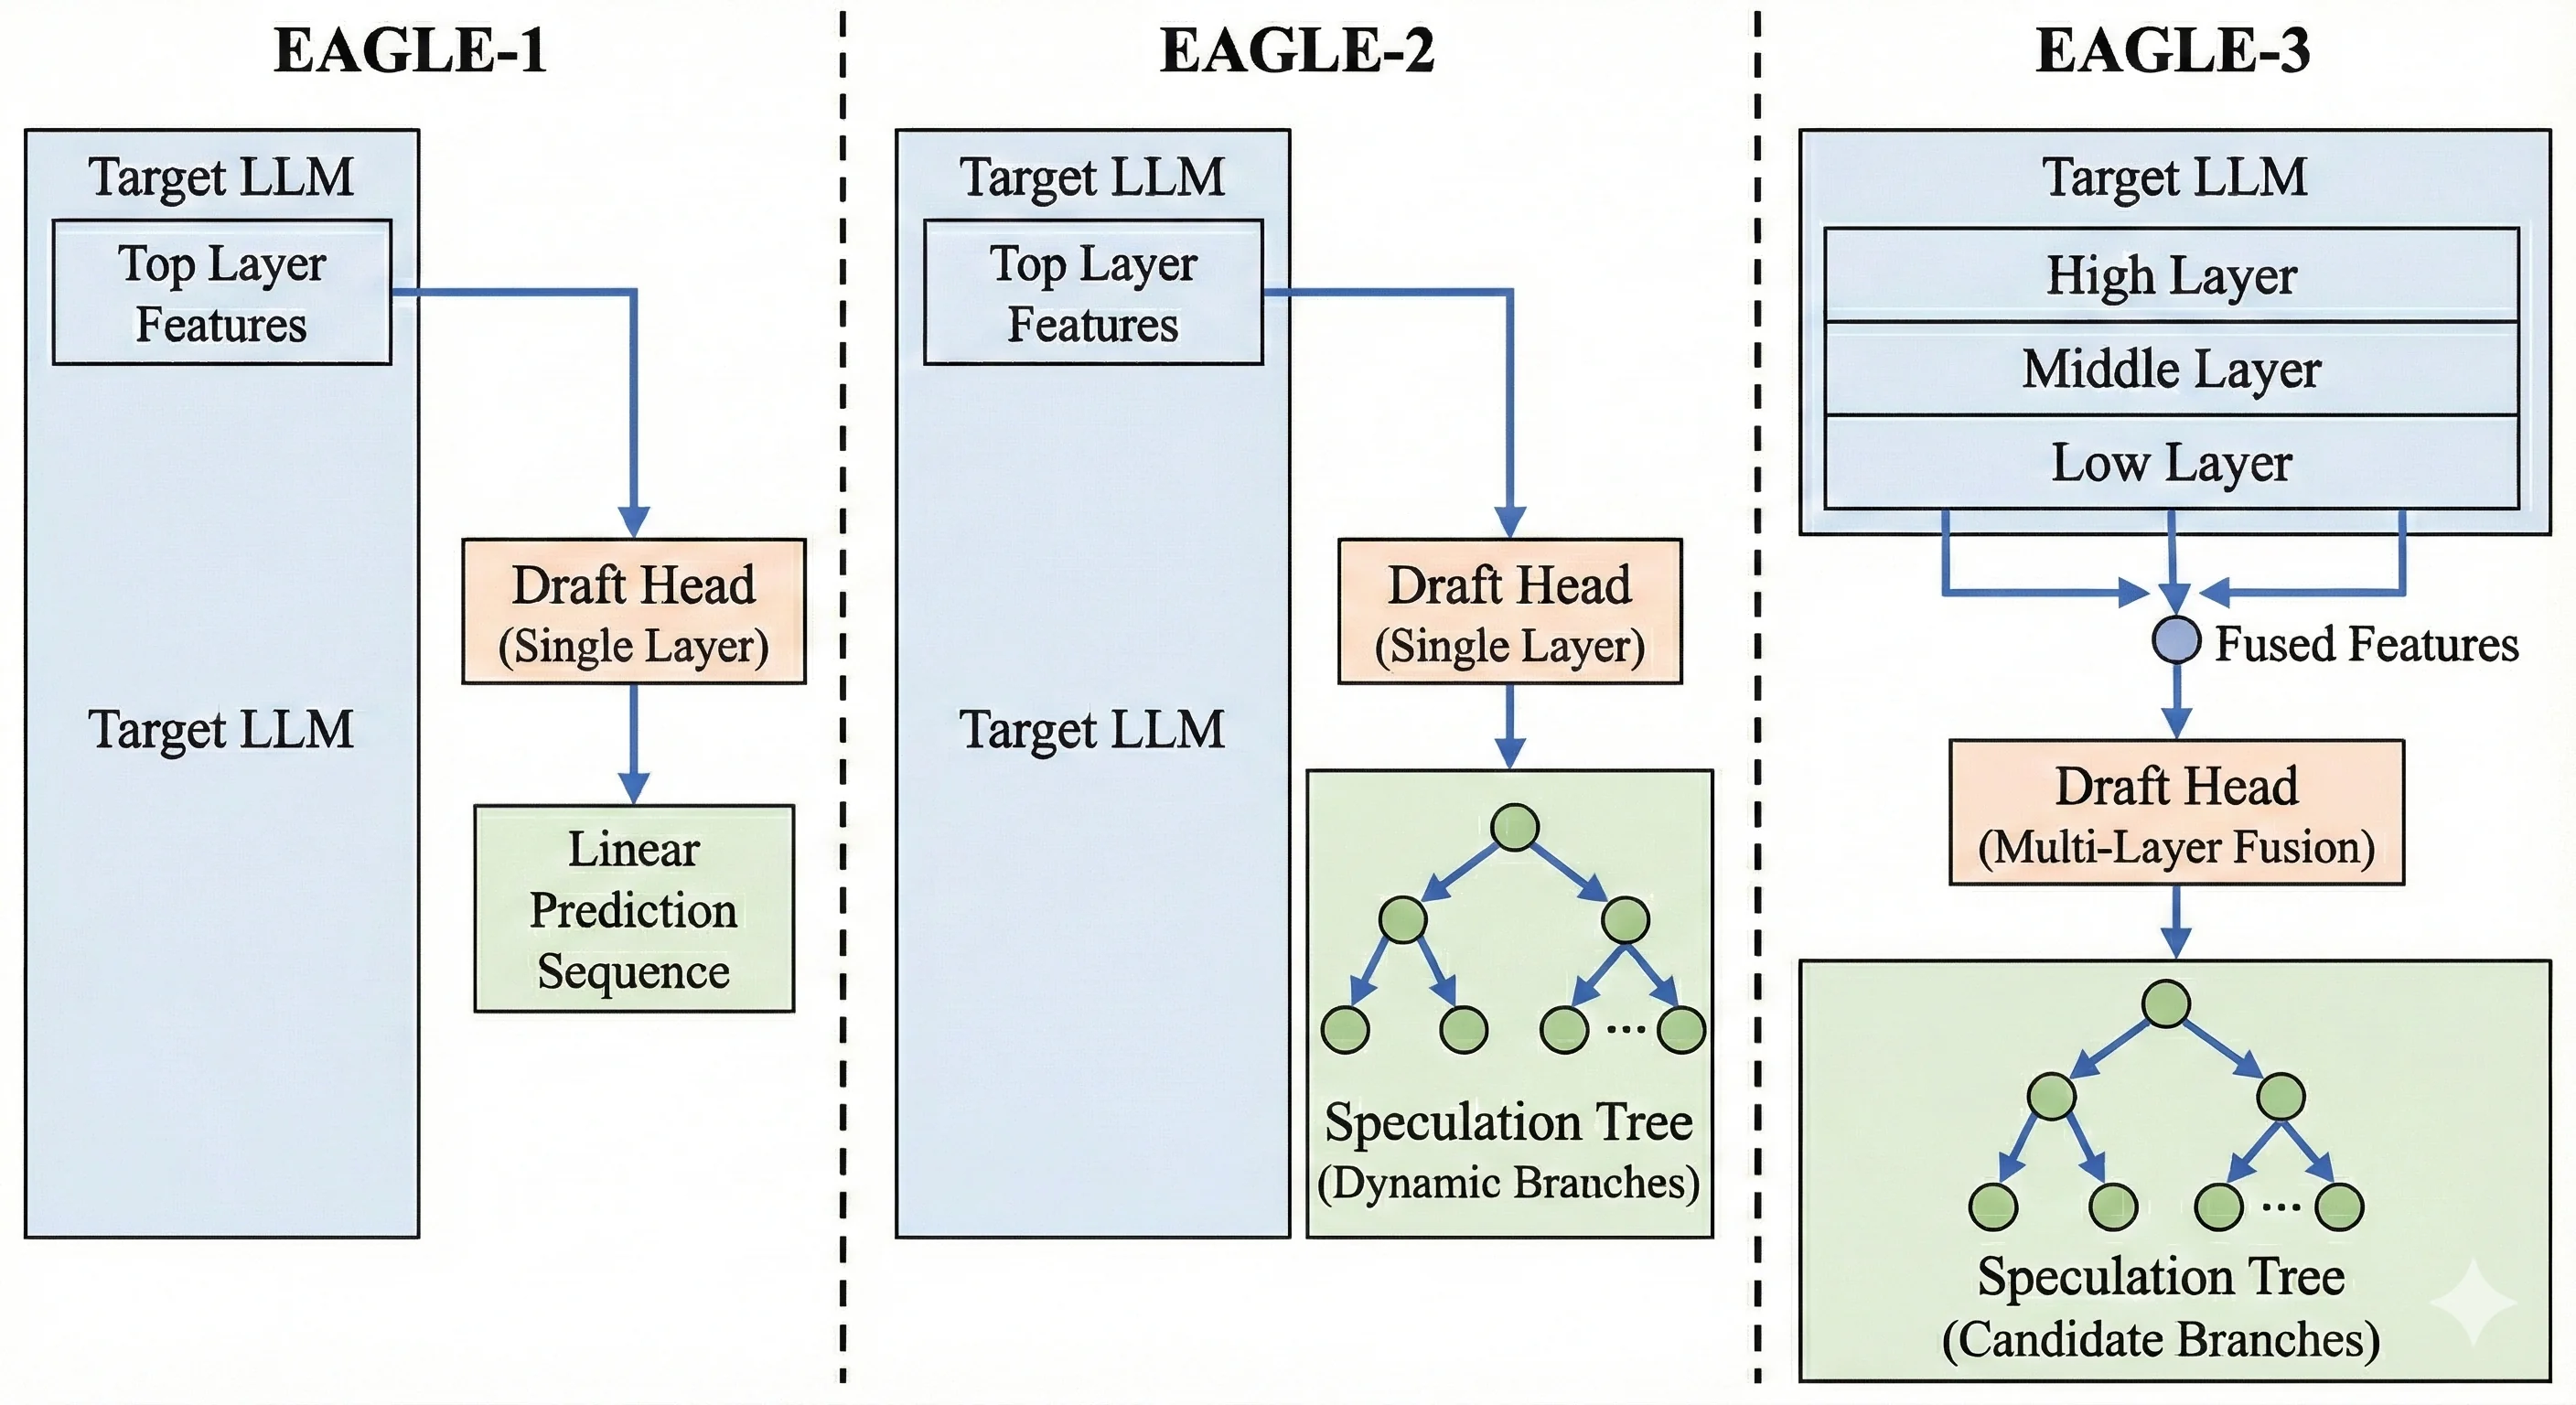
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

[Literature Review] SpecFed: Accelerating Federated LLM Inference with ...

SpecInfer: Accelerating Generative LLM Serving with Speculative ...

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube

Speculative Decoding: Accelerating LLM Inference Without Quality ...
Advertisement Space (336x280)

Speculative Decoding: Accelerating LLM Inference Without Quality ...

Speeding Up LLM Output with Speculative Decoding — Arabian Post

Paper page - Recursive Speculative Decoding: Accelerating LLM Inference ...
GitHub - ccs96307/fast-llm-inference: Accelerating LLM inference with ...

SpecEE: Accelerating Large Language Model Inference with Speculative ...
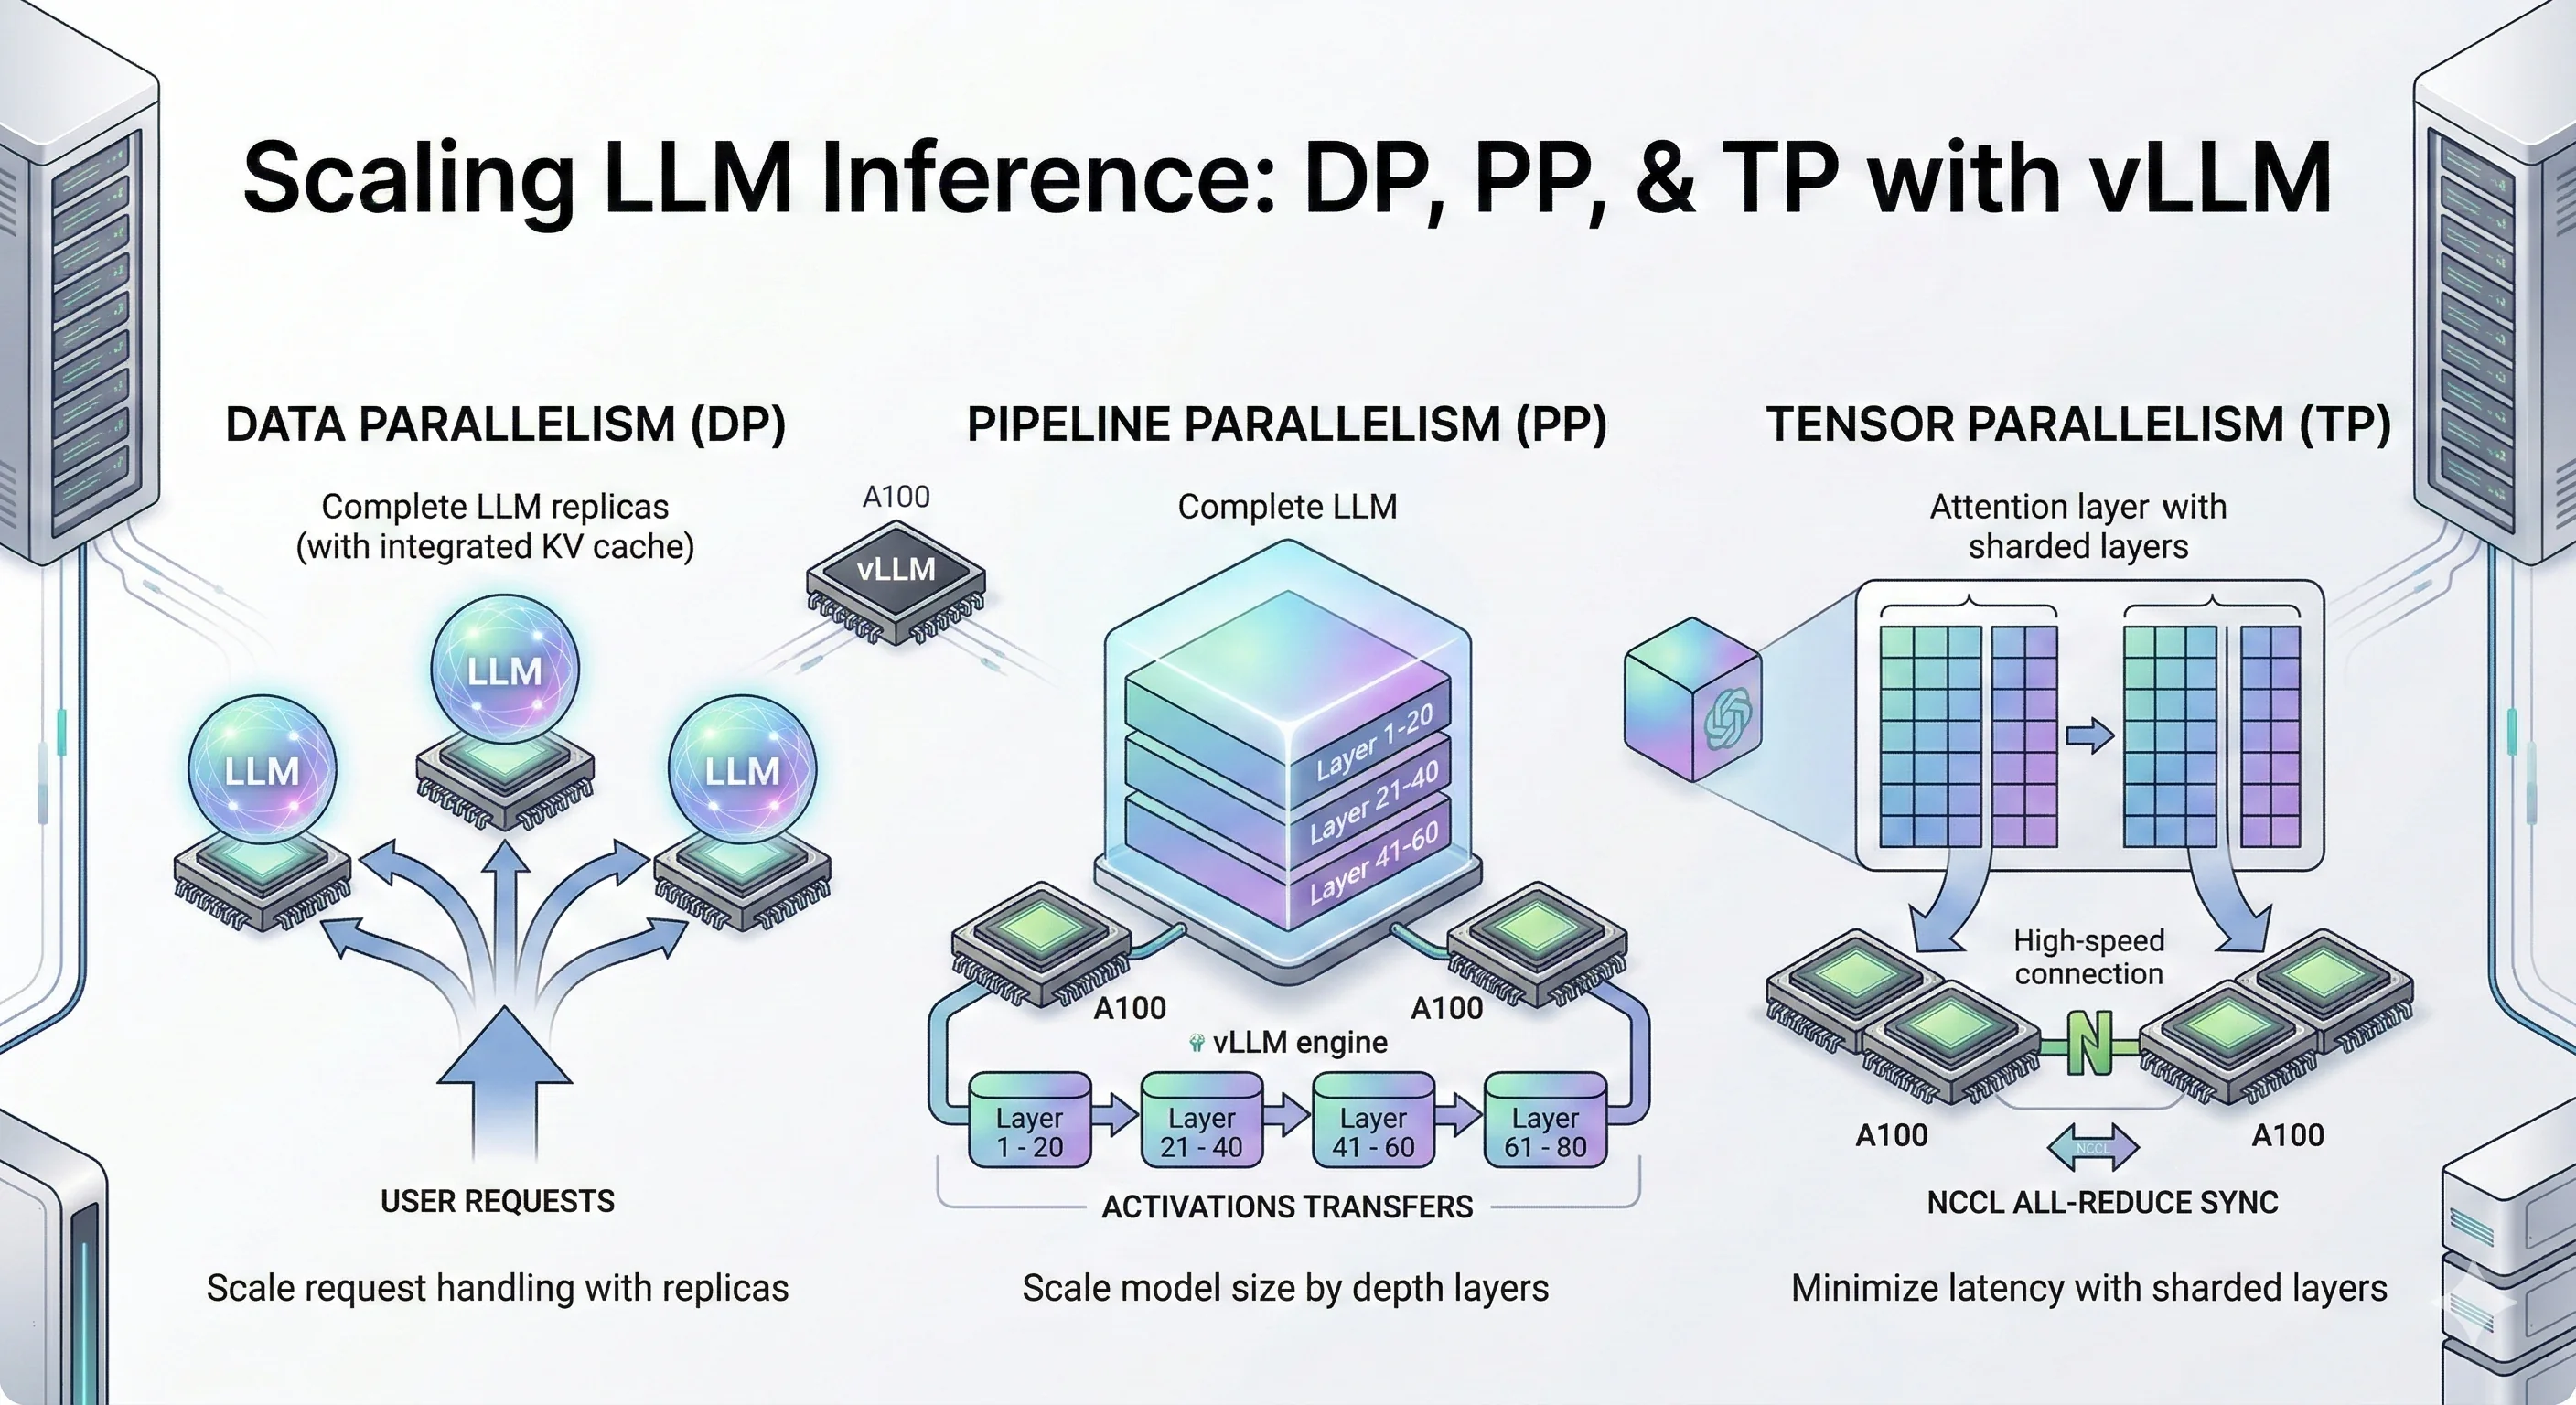
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...