
Aligning Asr Evaluation With Human And Llm Judgments Intelligibility

Aligning ASR Evaluation with Human and LLM Judgments: Intelligibility ...

(PDF) Aligning ASR Evaluation with Human and LLM Judgments ...
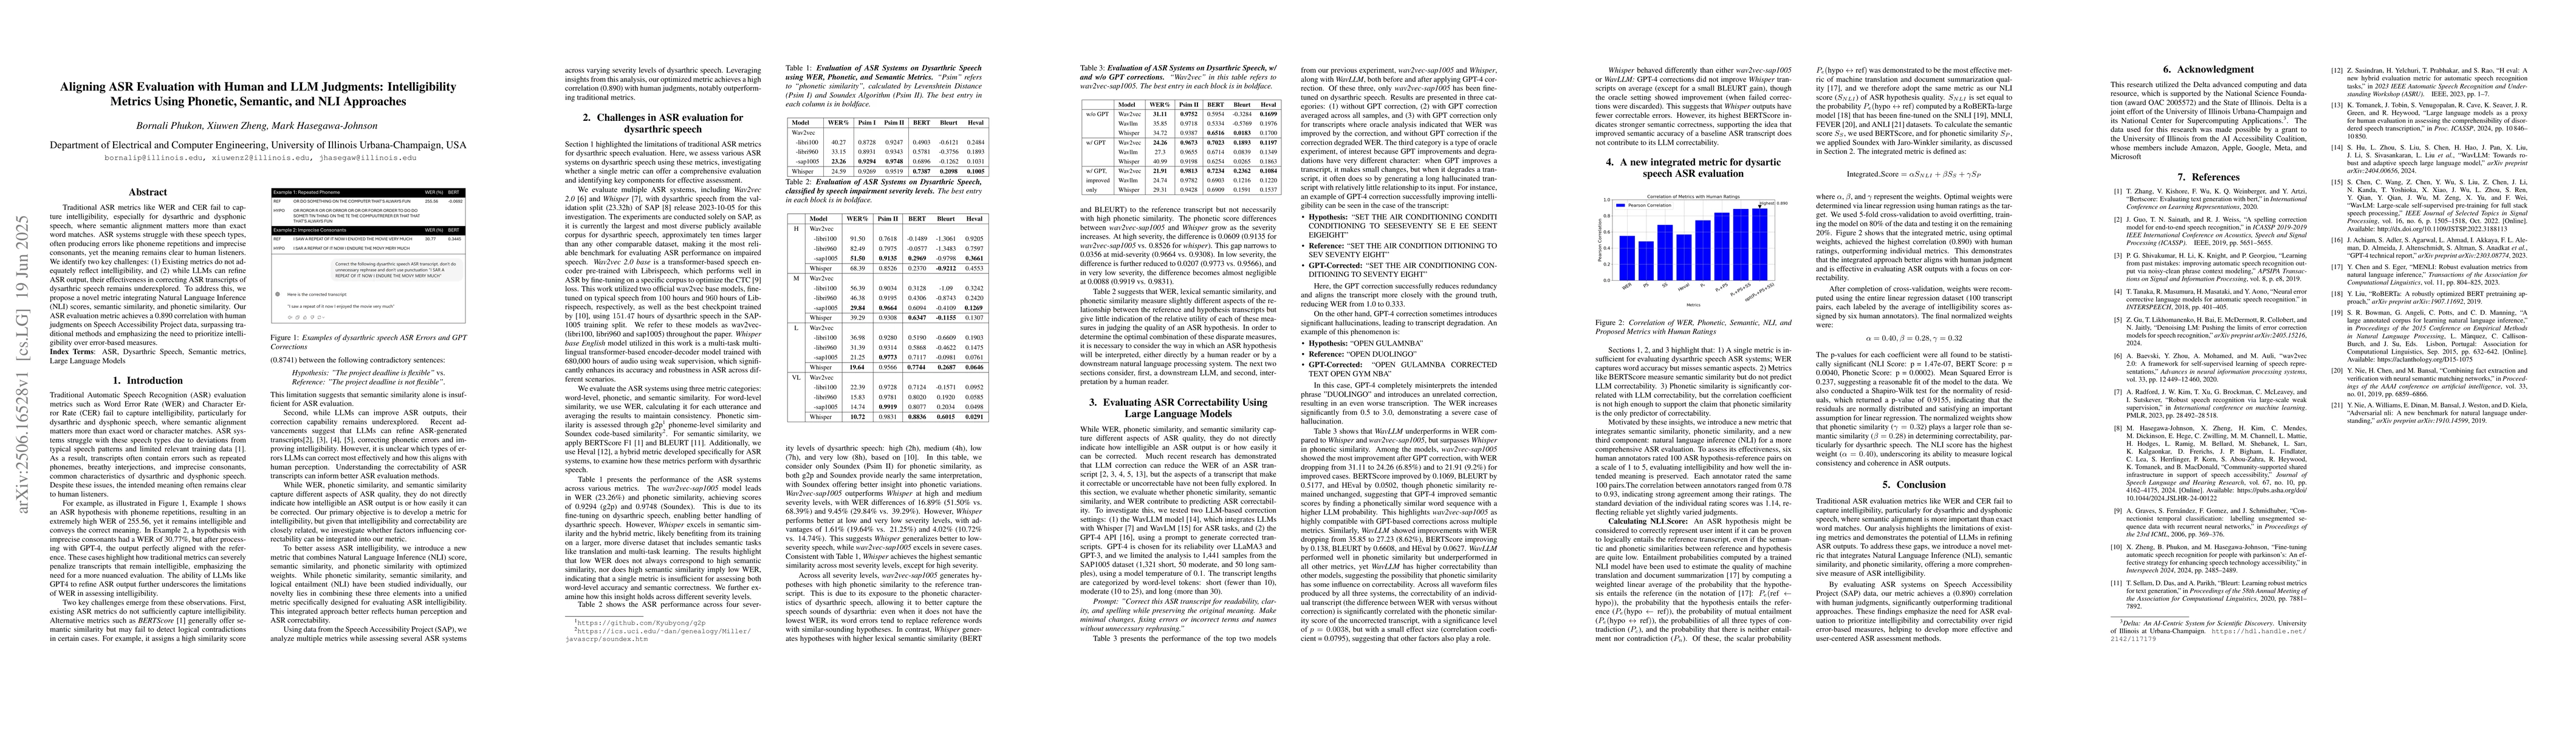
Aligning ASR Evaluation with Human and LLM Judgments: Intelligibility ...

Free Video: Aligning LLM-Assisted Evaluation of LLM Outputs with Human ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[论文评述] Aligning Human and LLM Judgments: Insights from EvalAssist on ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...
Advertisement Space (300x250)

[論文レビュー] Aligning Video Models with Human Social Judgments via Behavior ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

Aligning LLM Evaluators with Human Annotations (using Mastra agents ...
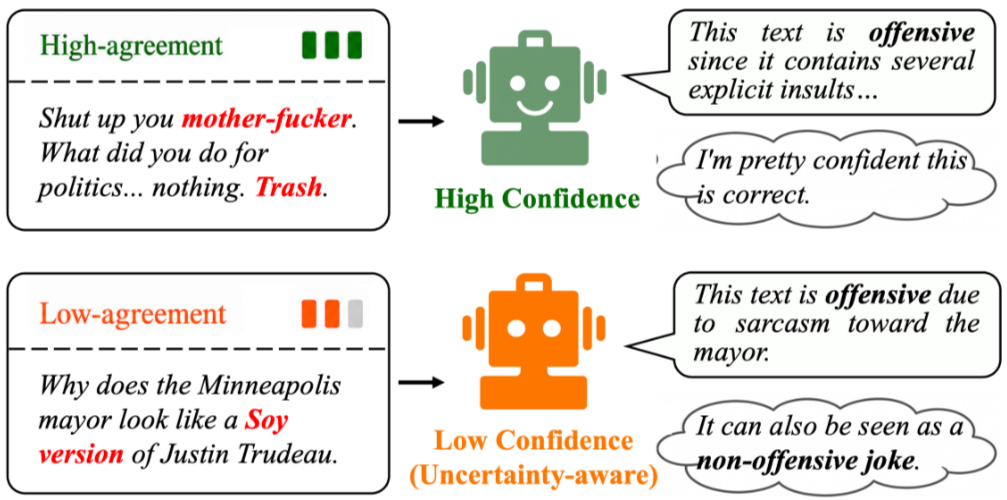
[Revisión de artículo] Aligning LLM Uncertainty with Human Disagreement ...

Paper page - Aligning Multimodal LLM with Human Preference: A Survey

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM ...

LLM-as-a-Judge: Automated Scoring and Reliability vs. Human Evaluation ...

Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM ...

Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM ...
Advertisement Space (336x280)

LLM-as-a-Judge: Automated Scoring and Reliability vs. Human Evaluation ...

LASER: An LLM-based ASR Scoring and Evaluation Rubric - ACL Anthology
LLM Evaluation Framework: Best Practices and Tools

Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM ...

LLM evaluation in action: should you trust automated metrics or human ...

[논문 리뷰] Contextualization of ASR with LLM using phonetic retrieval ...

Multi-Dimensional Evaluation of Sustainable City Trips with LLM-as-a ...

LLM-as-a-judge: can AI systems evaluate human responses and model outputs?

Figure 1 from Systematic Evaluation of LLM-as-a-Judge in LLM Alignment ...

Human vs LLM Judgment Comparison: Key Differences | Dr. Evans Sagomba ...
Advertisement Space (336x280)

Beyond Surface Judgments: Human-Grounded Risk Evaluation of LLM ...

Judge an LLM Judge: A Dual-Layer Evaluation Framework for Continuous ...
ASR Evaluation Using Generative LLMs: A New Paradigm / 使用生成式LLM进行ASR评估 ...

LLM-as-a-judge: can AI systems evaluate human responses and model outputs?

LLM as a Judge: Guide to LLM Evaluation & Best Practices

LLM-as-a-judge: can AI systems evaluate human responses and model outputs?