
Aligning Human And Llm Judgments Insights From Evalassist On

[论文评述] Aligning Human and LLM Judgments: Insights from EvalAssist on ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...
Advertisement Space (300x250)

[2410.00873] Aligning Human and LLM Judgments: Insights from EvalAssist ...

(PDF) Aligning ASR Evaluation with Human and LLM Judgments ...

Aligning ASR Evaluation with Human and LLM Judgments: Intelligibility ...
Aligning ASR Evaluation with Human and LLM Judgments: Intelligibility ...

Modeling and automating human preferences for LLM evaluation

EvalAssist: Insights on Task-Specific Evaluations and AI-Assisted ...

Aligning LLM Evaluators with Human Annotations (using Mastra agents ...

Aligning LLM-Assisted Evaluation of LLM Outputs with Human Preferences ...

LLM Analytics and Insights | Hootsuite

Figure 1 from Systematic Evaluation of LLM-as-a-Judge in LLM Alignment ...
Advertisement Space (336x280)

Evaluating LLM Alignment With Human Trust Models | AI Research Paper ...

Human vs LLM Judgment Comparison: Key Differences | Dr. Evans Sagomba ...

Who's Your Judge? On the Detectability of LLM-Generated Judgments | AI ...

The explanation makes sense: An Empirical Study on LLM Performance in ...
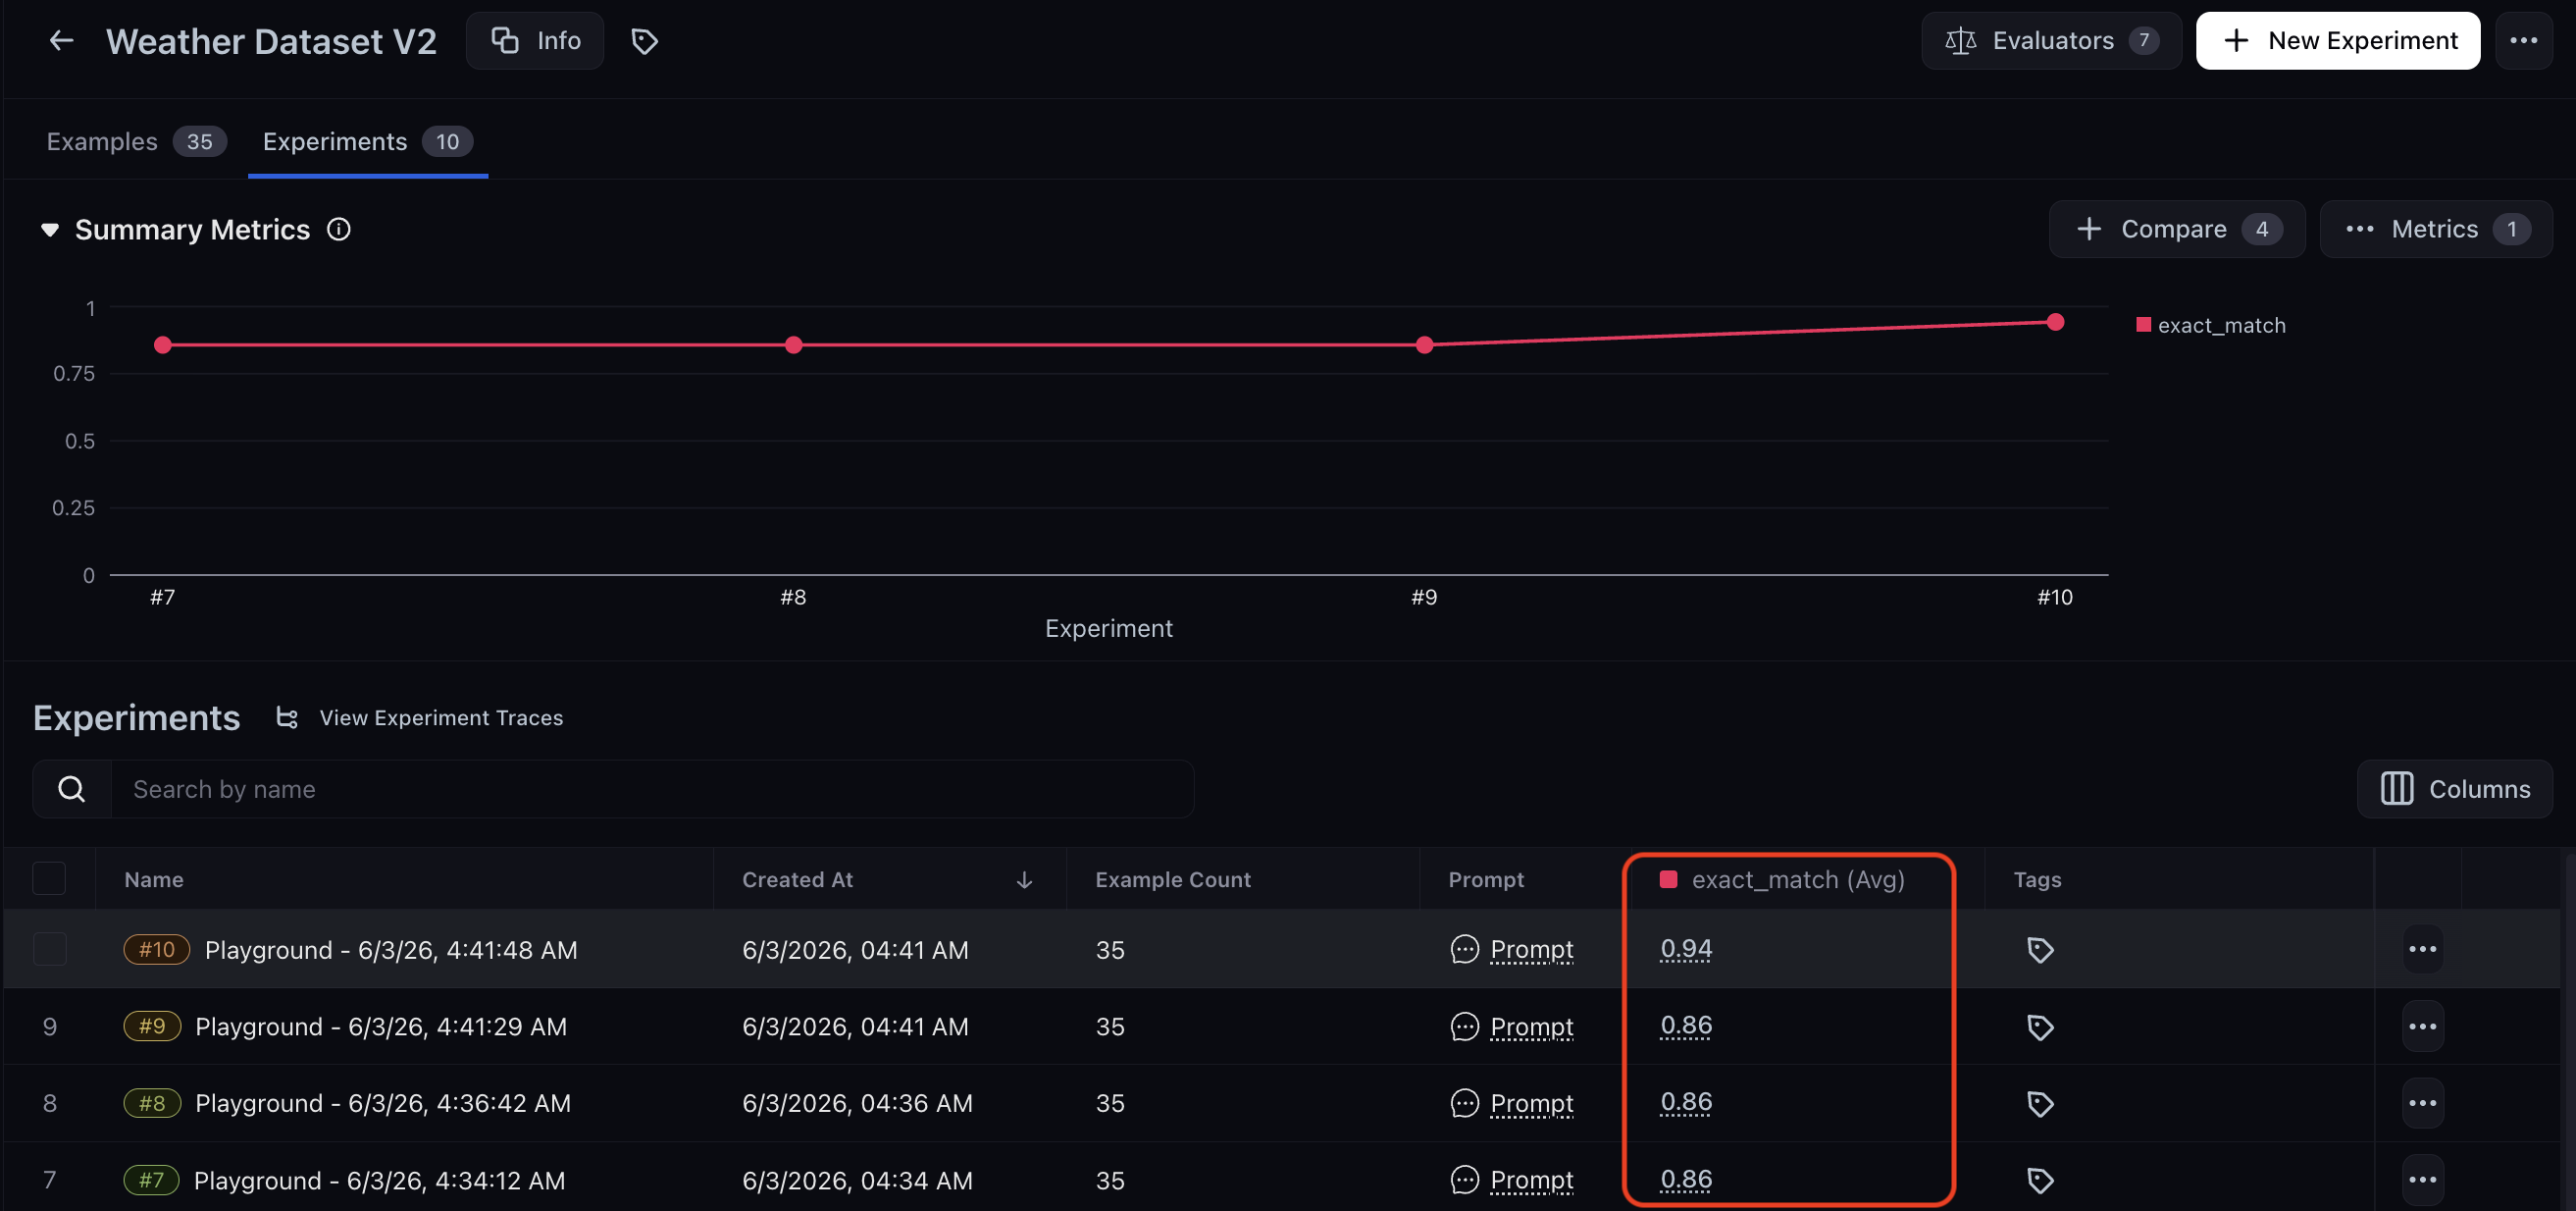
Align LLM Evals with Human Judgment - Arize AX Docs

Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM ...
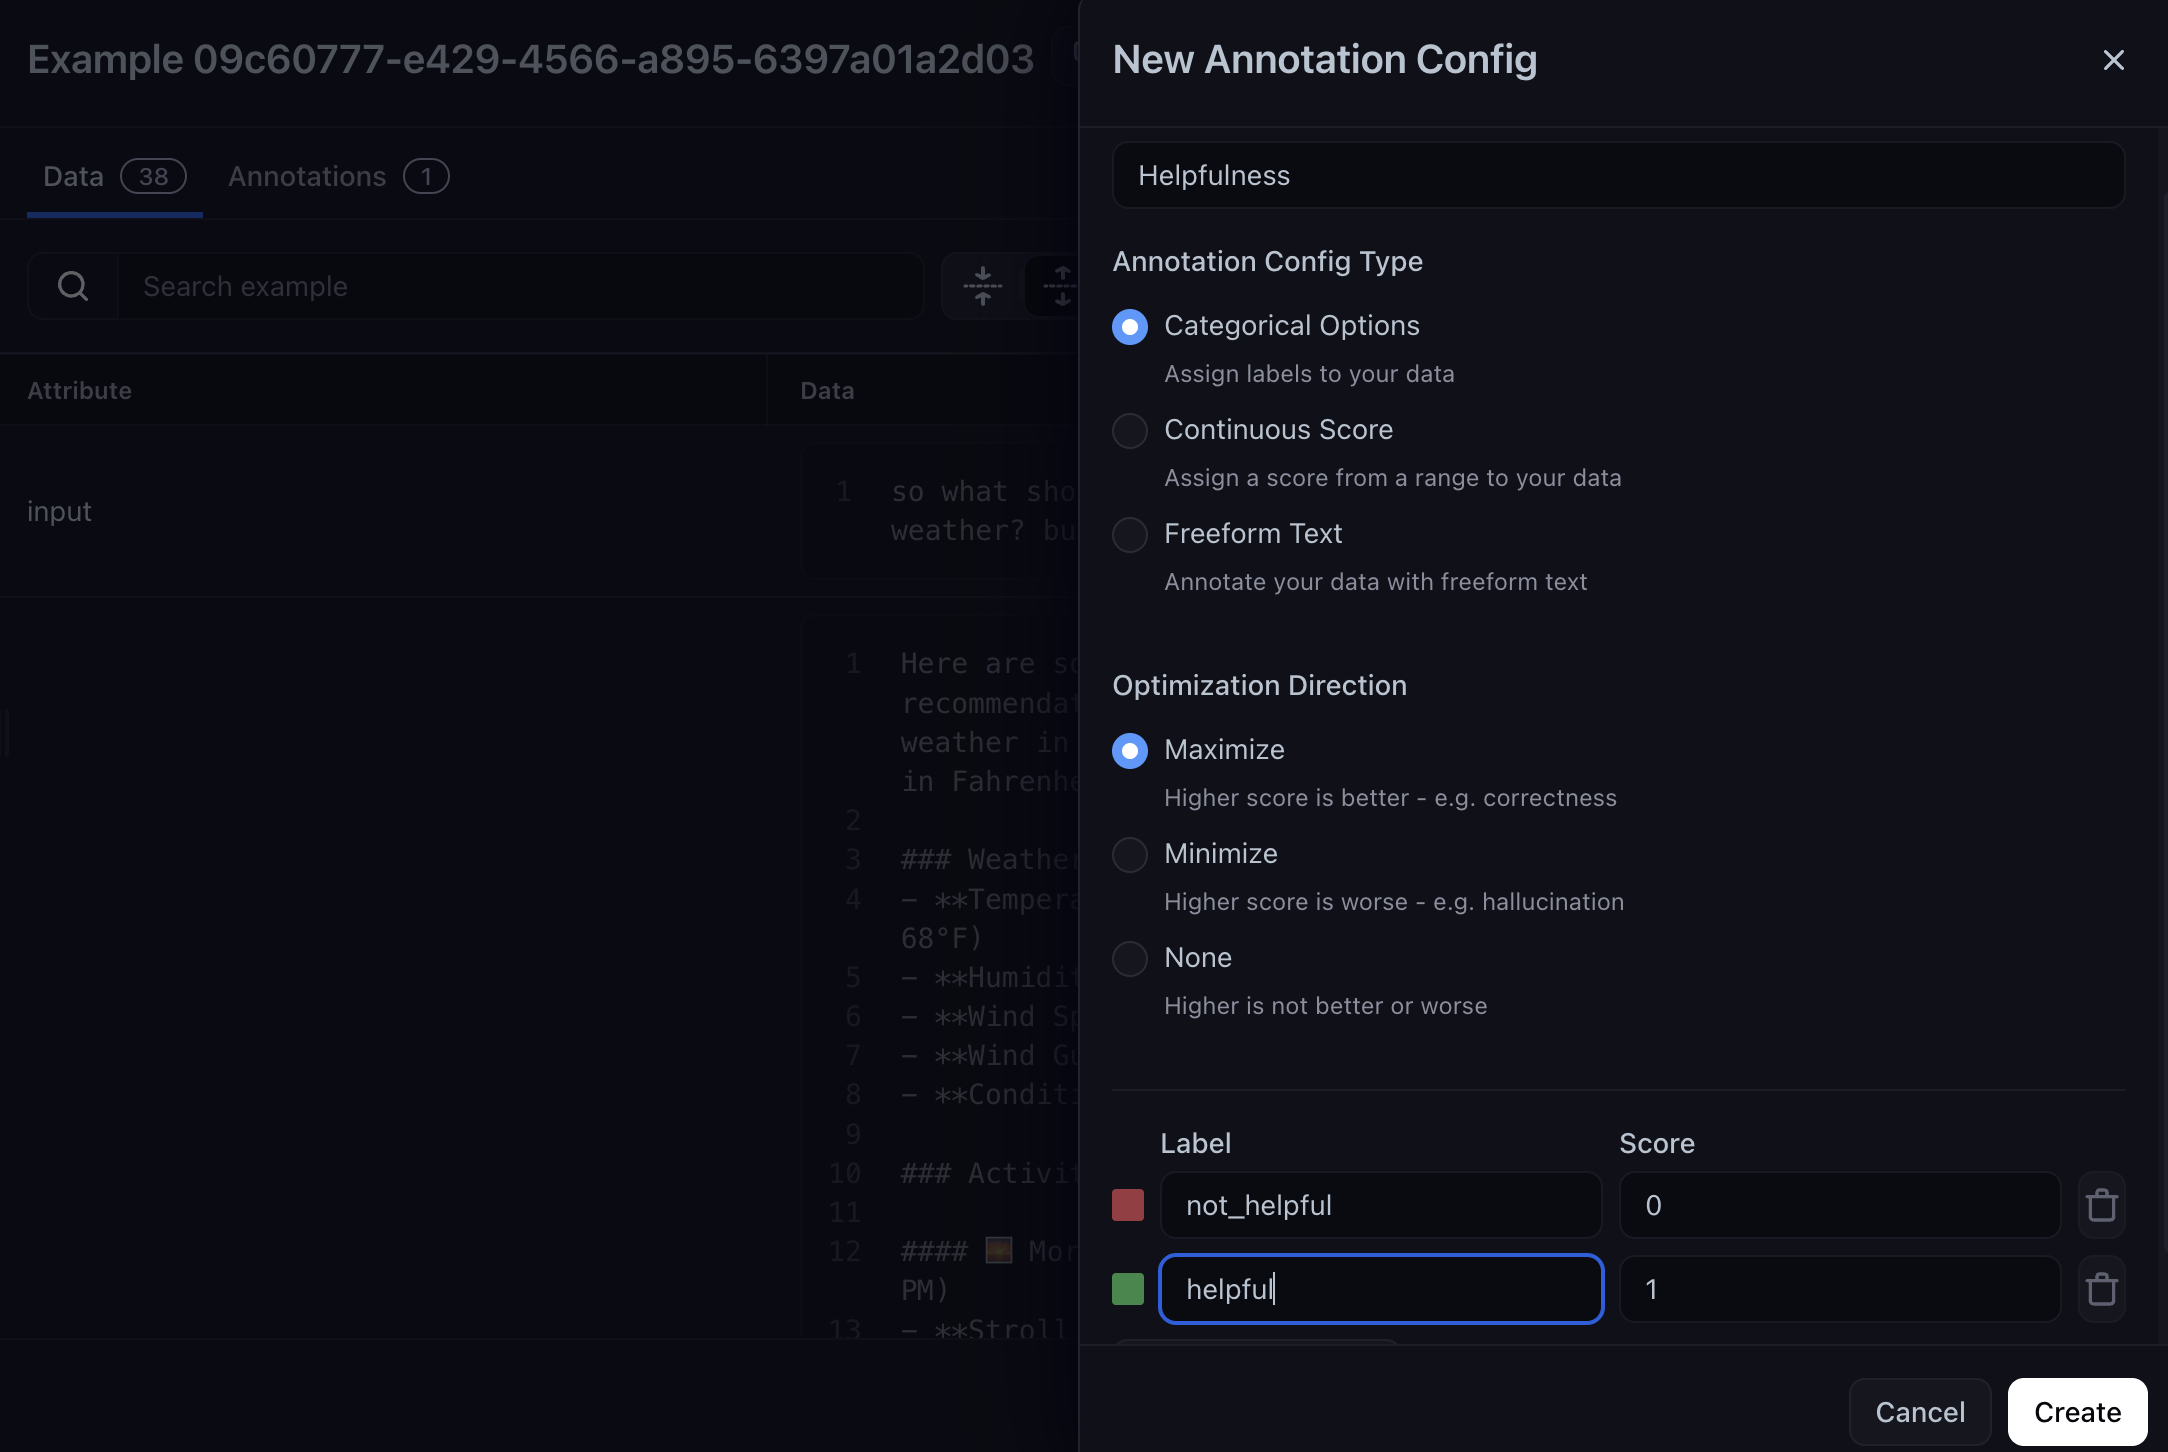
Align LLM Evals with Human Judgment - Arize AX Docs

LLM-as-a-Judge: Automated Scoring and Reliability vs. Human Evaluation ...

LLM evaluation in action: should you trust automated metrics or human ...
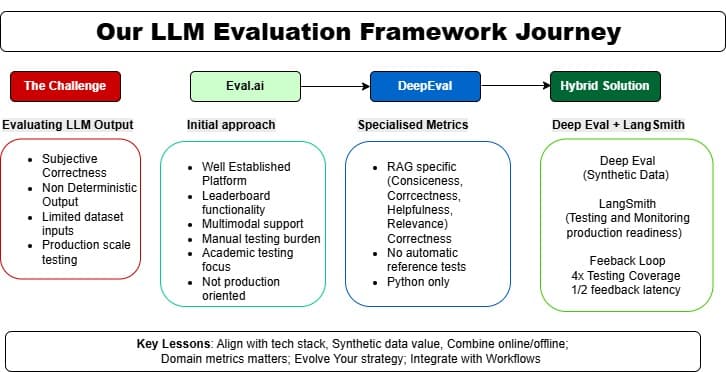
Decode LLM Quality - Eval Testing and Benchmarking LLMs: An Evaluation ...
Advertisement Space (336x280)

Can LLM Agents Drive Like Human Beings? Benchmarks, Feature ...

LLM-as-a-Judge: Automated Scoring and Reliability vs. Human Evaluation ...

How to Calibrate Your LLM Judge With Human Annotations

[Literature Review] RLTHF: Targeted Human Feedback for LLM Alignment

From Generation to Judgment: Opportunities and Challenges of LLM-as-a ...

LLM-as-Judge: Insights and Pipeline | PDF | Evaluation | Learning