
Autoscale Llm Inference Endpoints With Vllm And Kserve Atomic Loops
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops
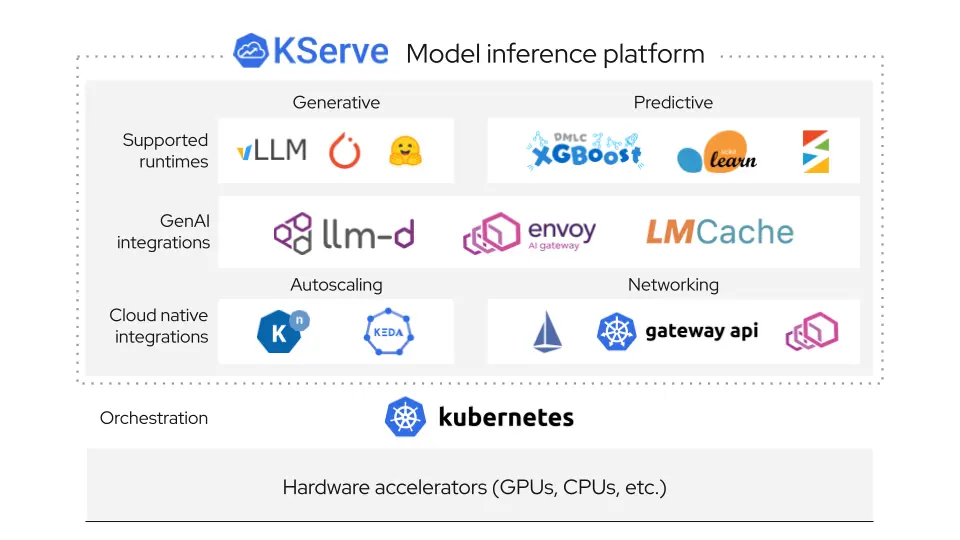
Production-Grade LLM Inference at Scale with KServe, llm-d, and vLLM ...

Serve High-Throughput Factory LLMs with vLLM and BentoML | Atomic Loops

Production-Grade LLM Inference at Scale with KServe, llm-d, and vLLM ...
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
Free Video: Improve AI Inference - Serving Models With KServe and VLLM ...

Scaling LLM inference with Ray and vLLM
Production-Grade LLM Inference at Scale with KServe, llm-d, and vLLM ...

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
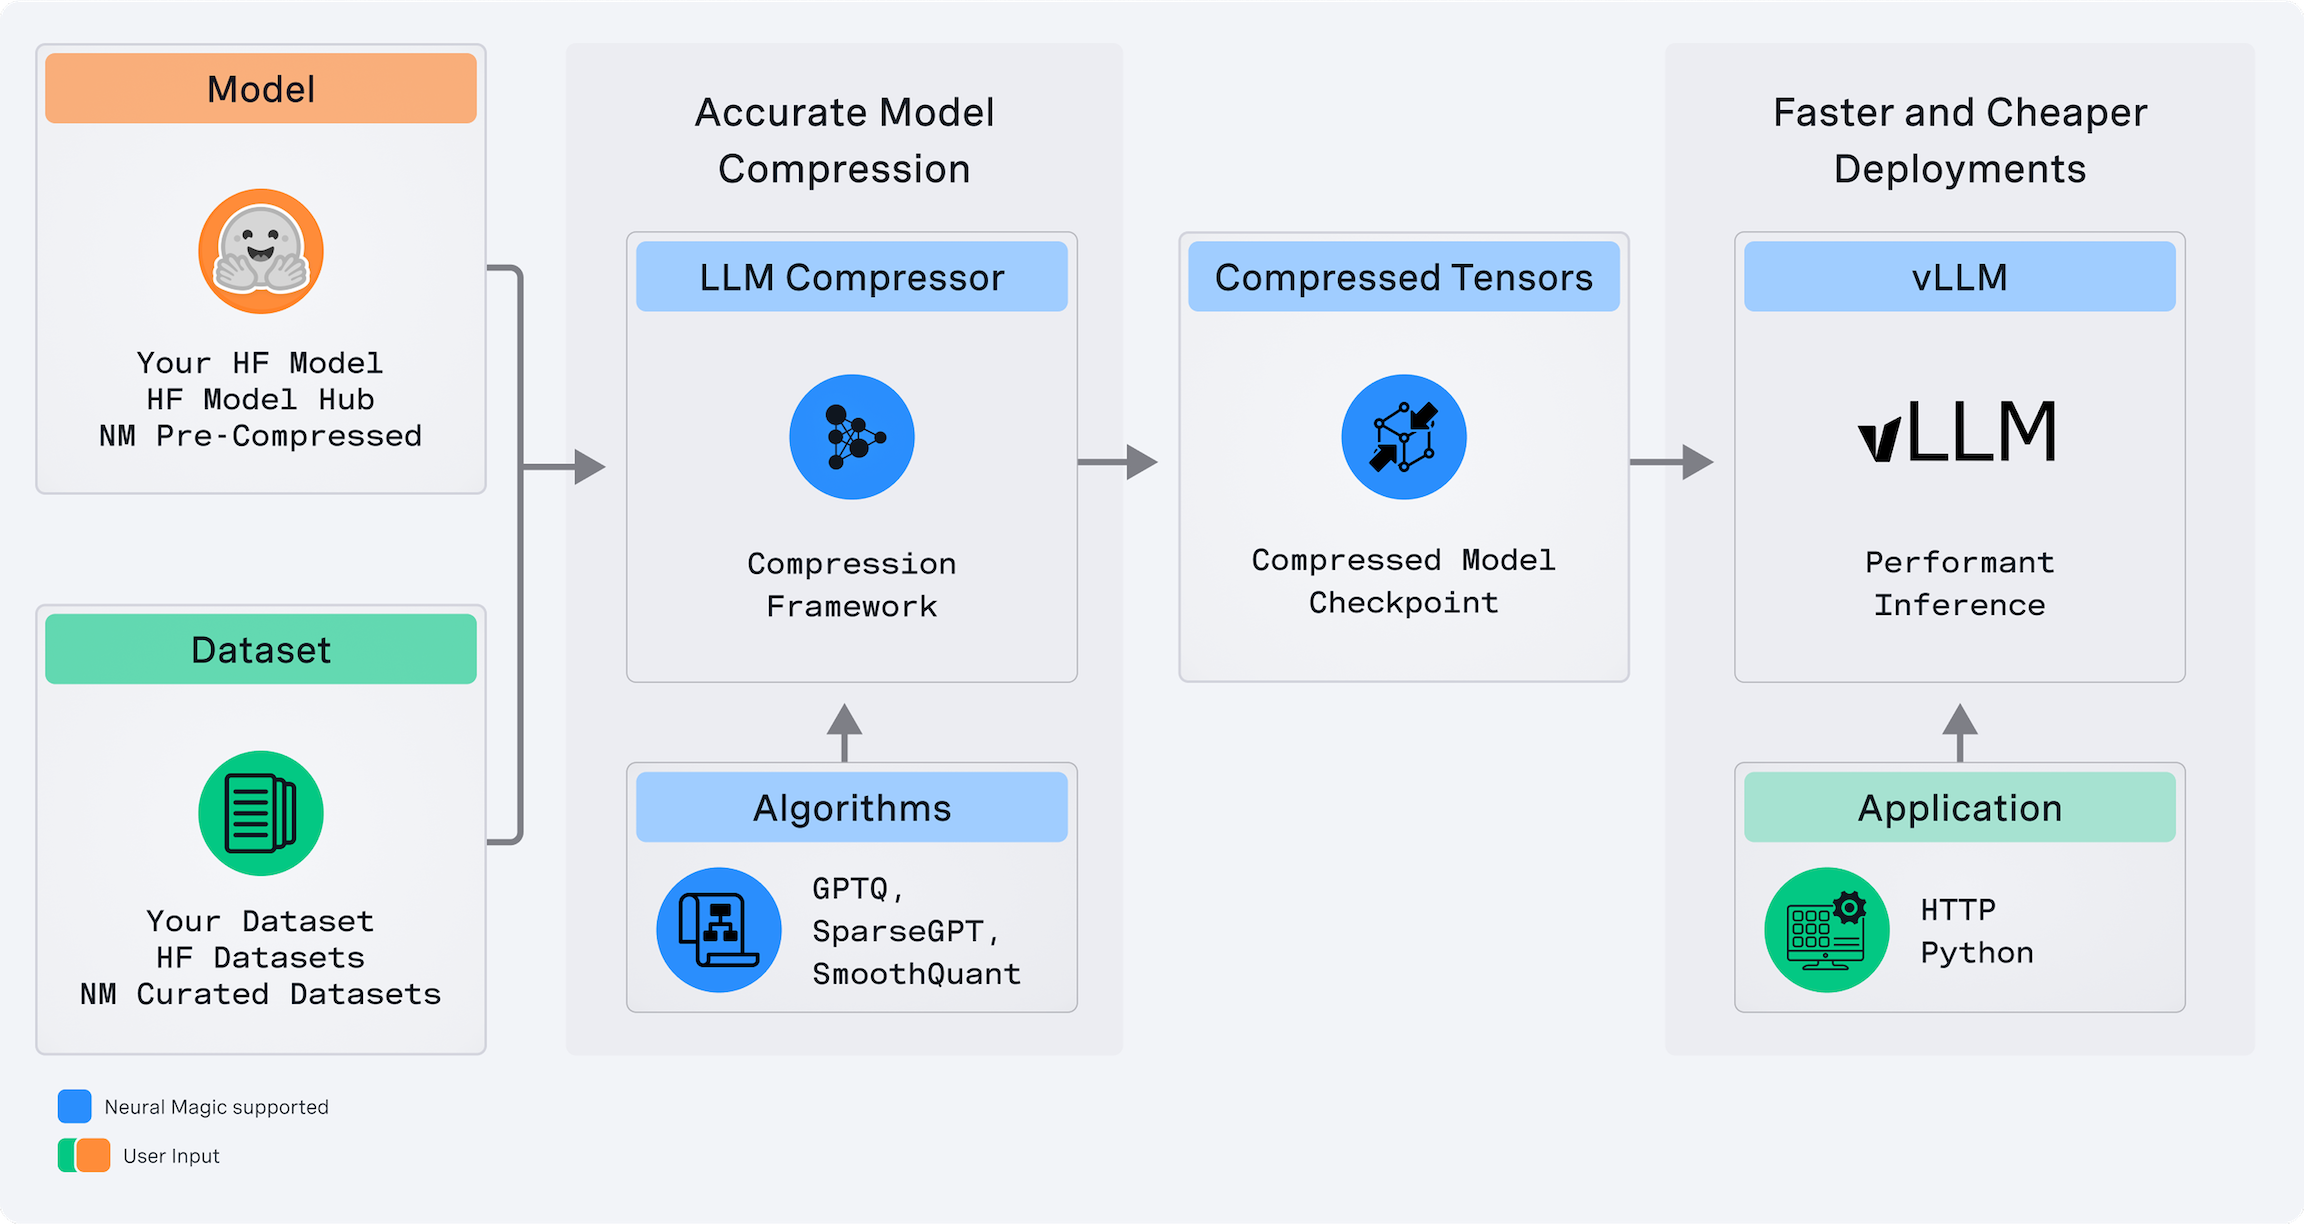
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
Advertisement Space (300x250)

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

Getting Started with vLLM: Fast and Efficient LLM Inference | by Wenyi ...

An End‑to‑End View of AI Inference Stacks with vLLM and Alternatives

Accelerating LLM Inference with vLLM - YouTube

Accelerating LLM and VLM Inference for Automotive and Robotics with ...
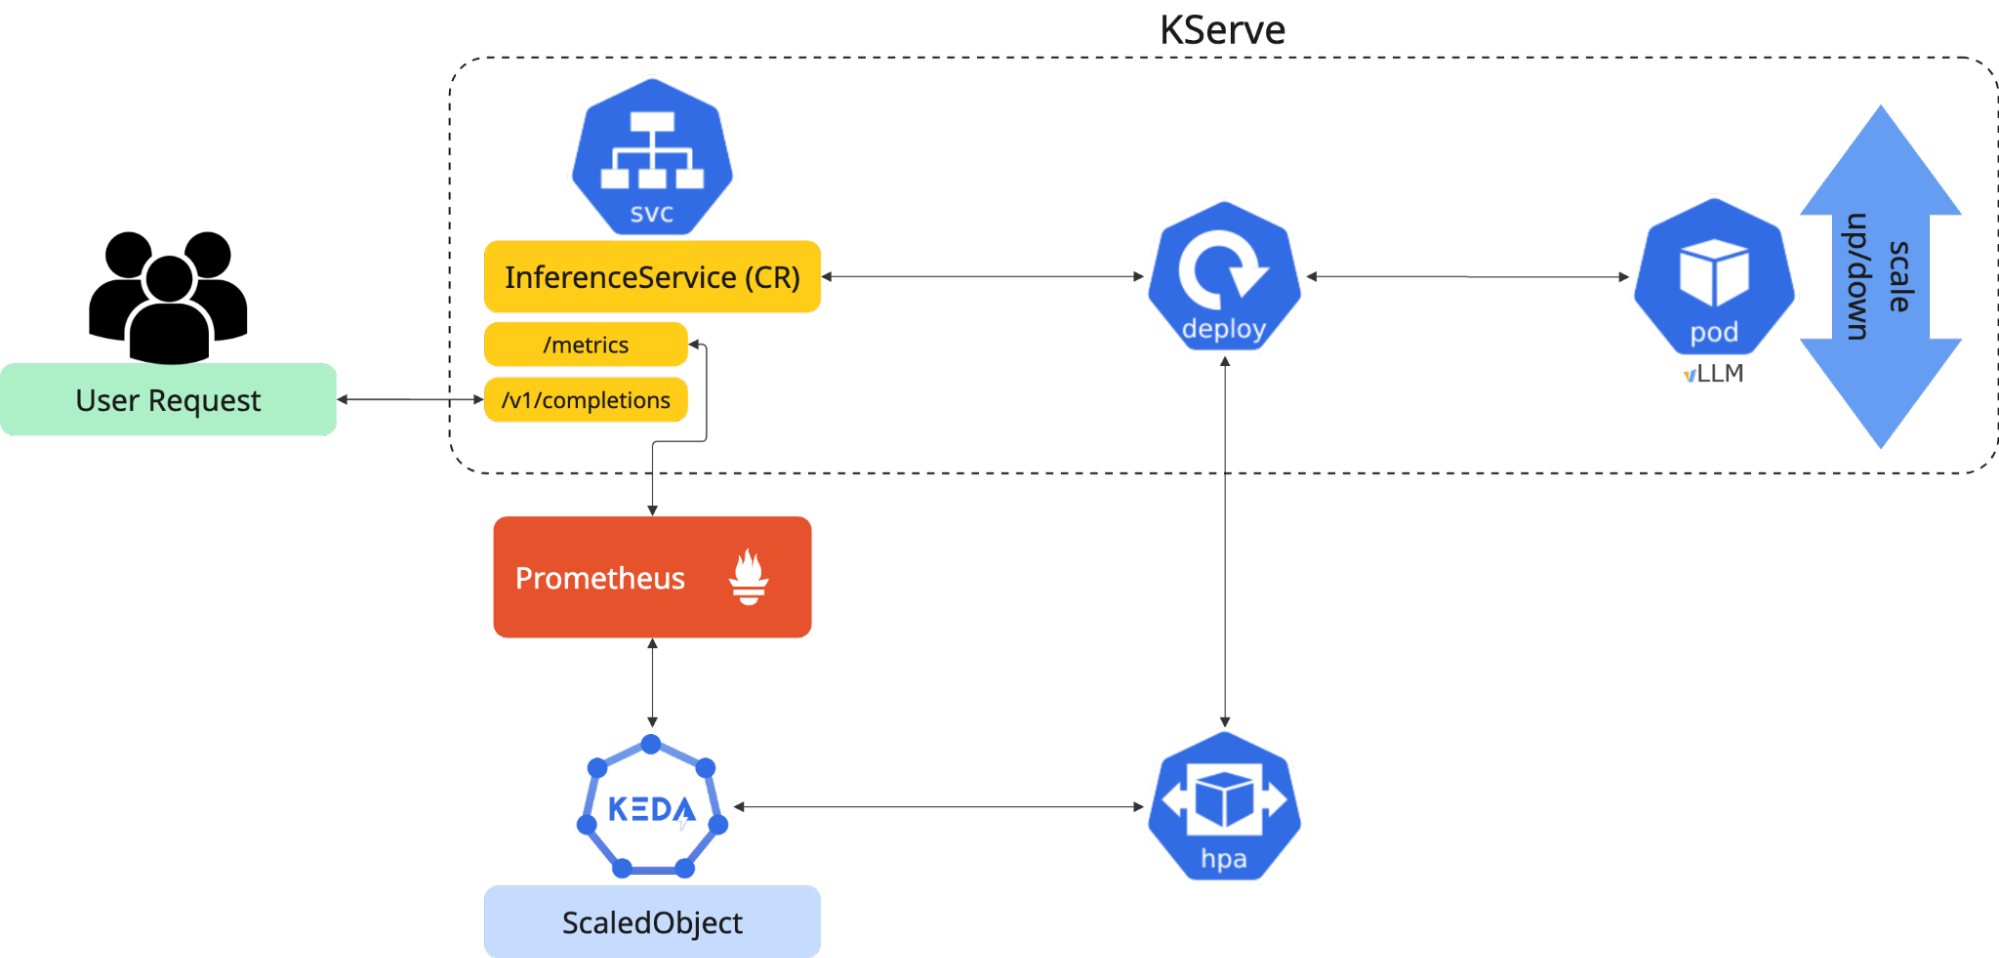
How to set up KServe autoscaling for vLLM with KEDA | Red Hat Developer

Building Production LLM Infrastructure with KServe v0.15 | by Simardeep ...
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
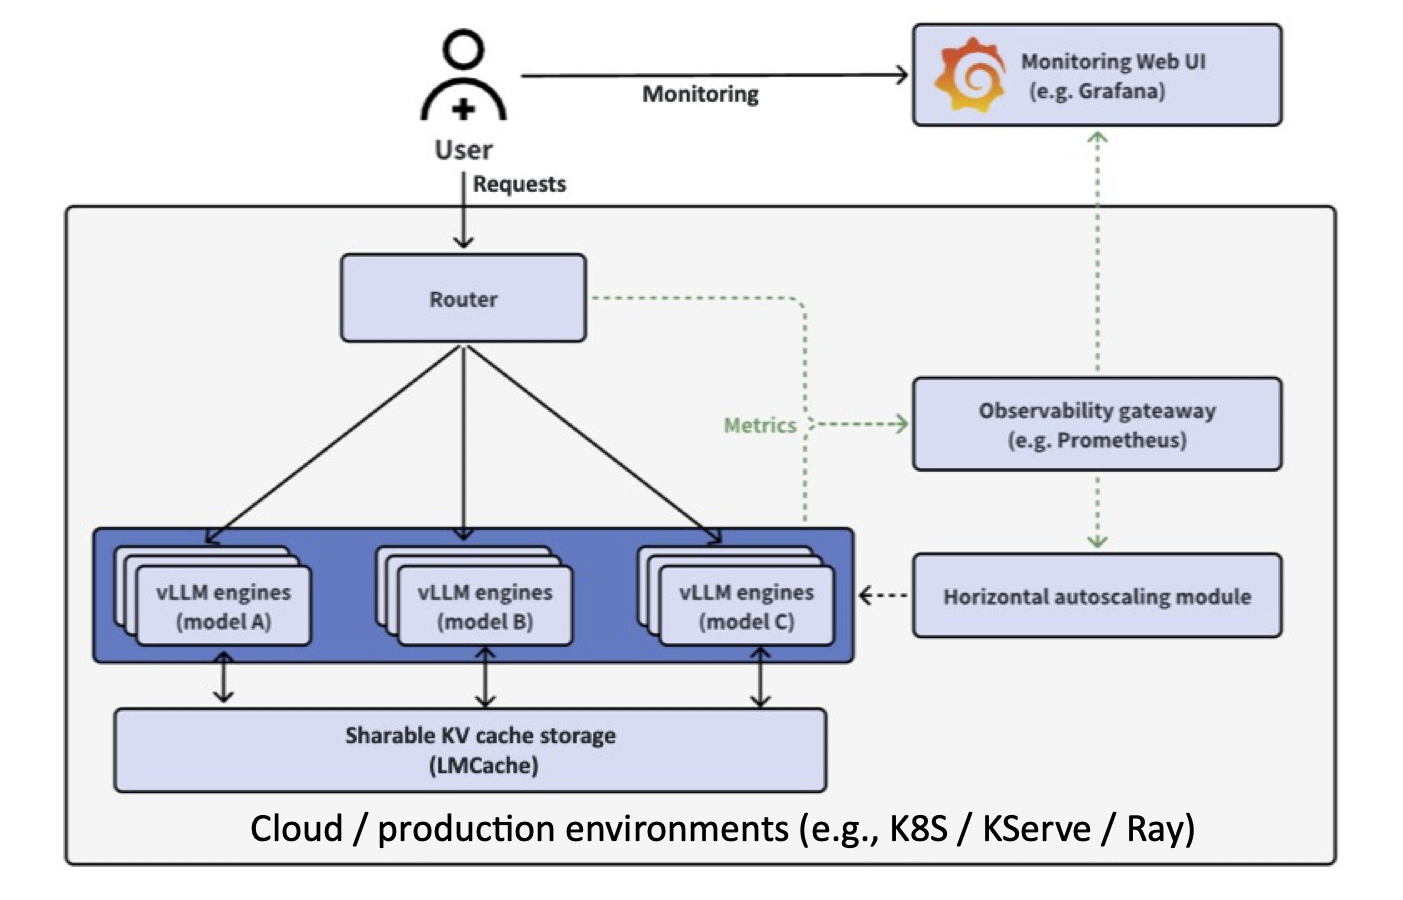
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...
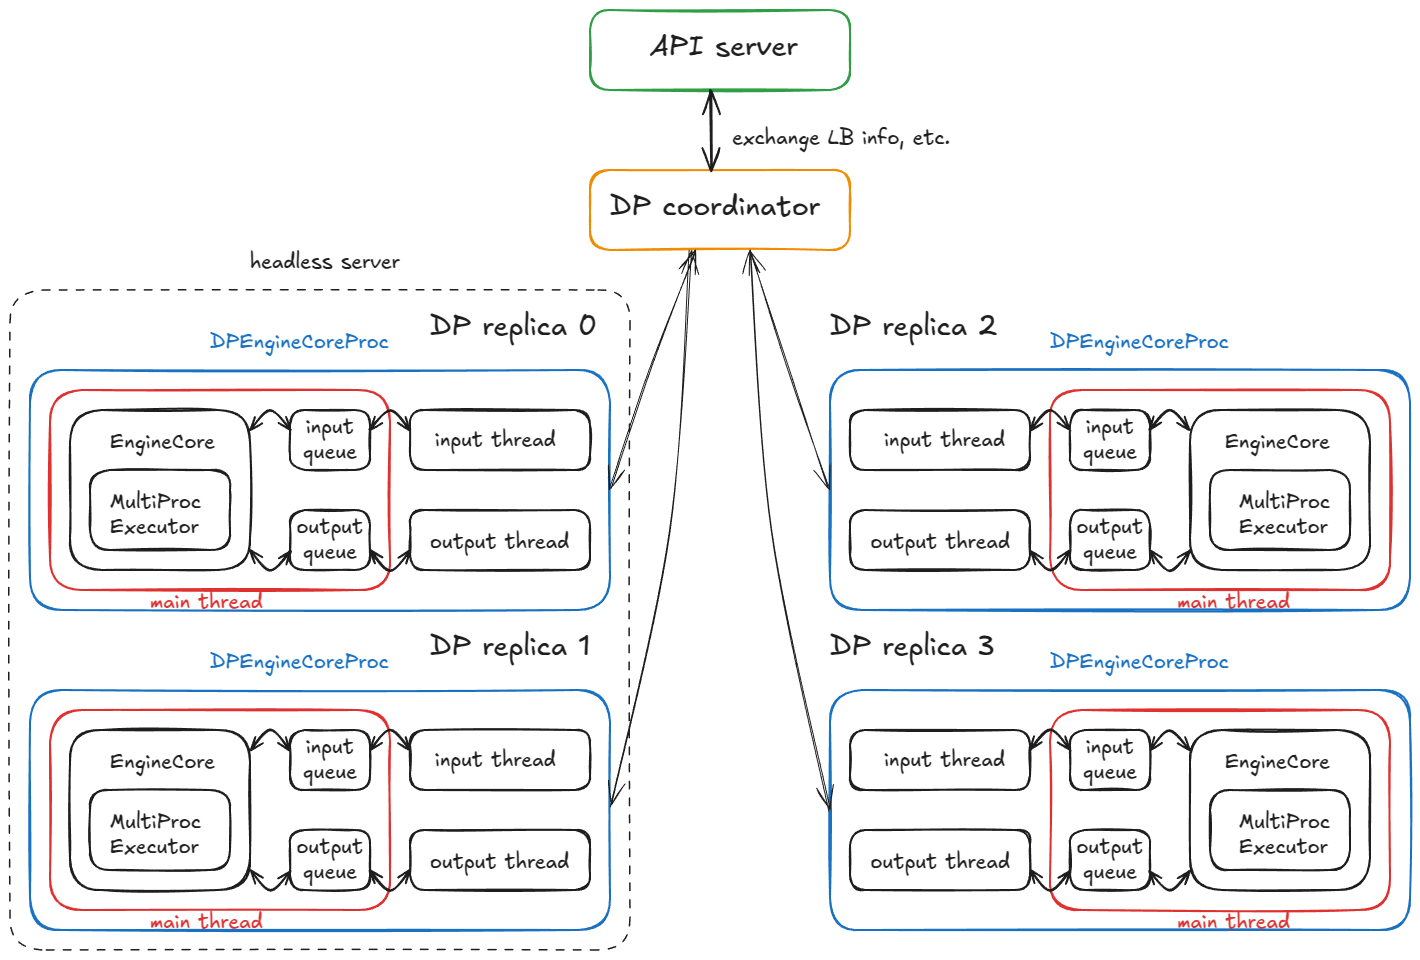
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
Advertisement Space (336x280)
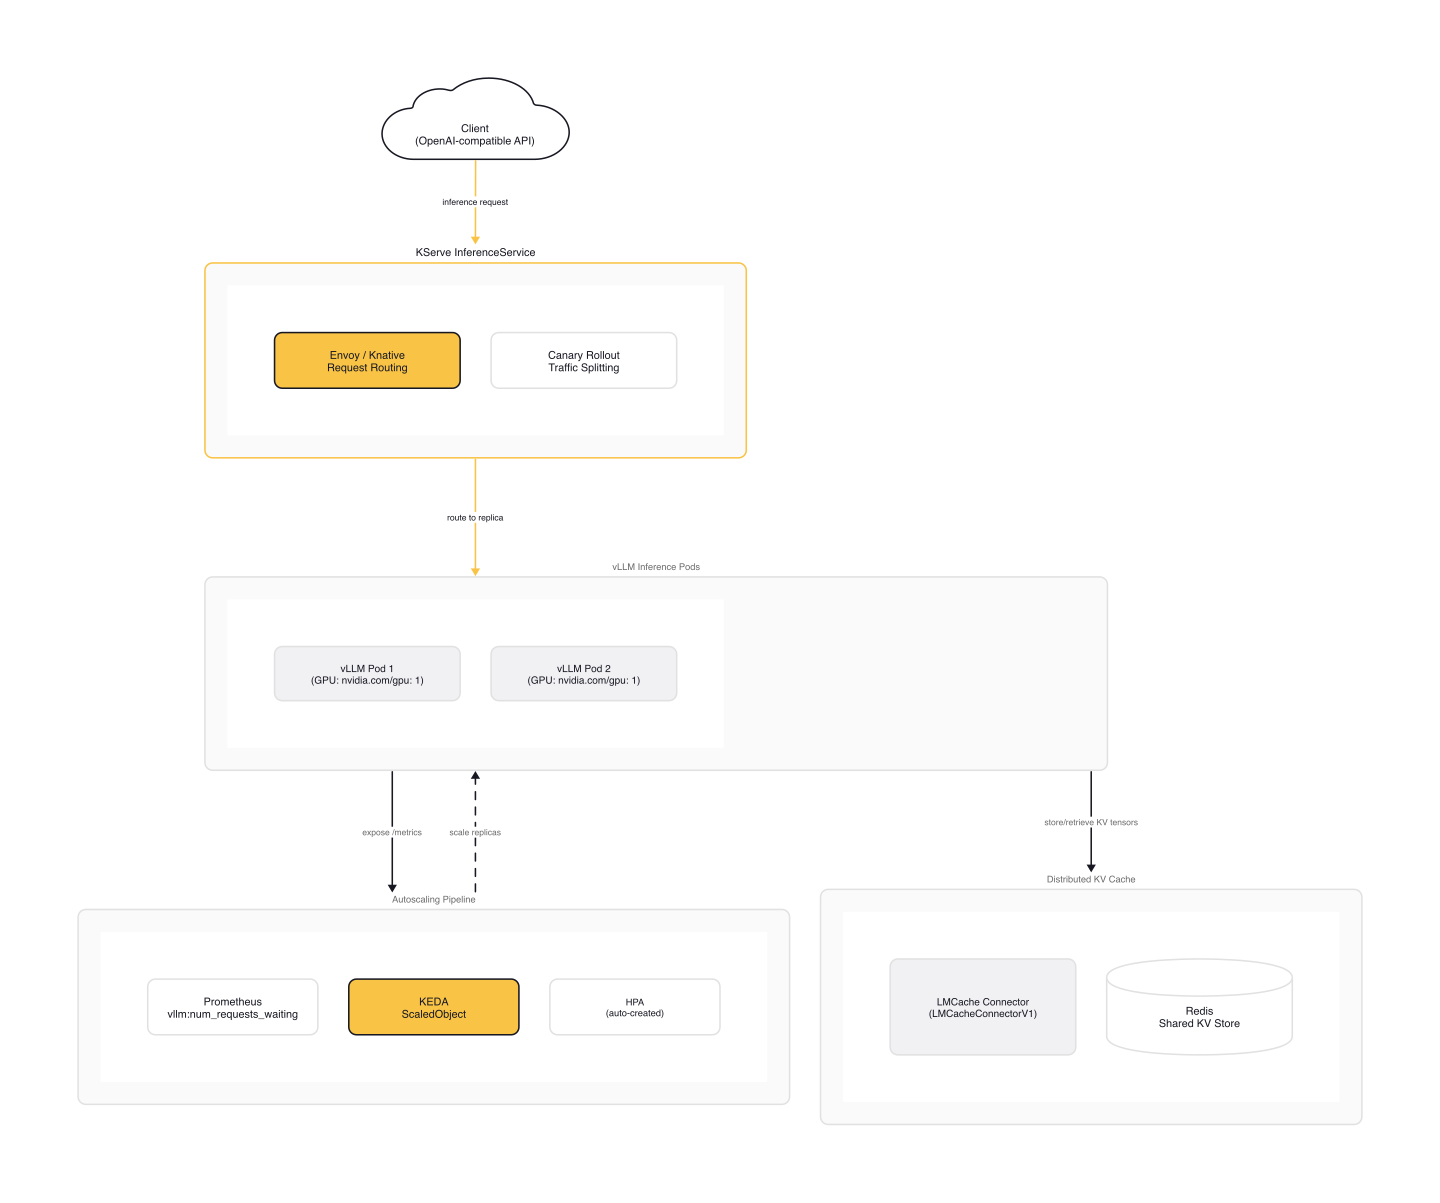
Production LLM Serving on Kubernetes: vLLM + KServe Stack — KubeDojo
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
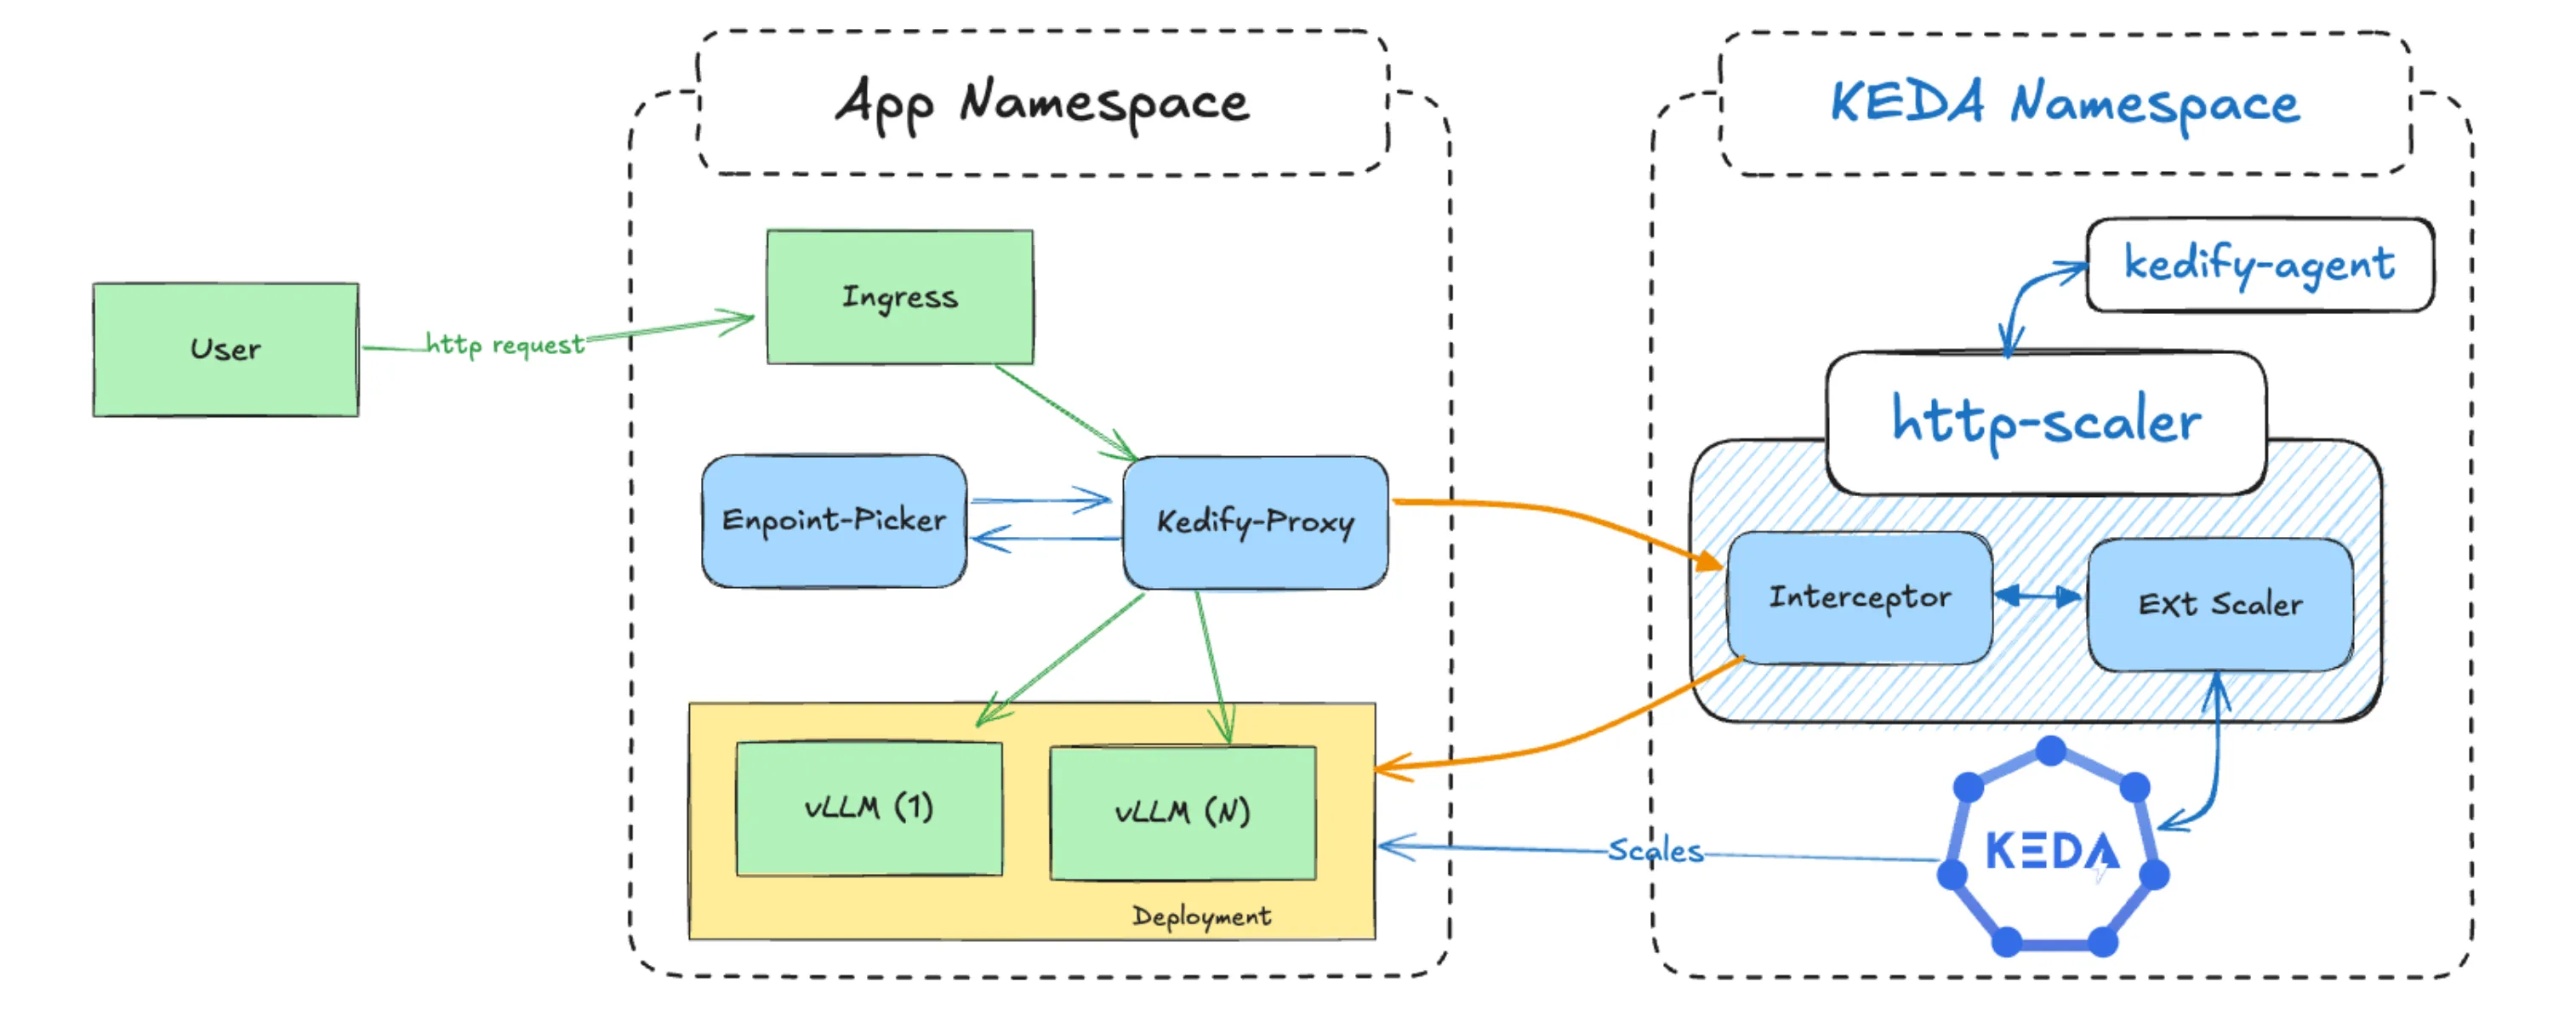
How to Autoscale GPU and LLM Workloads on Kubernetes | Kedify
Autoscaling LLM Inference Endpoints
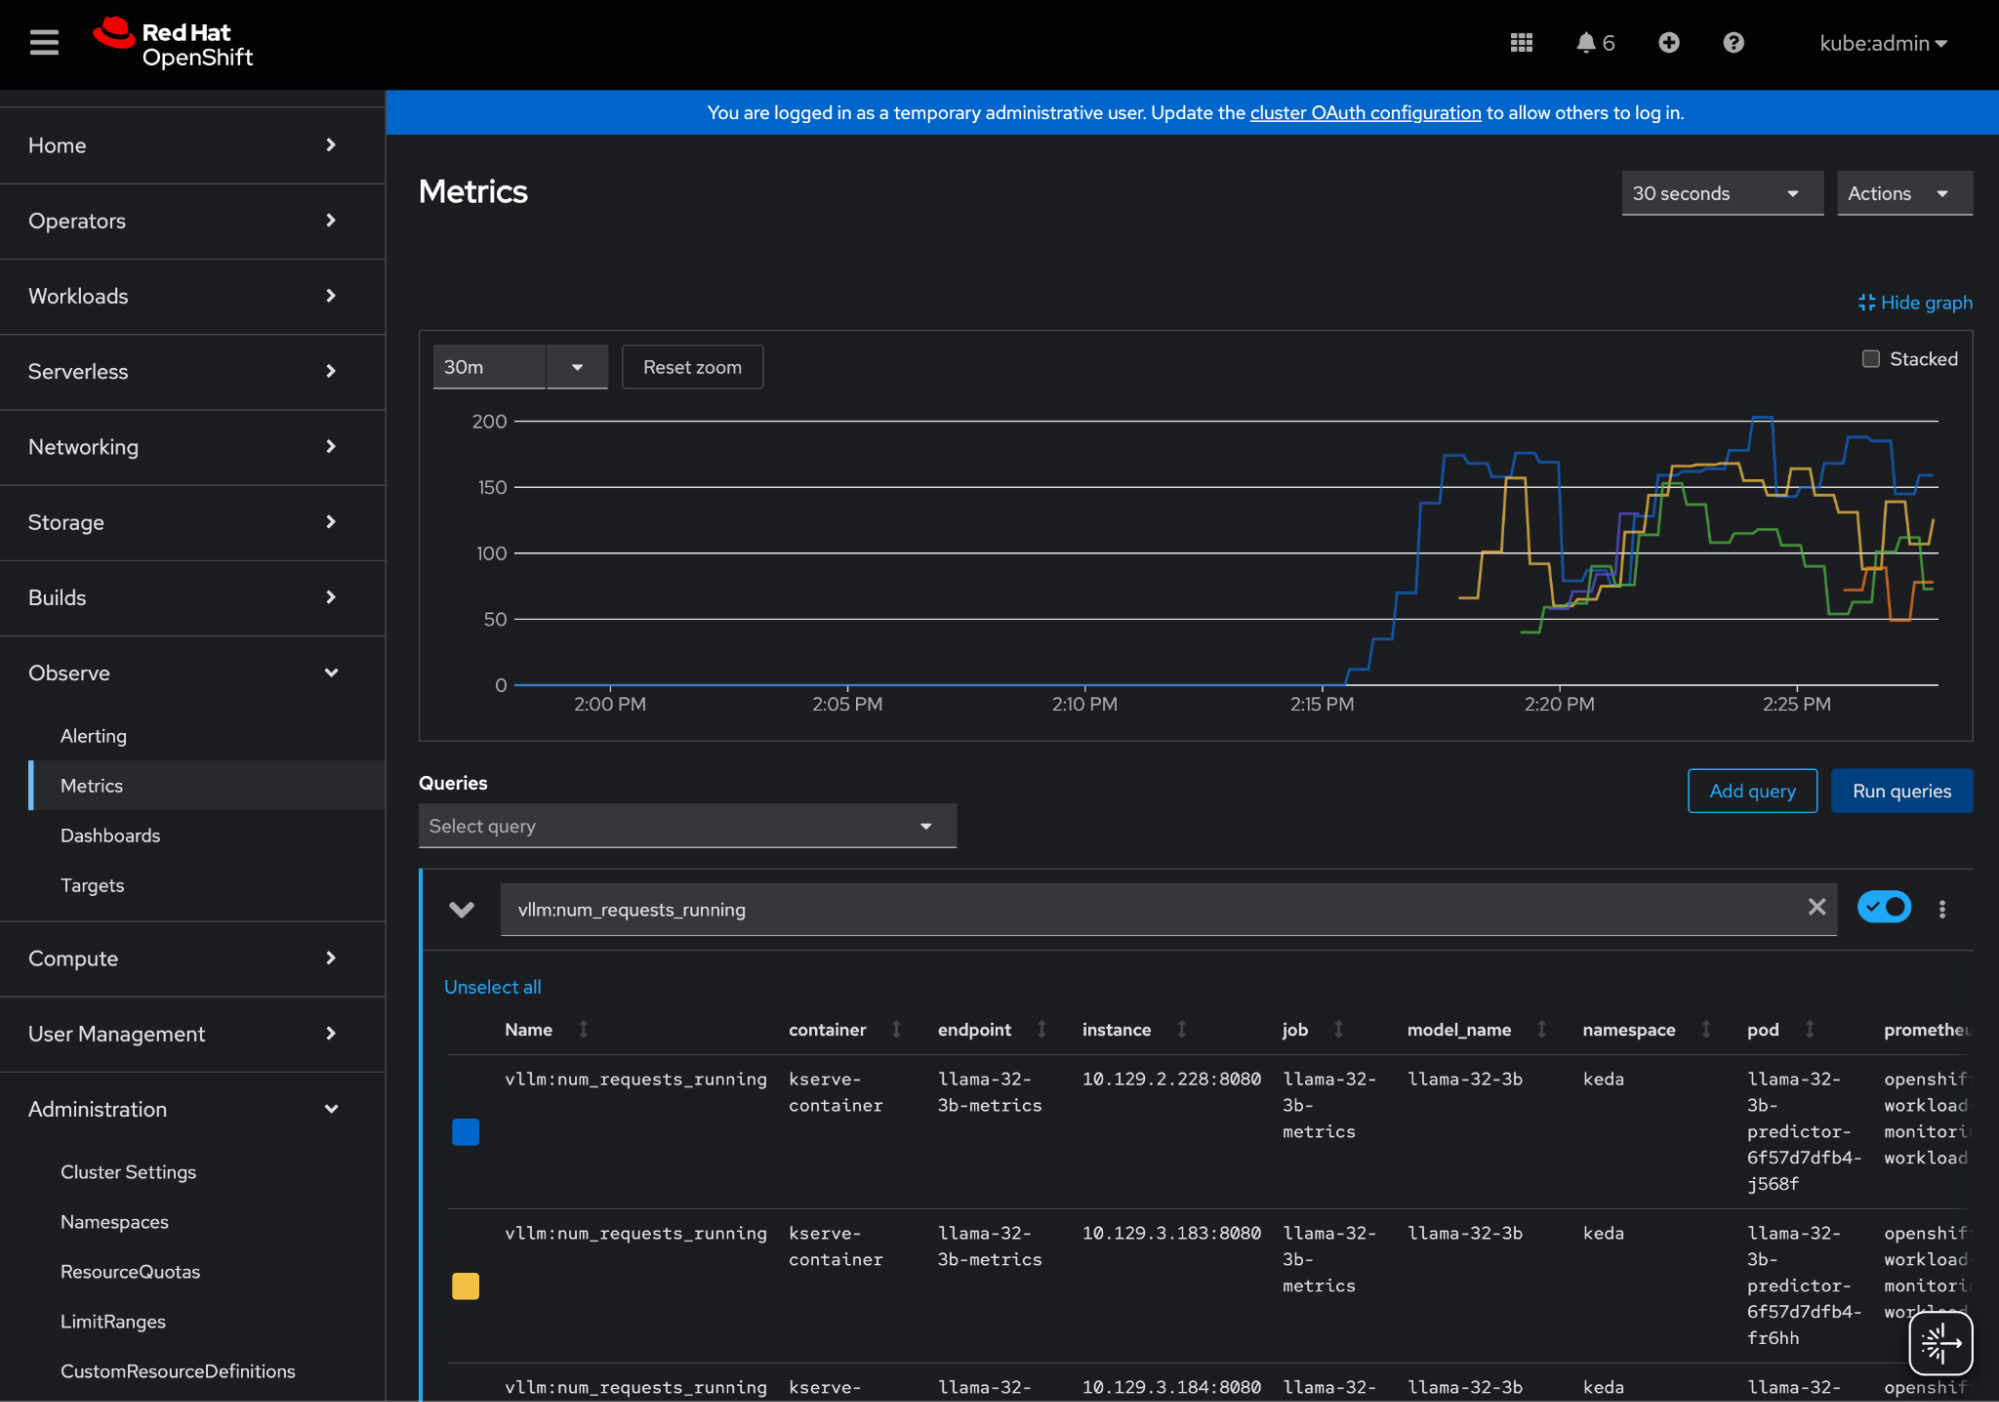
How to set up KServe autoscaling for vLLM with KEDA | Red Hat Developer
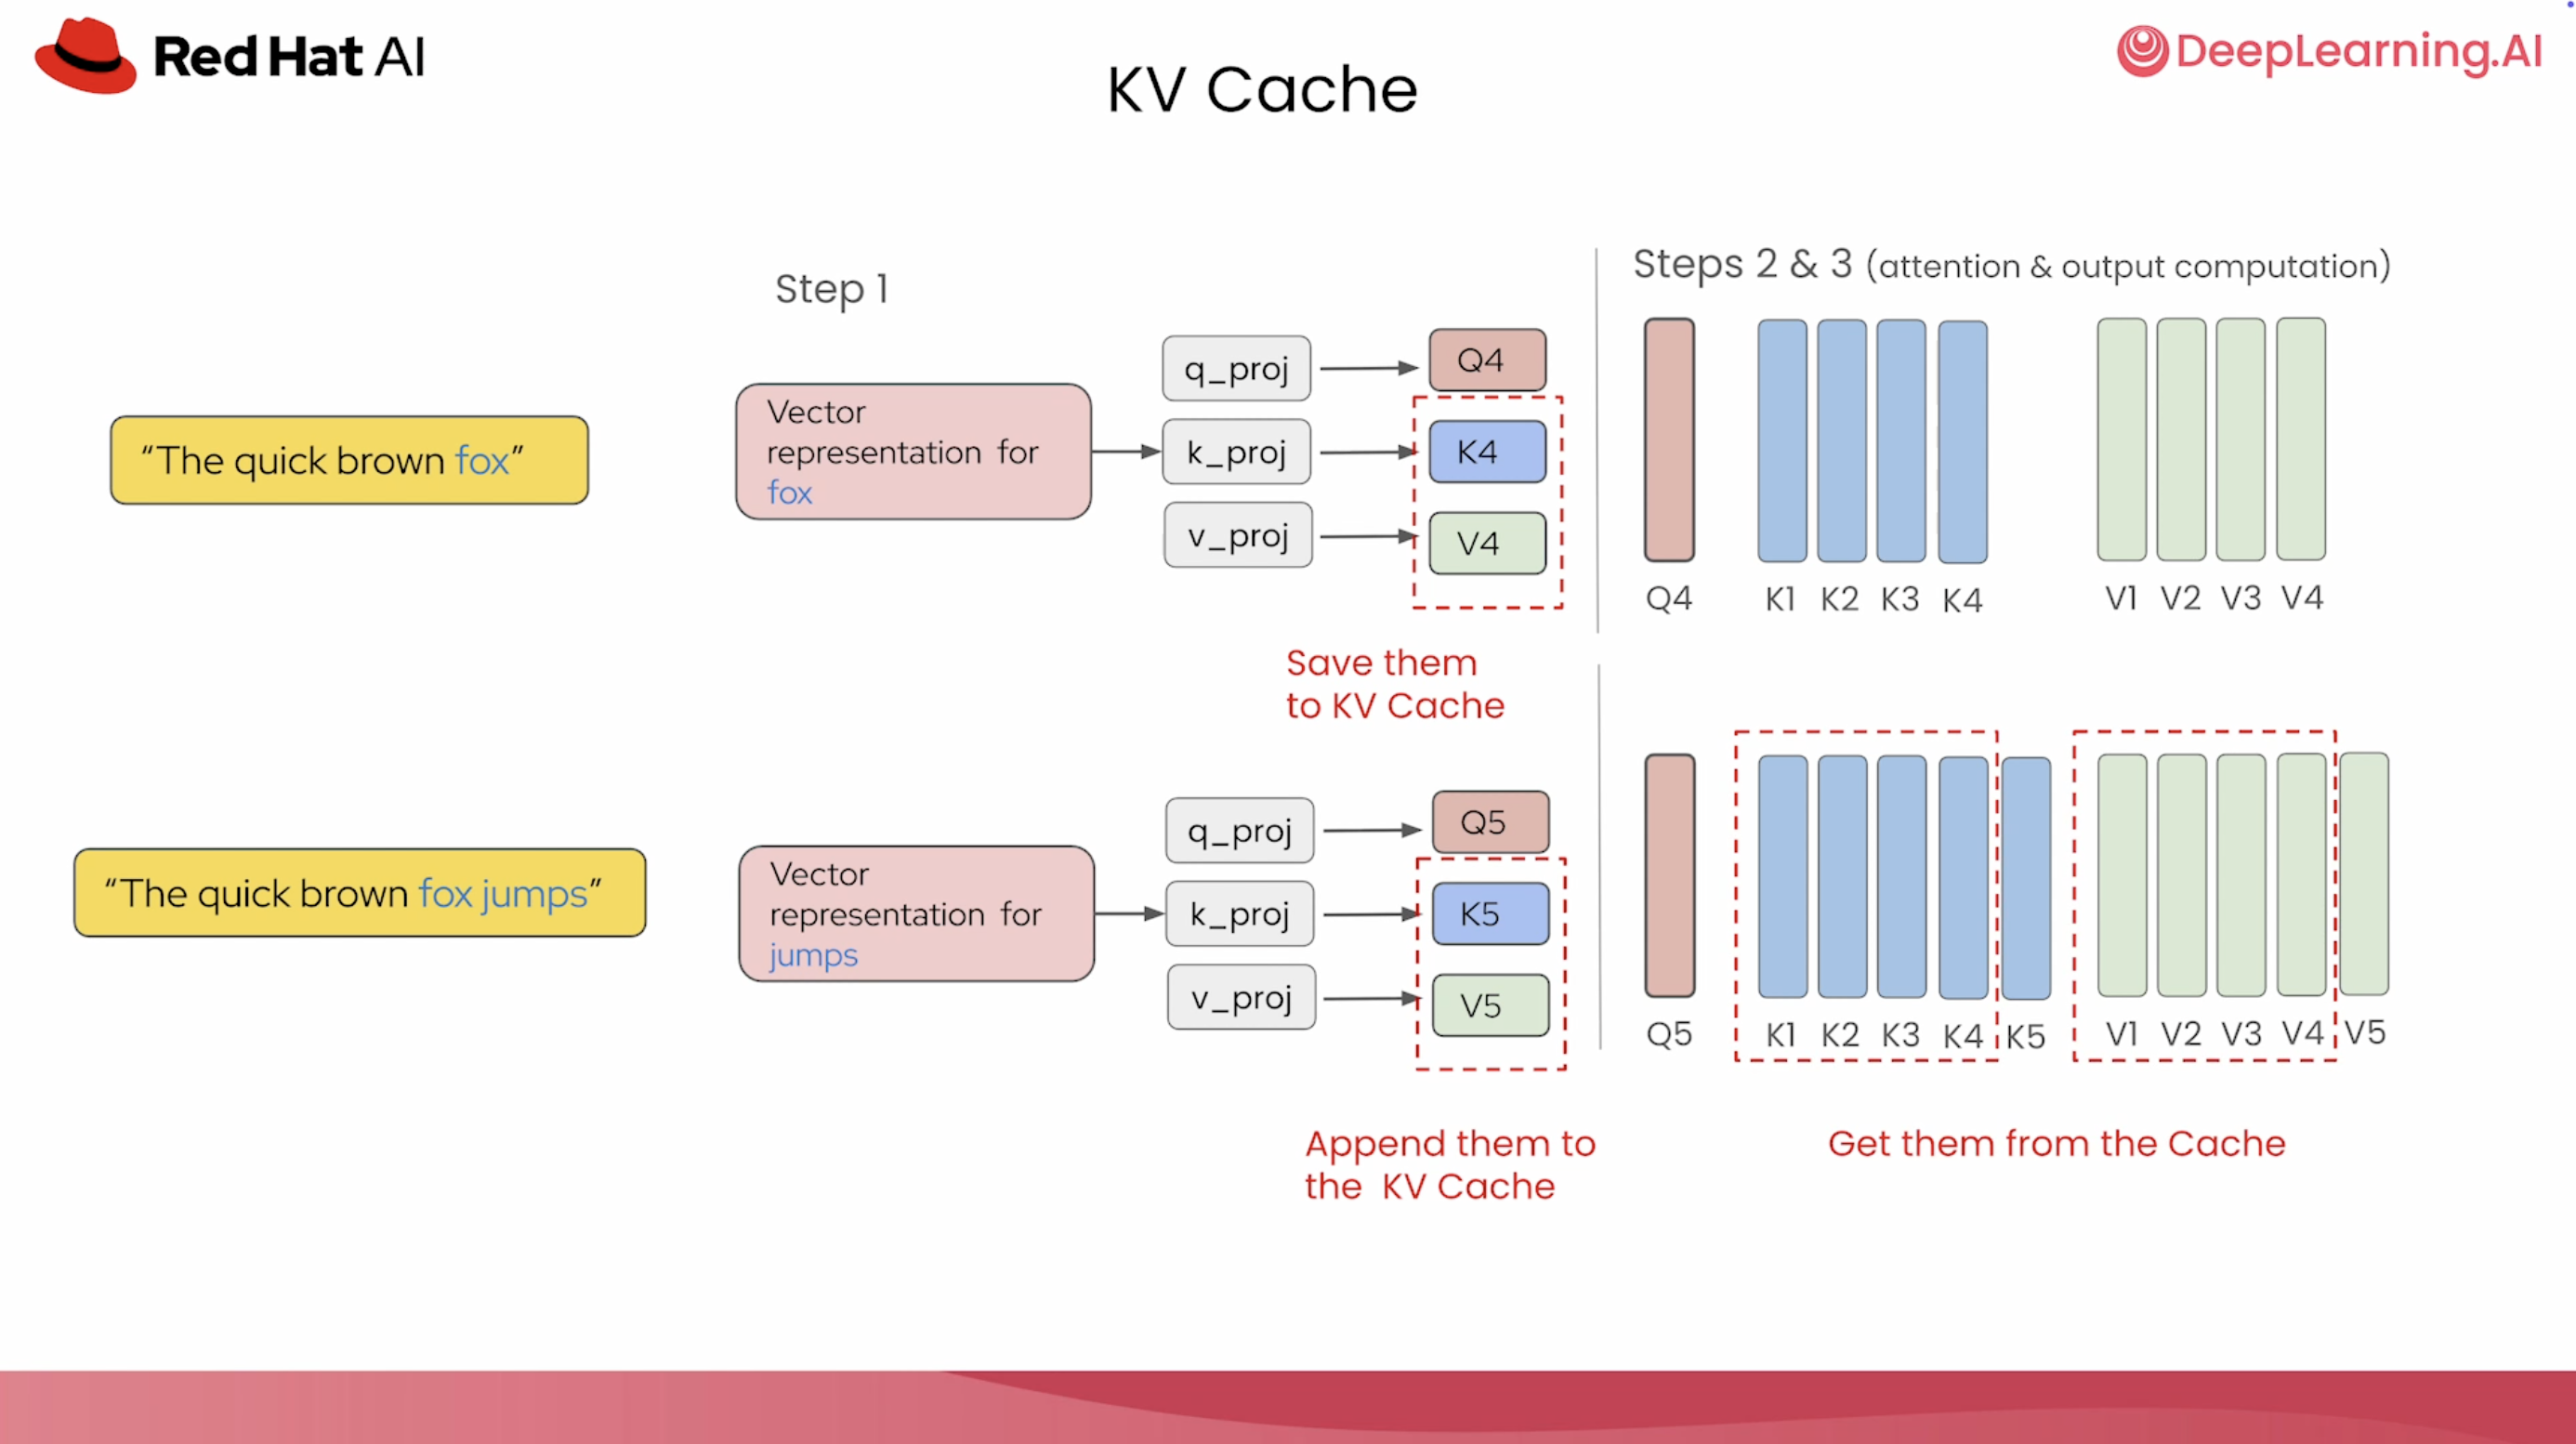
Fast & Efficient LLM Inference with vLLM: A New Course with ...

Deploying vLLM on ECS with EC2. Deploying Loci LLM on AWS | by Loci ...

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
Best LLM Inference Engine? TensorRT vs vLLM vs LMDeploy vs MLC-LLM ...

Meet vLLM: For faster, more efficient LLM inference and serving
Advertisement Space (336x280)

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

Deploy Large Language Model (LLM) with vLLM on K8s | by FiftyFive ...
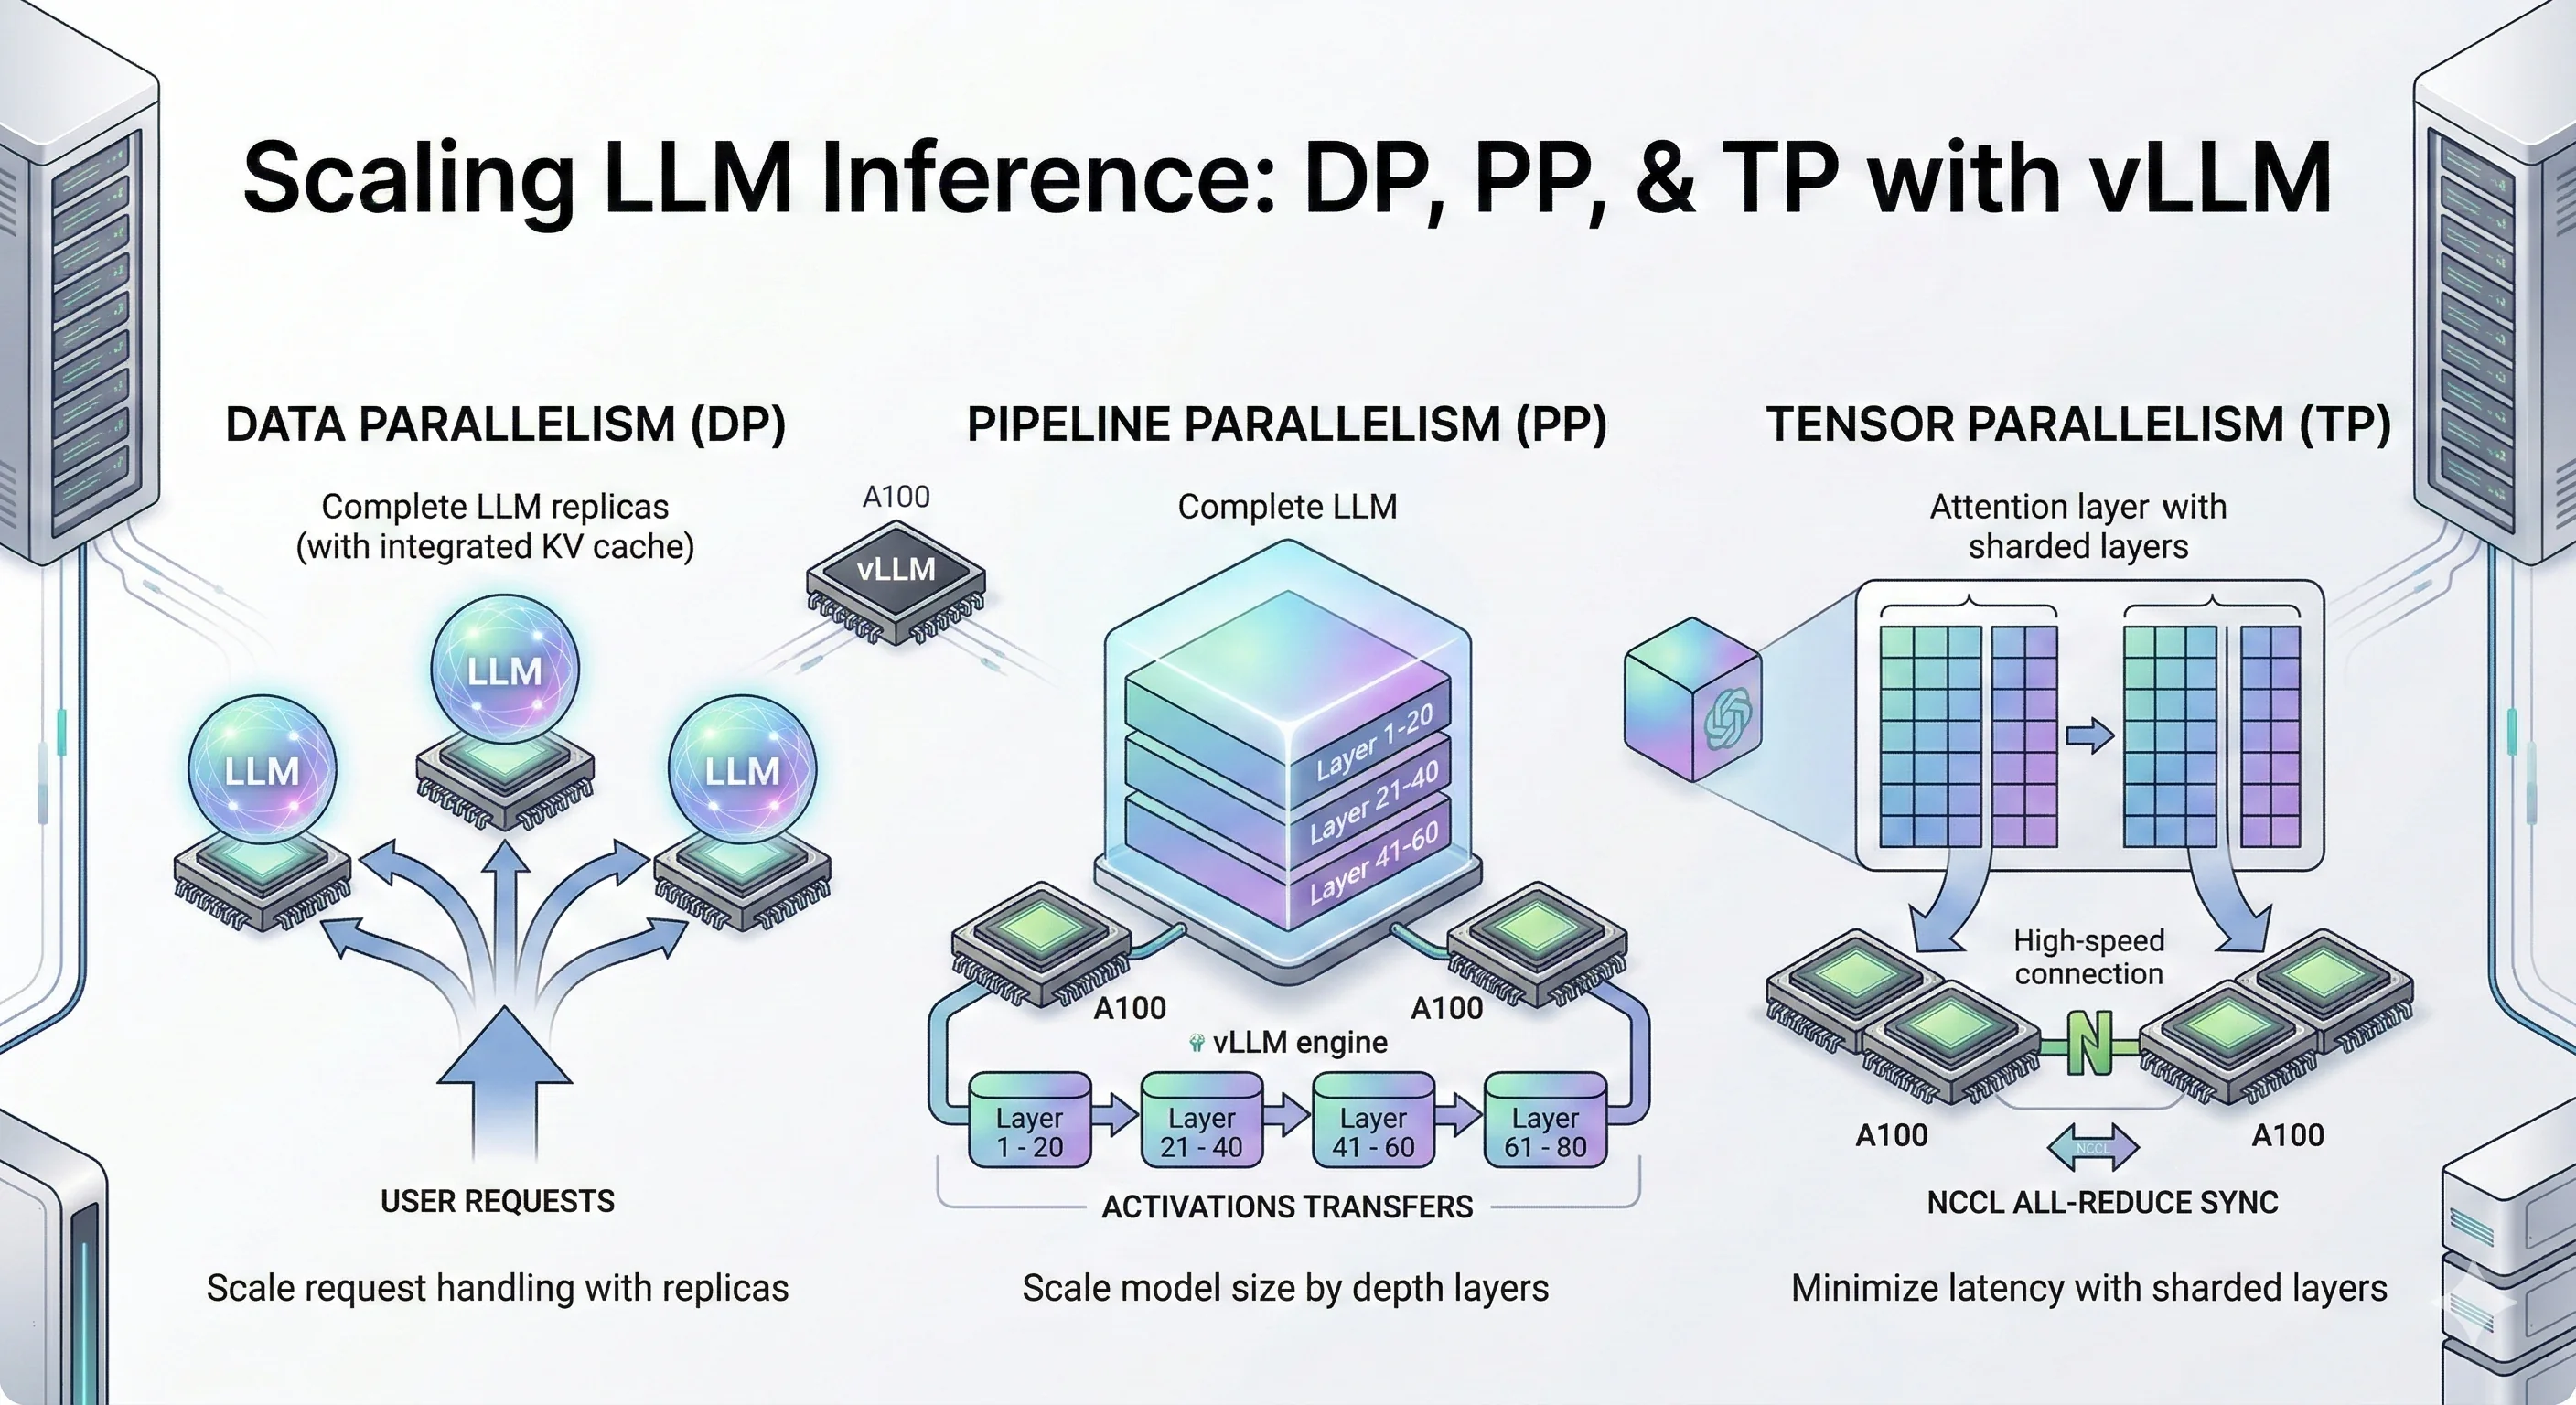
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...

GitHub - tensorchord/openmodelz: Autoscale LLM (vLLM, SGLang, LMDeploy ...

Implement LLM observability with Dynatrace on OpenShift AI | Red Hat ...
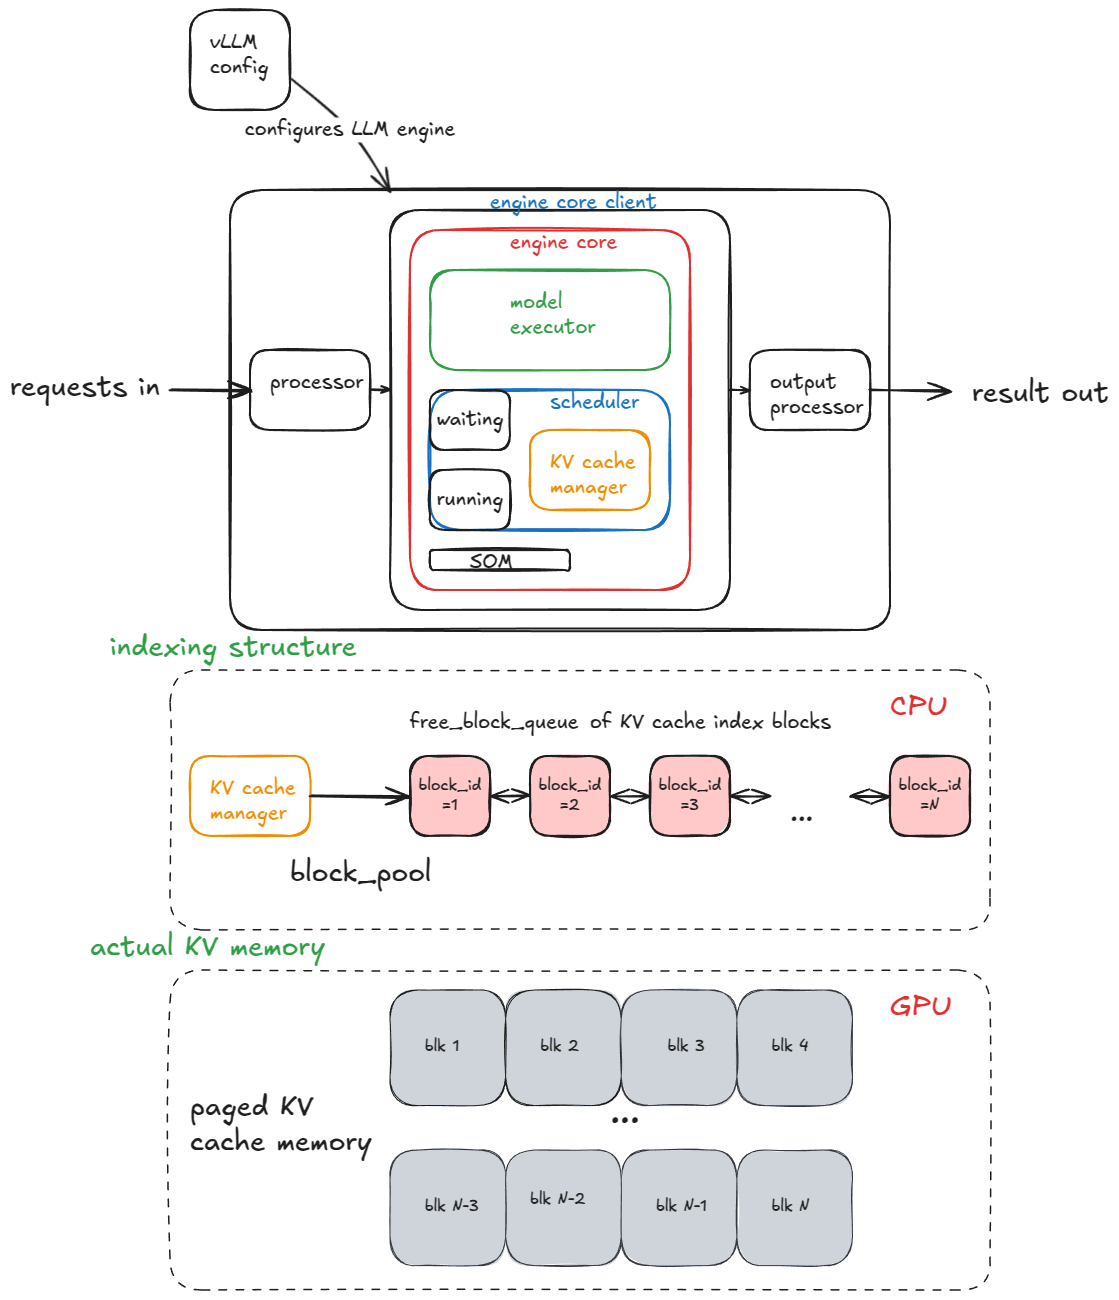
vLLM 내부: 초고처리량 LLM 추론 시스템의 해부 - Aleksa Gordić - RosettaLens 번역