
Optimize Edge Llm Serving With Vllm And Nvidia Model Optimizer Atomic
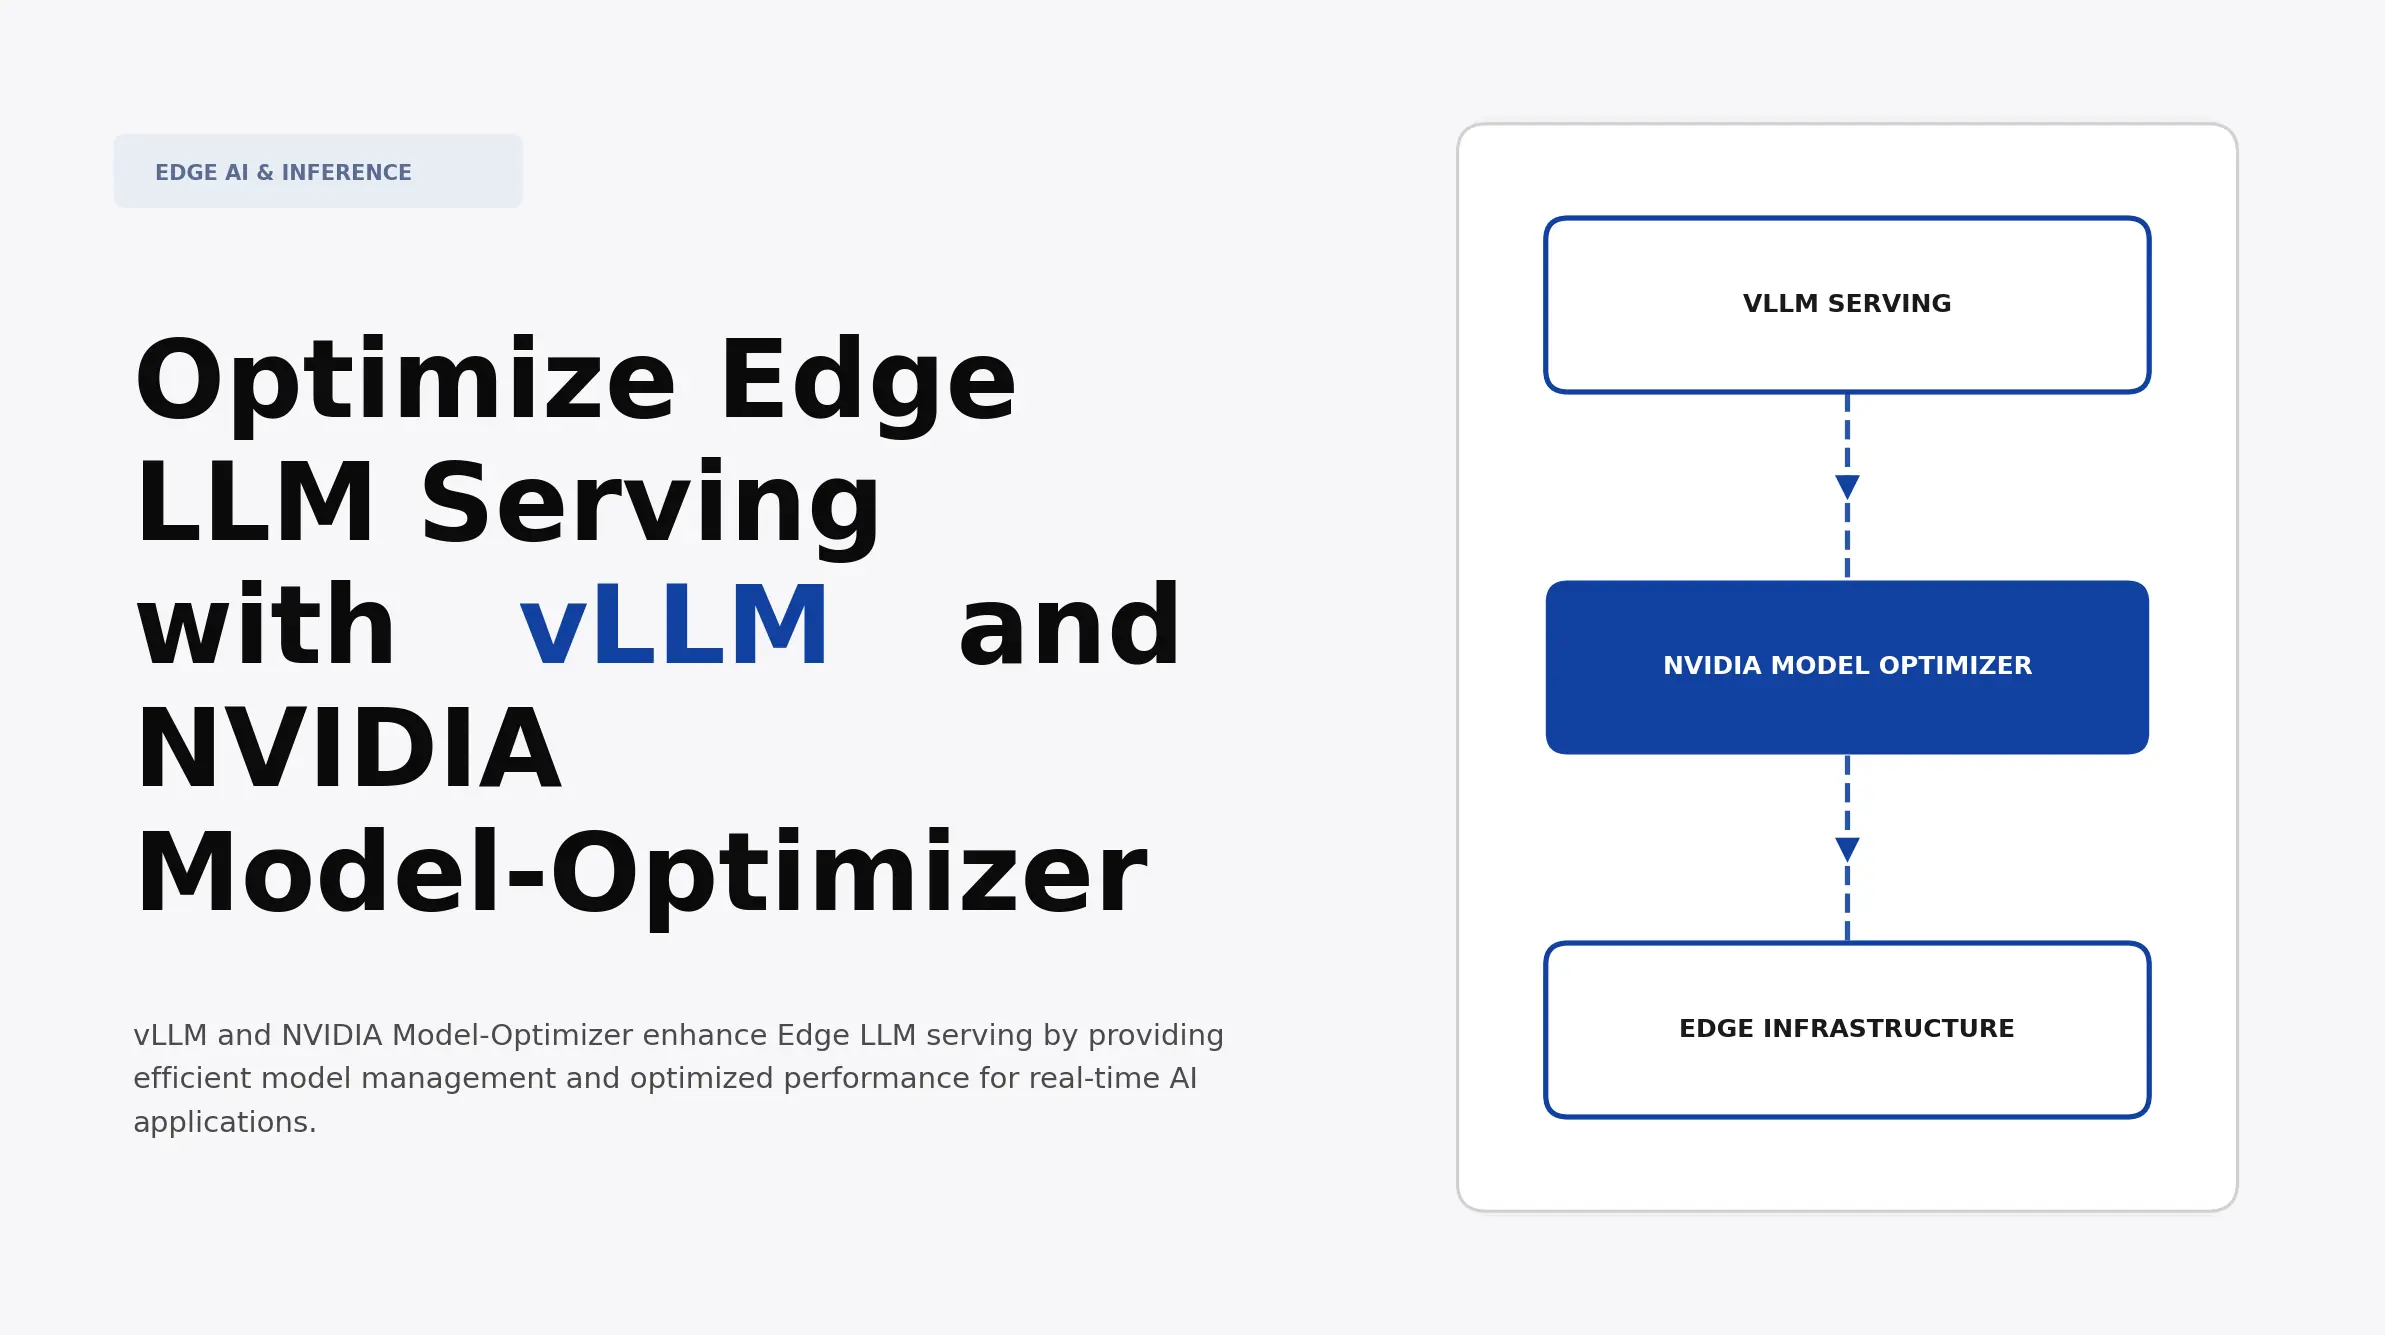
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
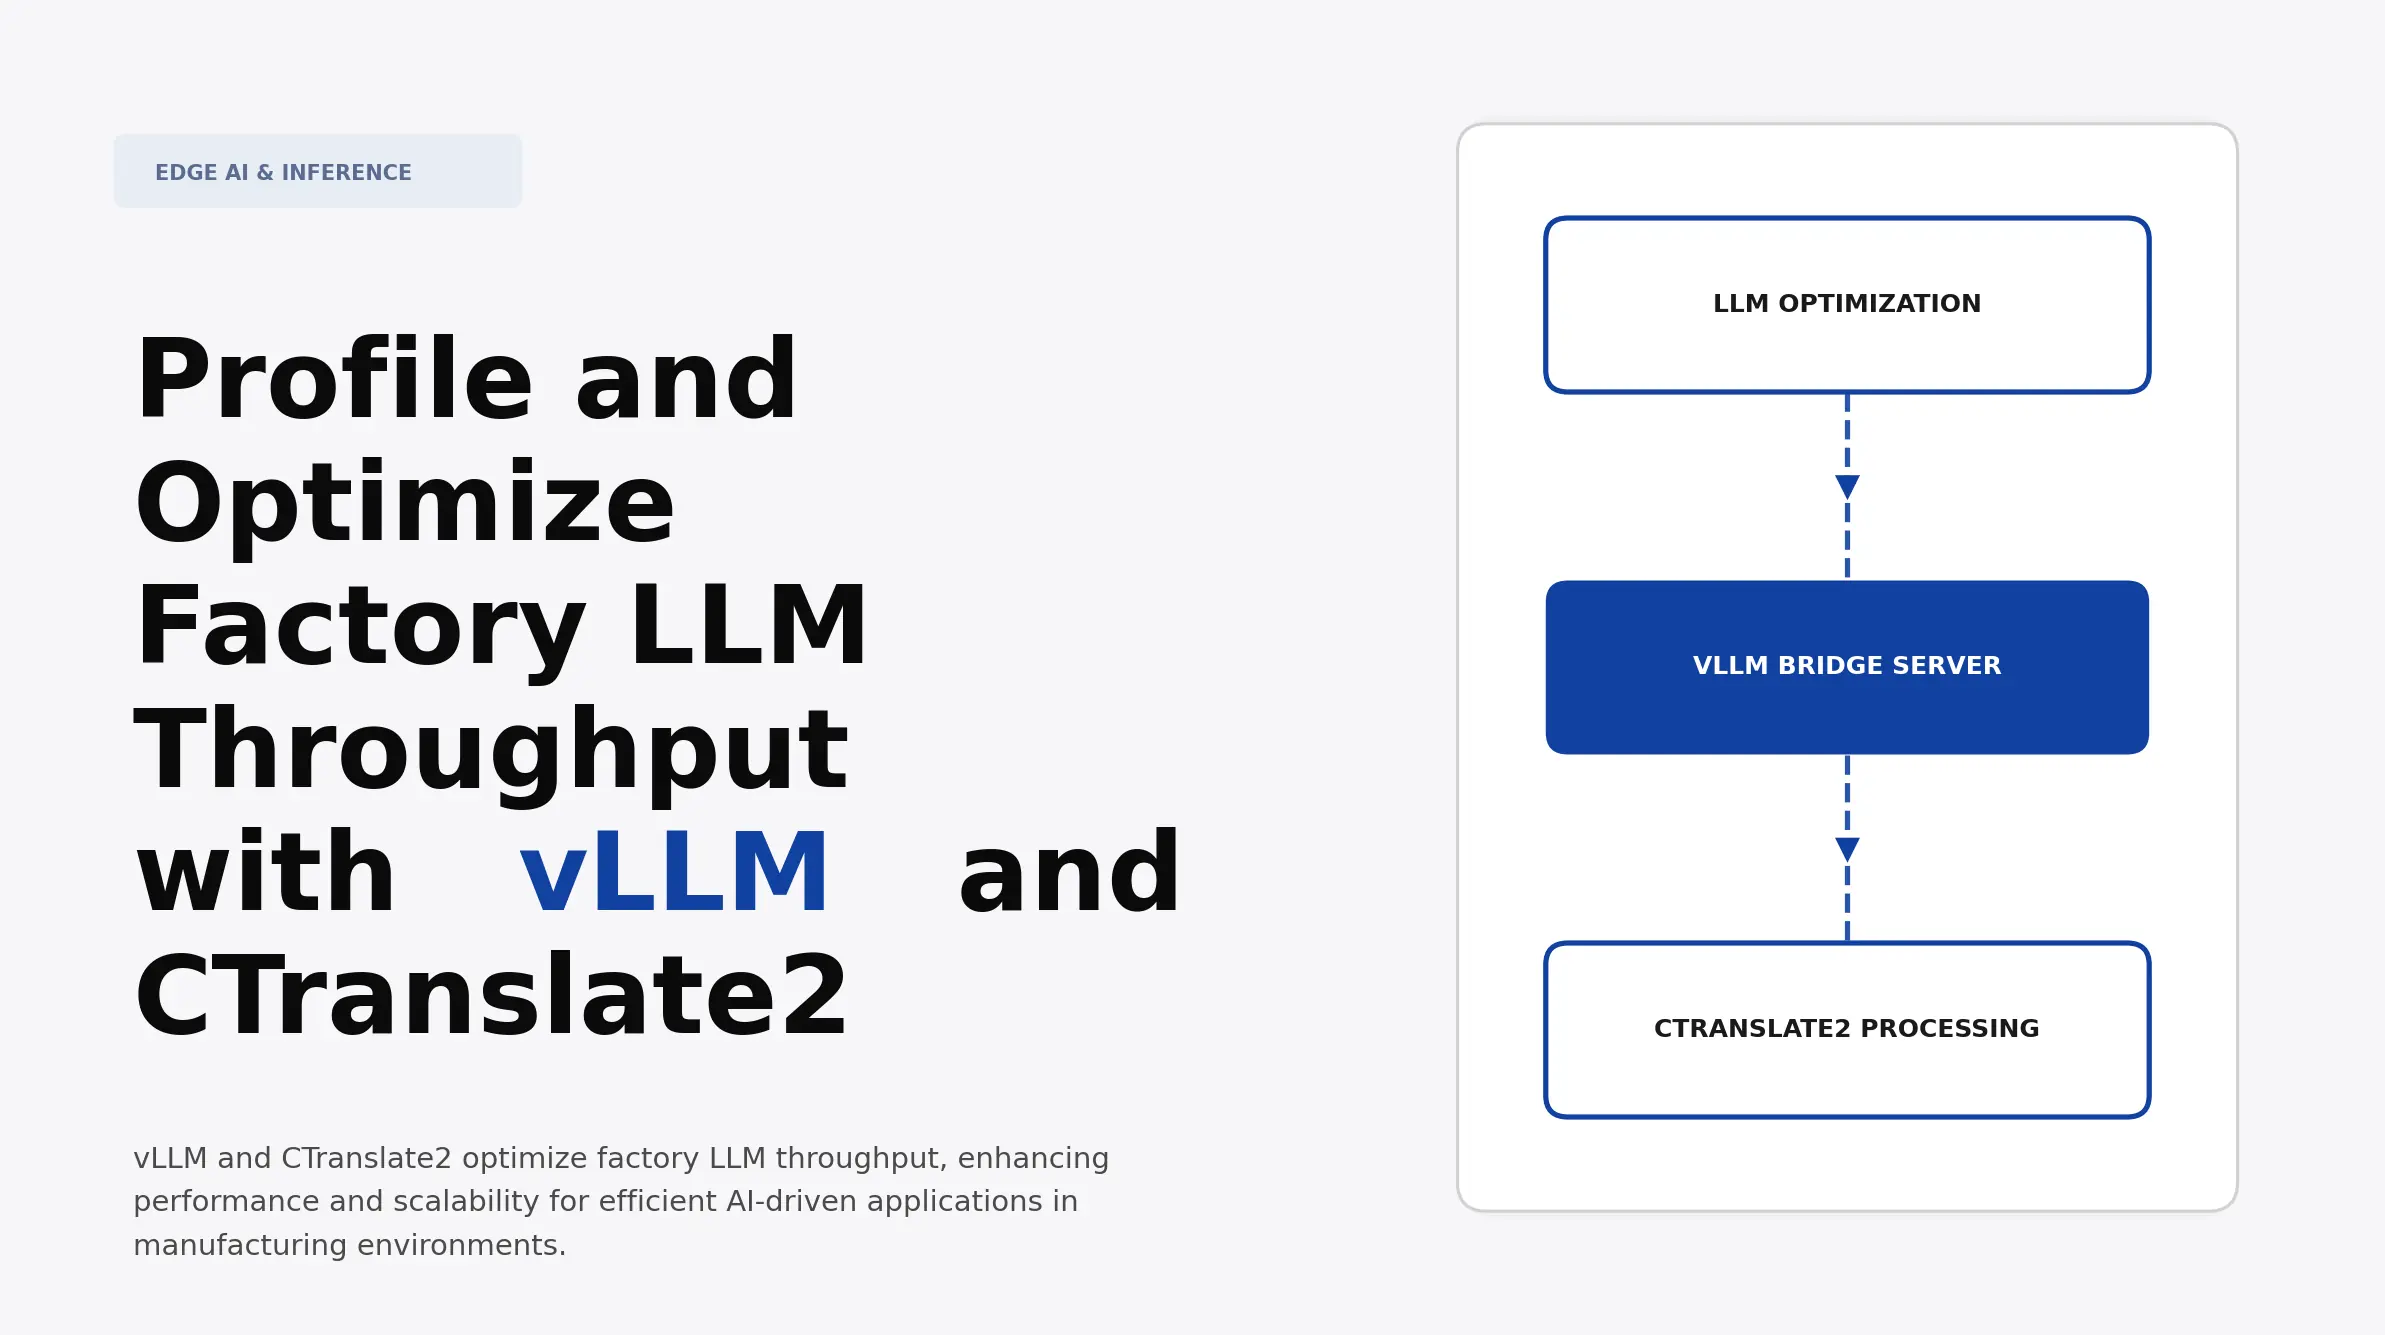
Profile and Optimize Factory LLM Throughput with vLLM and CTranslate2 ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving | PDF ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Deployment on Edge: LLM Serving on Jetson using vLLM
Advertisement Space (300x250)

Optimizing Large Language Models with vLLM and Related Tools.pdf

Optimizing Large Language Models with vLLM and Related Tools.pdf
Testing Adobe's New LLM Optimizer & Edge Optimization: Experiments ...
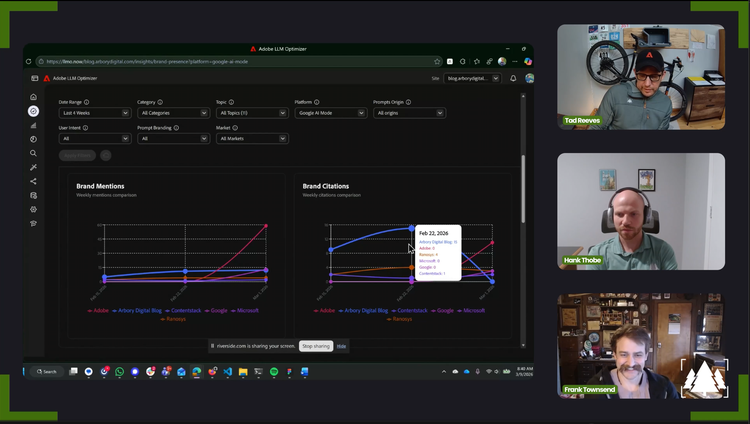
Testing Adobe's New LLM Optimizer & Edge Optimization: Experiments ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Review of MLSys 2025 — LLM Model Serving Session | by Don Moon | Byte ...

Stream Smarter and Safer: Learn how NVIDIA NeMo Guardrails Enhance LLM ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Supercharging LLM Applications on Windows PCs with NVIDIA RTX Systems ...
Advertisement Space (336x280)

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...

Post-Training Quantization of LLMs with NVIDIA NeMo and NVIDIA TensorRT ...
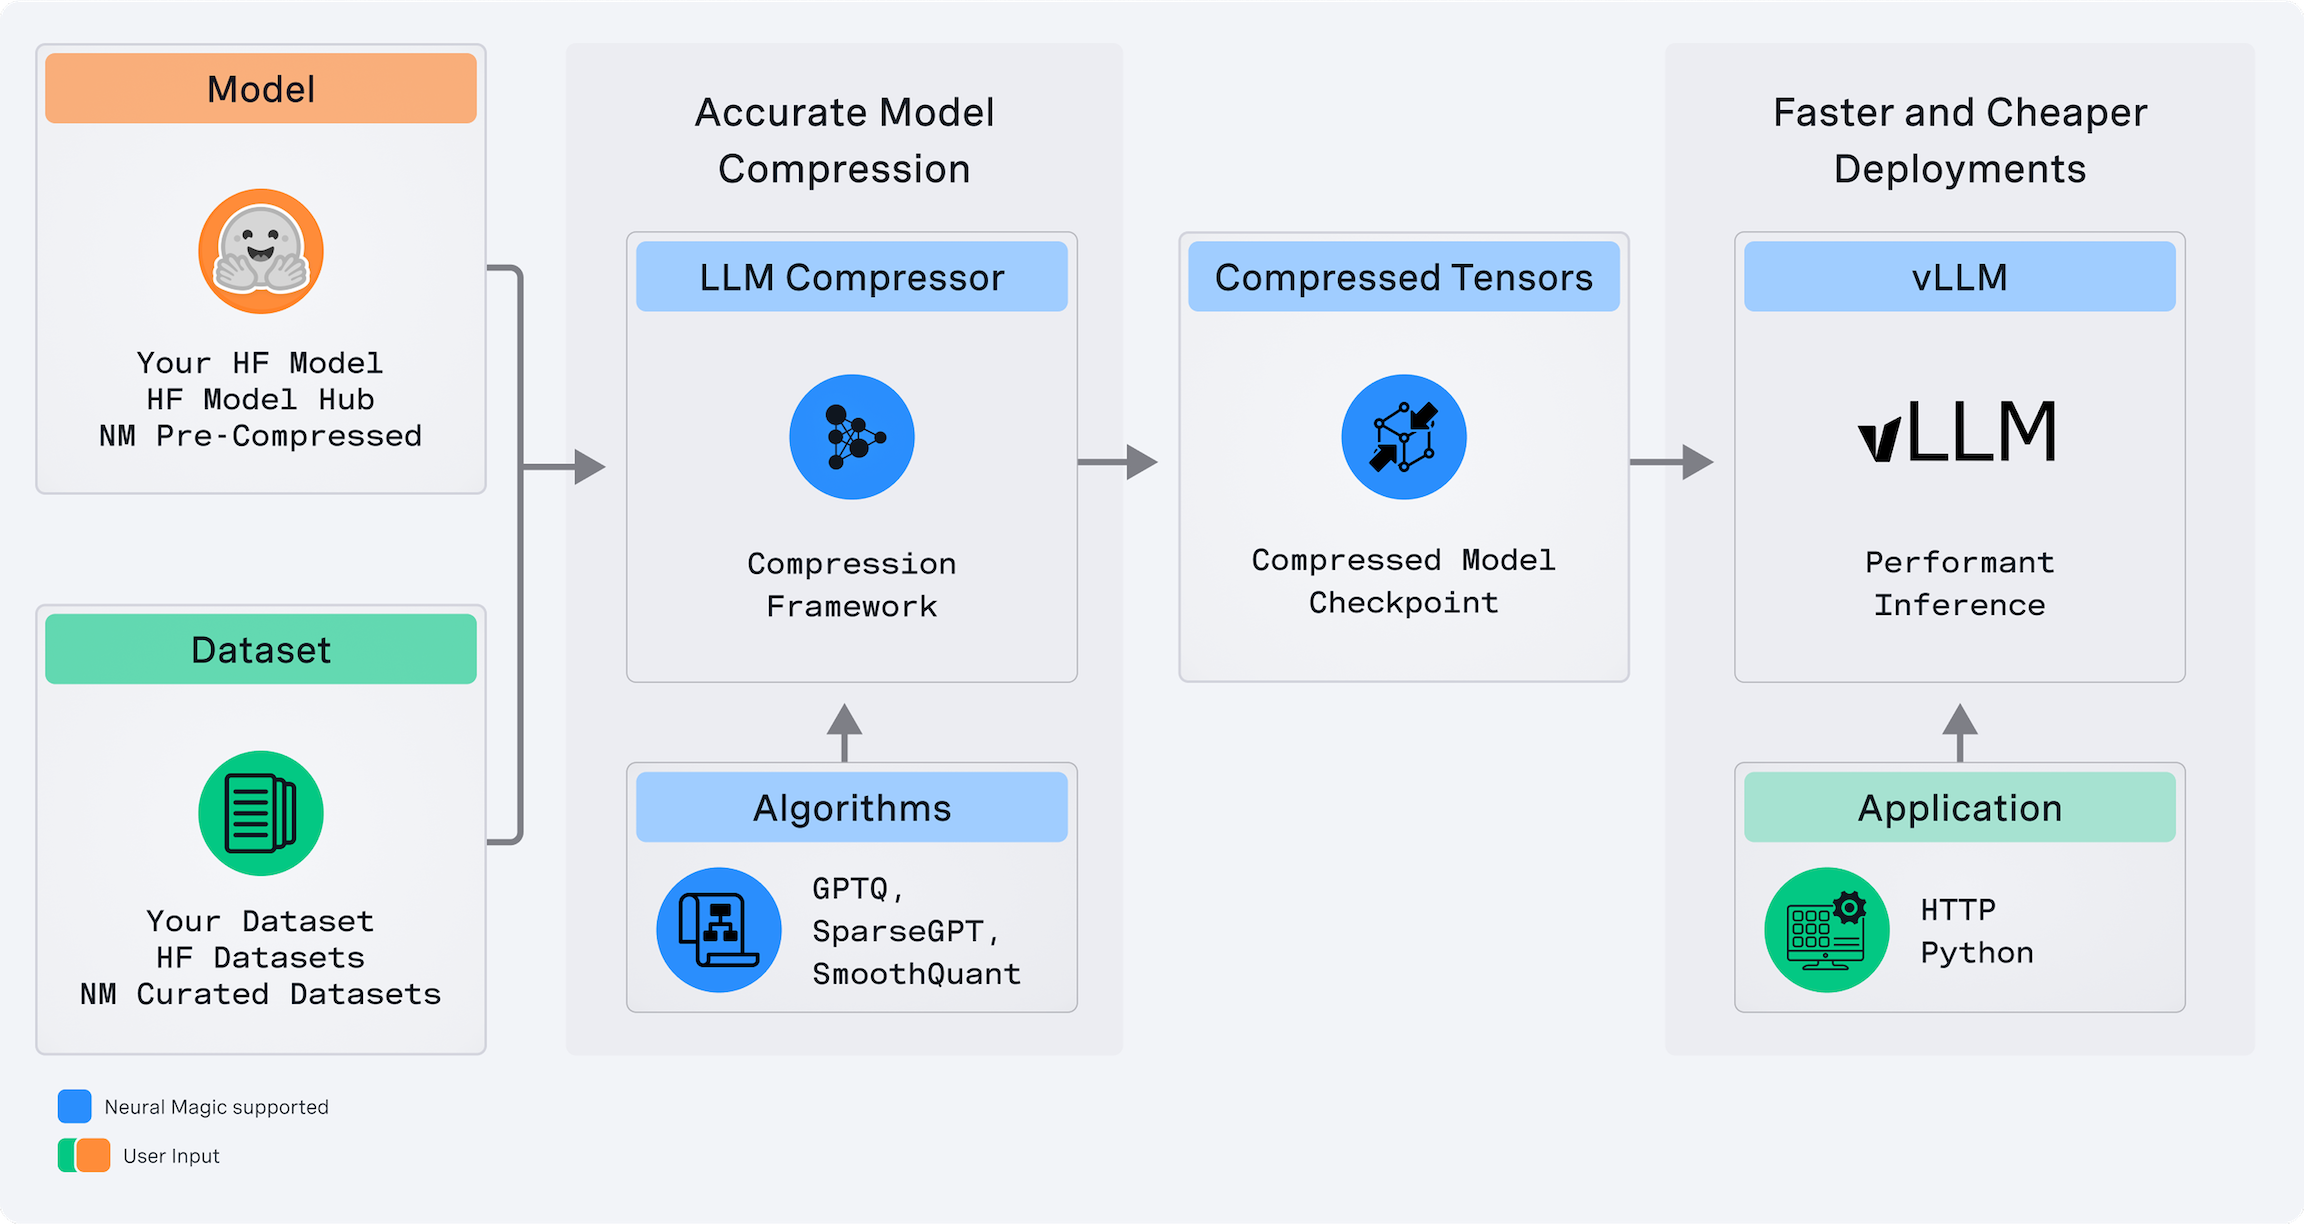
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
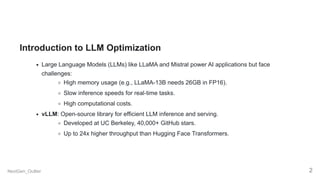
Optimizing Large Language Models with vLLM and Related Tools.pdf
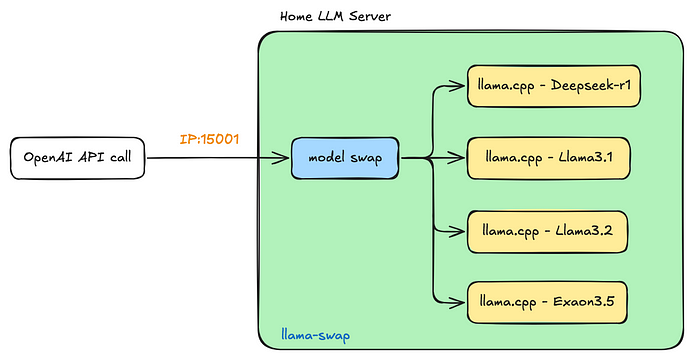
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
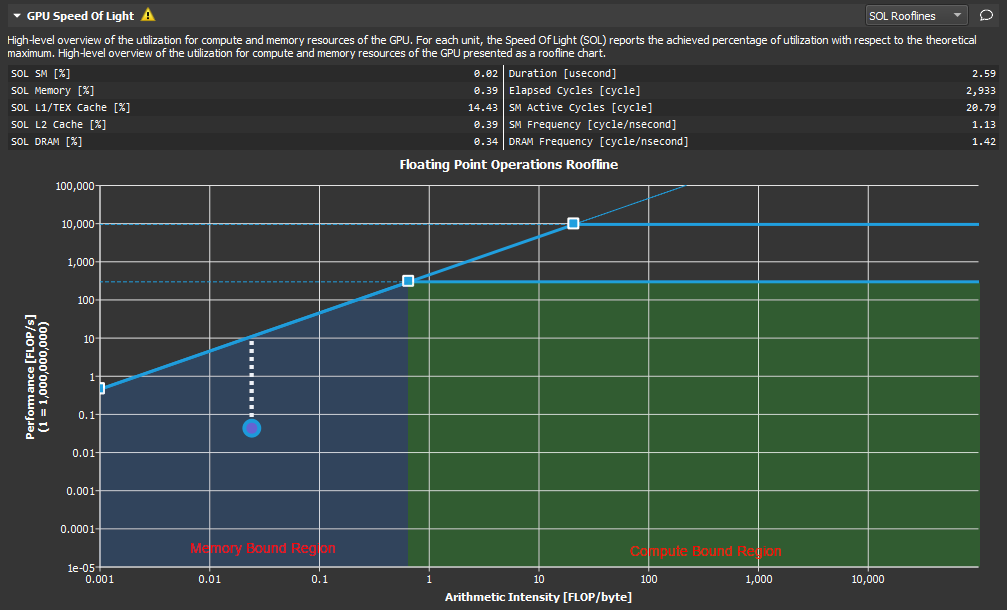
Profile vllm performance with nvidia-system and nvidia-compute – remaper
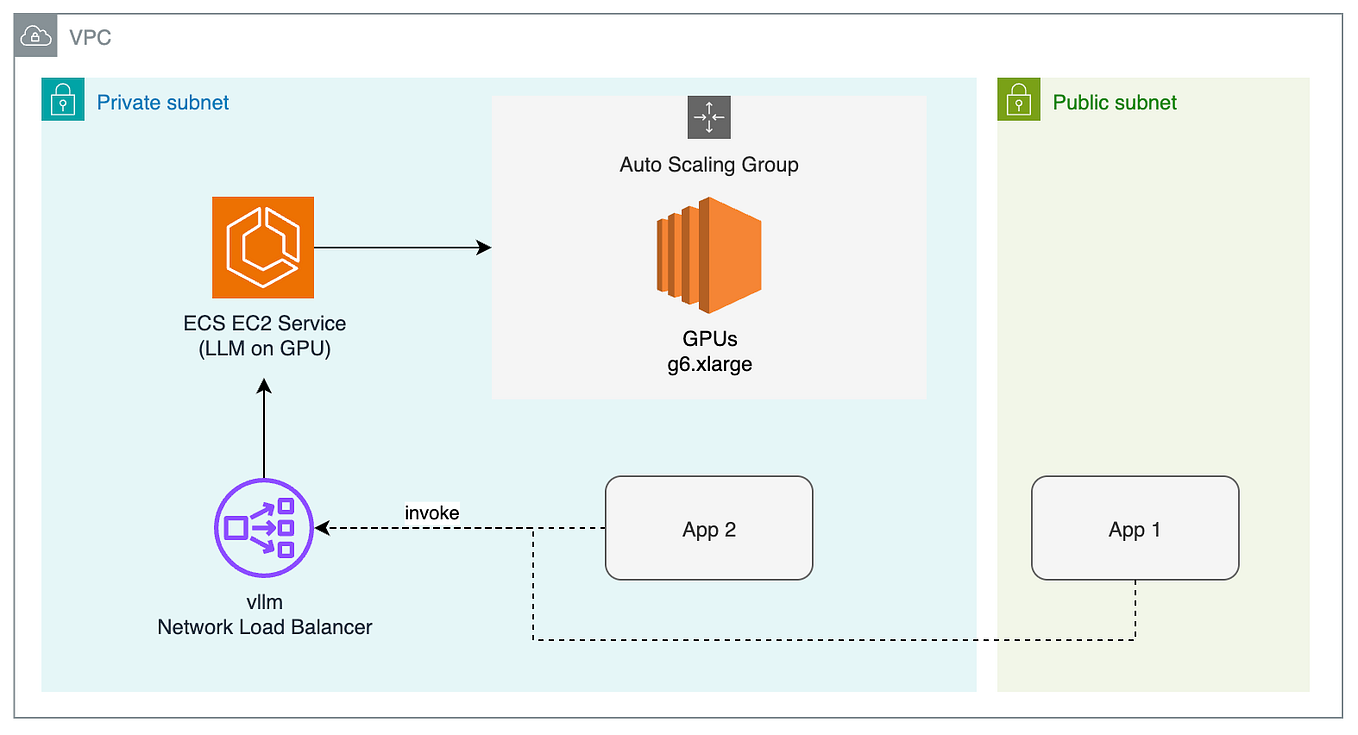
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

Optimizing LLMs for Performance and Accuracy with Post-Training ...
Mastering LLM Techniques: Inference Optimization | NVIDIA Technical ...
Advertisement Space (336x280)

NVIDIA TensorRT Edge-LLM 加速汽车与机器人领域的 LLM 和 VLM 推理 - NVIDIA 技术博客
Accelerating LLMs with llama.cpp on NVIDIA RTX Systems | NVIDIA ...

llm-optimizer: An Open-Source Tool for LLM Inference Benchmarking and ...

Develop Generative AI-Powered Visual AI Agents for the Edge | NVIDIA ...

Open Source AI Tool Upgrades Speed Up LLM and Diffusion Models on ...

Figure 2 from Performance-Aware NILM Model Optimization for Edge ...