
Big Model Quantization With Sequential Onloading Llm Compressor Docs

Big Model Quantization with Sequential Onloading - LLM Compressor Docs
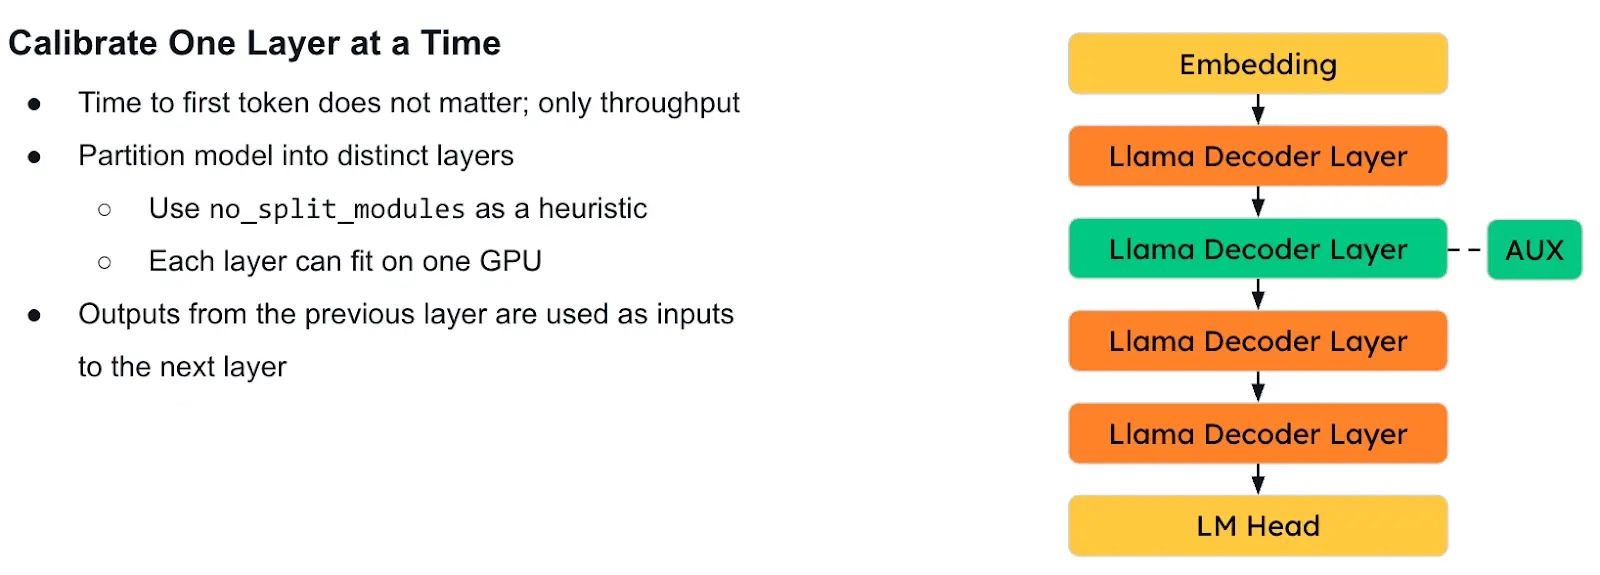
Sequential Onloading - LLM Compressor Docs
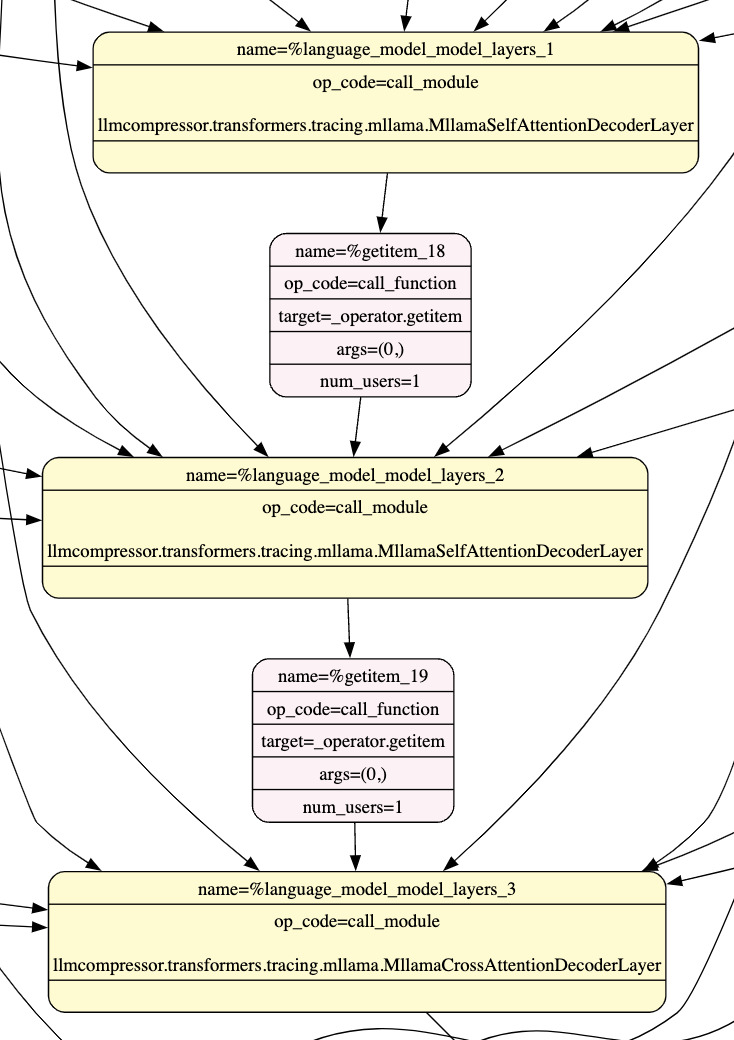
Sequential Onloading - LLM Compressor Docs
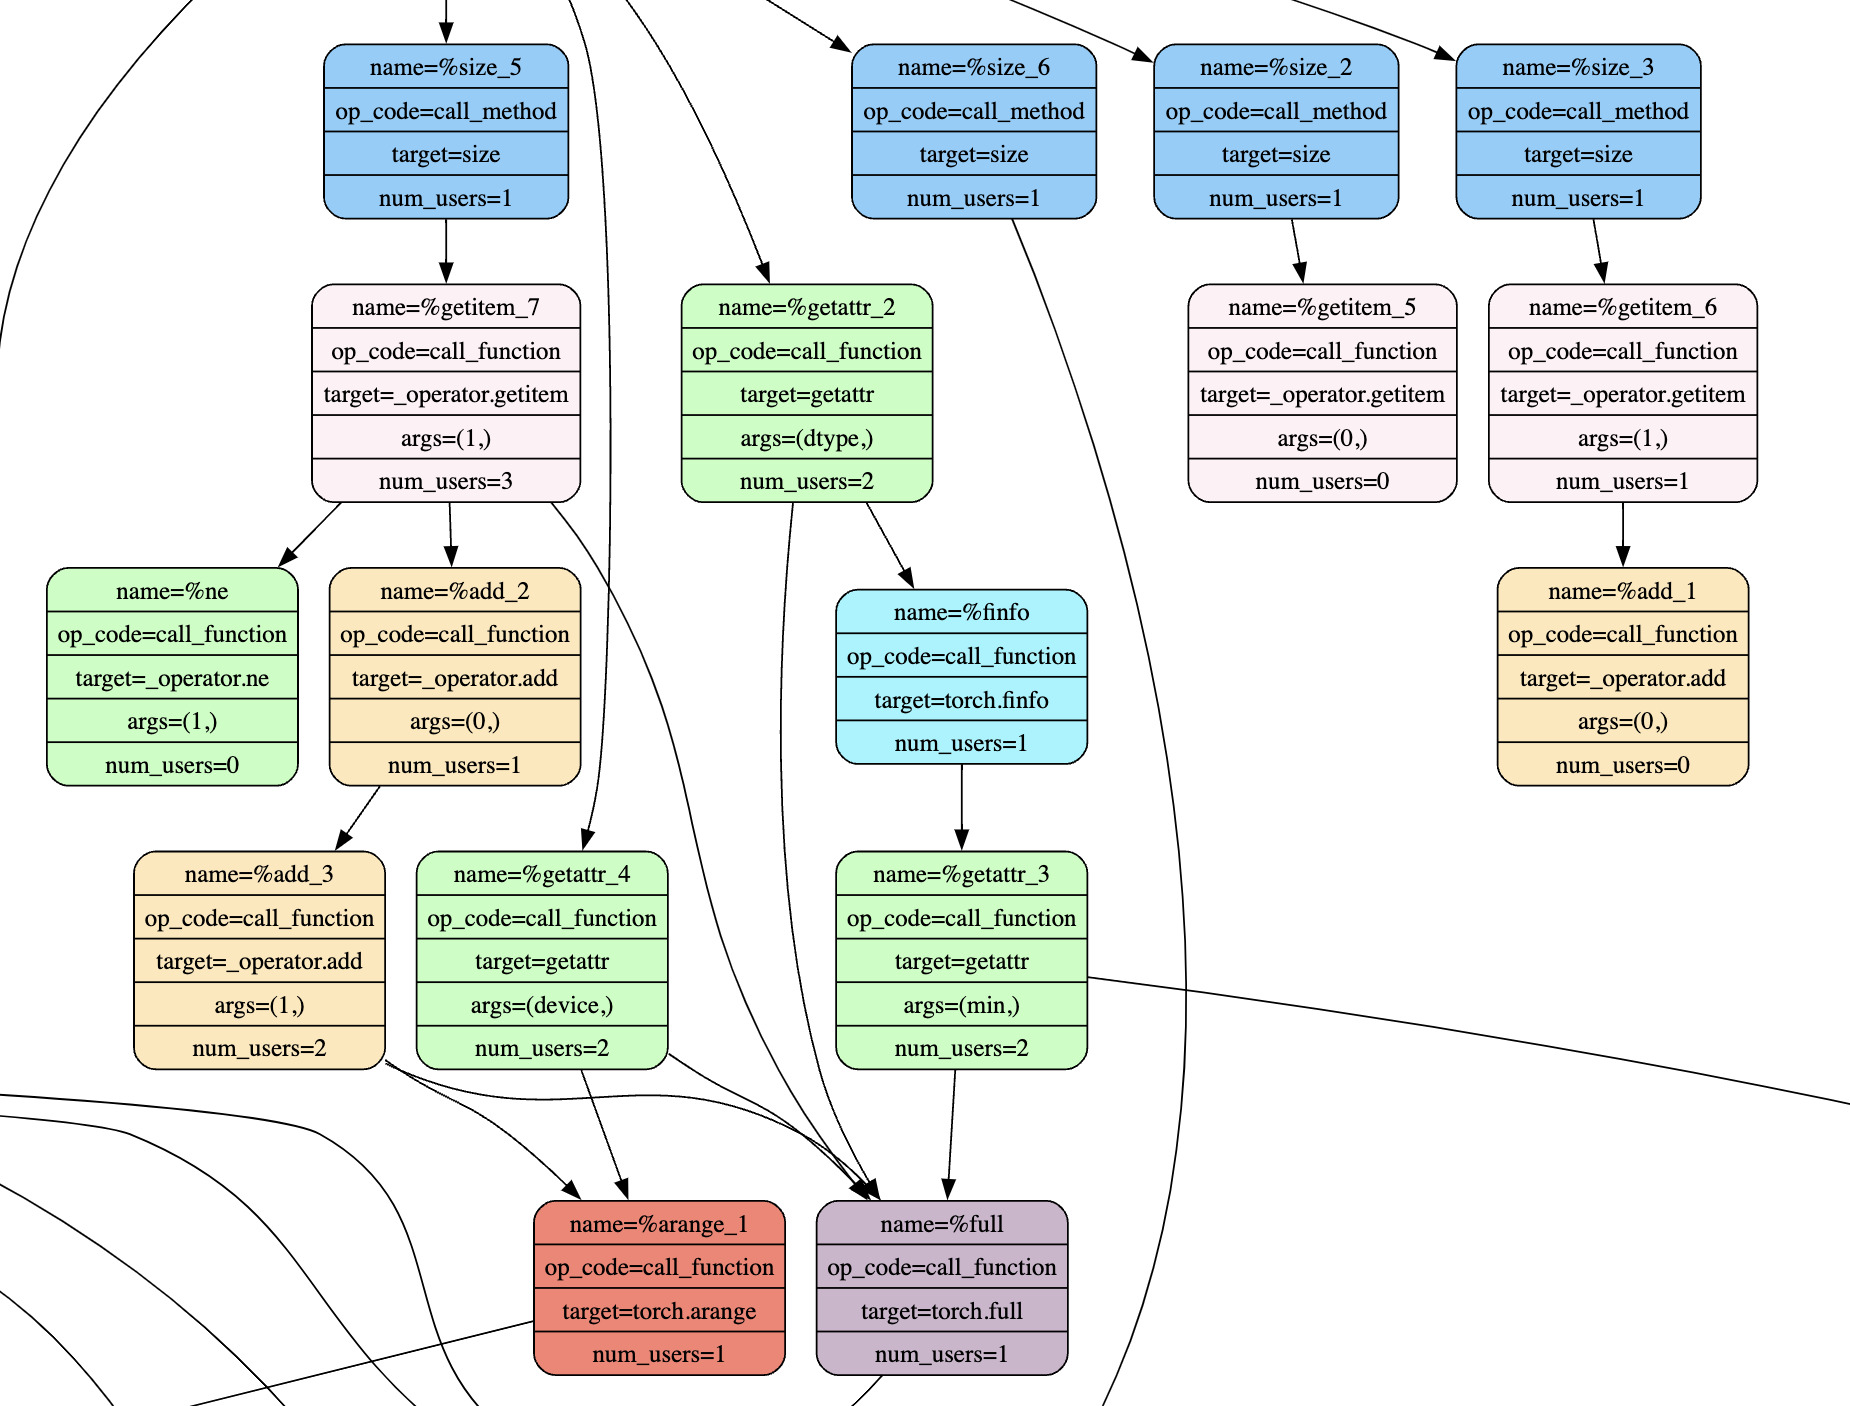
Sequential Onloading - LLM Compressor Docs

fp8 Weight, Activation, and KV Cache Quantization - LLM Compressor Docs

[论文评述] LLMC: Benchmarking Large Language Model Quantization with a ...

LLM inference optimization: Model Quantization and Distillation - YouTube

llmcompressor.utils - LLM Compressor Docs
Quantizing Models with Activation-Aware Quantization (AWQ) - LLM ...
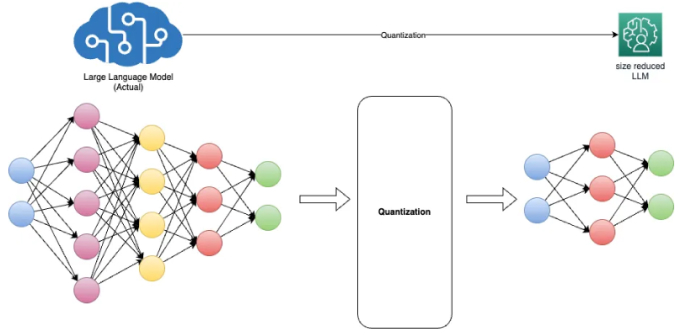
Top LLM Quantization Methods and Their Impact on Model Quality
Advertisement Space (300x250)
Model Quantization Guide: Reduce LLM Size and Cost | DevOpsNess
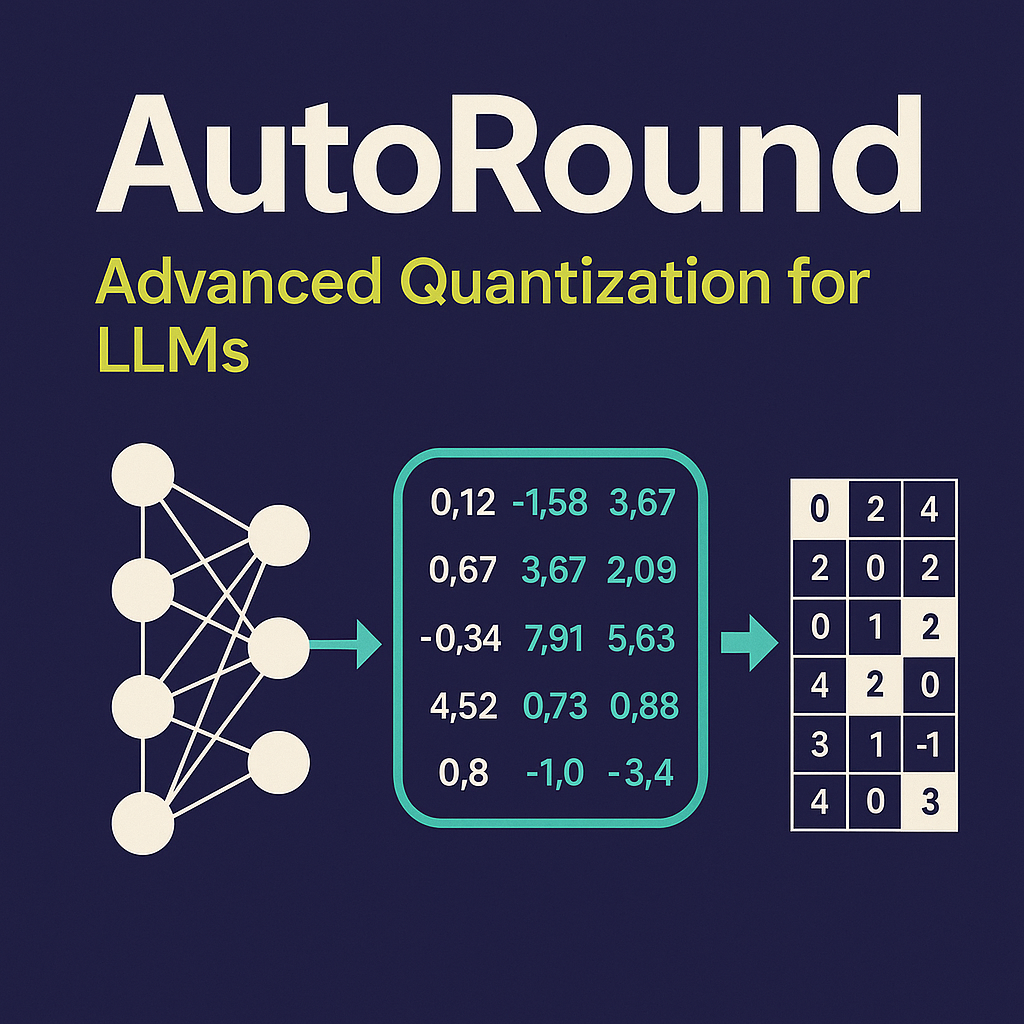
Advancing Low‑Bit Quantization for LLMs: AutoRound x LLM Compressor ...

Quantization of Transformer Models with Neural Compressor

Paper page - MixLLM: LLM Quantization with Global Mixed-precision ...
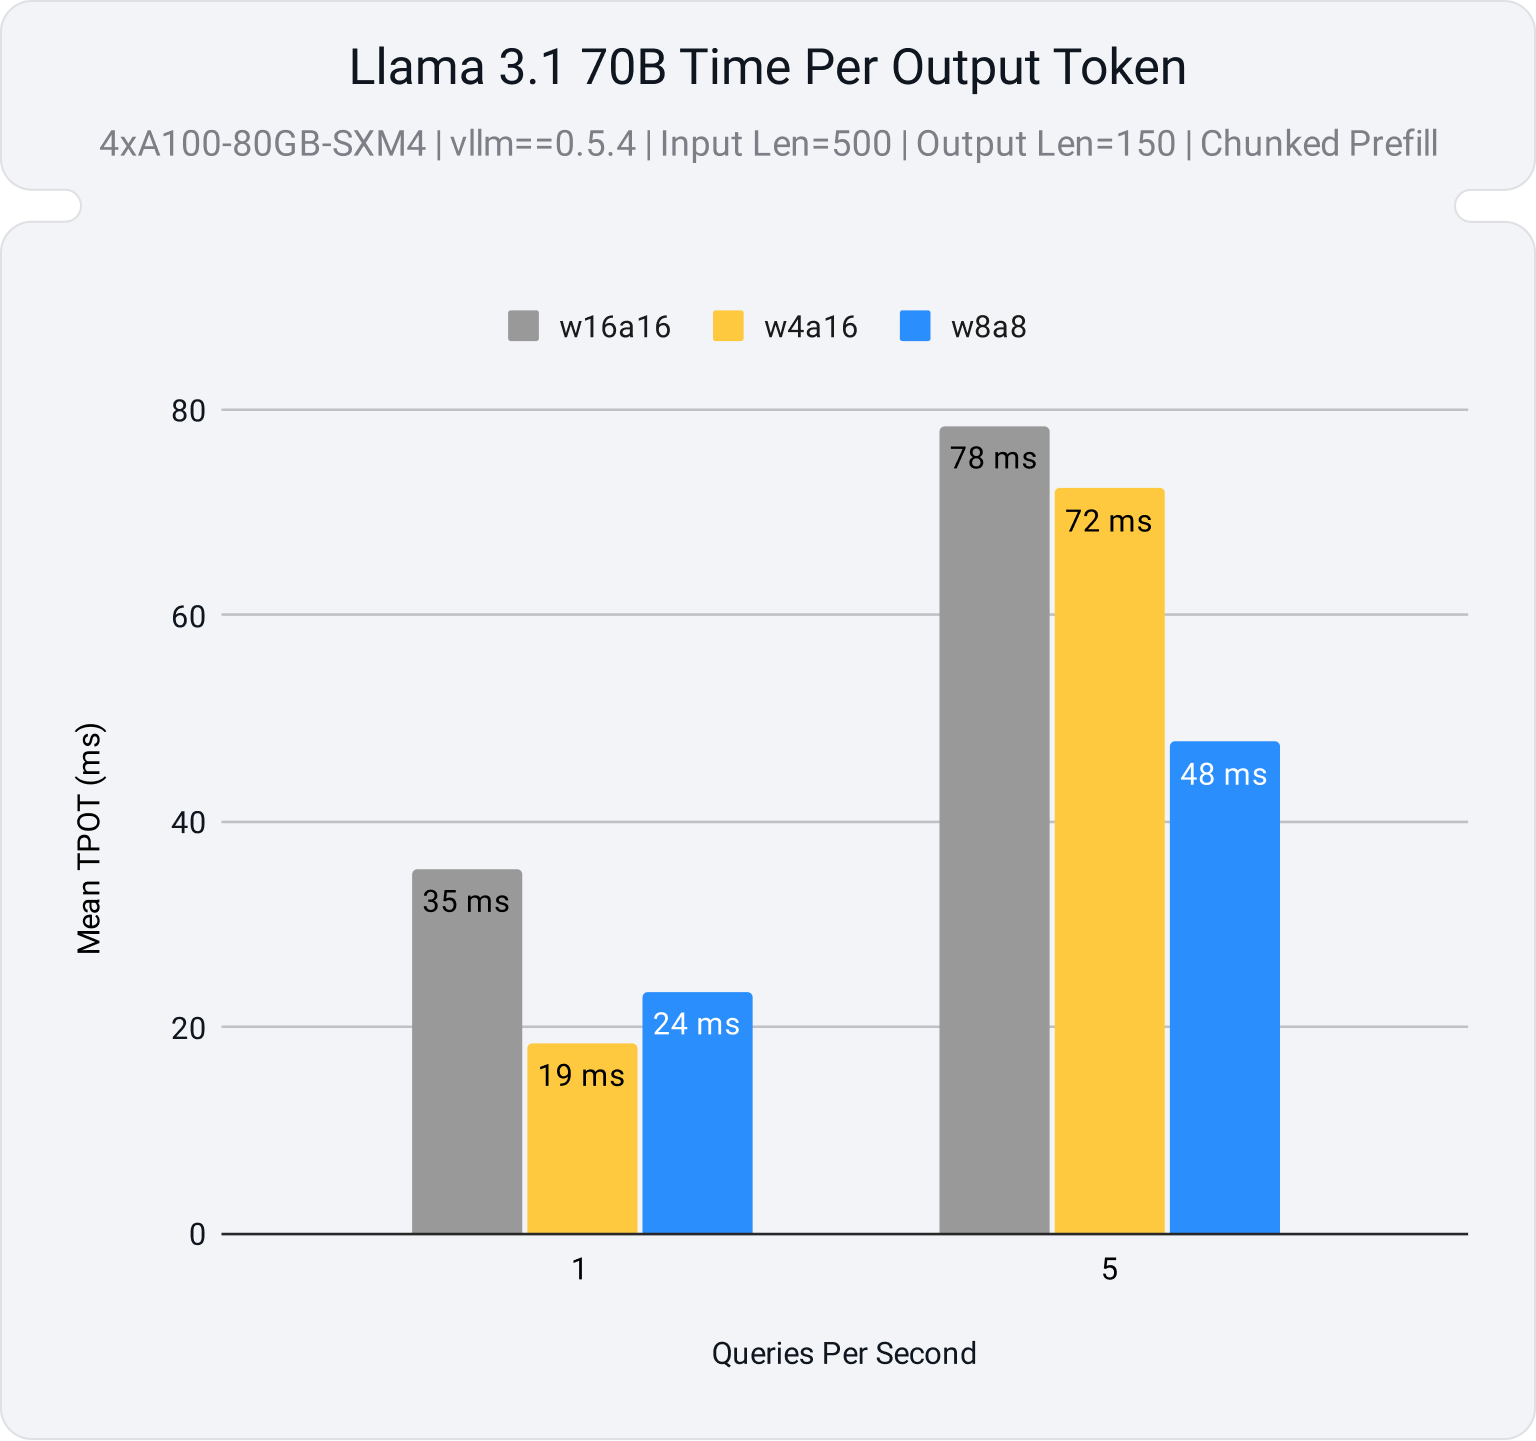
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

Top LLM Quantization Methods and Their Impact on Model Quality

LLM Inference, Quantization, and Model Compression

顺序加载 - LLM Compressor 文档 - vLLM 文档

The Ultimate Handbook for LLM Quantization | Towards Data Science

LLM Model Compression Techniques - Best Generative AI & Machine ...
Advertisement Space (336x280)
Model Compression with LLM-Compressor and Deployment on Vast.ai (Part 1)
LLM Compressor 0.9.0: Attention quantization, MXFP4 support, and more ...

LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI
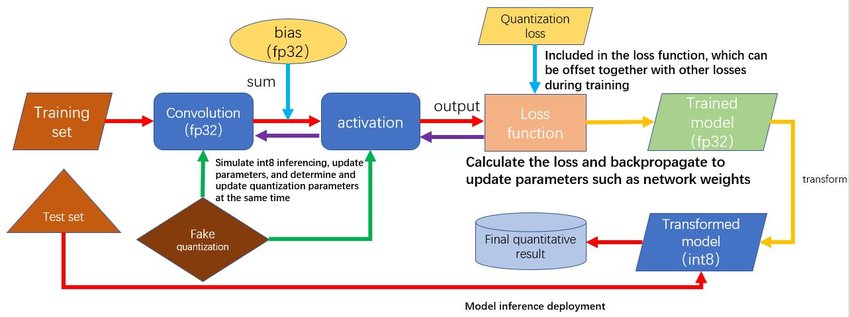
A Comprehensive Guide on LLM Quantization and Use Cases

LLM Quantization Techniques- GPTQ
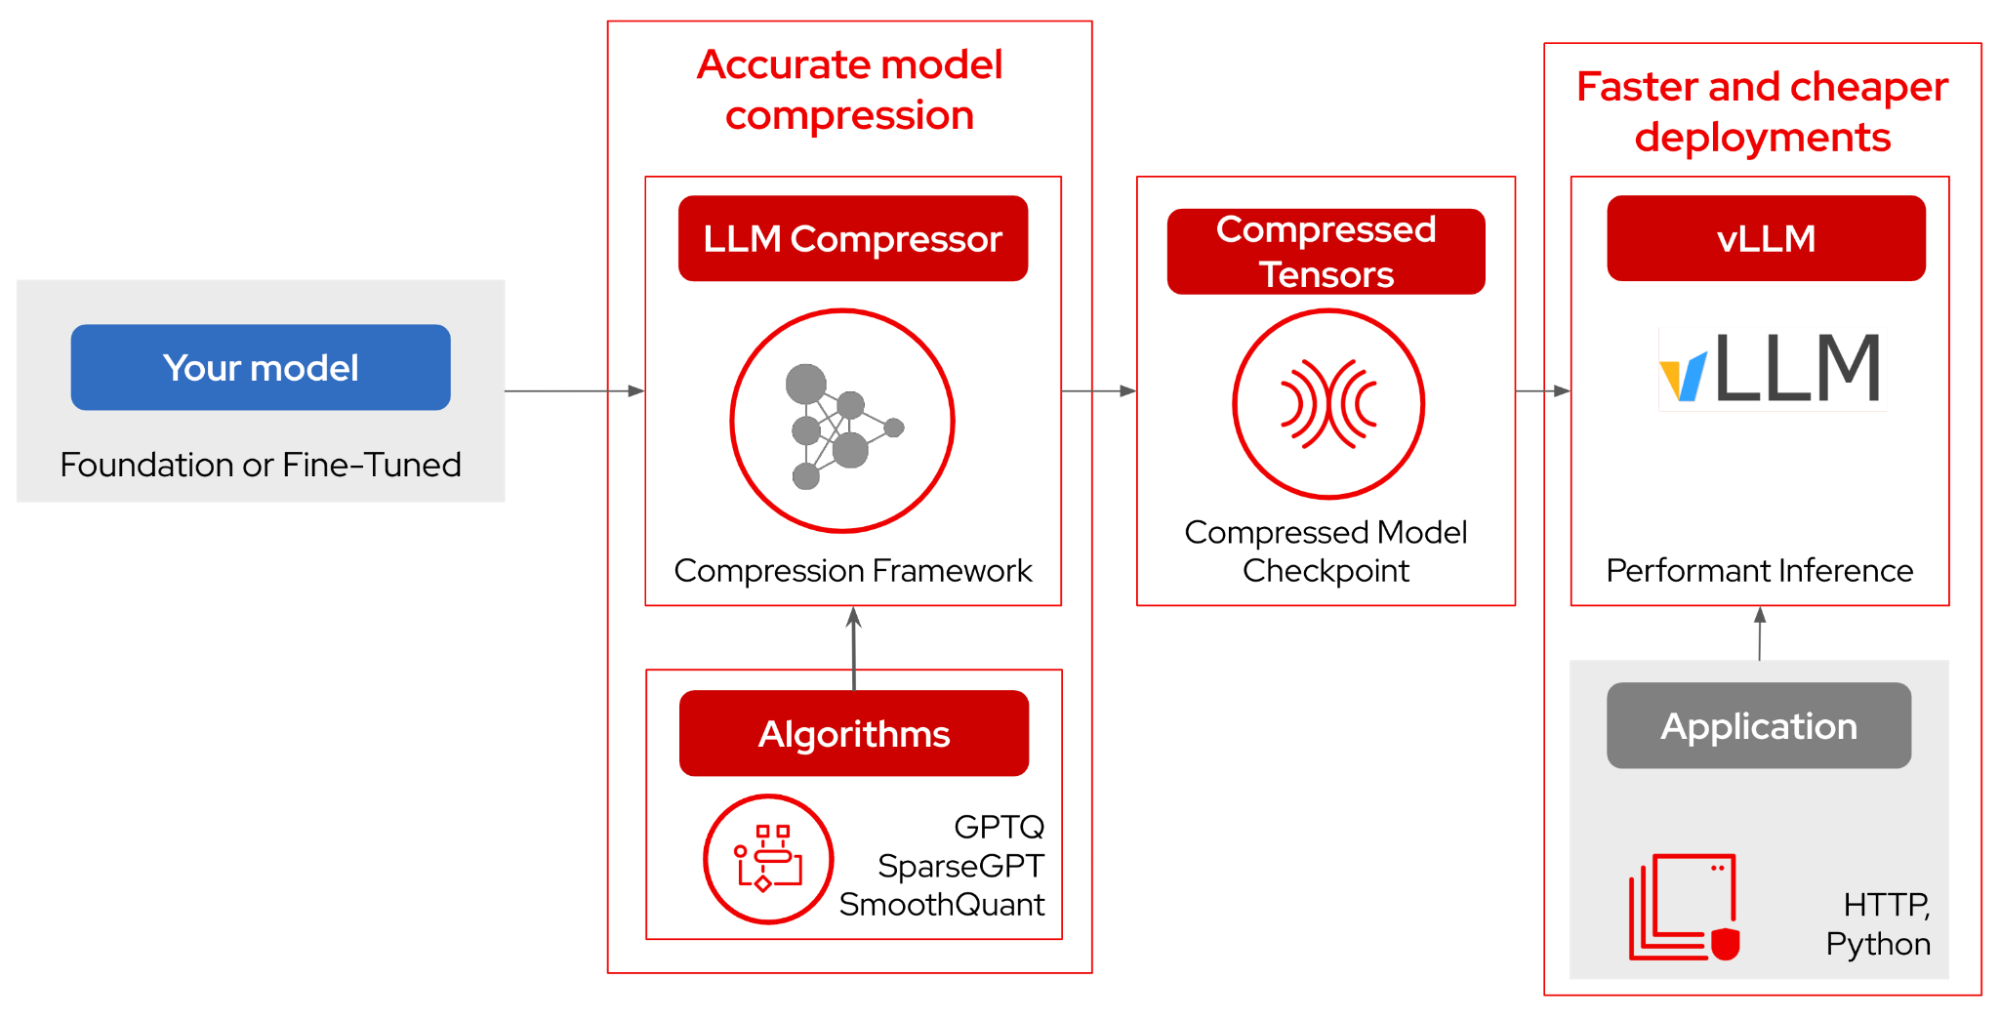
LLM compression and optimization: Cheaper inference with fewer hardware ...
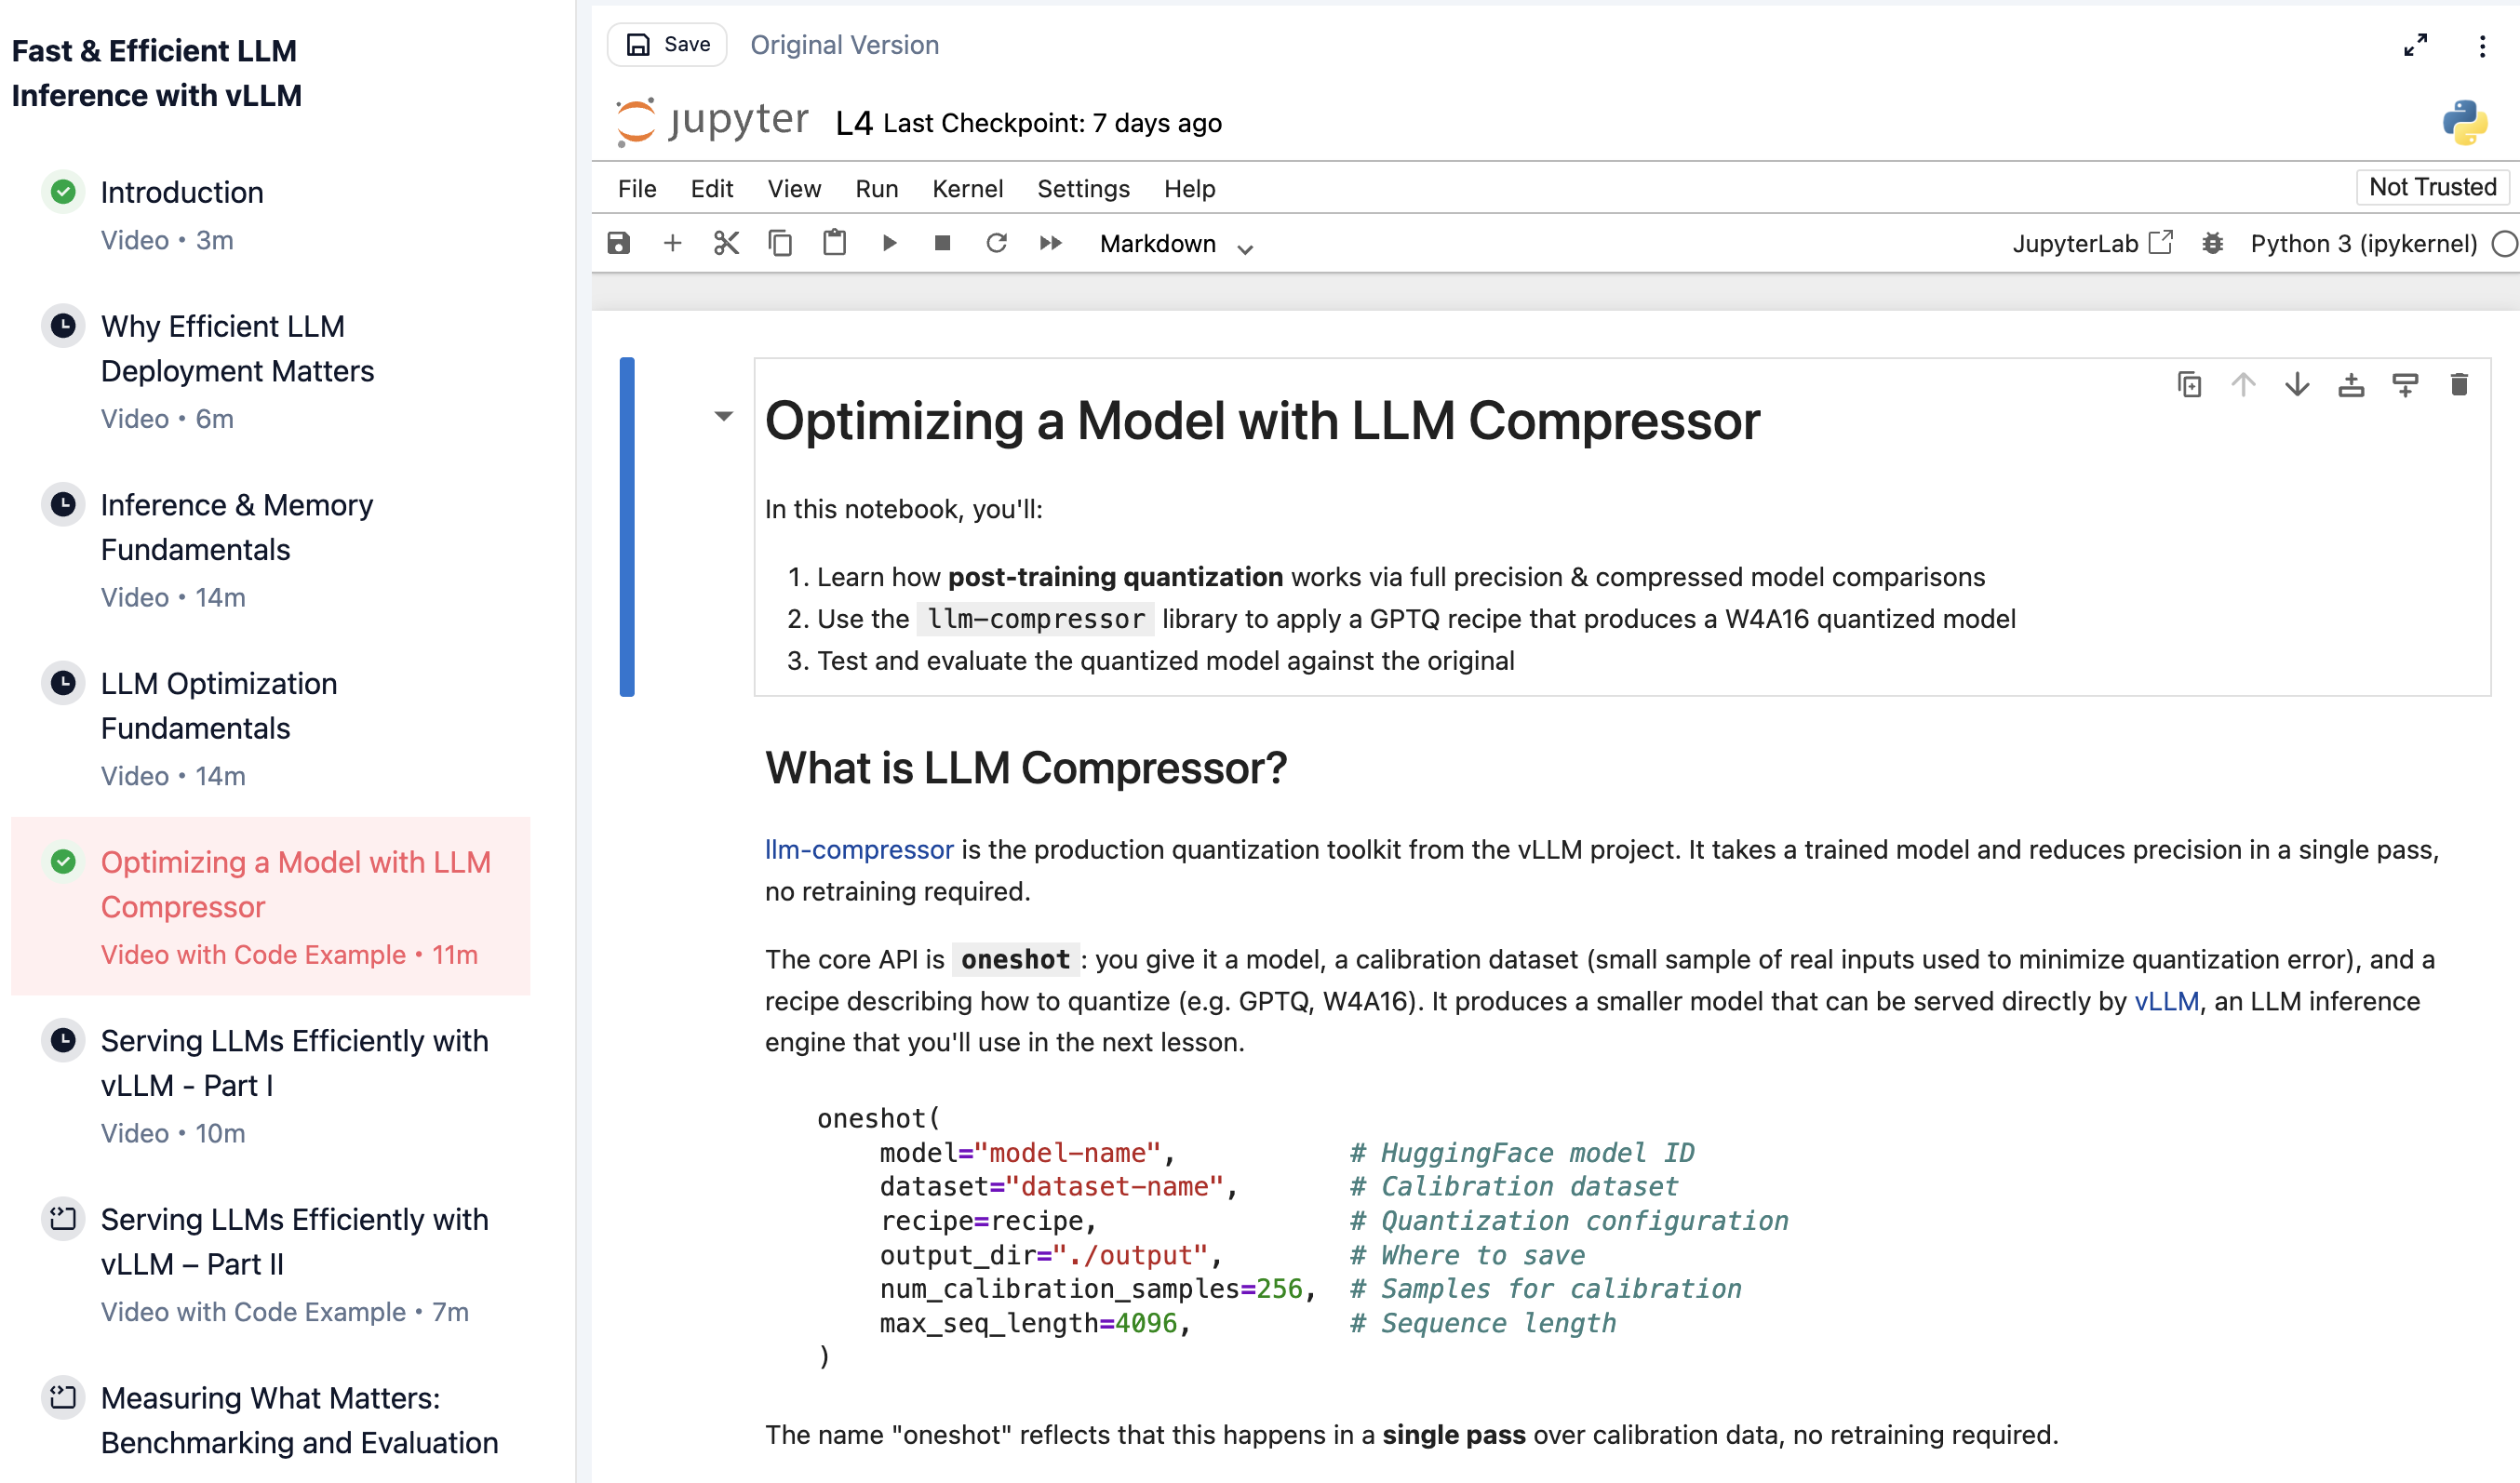
Fast & Efficient LLM Inference with vLLM: A New Course with ...

The Ultimate Handbook for LLM Quantization | Towards Data Science

LLM Compressor 0.7.0 release recap | Red Hat Developer
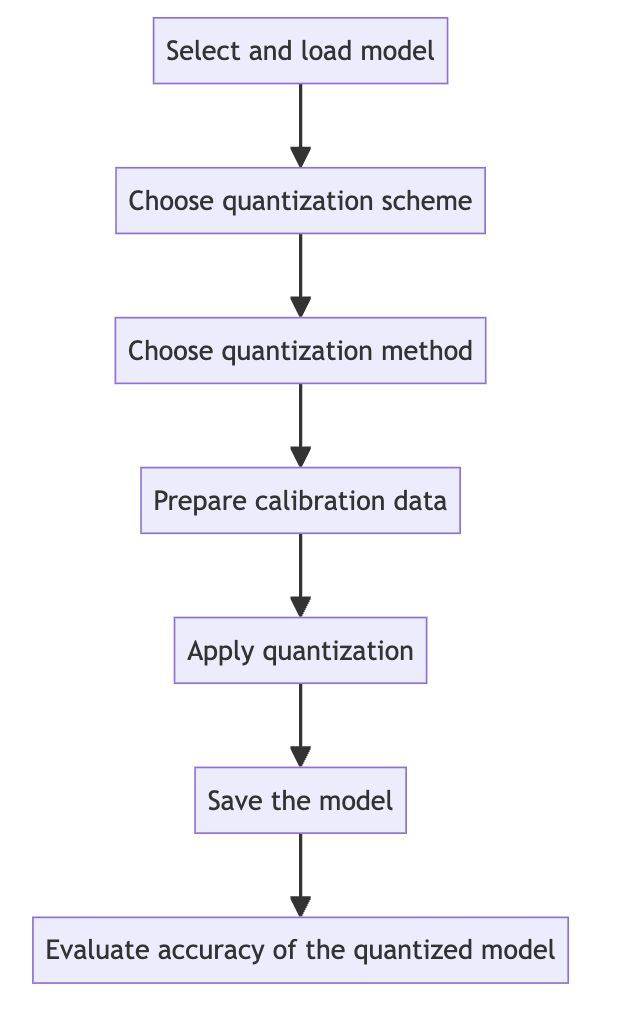
Model optimization :: LLM optimization and inference leveraging
Advertisement Space (336x280)

LongVQ: Long Sequence Modeling with Vector Quantization on Structured ...
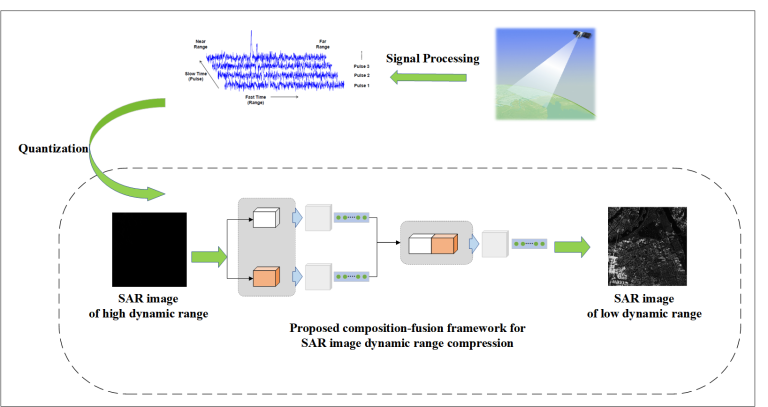
A Comprehensive Guide on LLM Quantization and Use Cases

The Great AI Compression: How LLM Quantization Solves the VRAM Bottleneck

Improving Sequential Recommendations with LLMs | ACM Transactions on ...
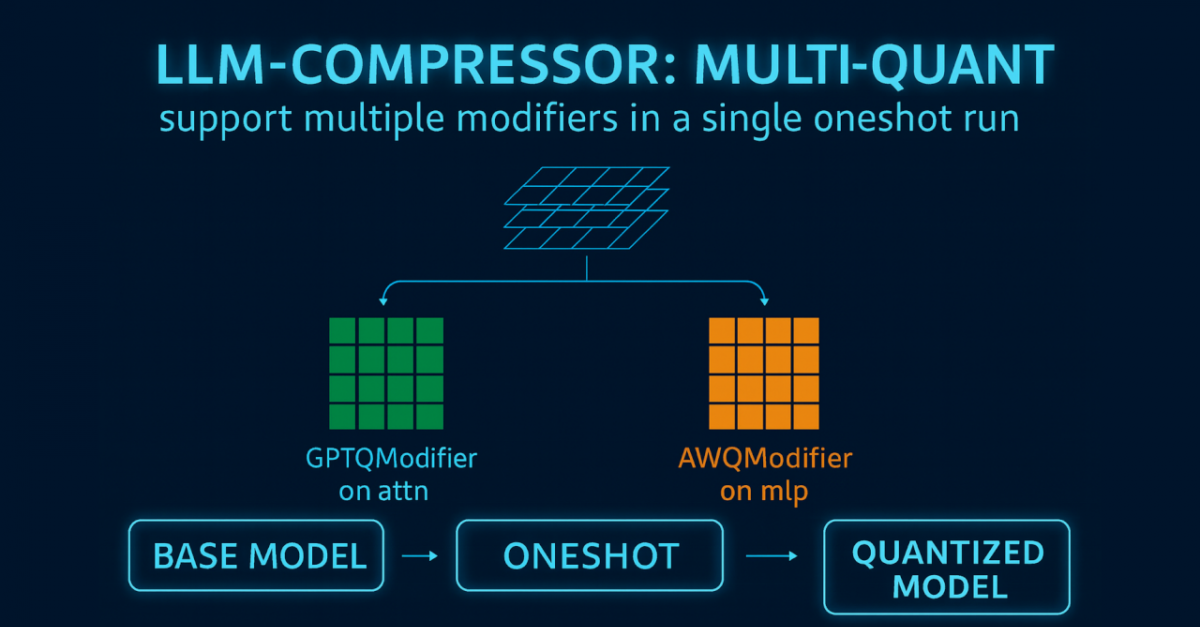
LLM Compressor 0.8.0: Extended support for Qwen3 and more | Red Hat ...
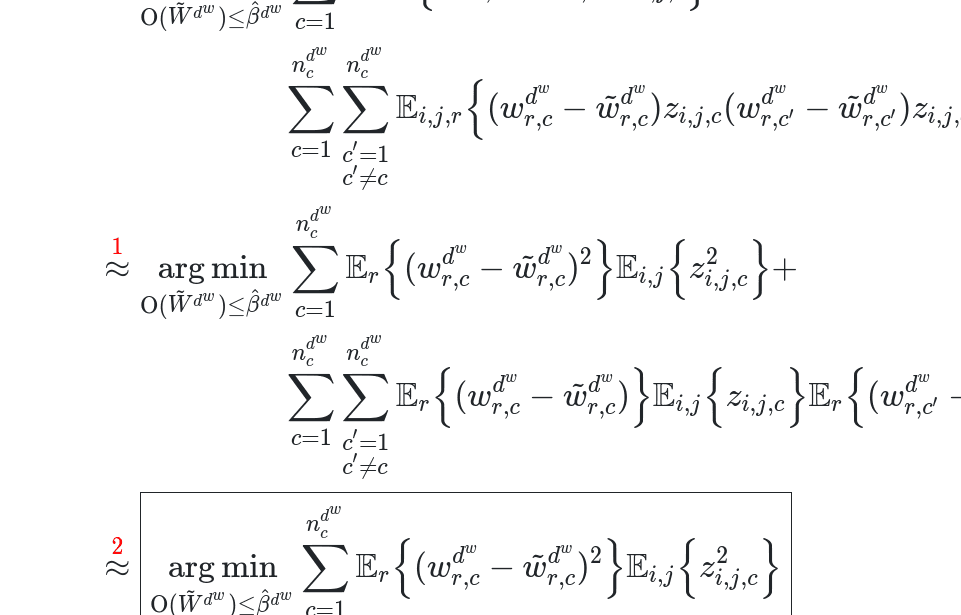
picoLLM — Towards Optimal LLM Quantization — Picovoice