
Bug Prefix Caching Doesnt Work On Cpu Vllm Issue 17954 Vllm
[Bug]: prefix caching doesn't work on CPU vLLM · Issue #17954 · vllm ...
[Bug]: Prefix caching does not work on Pascal GPUs · Issue #4438 · vllm ...
[Installation]: vLLM does not work on old CPU · Issue #4542 · vllm ...
[Usage]: Prefix caching in VLLM · Issue #5176 · vllm-project/vllm · GitHub
[Bug]: CPU infrencing won't work for DeepSeek-R1 · Issue #15044 · vllm ...
[Bug]: Prefix Caching with Multi-Lora Support · Issue #5475 · vllm ...
[Misc]: Prefix caching in the BlockManagerV2 · Issue #3667 · vllm ...
[Bug]: Prefix caching doesn't work for LlavaOneVision · Issue #11371 ...
[Bug]: Unable to embed any text using the vLLM CPU server · Issue #9379 ...
[Performance]: Prefix cache hit lower on vLLM than on other inference ...
Advertisement Space (300x250)
[Bug]: Exception: Invalid prefix encountered · Issue #17448 · vllm ...
[Bug]: VLLM run very very slow in ARM cpu · Issue #10706 · vllm-project ...
Automatic Prefix Caching Bug · Issue #3193 · vllm-project/vllm · GitHub
[Bug]: vLLM CPU mode broken Unable to get JIT kernel for brgemm · Issue ...
NotImplementedError: Vlm do not work with prefix caching yet · Issue ...
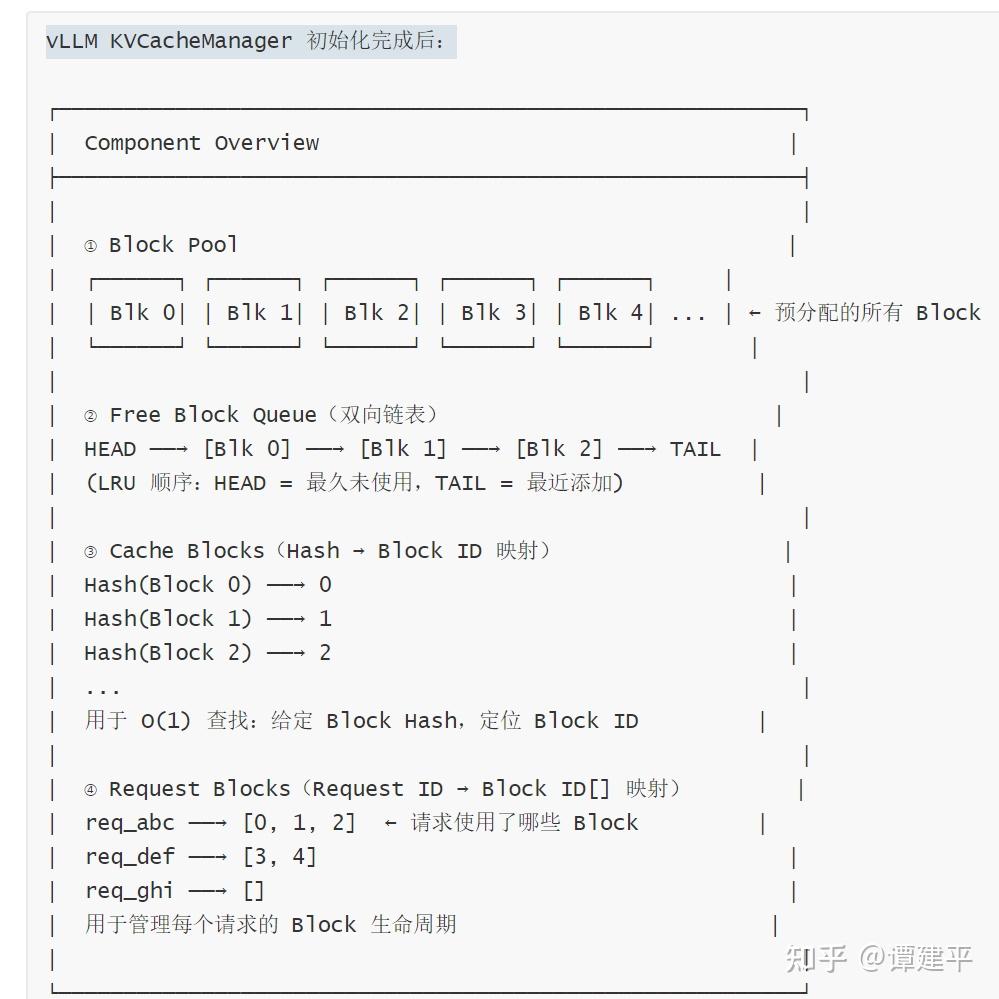
vLLM Automatic Prefix Caching (前缀缓存) 详细分析 - 知乎
[Bug]: AutoGen can't work with vLLM v0.5.1 · Issue #3120 · microsoft ...

Prefix caching in vLLM under multi-tenant agent traffic - DEV Community
Loading vLLM models into CPU memory · Issue #3327 · vllm-project/vllm ...
[Bug]: Issues with Applying LoRA in vllm on a T4 GPU · Issue #5199 ...
Advertisement Space (336x280)

Automatic Prefix Caching - vLLM
Clarification on Serverless vLLM image caching - Runpod
[Feature]: Prefix cache aware load balancing · Issue #11477 · vllm ...

Automatic Prefix Caching - vLLM
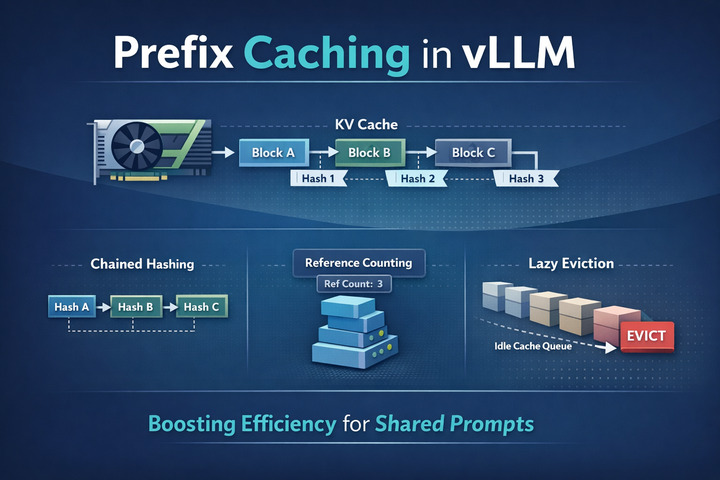
vLLM Prefix Caching详解:引用计数与LRU缓存驱逐策略 - 知乎

Caching Strategies for VLM Inference: vLLM APC vs LangChain Cache | by ...
vLLM stops all processing when CPU KV cache is used, has to be shut ...
[Bug]: Unable to Use Prefix Caching in AsyncLLMEngine · Issue #5162 ...
[Bug]: illegal memory access error when using prefix caching · Issue ...
[Bug]: vllm 0.8.3 serve error · Issue #15457 · vllm-project/vllm · GitHub
Advertisement Space (336x280)
[Bug]: Error Running Llama 3.2 1B on CPU · Issue #9037 · vllm-project ...
[Usage]: prefix caching support for multimodal models · Issue #9790 ...
[Bug]: Ngram speculative decoding doesn't work in vLLM 0.8.3/0.8.4 with ...
[Bug]: When using the VLLM framework to load visual models, CPU memory ...
Error when prompt_logprobs + enable_prefix_caching · Issue #3251 · vllm ...
[Bug]: vLLM doesn't release memory on deletion of the LLM runner with ...