
Usage Prefix Caching In Vllm Issue 5176 Vllm Projectvllm Github
[Usage]: Prefix caching in VLLM · Issue #5176 · vllm-project/vllm · GitHub
Inquiry Regarding Prefix Caching in the vllm Baseline · Issue #2 ...
[Usage]: Do vllm support the prefix caching in multi node? · Issue ...
[Misc]: Prefix caching in the BlockManagerV2 · Issue #3667 · vllm ...
[Bug]: prefix caching doesn't work on CPU vLLM · Issue #17954 · vllm ...
[Bug]: Prefix Caching with Multi-Lora Support · Issue #5475 · vllm ...
[Bug]: Prefix caching does not work on Pascal GPUs · Issue #4438 · vllm ...

Prefix caching in vLLM under multi-tenant agent traffic - DEV Community
[Bug]: Unable to Use Prefix Caching in AsyncLLMEngine · Issue #5162 ...
[Feature]: Prefix cache aware load balancing · Issue #11477 · vllm ...
Advertisement Space (300x250)
[Usage]: Automatic Prefix Cache life cycle · Issue #12077 · vllm ...
[RFC] Automatic Prefix Caching · Issue #2614 · vllm-project/vllm · GitHub
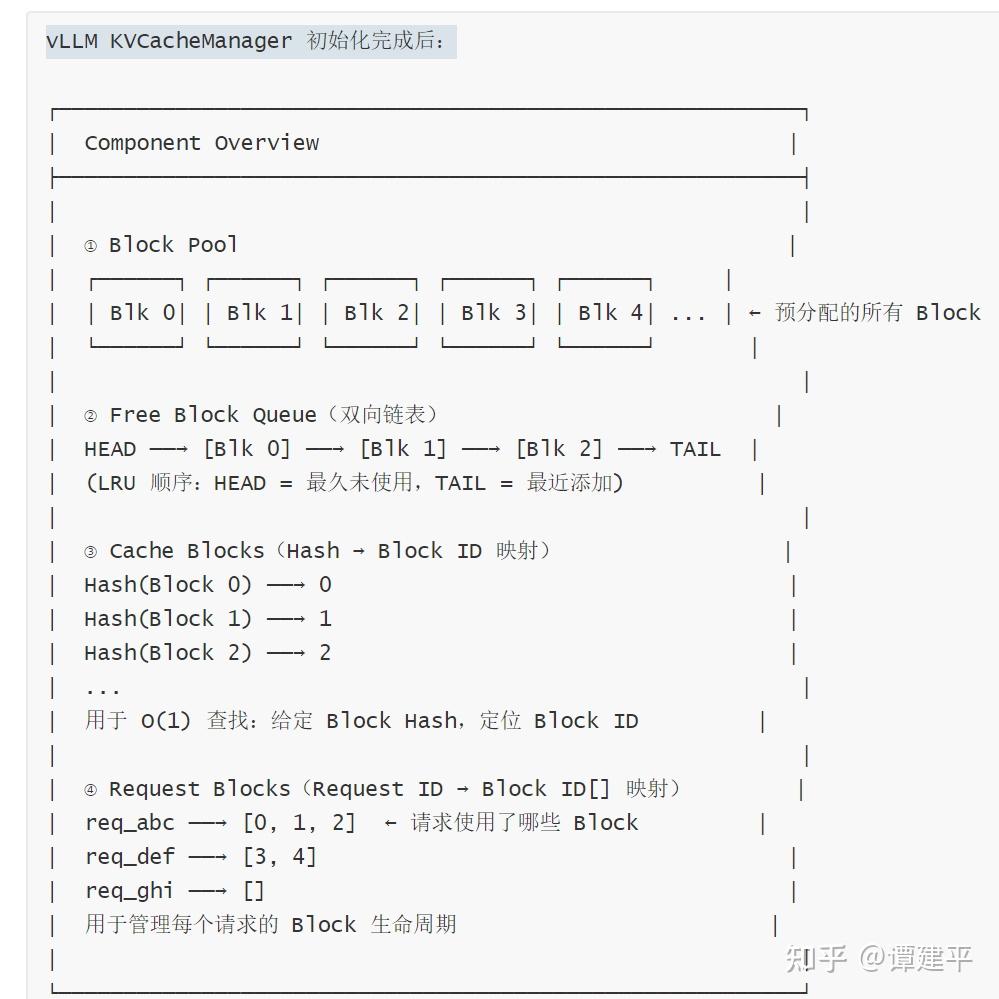
vLLM Automatic Prefix Caching (前缀缓存) 详细分析 - 知乎
Automatic Prefix Caching Bug · Issue #3193 · vllm-project/vllm · GitHub
usage of vllm for extracting embeddings · Issue #1654 · vllm-project ...

Automatic Prefix Caching - vLLM
[Bug]: Critical Memory Leak in vLLM V1 Engine: 200+ GB RAM Usage from ...
[RFC]: vLLM plugin system · Issue #7131 · vllm-project/vllm · GitHub
[RFC]: Deprecating vLLM V0 · Issue #18571 · vllm-project/vllm · GitHub
[Bug]: vllm 0.8.3 serve error · Issue #15457 · vllm-project/vllm · GitHub
Advertisement Space (336x280)
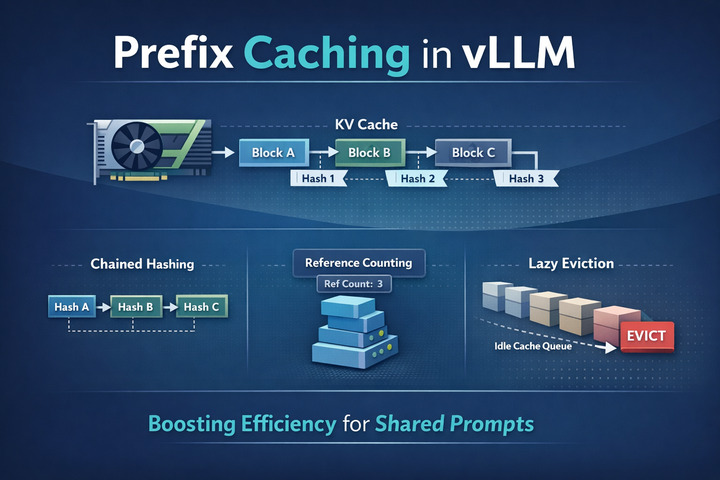
vLLM Prefix Caching详解:引用计数与LRU缓存驱逐策略 - 知乎

Caching Strategies for VLM Inference: vLLM APC vs LangChain Cache | by ...
[Usage]: prefix caching support for multimodal models · Issue #9790 ...
Error when prompt_logprobs + enable_prefix_caching · Issue #3251 · vllm ...
[Usage]: Using VLLM with Langchain for RAG purposes · Issue #5572 ...
[Performance]: Automatic Prefix Caching in multi-turn conversations ...
[Feature]: continuous batching for vllm.LLM · Issue #7353 · vllm ...
prefix caching error with baichuan model · Issue #2513 · vllm-project ...
[Bug]: VLLM_USE_V1=1 failed with deepseek-v3 · Issue #12956 · vllm ...
[Bug]: illegal memory access error when using prefix caching · Issue ...
Advertisement Space (336x280)
[Bug]: Prefix caching doesn't work for LlavaOneVision · Issue #11371 ...
[Performance]: reproducing vLLM performance benchmark · Issue #8176 ...
[Usage]: How to use breakpoints with VLLM to debug · Issue #13120 ...
[Usage]: How to stop VLLM during generation ? · Issue #8332 · vllm ...
[Bug]: VLLM Build Using Docker Error Deploy · Issue #15376 · vllm ...
[Usage]: vLLM For maximally batched use case · Issue #9760 · vllm ...