
Bug Using Vllm As The Inference Engine There Is An Incorrect
[Bug]: Using vllm as the inference engine, there is an incorrect ...

Want to deploy open models using vLLM as the inference engine? We just ...

How the VLLM inference engine works? - YouTube

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...

How the vLLM inference engine works? - DevOps Video | Pulse
[Bug]: Qwen2.5 VL offline inference example bug · Issue #19130 · vllm ...
[Bug]: Incorrect Example for the Inference with Prefix · Issue #5177 ...

vLLM vs TensorRT-LLM: Which Inference Engine Should You Use in 2026 ...
[Bug]: Unable to embed any text using the vLLM CPU server · Issue #9379 ...
[Bug]: vllm 0.8.3 v1 engine CUDA Graph Capturing time is too long ...
Advertisement Space (300x250)
What is vLLM? | High-Throughput LLM Inference Engine | Inference Systems
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
VLLM Inference Engine | omni-ai-npu/omni-infer | DeepWiki
[Bug]: When using the locally deployed vLLM large model, the server ...

An End‑to‑End View of AI Inference Stacks with vLLM and Alternatives
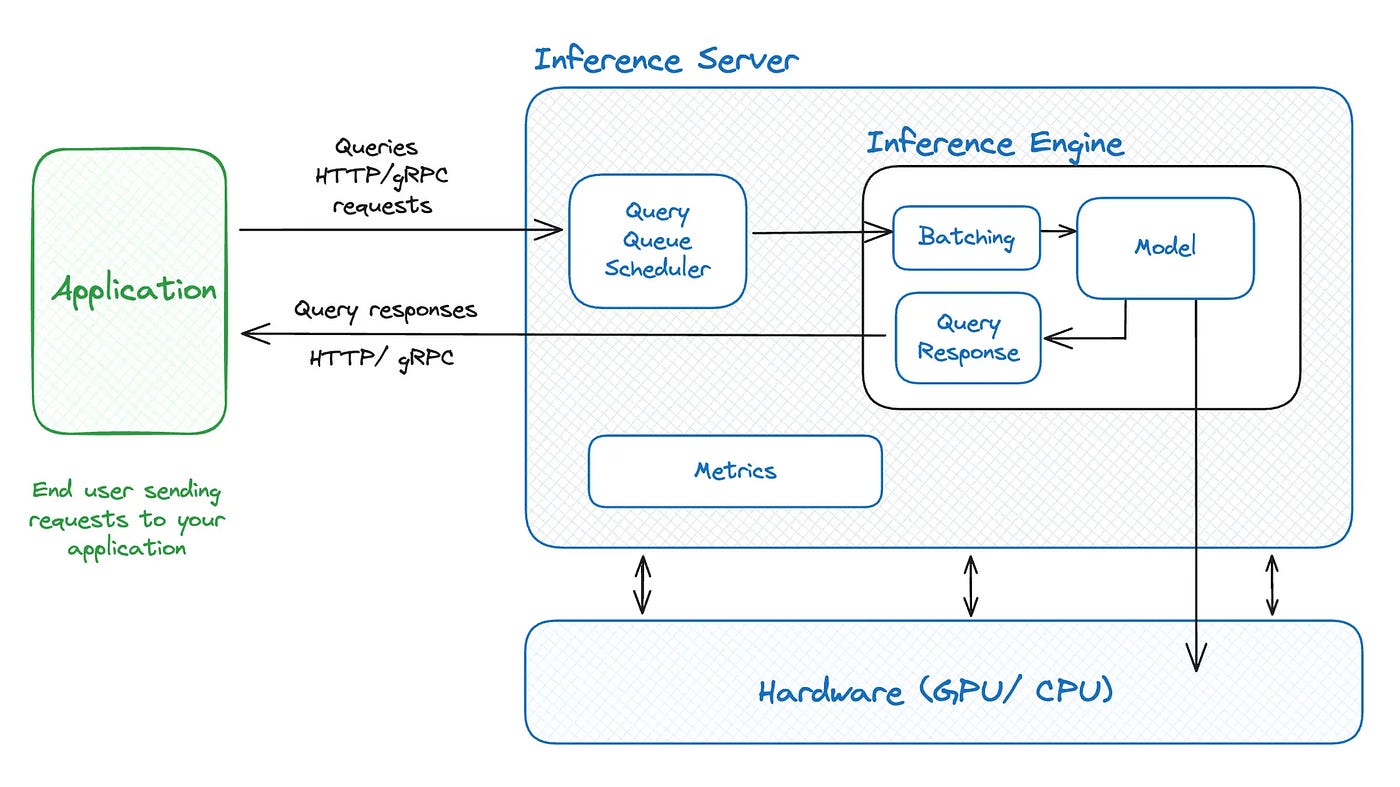
Nano vLLM: A Tiny Inference Engine that Teaches you the Big Ideas ...
vLLM Review: High-Performance LLM Inference Engine for GPU ...
[Bug]: InternVL2 Inference RuntimeError: GET was unable to find an ...
[Bug]: llava inference result is wrong ! · Issue #4831 · vllm-project ...
[Bug]: Qwen2-VL-72B-Instruct Inference failure · Issue #115 · vllm ...
Advertisement Space (336x280)
[Bug]: v0.8.2 vLLM engine crashes when starting after V1 environment ...
[Bug]: When using multi-node offline distributed inference, VLLM gets ...
[Bug]: Runtime Error: GET was unable to find an engine to execute this ...
[Bug]: inferences are not the same with batch mode when using · Issue ...
[Bug]: ValueError: There is no module or parameter named 'mlp_AR' in ...
[Bug]: vLLM Multinode Pipeline Error with pipeline parallelism using ...
[Bug]: Qwen2-VL-72B Inference on Multiple-GPUs · Issue #9363 · vllm ...
inference Bug · Issue #1130 · vllm-project/vllm · GitHub
[Bug]: Qwen2.5-32B-GPTQ-Int4 inference `!!!!!` · Issue #10656 · vllm ...
[Bug]: Can't use offline inference embedding · Issue #4908 · vllm ...
Advertisement Space (336x280)

What is vLLM: Unveiling the Mystery
[Bug]: vllm wrong raised the ERROR : Failed to import vllm_ascend_C:No ...
vLLM: High-Throughput LLM Inference Engine | Inference Systems
Possible sampling parameter bug in VLLM Server · Issue #2754 · vllm ...
[Bug]: vllm much slower on long context inputs when using --enable-lora ...
[Bug]: Can't deploy DeepSeek R1 with lora failure on vLLM Engine V1 ...