
Bug Vllm Doesnt Release Memory On Deletion Of The Llm Runner With
[Bug]: vLLM doesn't release memory on deletion of the LLM runner with ...
vLLM CUDA Out of Memory Fix: GPU Optimization for LLM Serving (2026)
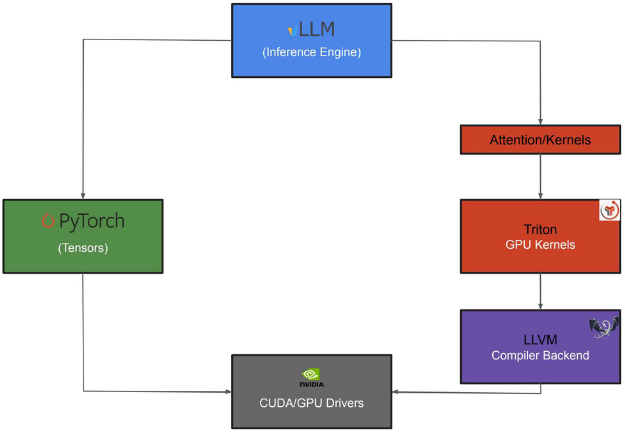
LLM Inference with vLLM Using GPU on Power9
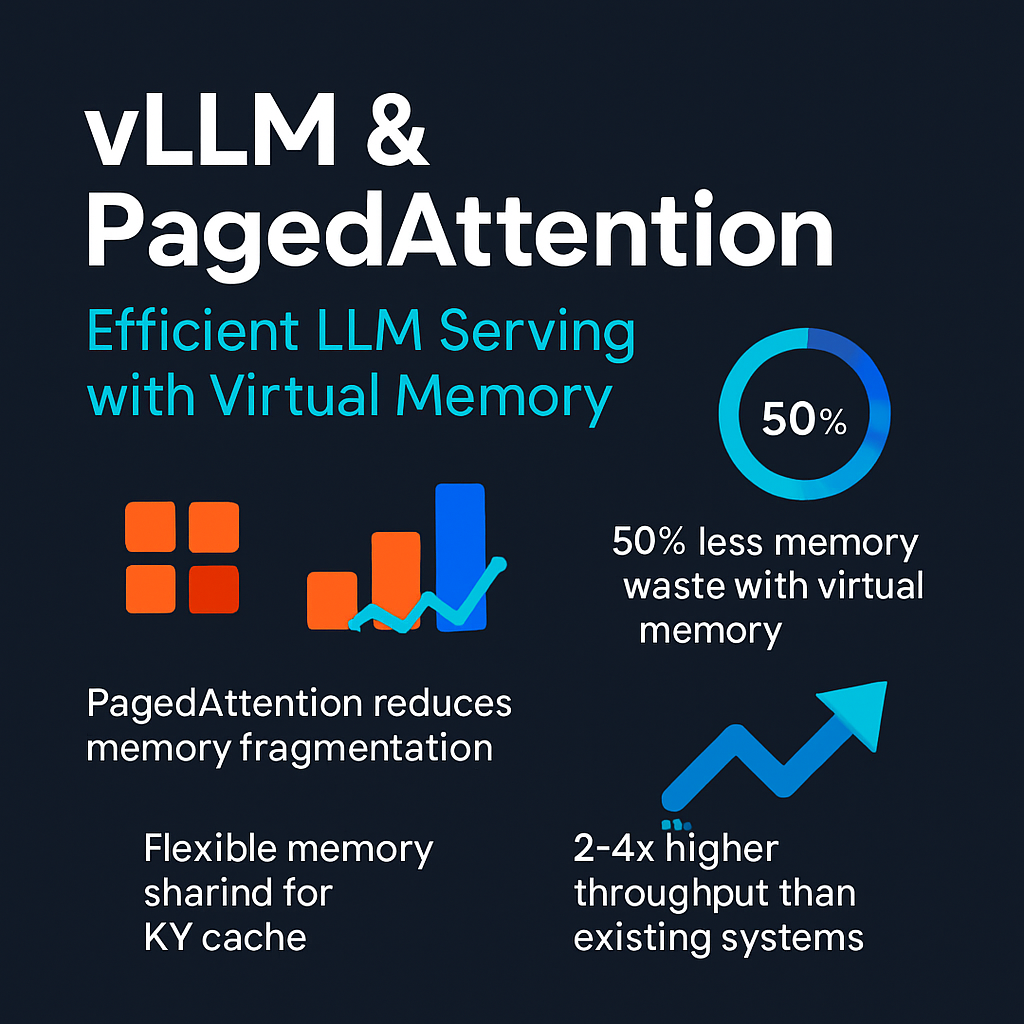
vLLM & PagedAttention: Efficient LLM Serving with Virtual Memory — AI ...
[Bug]: Ray + vLLM failing to automatically release GPU memory when ...
[Bug ] Memory leak on latest release 0.2.7 · Issue #2624 · vllm-project ...

Memory Management and Scheduling in the vLLM Engine | by Priyadarshini ...
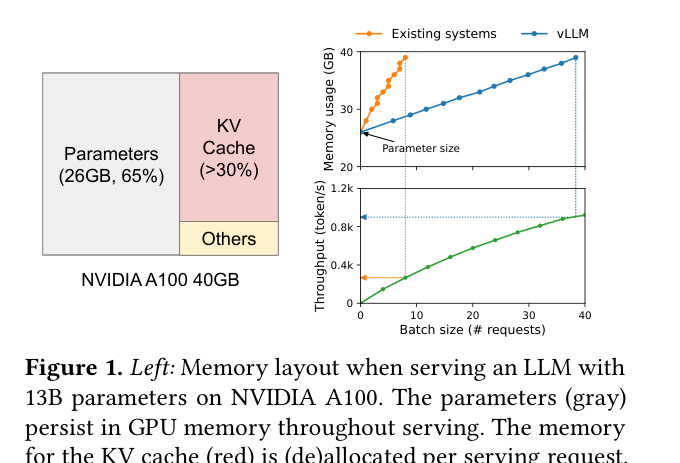
vLLM & PagedAttention: Memory Revolution in LLM Inference | AI Learning ...
[Bug]: When using the VLLM framework to load visual models, CPU memory ...

vLLM (4) - LLMEngine上篇_this happens when the gpu memory was not ...
Advertisement Space (300x250)

Install vLLM on Linux for Production LLM Serving (2026 Guide)
[Bug]: Critical Memory Leak in vLLM V1 Engine: 200+ GB RAM Usage from ...
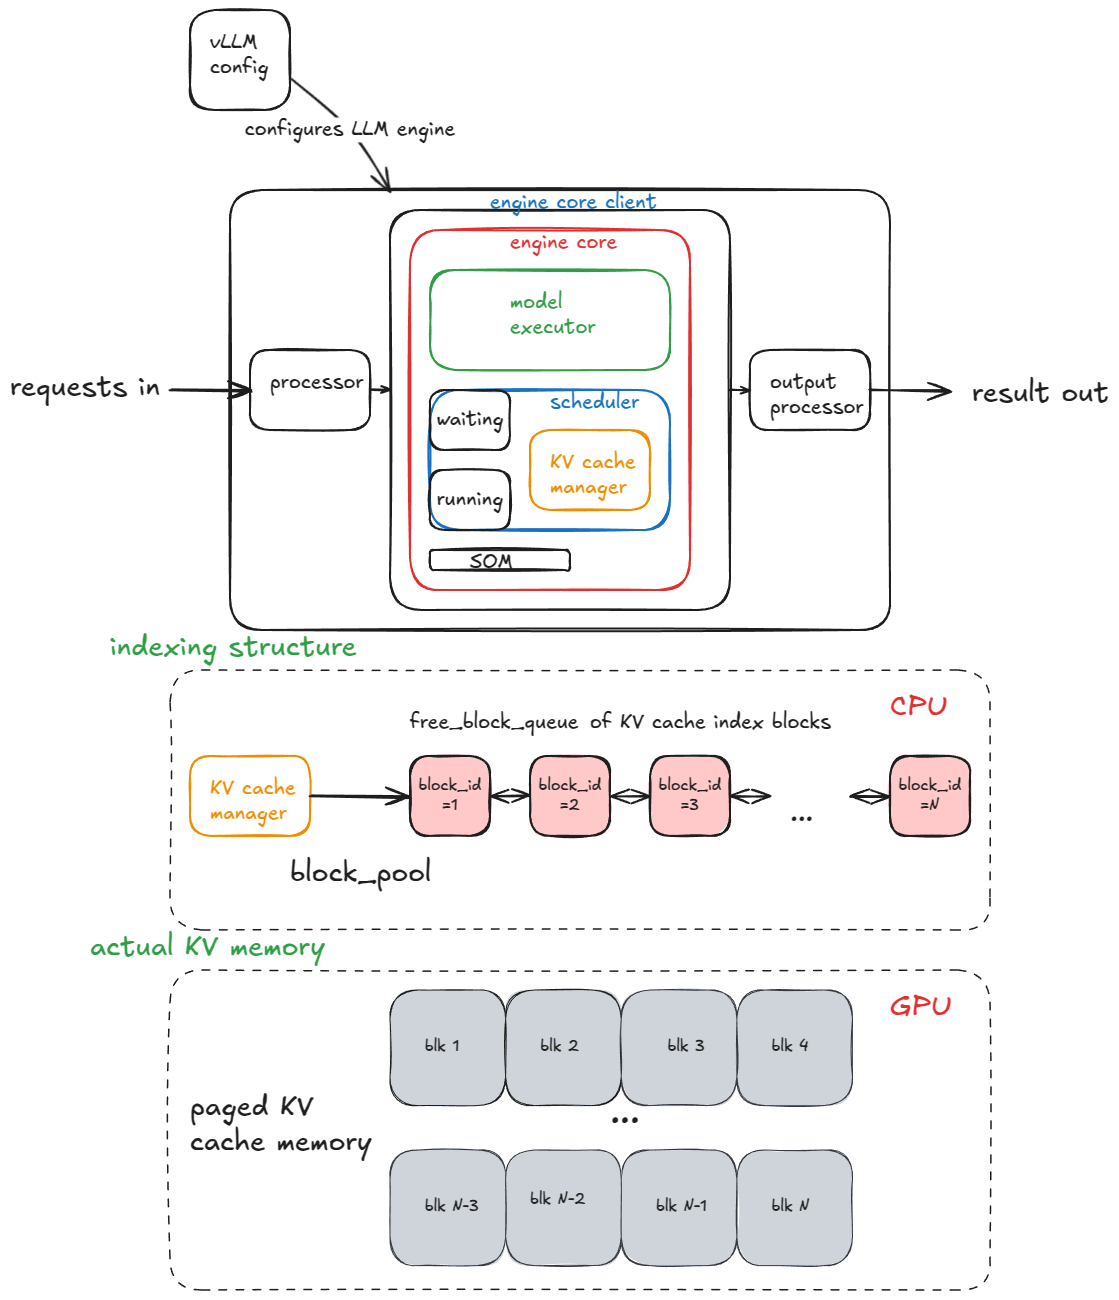
vLLM 내부: 초고처리량 LLM 추론 시스템의 해부 - Aleksa Gordić - RosettaLens 번역
Debugging Memory Leak in vLLM - Datatunnel

Efficient AI Lecture 13: LLM Deployment Techniques The lecture helped ...
[Bug]: Can't load any LLM with v0.8.* · Issue #15631 · vllm-project ...
vLLM memory management analysis

UC Berkeley researchers solved the biggest bottleneck in LLM inference ...
[BUG] vLLM Baichuan model is not working in latest vLLM release · Issue ...
[Bug]: The vllm is disconnected after running for some time · Issue ...
Advertisement Space (336x280)
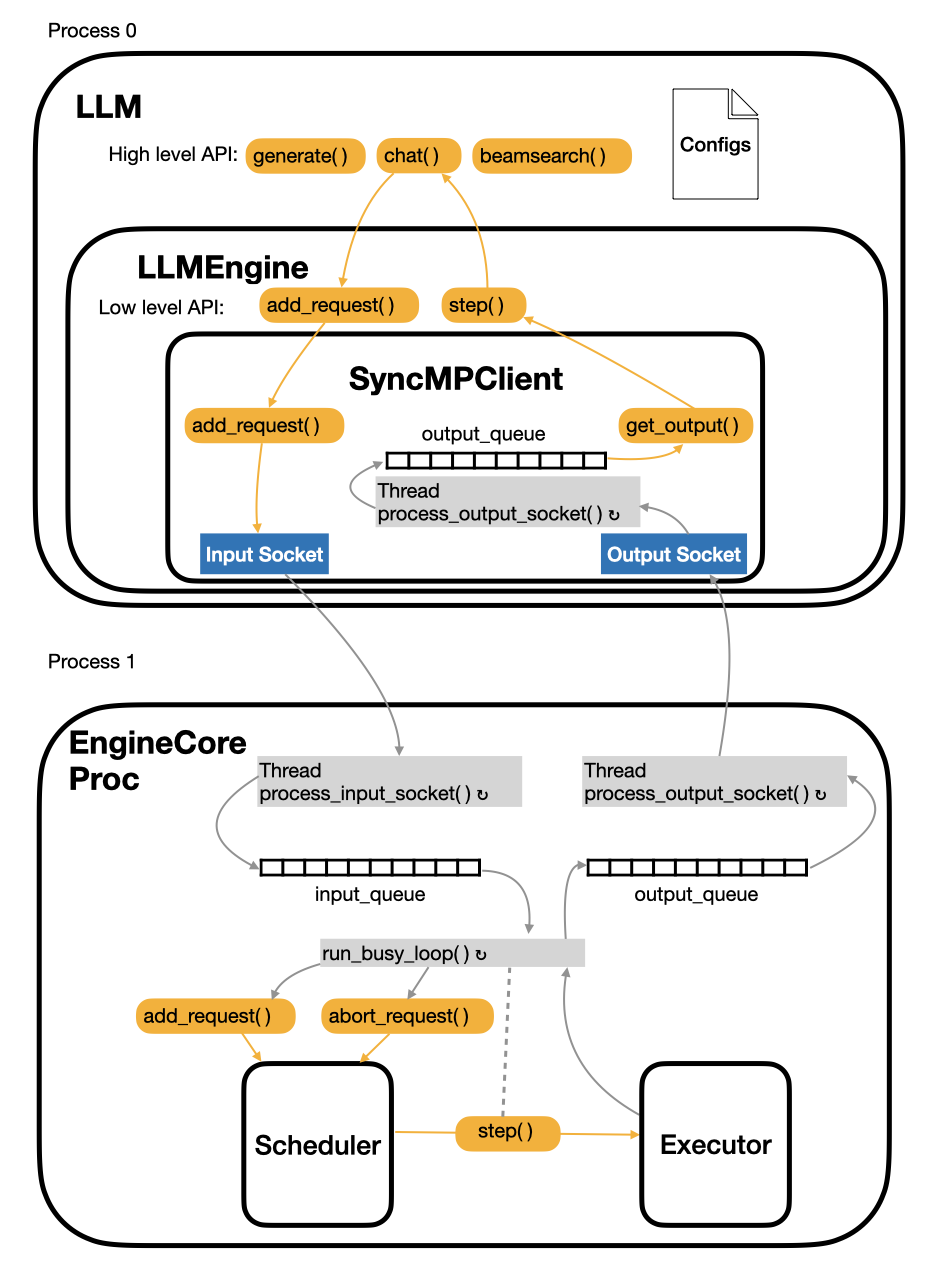
vLLM V1 Engine Design Ⅰ: The Excution Loop - Haisheng's Note Zoo
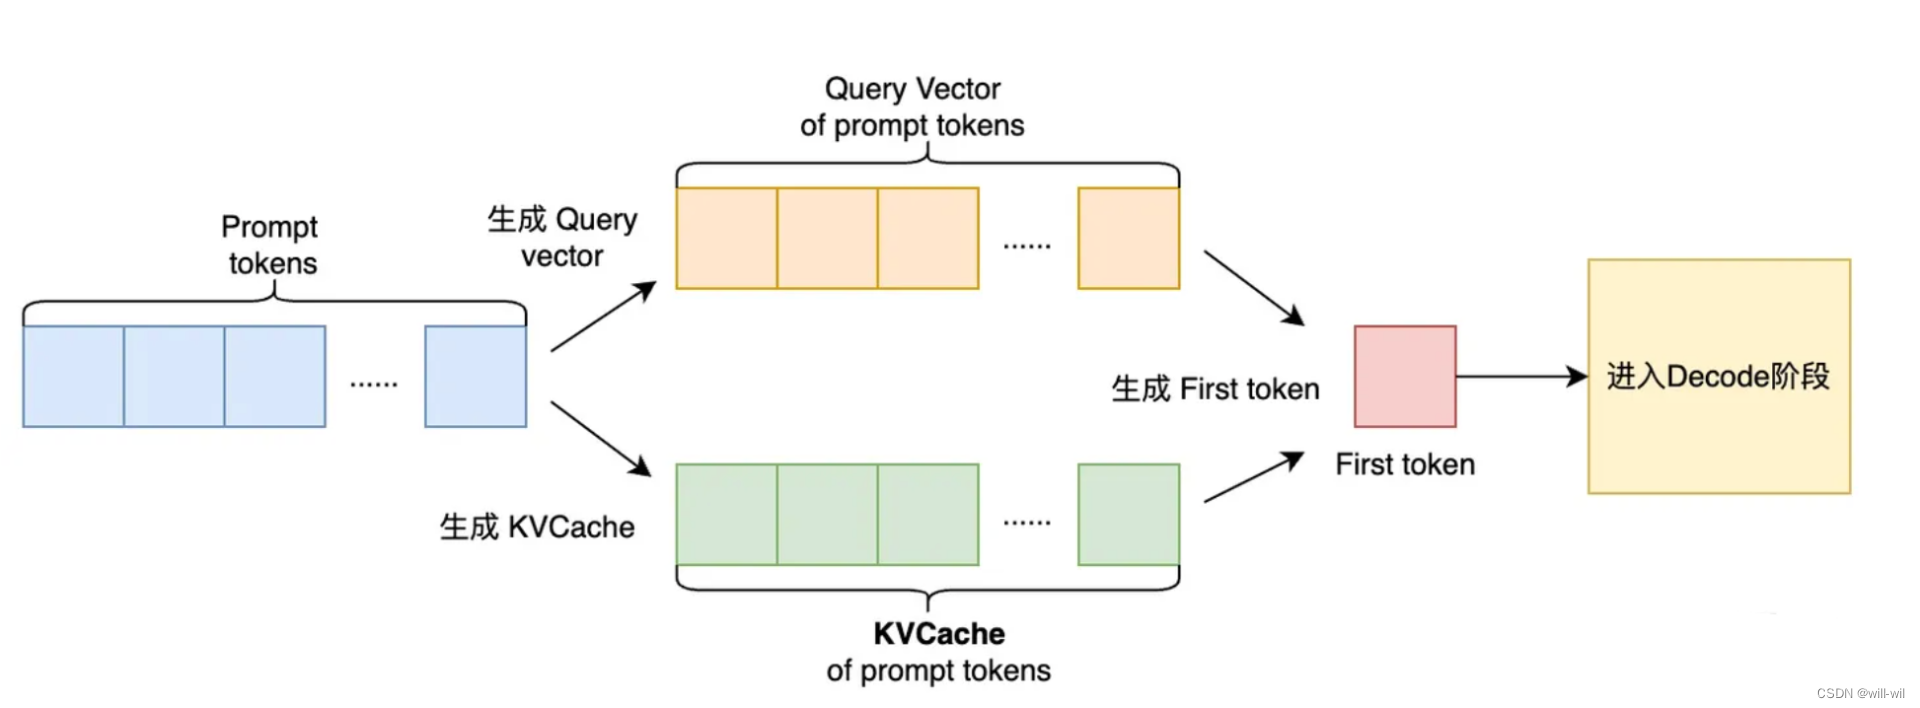
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
[Bug]: When using the locally deployed vLLM large model, the server ...
[Bug]: Docker vLLM 0.9.1 CUDA error: an illegal memory access, sampled ...

vLLM 完整使用教學 2026:PagedAttention 高吞吐量 LLM 推論引擎完整指南
[Bug]: VLLM_USE_V1=1 failed with deepseek-v3 · Issue #12956 · vllm ...
[Bug]: gemma-2-27b error loading with vllm.LLM · Issue #6192 · vllm ...

Free Video: vLLM Inference and LLM Server Engine for Machine Learning ...
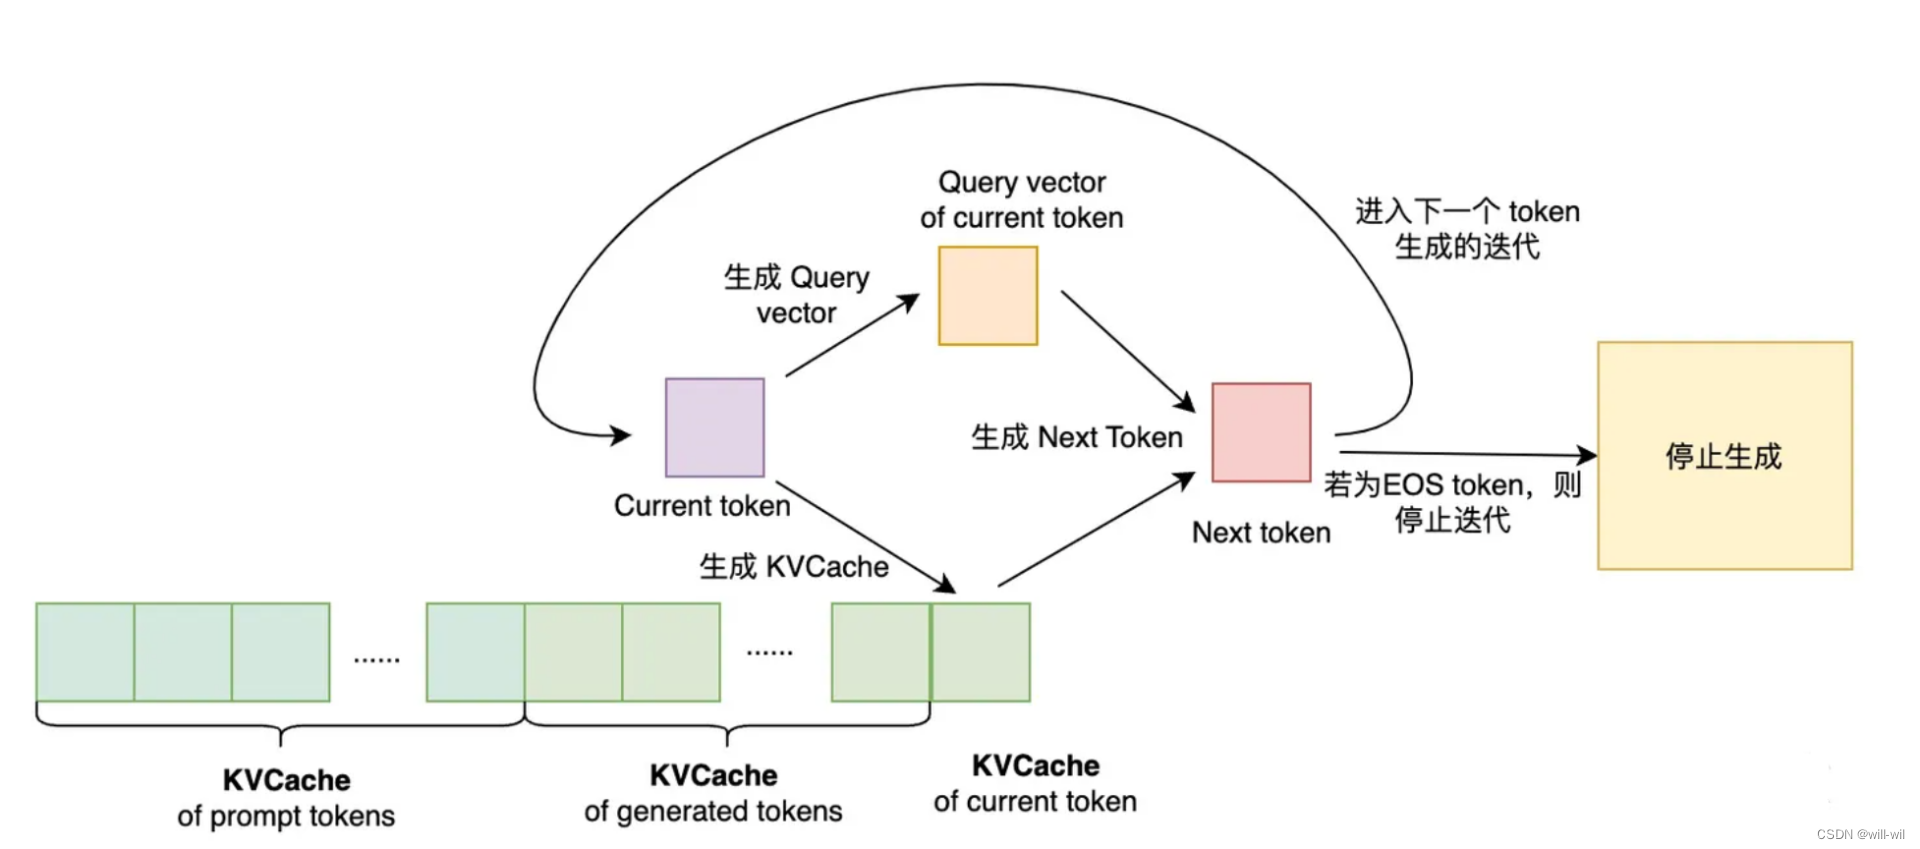
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
[Bug]: Unable to embed any text using the vLLM CPU server · Issue #9379 ...
Advertisement Space (336x280)
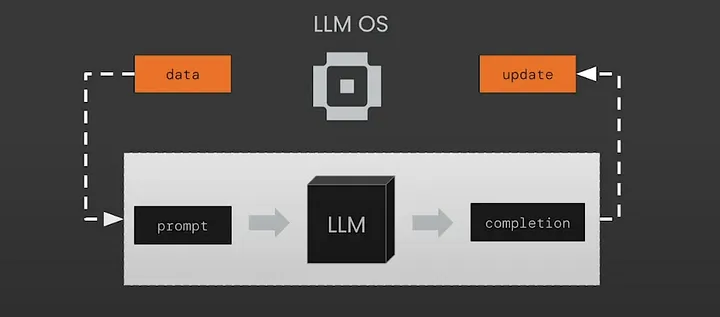
Memory in LLM Agent - Viblo

vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
[Bug]: memory usage is greater than expected · Issue #16184 · vllm ...
Bug - vllm not working for L4 GPUs and tensor_parallel_size > 1 · Issue ...
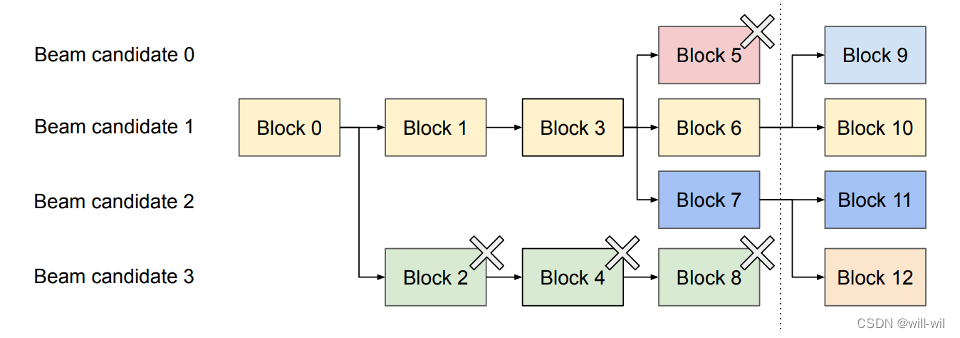
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
[Bug]: VLLM process dies when trying to profile with nsight systemss ...