
Llm Inference With Vllm Using Gpu On Power9
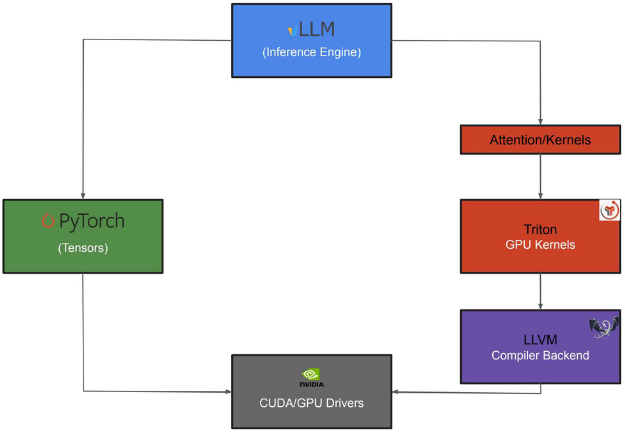
LLM Inference with vLLM Using GPU on Power9
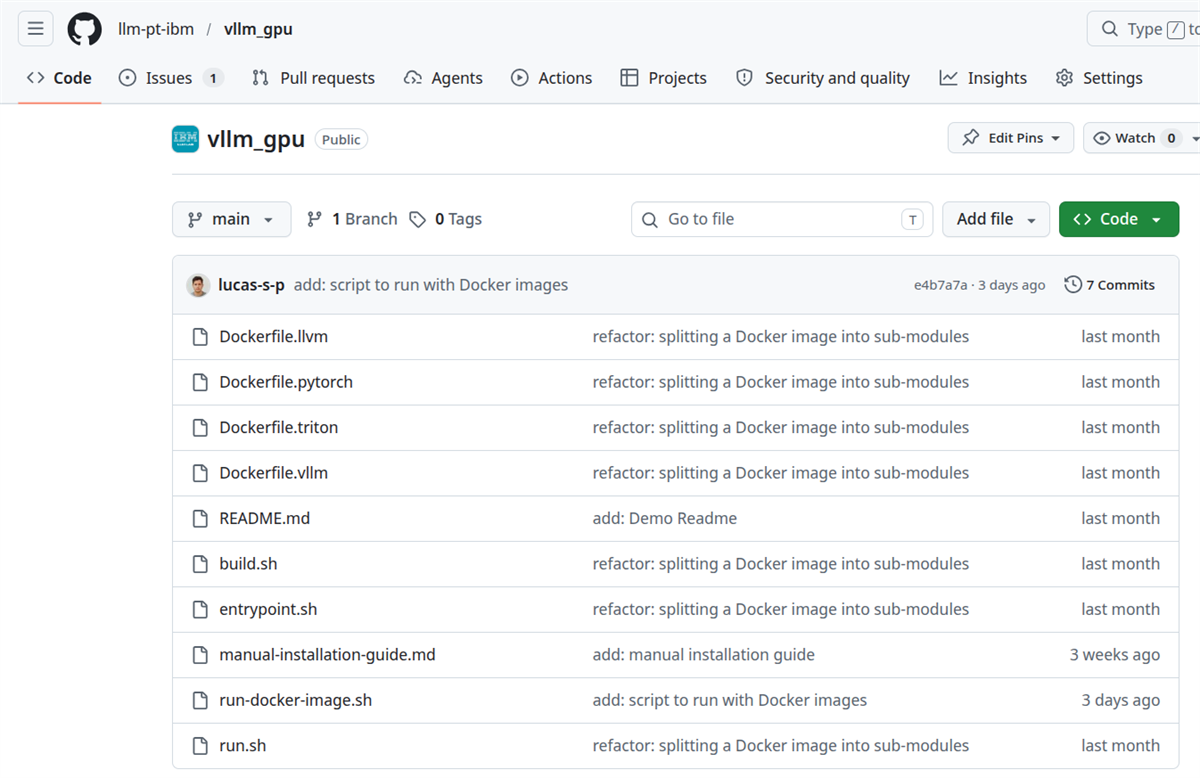
LLM Inference with vLLM Using GPU on Power9
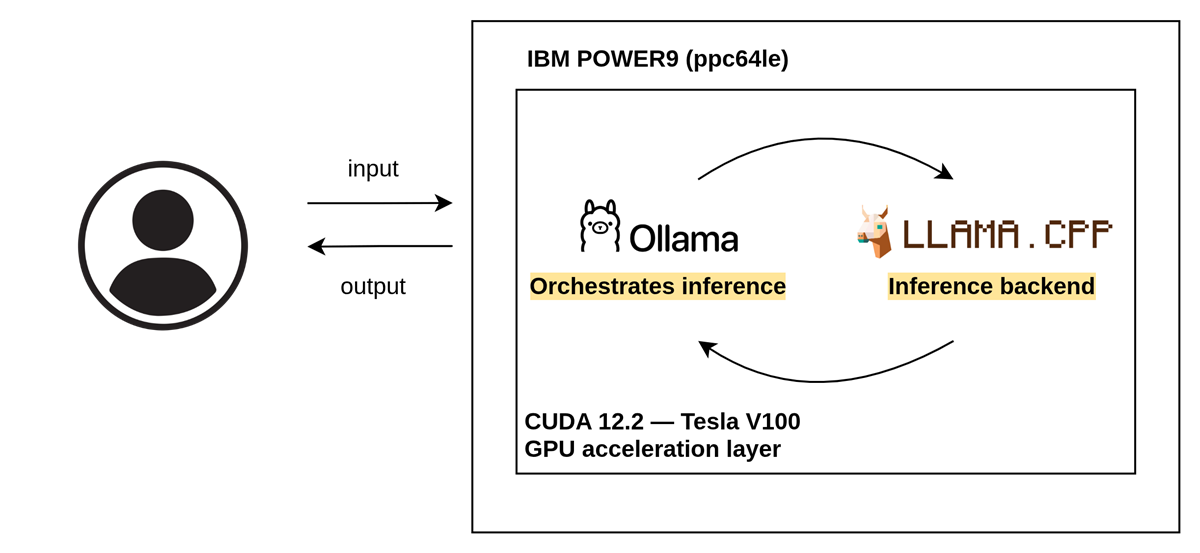
LLM Inference with Ollama on IBM POWER9 using the GPU
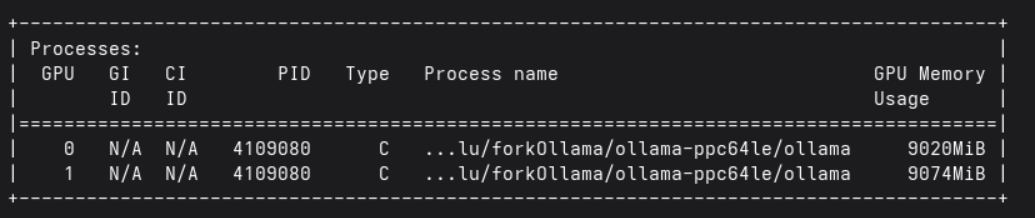
LLM Inference with Ollama on IBM Power9 Using GPU - IBM UFCG
Deploy FlashInfer on GPU Cloud: LLM Inference Kernels for vLLM and ...
vLLM Model Runner V2 on GPU Cloud: Deploy MRV2 for Faster LLM Inference ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

vLLM Review: High-Performance LLM Inference Engine for GPU ...
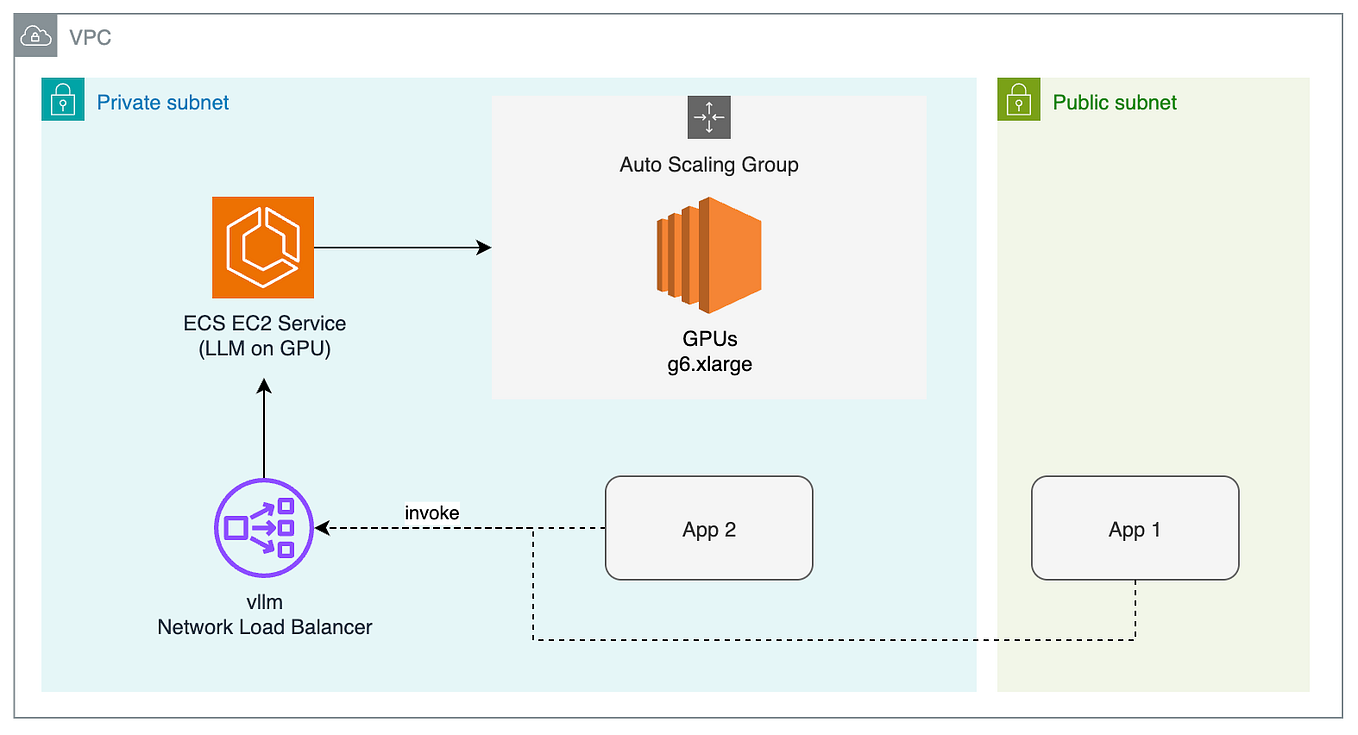
LLM Inference on multiple GPUs with 🤗 Accelerate | by Geronimo | Medium

LLM Inference on multiple GPUs with 🤗 Accelerate | by Geronimo | Medium
Advertisement Space (300x250)

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Optimized LLM inference API for Mistral 7B using vLLM - a Lightning ...

Accelerating LLM Inference with vLLM - APC 技術ブログ
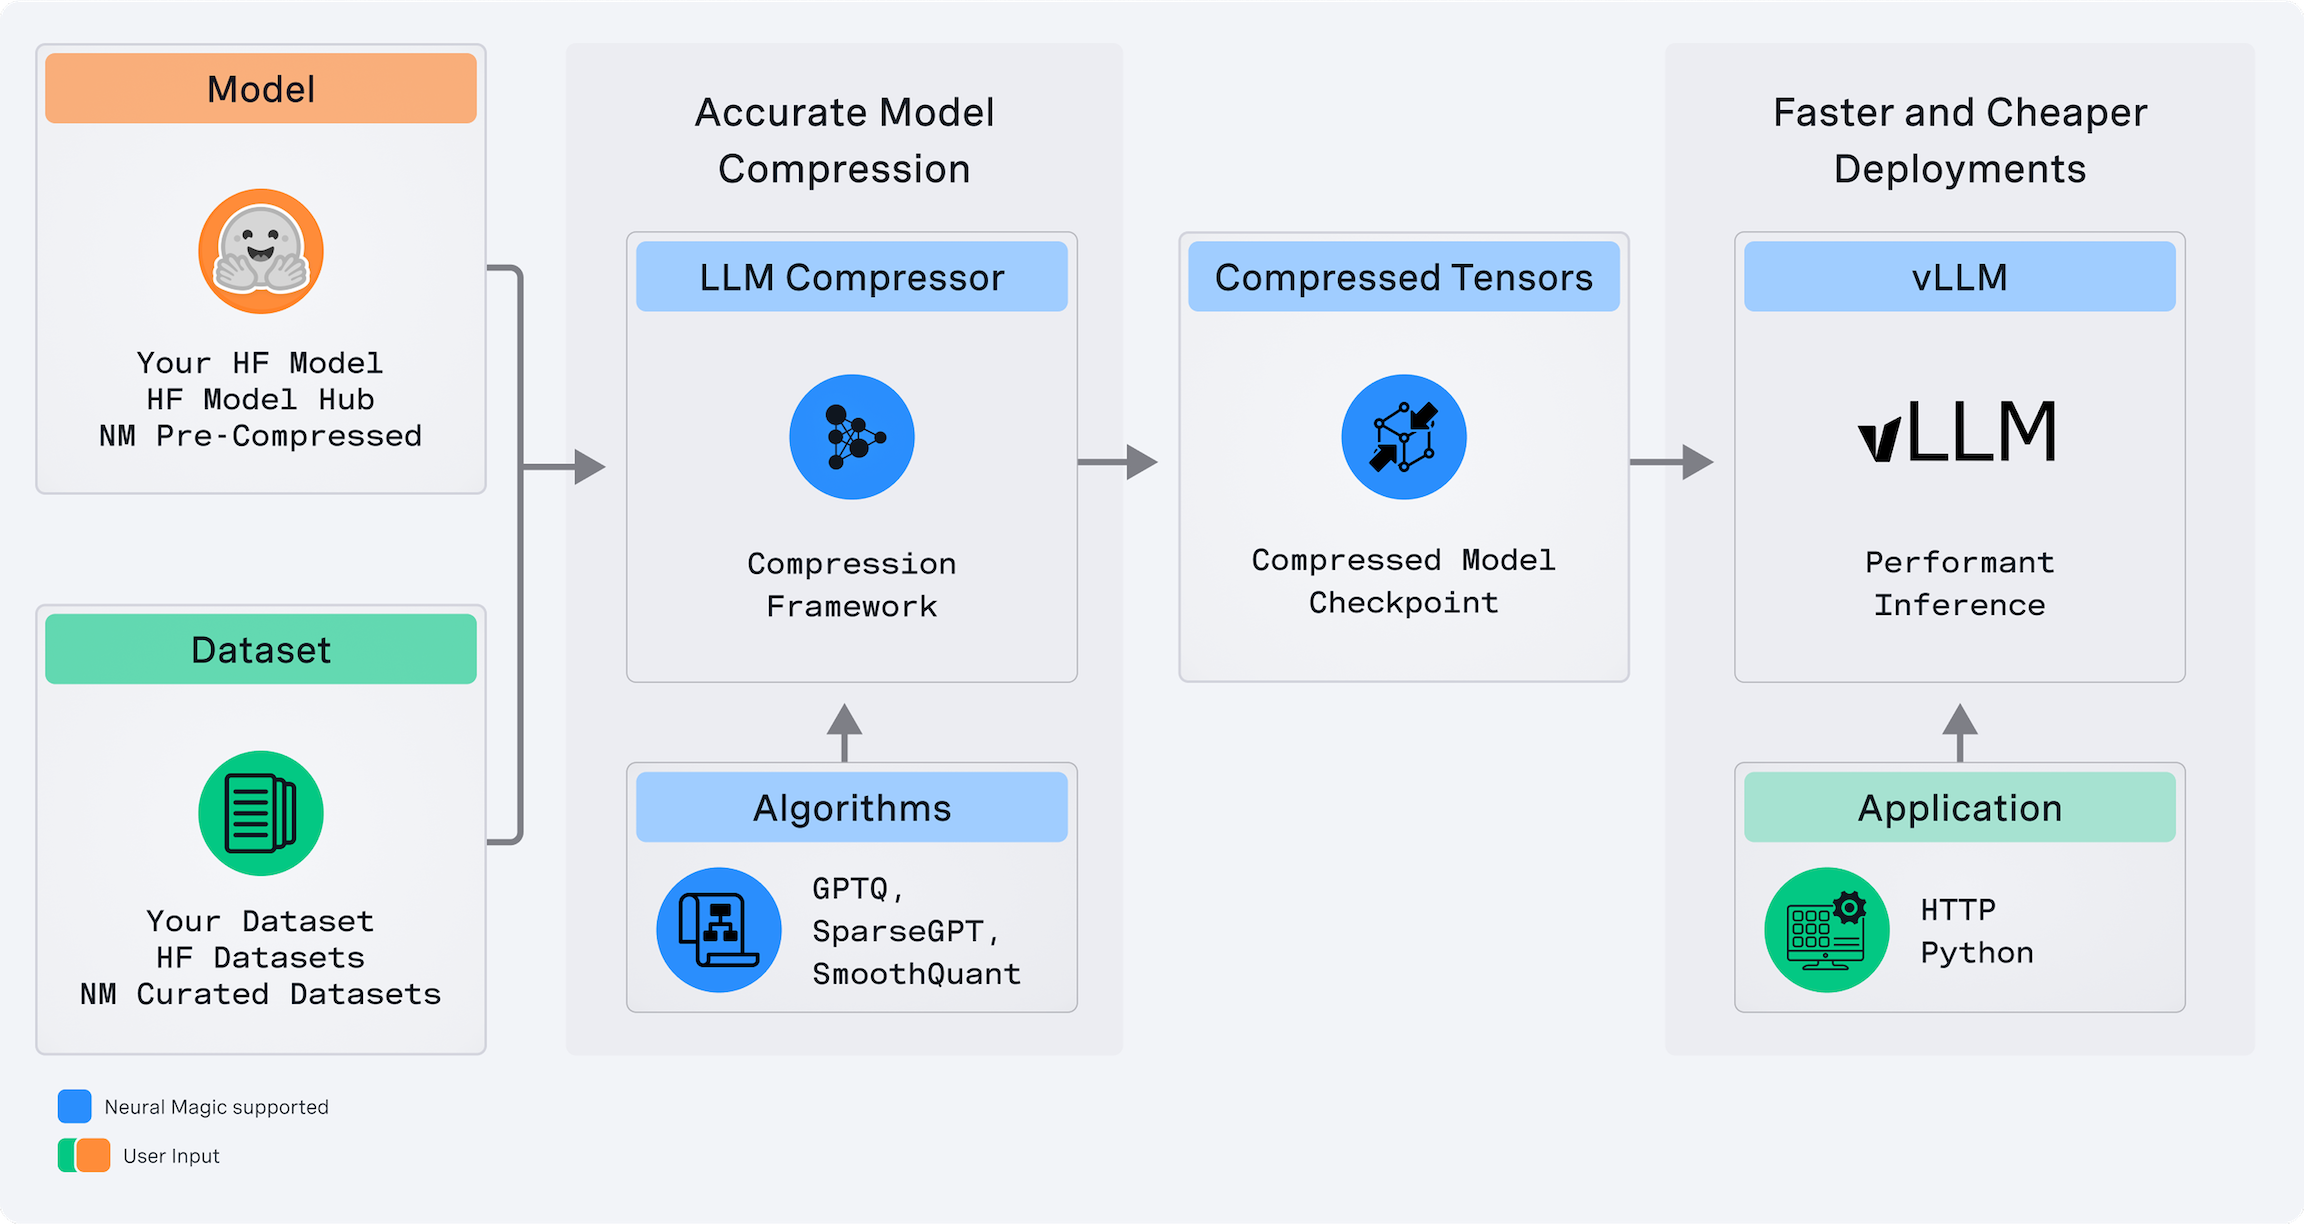
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

Run LLMs Locally on Your GPU with vLLM (No APIs) | Top Python Libraries

[Project] LLM inference with vLLM and AMD: Achieving LLM inference ...
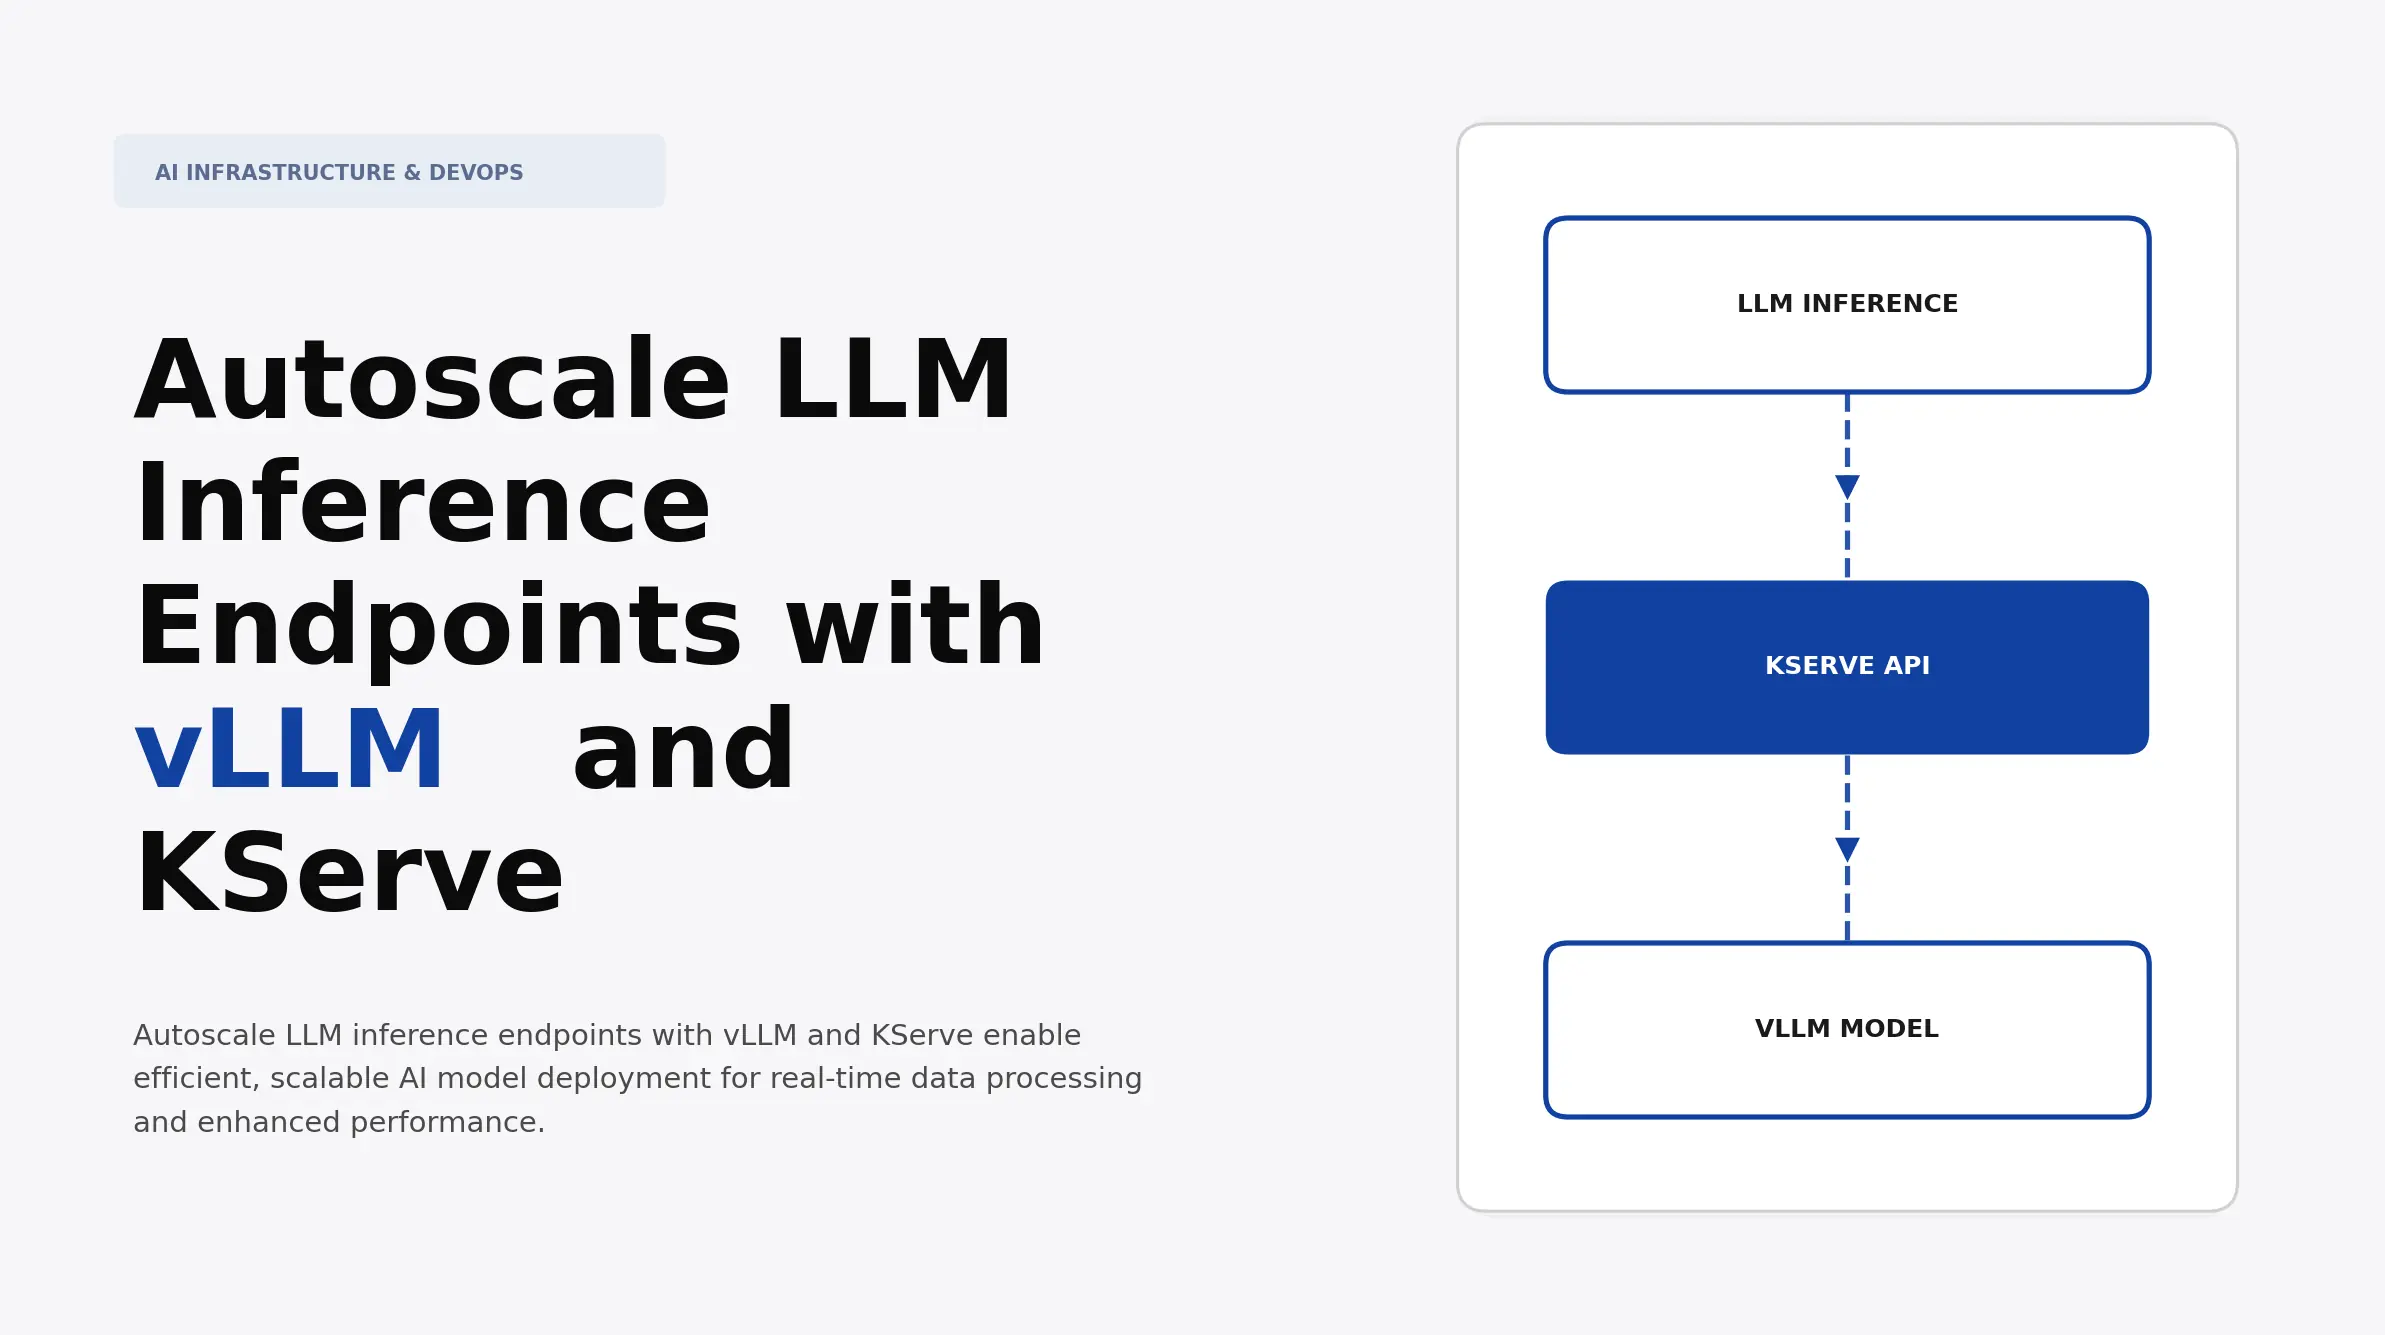
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops

vLLM x AMD: Highly Efficient LLM Inference on AMD Instinct™ MI300X GPUs

Figure 2 from Efficient LLM inference solution on Intel GPU | Semantic ...
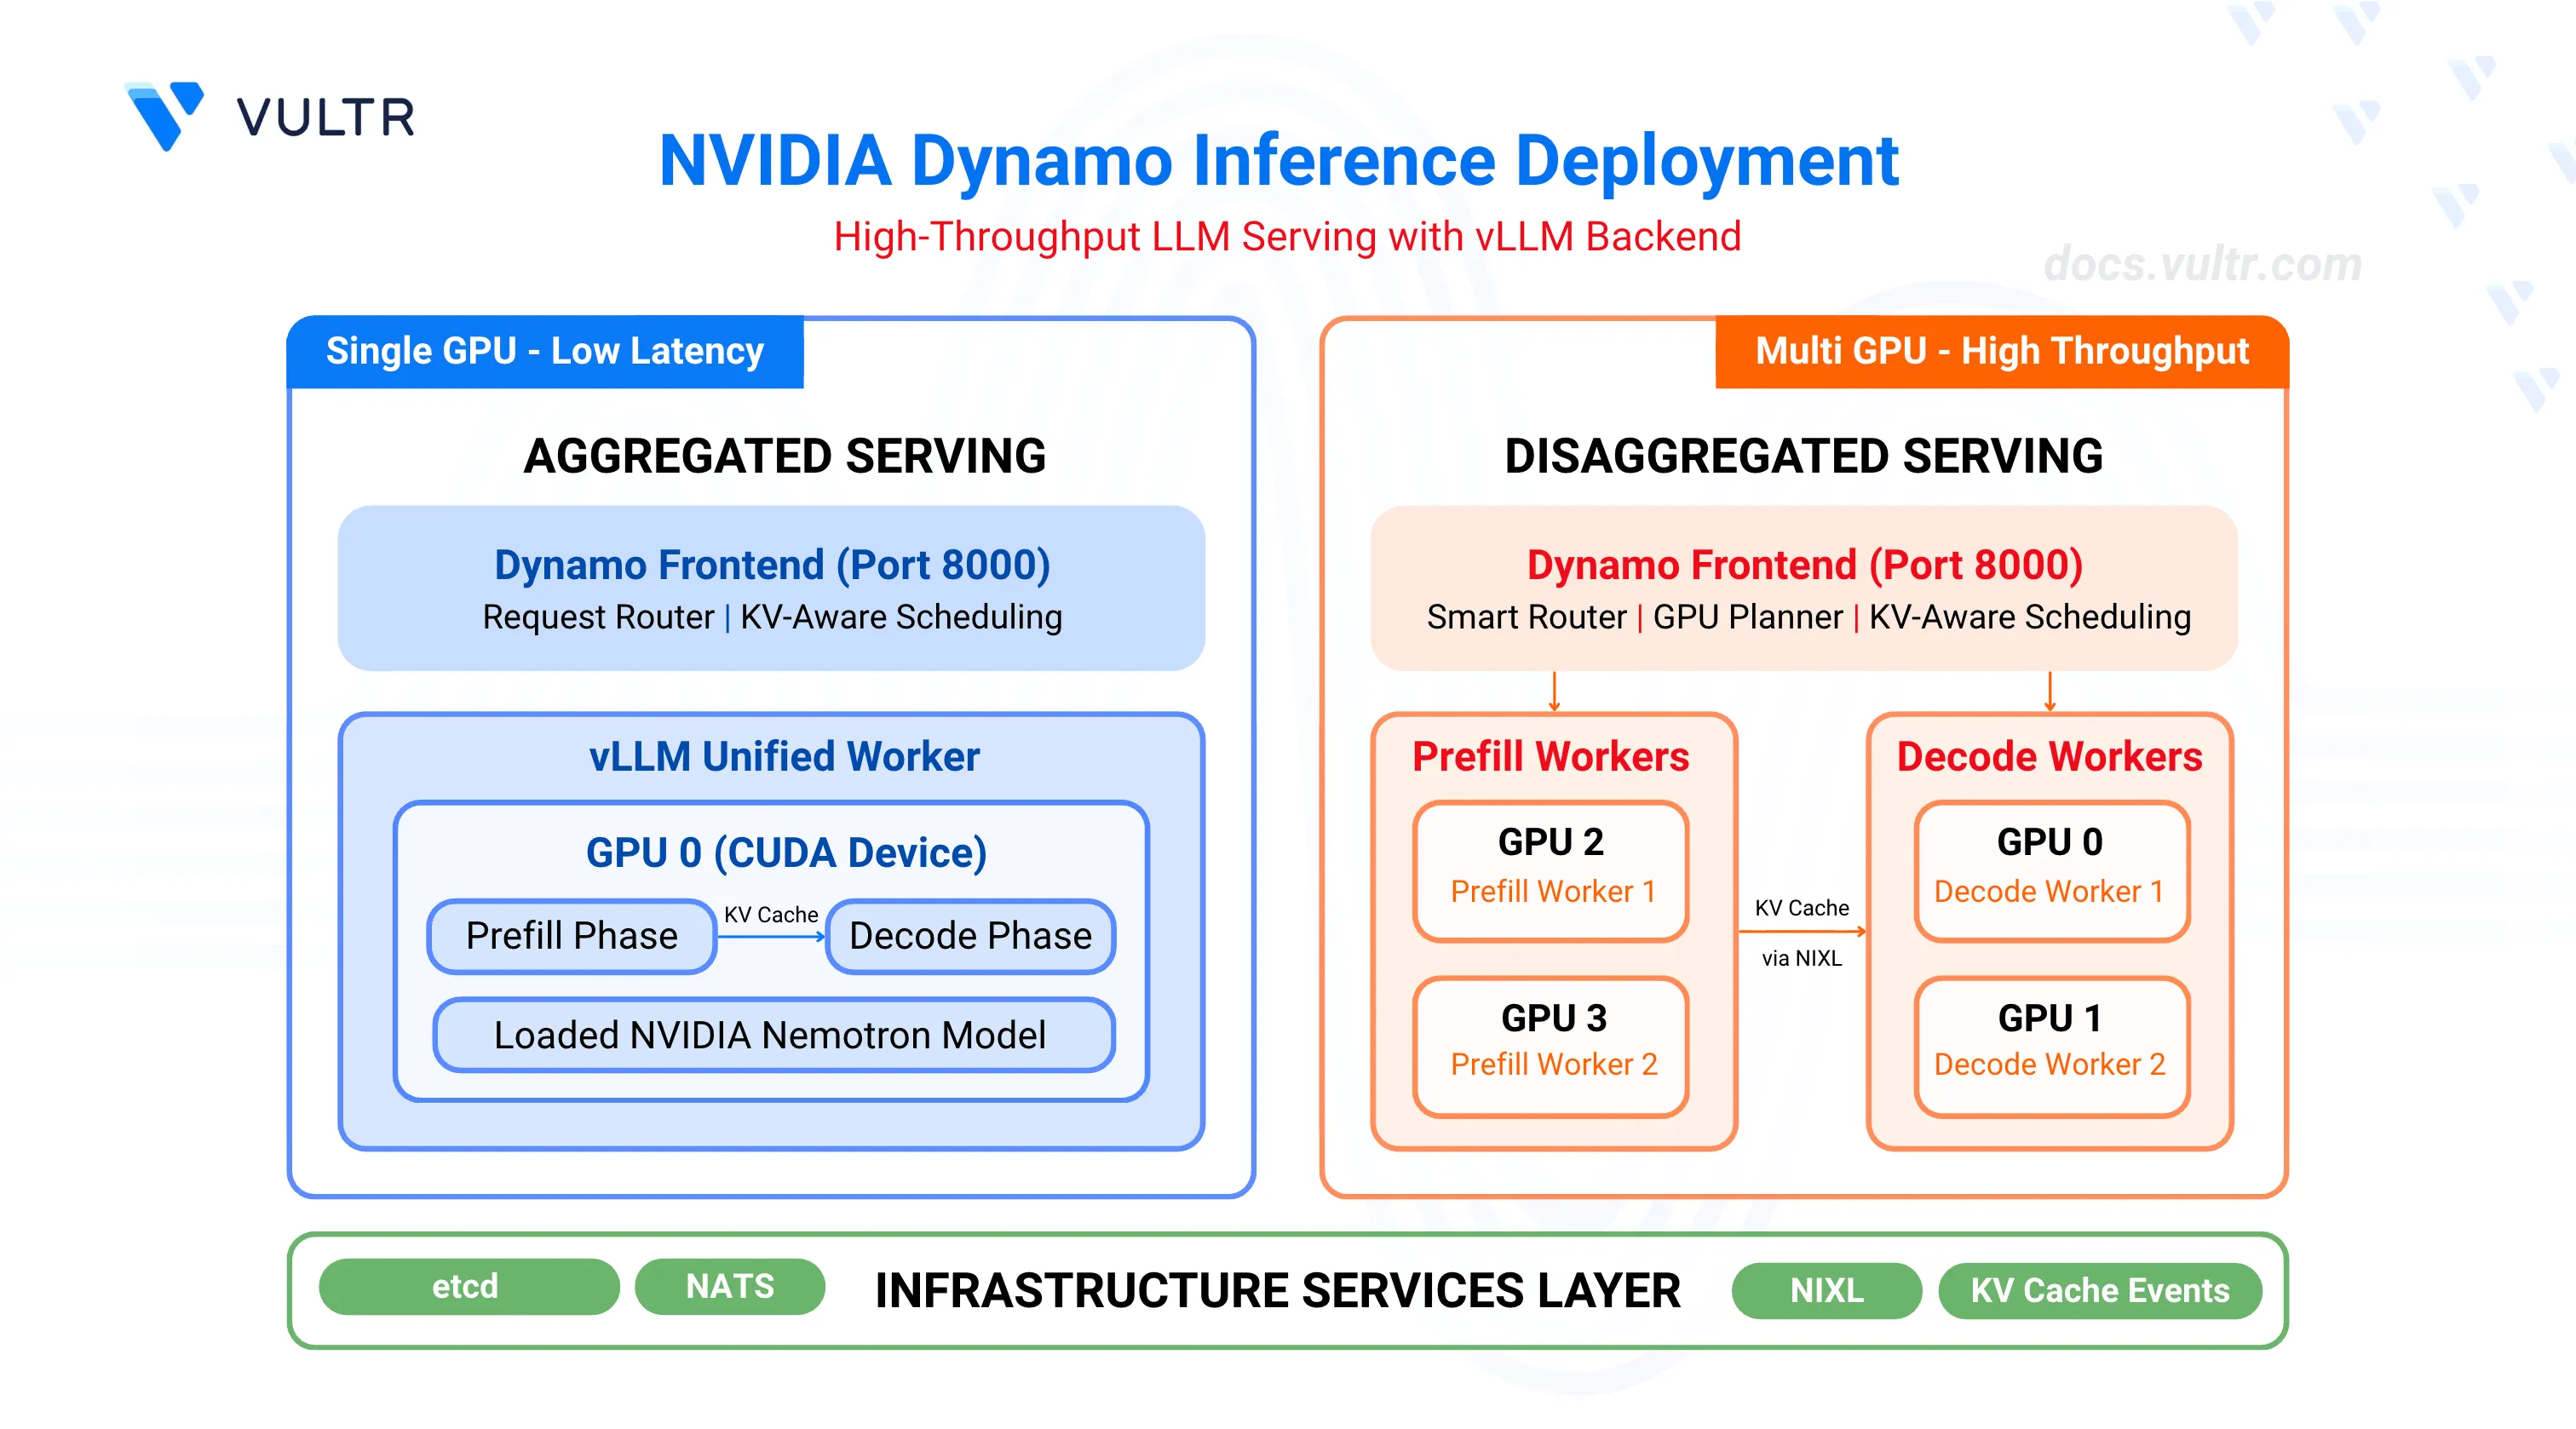
How to Deploy Inference Using NVIDIA Dynamo and vLLM | Vultr Docs
Advertisement Space (336x280)
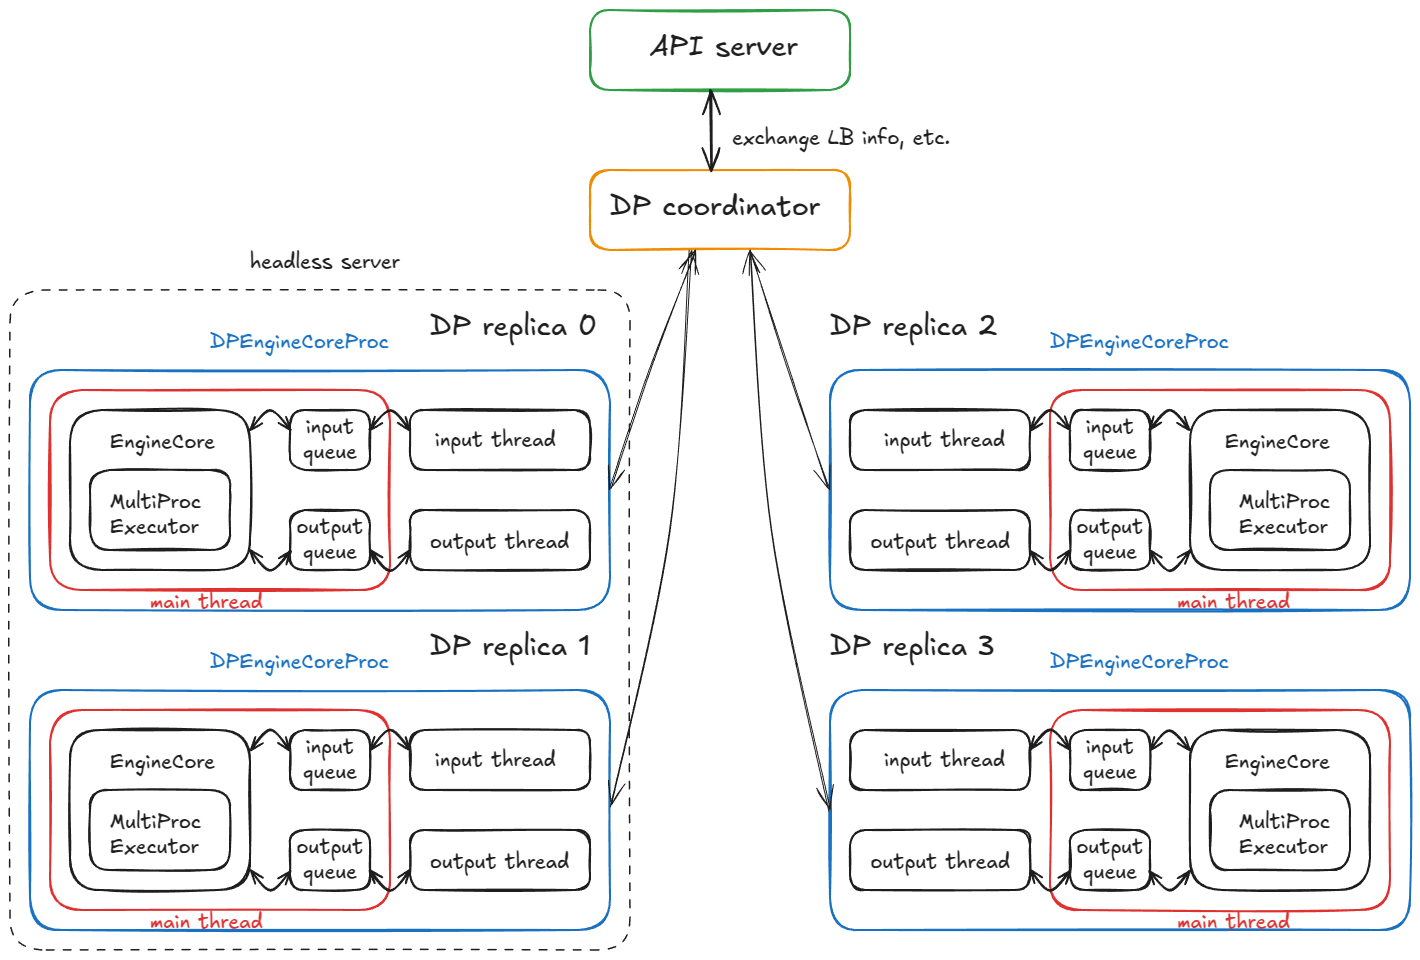
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
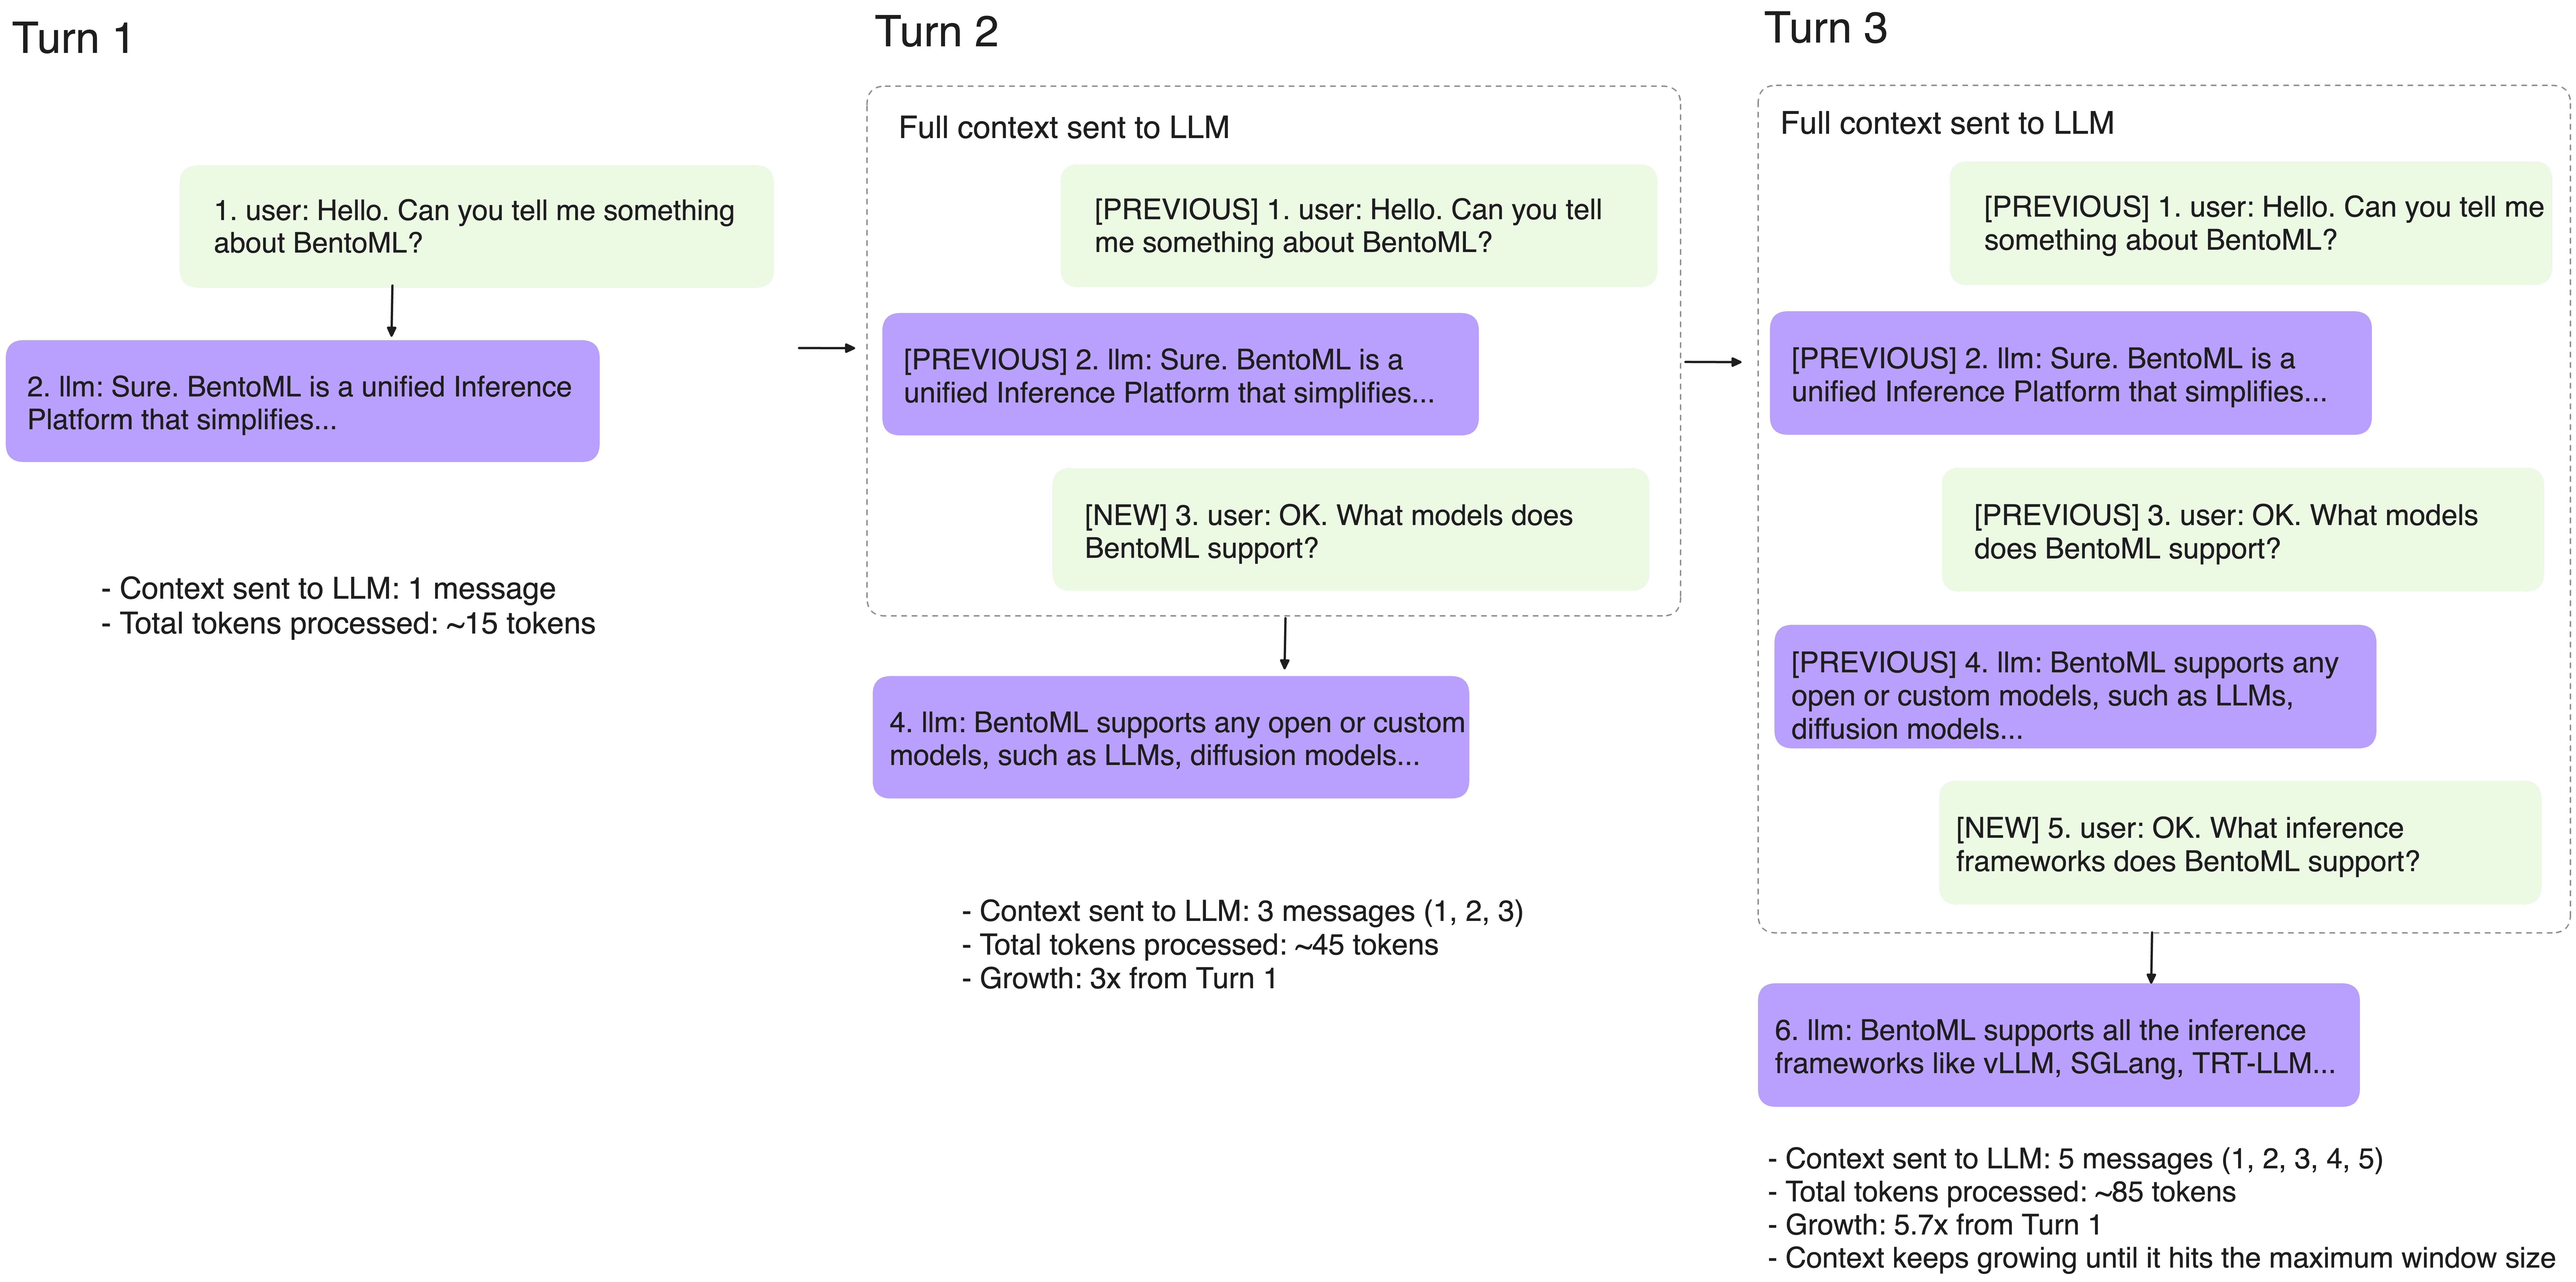
What is GPU Memory and Why it Matters for LLM Inference
How to Choose the Right GPU for vLLM Inference | DigitalOcean

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...

VLLM Quickstart Guide of HOS: High-Performance LLM Inference for ...

LLM Inference - Consumer GPU performance | Puget Systems

Parallel CPU-GPU Execution for LLM Inference on Constrained GPUs | AI ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving | PDF ...
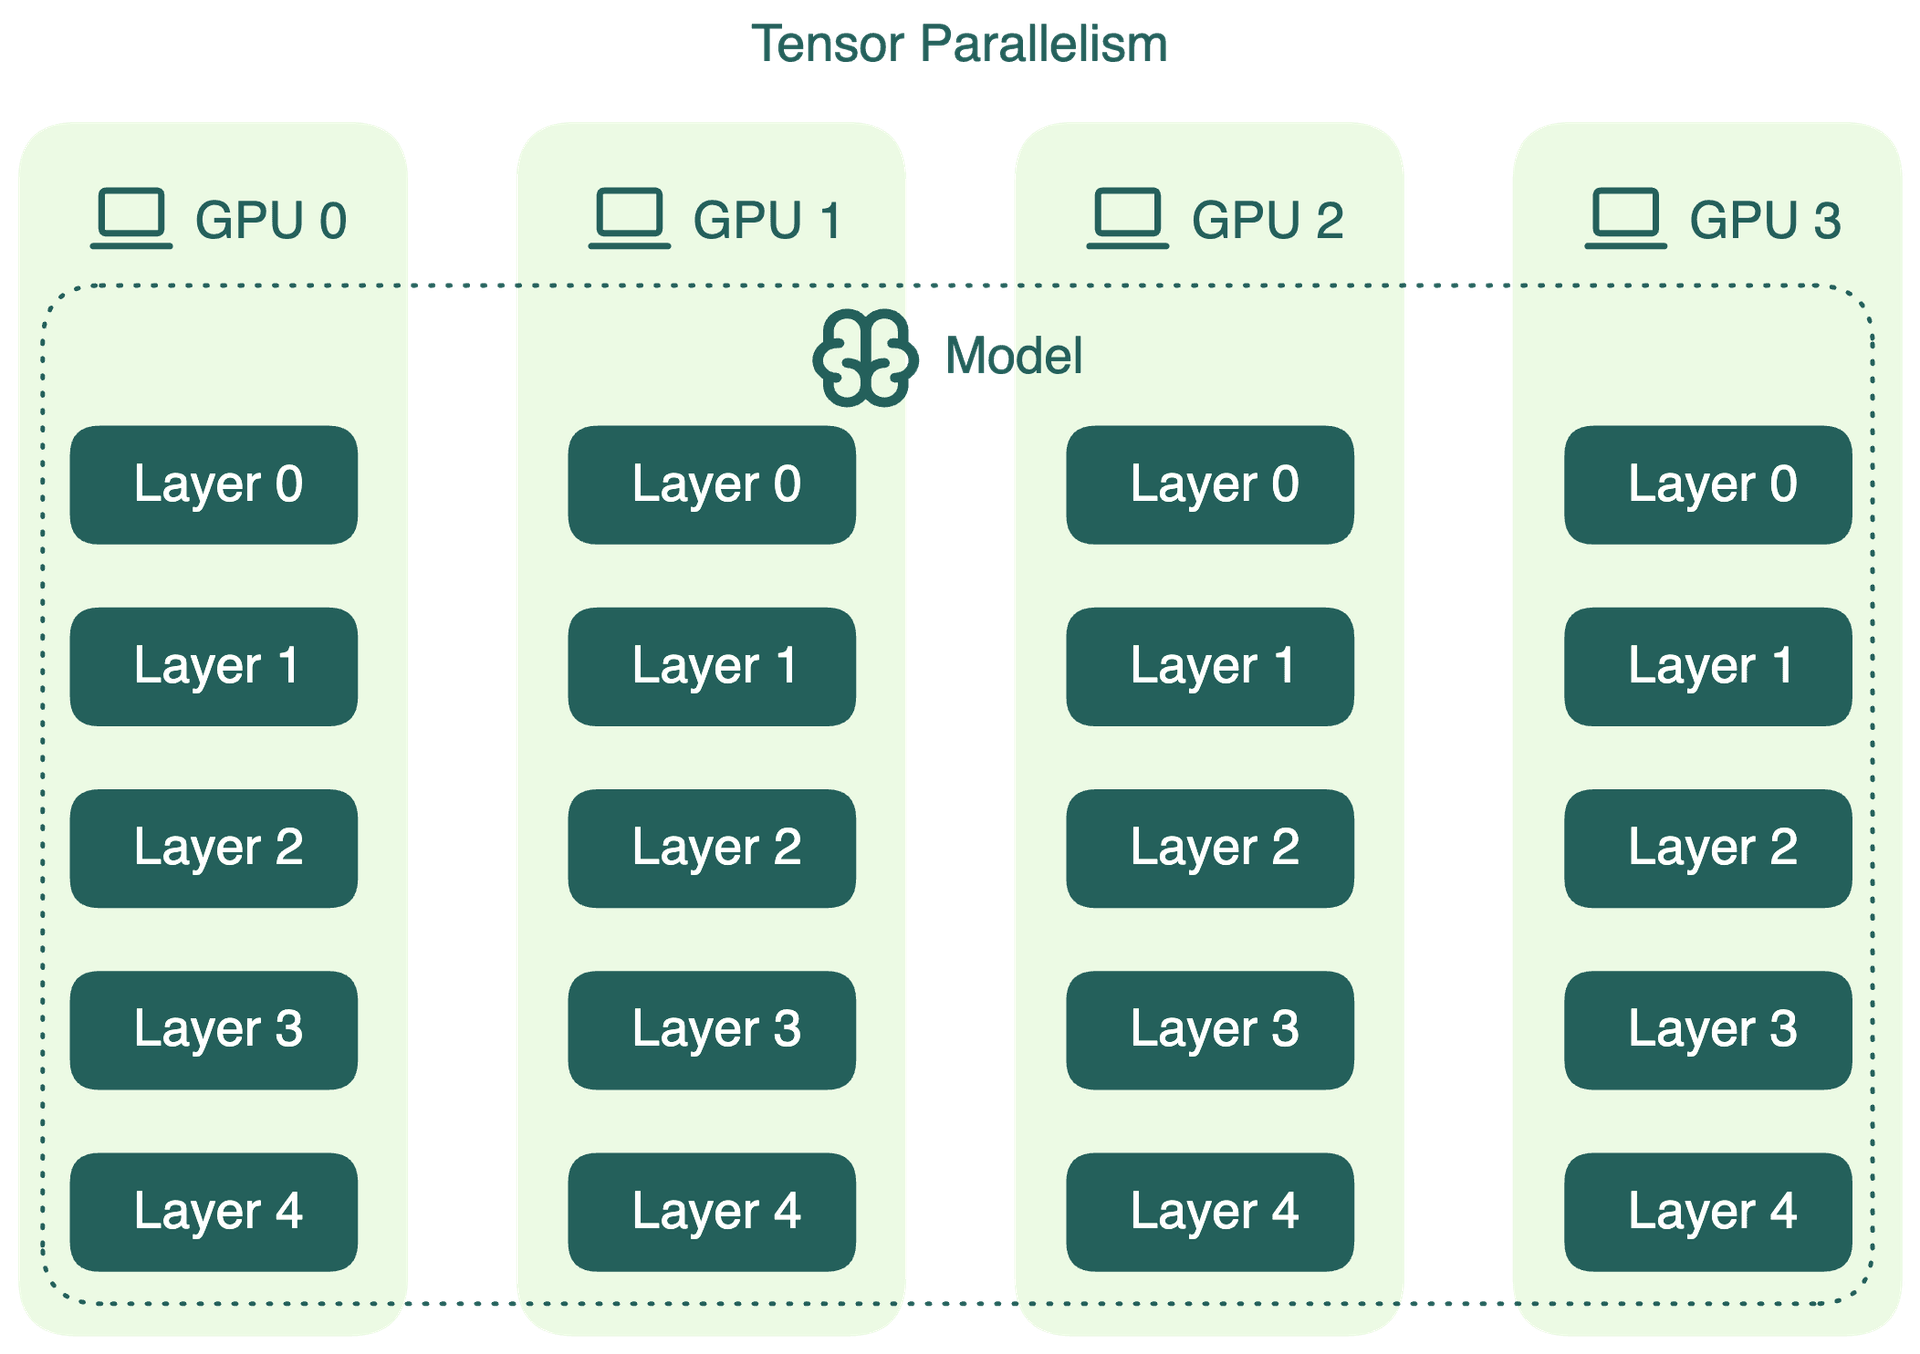
What is GPU Memory and Why it Matters for LLM Inference
vLLM Distributed Inference stuck when using multi -GPU · Issue #2466 ...
Advertisement Space (336x280)
Fast & Efficient LLM Inference with vLLM: A New Course with ...
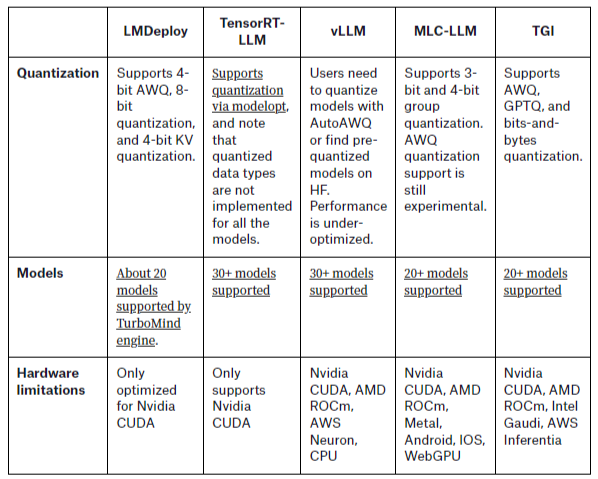
A Comprehensive Study by BentoML on Benchmarking LLM Inference Backends ...

(PDF) Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...

LLM inference engines performance testing: SGLang VS. vLLM | by ...
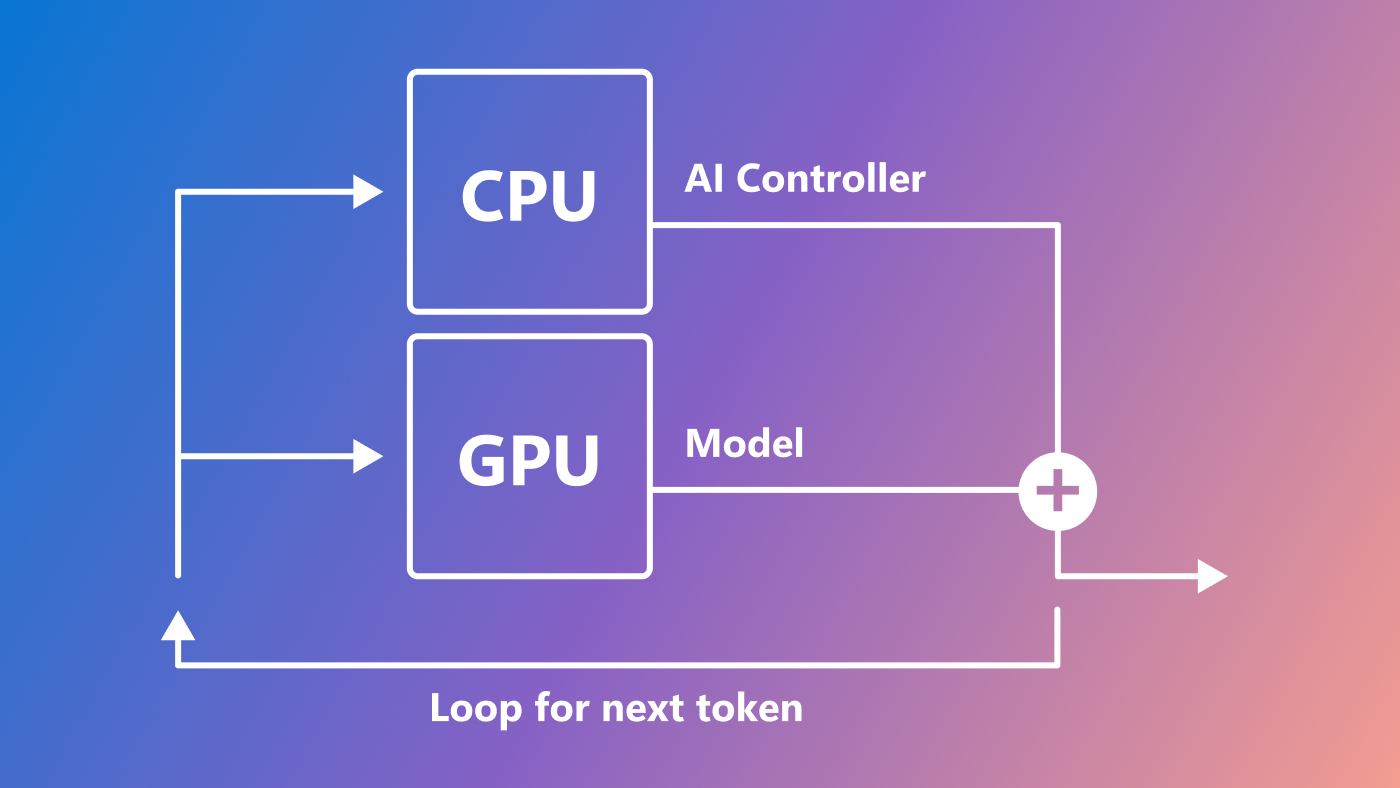
Splitwise improves GPU usage by splitting LLM inference phases ...

GPU VRAM Calculation for LLM Inference and Training - YouTube