
Convert Fp16 Killed Tensorrt Nvidia Developer Forums

Convert fp16 killed - TensorRT - NVIDIA Developer Forums

Convert fp16 killed - TensorRT - NVIDIA Developer Forums
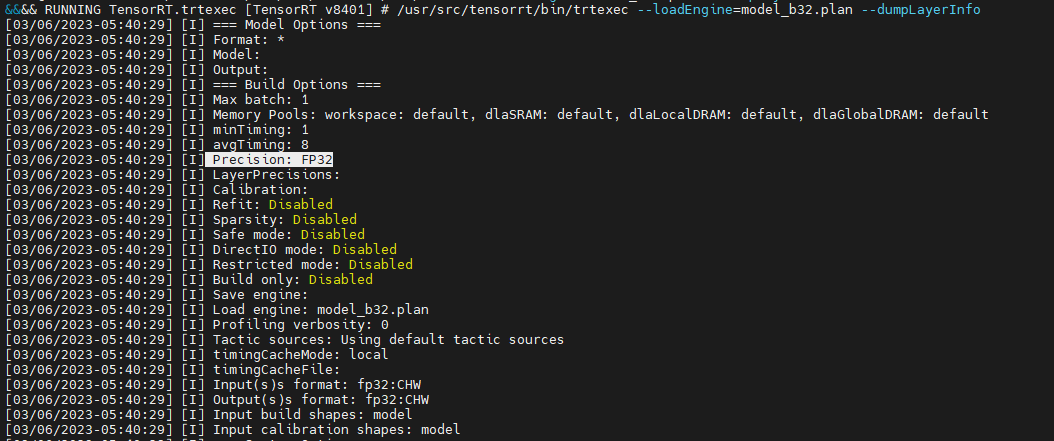
Tensorrt FP16 conversion issue - TensorRT - NVIDIA Developer Forums

Conv inference problem fp32 to fp16 - TensorRT - NVIDIA Developer Forums

Conv inference problem fp32 to fp16 - TensorRT - NVIDIA Developer Forums

Model does not get Int8 layers - TensorRT - NVIDIA Developer Forums

Convert to TensorRT engine(FP16). Stop here - TAO Toolkit - NVIDIA ...

Convert to TensorRT engine(FP16). Stop here - TAO Toolkit - NVIDIA ...

Using trtexec fails to convert onnx to tensorrt engine (DLAcore) FP16 ...
fp16 onnx -> fp16 tensorrt mismatched outputs · Issue #2336 · NVIDIA ...
Advertisement Space (300x250)

How to Convert CO-DETR Model? - #5 by anenbergb - TensorRT - NVIDIA ...

TensorRT process killed with Orin Nano - Jetson Orin Nano - NVIDIA ...

TensorRT process killed with Orin Nano - Jetson Orin Nano - NVIDIA ...
webui.sh get's killed on TensorRT SDXL conversion · Issue #105 · NVIDIA ...
Result wrong when Fcos model convert to tensorrt in fp16 mode. · Issue ...

tensorflow - No speed up with TensorRT FP16 or INT8 on NVIDIA V100 ...
FP16 Accuracy failure of TensorRT 8.6.3 when running trtexec built ...

TensorRT int8 slower than FP16 due to reformat layer - TensorRT ...
FP16 failure of TensorRT 8.6.1.6 when running GroundingDINO on GPU ...

TensorRT Inferencing using TF-TRT framework FP32 vs FP16 - Jetson AGX ...
Advertisement Space (336x280)
ONNX Runtime convert to TensorRT: fp32 & fp16 mode success but int8 ...
TensorRT Explicit Quantization and Fallback to FP16 · Issue #4021 ...
BF16 is slower than fp16 of TensorRT 9.1 when running my R50 model on ...

Trtexec failed to create an engine from onnx file with fp16 - TensorRT ...
Can't avoid fp16 conversion of an onnx node · Issue #2899 · NVIDIA ...

Process Killed when Generating a TensorRT Engine for the ViT models ...

Trtexec failed to create an engine from onnx file with fp16 - TensorRT ...
Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...

TensorRT RT-Detr model conversion precision loss - TAO Toolkit - NVIDIA ...
No speedup between fp16 and int8 precisions · Issue #2197 · NVIDIA ...
Advertisement Space (336x280)
Trtexec failed to create an engine from onnx file with fp16 - TensorRT ...

NVIDIA TensorRT for RTX 在 Windows 11 上推出优化的推理 AI 库 - NVIDIA 技术博客
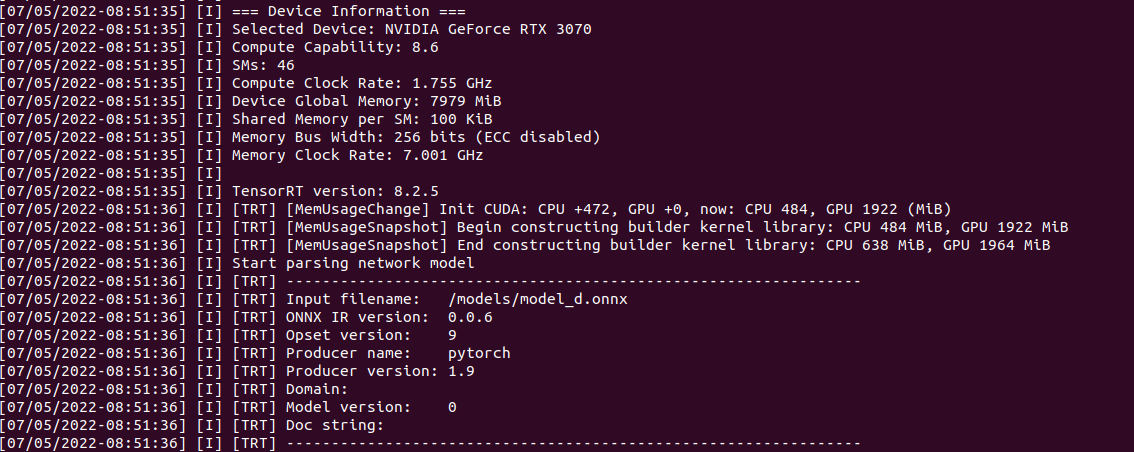
Trtexec failed to create an engine from onnx file with fp16 - TensorRT ...
Roberta fp16 got wrong inference results · Issue #2466 · NVIDIA ...

Killed while using DeepStream YOLO master for conversion - TensorRT ...
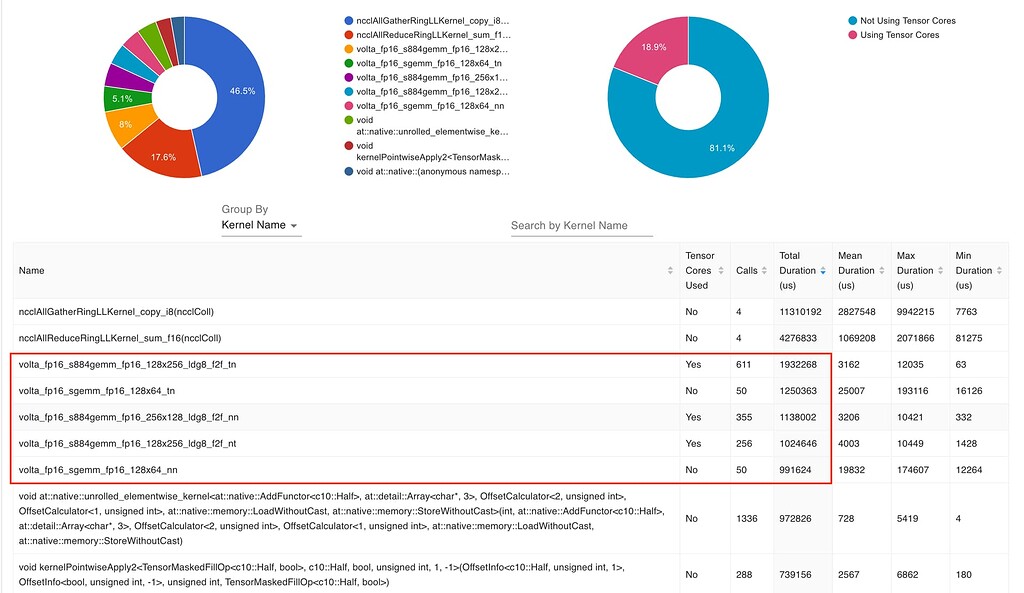
Why some fp16 gemm does not utilize Tensor Core - cuDNN - NVIDIA ...