
Tensorrt Fp16 Conversion Issue Tensorrt Nvidia Developer Forums
Tensorrt FP16 conversion issue - TensorRT - NVIDIA Developer Forums

Conv inference problem fp32 to fp16 - TensorRT - NVIDIA Developer Forums

Convert fp16 killed - TensorRT - NVIDIA Developer Forums

Convert fp16 killed - TensorRT - NVIDIA Developer Forums
fp16 onnx -> fp16 tensorrt mismatched outputs · Issue #2336 · NVIDIA ...

Converting .pt to tensorRT (.engine) - TensorRT - NVIDIA Developer Forums

TensorRT quantization Optimization - TensorRT - NVIDIA Developer Forums

Convert onnx to tensorrt - DeepStream SDK - NVIDIA Developer Forums

Cannot install TensorRT - TensorRT - NVIDIA Developer Forums
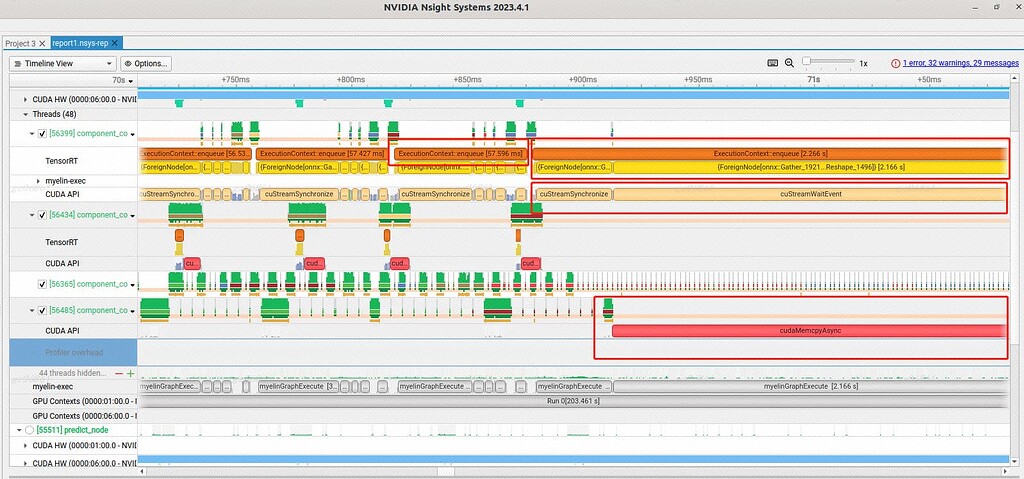
TensorRT enqueueV2 take a long time - TensorRT - NVIDIA Developer Forums
Advertisement Space (300x250)

Human pose detection model (MoveNet) TensorRT conversion on NVIDIA ...
TensorRT Explicit Quantization and Fallback to FP16 · Issue #4021 ...
Can't avoid fp16 conversion of an onnx node · Issue #2899 · NVIDIA ...

TensorRT RT-Detr model conversion precision loss - TAO Toolkit - NVIDIA ...
Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...
Compilation error in Tensorrt model using CMake · Issue #3819 · NVIDIA ...
Tensorrt Conversion For stable diffusion 2.1 is not working · Issue ...
How to enable FP8 convolution in TensorRT 10.2 · Issue #3987 · NVIDIA ...

There was a problem installing Tensorrt - TensorRT - NVIDIA Developer ...
Result wrong when Fcos model convert to tensorrt in fp16 mode. · Issue ...
Advertisement Space (336x280)

tensorflow - No speed up with TensorRT FP16 or INT8 on NVIDIA V100 ...
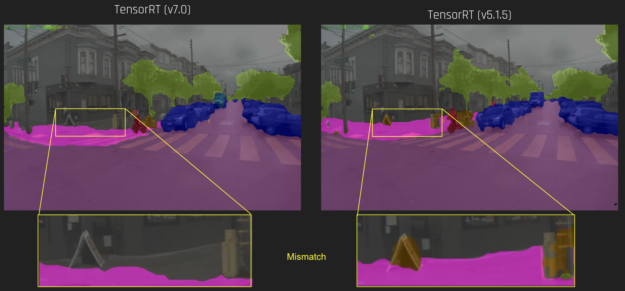
Optimizing NVIDIA TensorRT Conversion for Real-time Inference on ...

Convert to TensorRT engine(FP16). Stop here - TAO Toolkit - NVIDIA ...

Convert to TensorRT engine(FP16). Stop here - TAO Toolkit - NVIDIA ...

TensorRT Inferencing using TF-TRT framework FP32 vs FP16 - Jetson AGX ...

Using trtexec fails to convert onnx to tensorrt engine (DLAcore) FP16 ...

TensorRT int8 slower than FP16 due to reformat layer - TensorRT ...
FP16 Accuracy failure of TensorRT 8.6.3 when running trtexec built ...
fp16 conversion breaks model · Issue #4175 · NVIDIA/TensorRT · GitHub
FP16 failure of TensorRT 8.6.1.6 when running GroundingDINO on GPU ...
Advertisement Space (336x280)

TensorRT int8 slower than FP16 due to reformat layer - TensorRT ...
BF16 is slower than fp16 of TensorRT 9.1 when running my R50 model on ...

Tensorrt's results are inconsistent with onnxrt - TensorRT - NVIDIA ...
Implications of converting onnx fp16-> TensorRT engine · Issue #3057 ...
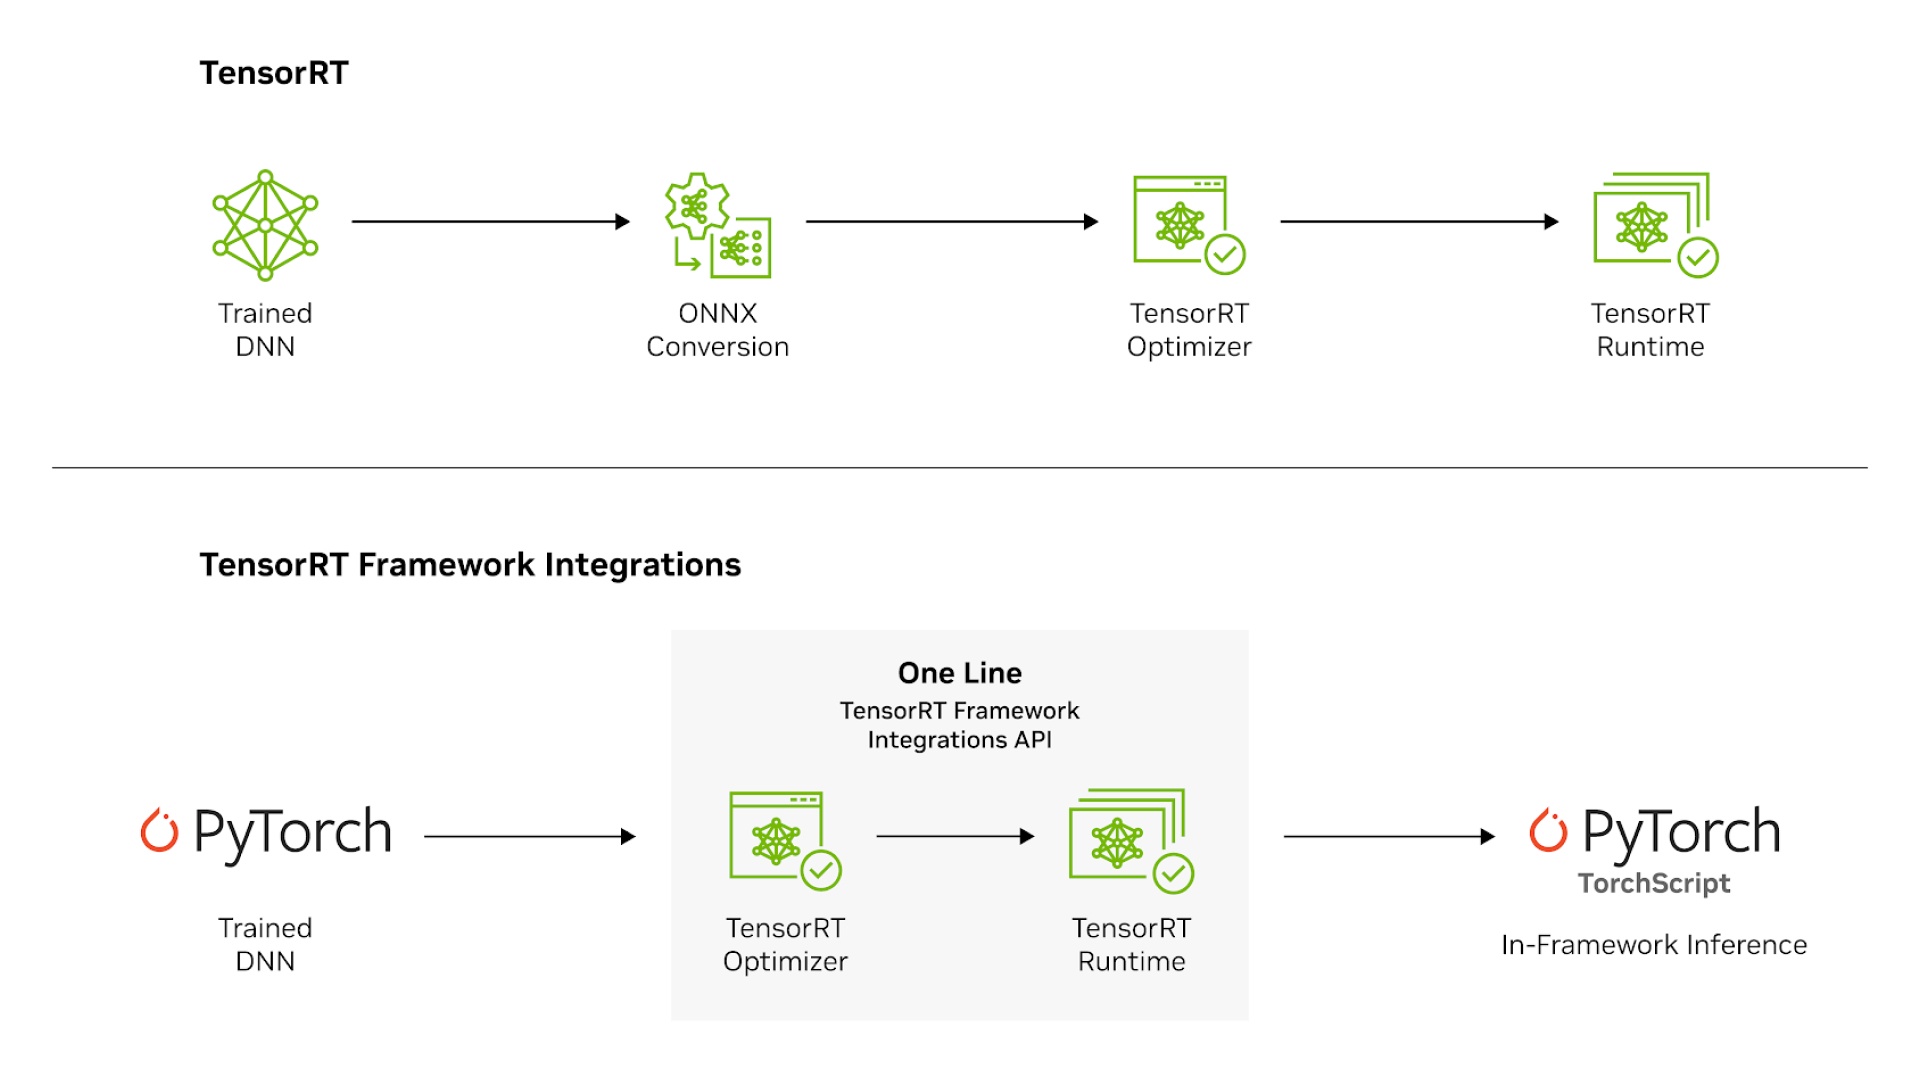
NVIDIA TensorRT | NVIDIA 开发者
converting to TensorRT barely increases performance · Issue #3646 ...