
Dart Diffusion Inspired Speculative Decoding For Fast Llm Inference

DART: Diffusion-Inspired Speculative Decoding for Fast LLM Inference ...

Paper page - DART: Diffusion-Inspired Speculative Decoding for Fast LLM ...
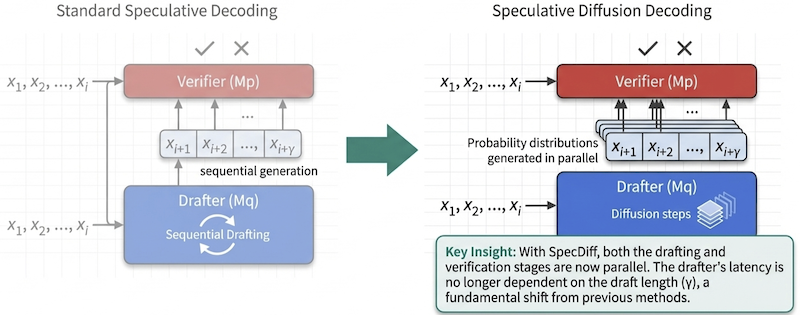
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
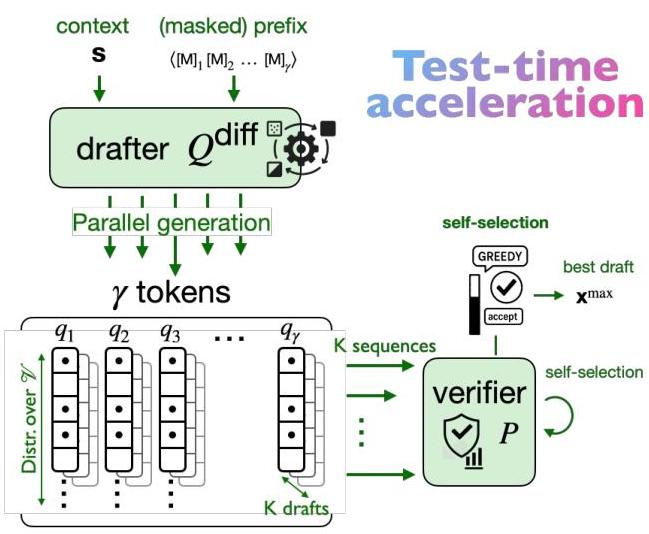
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
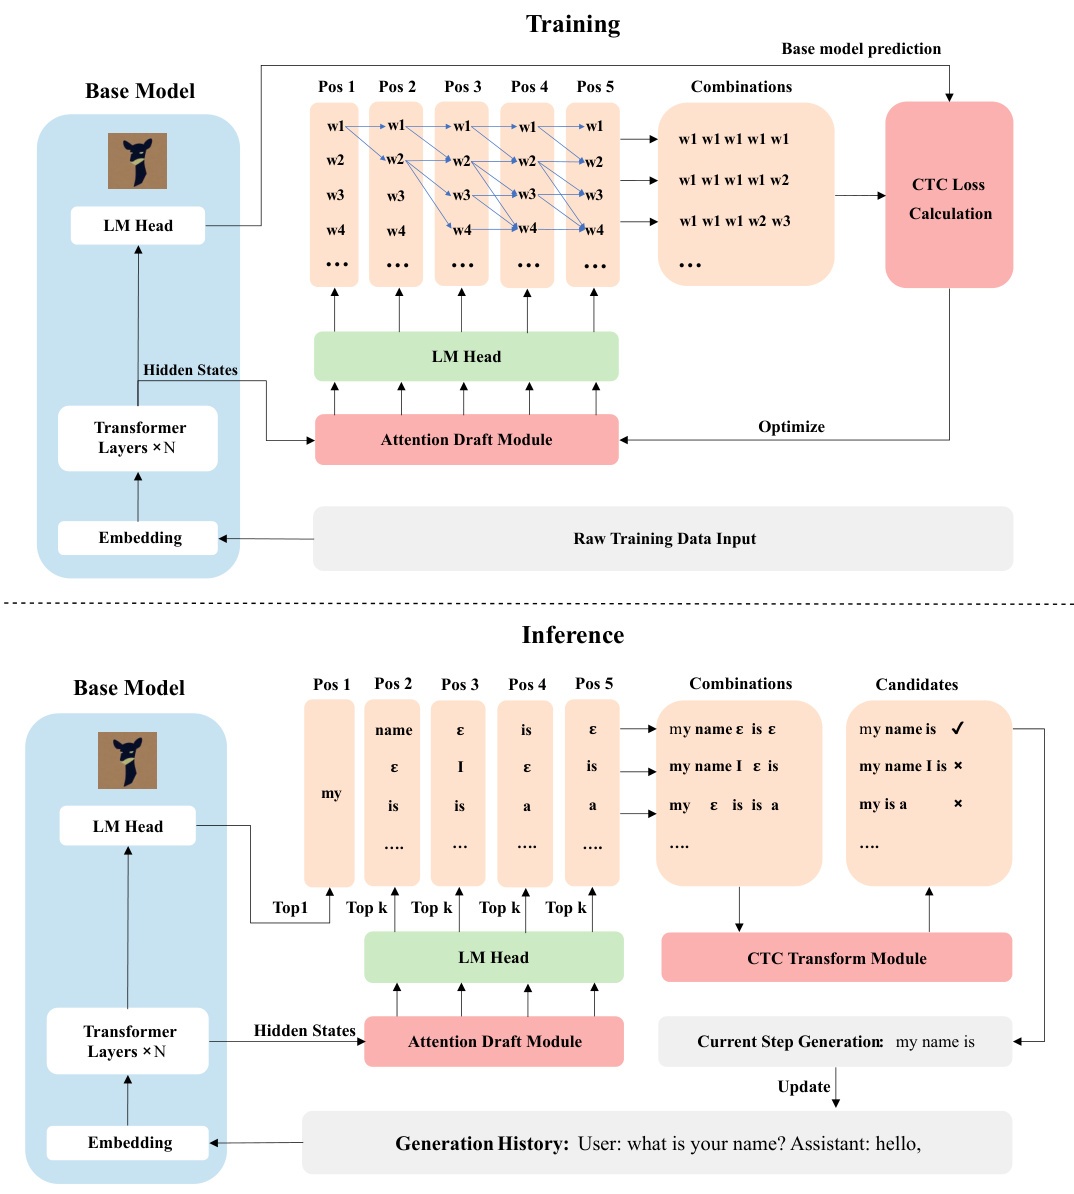
Speculative Decoding with CTC-based Draft Model for LLM Inference ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
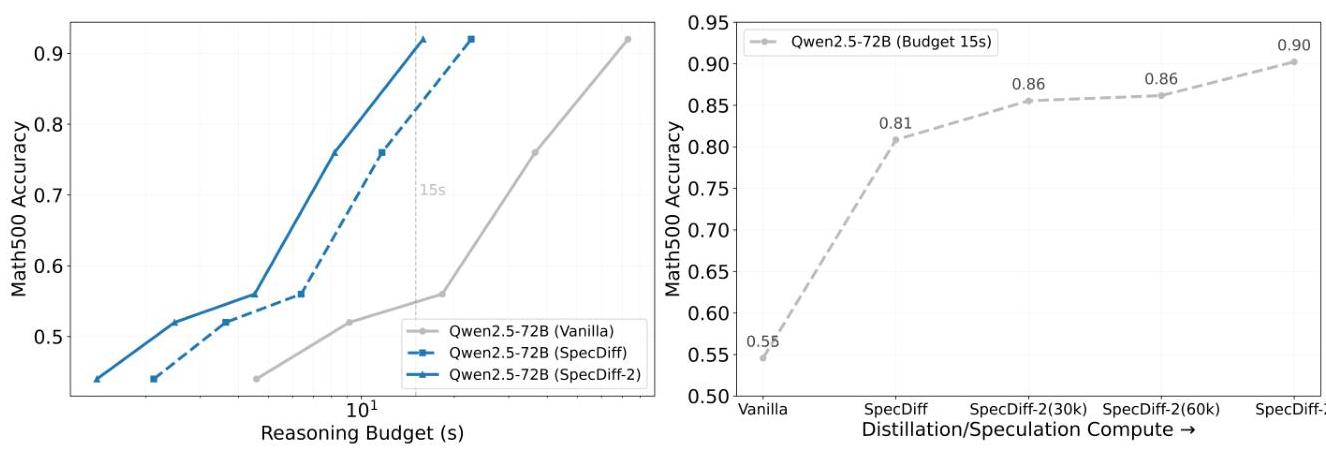
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
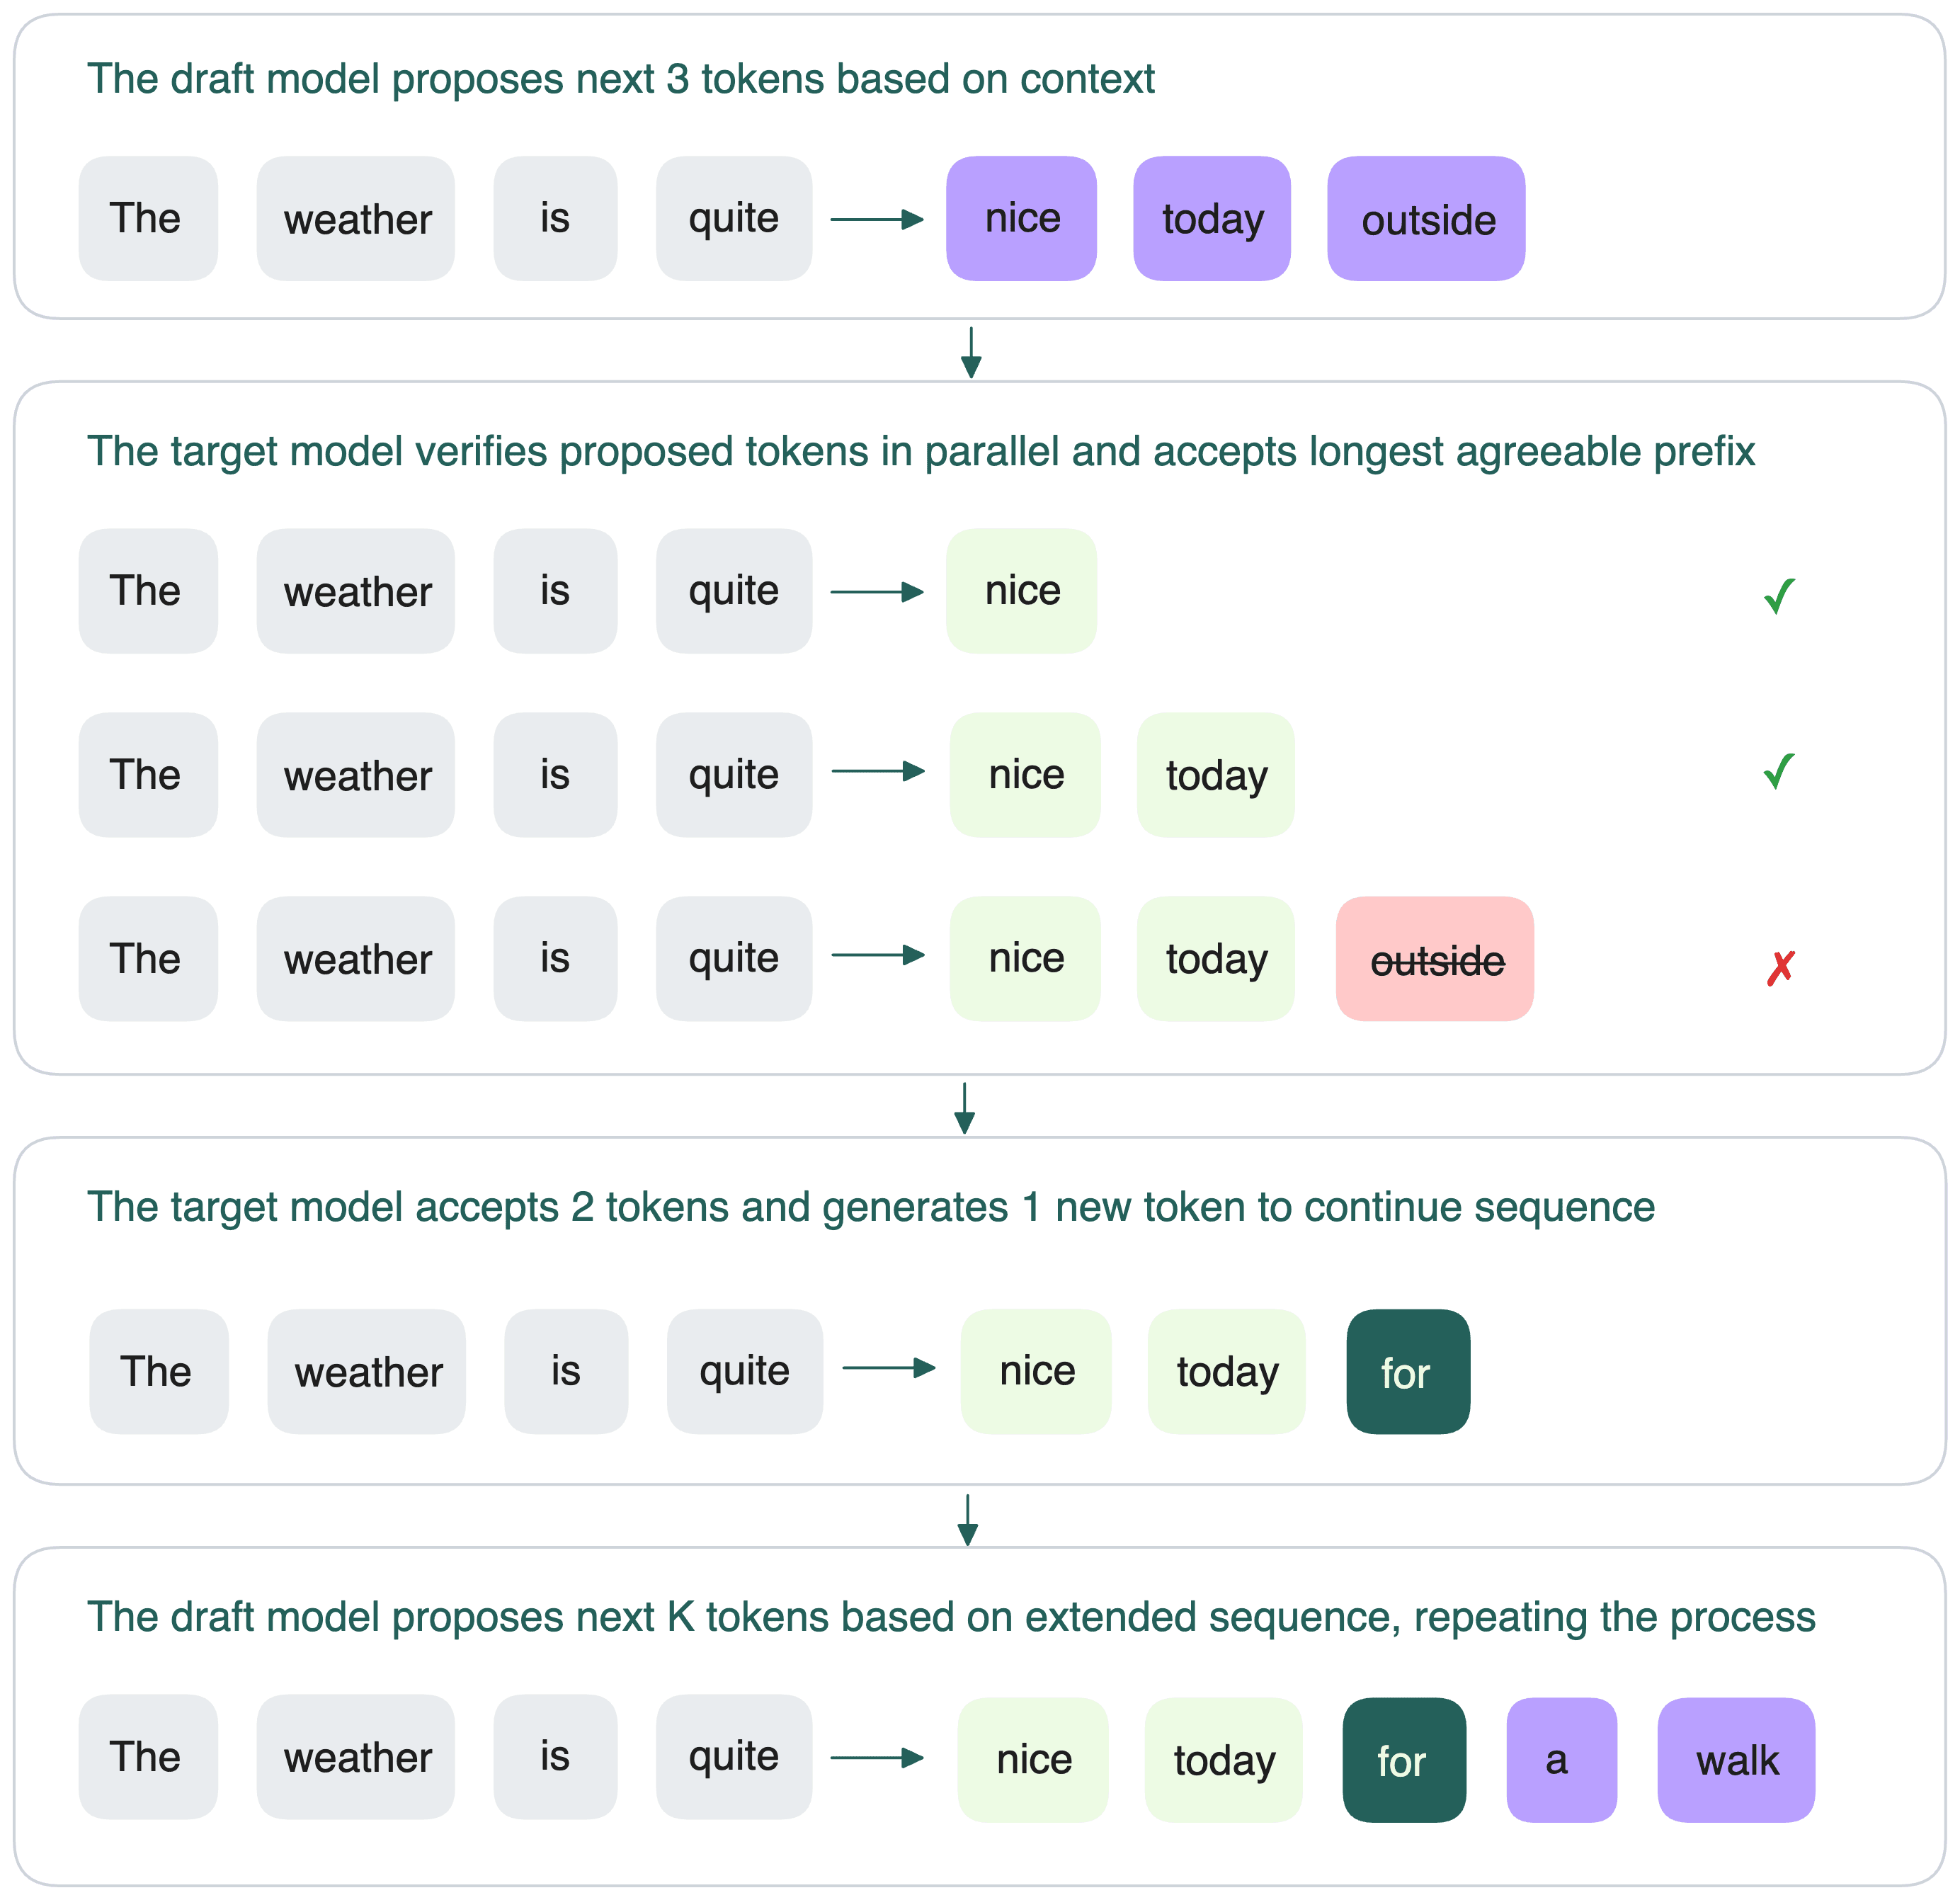
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

[2503.10325] Collaborative Speculative Inference for Efficient LLM ...
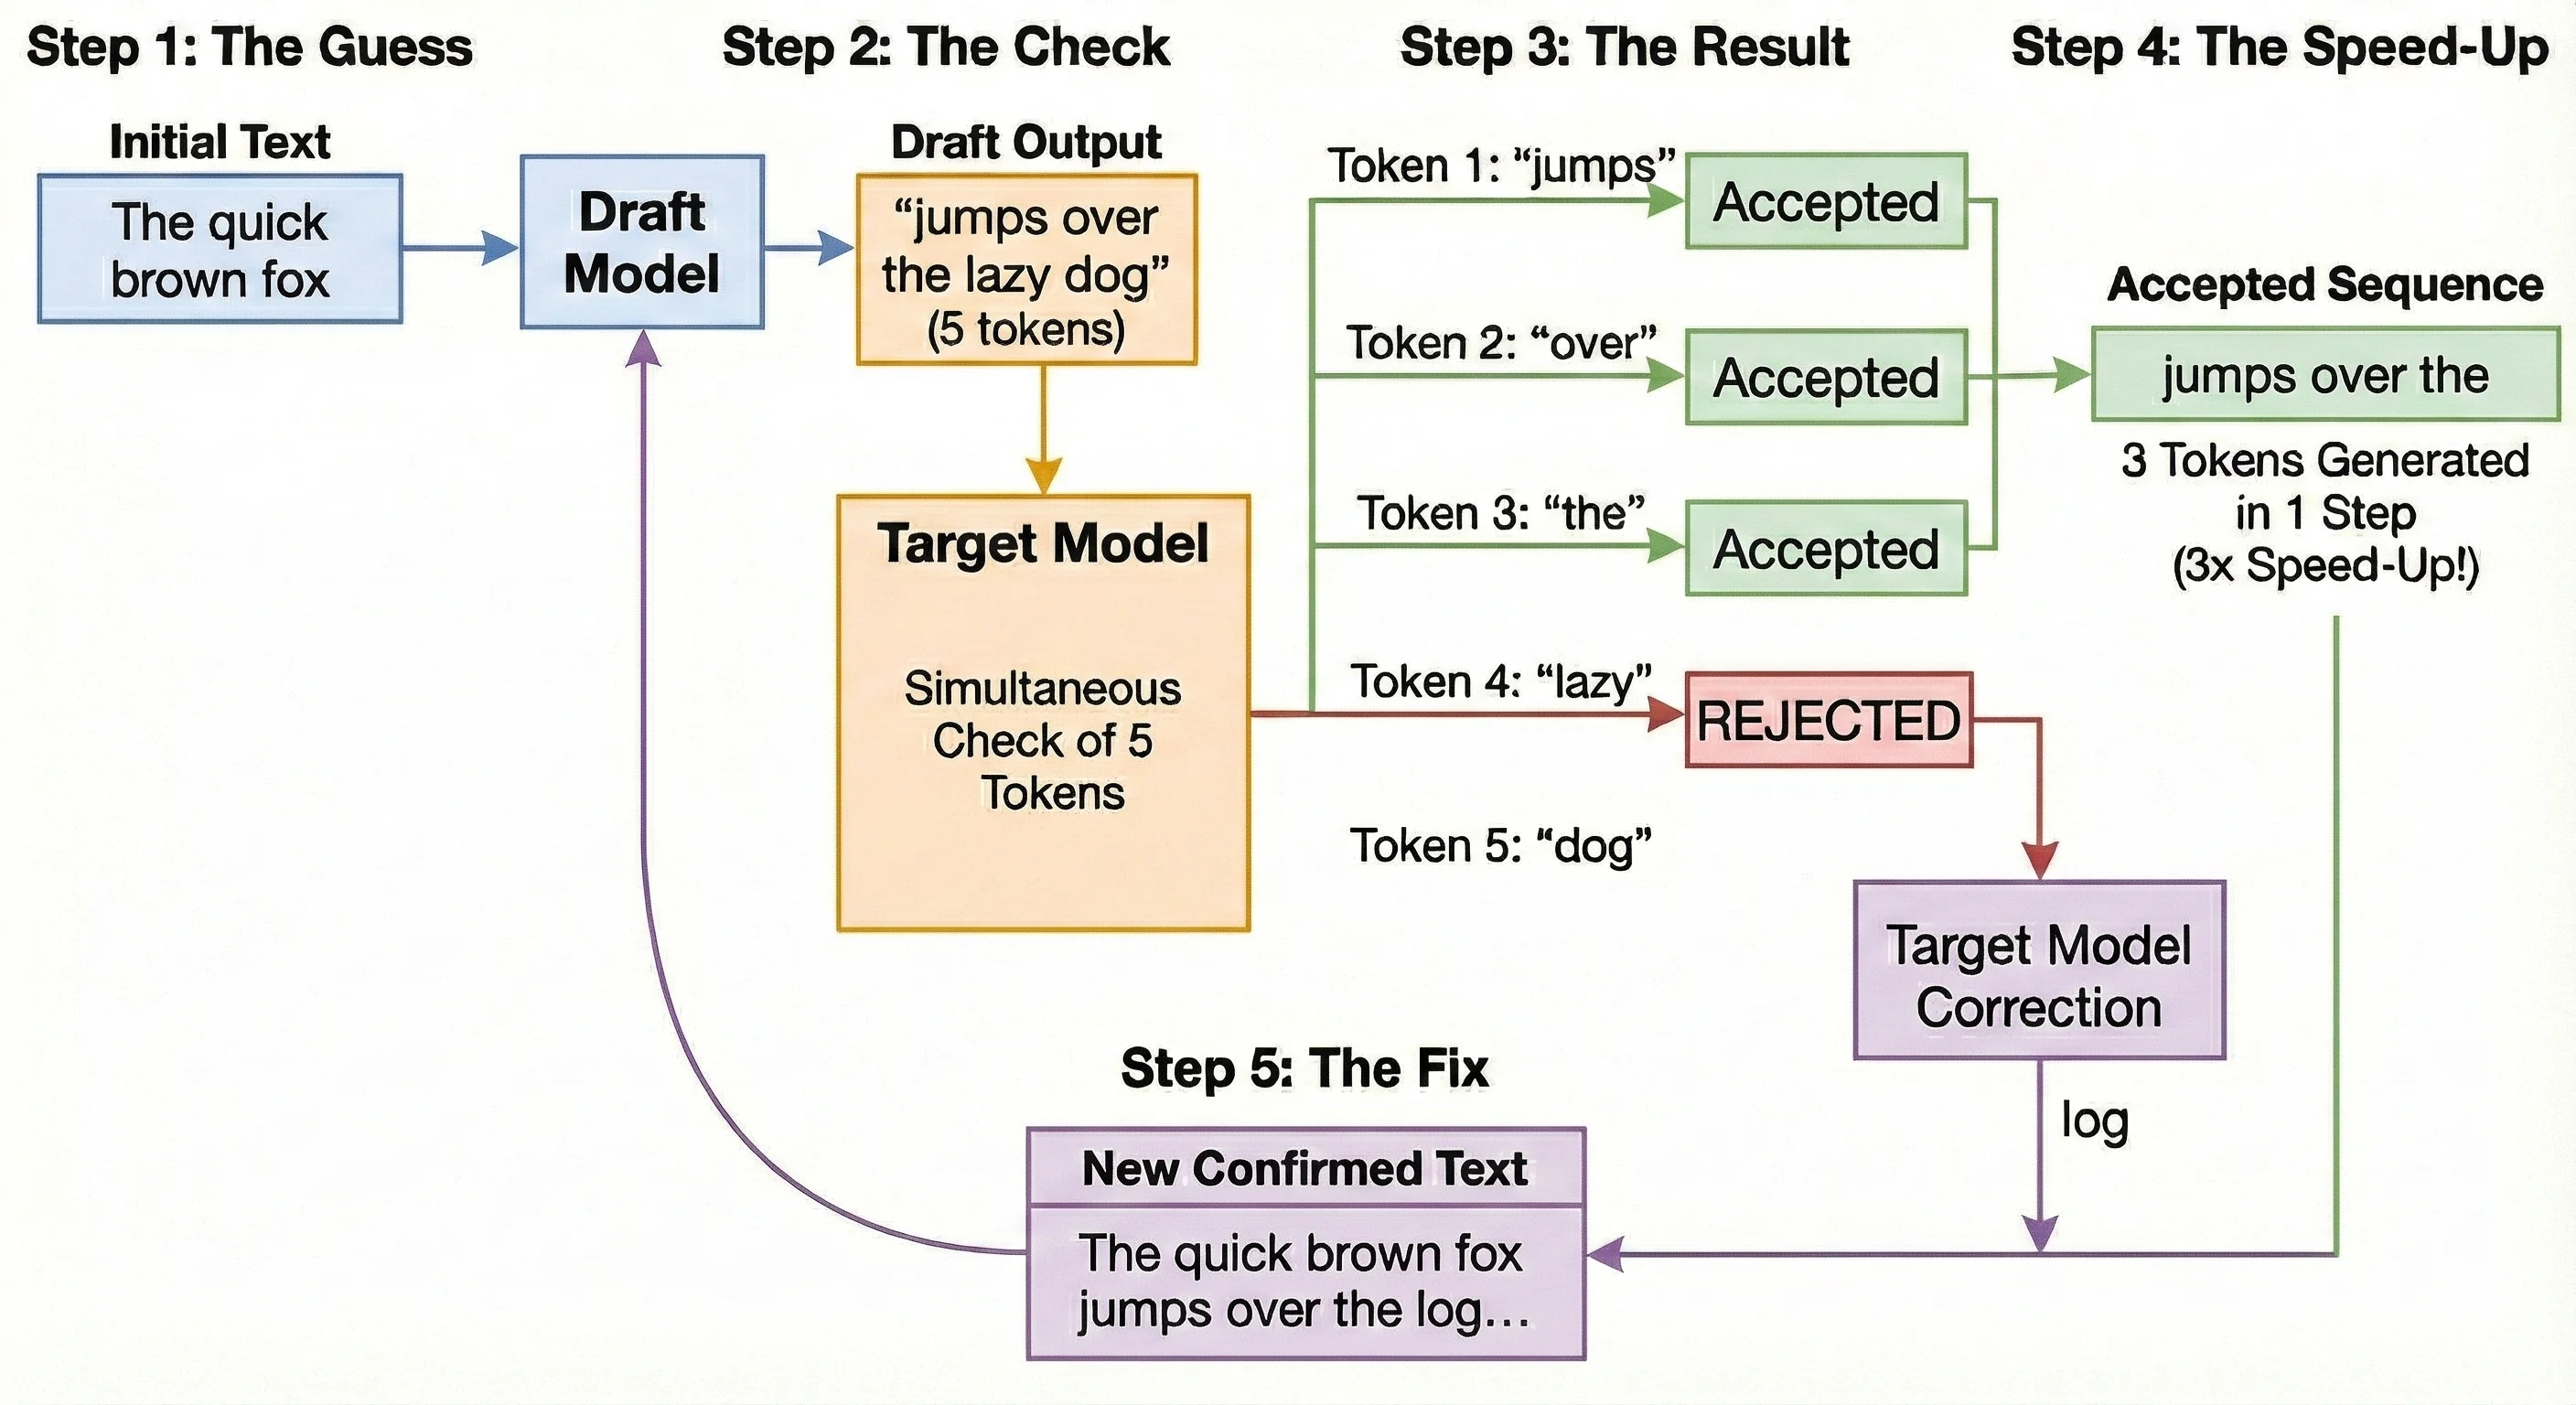
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (300x250)

S2D2: Fast Decoding for Diffusion LLMs via Training-Free Self-Speculation
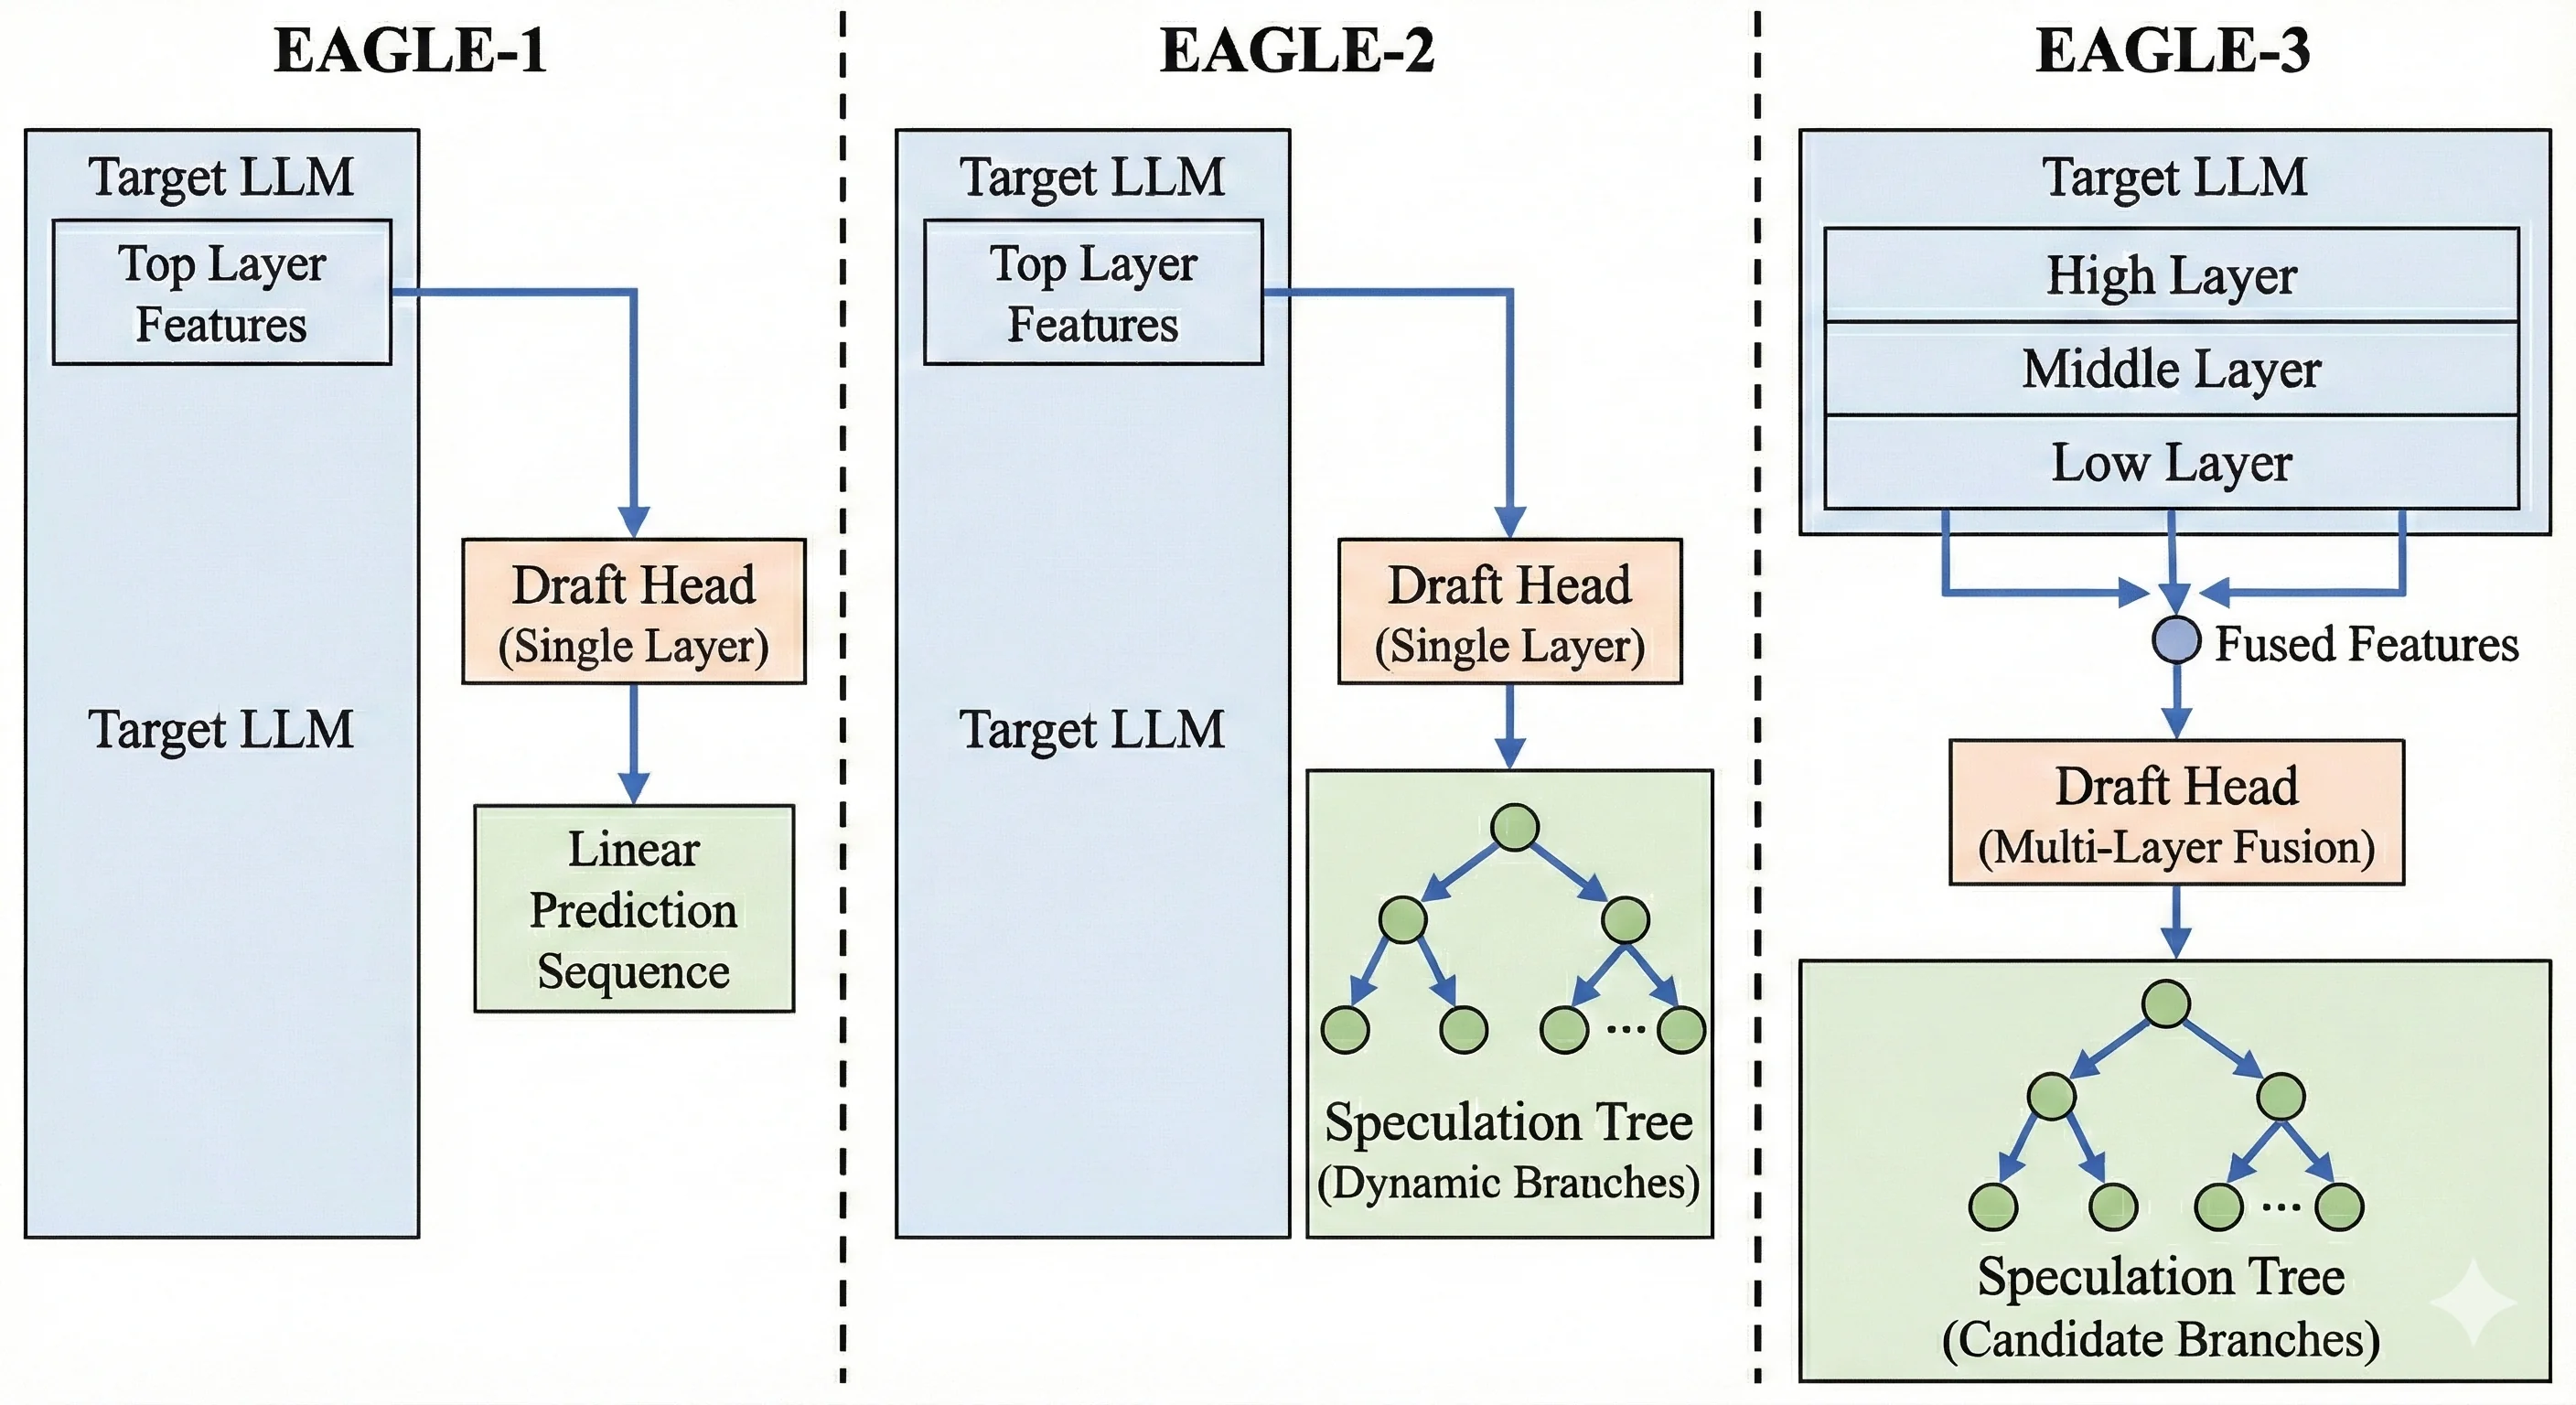
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
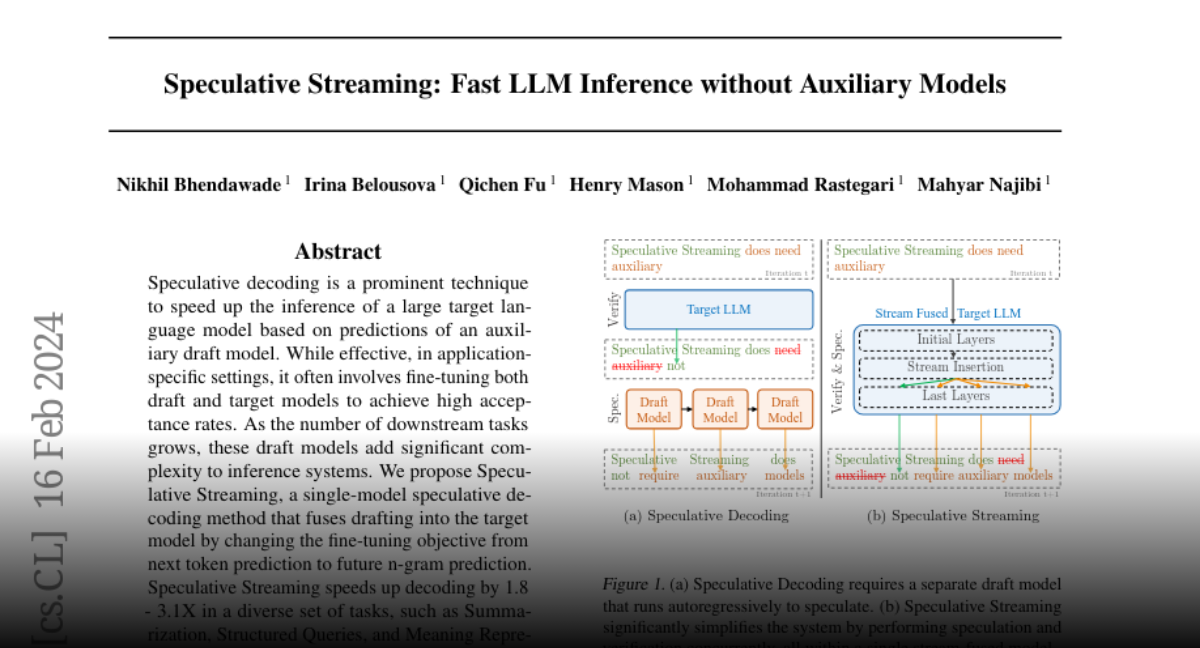
Paper page - Speculative Streaming: Fast LLM Inference without ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...

Paper page - DFlash: Block Diffusion for Flash Speculative Decoding

DFlash: Block Diffusion for Flash Speculative Decoding | AI Research ...
DART Brings Diffusion Concepts to Accelerate LLM Inference

Speculative Streaming: Fast LLM Inference without Auxiliary Models
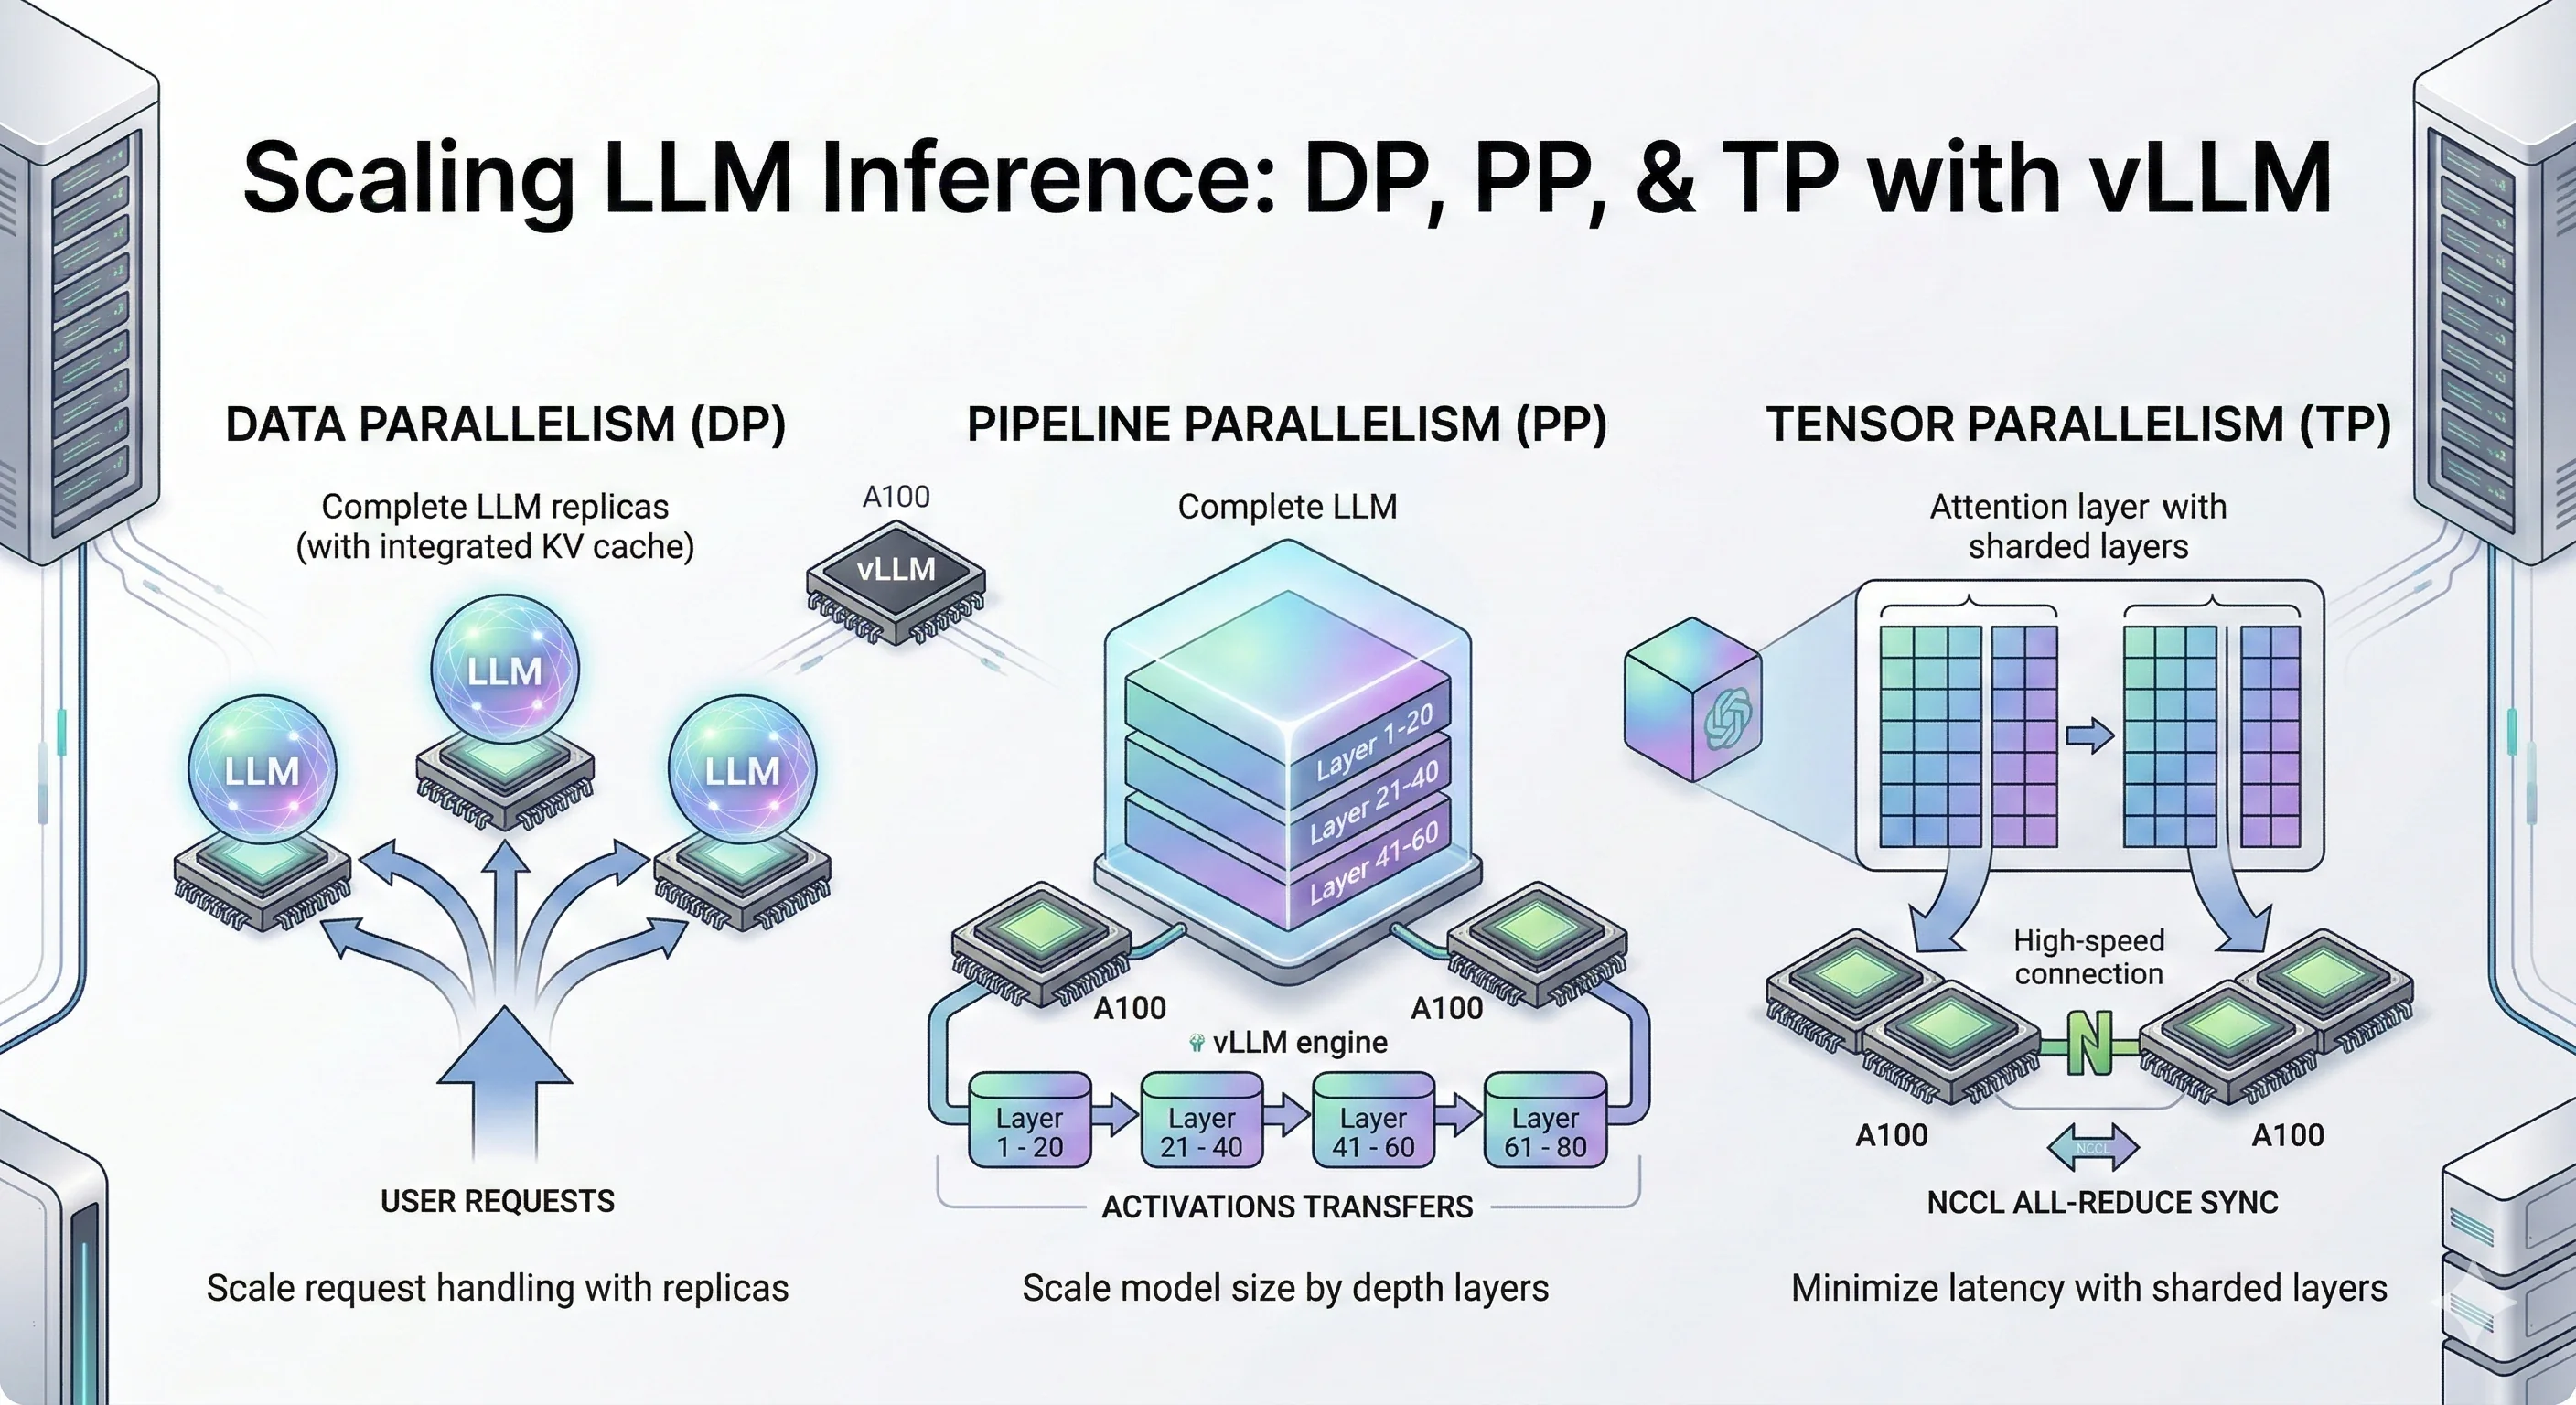
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
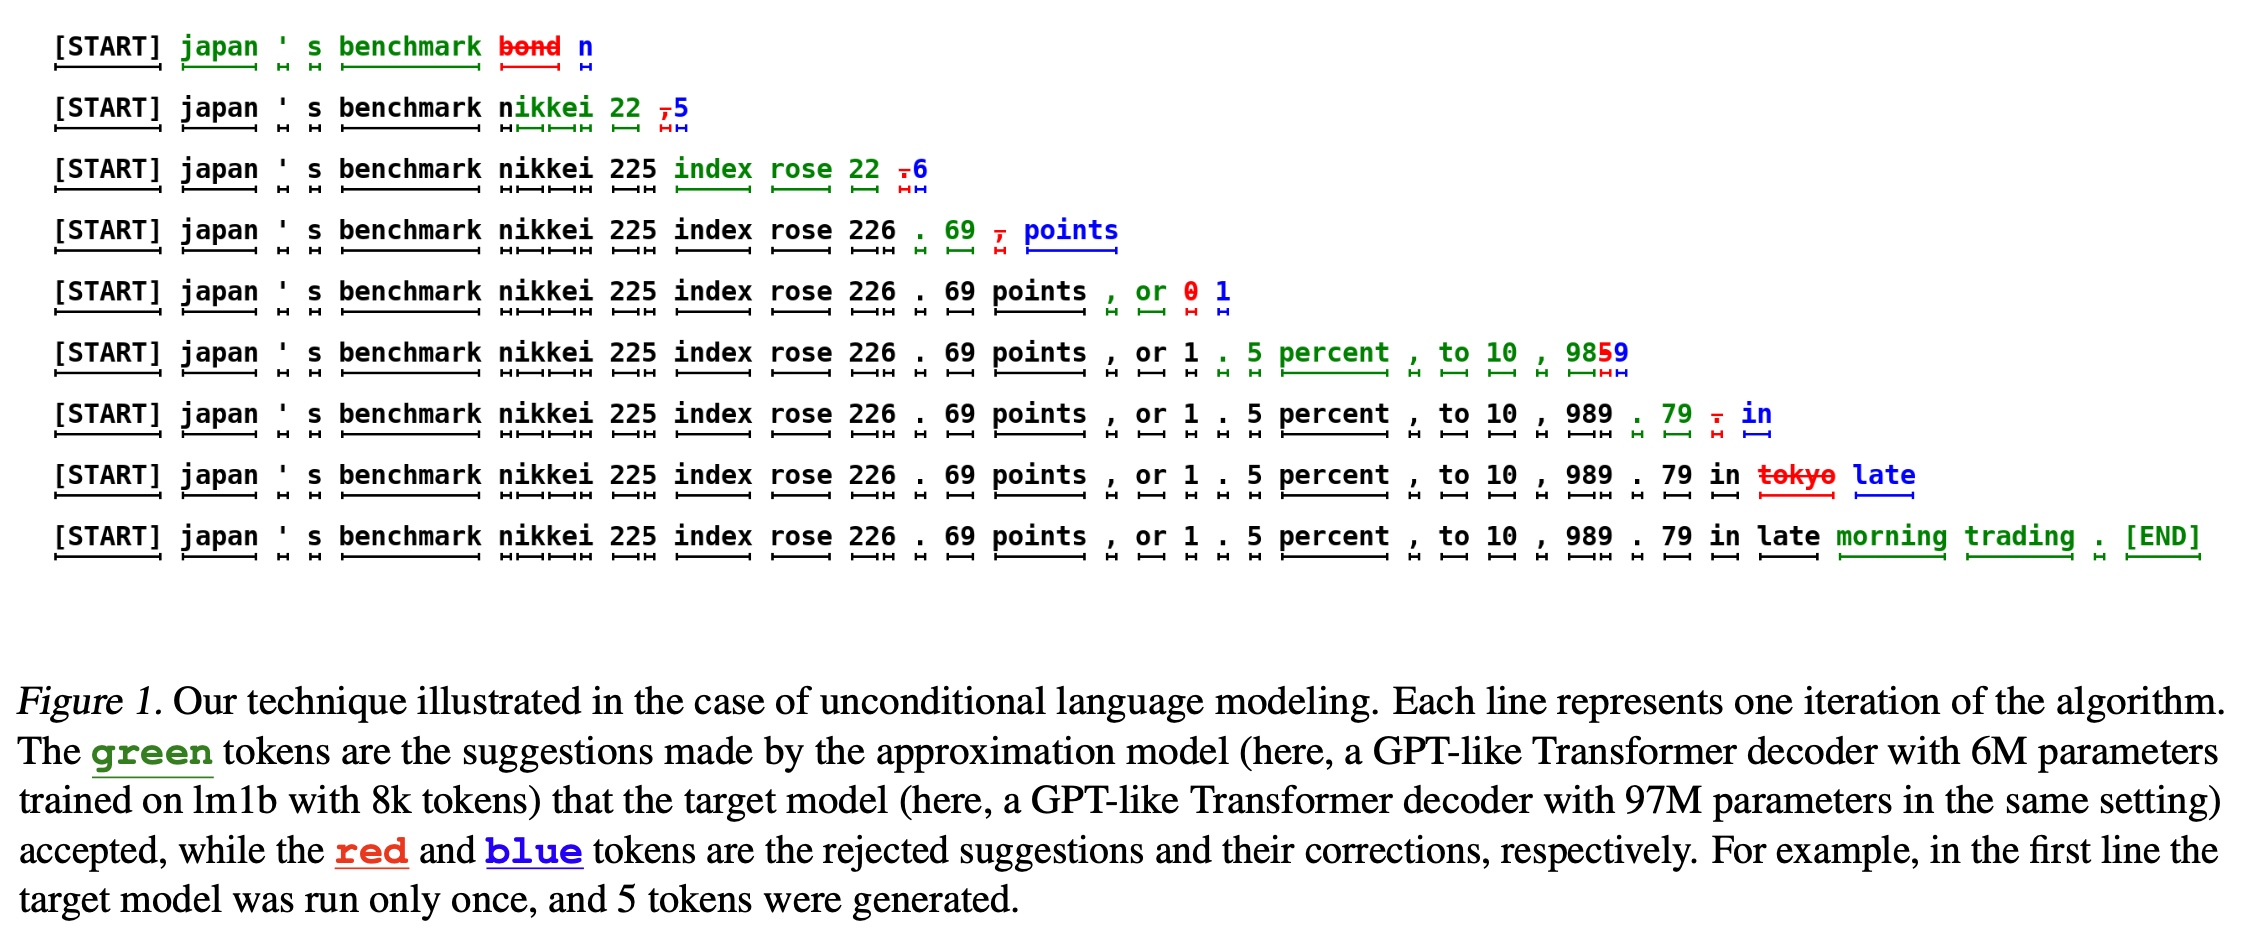
Accelerate LLM Inference with Speculative Decoding | Charles Xu
Advertisement Space (336x280)

Figure 2 from Speculative Streaming: Fast LLM Inference without ...
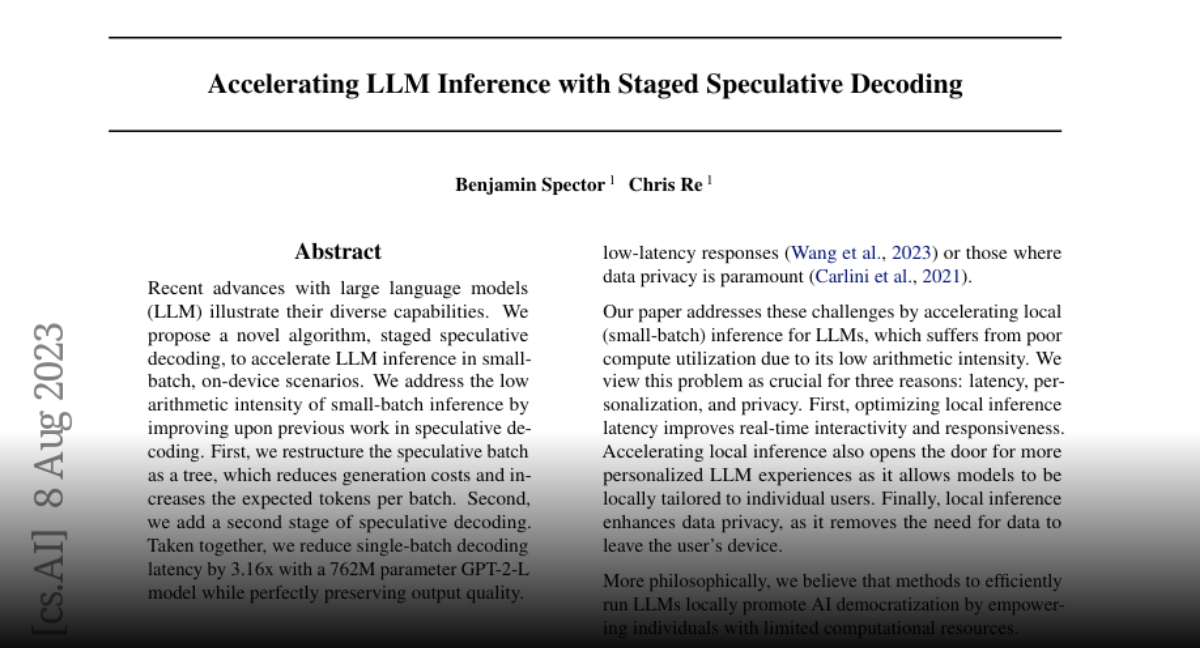
Paper page - Accelerating LLM Inference with Staged Speculative Decoding
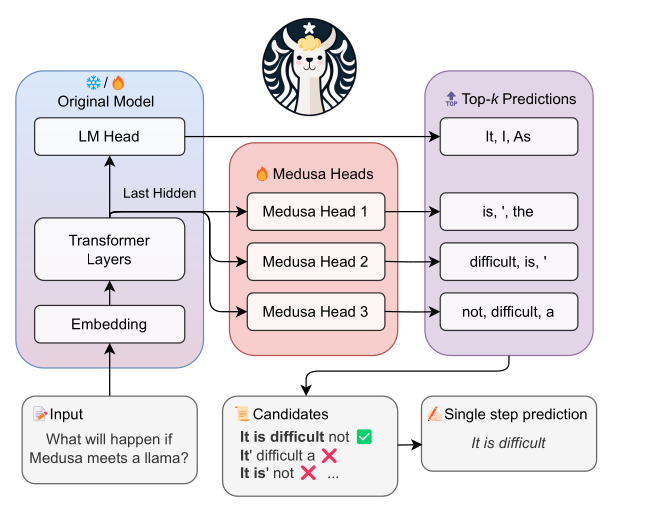
A Survey of Speculative Decoding Techniques in LLM Inference

Self Speculative Decoding for Diffusion Large Language Models | AI ...
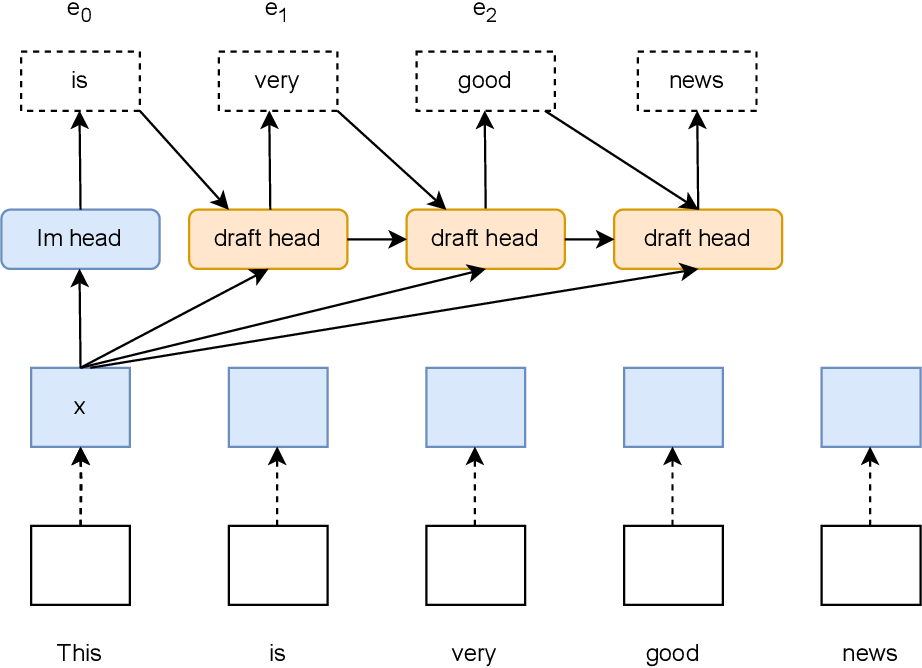
Figure 1 from Recurrent Drafter for Fast Speculative Decoding in Large ...

(PDF) Fast Inference from Transformers via Speculative Decoding
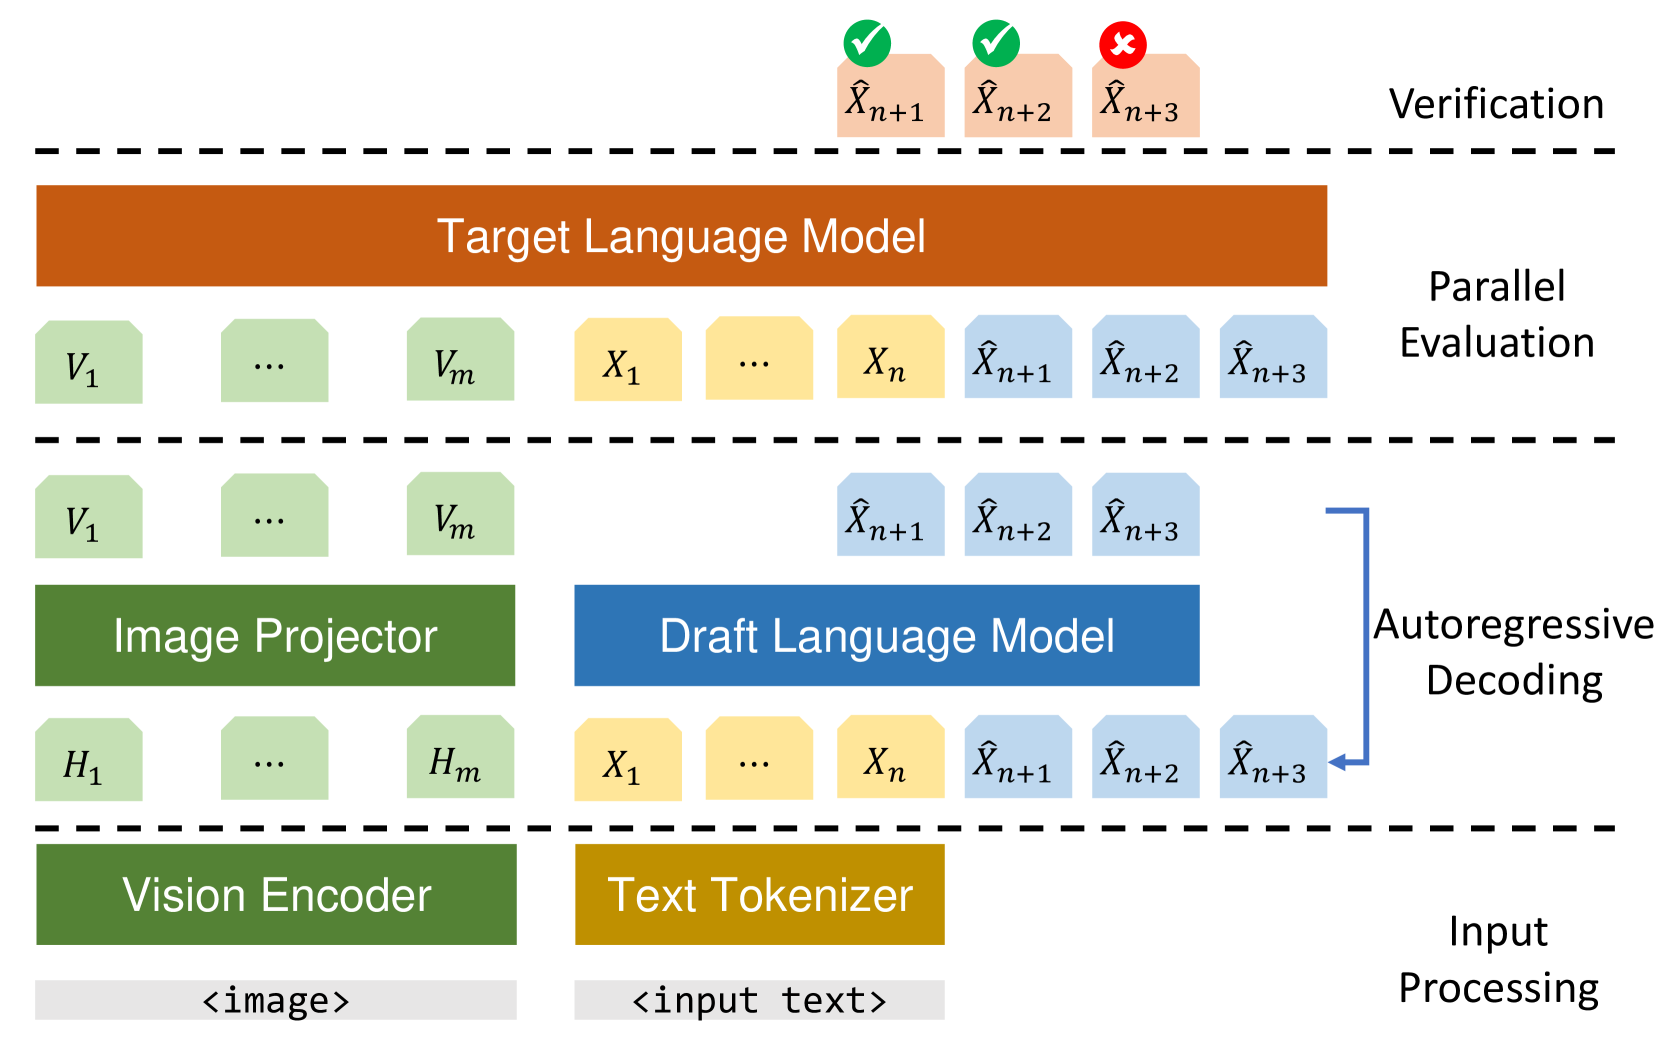
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
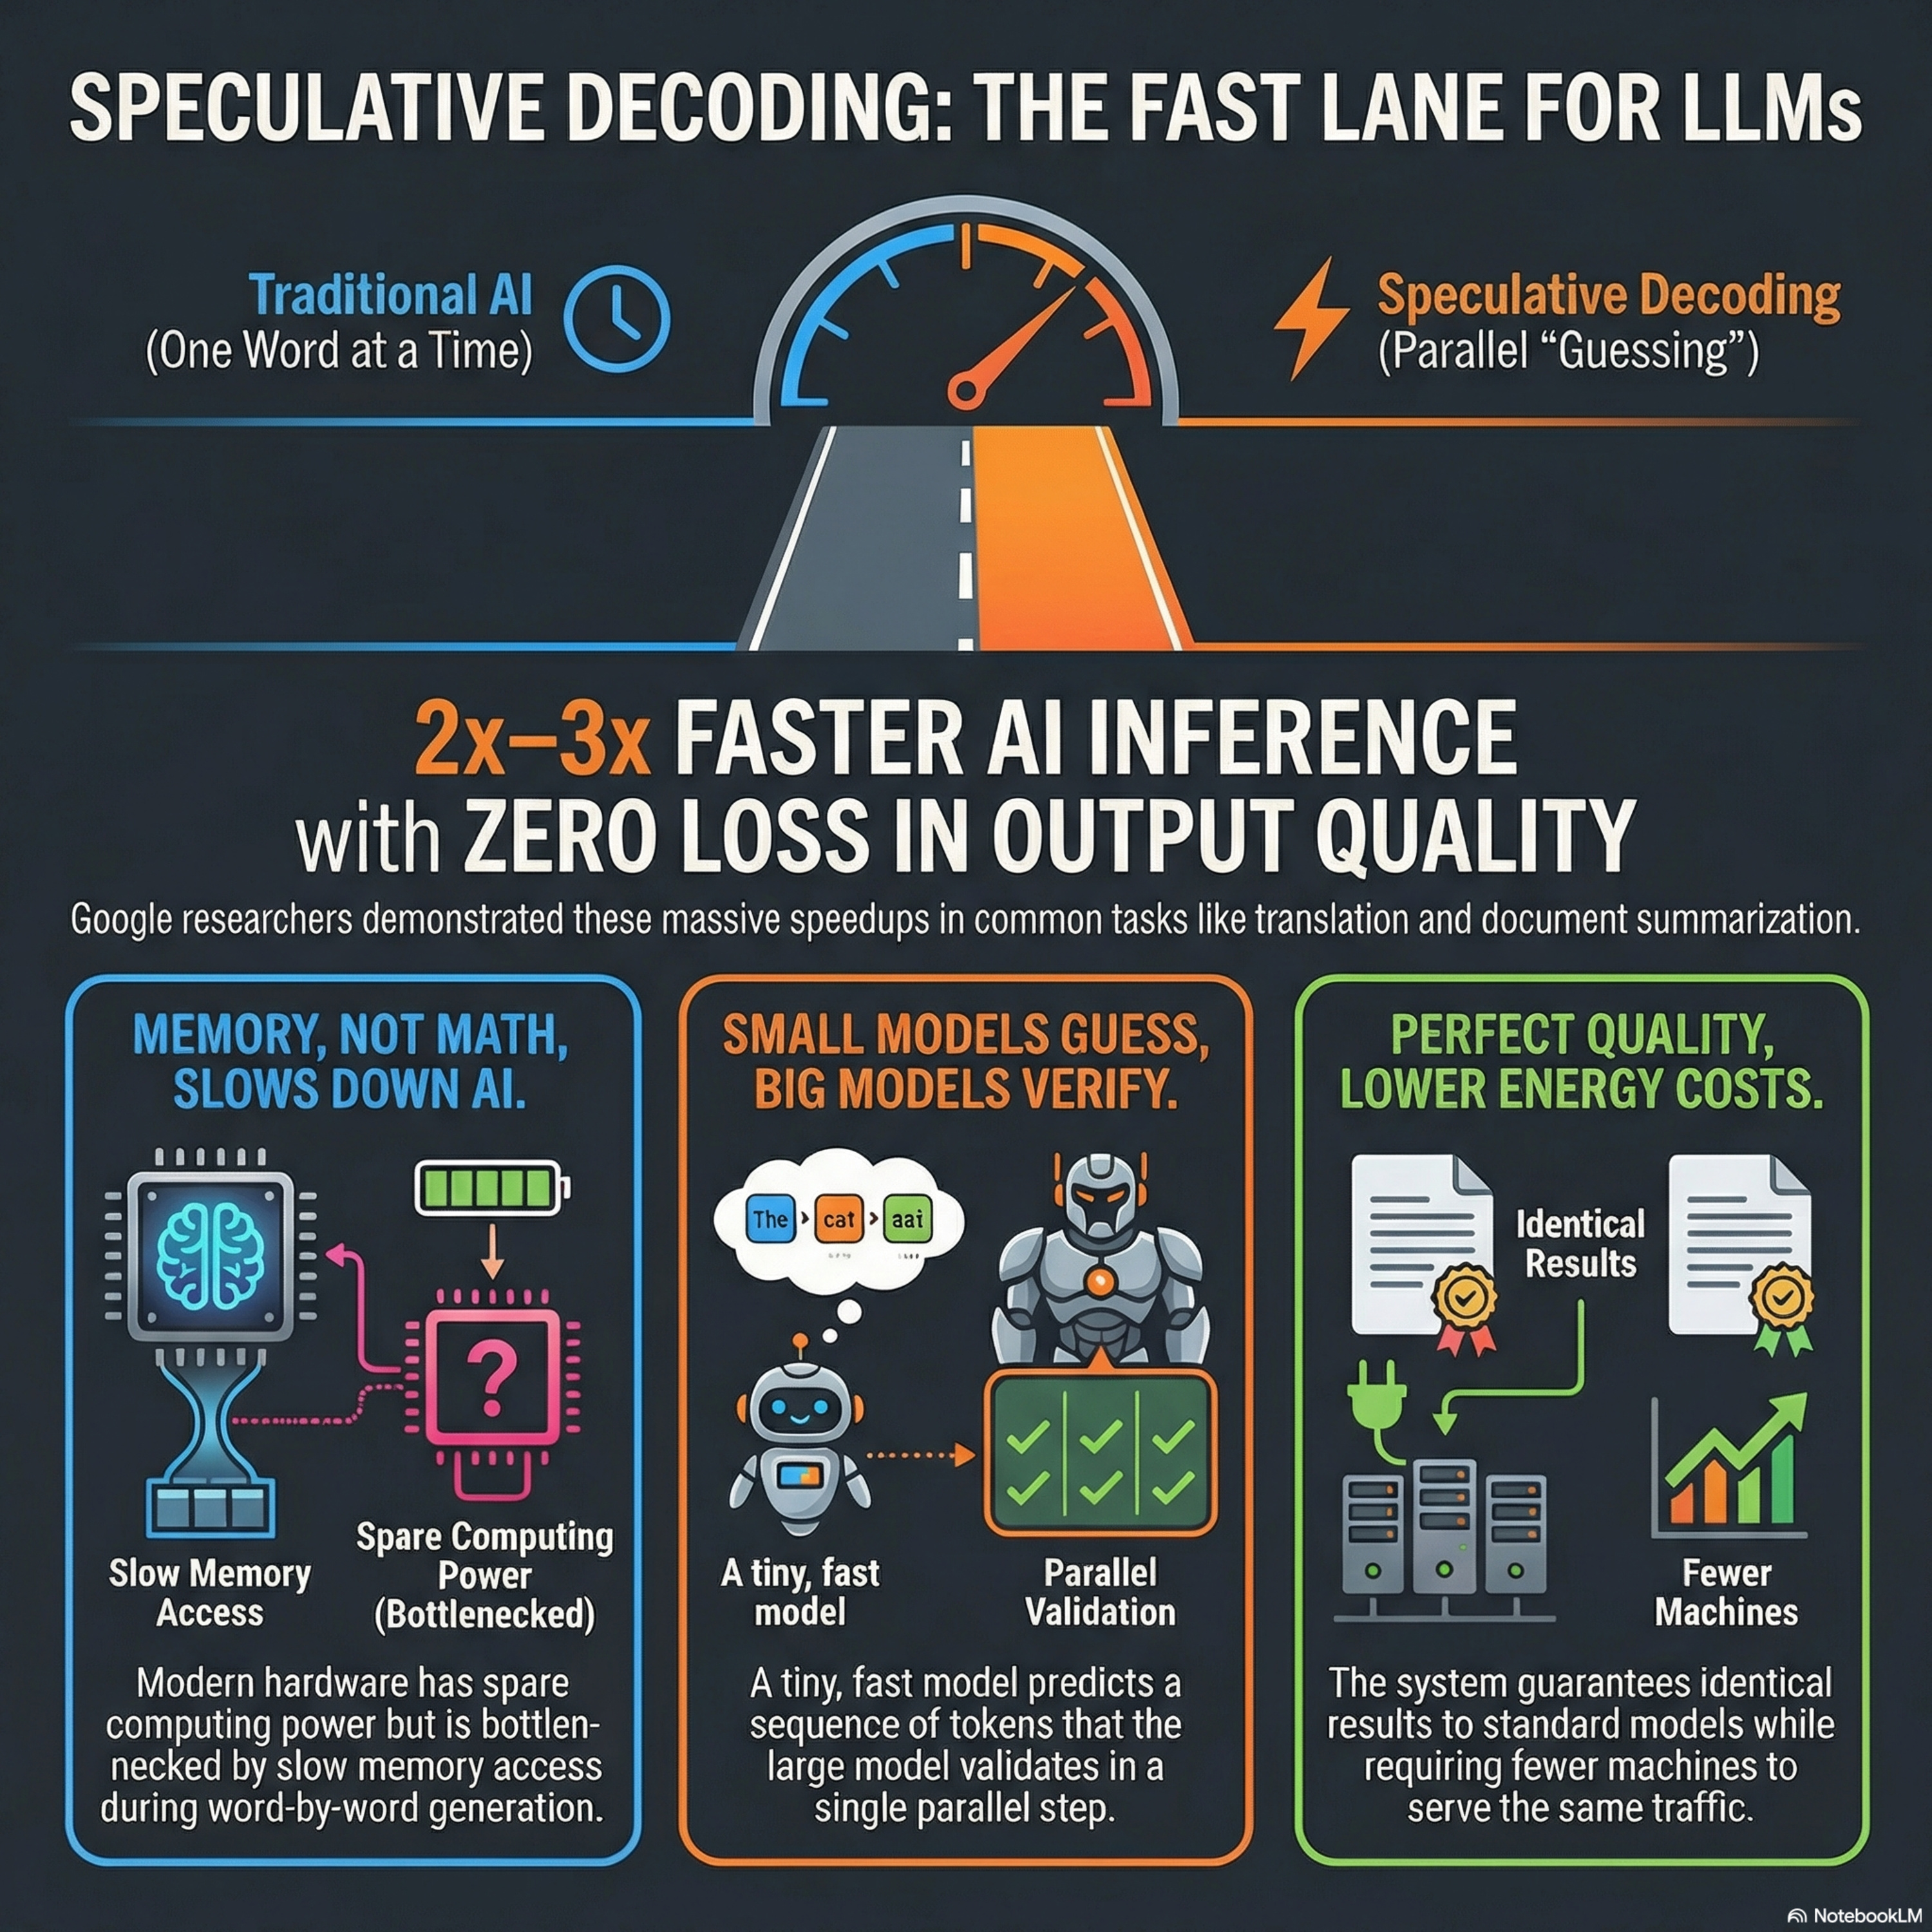
Fast Inference from Transformers via Speculative Decoding — AI Post ...
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

(PDF) Accelerating LLM Inference with Staged Speculative Decoding
Advertisement Space (336x280)
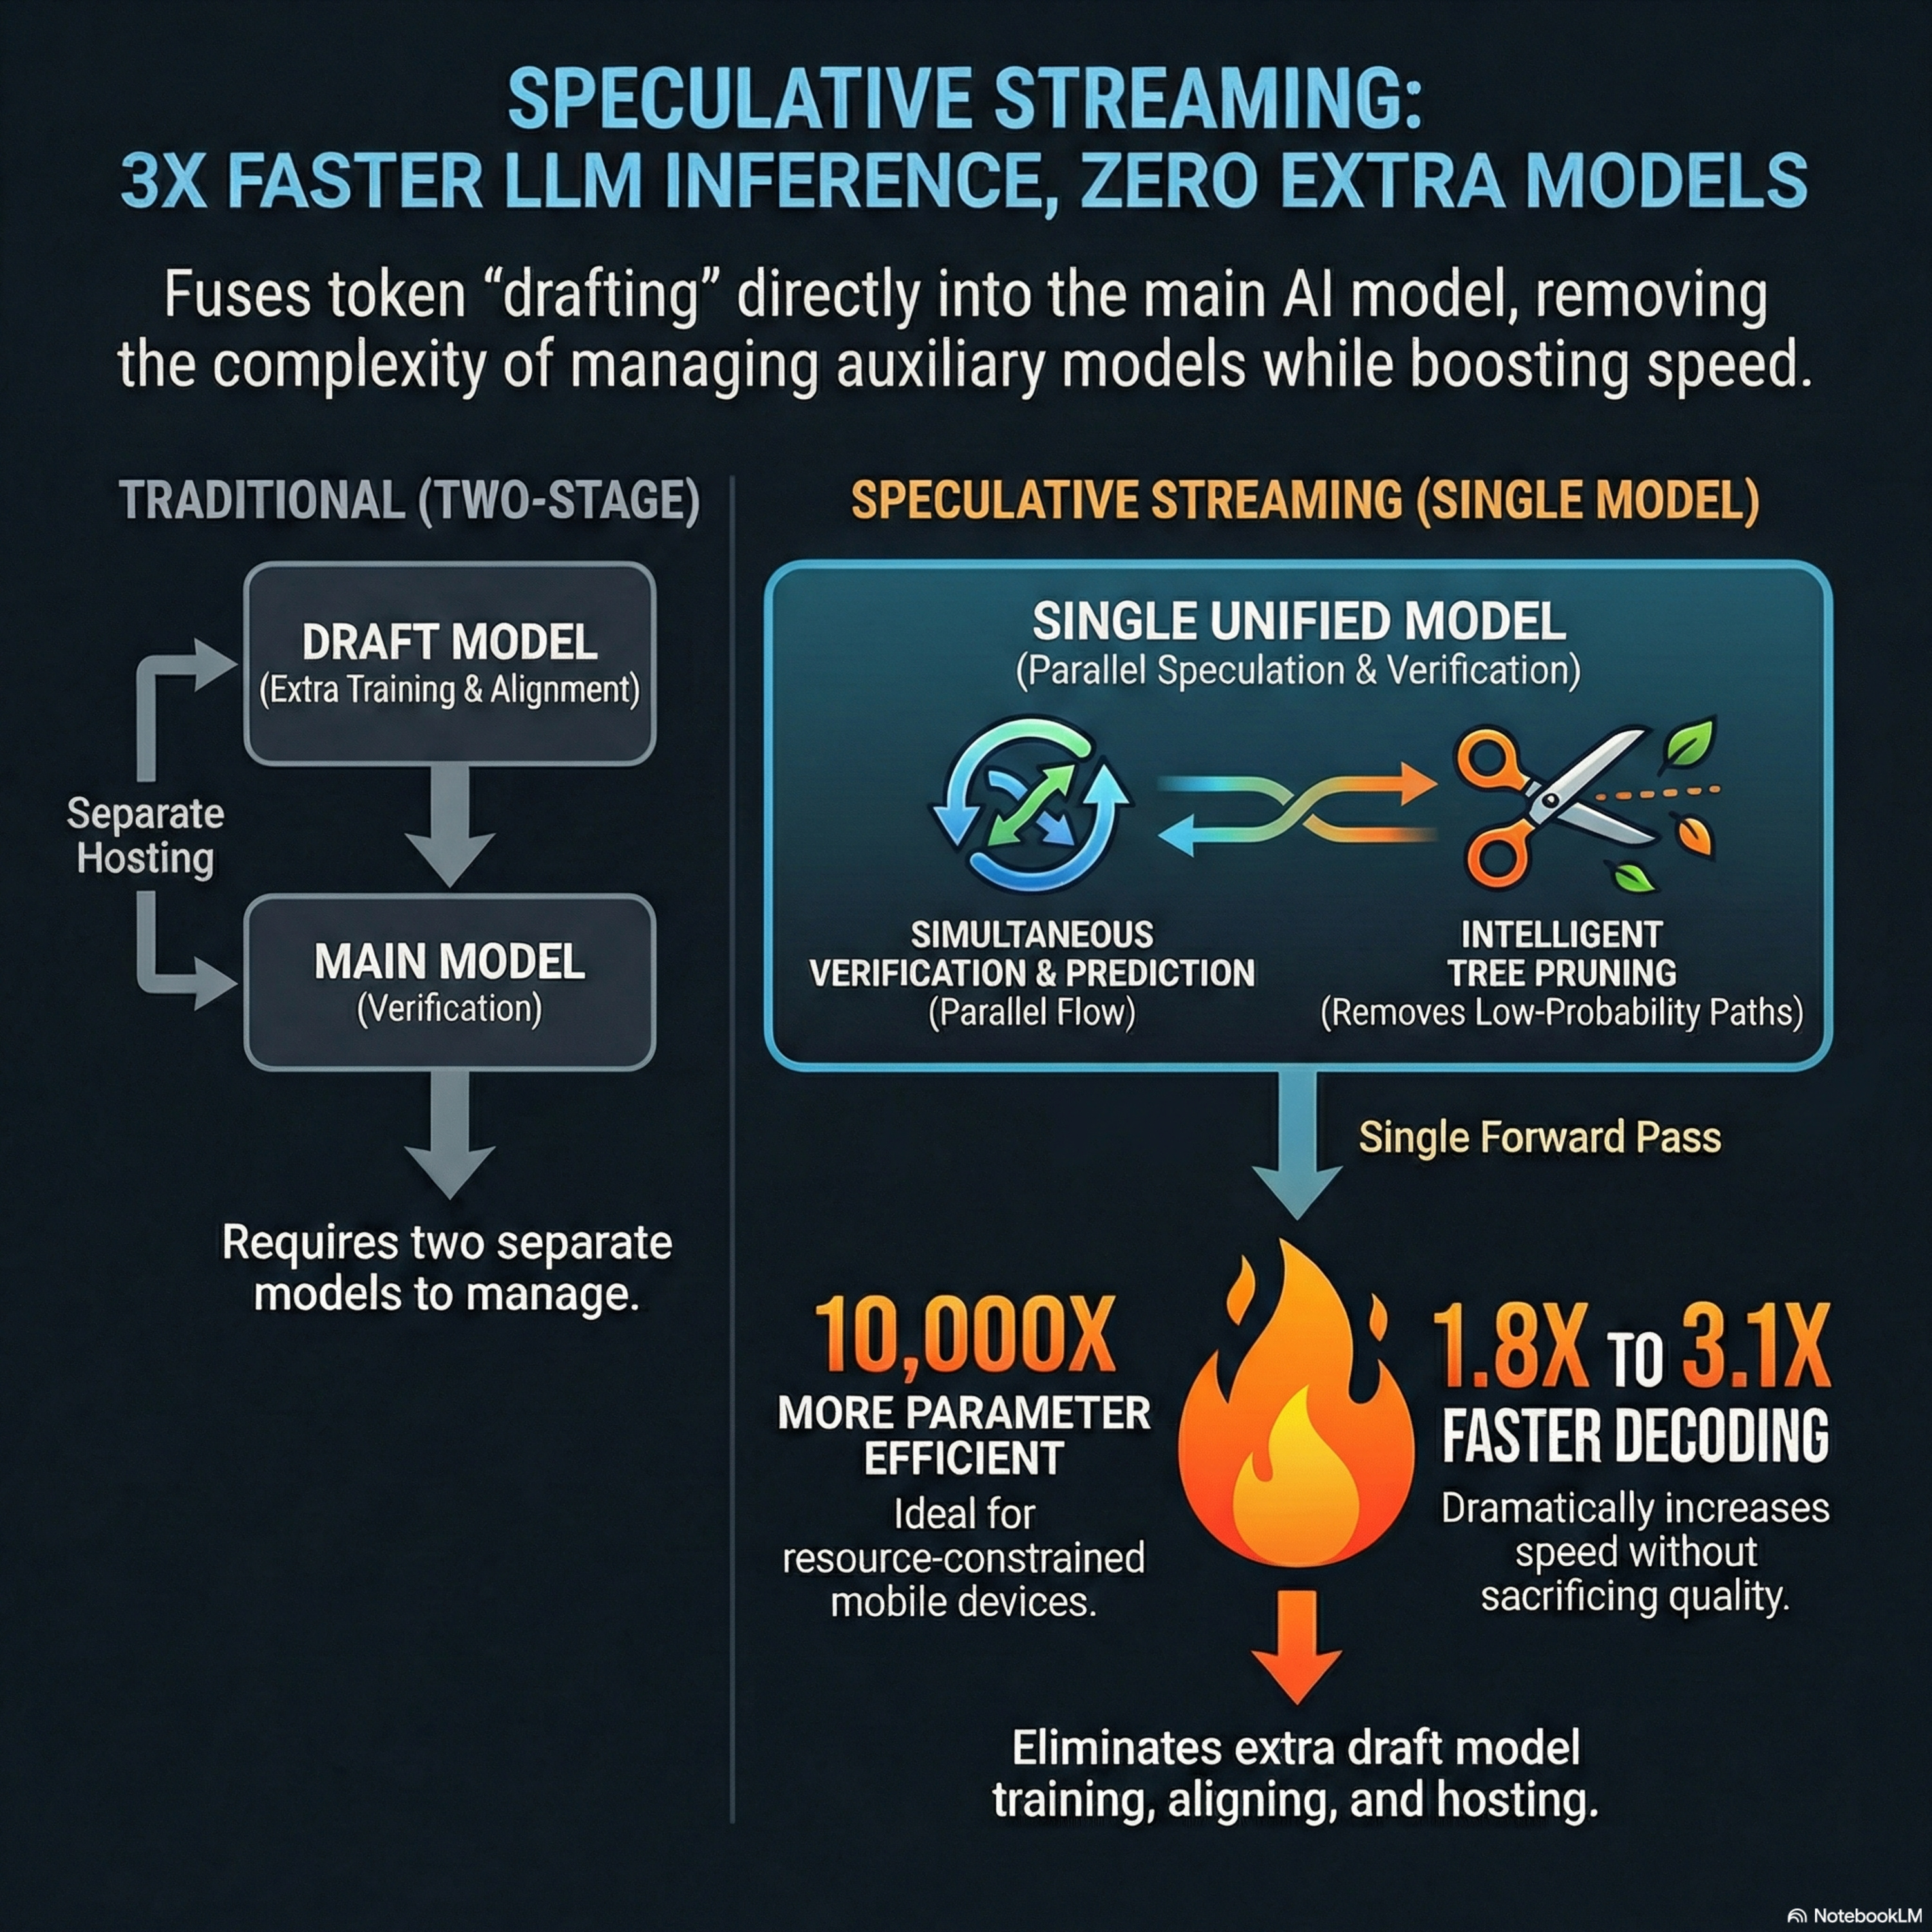
Apple's Speculative Streaming: Fast LLM Inference without Auxiliary ...

(PDF) Towards Fast Multilingual LLM Inference: Speculative Decoding and ...
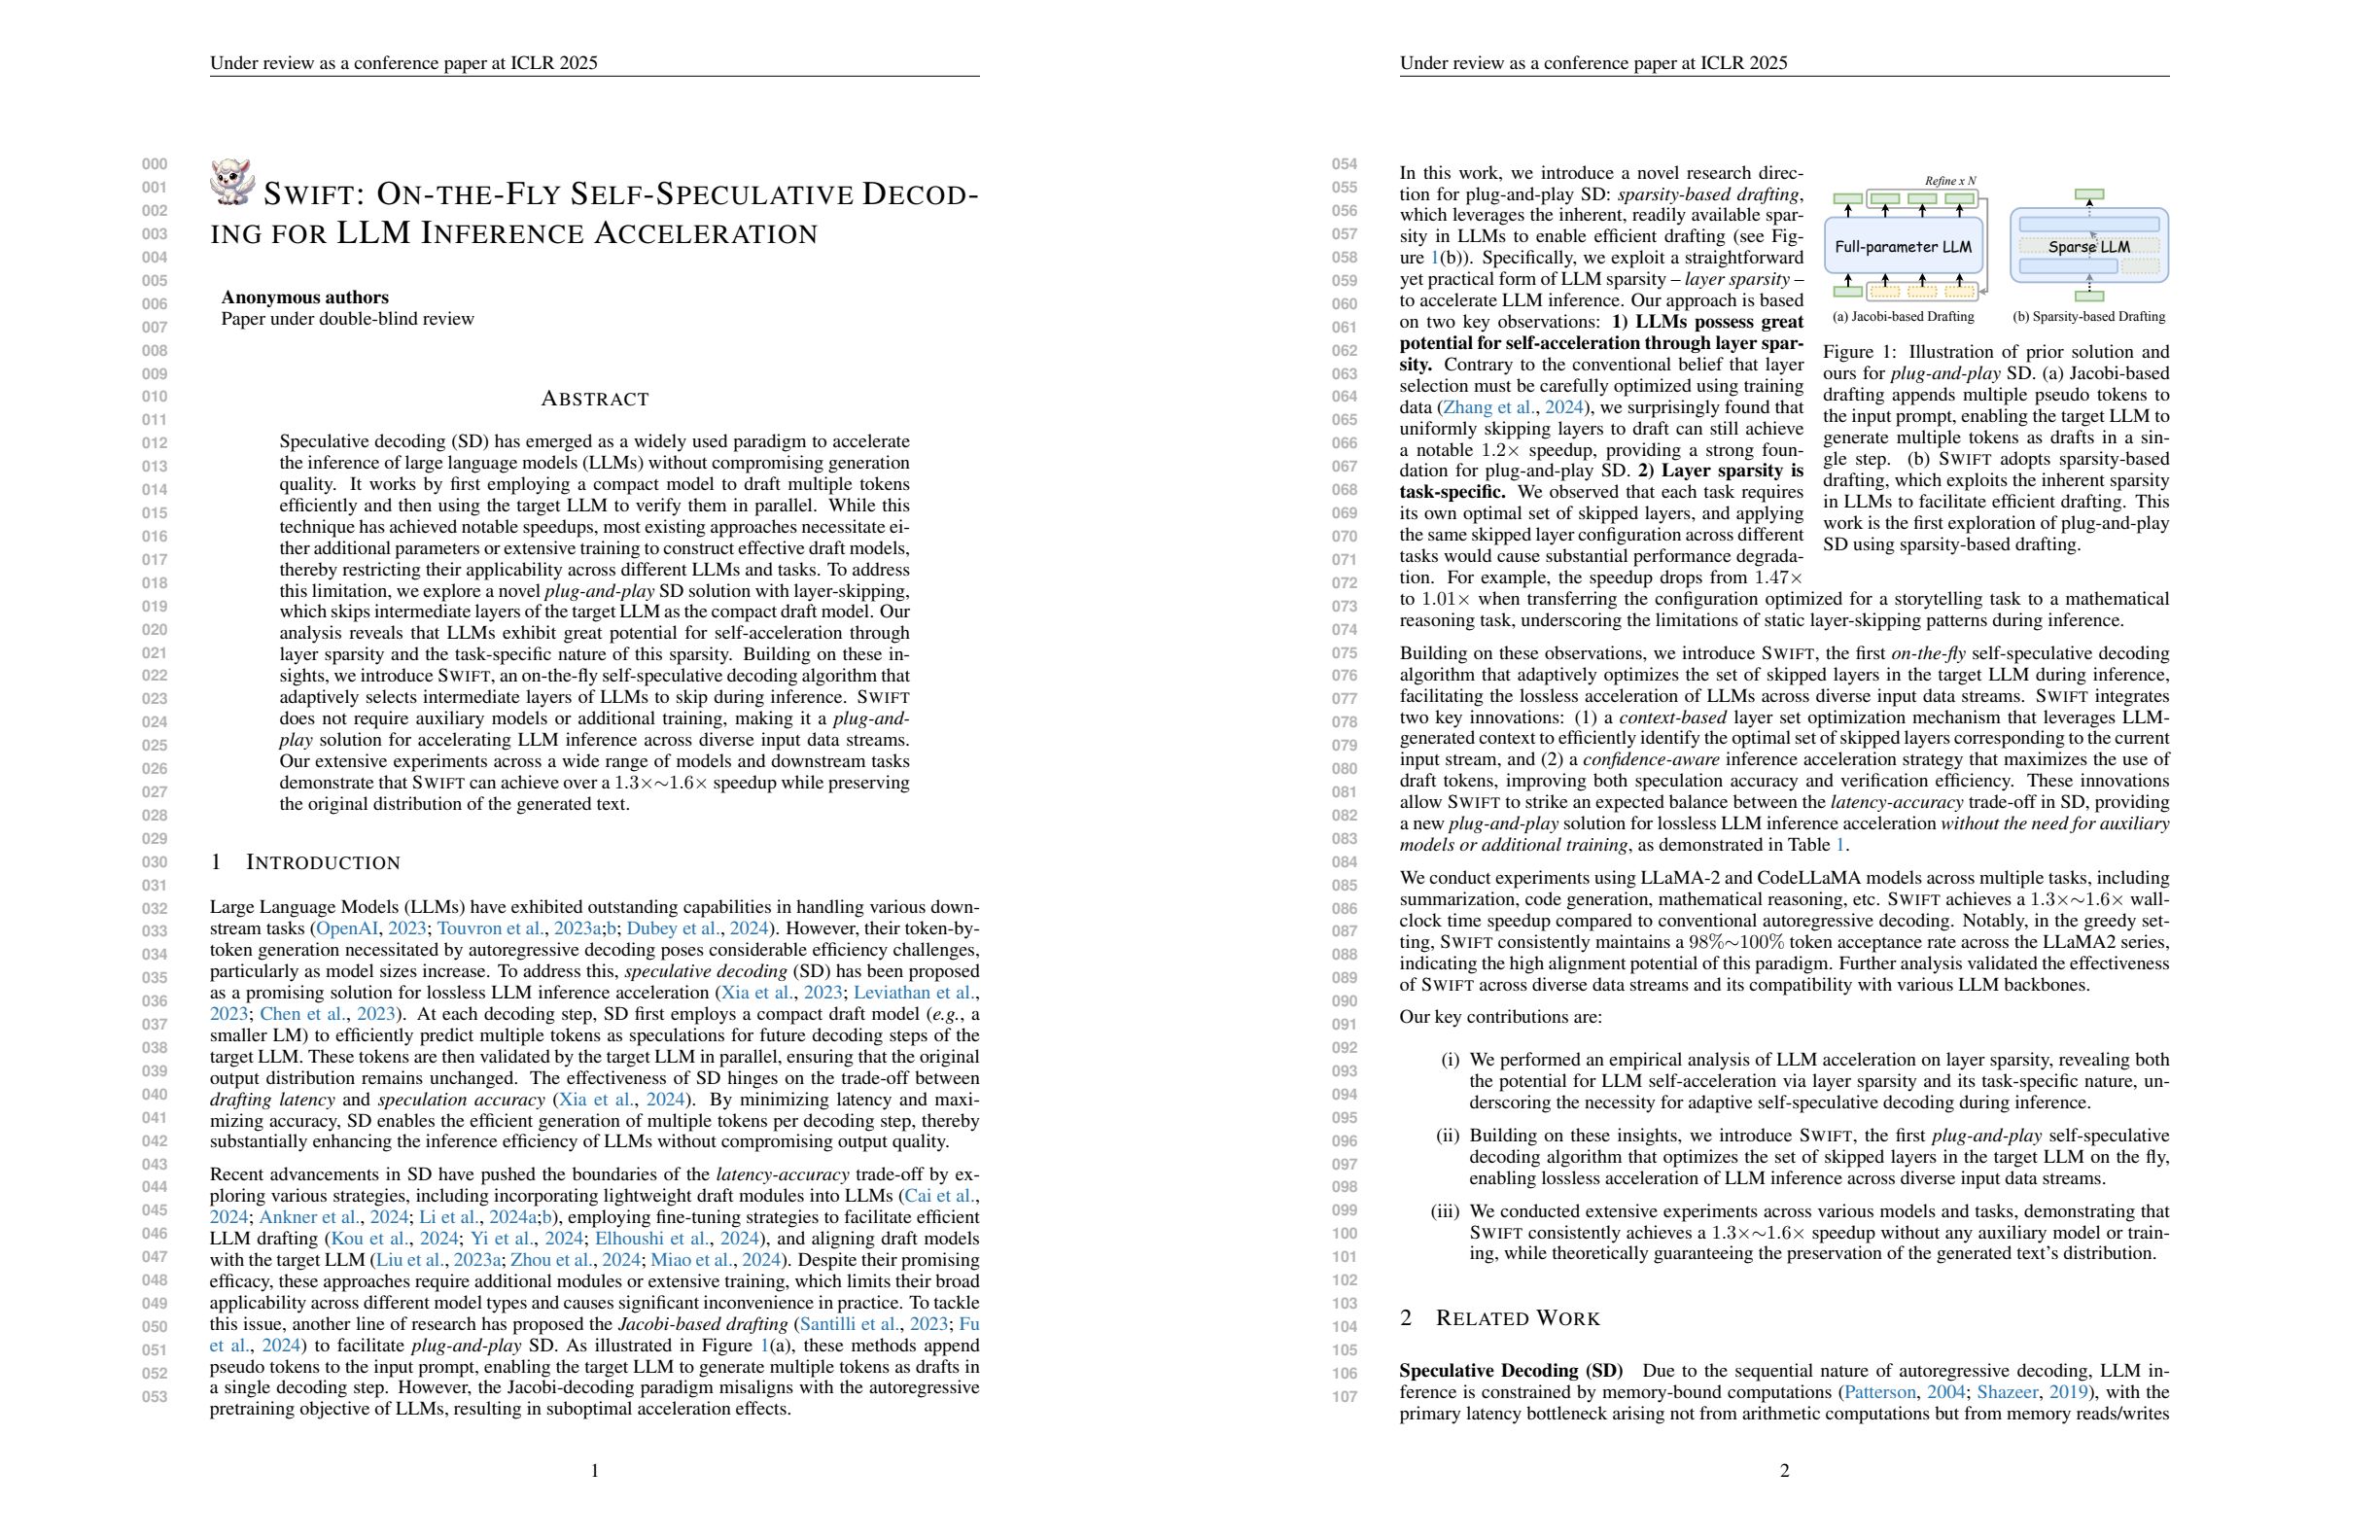
SWIFT: On-the-Fly Self-Speculative Decoding for LLM Inference Acceleration
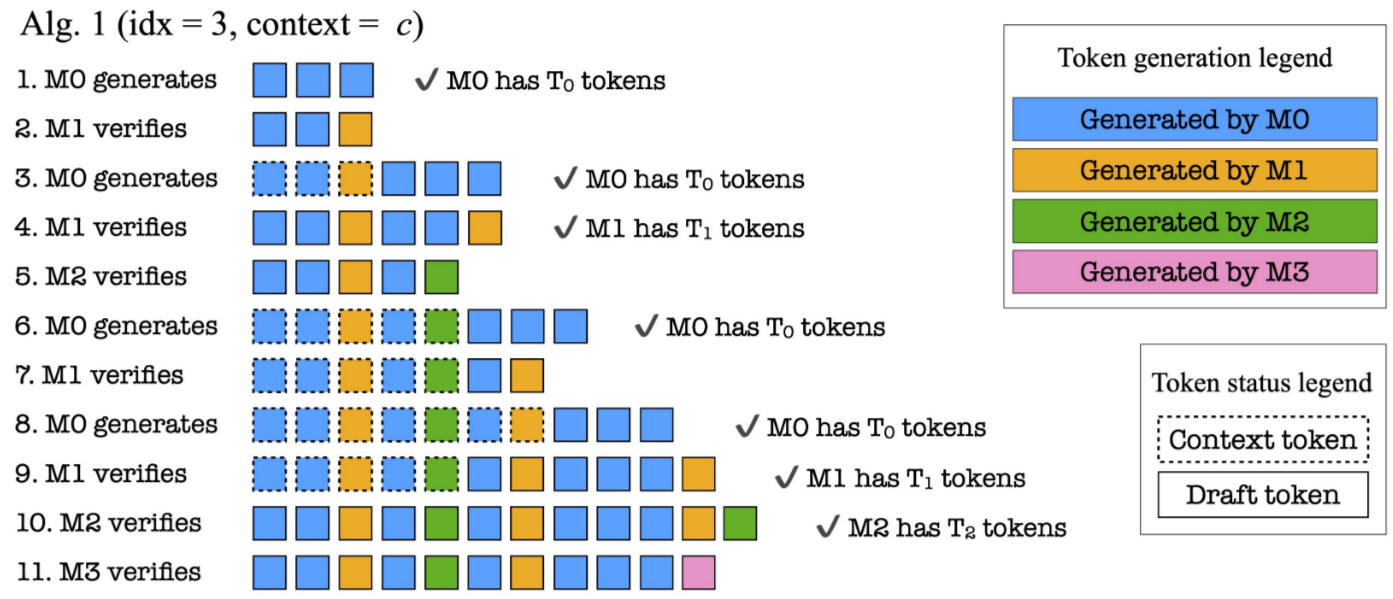
[論文レビュー] Fast Inference via Hierarchical Speculative Decoding
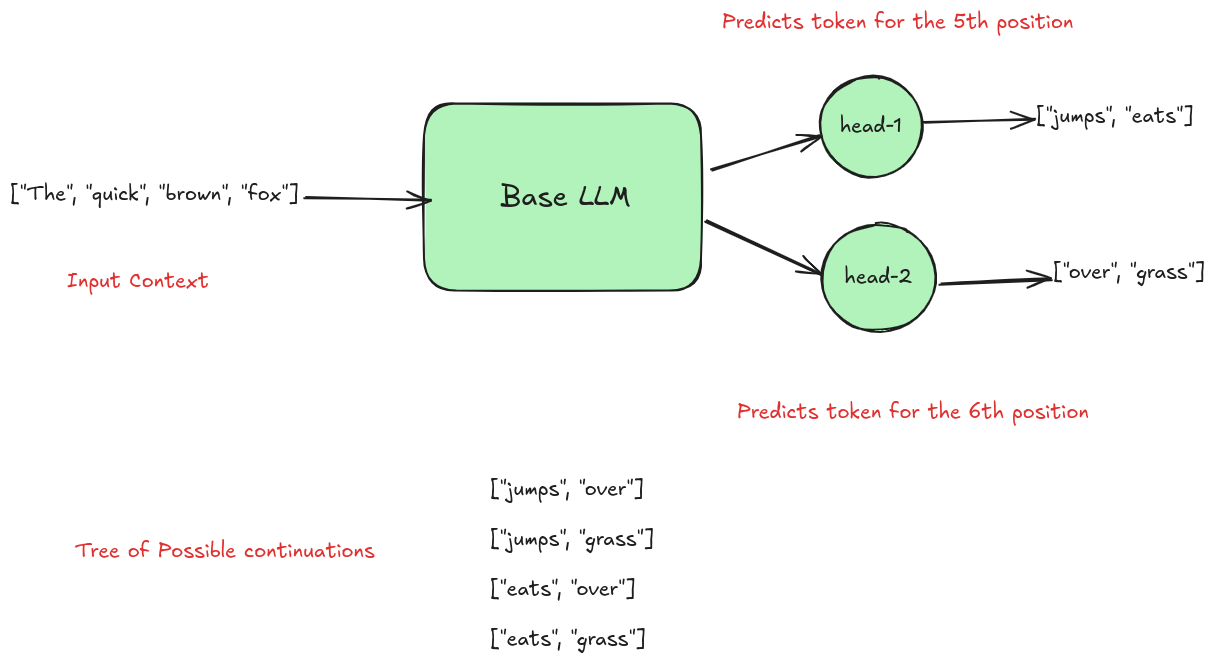
A Survey of Speculative Decoding Techniques in LLM Inference
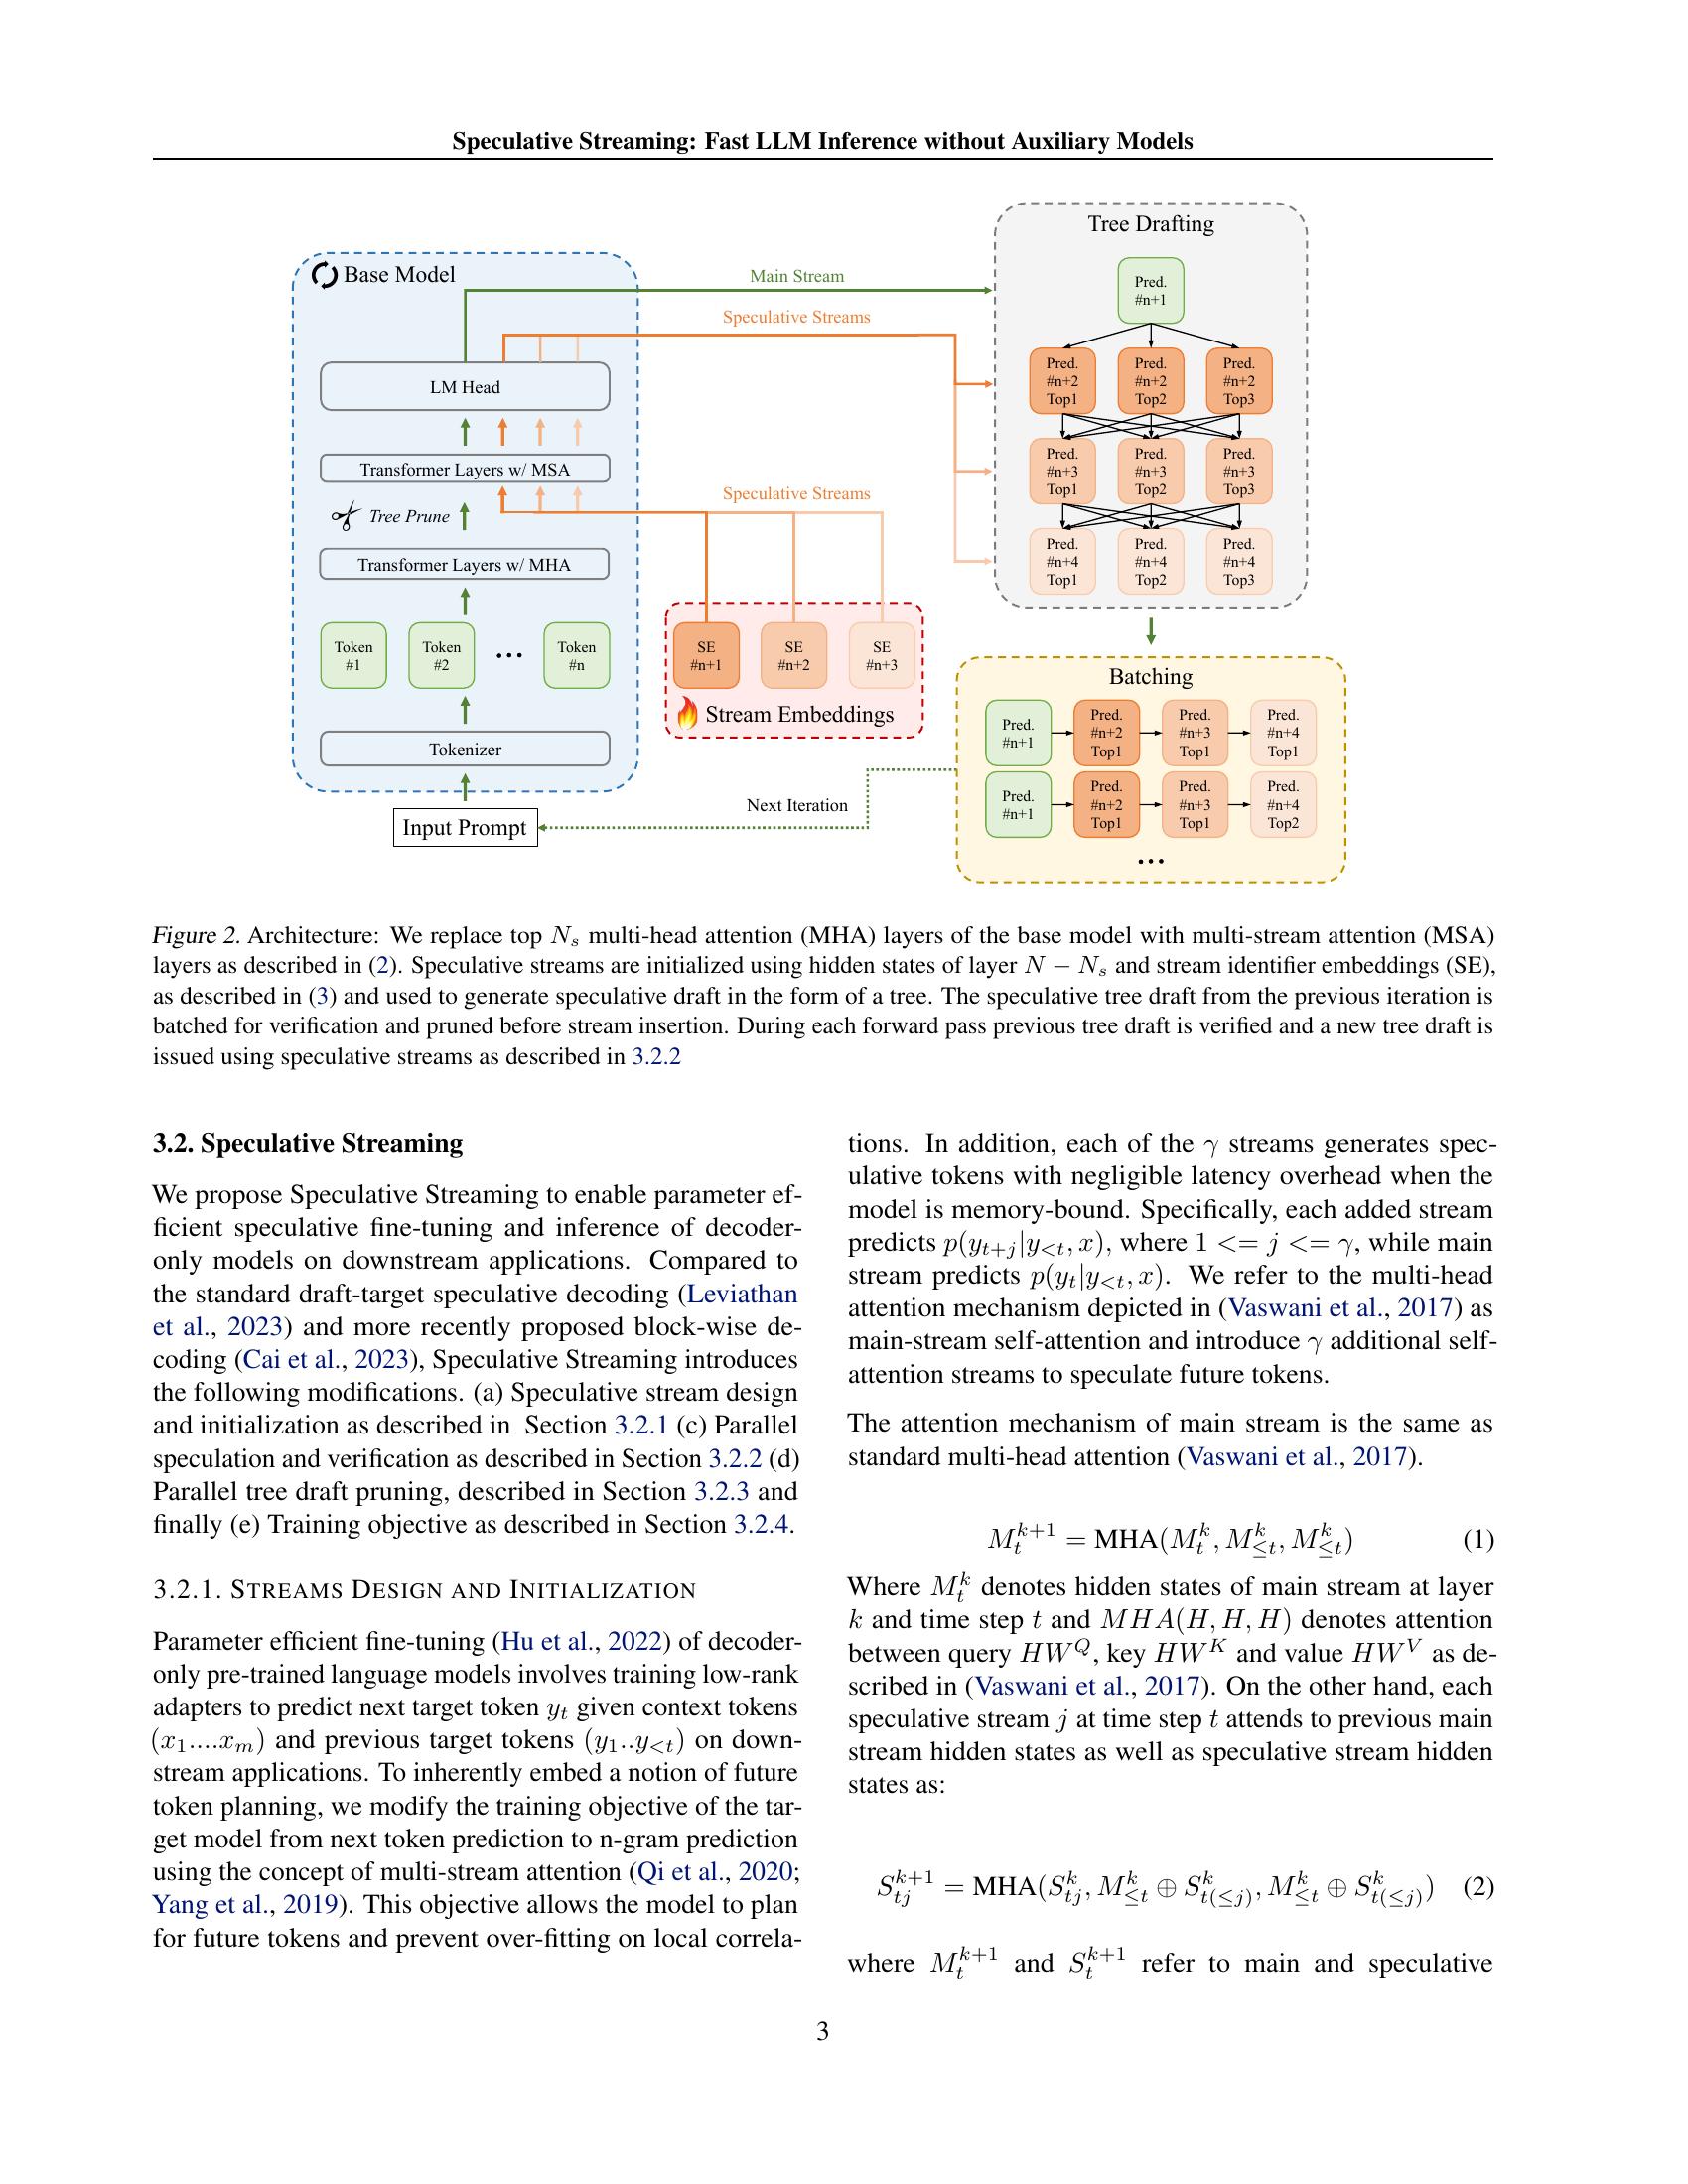
Speculative Streaming: Fast LLM Inference without Auxiliary Models - 智源社区论文