
Paper Page Dart Diffusion Inspired Speculative Decoding For Fast Llm

Paper page - DART: Diffusion-Inspired Speculative Decoding for Fast LLM ...

Paper page - Speculative Decoding via Early-exiting for Faster LLM ...

Paper page - Self Speculative Decoding for Diffusion Large Language Models

Paper page - Nearest Neighbor Speculative Decoding for LLM Generation ...

DART: Diffusion-Inspired Speculative Decoding for Fast LLM Inference ...

DFlash: block diffusion accelerates speculative decoding for faster LLM ...
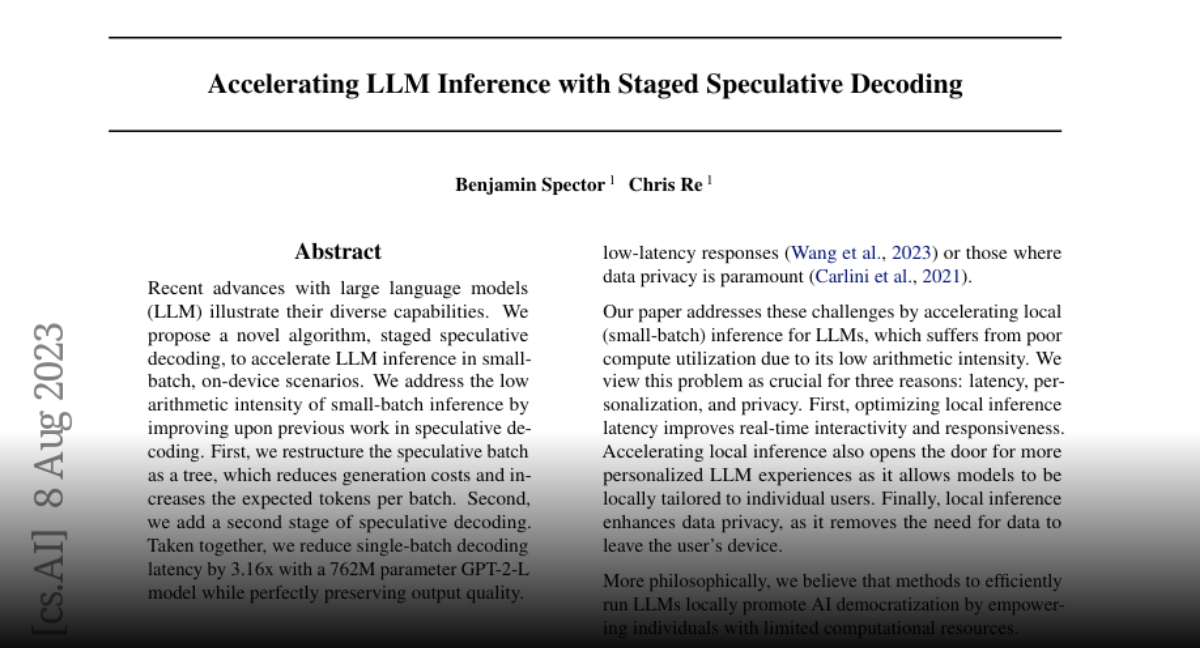
Paper page - Accelerating LLM Inference with Staged Speculative Decoding
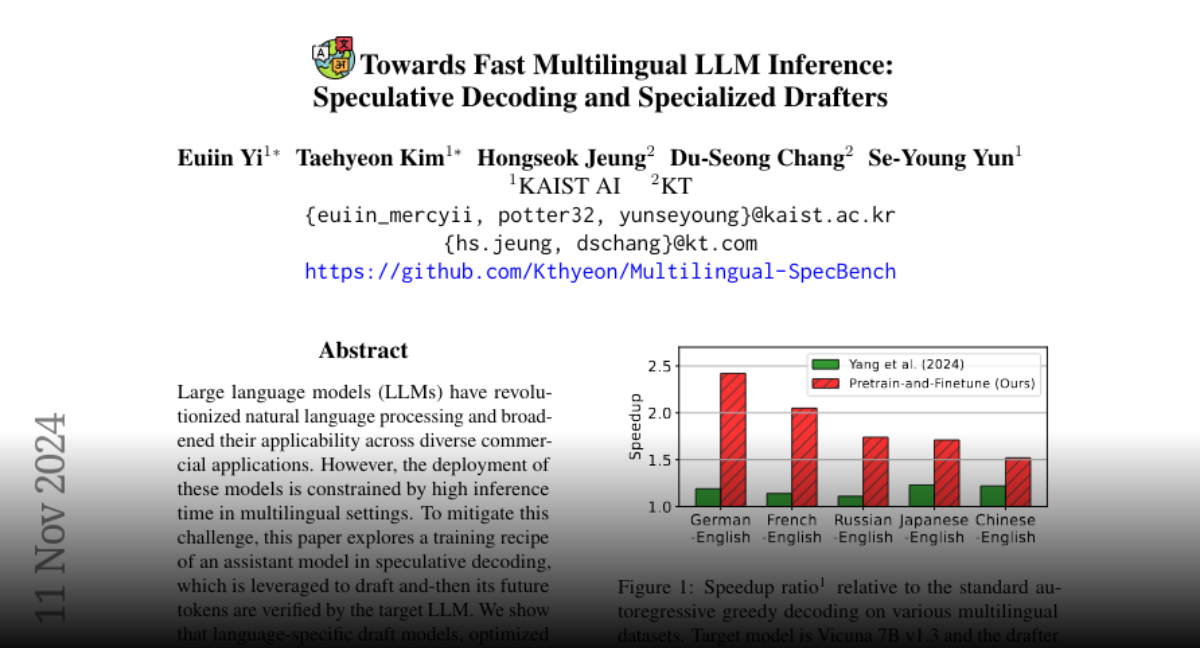
Paper page - Towards Fast Multilingual LLM Inference: Speculative ...

Paper page - SpecVLM: Fast Speculative Decoding in Vision-Language Models

Paper page - Accelerating Speculative Decoding with Block Diffusion ...
Advertisement Space (300x250)
PSD paper — Parallel speculative decoding for diffusion LLMs — What ...
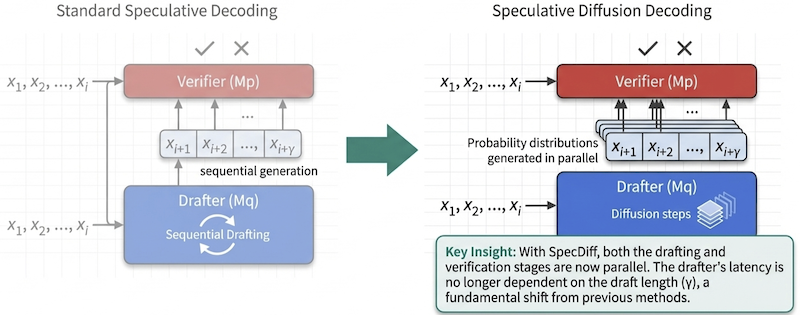
Massively Speeding up LLM inference with Speculative Diffusion Decoding ...
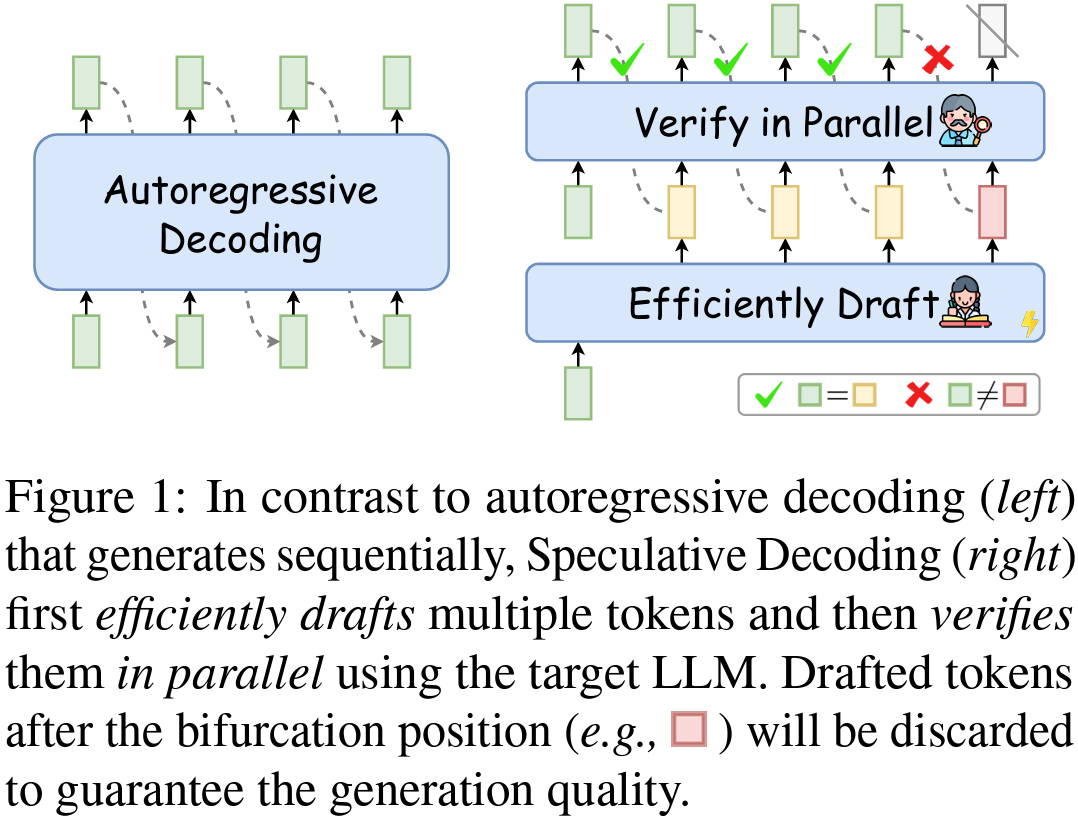
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...

Paper page - Speculative Ensemble: Fast Large Language Model Ensemble ...
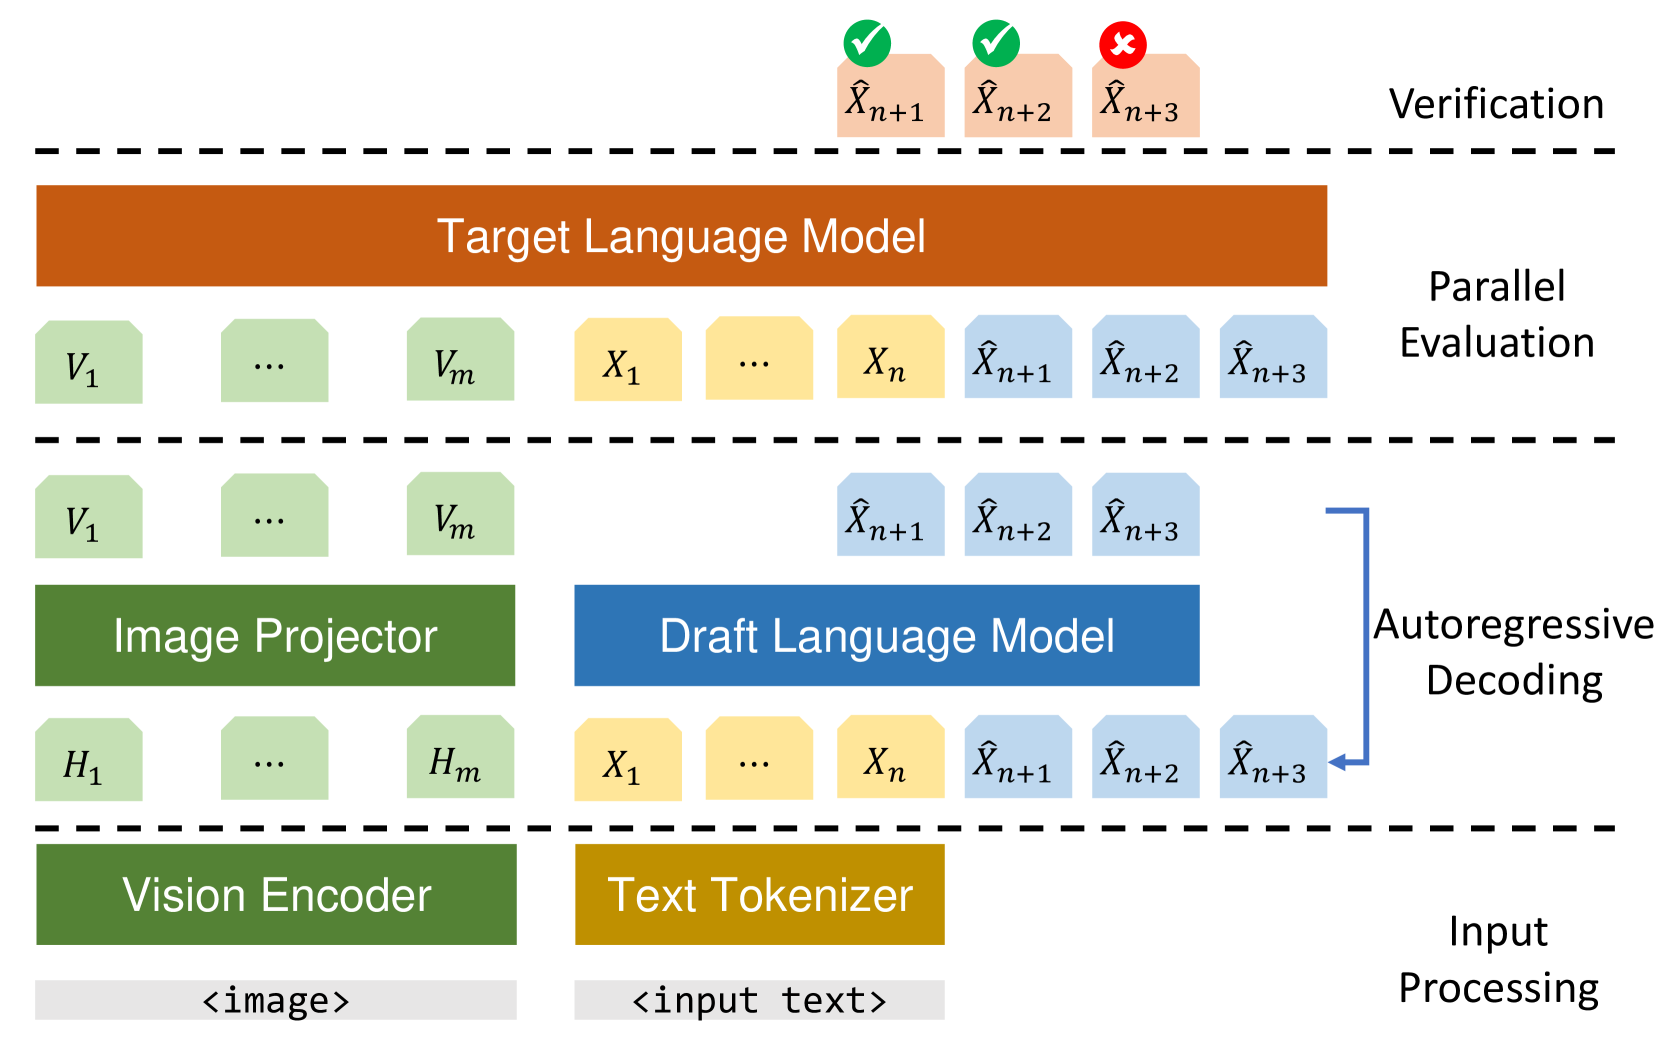
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...
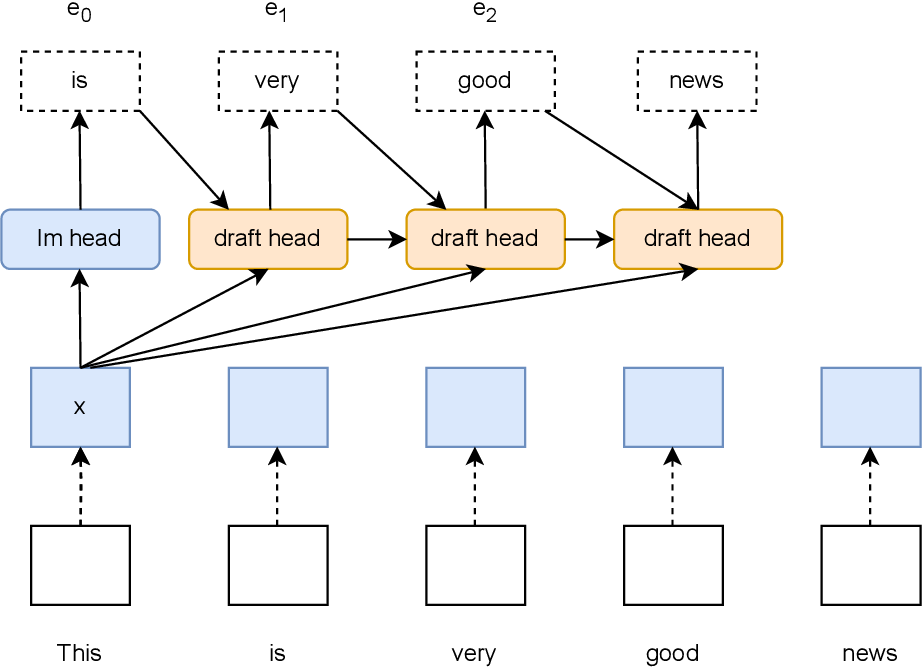
Figure 1 from Recurrent Drafter for Fast Speculative Decoding in Large ...

Paper page - Fast-dLLM: Training-free Acceleration of Diffusion LLM by ...

Paper page - Speculative Diffusion Decoding: Accelerating Language ...

DFlash: Block Diffusion for Flash Speculative Decoding | Papers with Code
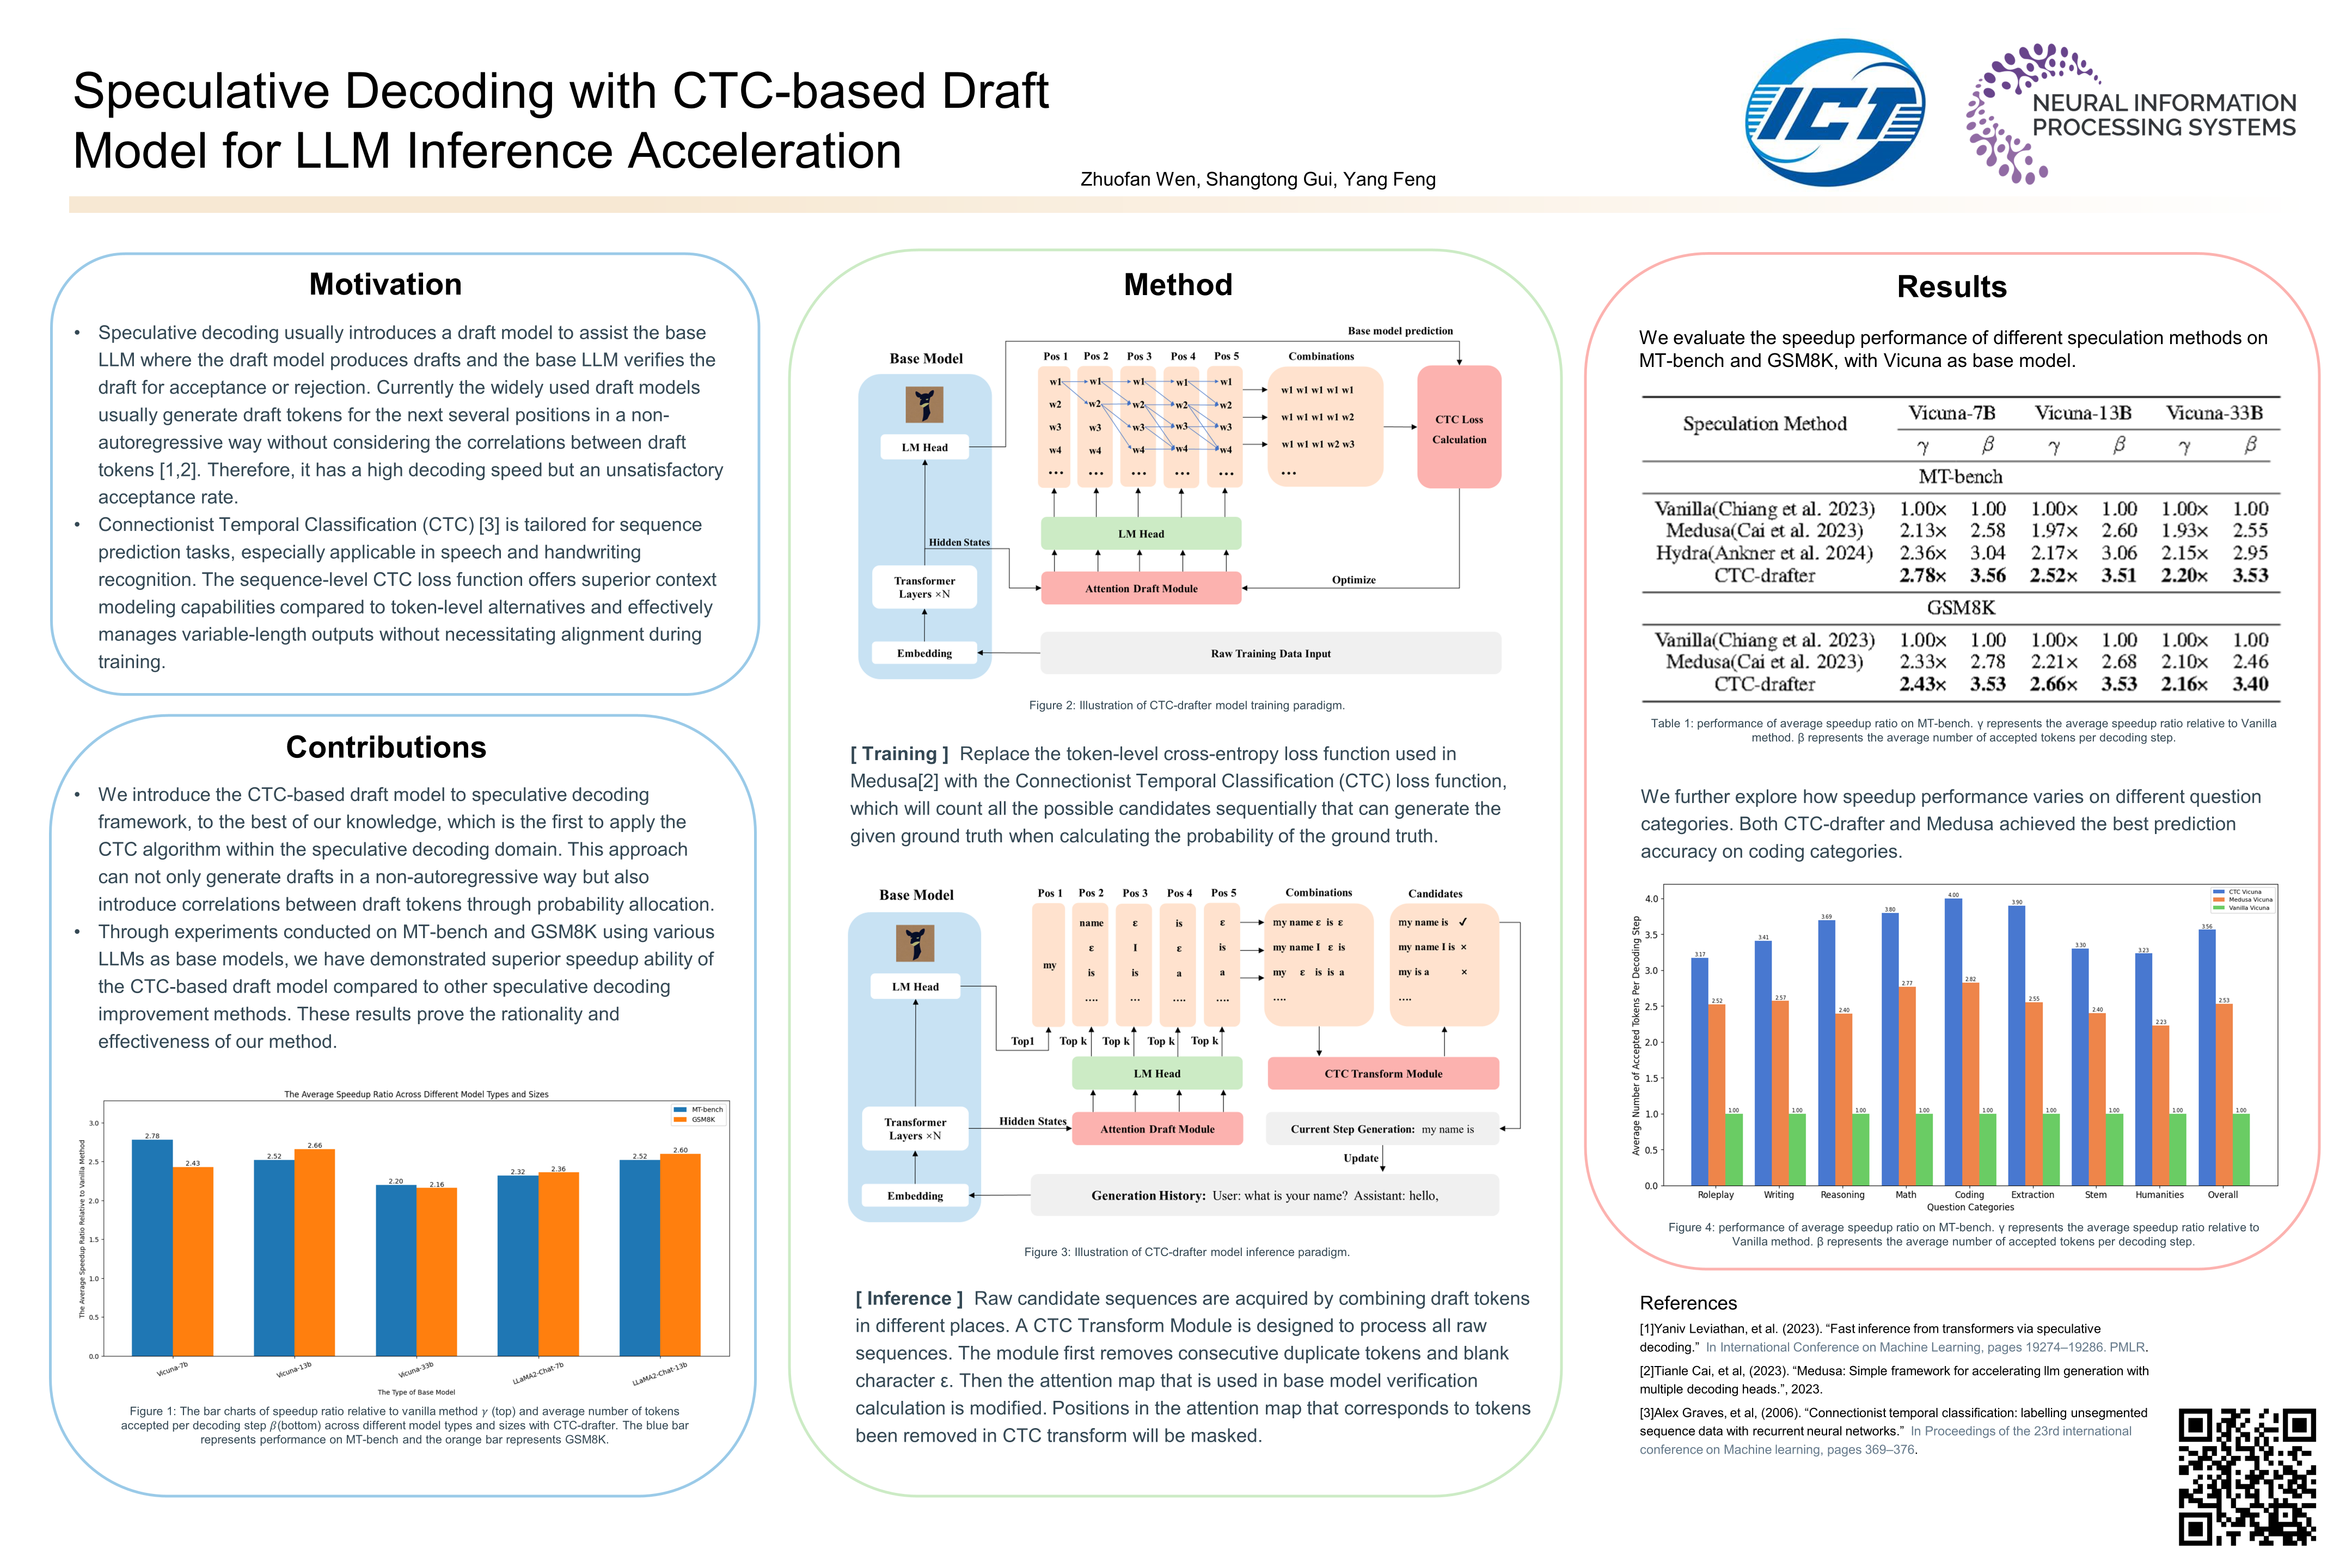
NeurIPS Poster Speculative Decoding with CTC-based Draft Model for LLM ...
Advertisement Space (336x280)

Paper page - Fast Diffusion Model

Paper page - FASER: Fine-Grained Phase Management for Speculative ...
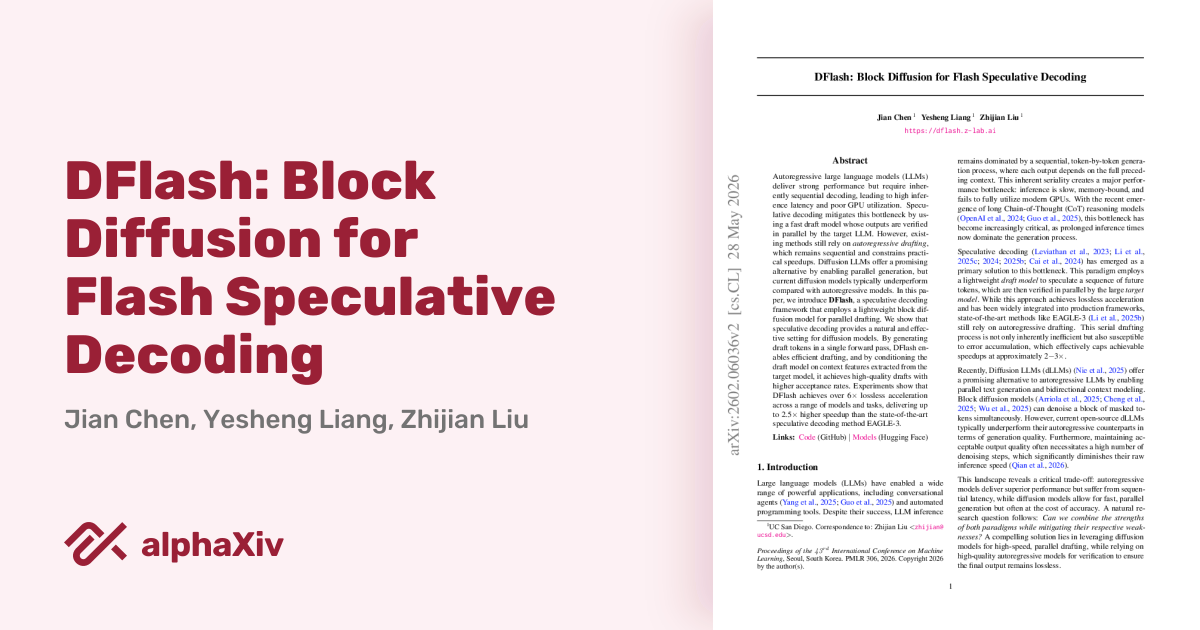
DFlash: Block Diffusion for Flash Speculative Decoding | alphaXiv

Paper page - Accelerating Speculative Decoding using Dynamic ...

Self Speculative Decoding for Diffusion Large Language Models | AI ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...

Paper page - Online Speculative Decoding

Paper page - Self-Speculative Decoding for LLM-based ASR with CTC ...

This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
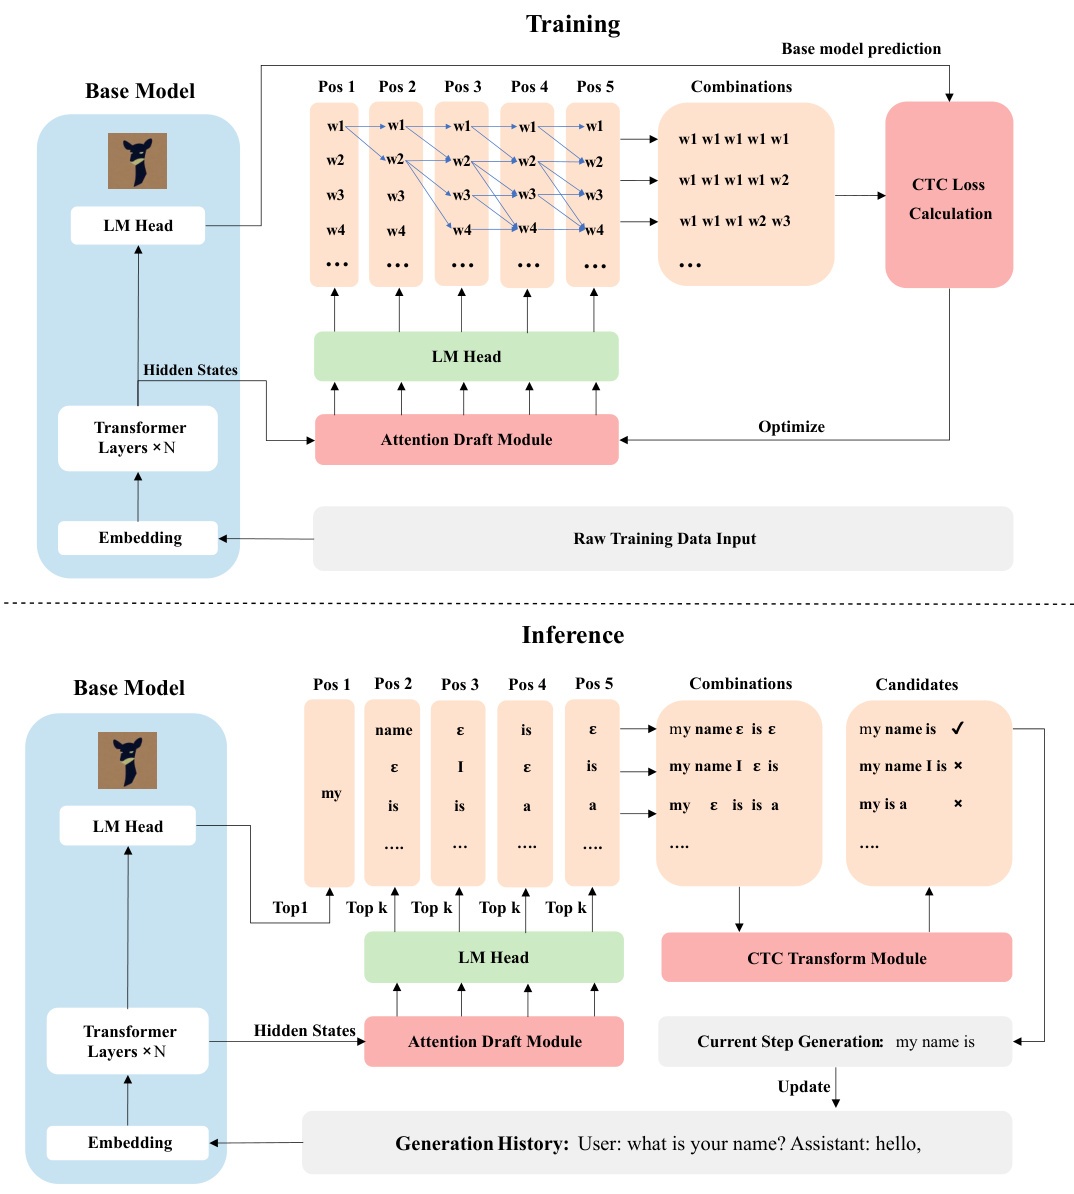
Speculative Decoding with CTC-based Draft Model for LLM Inference ...
Advertisement Space (336x280)

Paper page - Boosting Lossless Speculative Decoding via Feature ...

Paper page - Parallel Speculative Decoding with Adaptive Draft Length
Paper page - Recursive Speculative Decoding: Accelerating LLM Inference ...
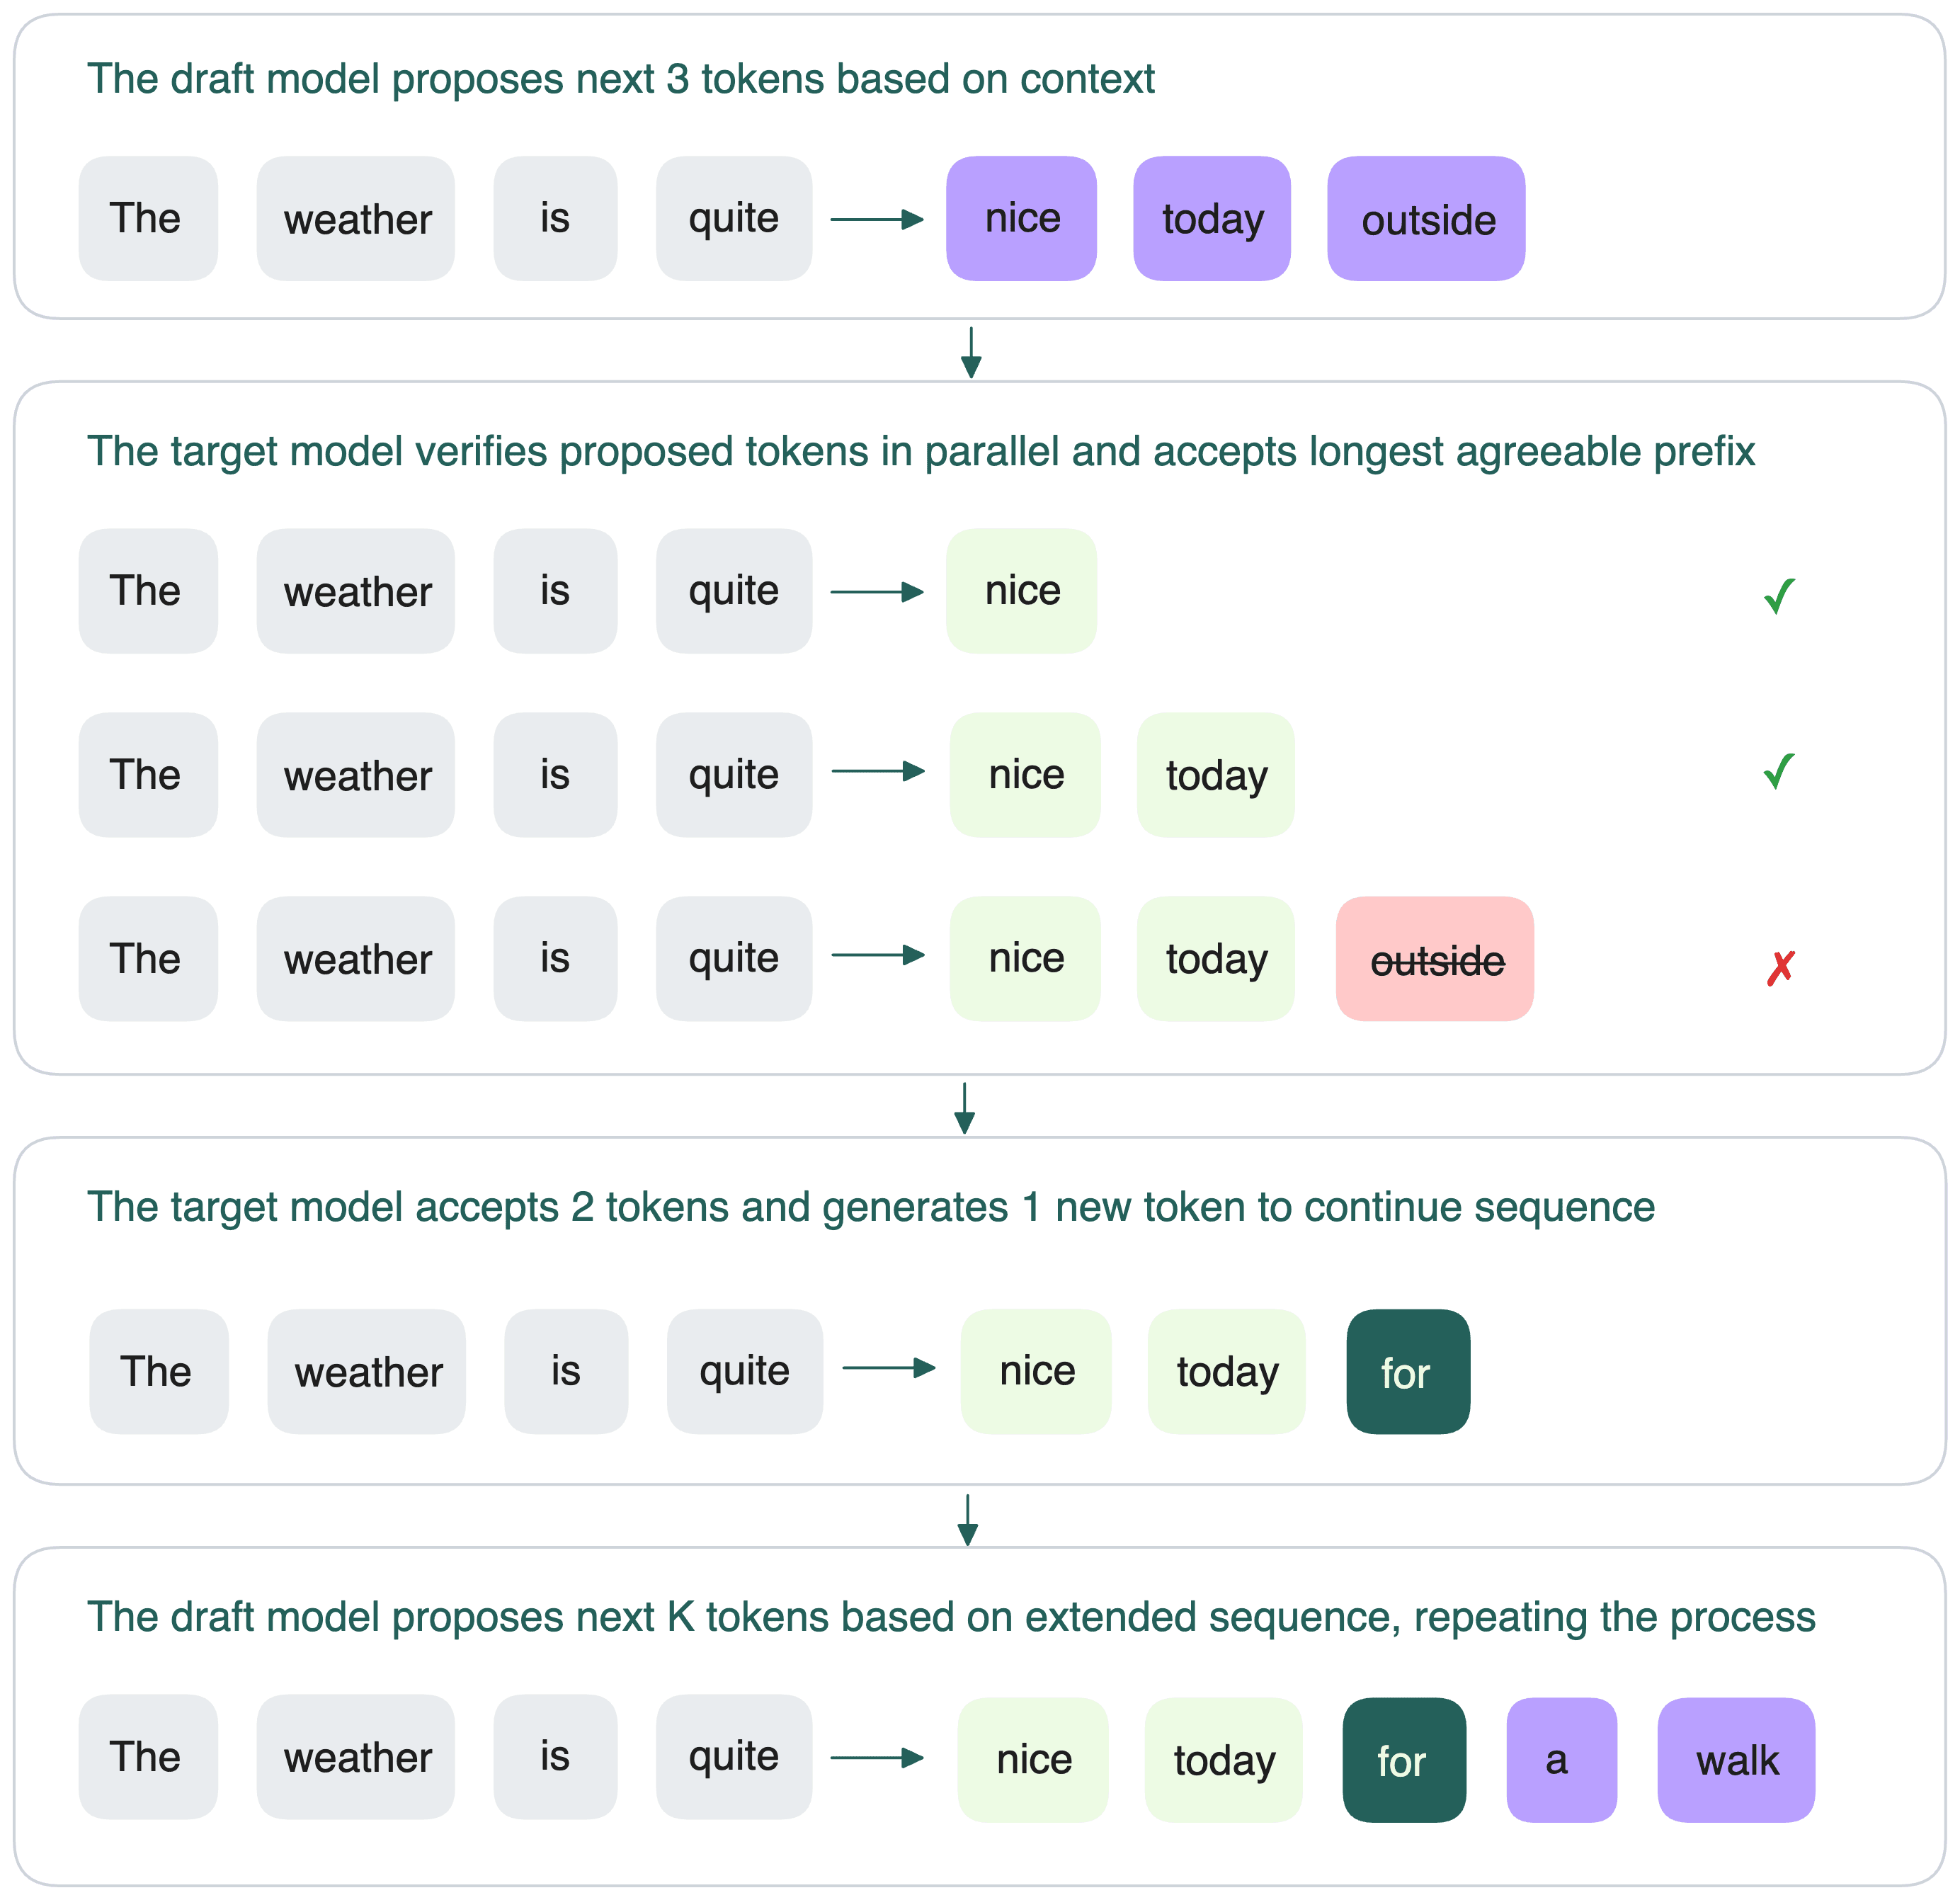
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Paper page - Fast-Decoding Diffusion Language Models via Progress-Aware ...
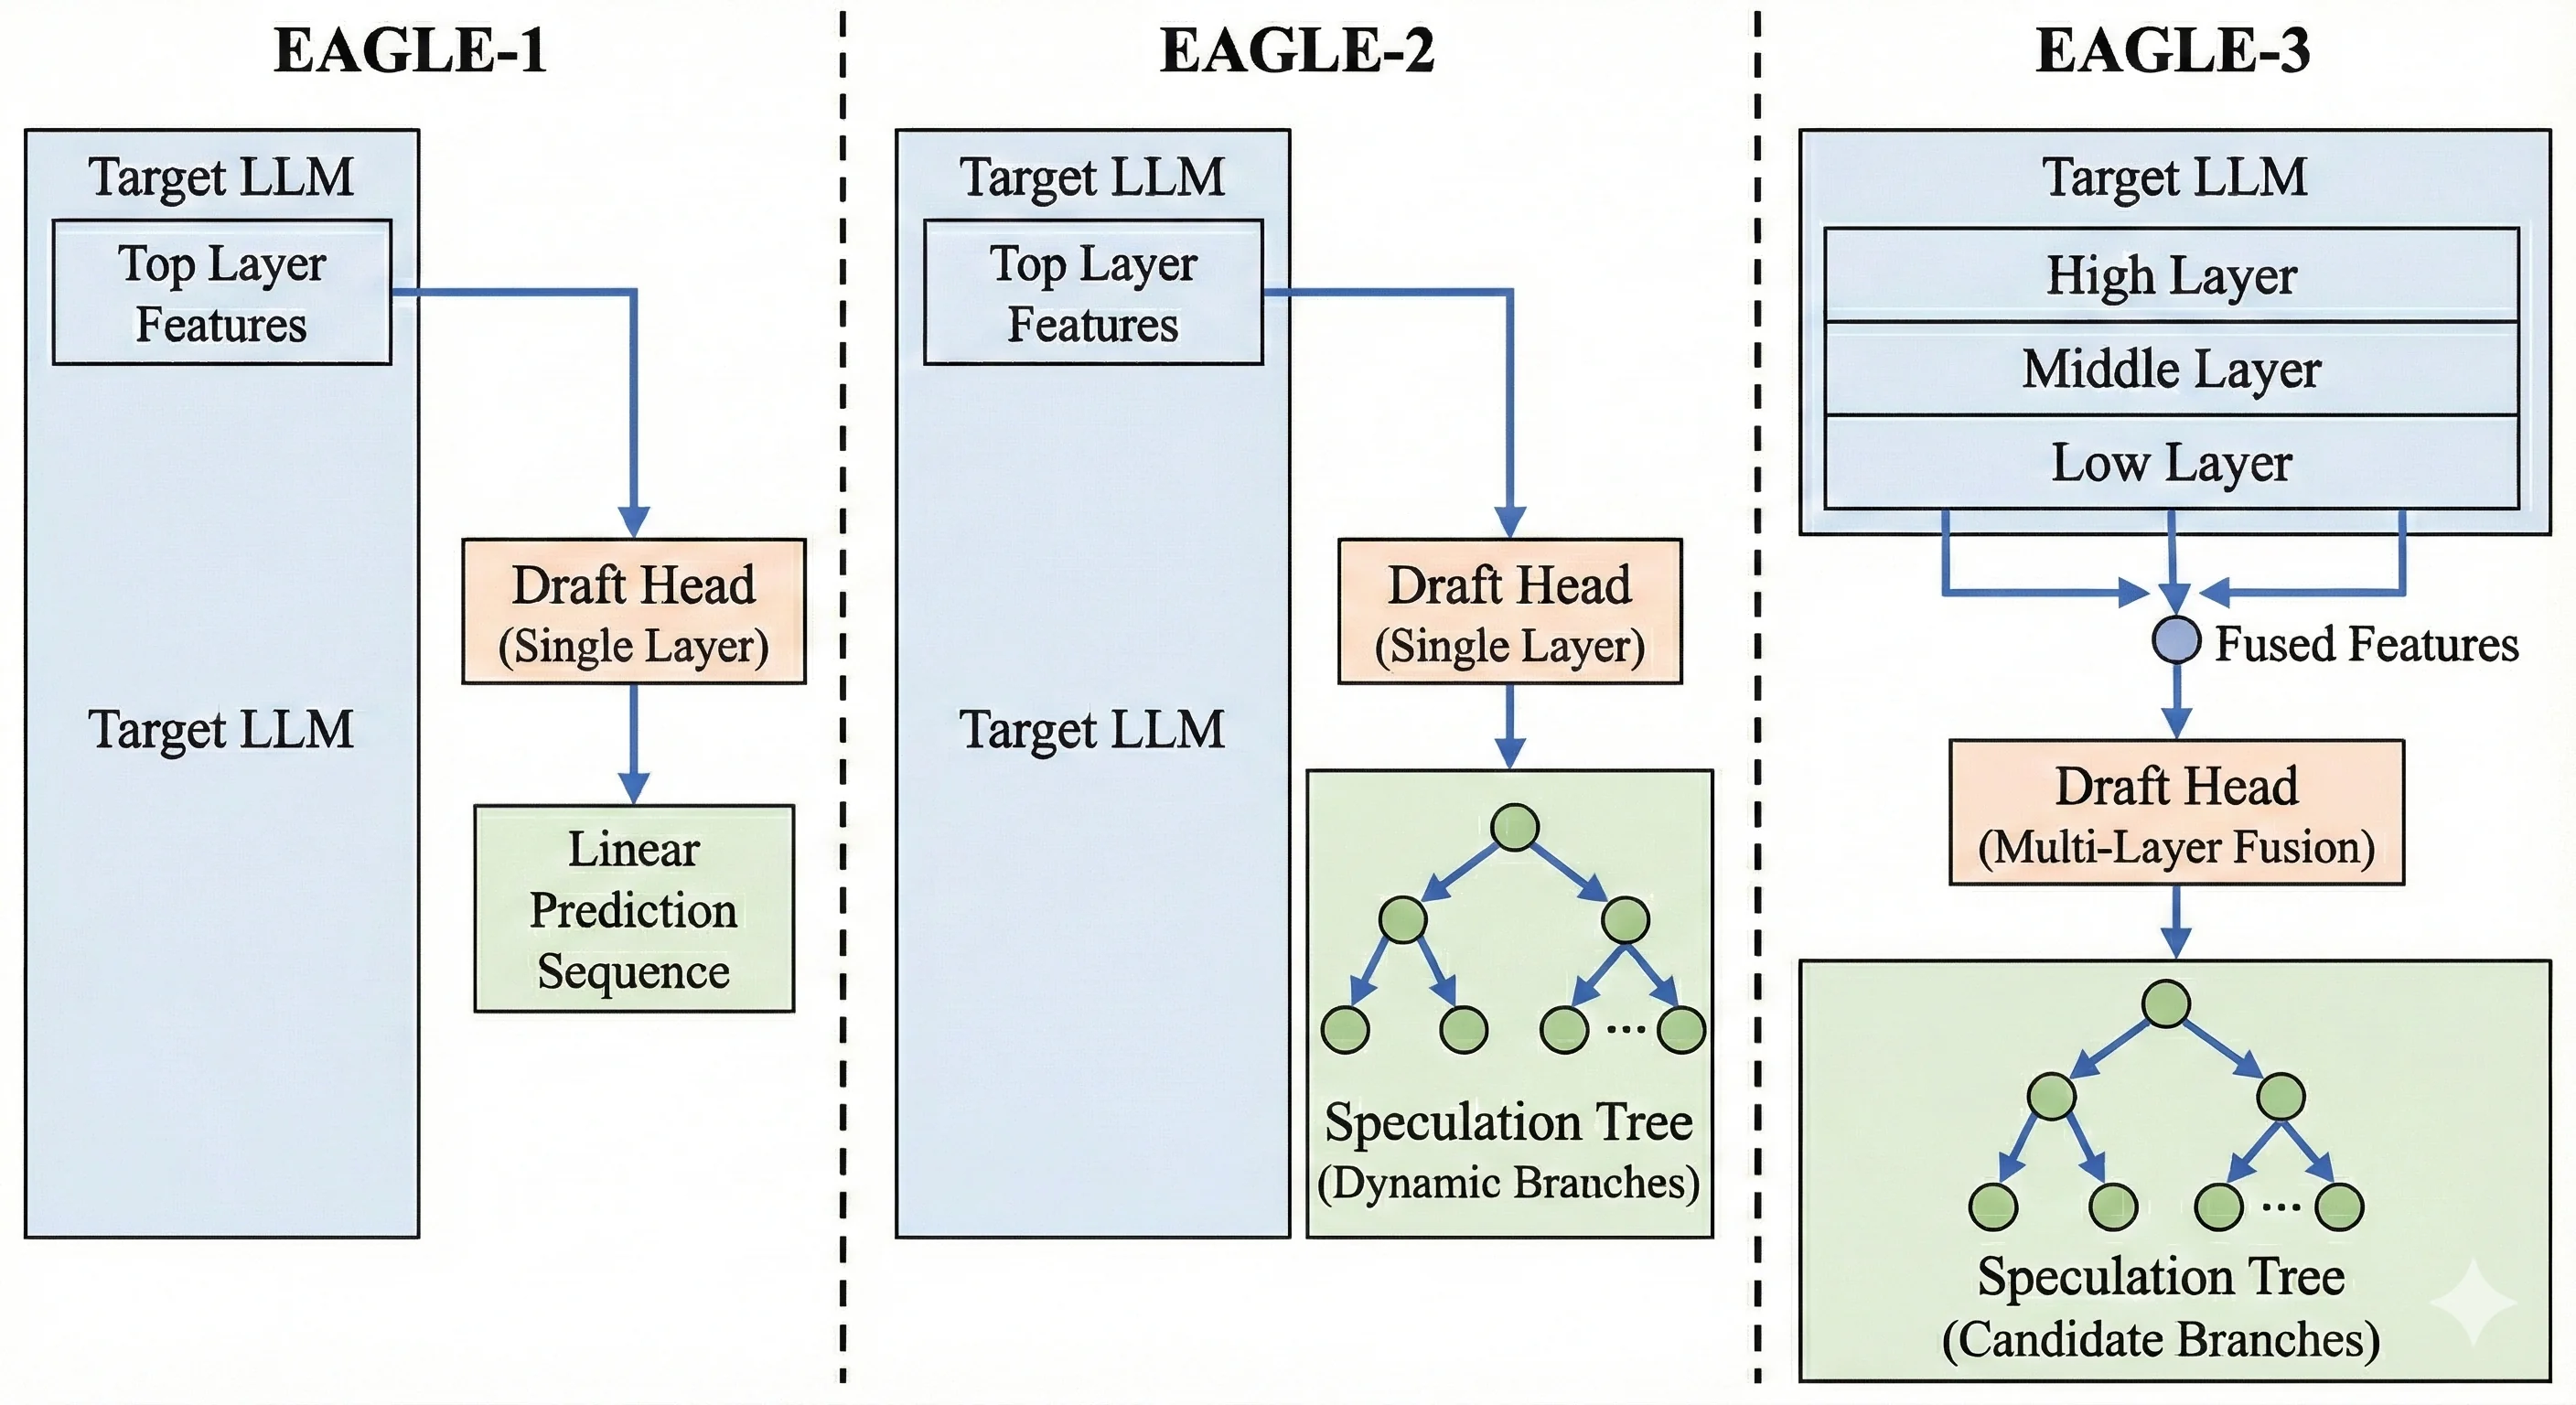
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...