
Data Parallel Deployment Vllm

Data Parallel Deployment - vLLM
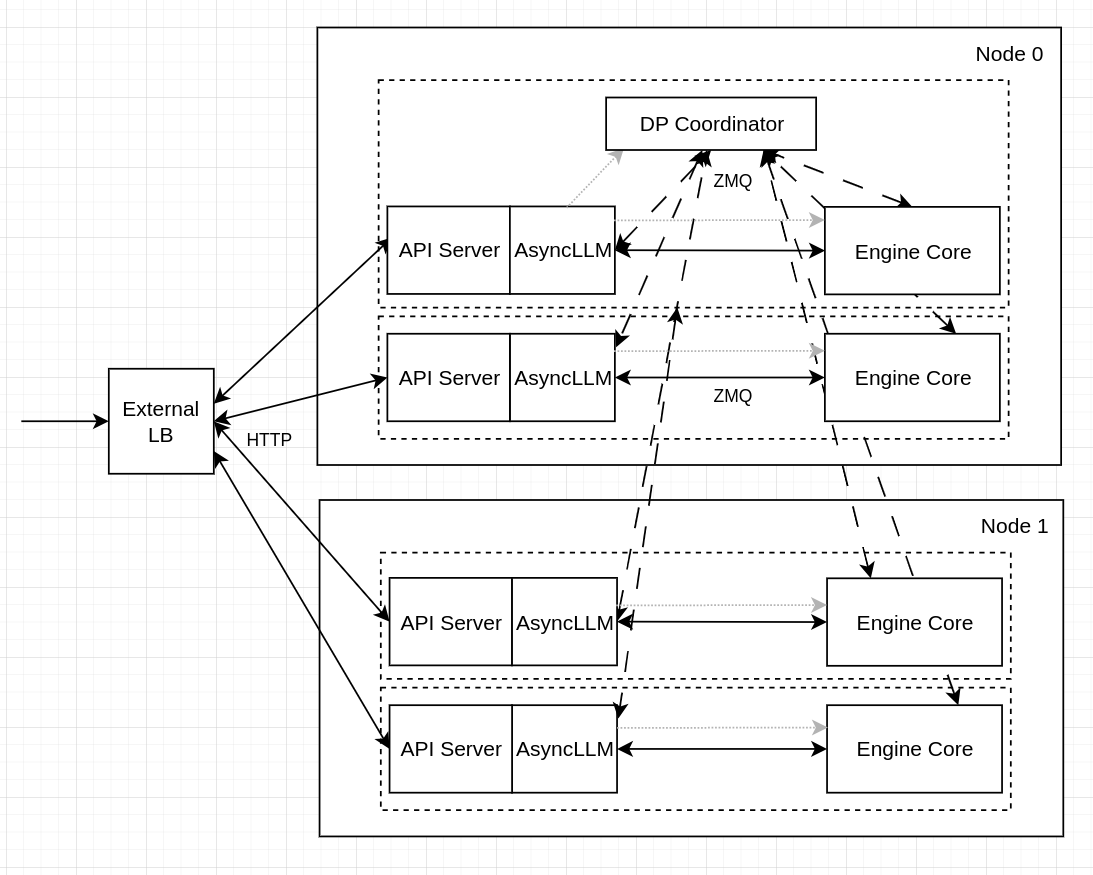
Data Parallel Deployment - vLLM
vLLM Production Deployment 2026: Multi-GPU Tensor Parallel + FP8 Docker ...

Context Parallel - vLLM Ascend - vLLM 文件
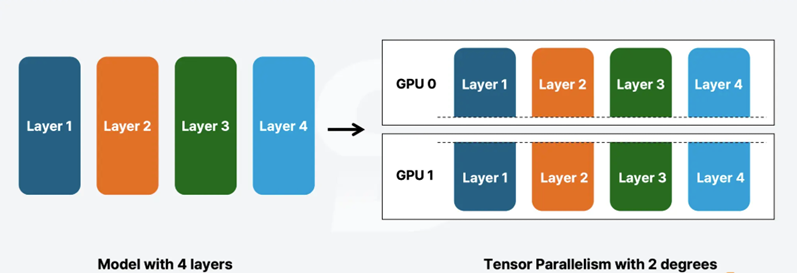
Run your own AI at scale: Tuning vLLM for Superb LLM Deployment (Vol. 1 ...
Data Parallel Workers | vllm-project/router | DeepWiki

Zero Data Parallel at Nick Mendoza blog
Hexon Global Guide: Streamlining LLM Model Deployment with vLLM - Hexon ...

Context Parallel - vLLM Ascend - vLLM 文档

Context Parallel - vLLM Ascend - vLLM 文档
Advertisement Space (300x250)
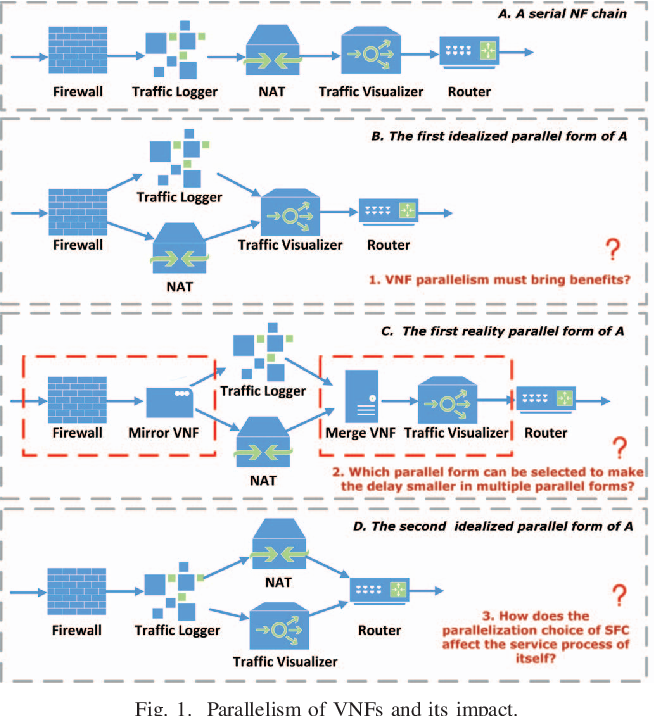
Figure 1 from Parallel Deployment of VNFs in Service Function Chain ...

Distributed and parallel deployment of the sample query from Figure 3 ...
Data parallel inference · Issue #1237 · vllm-project/vllm · GitHub
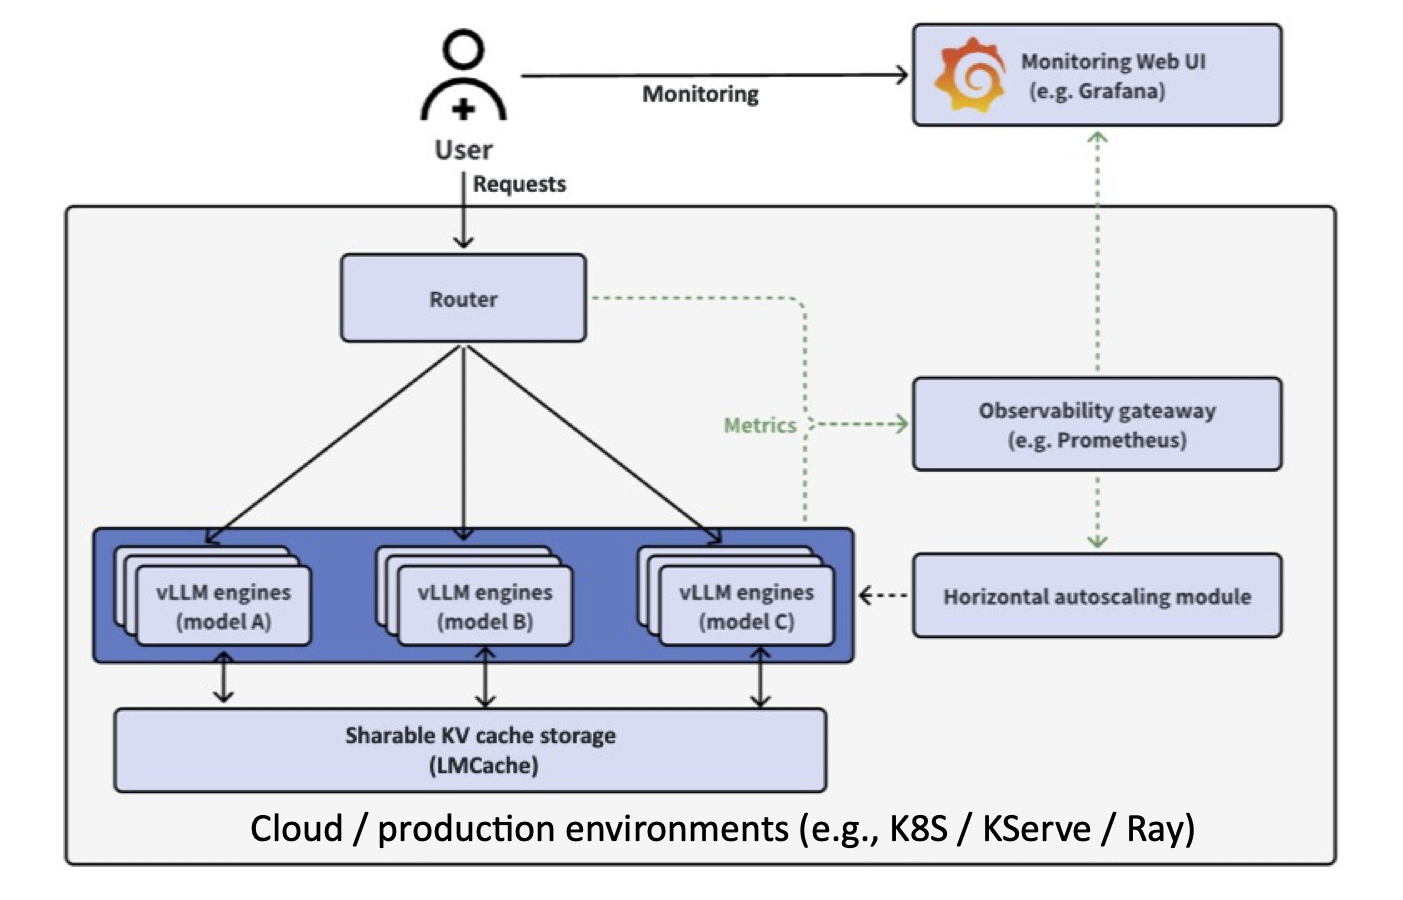
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...
vLLM for beginners: Deployment Options (PartIII) - Cloudthrill

How DDP works || Distributed Data Parallel || Quick explained - YouTube

ML Model Deployment Strategies | Towards Data Science
DT parallel deployment architecture | Download Scientific Diagram
[RFC]: Data Parallel Attention and Expert Parallel MoEs · Issue #16037 ...
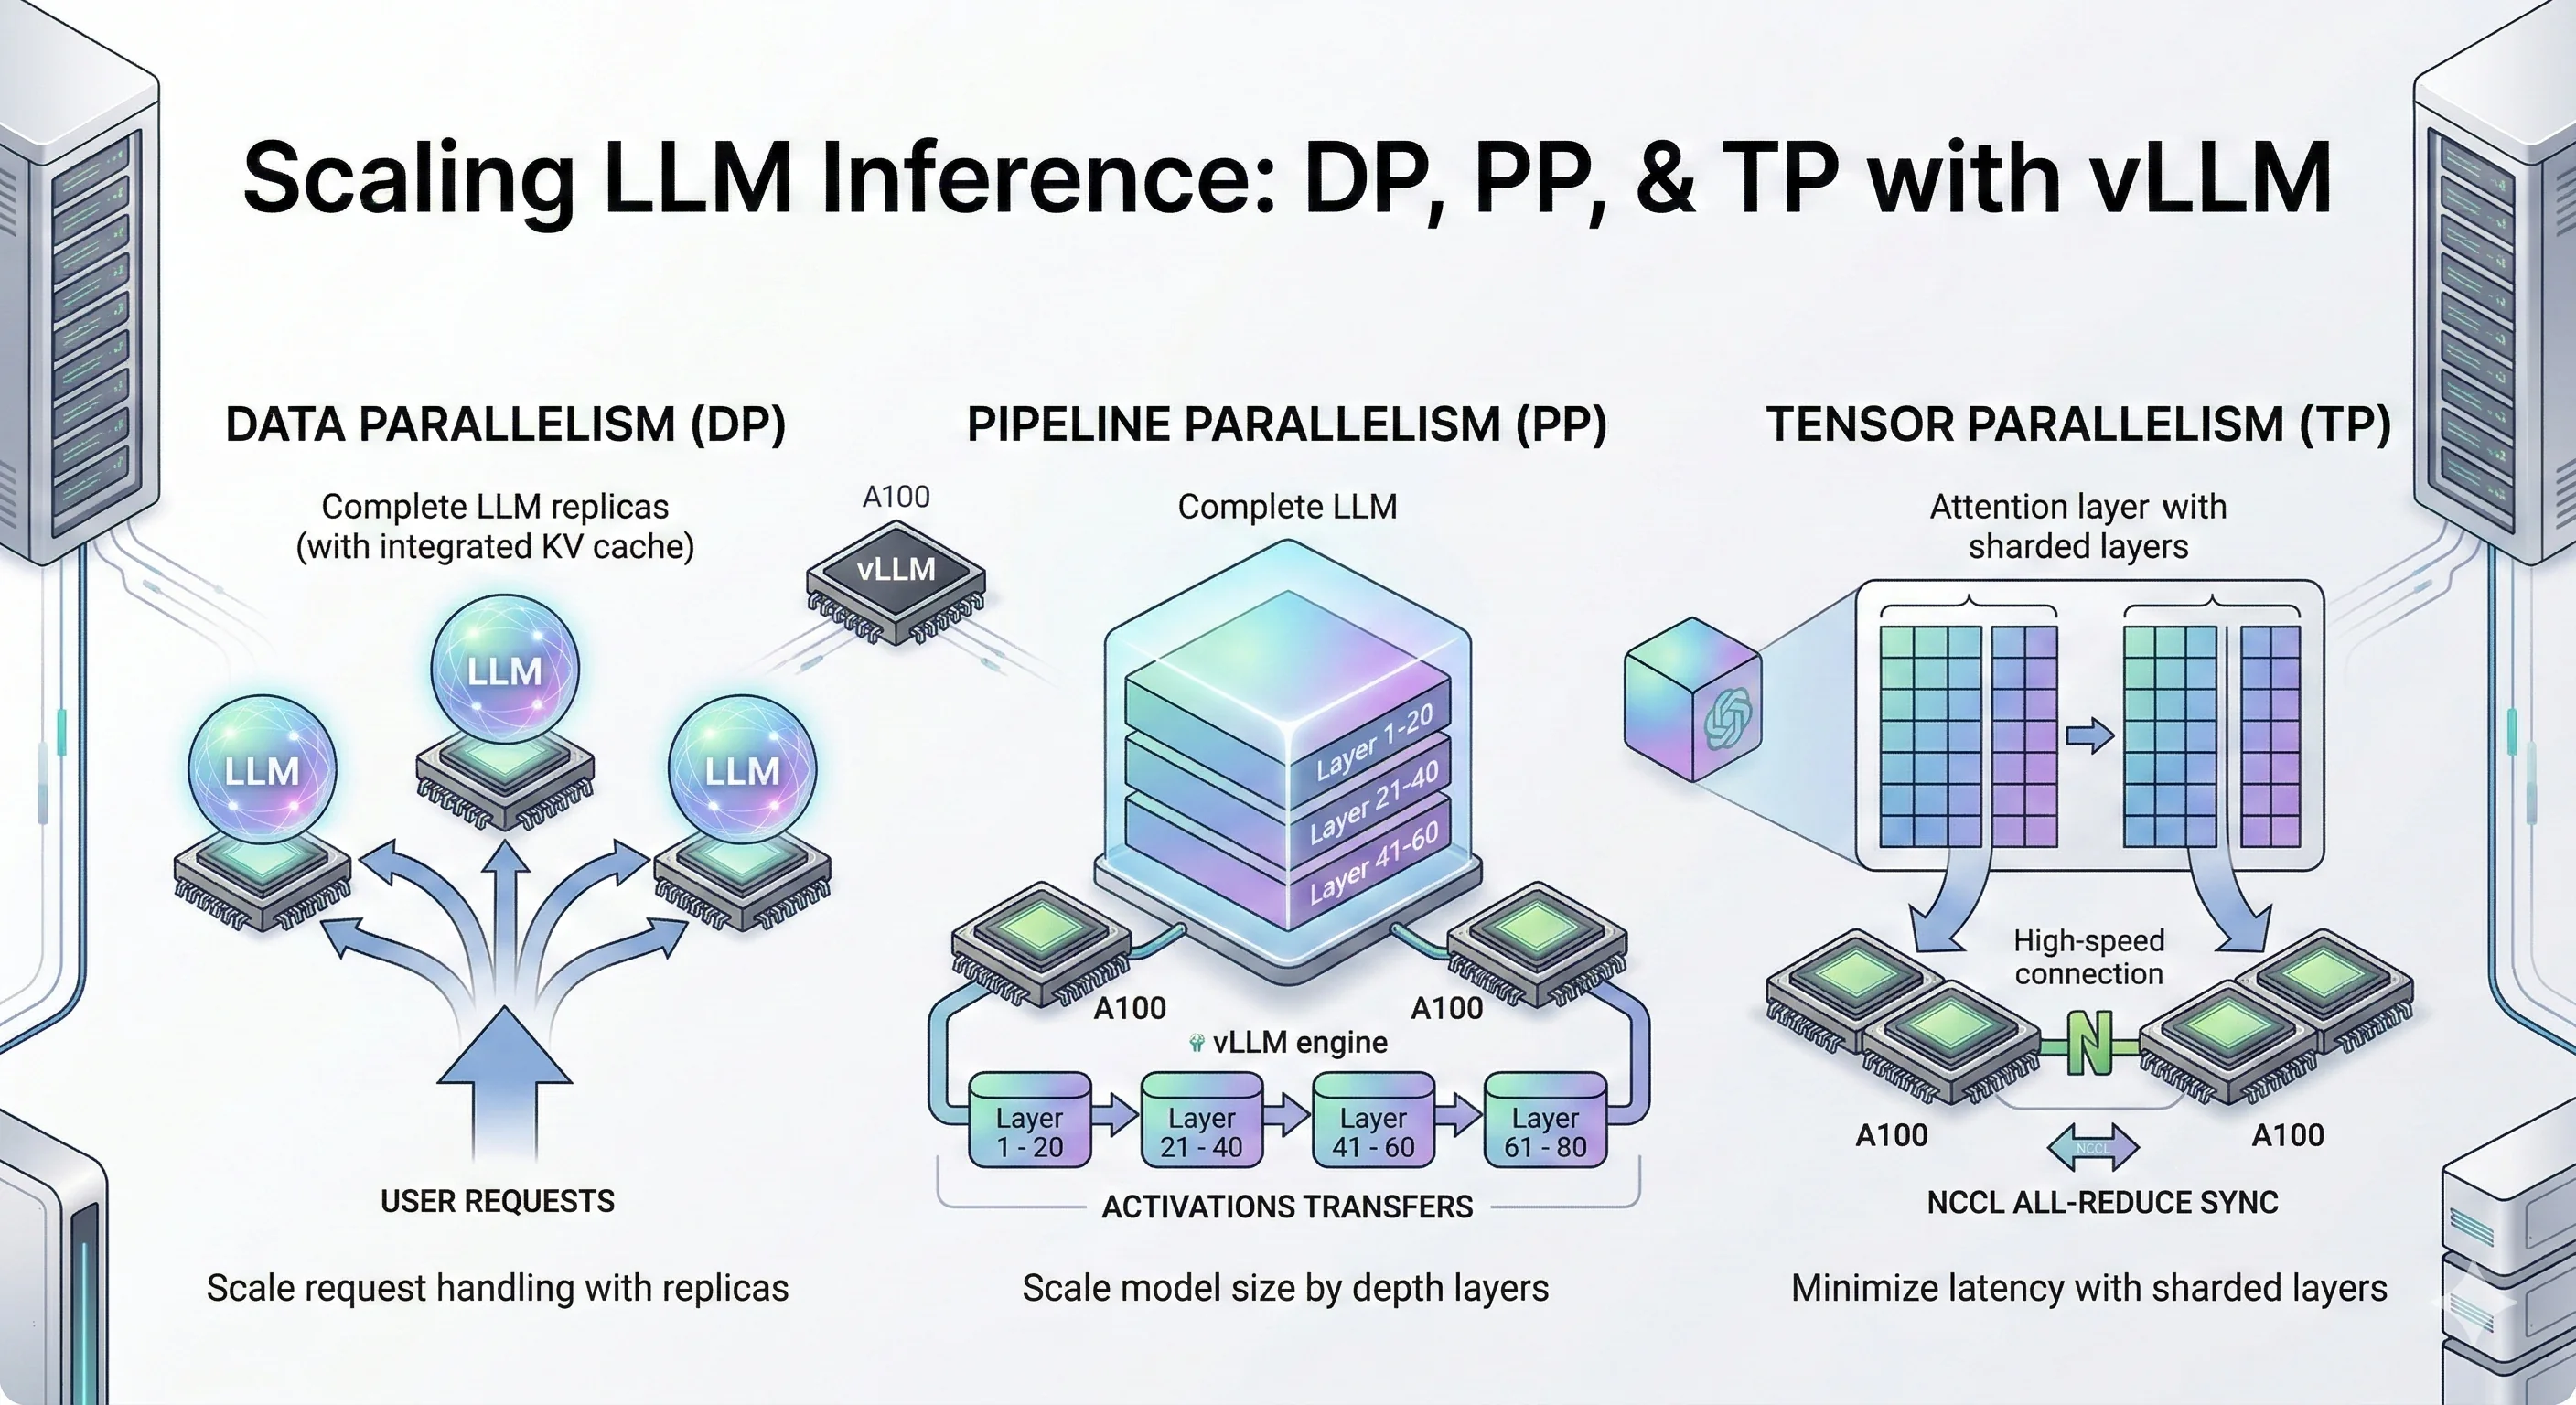
vLLM Optimization Techniques: 5 Practical Methods to Improve ...
Advertisement Space (336x280)
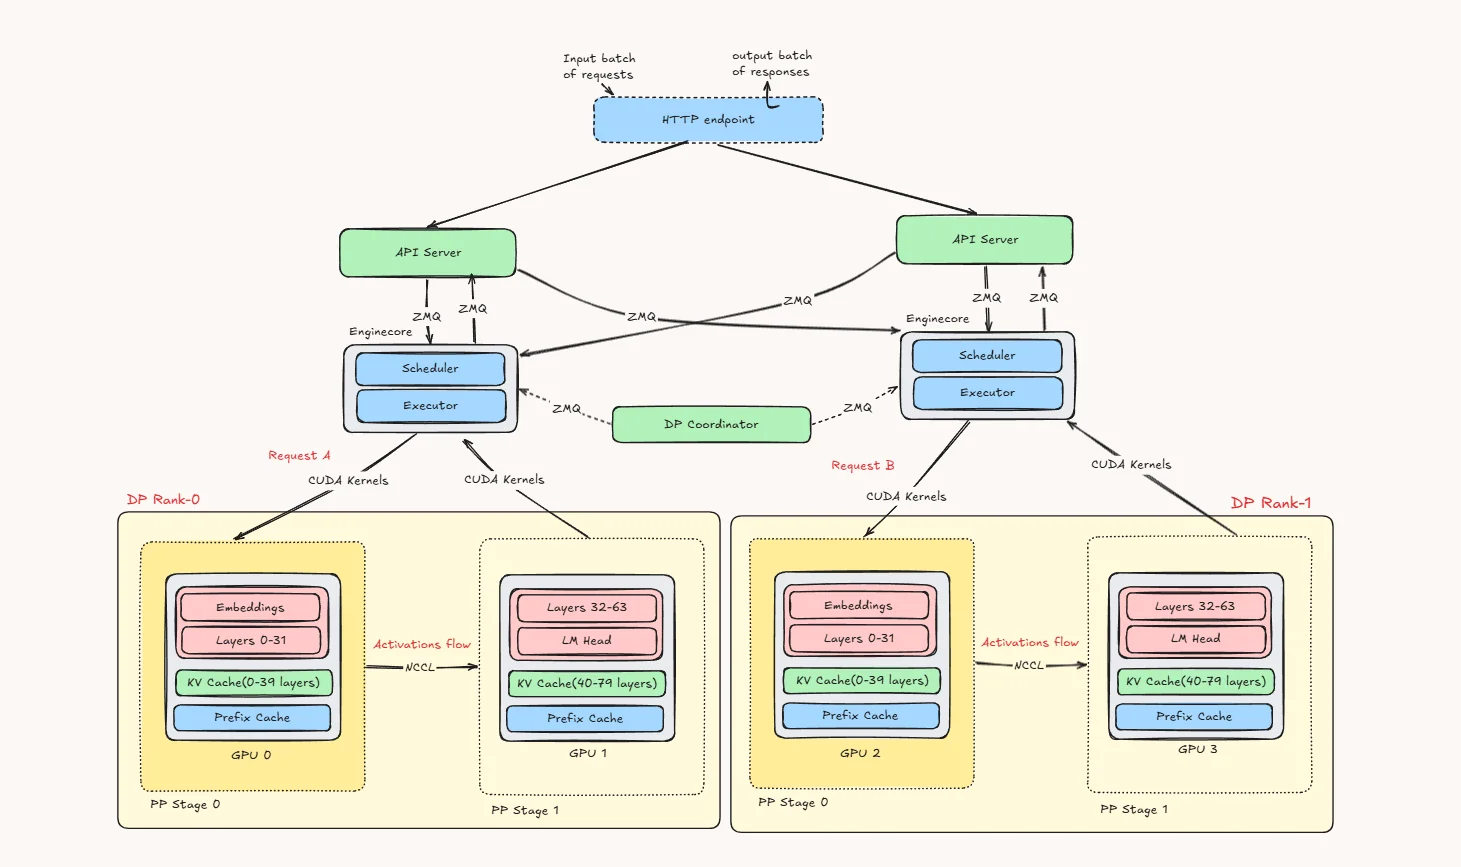
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
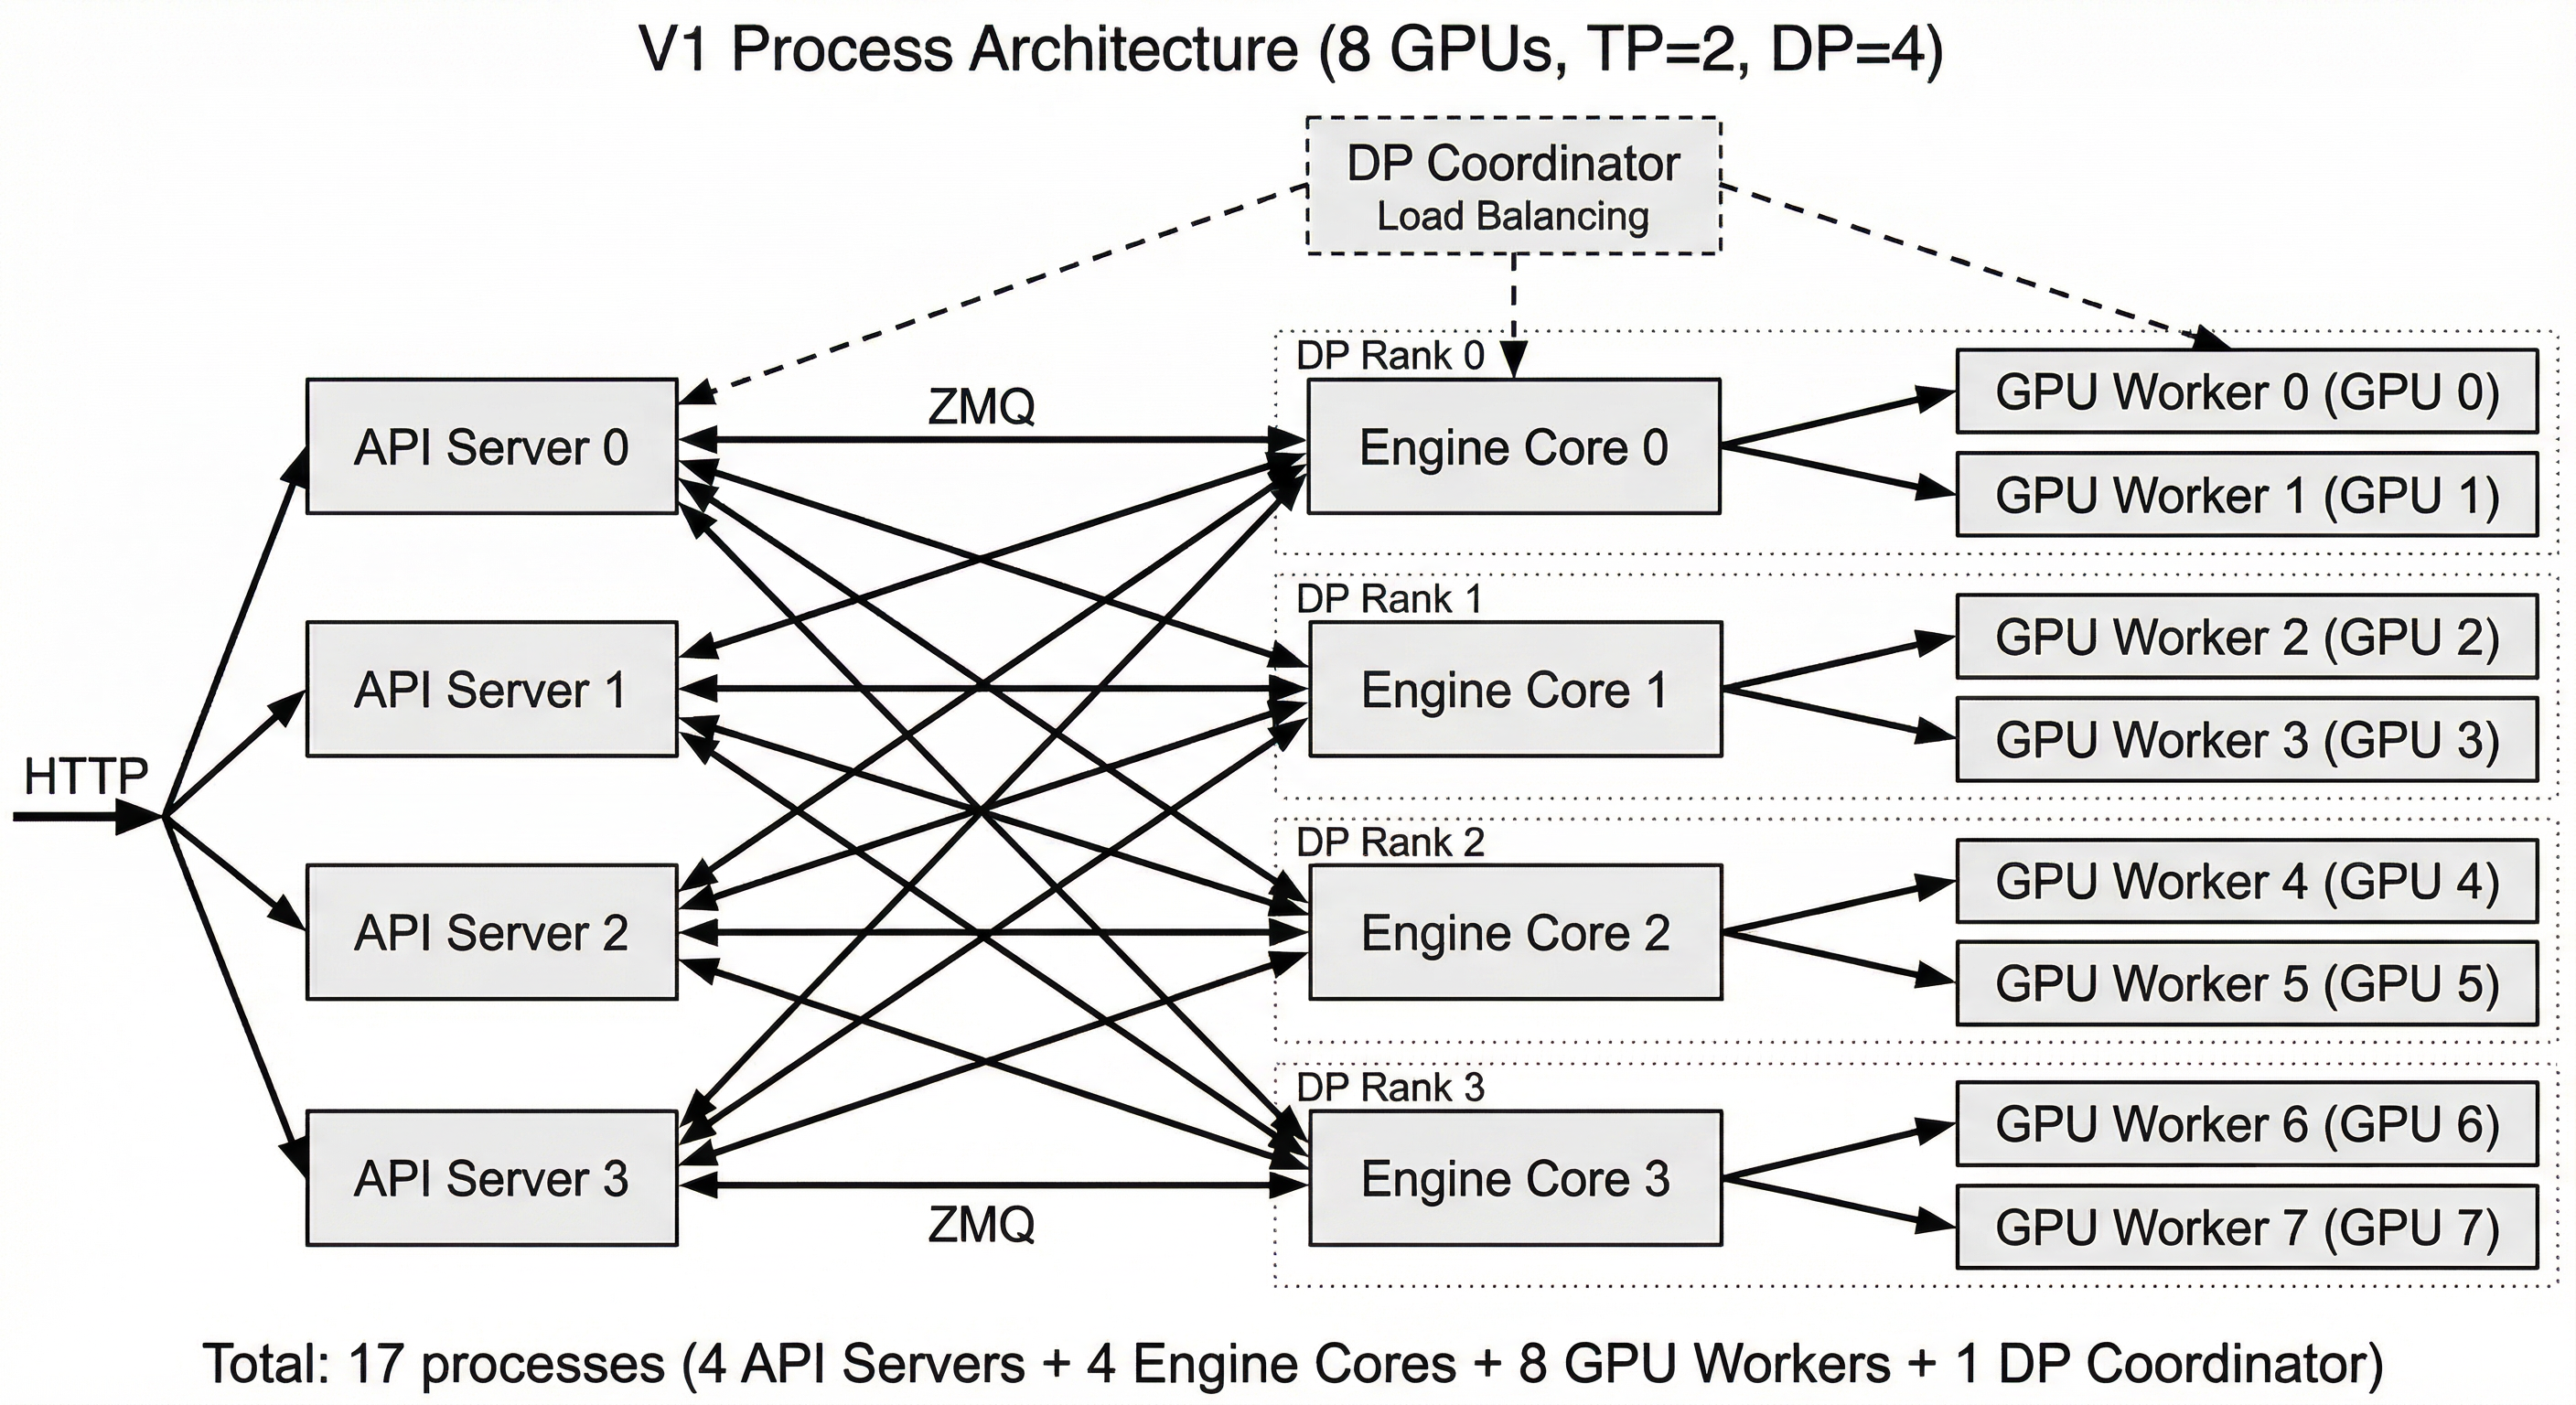
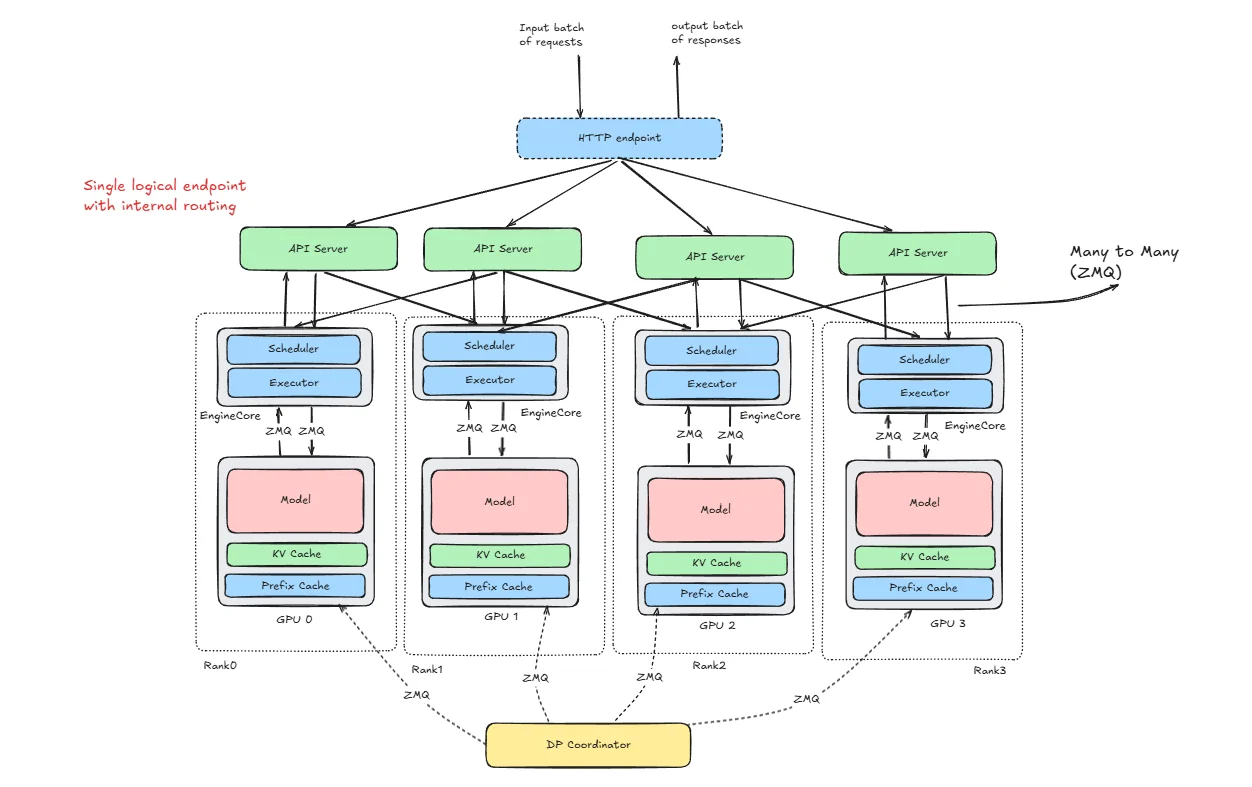
Architecture Overview - vLLM
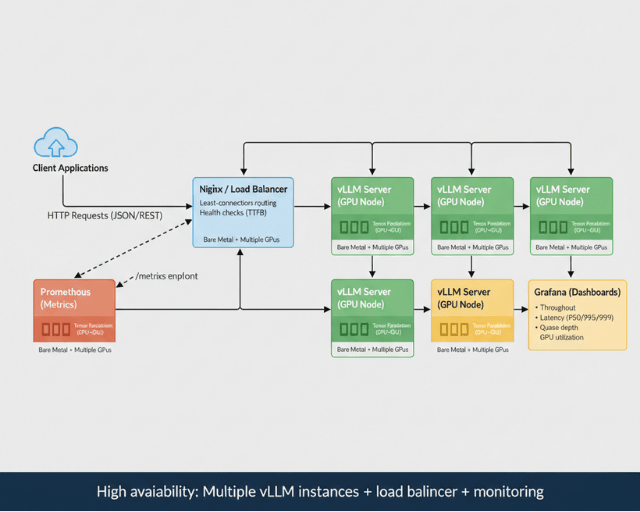
vLLM Throughput Guide - PagedAttention and Batching Tips (2026)
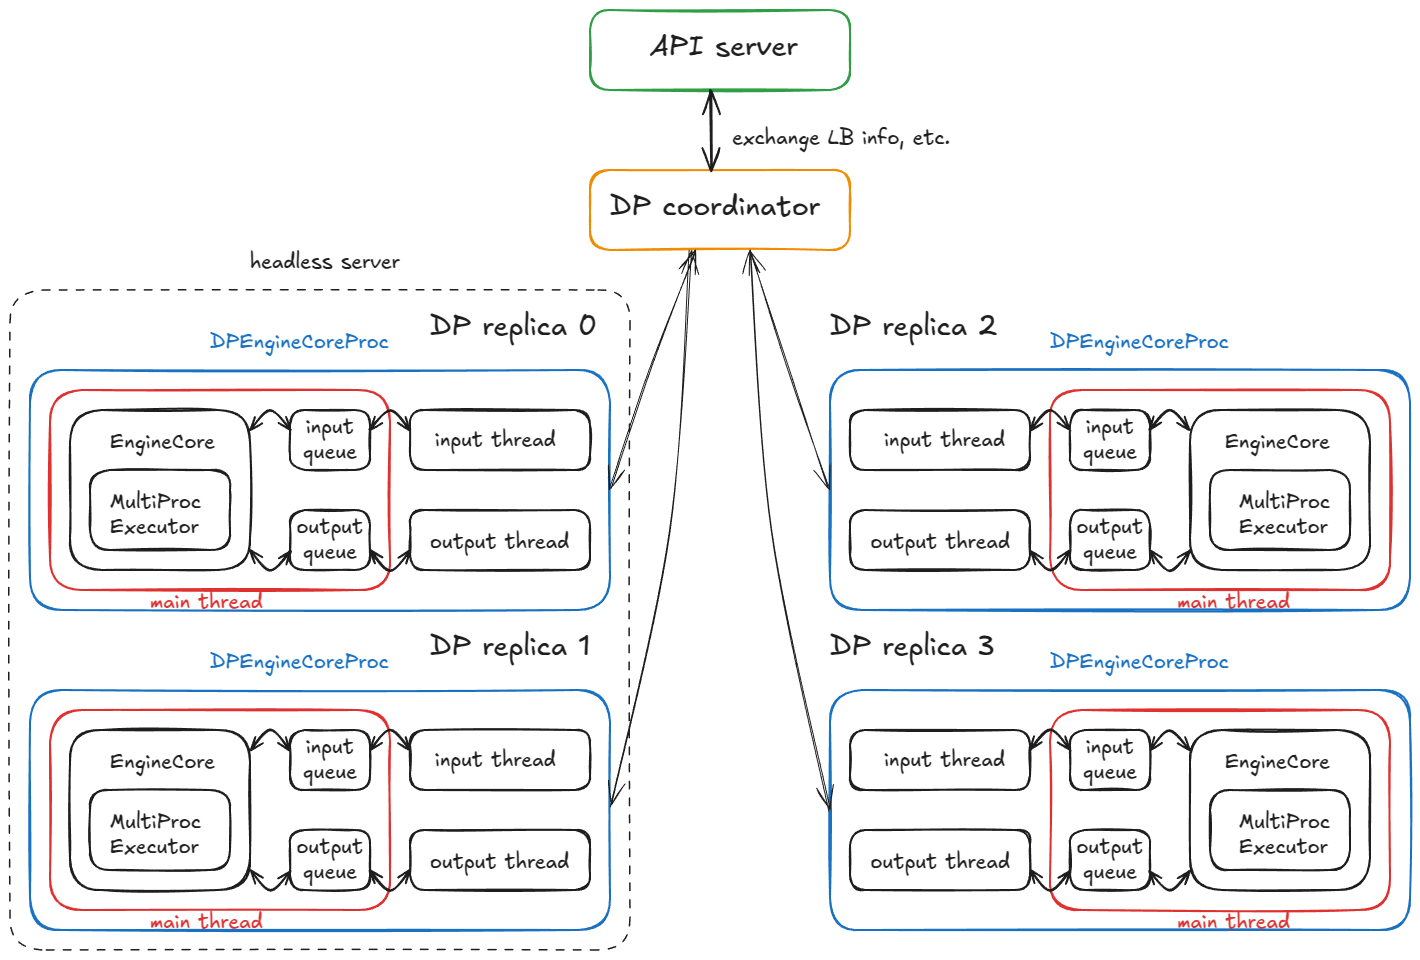
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
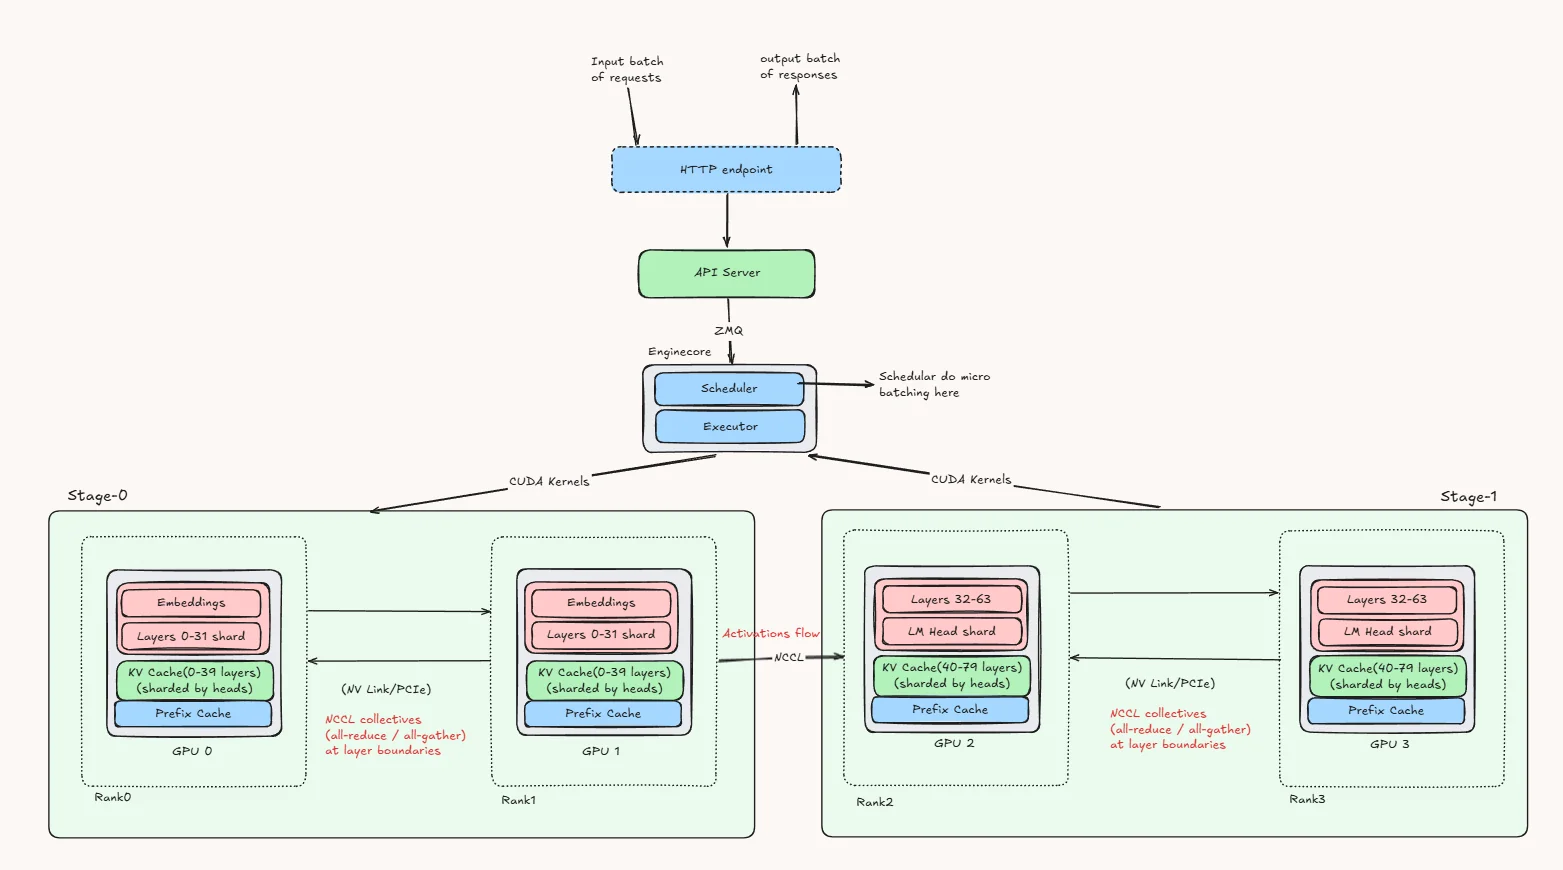
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
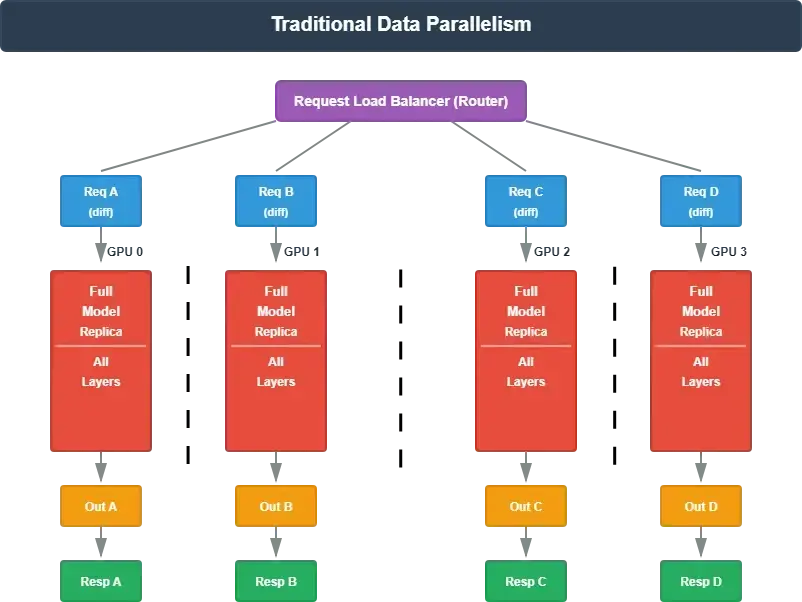
vLLM MoE 调优手册(上篇):TP、DP、PP 与 Expert Parallelism 实战指南 - 知乎
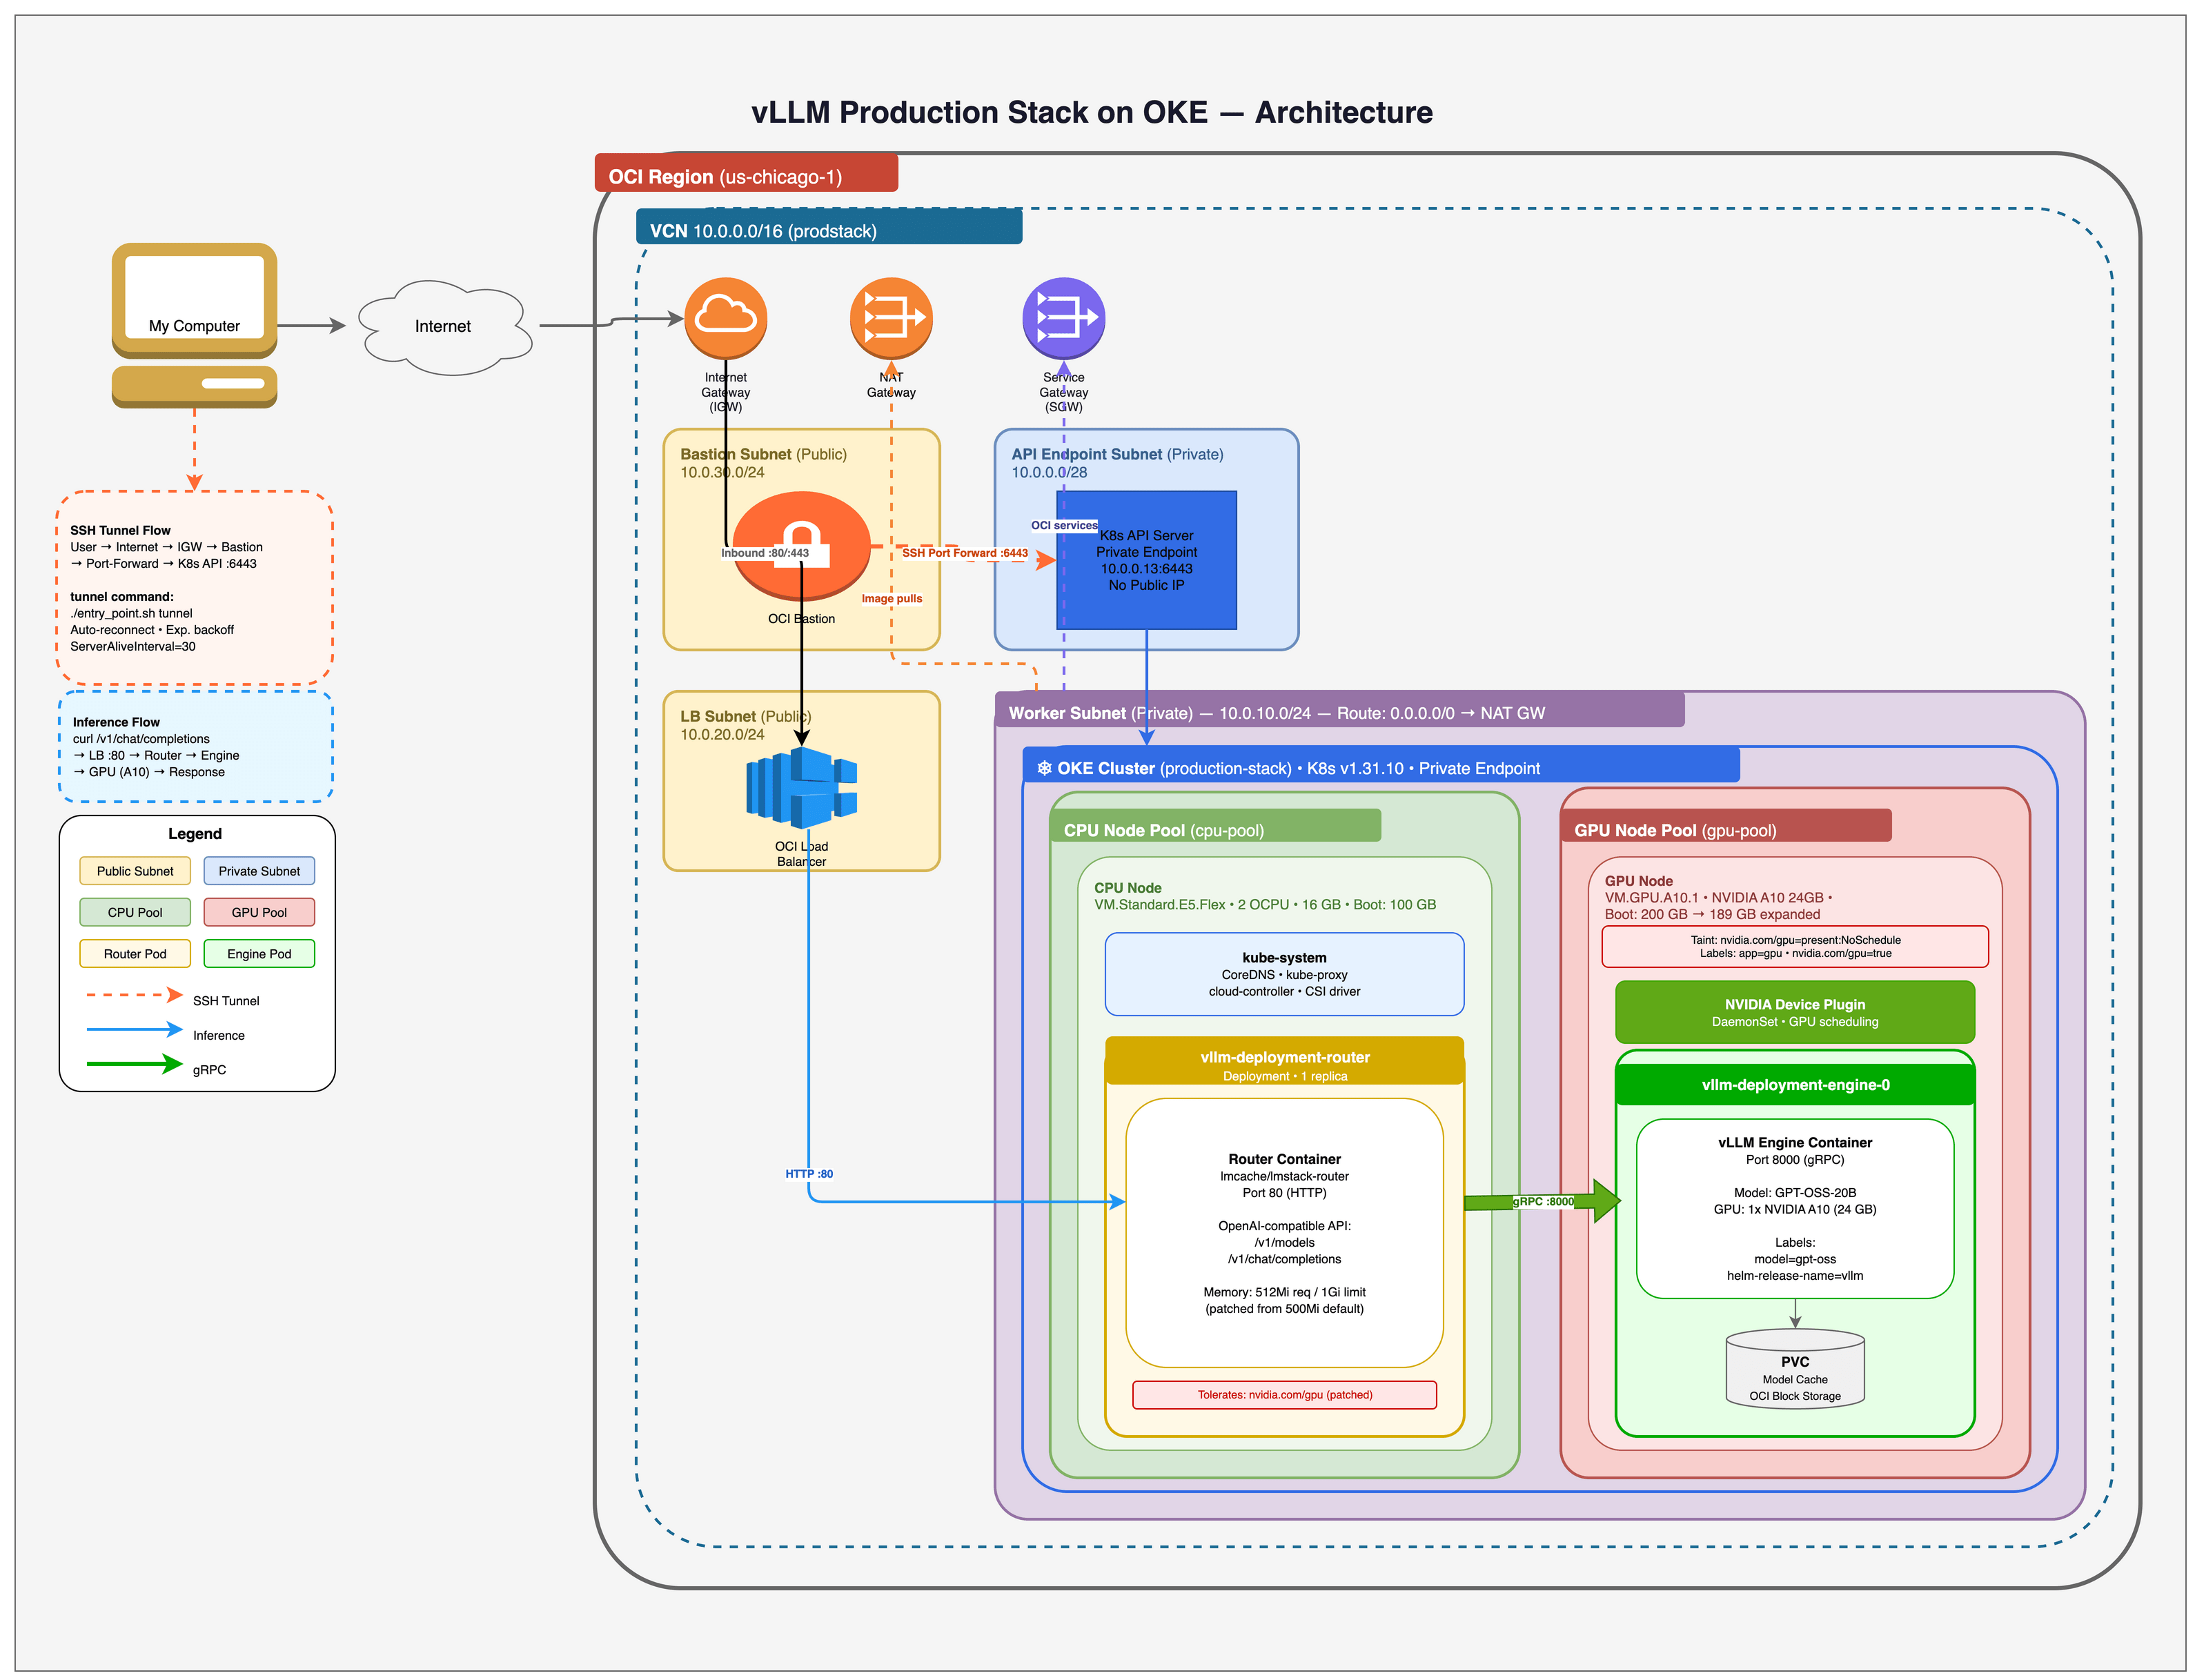
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)
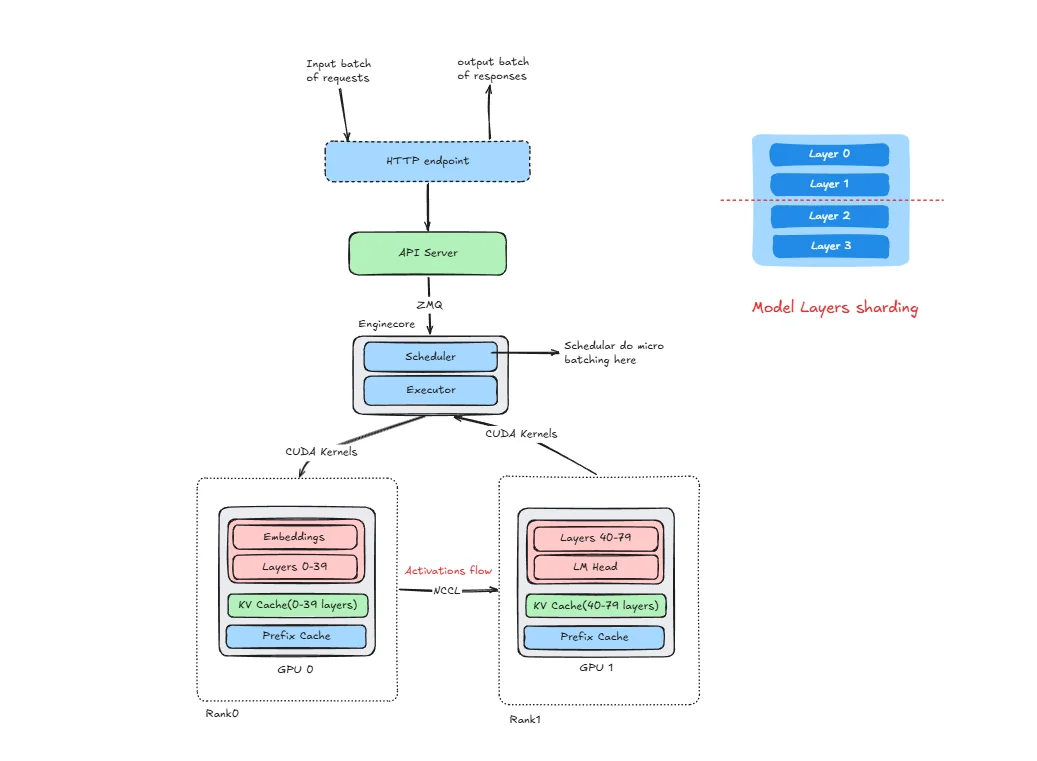
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
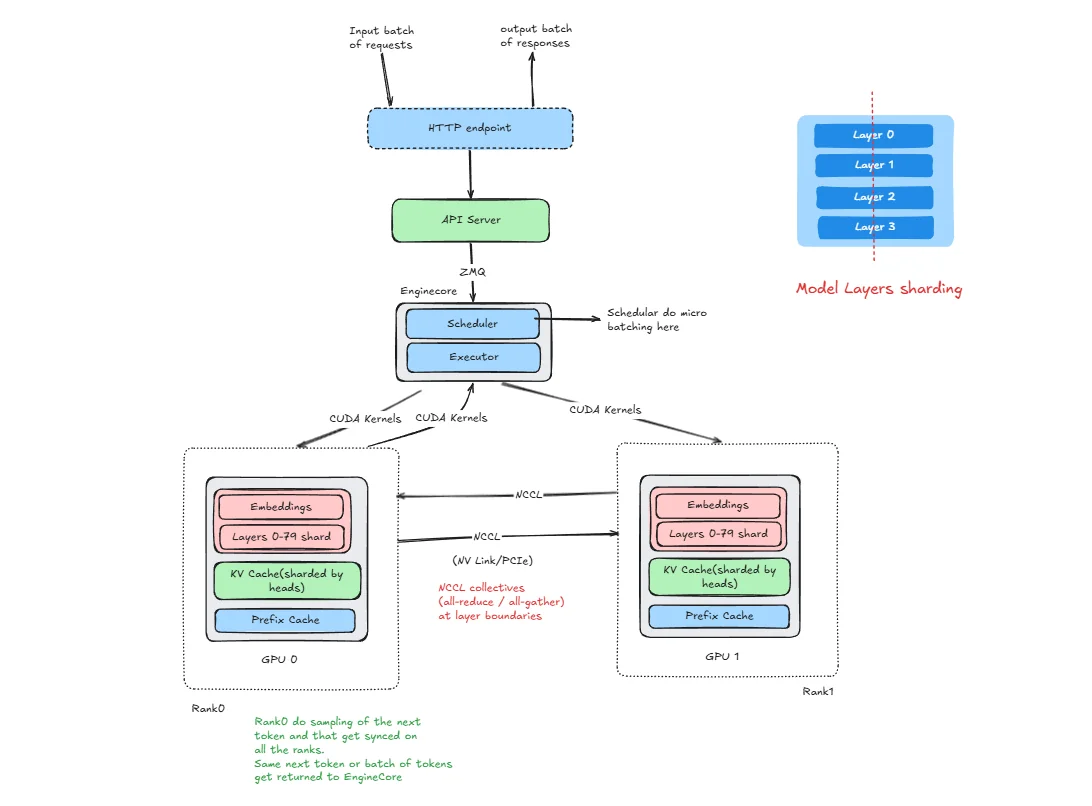
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
Advertisement Space (336x280)
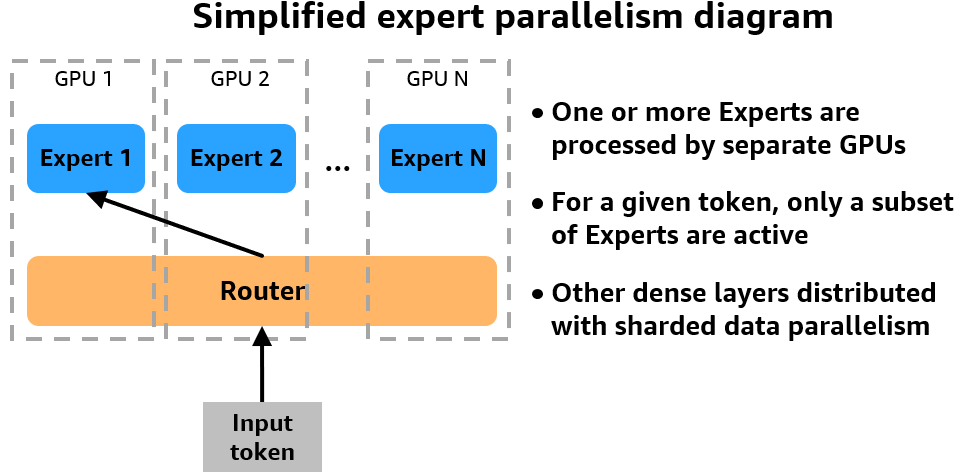
vllm 学习笔记 | Okabe's LAB
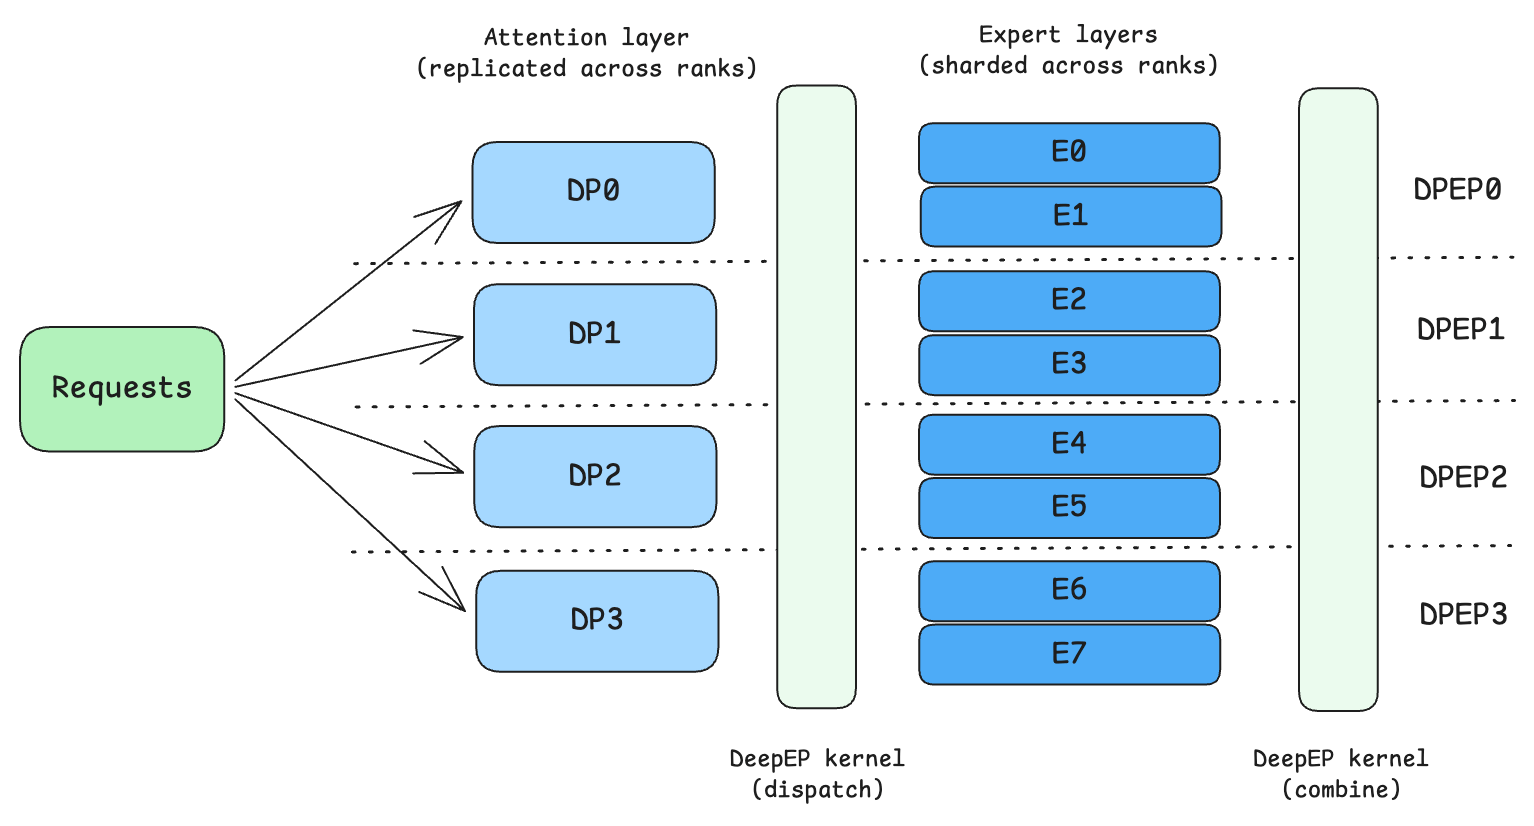
Announcing DP Group Fault Tolerance for vLLM WideEP Deployments with ...

Distributed vLLM Inference - Bristol Centre for Supercomputing ...

(4/6) AI in Multiple GPUs: Grad Accum & Data Parallelism – Lorenzo ...
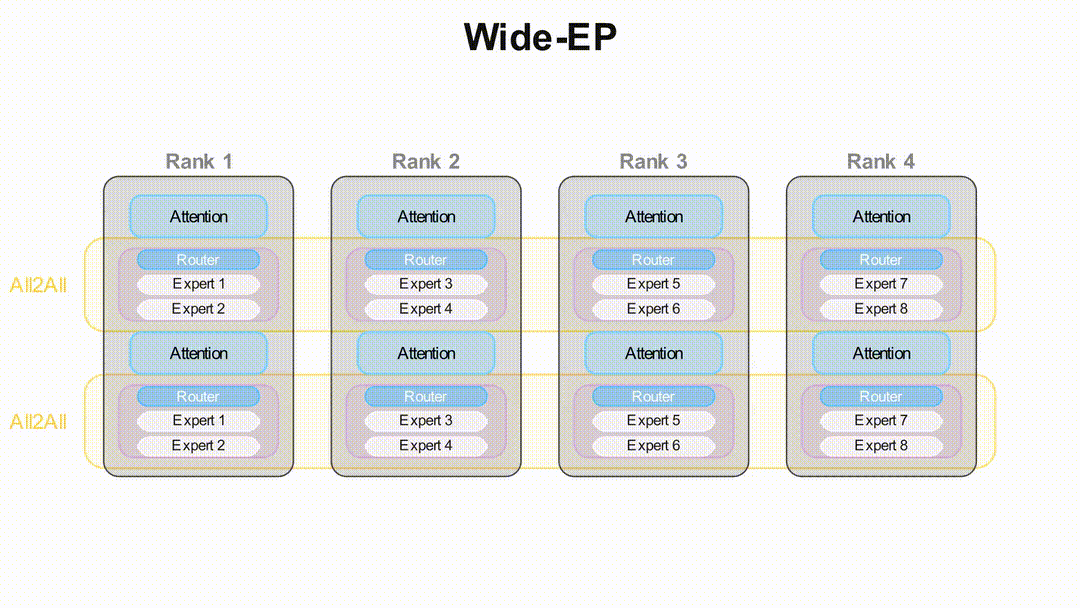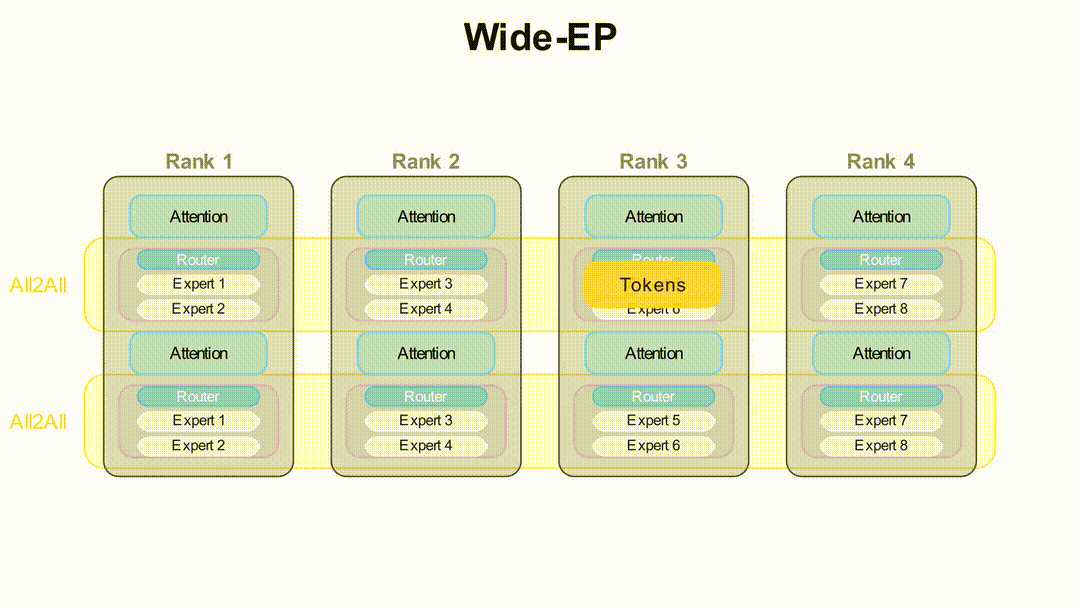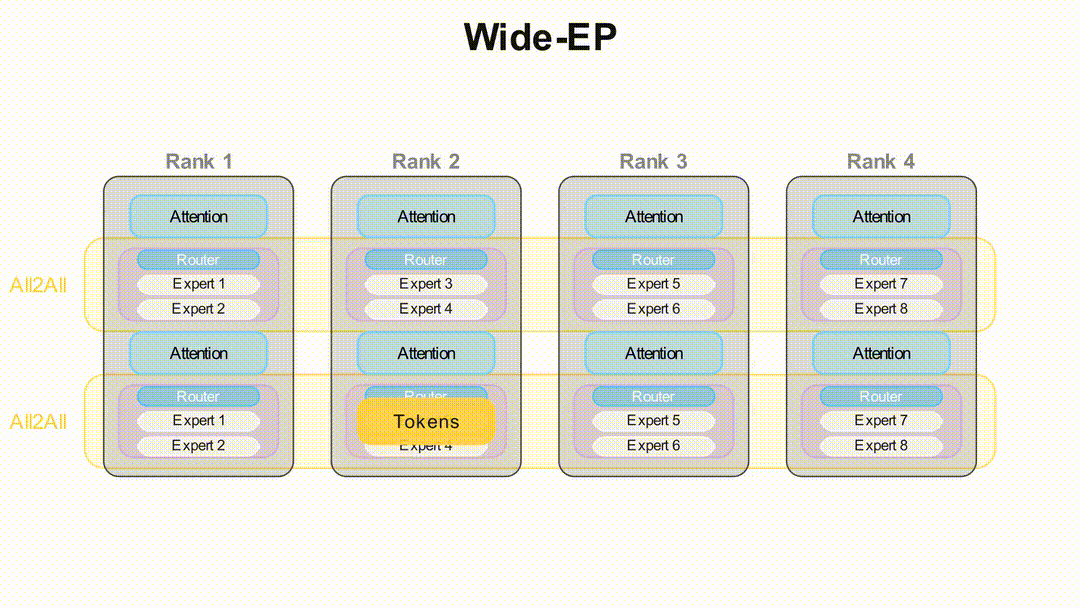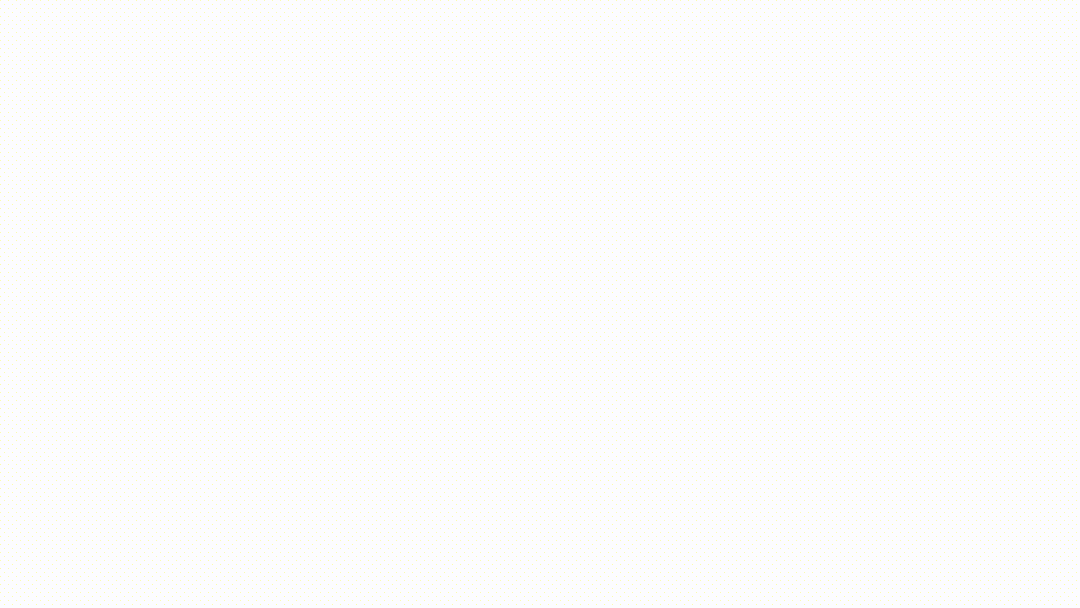
vLLM Large Scale Serving: DeepSeek @ 2.2k tok/s/H200 with Wide-EP ...
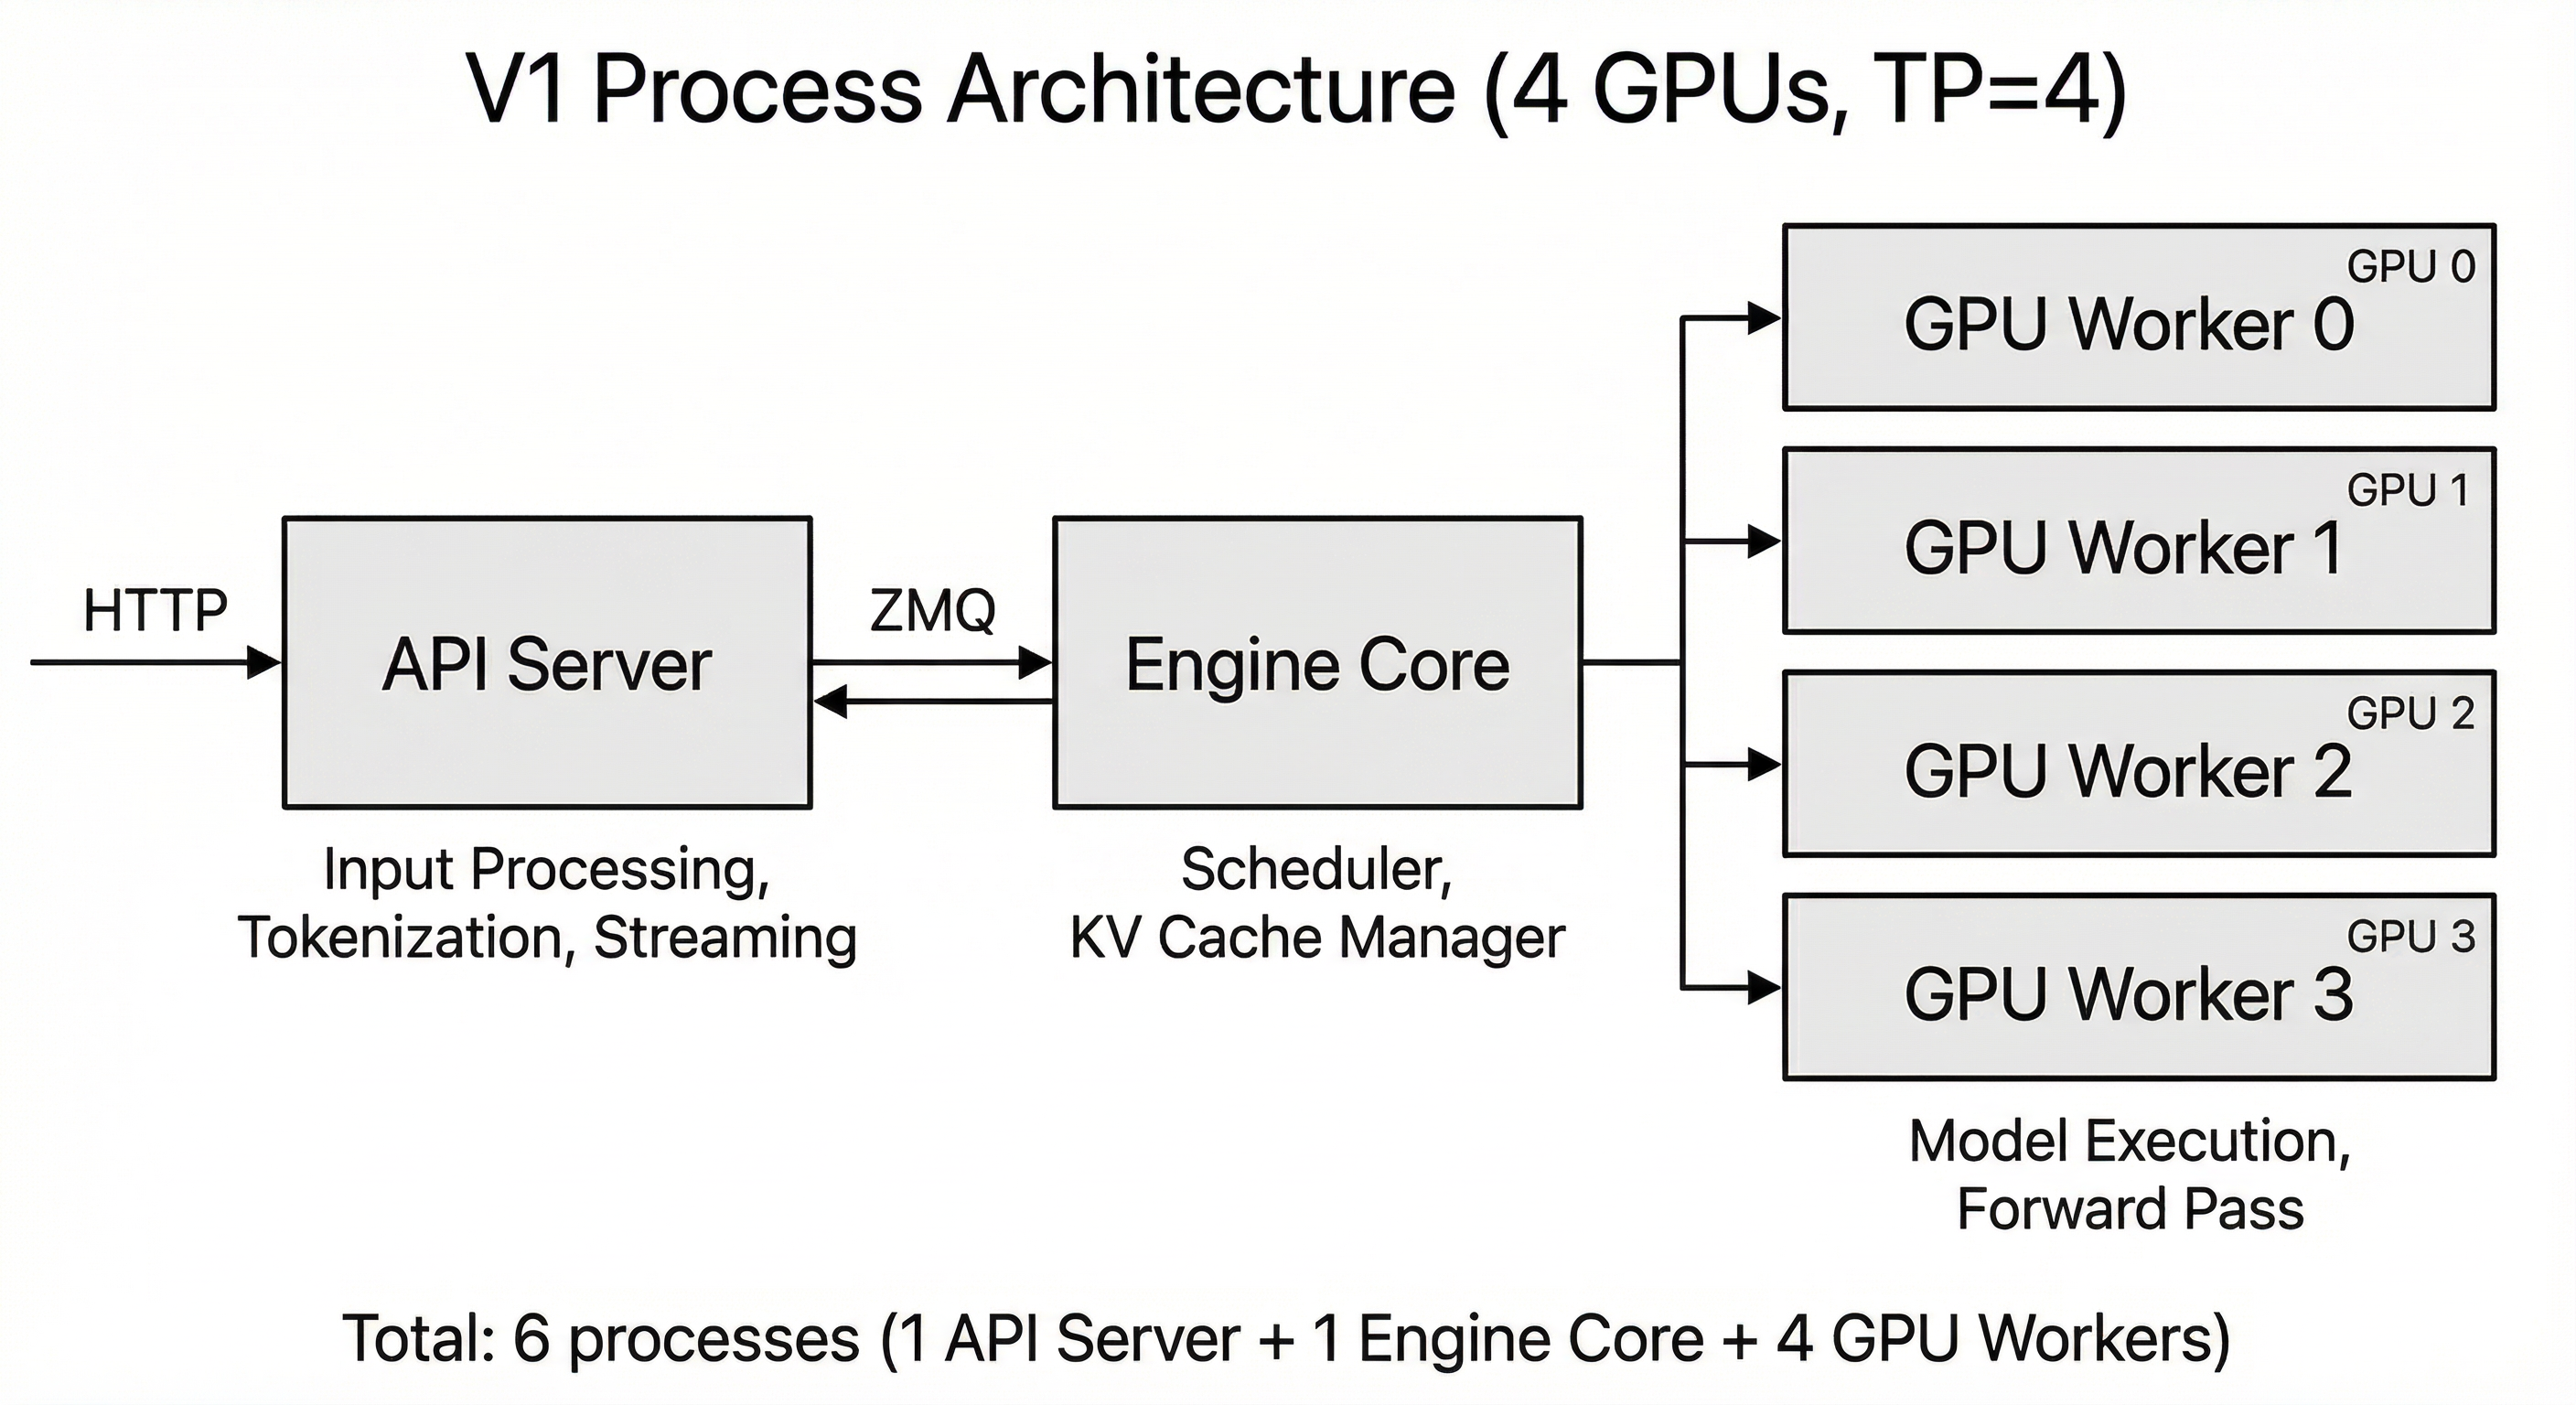
Architecture Overview - vLLM