
Deploy A Dynamo Inference Service With Pd Disaggregation Container
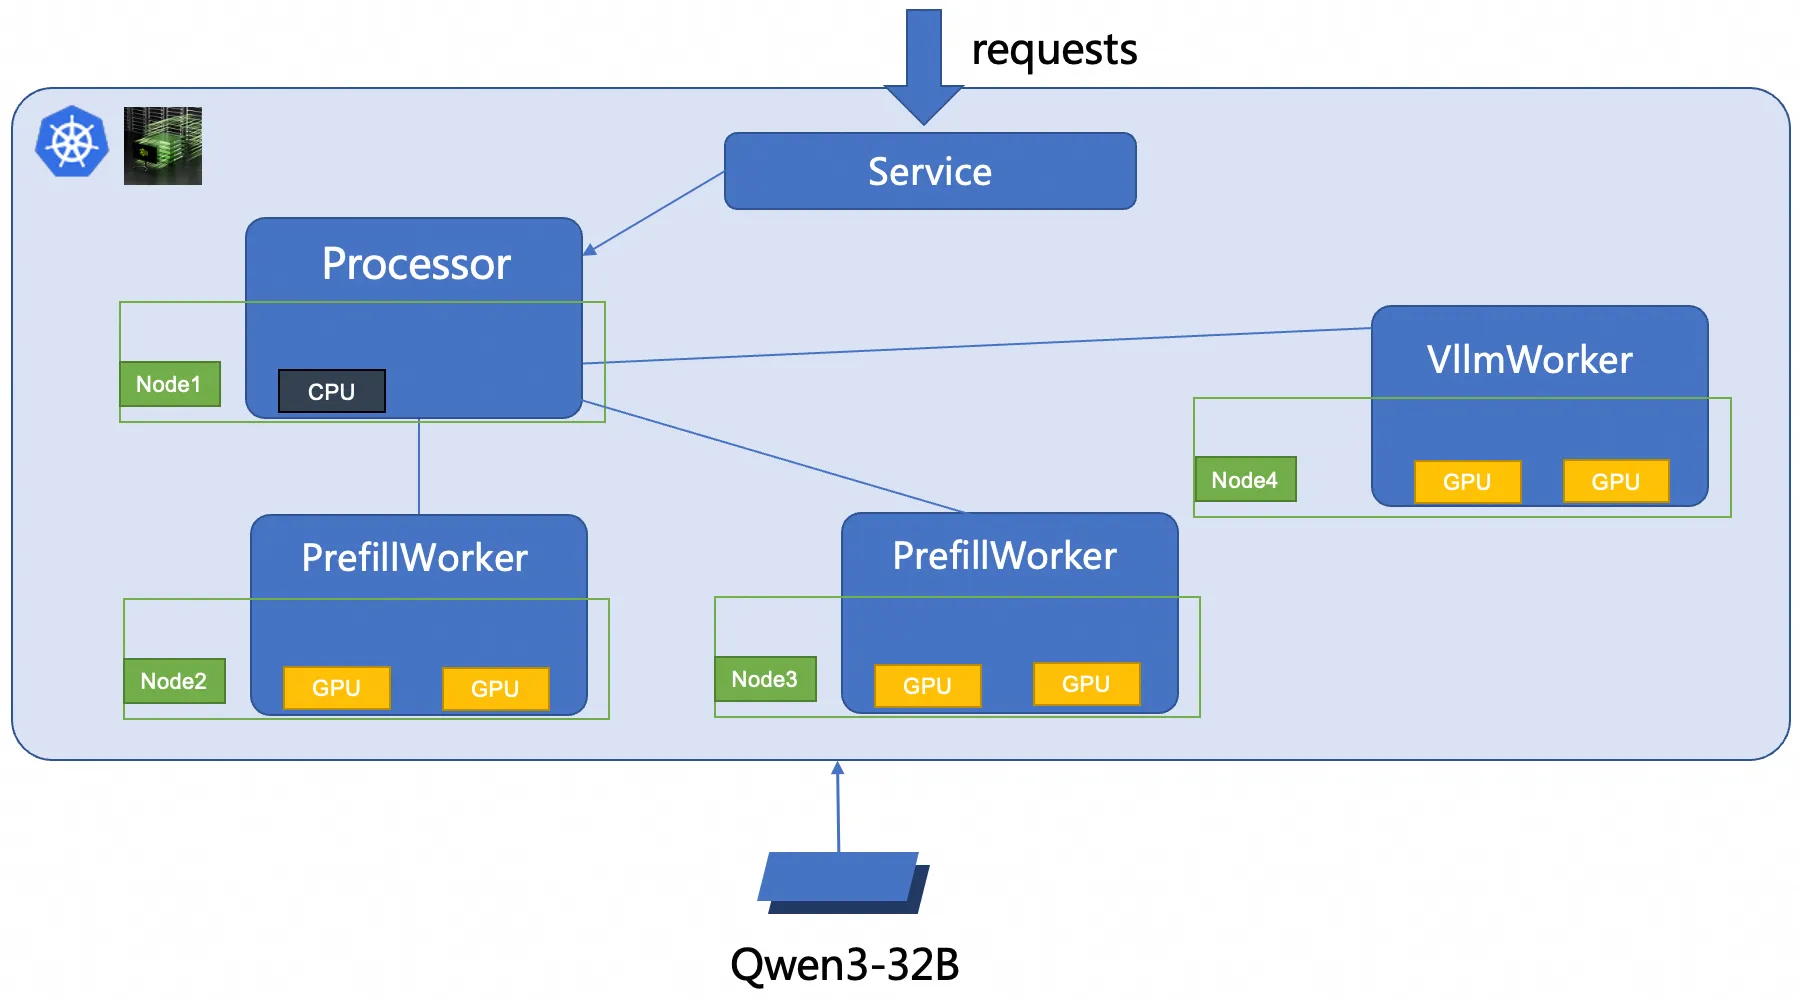
Deploy a Dynamo inference service with PD disaggregation - Container ...
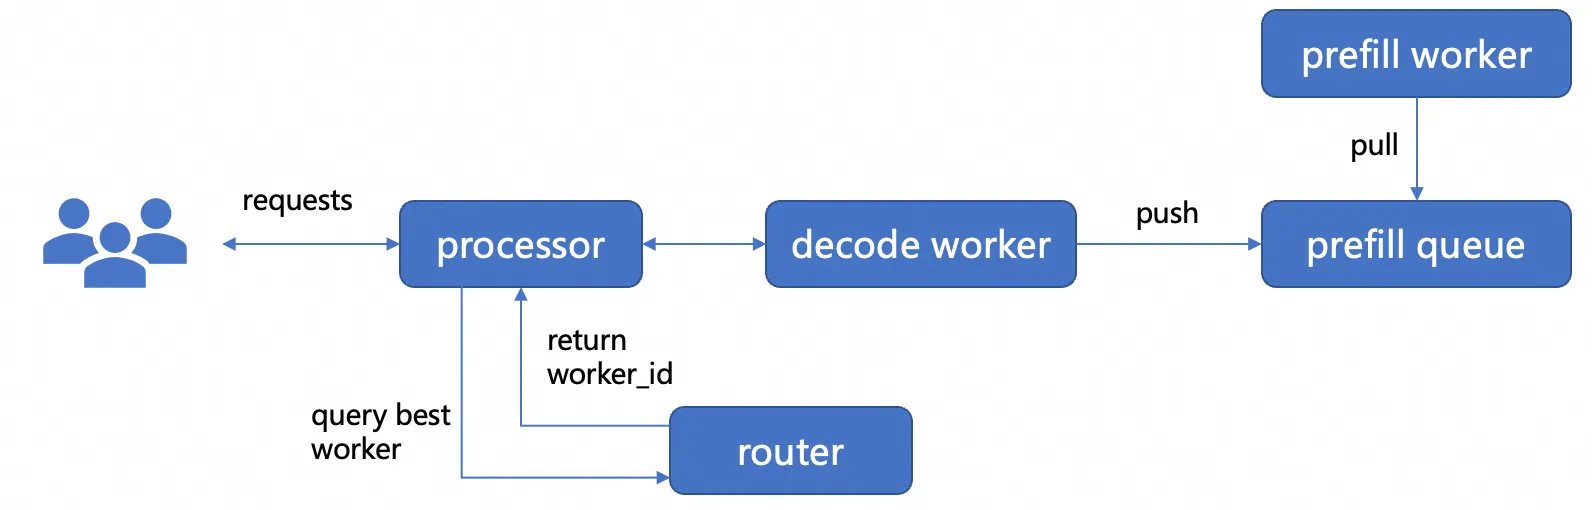
Deploy a Dynamo inference service with PD disaggregation - Container ...
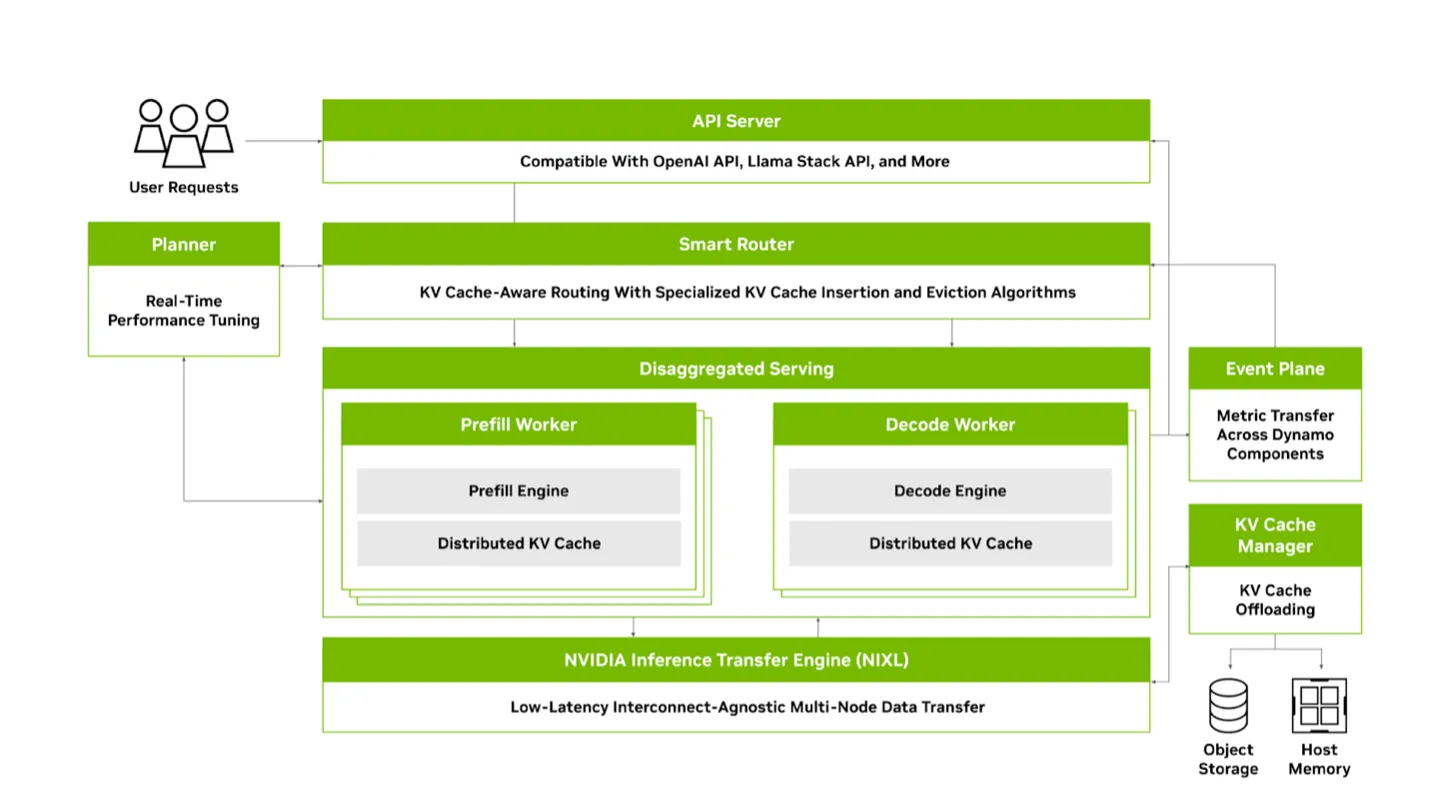
Deploy a Dynamo inference service with PD disaggregation - Container ...
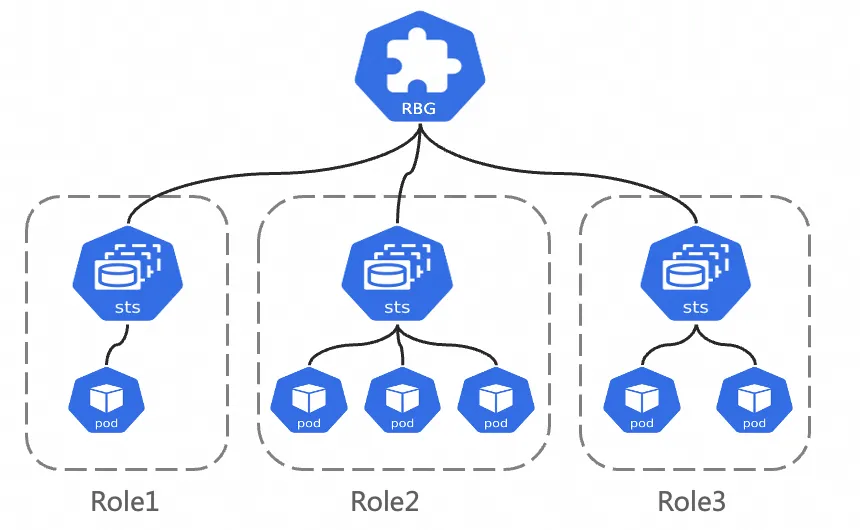
Deploy a Dynamo inference service with PD disaggregation - Container ...
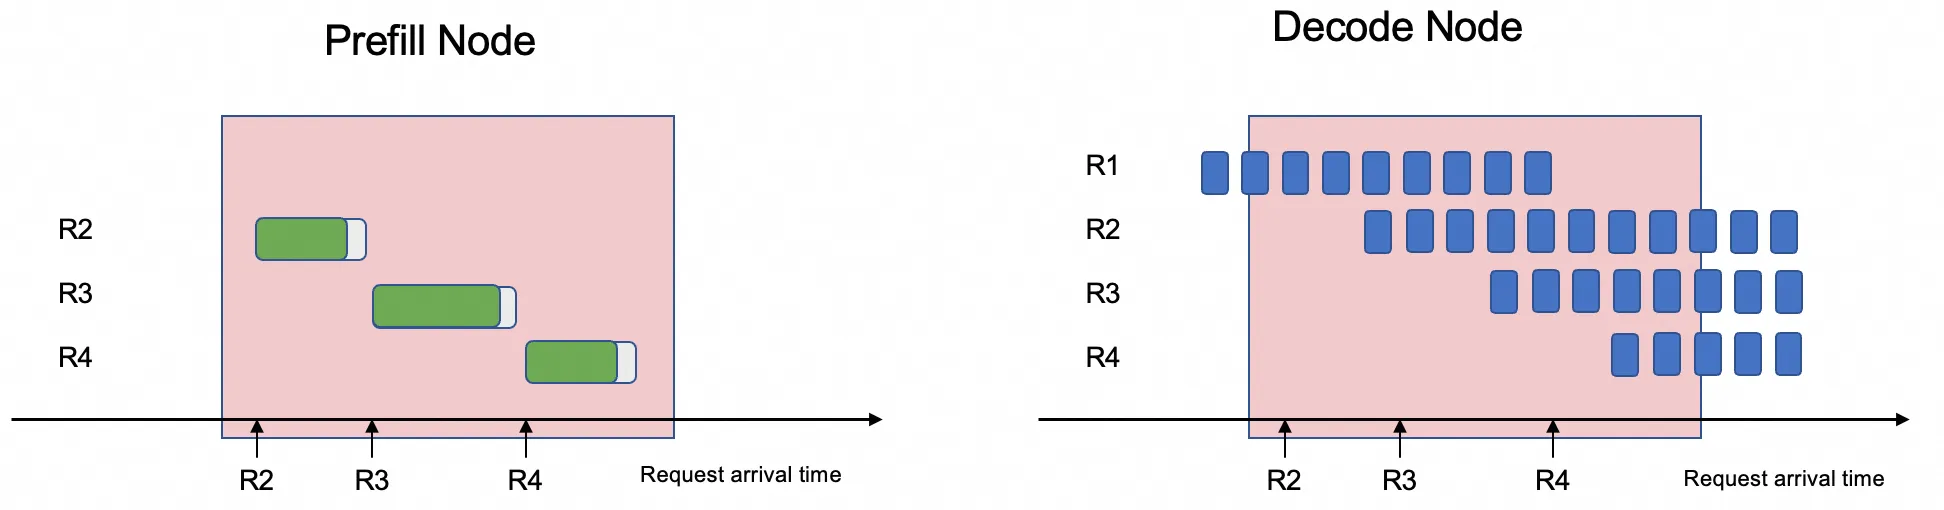
Deploy a Dynamo inference service with PD disaggregation - Container ...
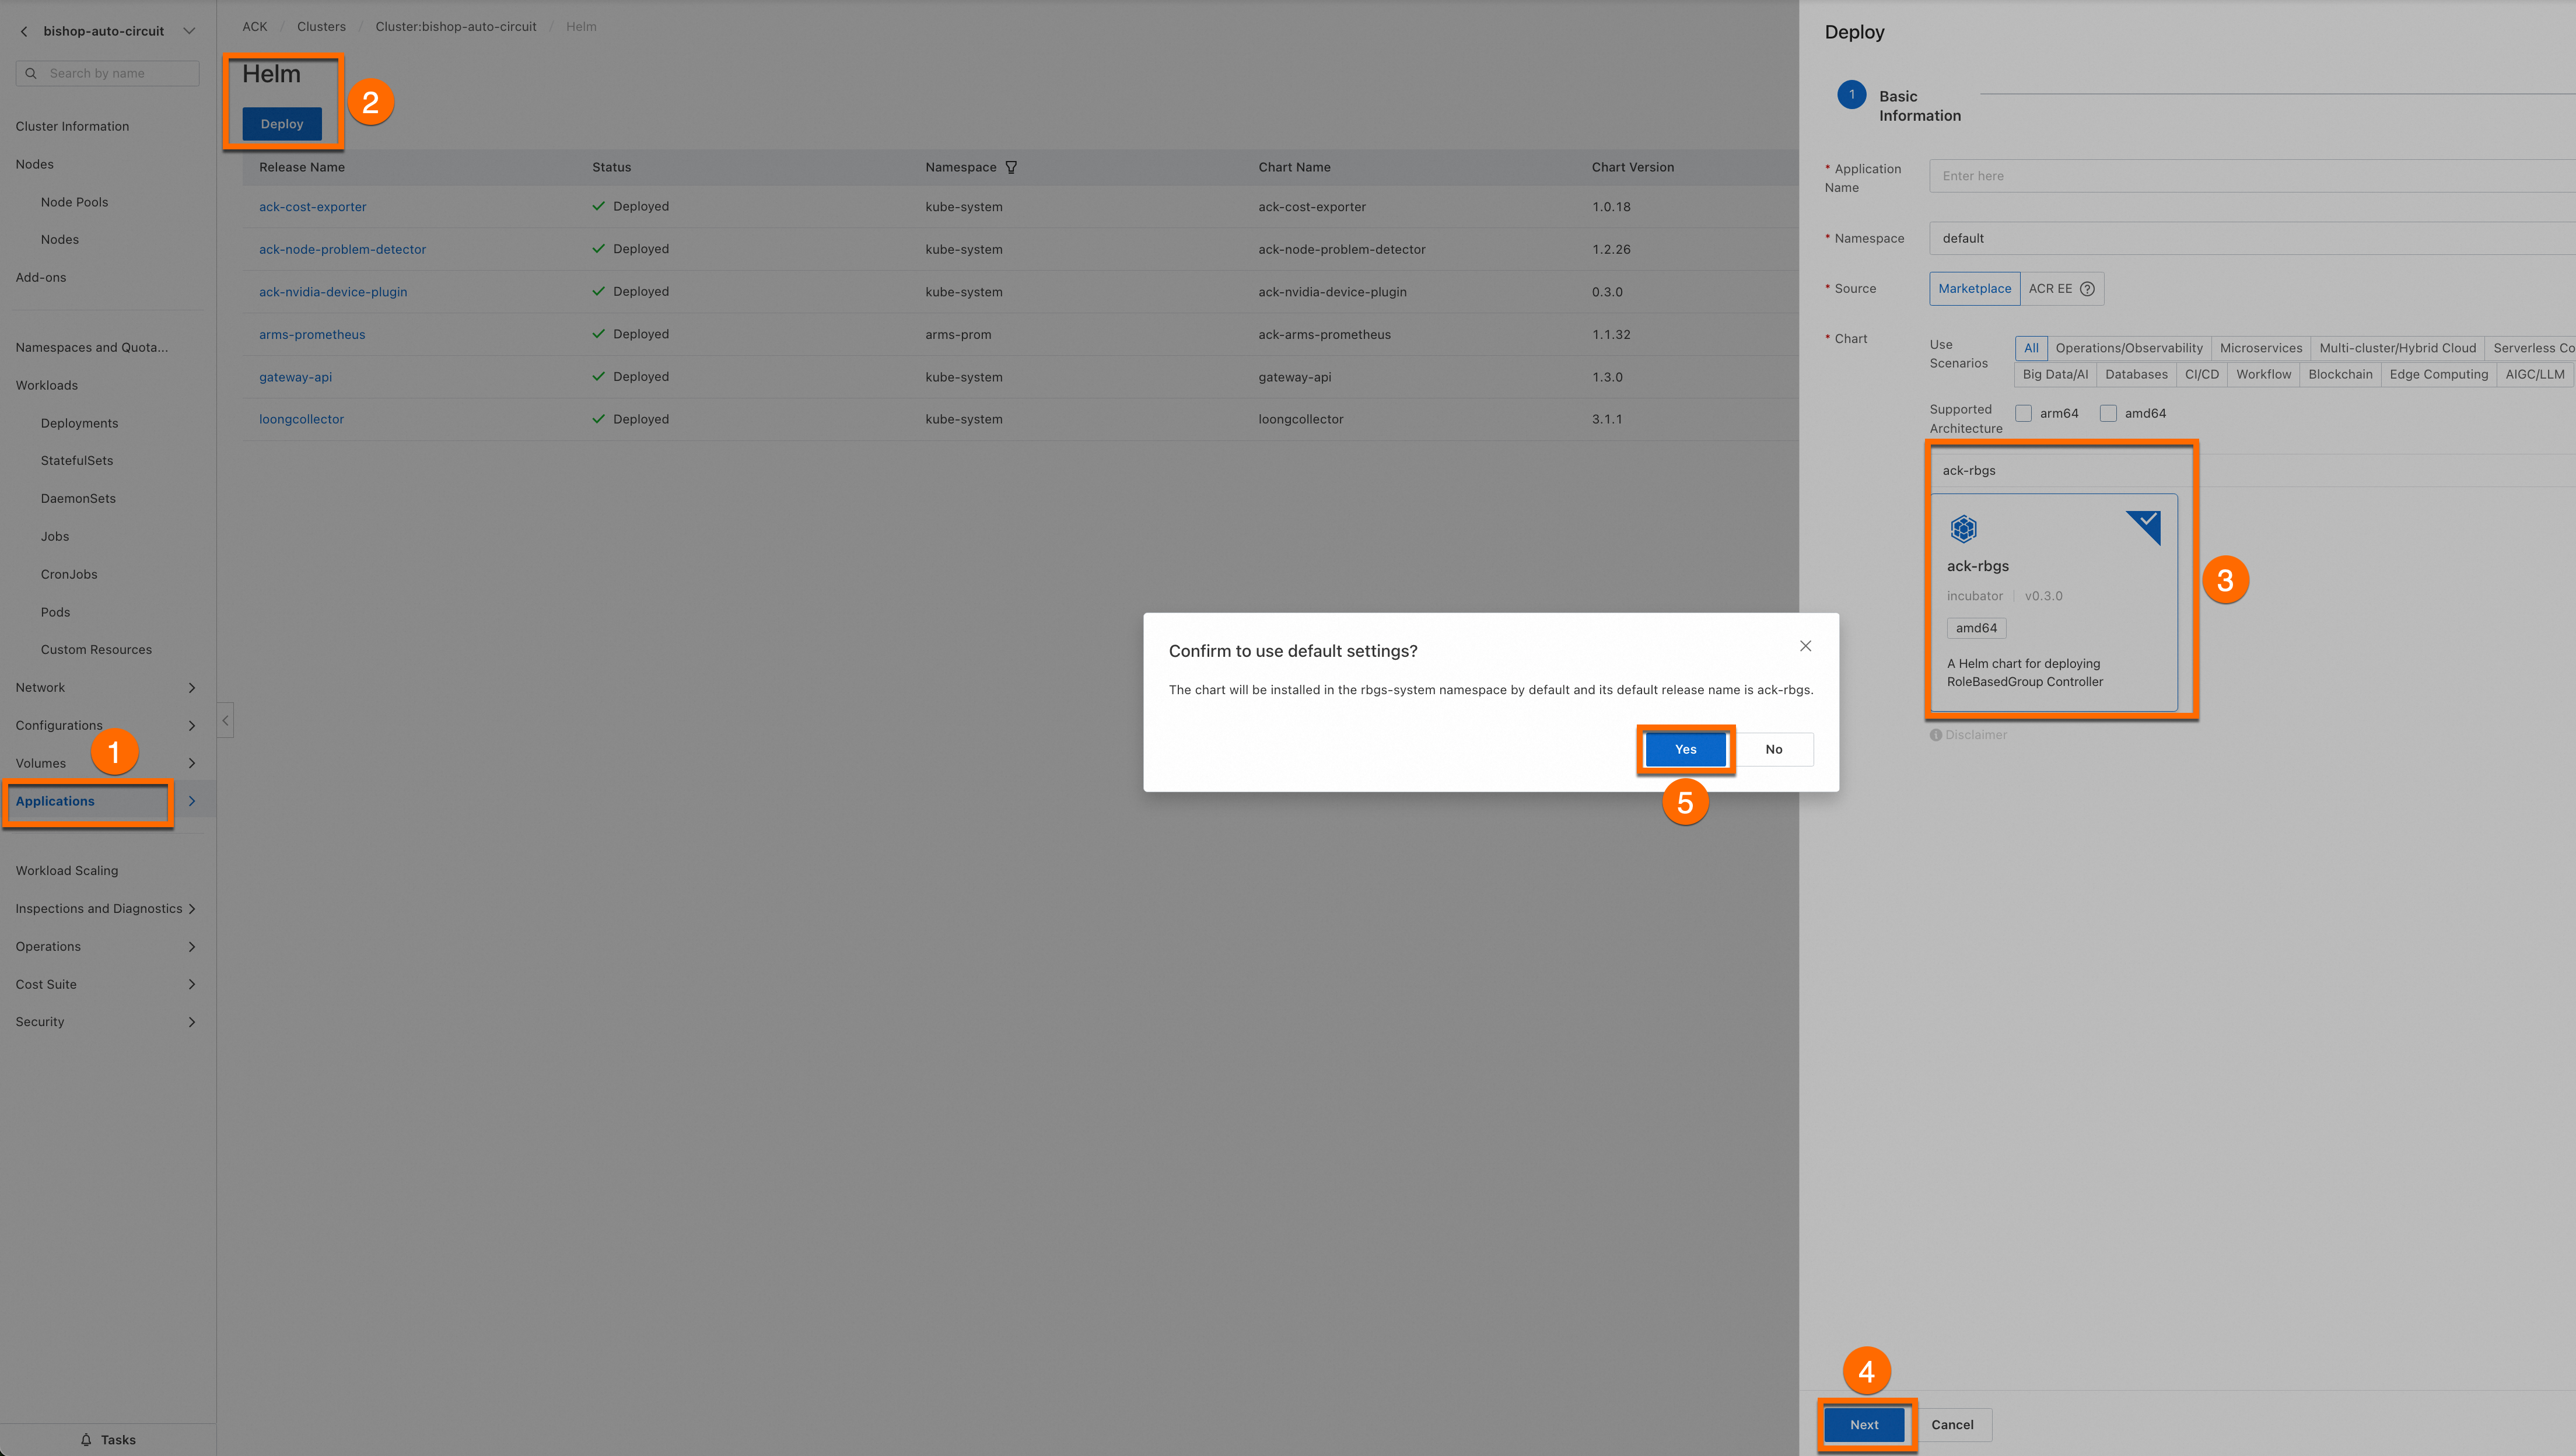
Deploy a Dynamo inference service with PD disaggregation - Container ...
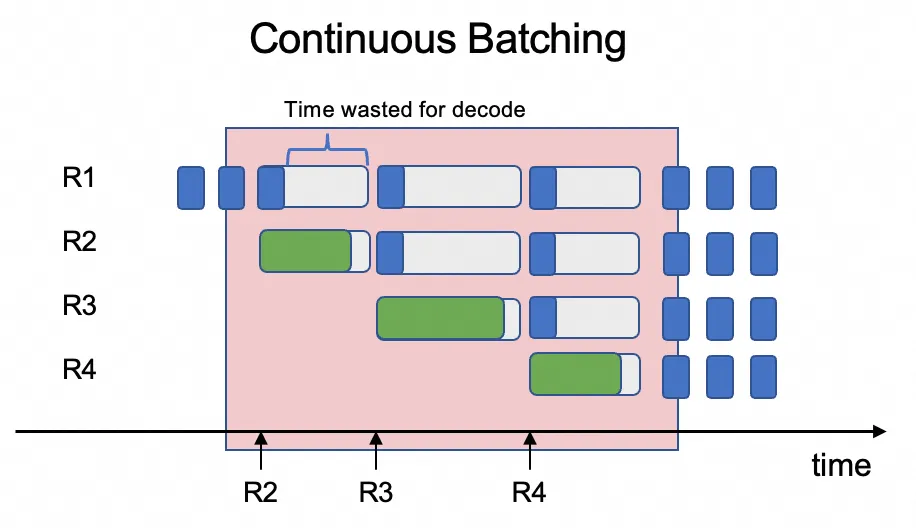
Deploy a Dynamo inference service with PD disaggregation - Container ...
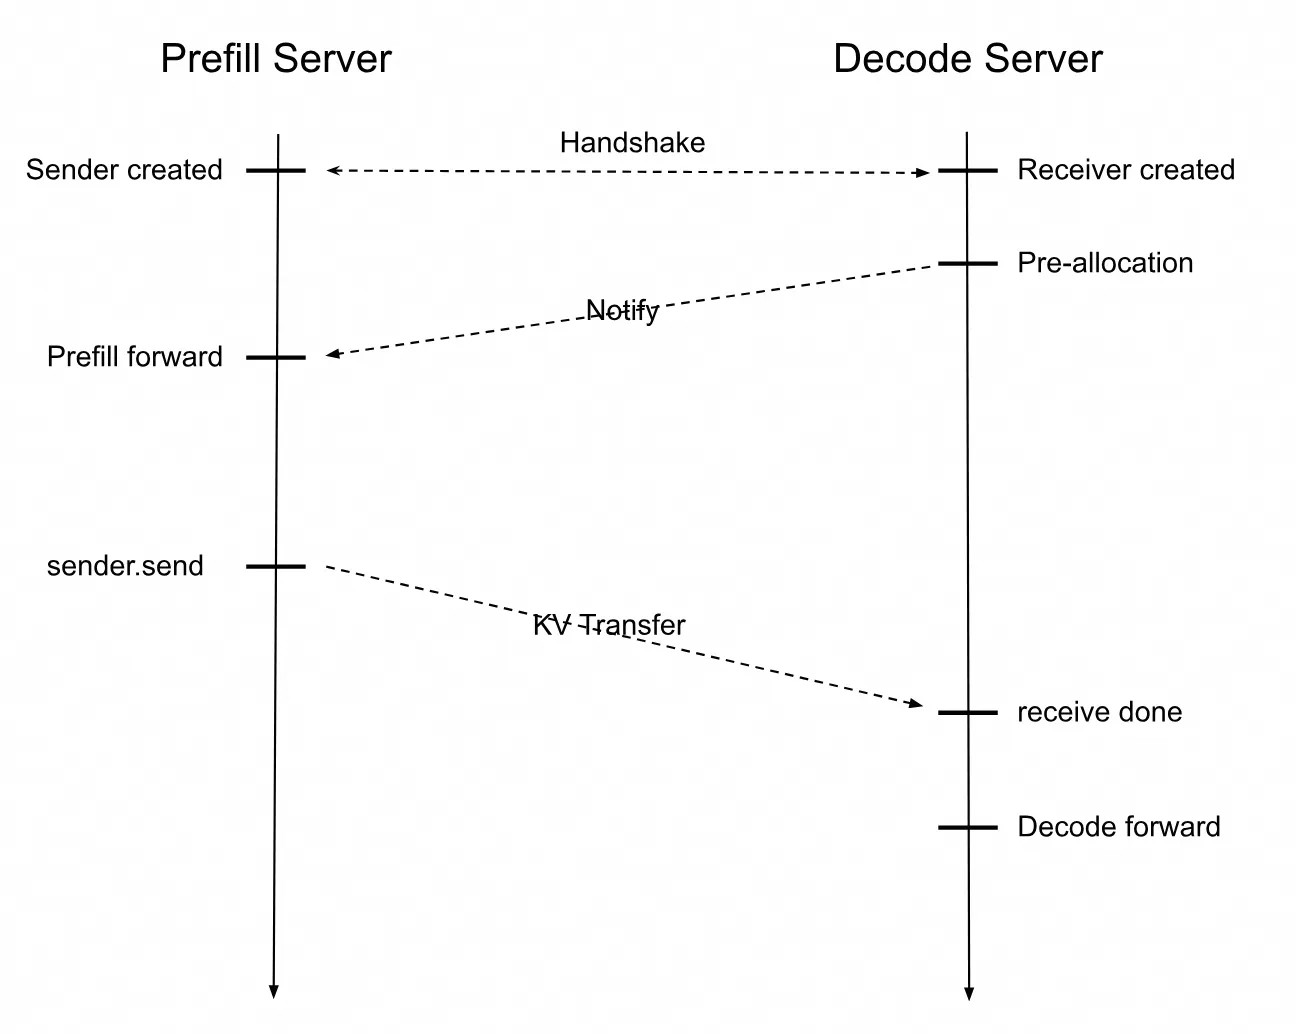
Deploy an SGLang inference service with Prefill-Decode Disaggregation ...

Unleashing Intelligent Applications with AI Inference as a Service and ...

Scaling multi-node LLM inference with NVIDIA Dynamo and NVIDIA GPUs on ...
Advertisement Space (300x250)

How to Deploy Inference Using NVIDIA Dynamo and TensorRT-LLM | Vultr Docs

Accelerate generative AI inference with NVIDIA Dynamo and Amazon EKS ...
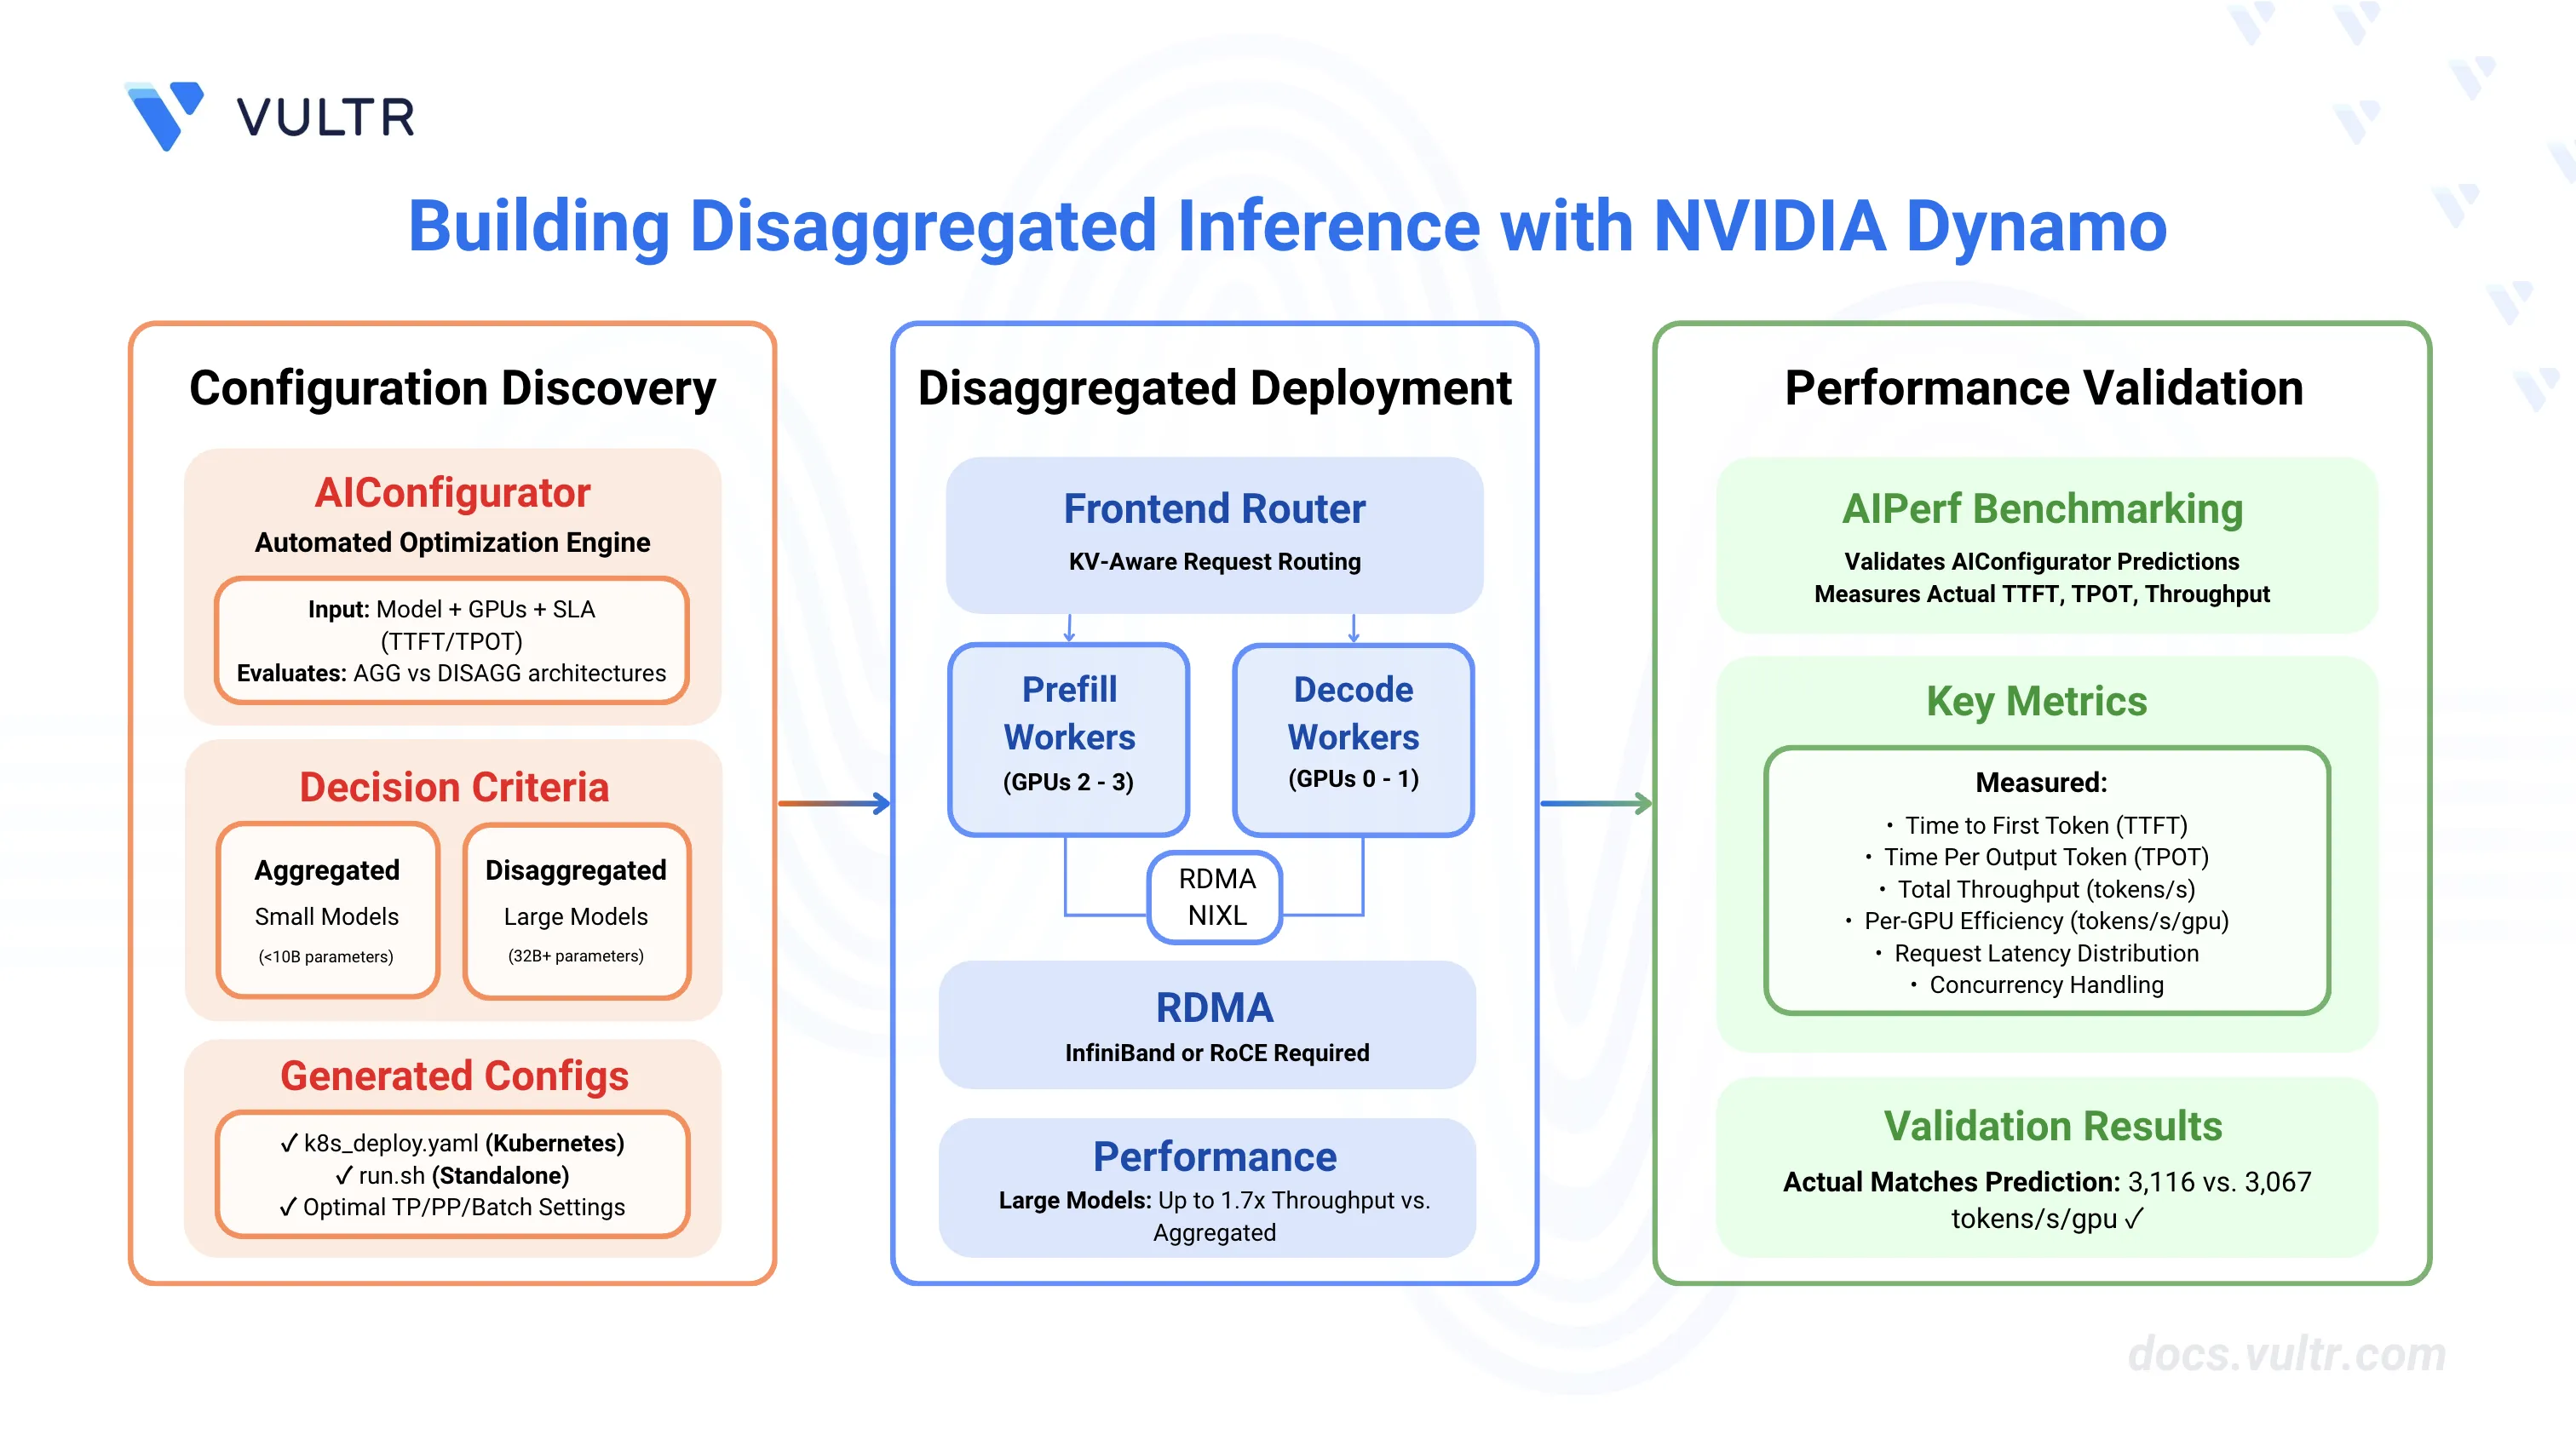
How to Build Disaggregated Inference with NVIDIA Dynamo | Vultr Docs

Nvidia Dynamo Disaggregated inference setup with DGX Spark + x86 RTX ...
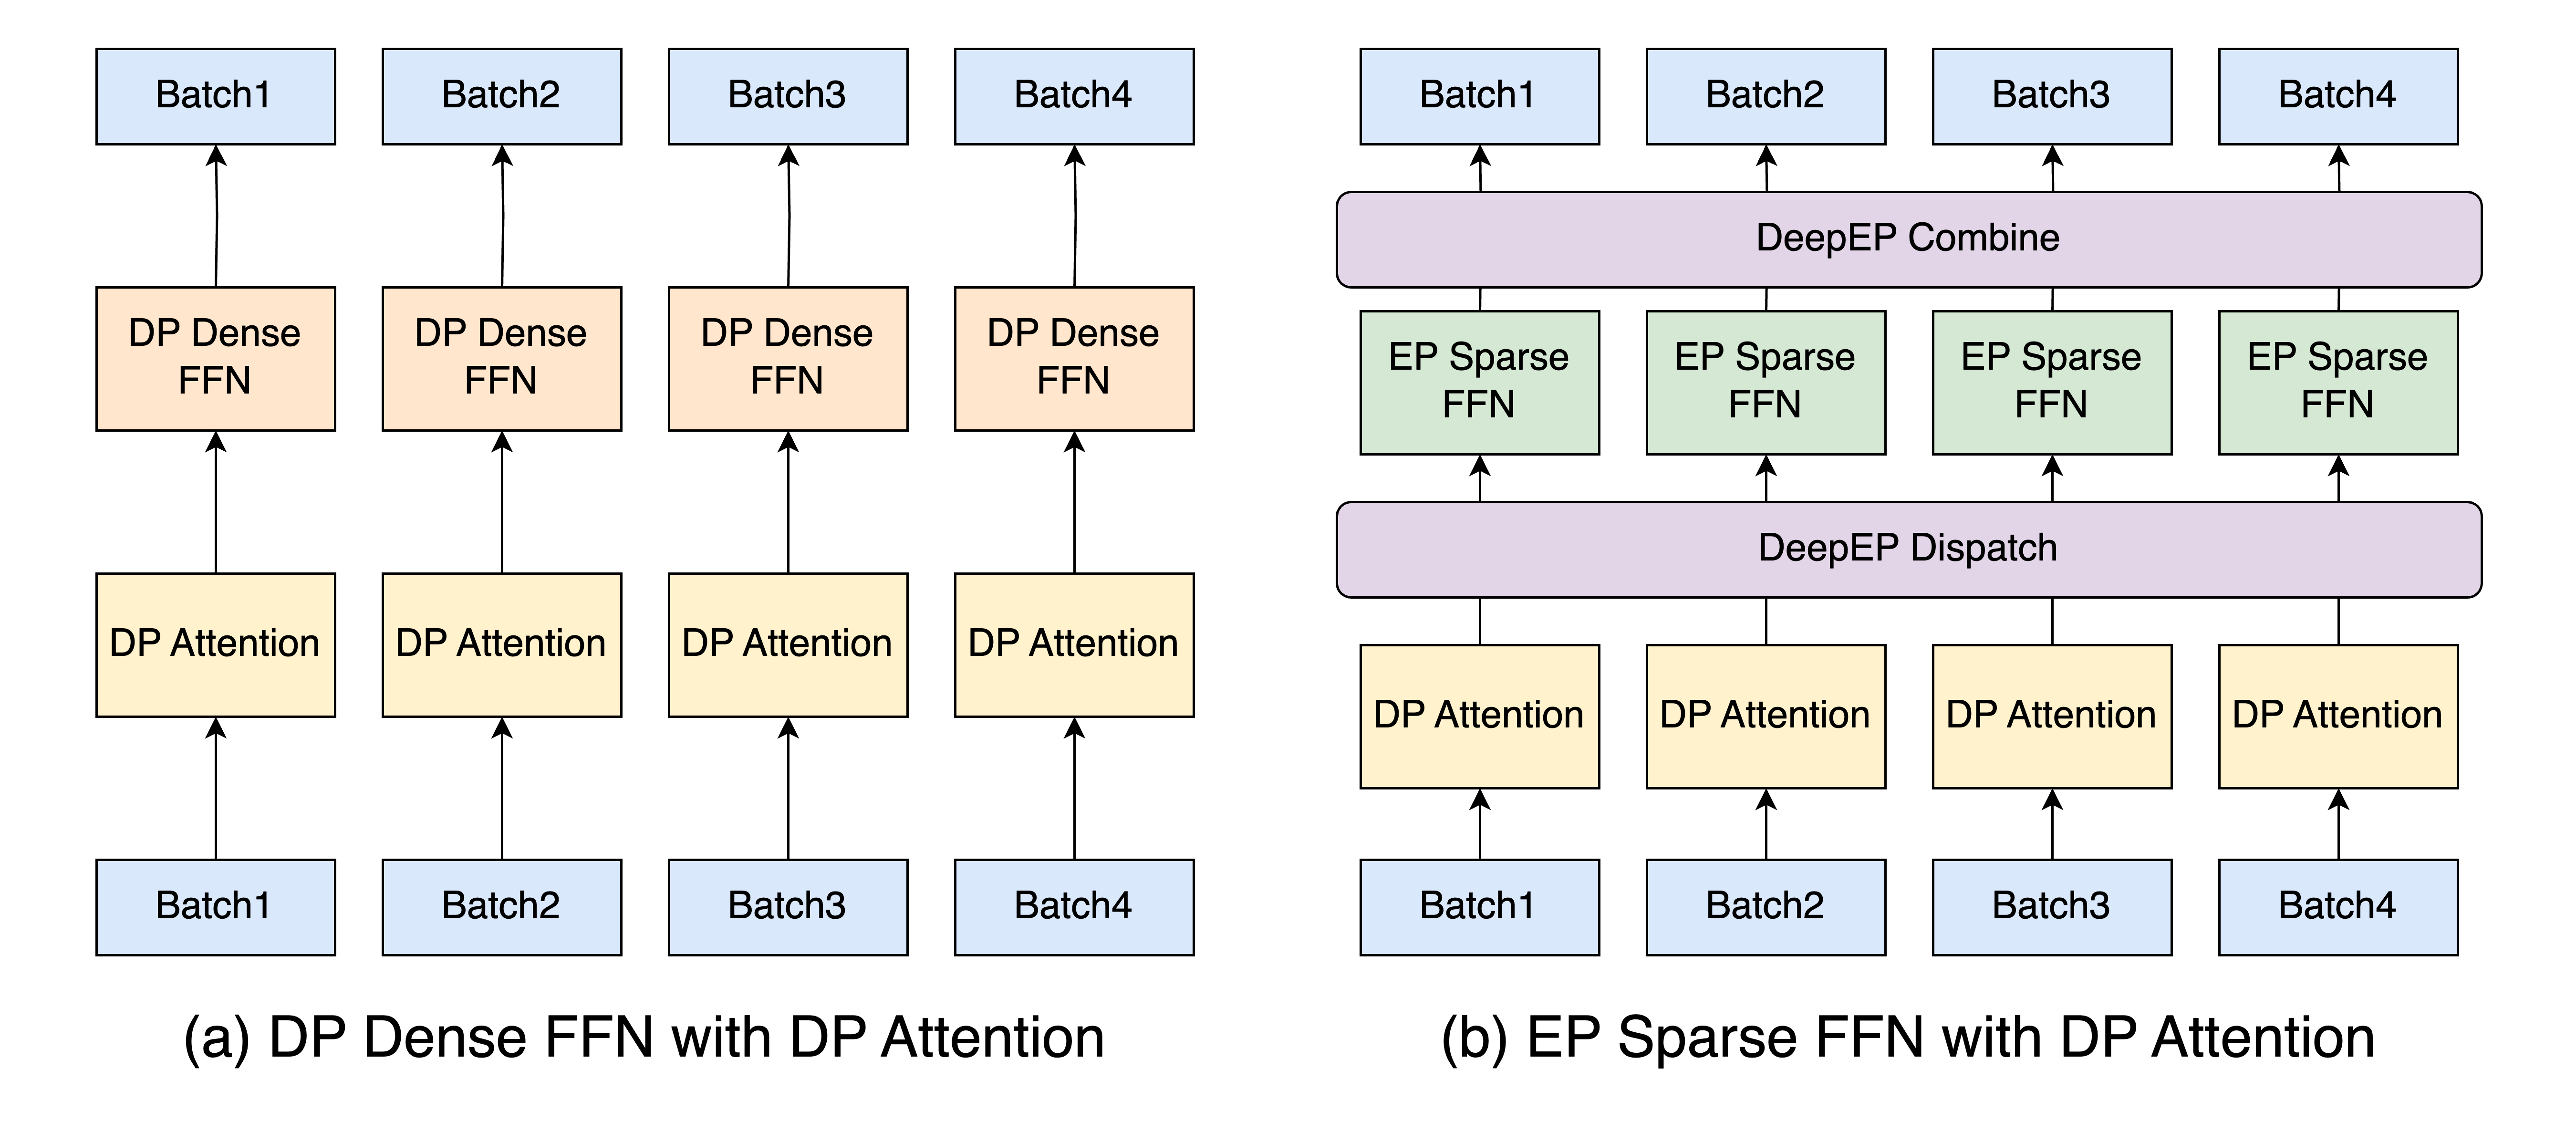
Deploying DeepSeek with PD Disaggregation and Large-Scale Expert ...
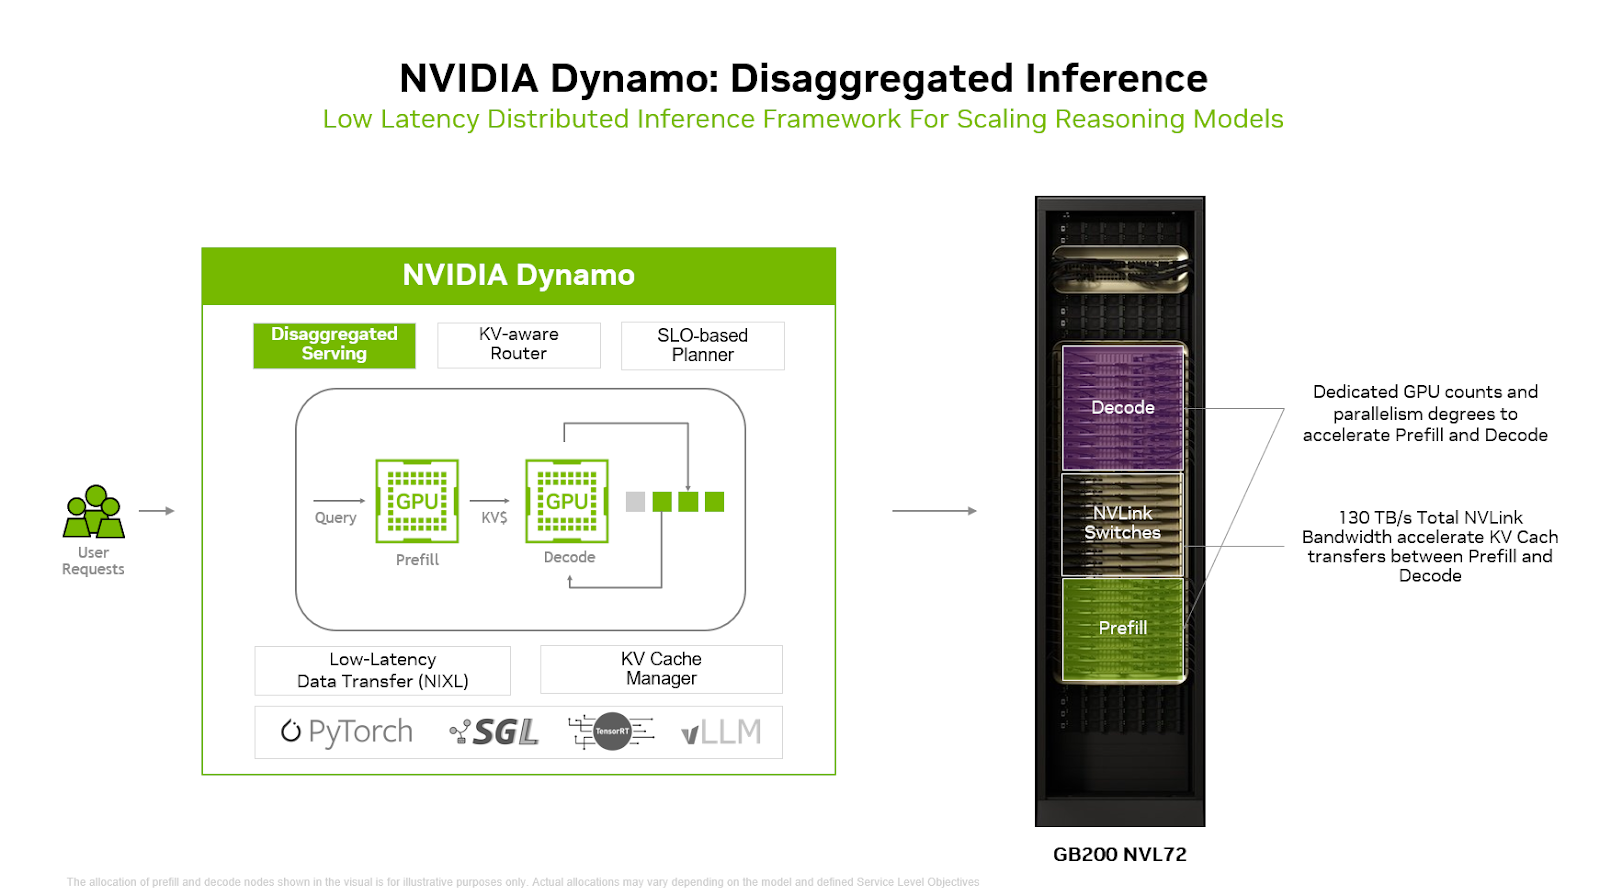
Scaling multi-node LLM inference with NVIDIA Dynamo and ND GB200 NVL72 ...
Model inference with Prefill-Decode disaggregation - dstack
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

Accelerate generative AI inference with NVIDIA Dynamo and Amazon EKS ...

Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...
Advertisement Space (336x280)

Accelerate generative AI inference with NVIDIA Dynamo and Amazon EKS ...

AI Inference recipe using NVIDIA Dynamo with AI Hypercomputer | Google ...
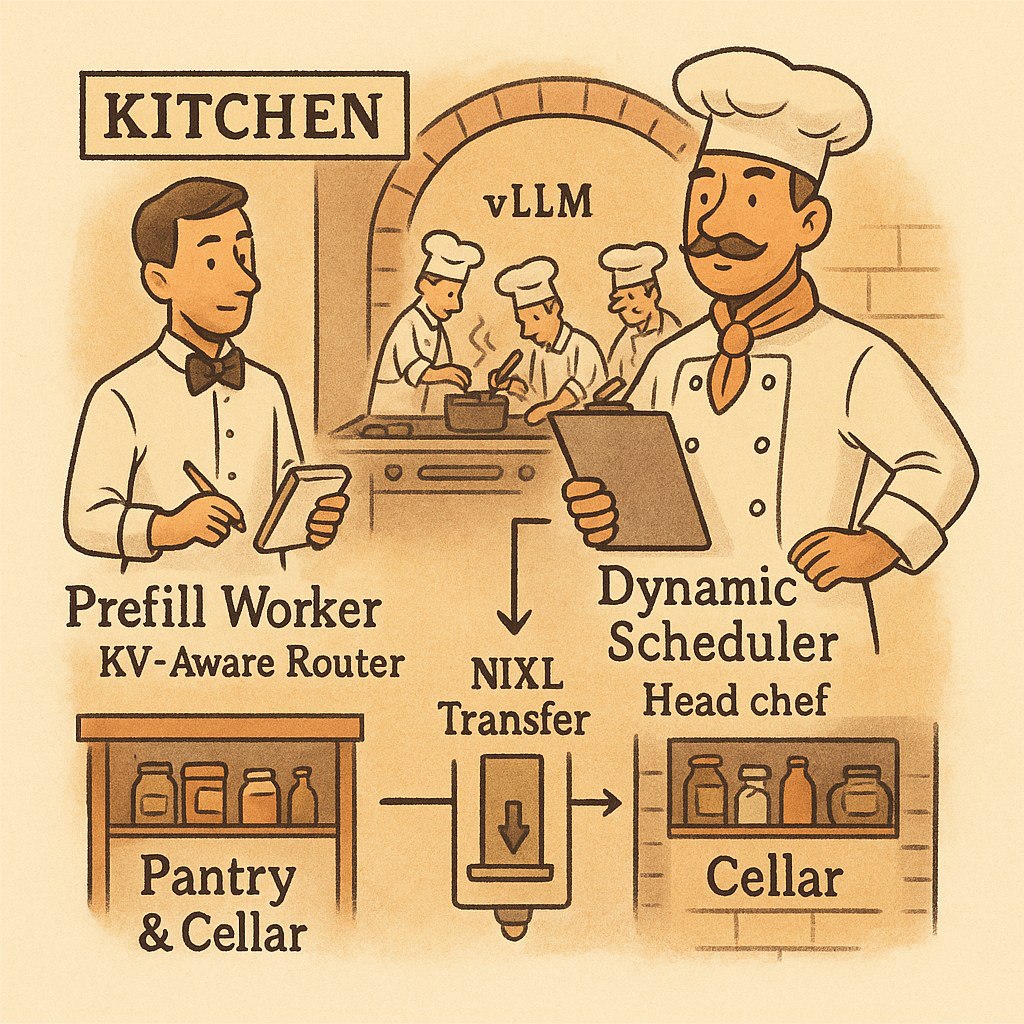
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...
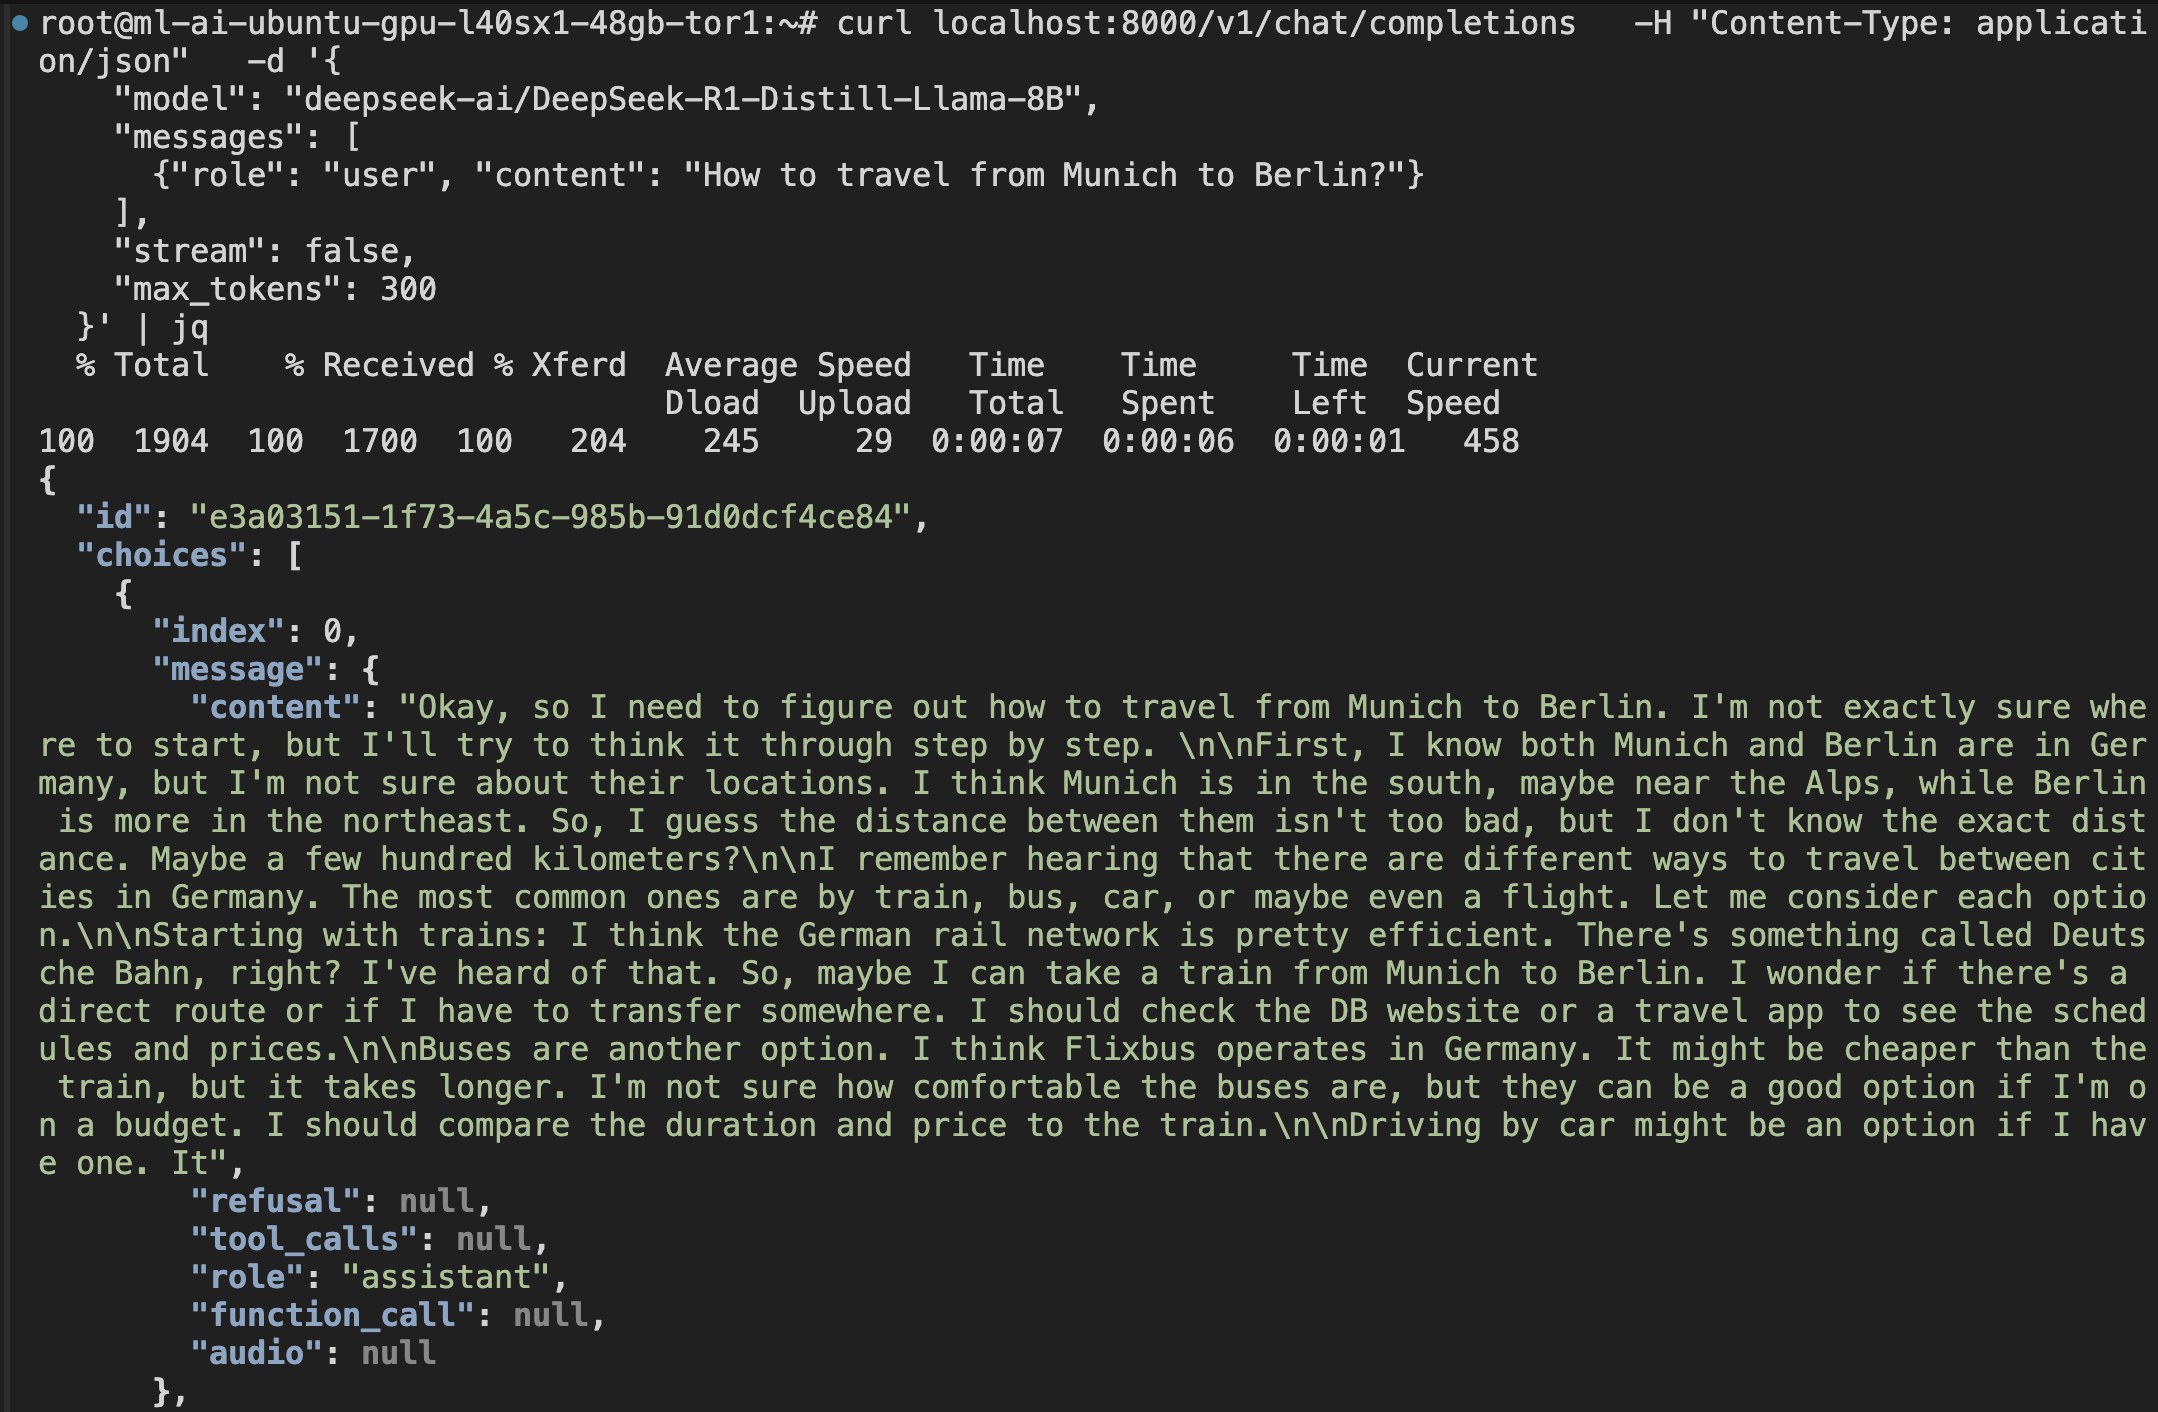
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

Deploy a machine learning inference data capture solution on AWS Lambda ...
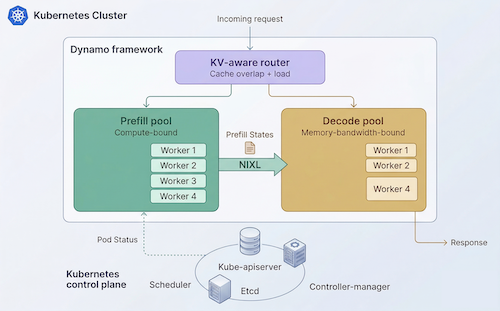
NVIDIA Dynamo: Turning Disaggregated Inference Into a Production System ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

How NVIDIA GB200 NVL72 and NVIDIA Dynamo Boost Inference Performance ...
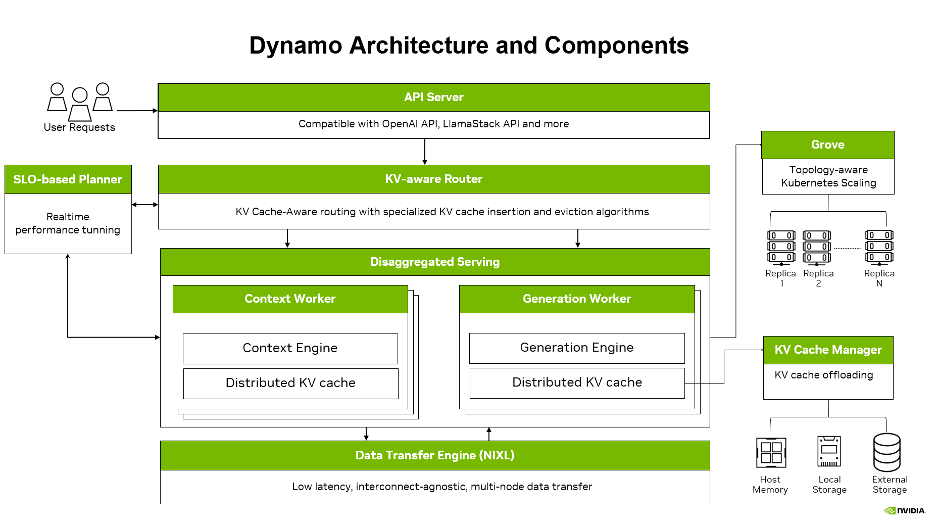
Managed NVIDIA Dynamo on Gcore: faster, lower-cost inference
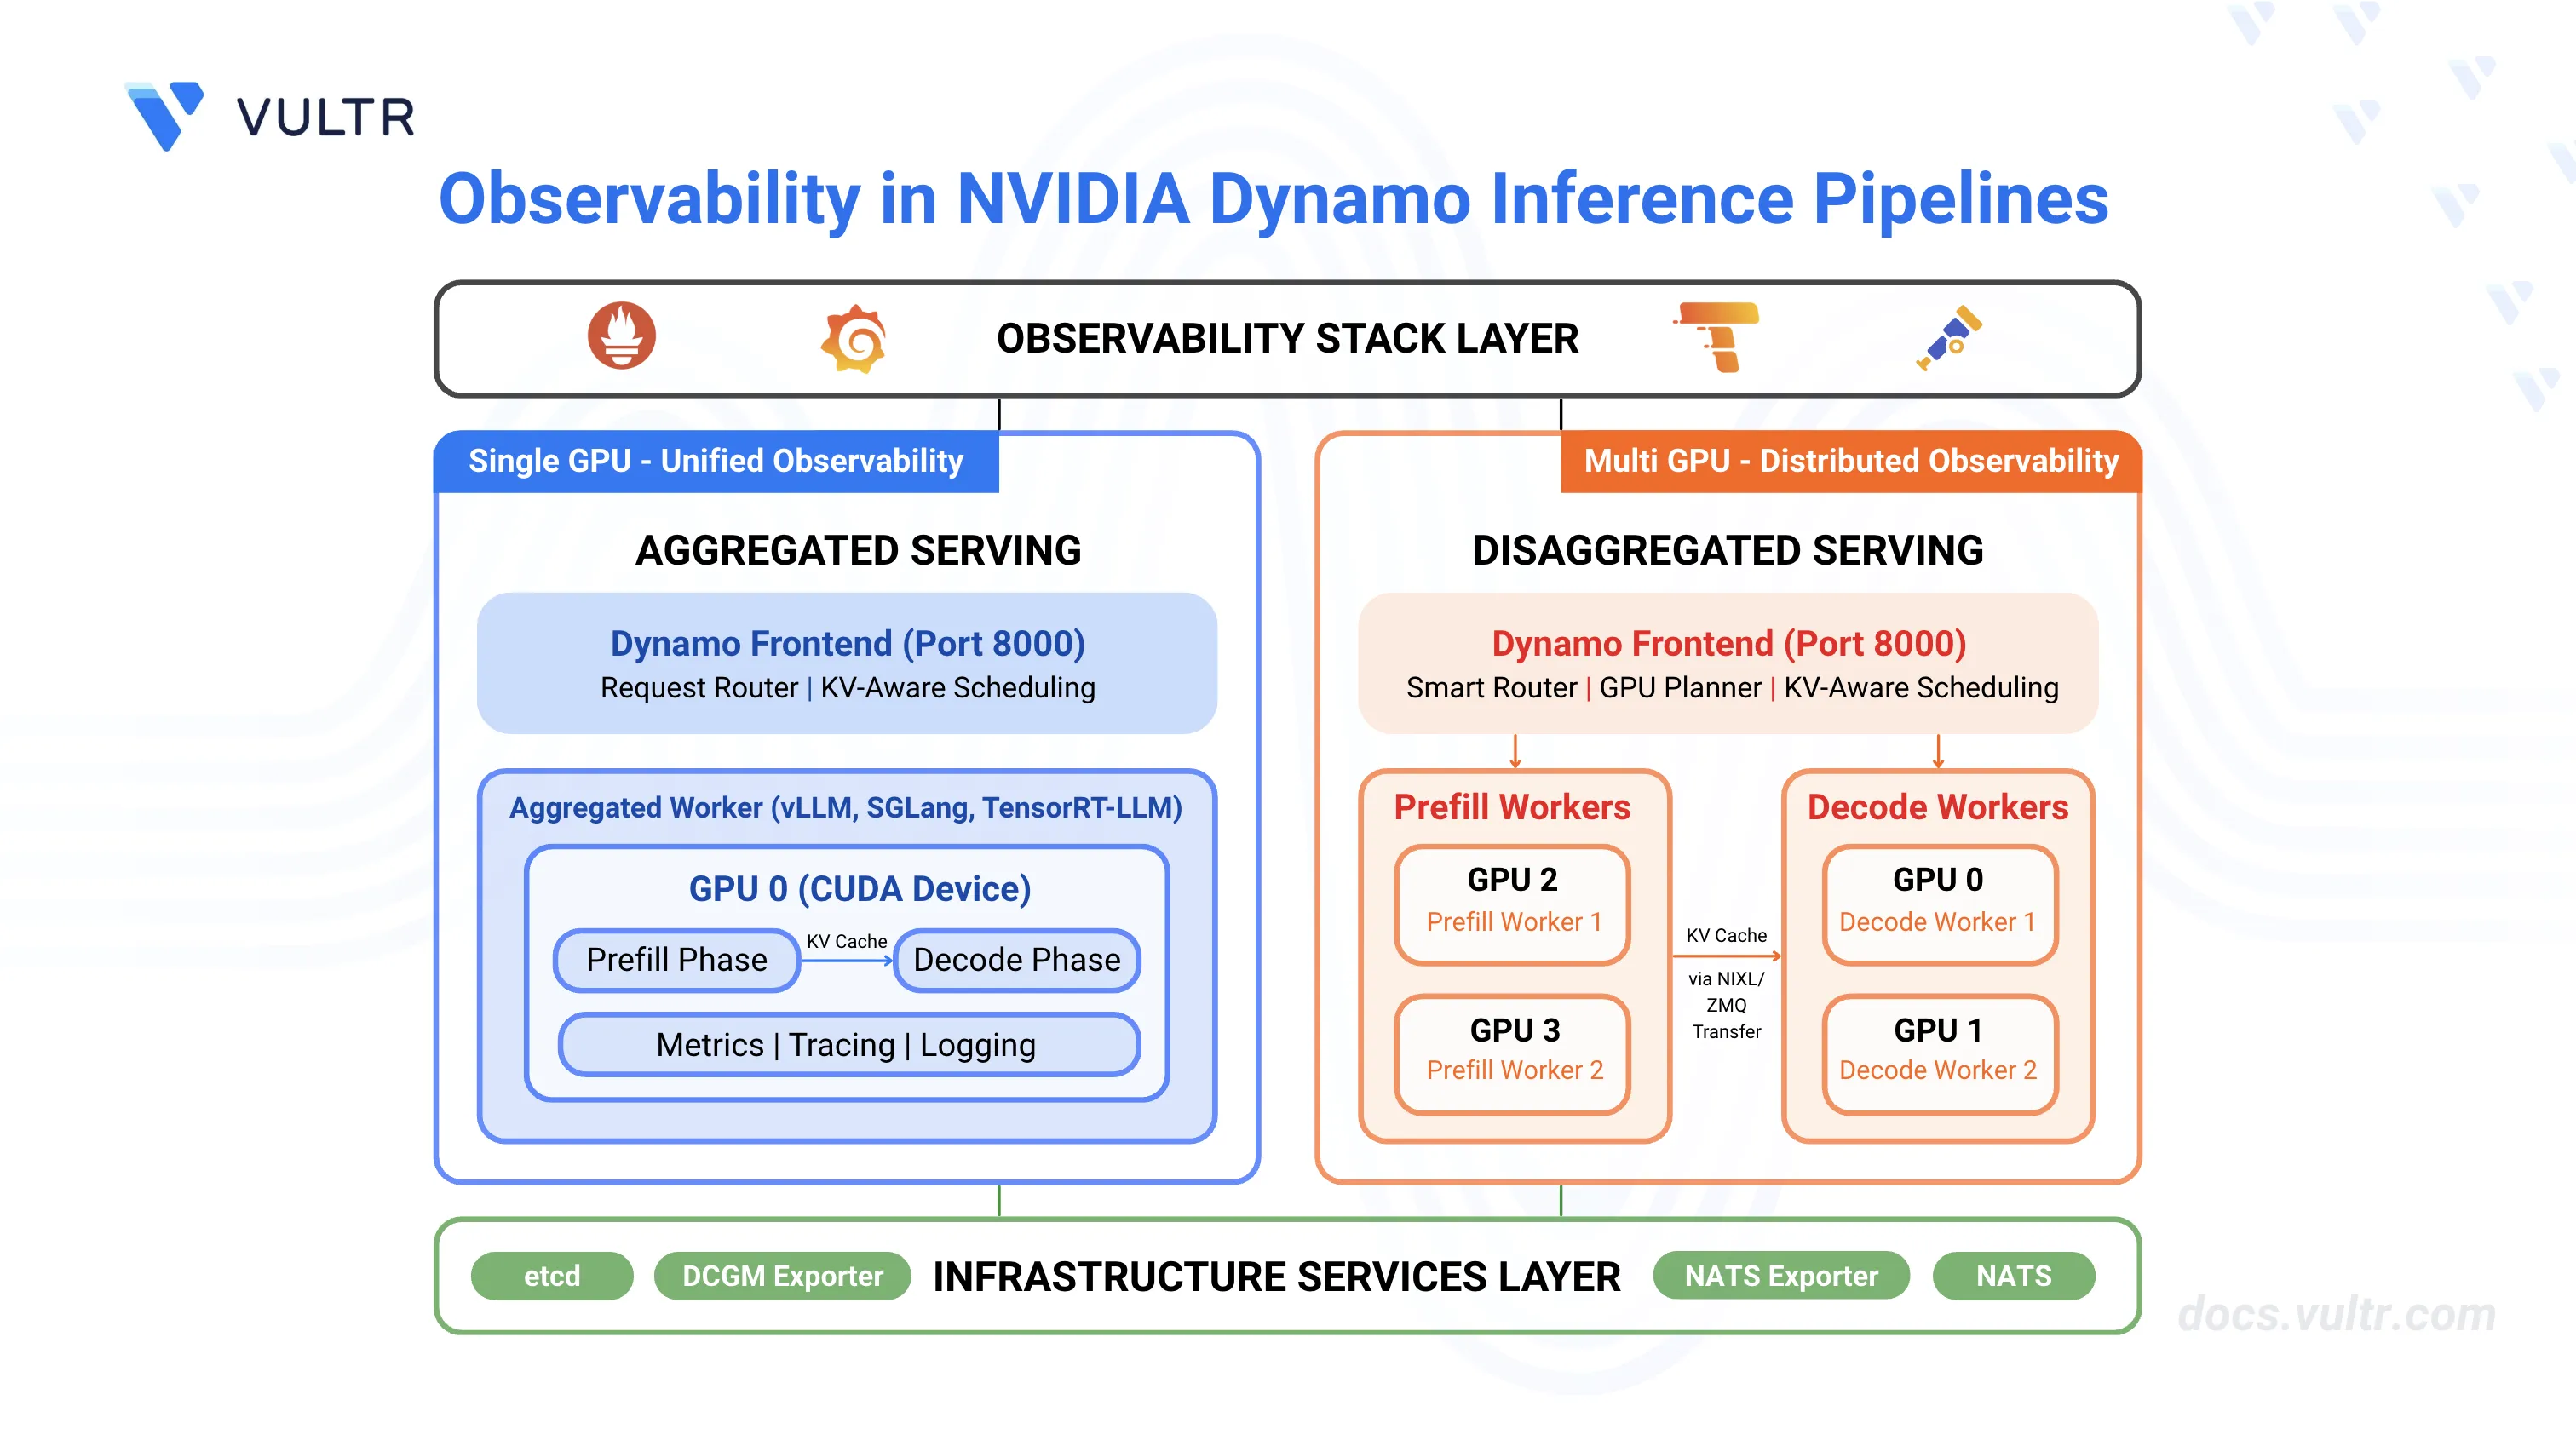
How to Enable Observability in NVIDIA Dynamo Inference Pipelines ...
Advertisement Space (336x280)
NVIDIA Dynamo Disaggregated Inference Deployment | SaaS | Run:ai ...
NVIDIA Dynamo 1.0: Disaggregated LLM Inference Deployment Guide (2026 ...

使用 NVIDIA Dynamo 部署 72B 模型提升 PD 分离性能 - NVIDIA 技术博客

NVIDIA Dynamo, A Low-Latency Distributed Inference Framework for ...
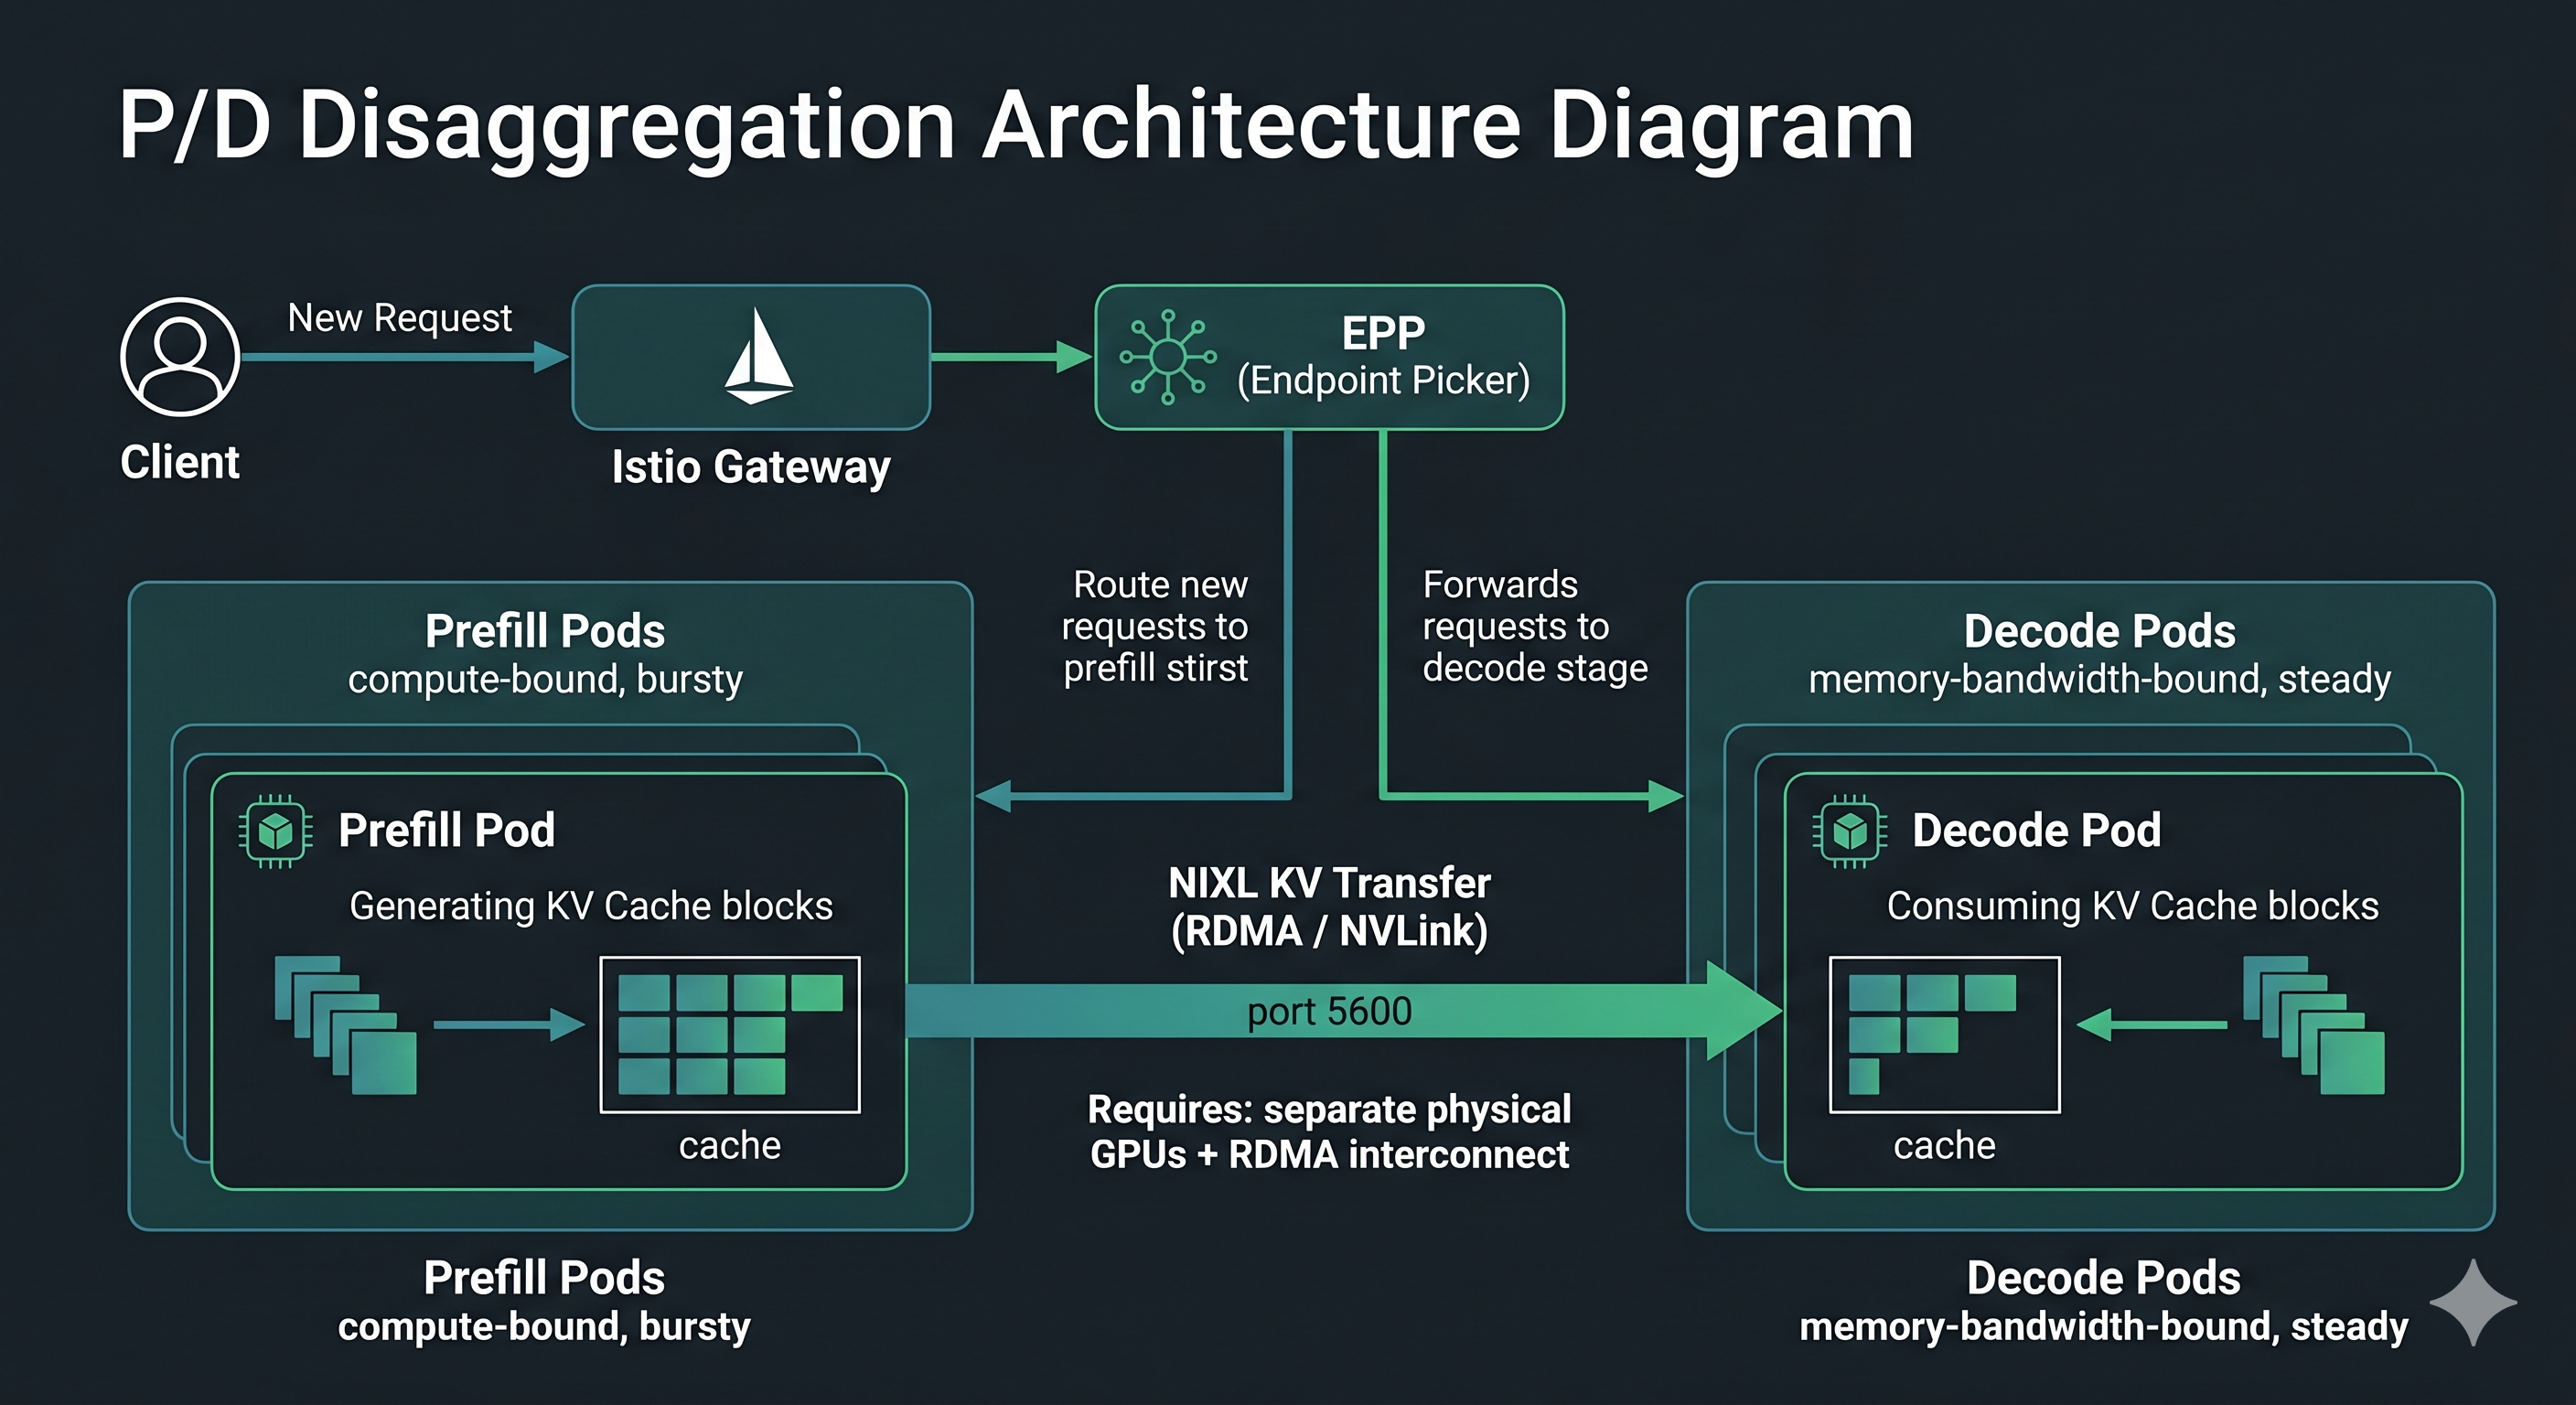
P/D Disaggregation on a Single GPU — What the Architecture Actually ...
NVIDIA Dynamo: Turning Disaggregated Inference Into a Production System ...