
How To Deploy Inference Using Nvidia Dynamo And Tensorrt Llm Vultr Docs
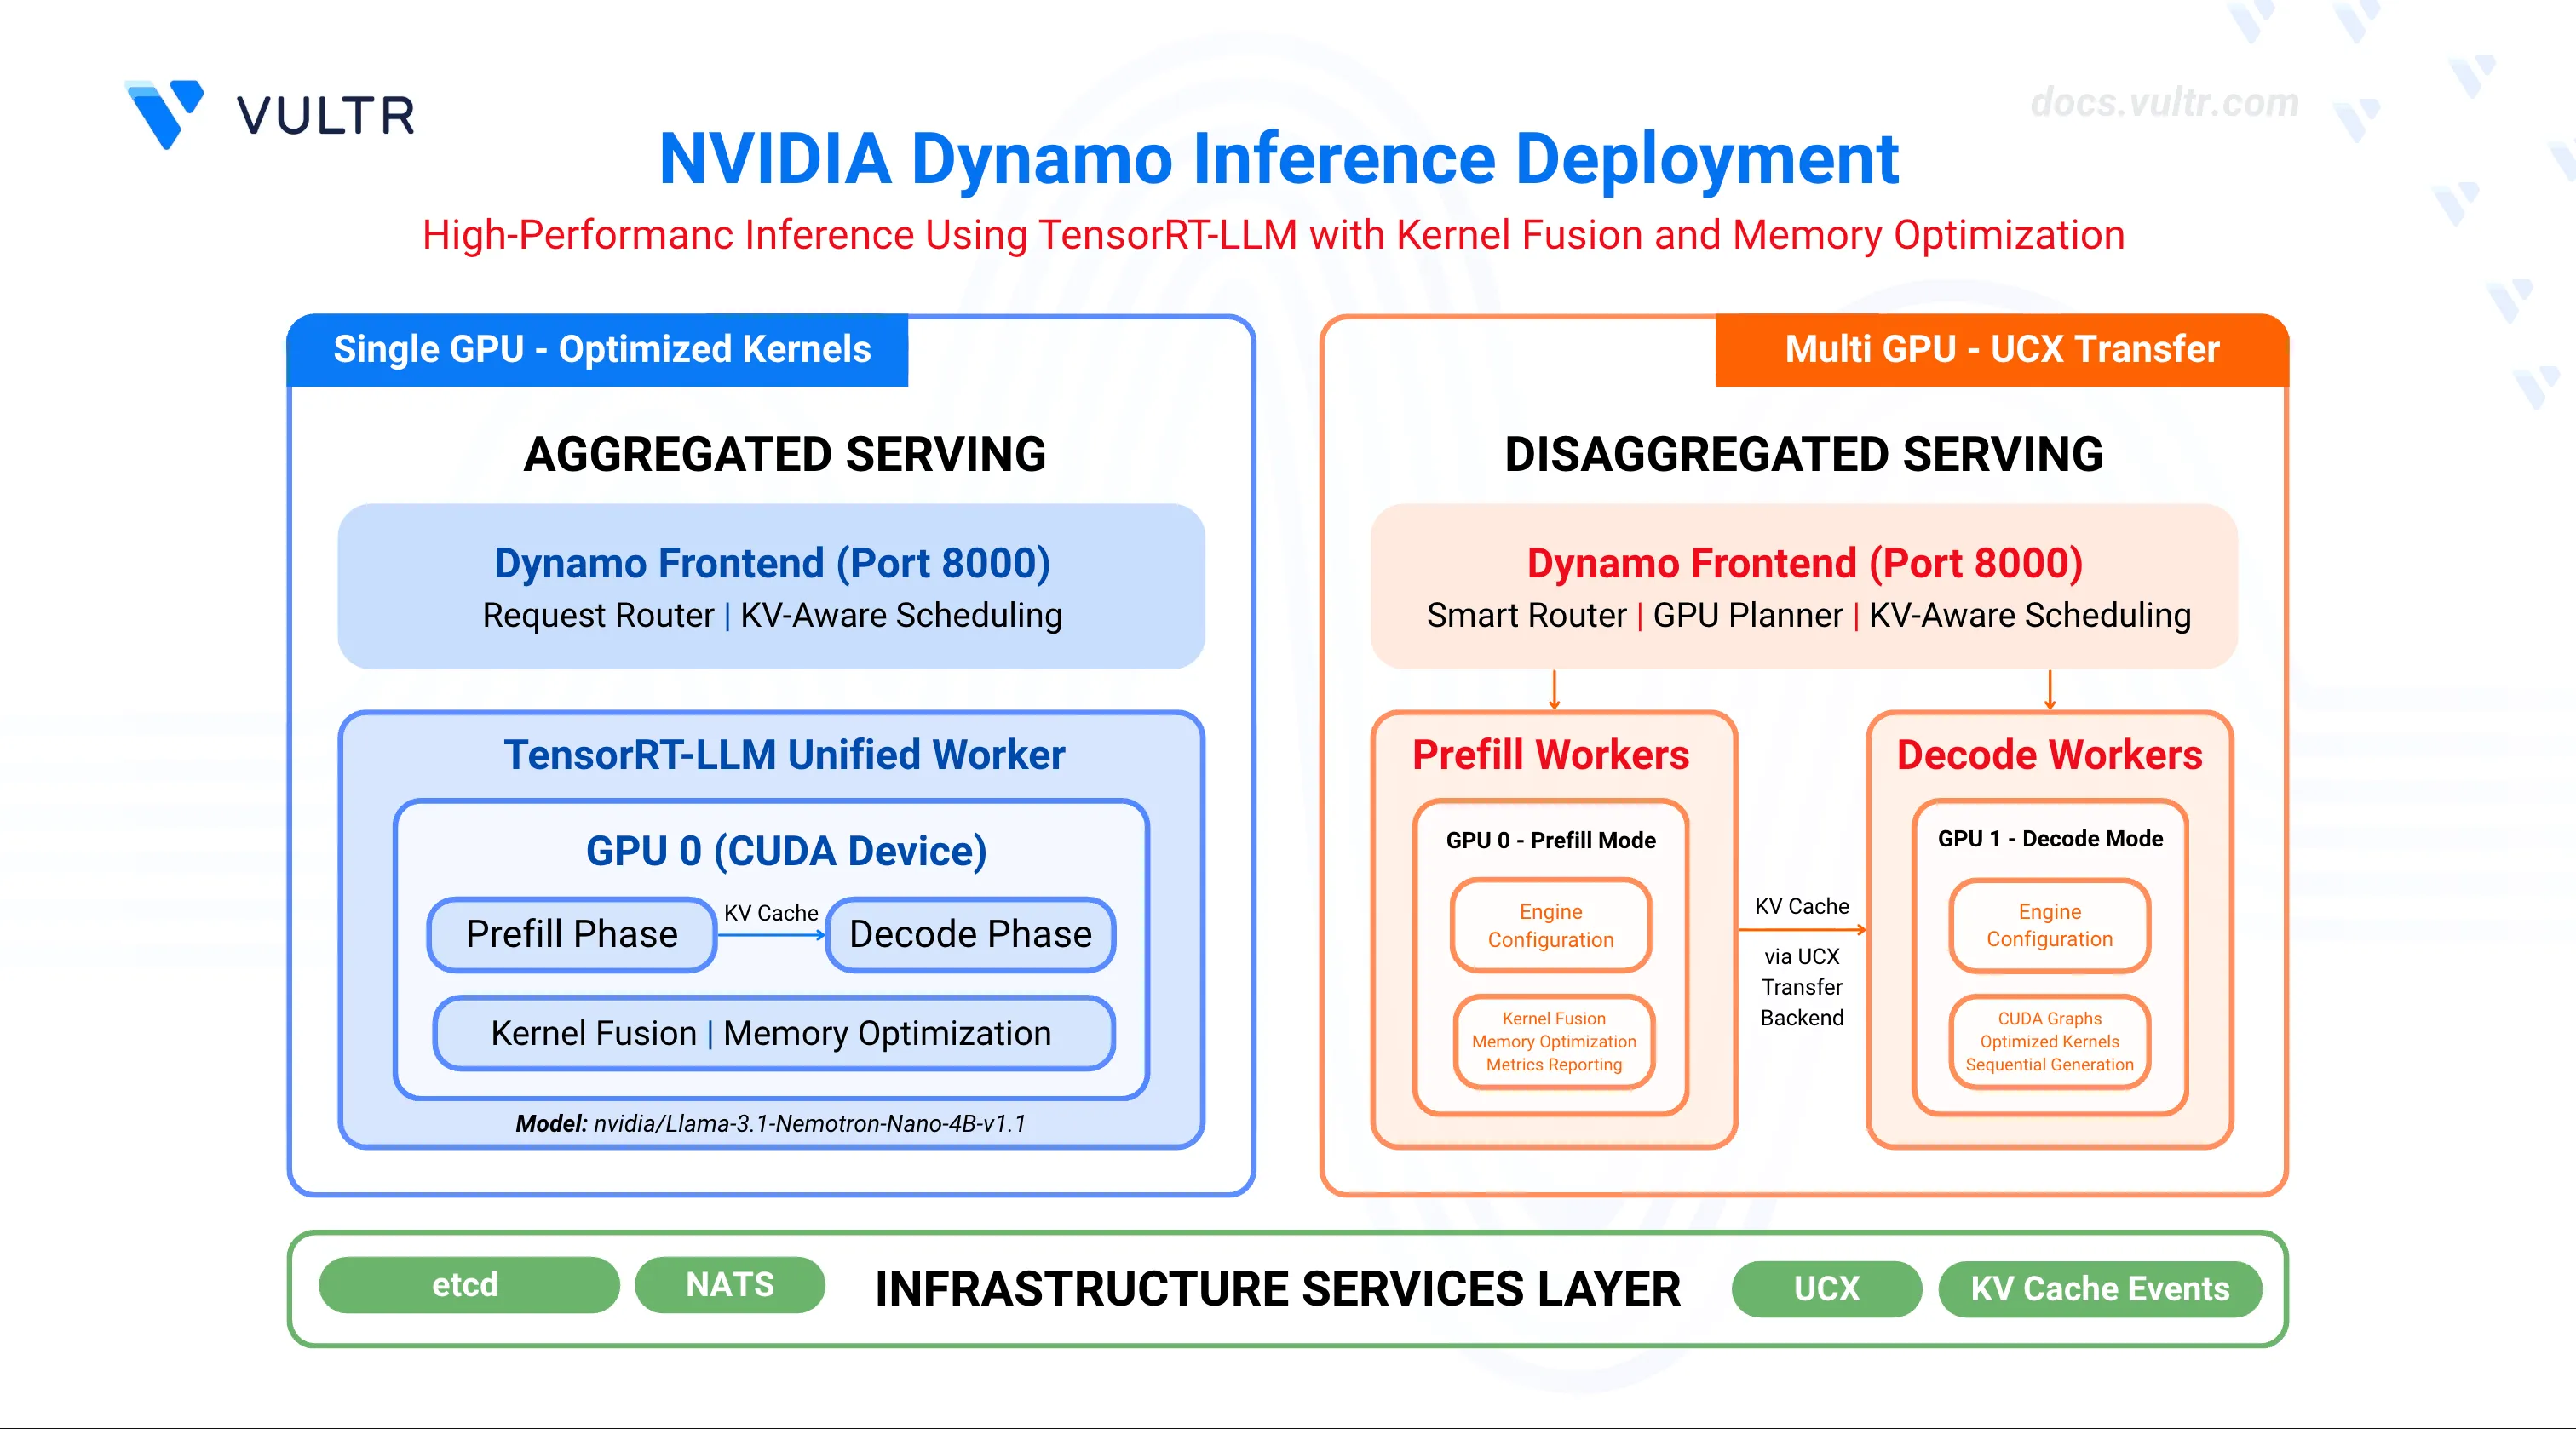
How to Deploy Inference Using NVIDIA Dynamo and TensorRT-LLM | Vultr Docs
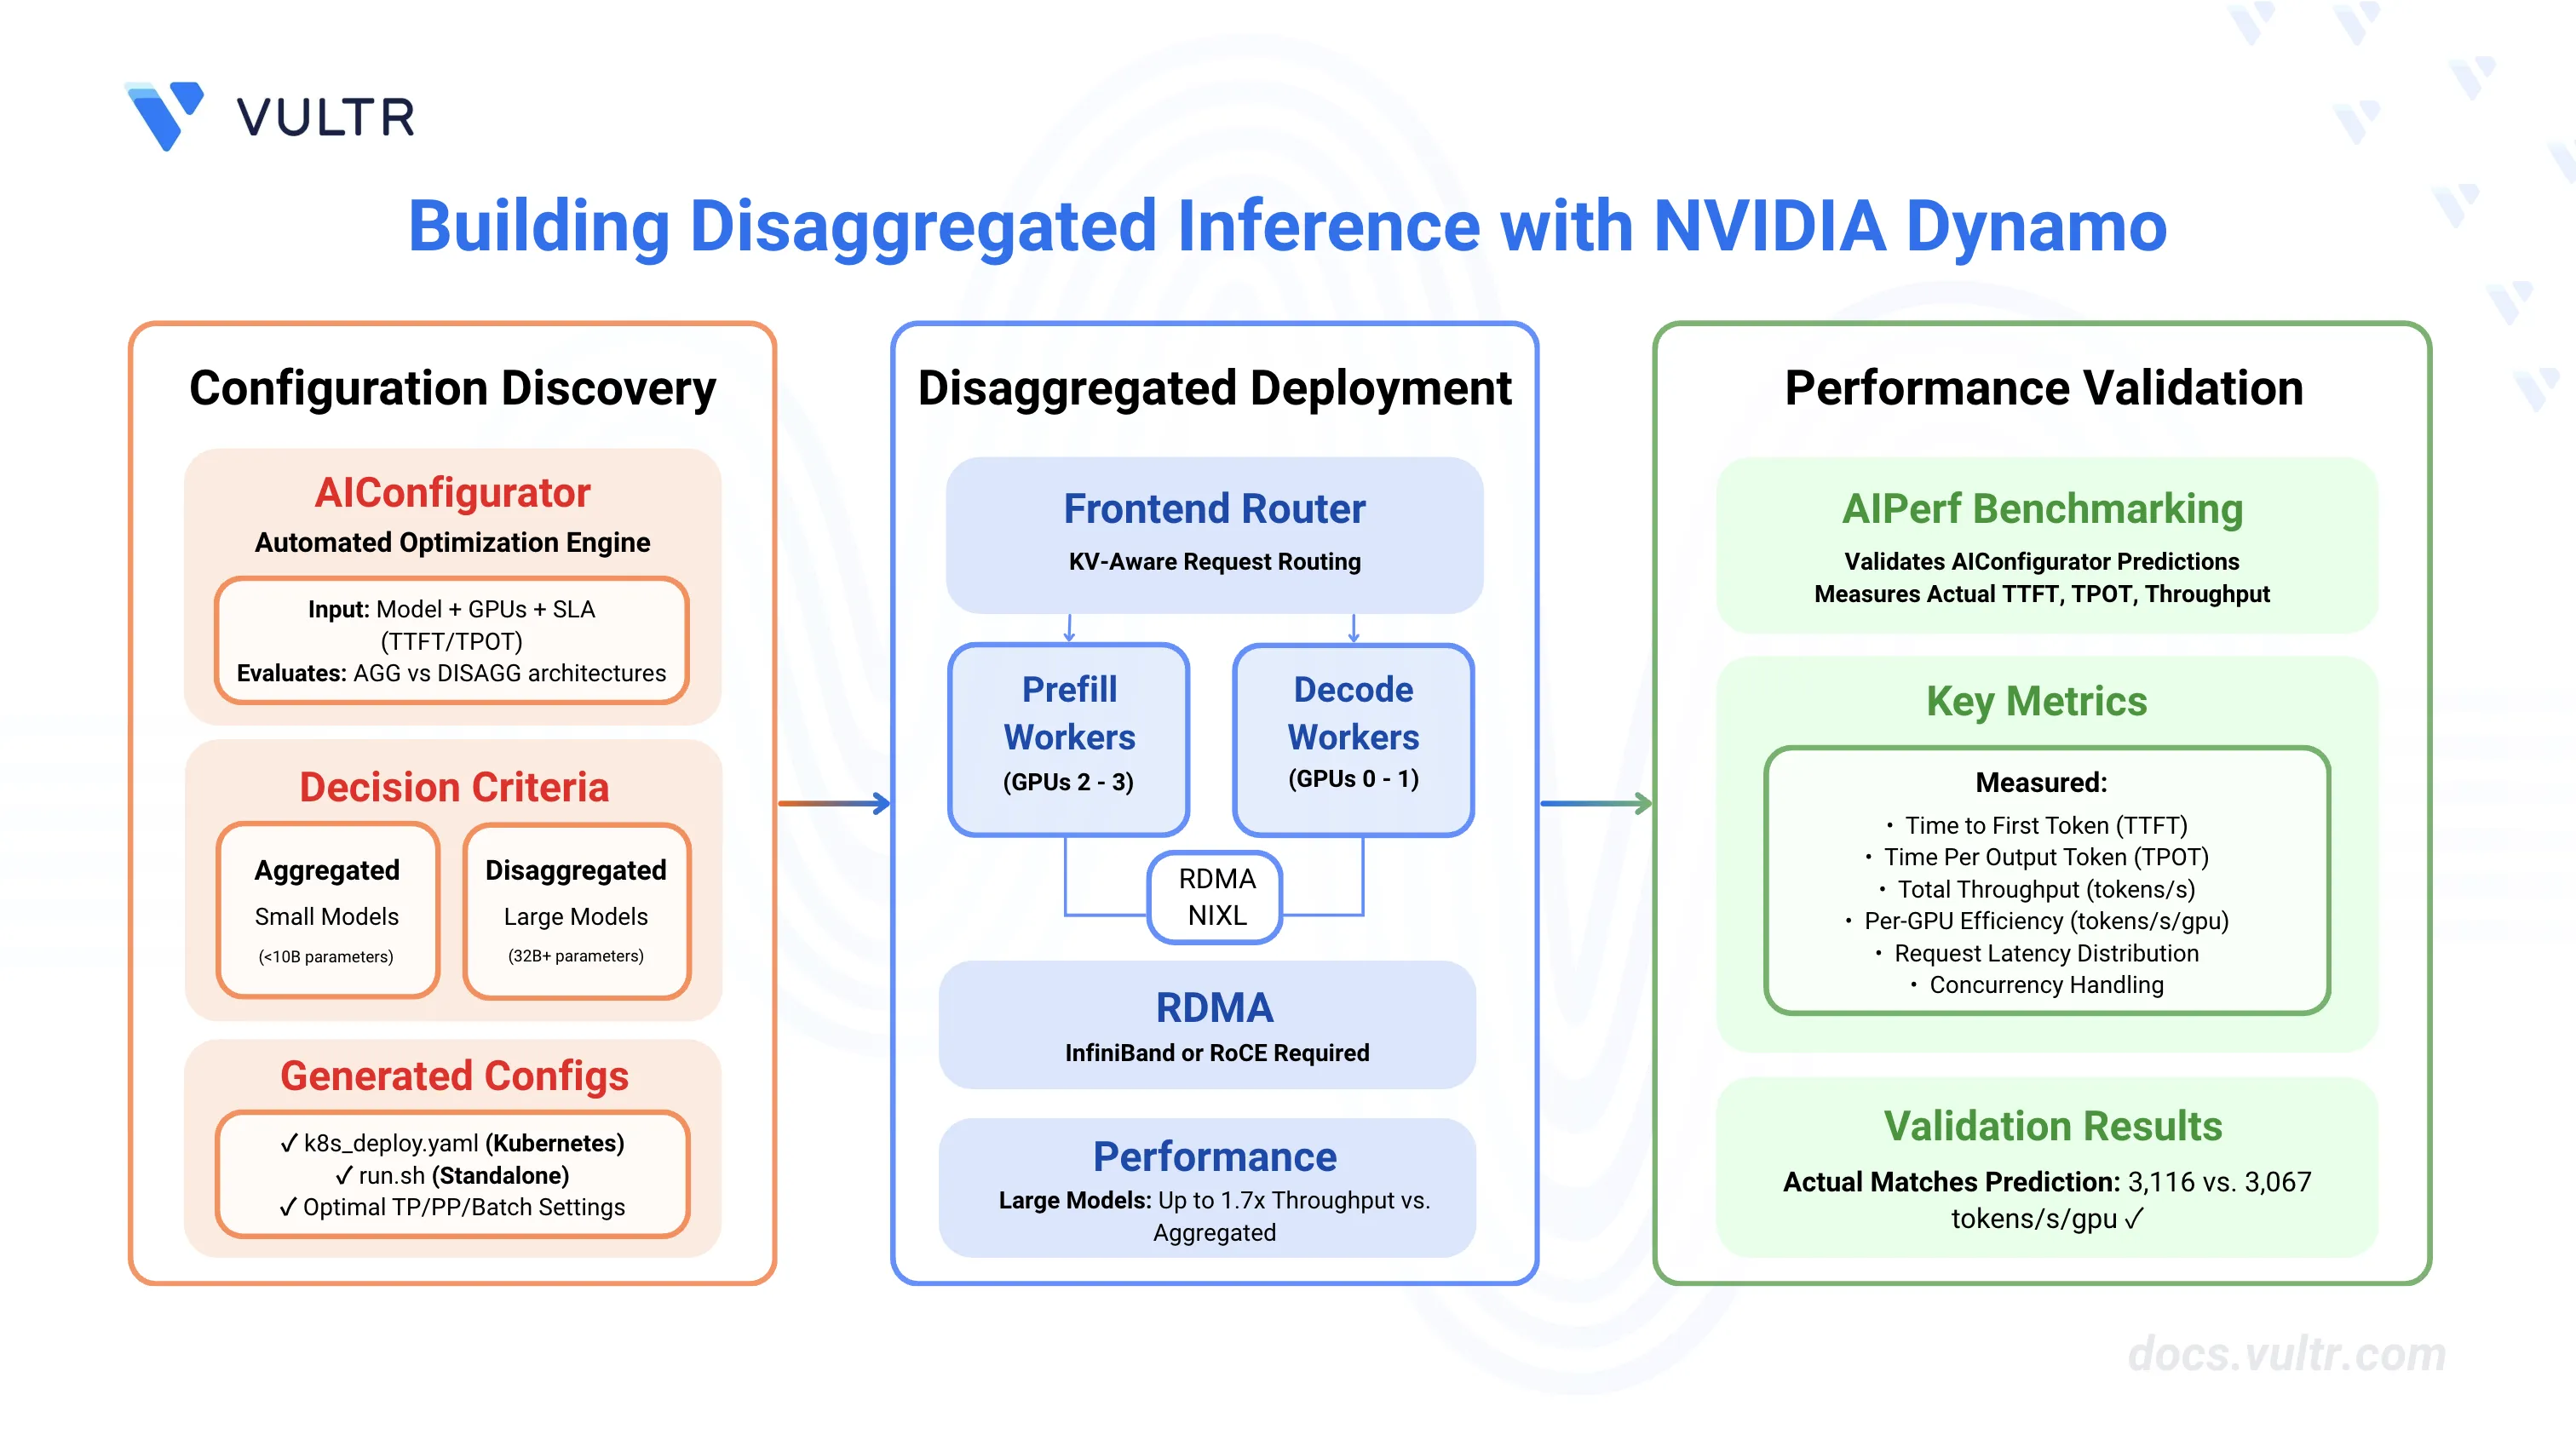
How to Build Disaggregated Inference with NVIDIA Dynamo | Vultr Docs
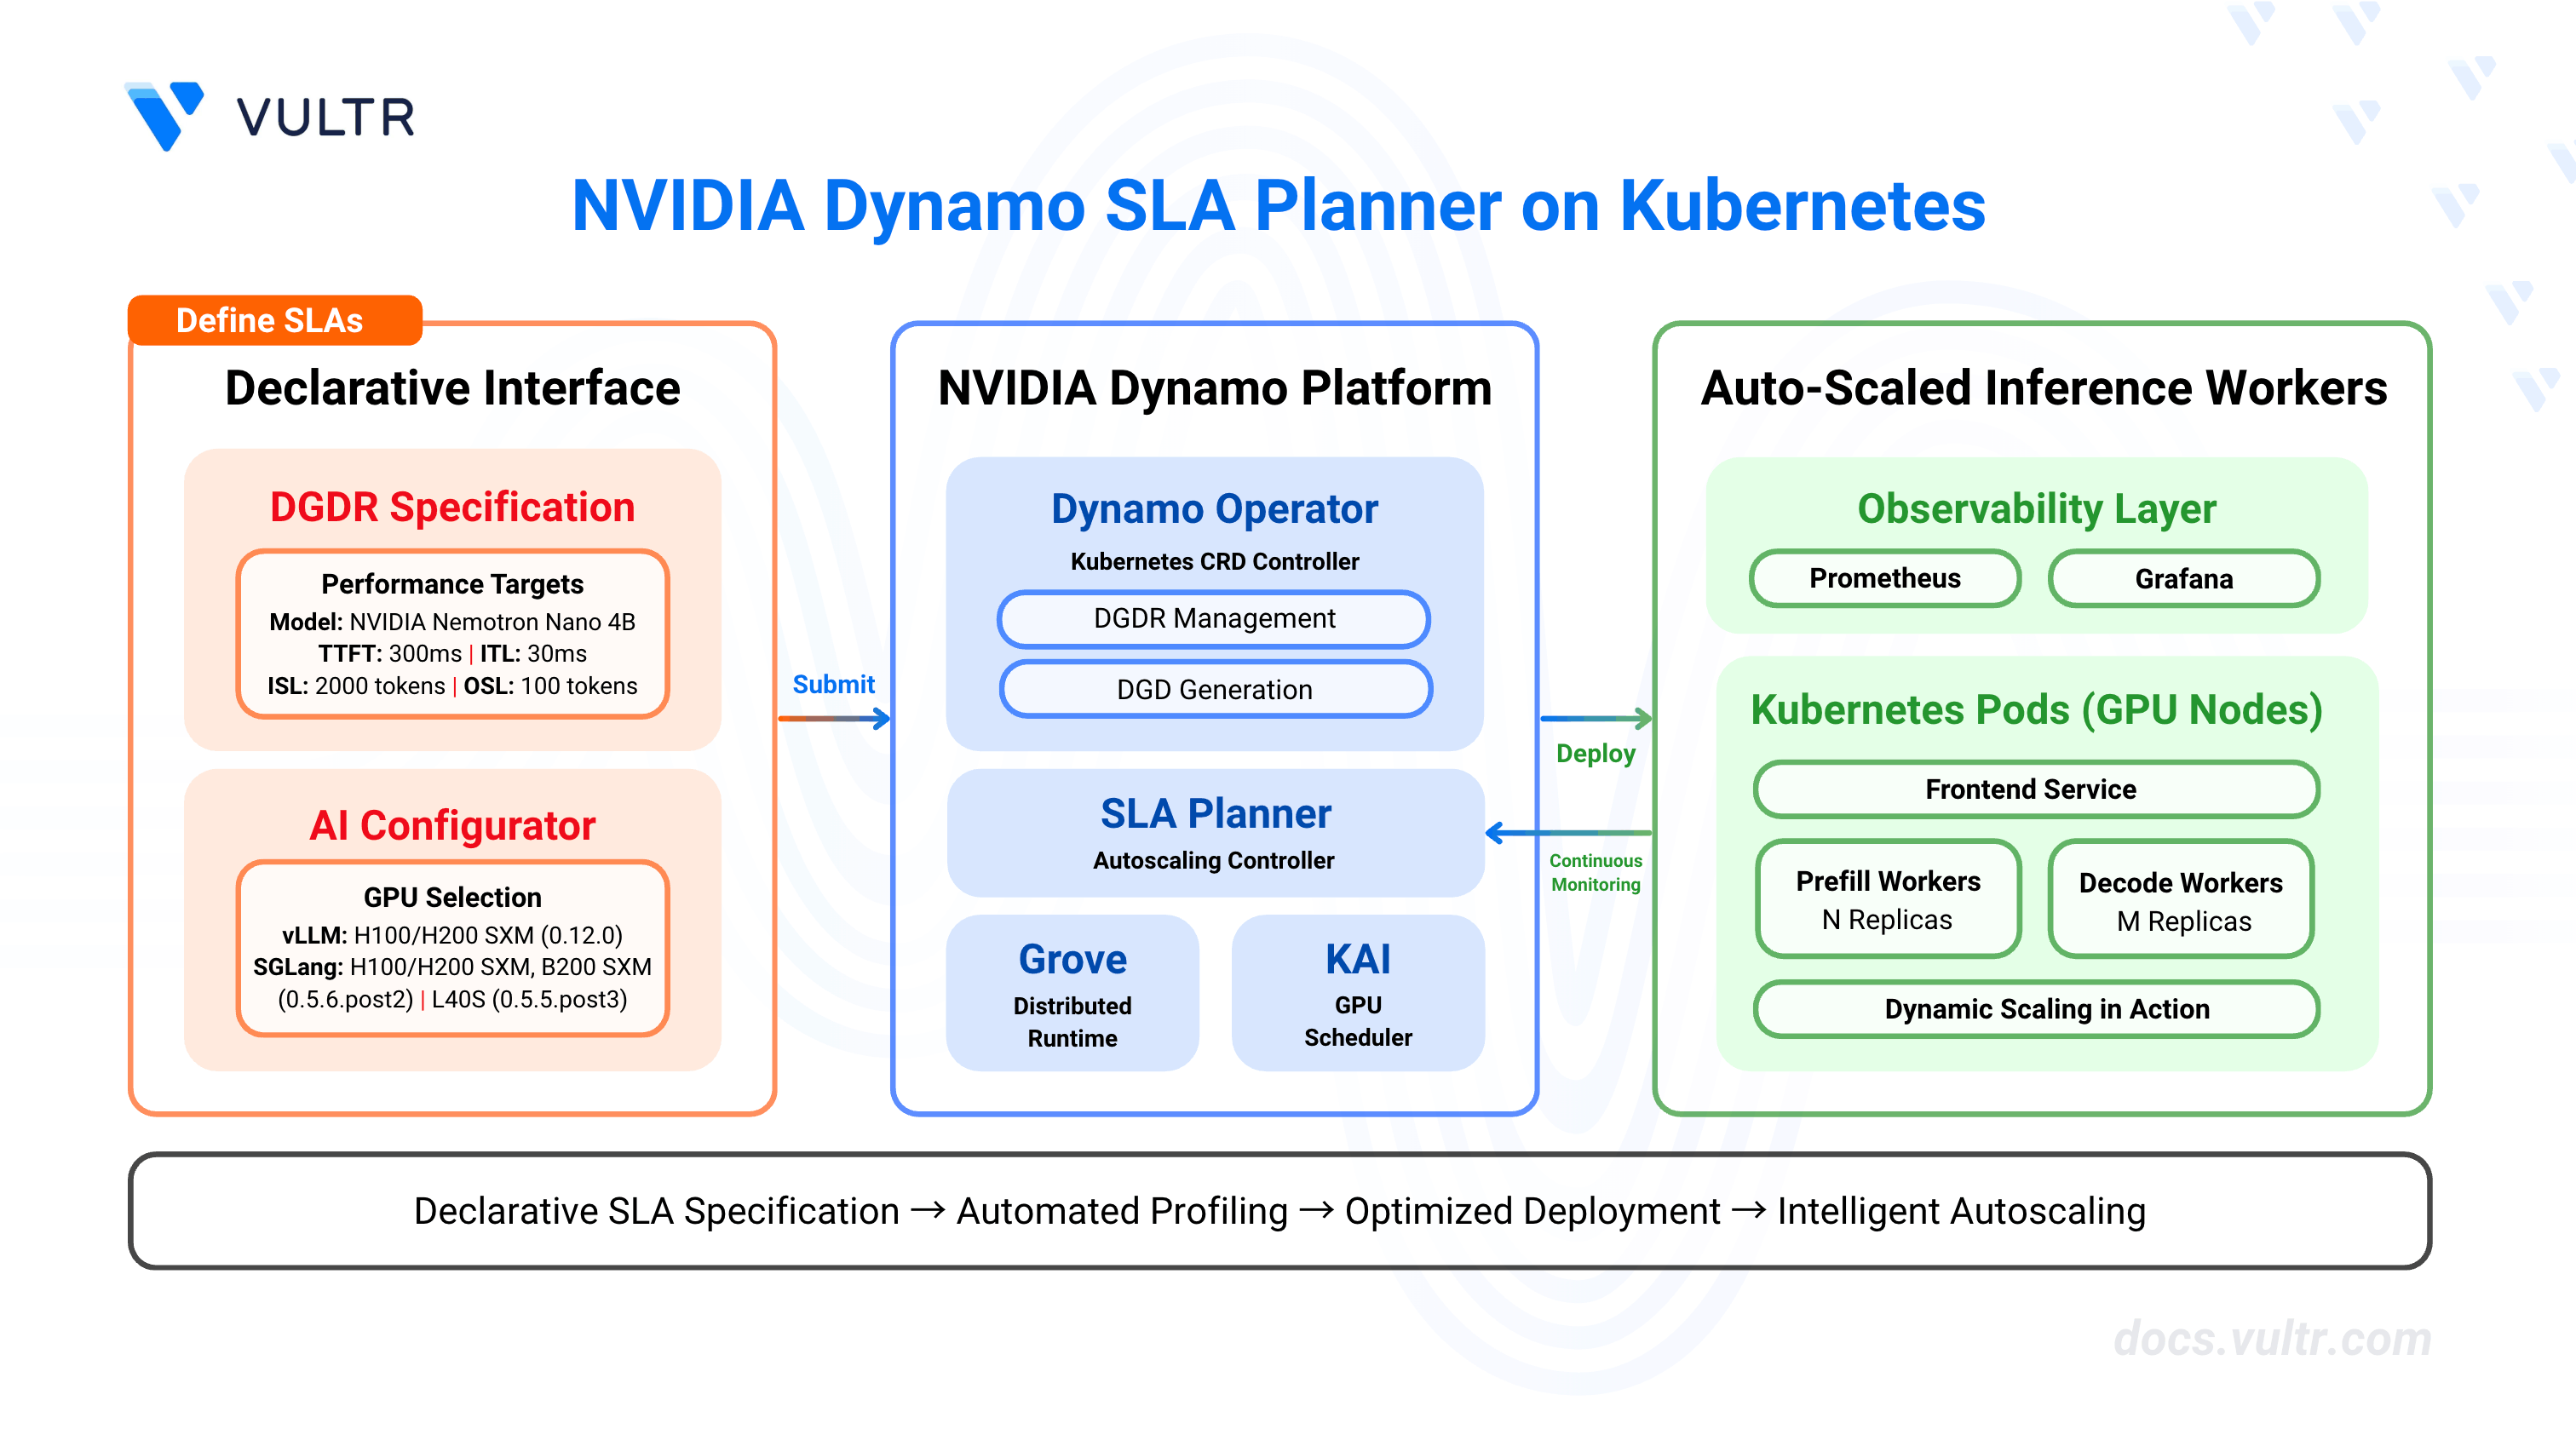
How to Optimize GPU Resource Planning with NVIDIA Dynamo | Vultr Docs
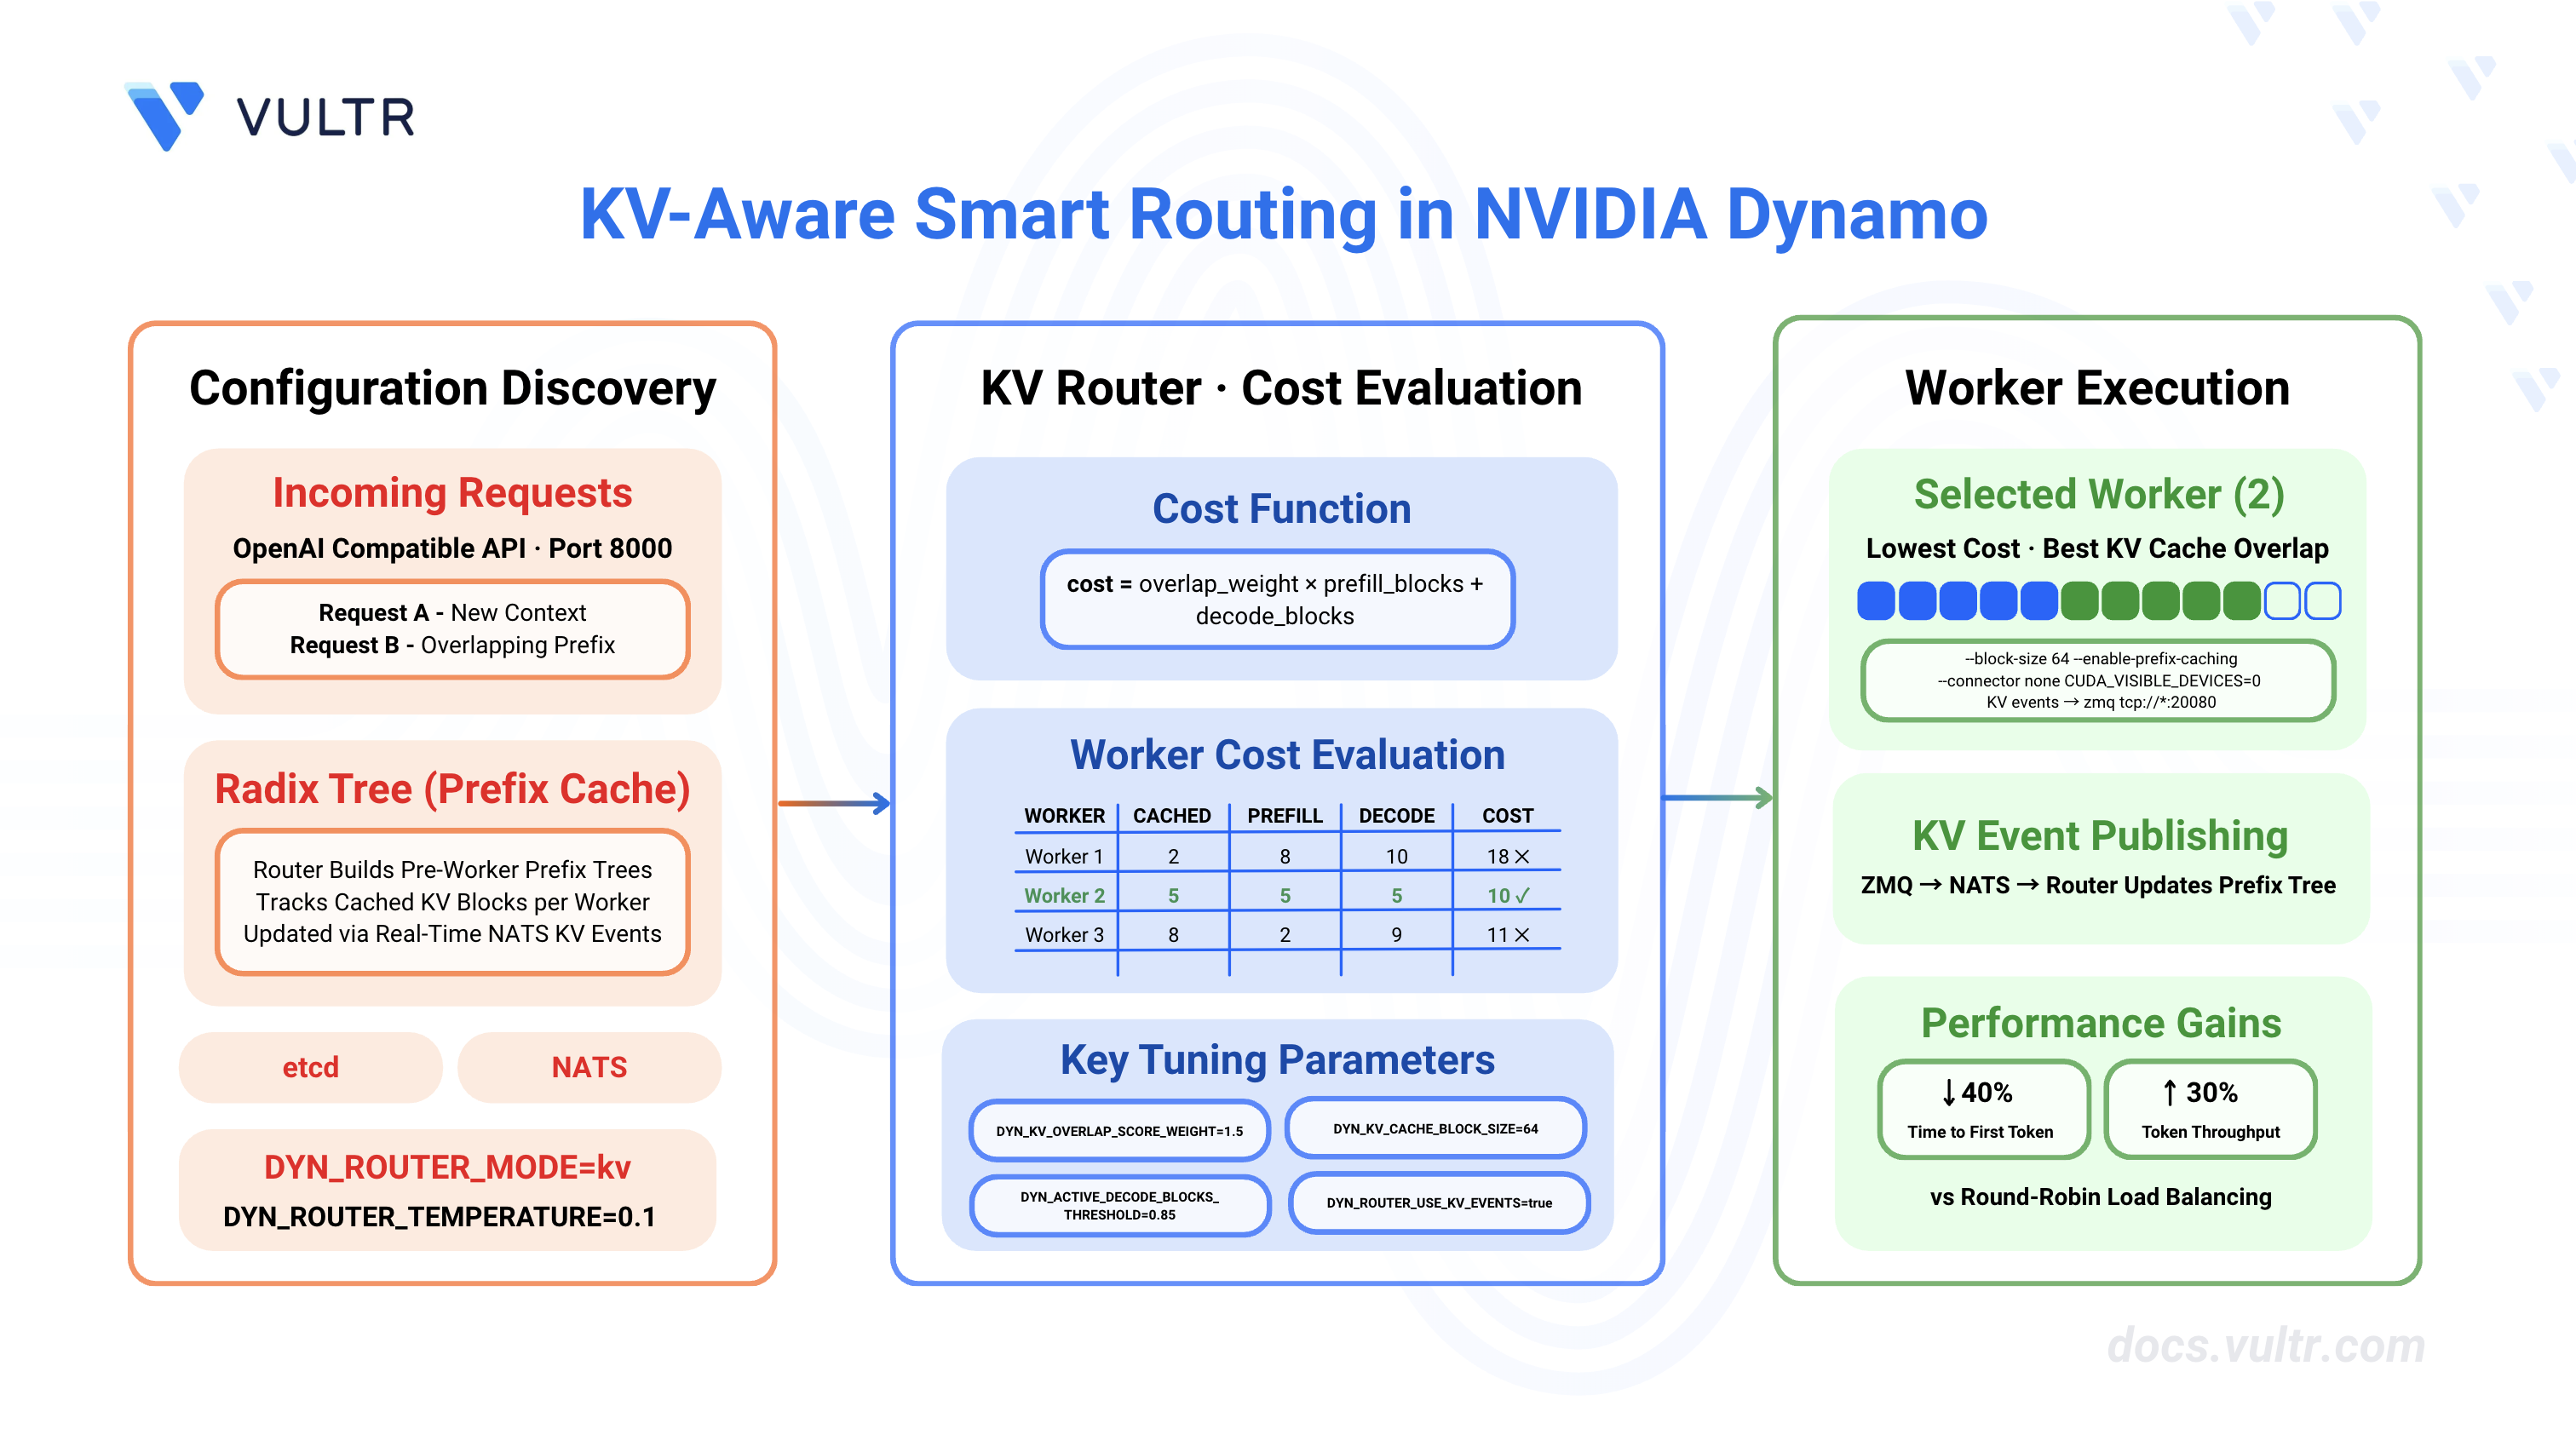
How to Configure Smart Routing in NVIDIA Dynamo | Vultr Docs
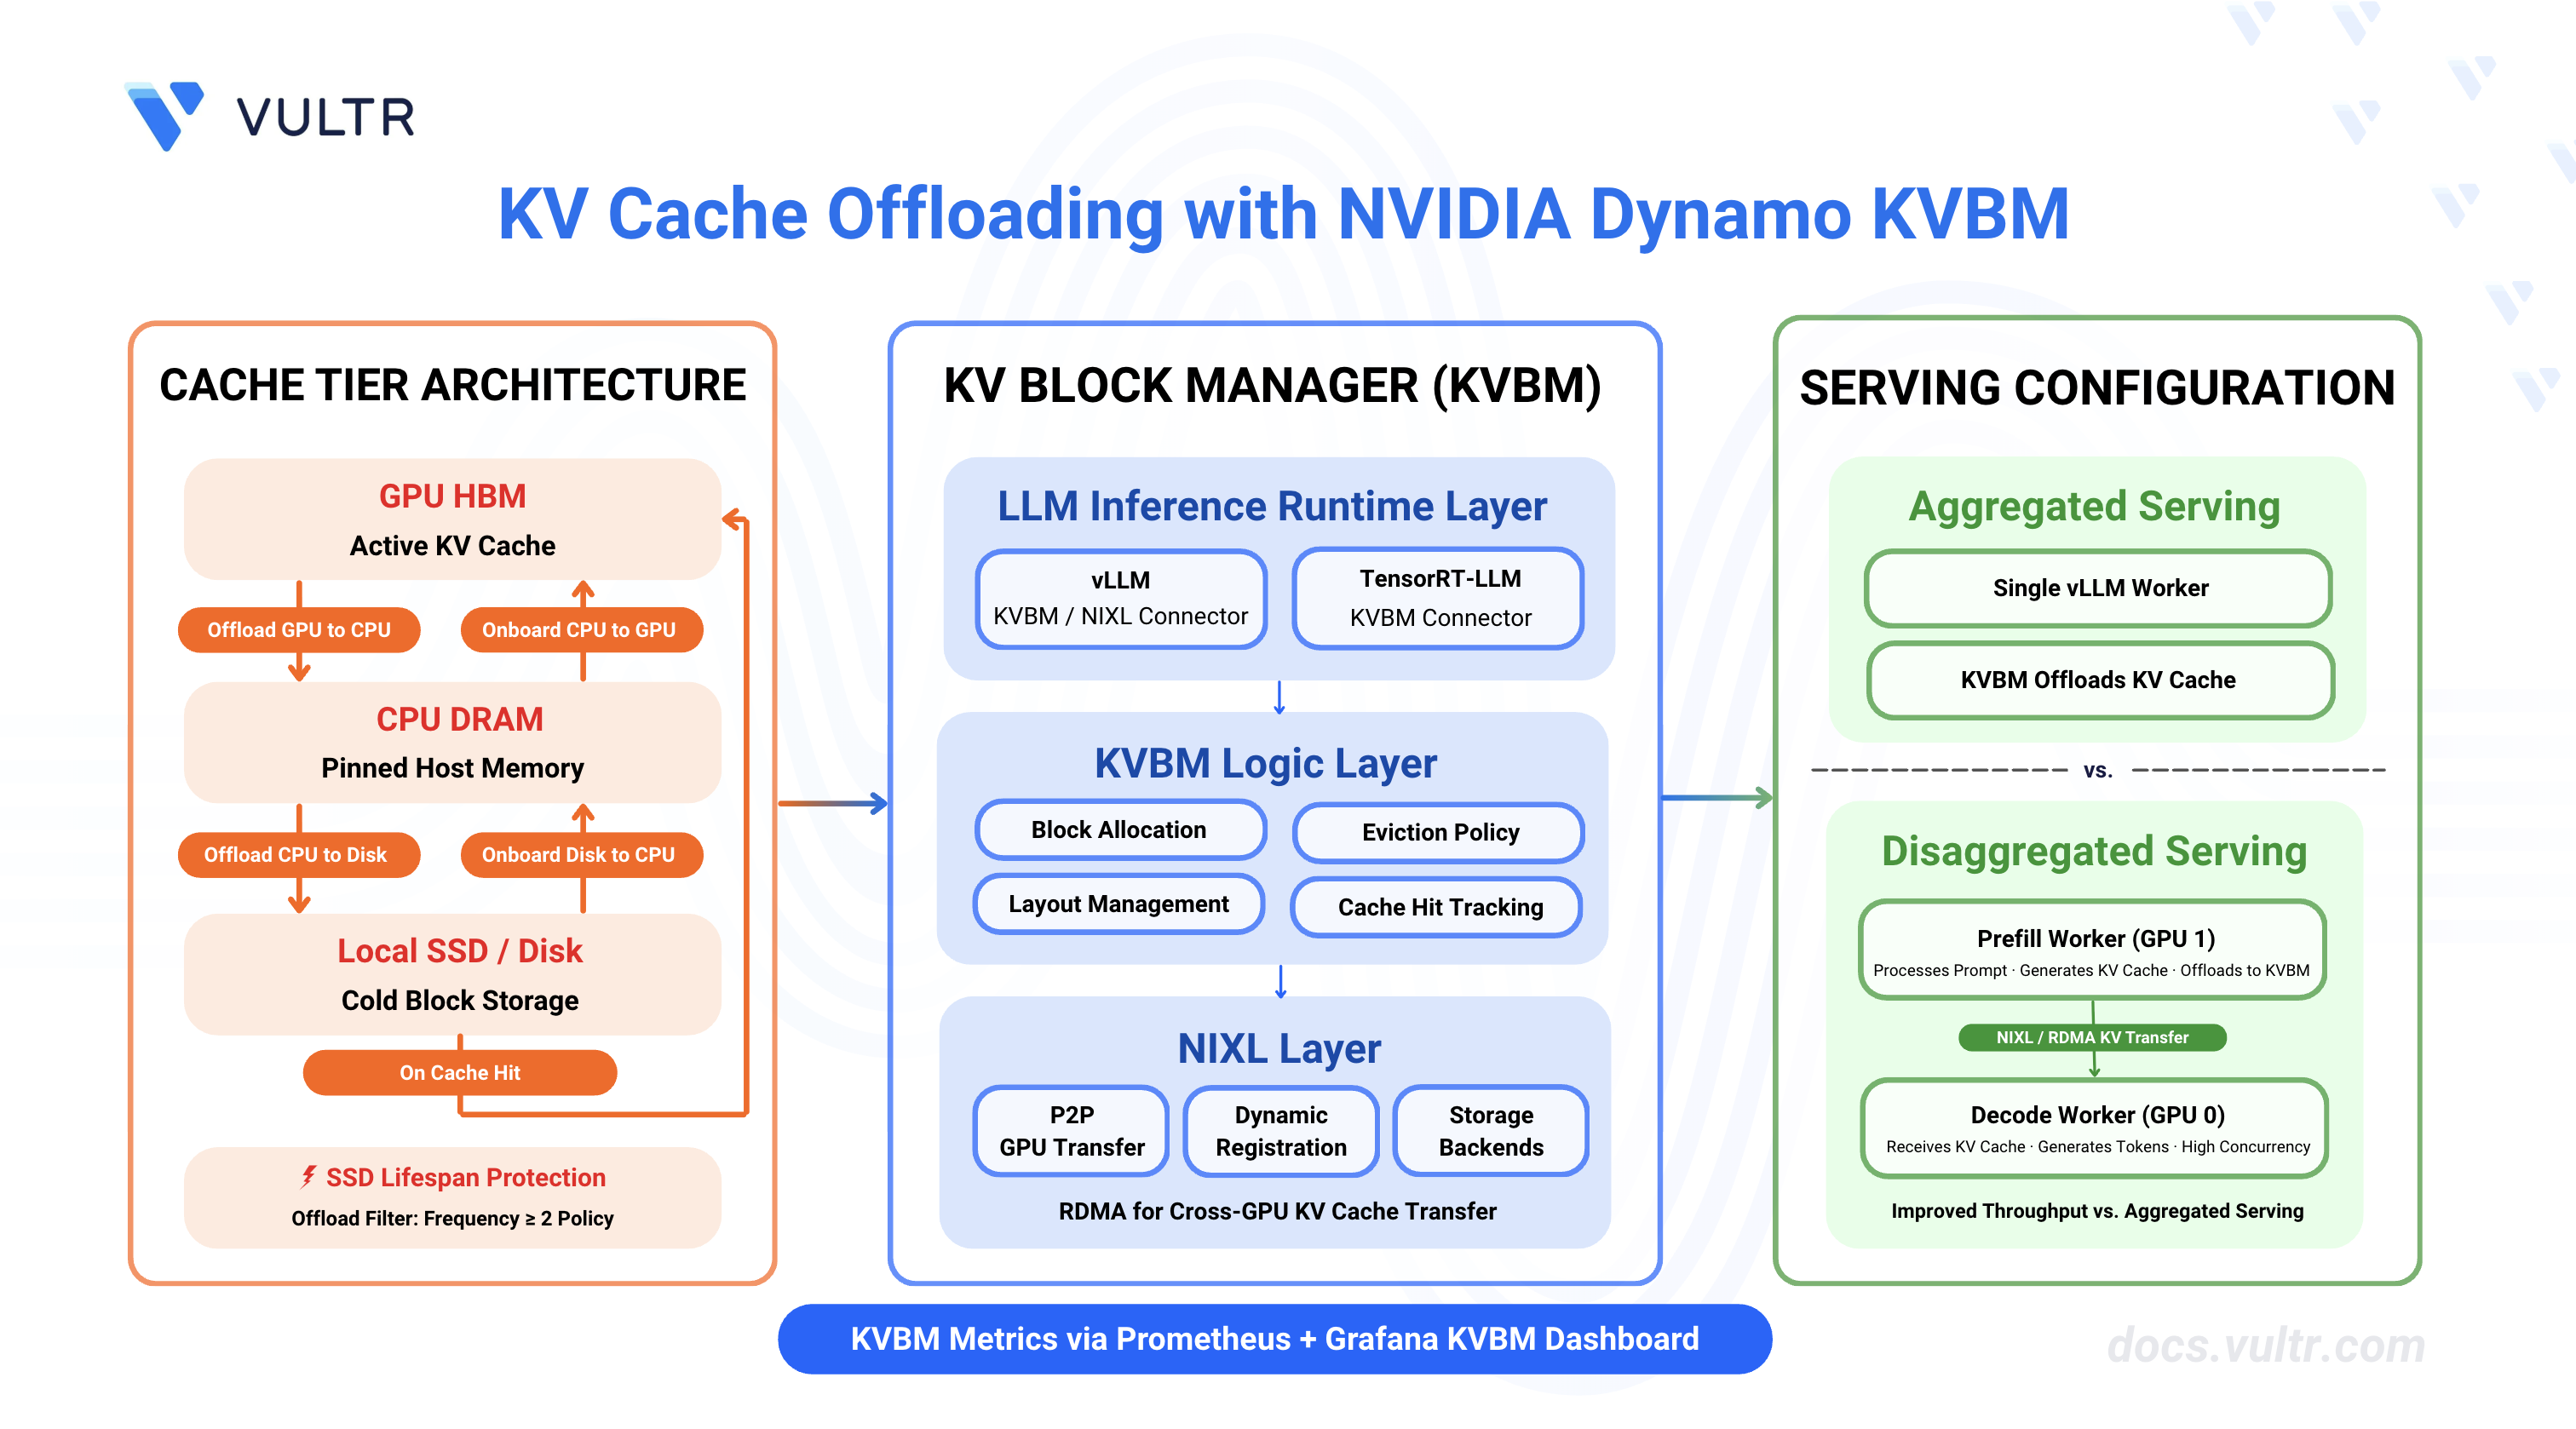
How to Manage KV Cache in NVIDIA Dynamo | Vultr Docs
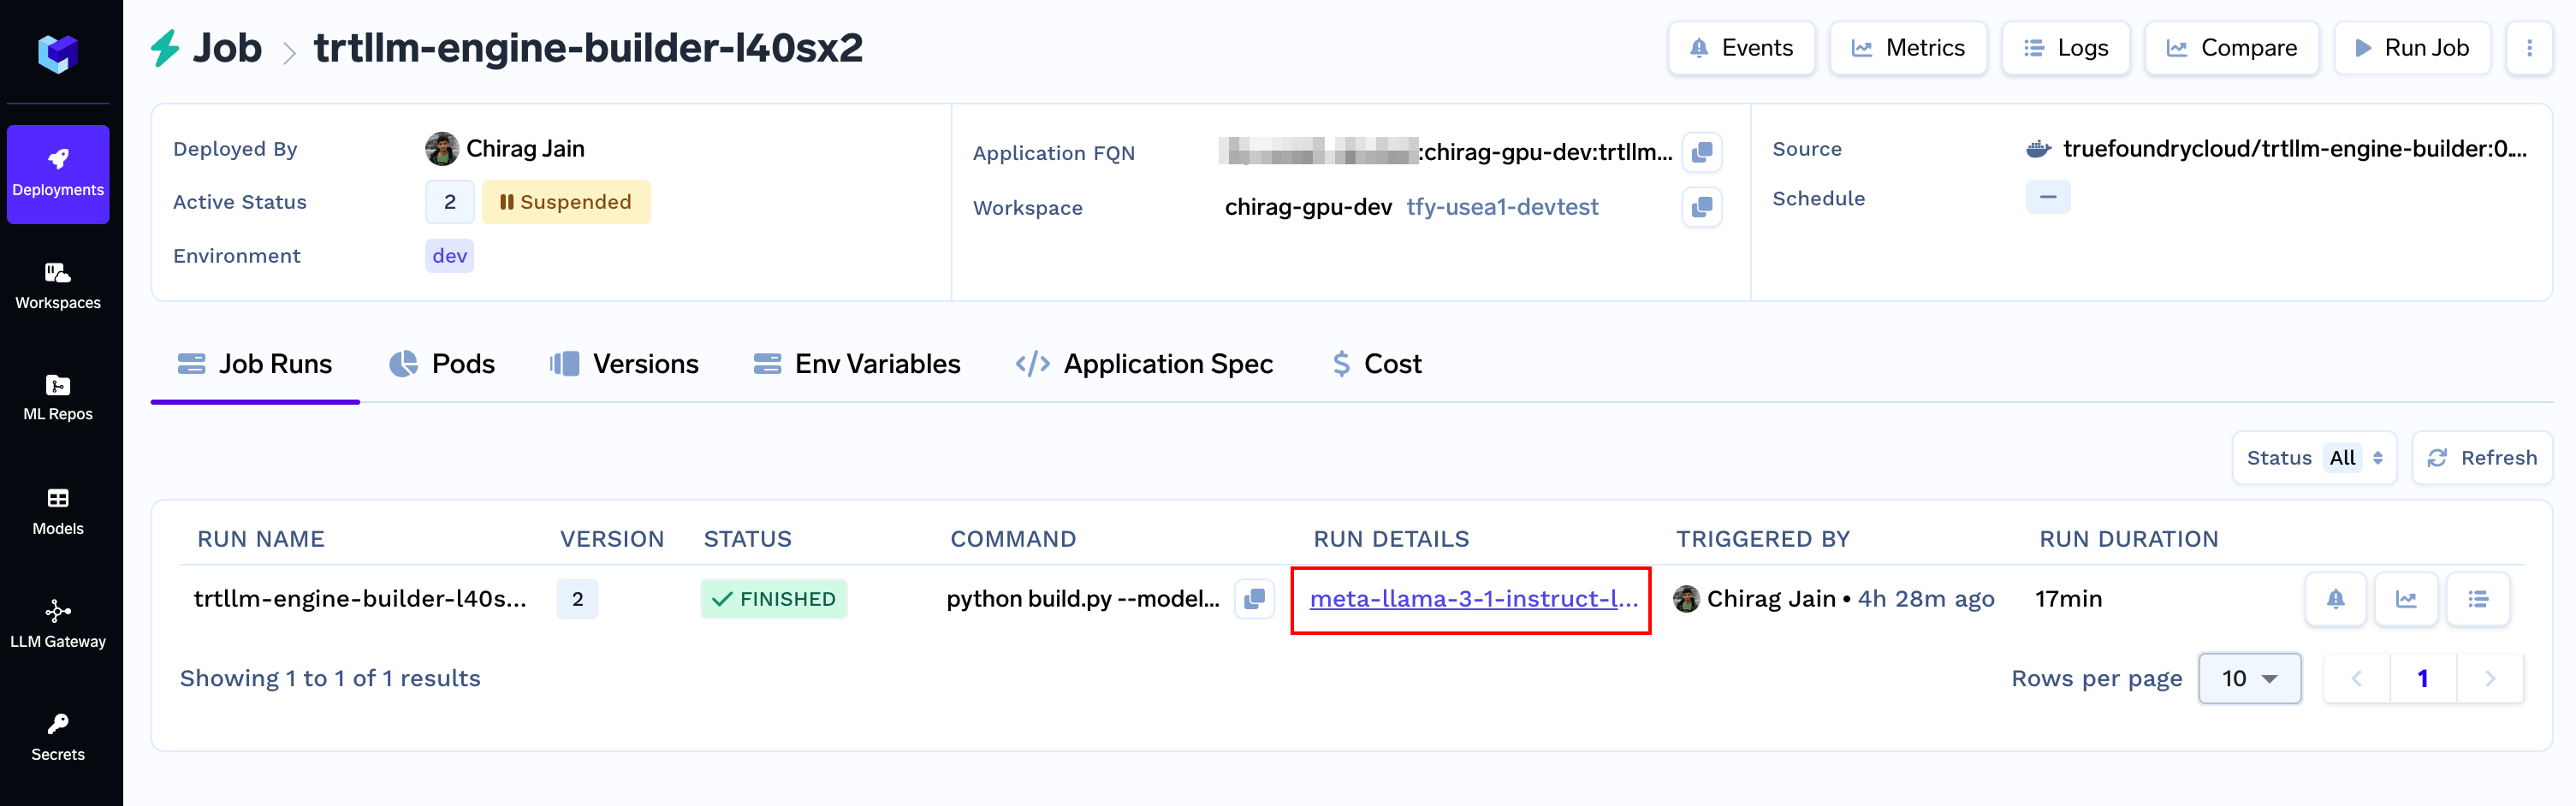
Deploy LLMs using Nvidia TensorRT LLM (TRT LLM) - TrueFoundry Docs
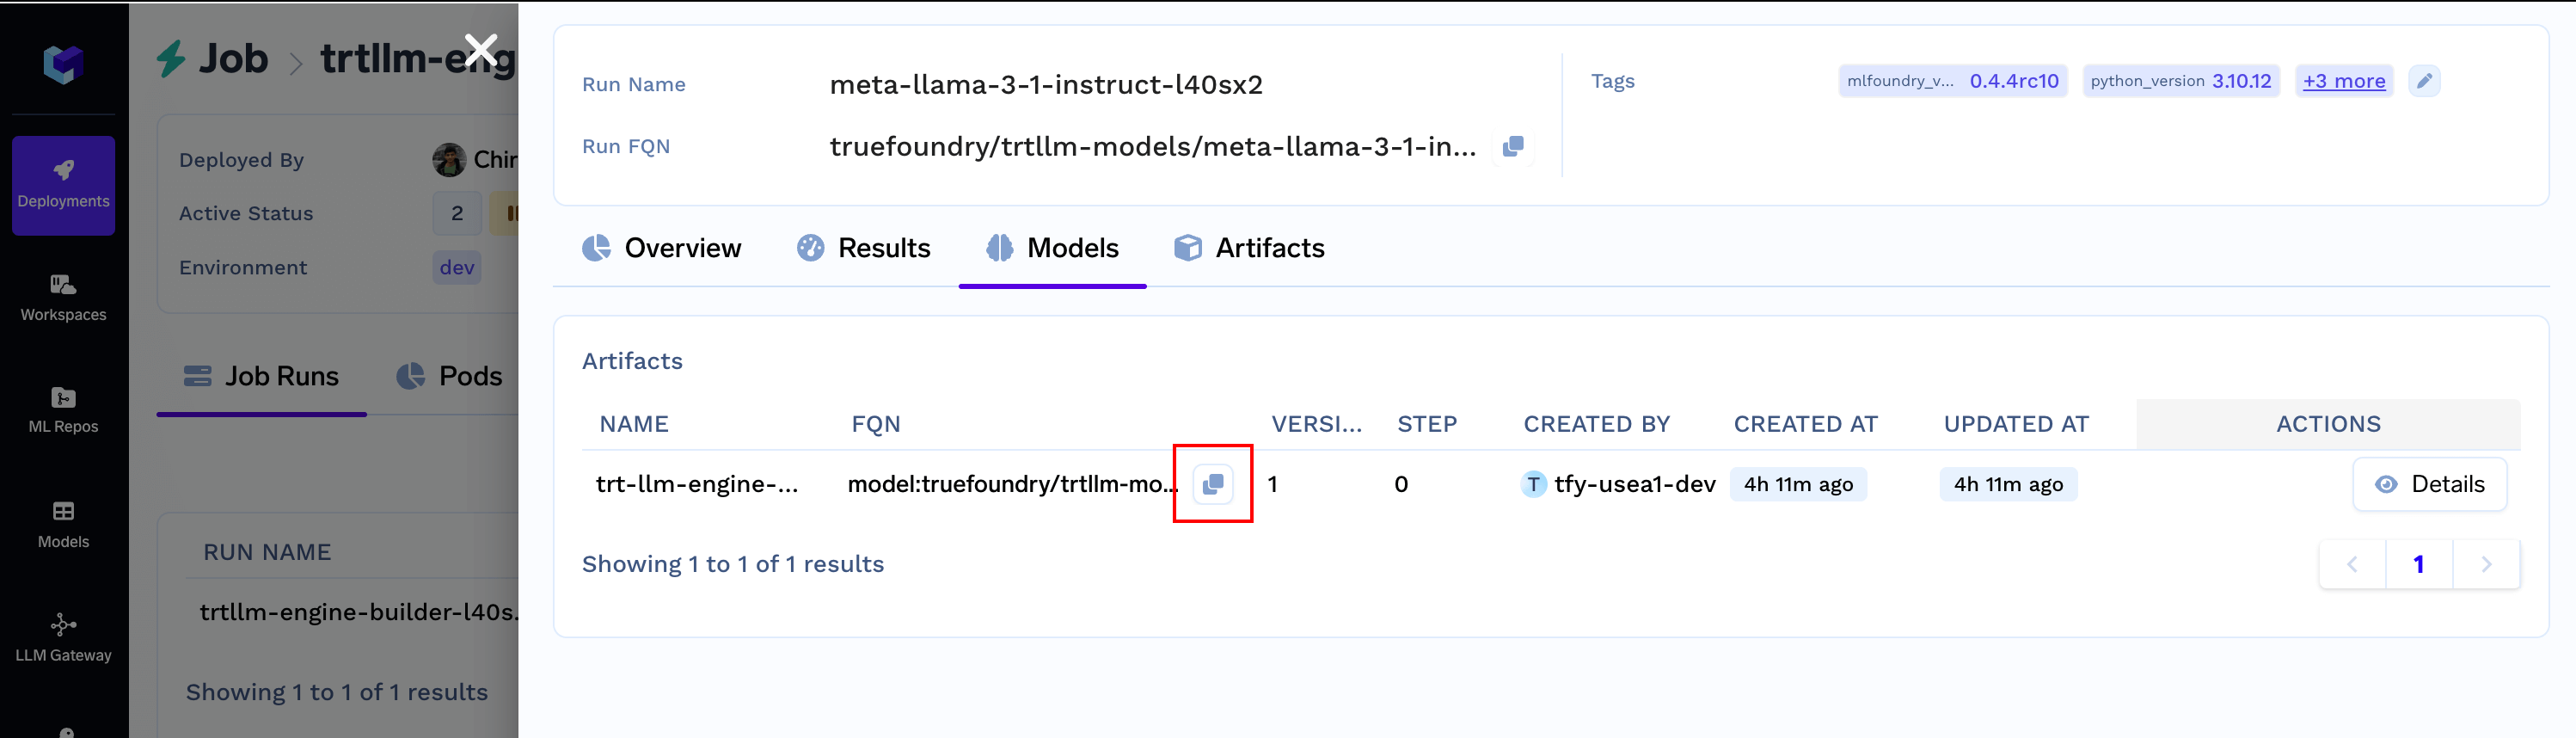
Deploy LLMs using Nvidia TensorRT LLM (TRT LLM) - TrueFoundry Docs
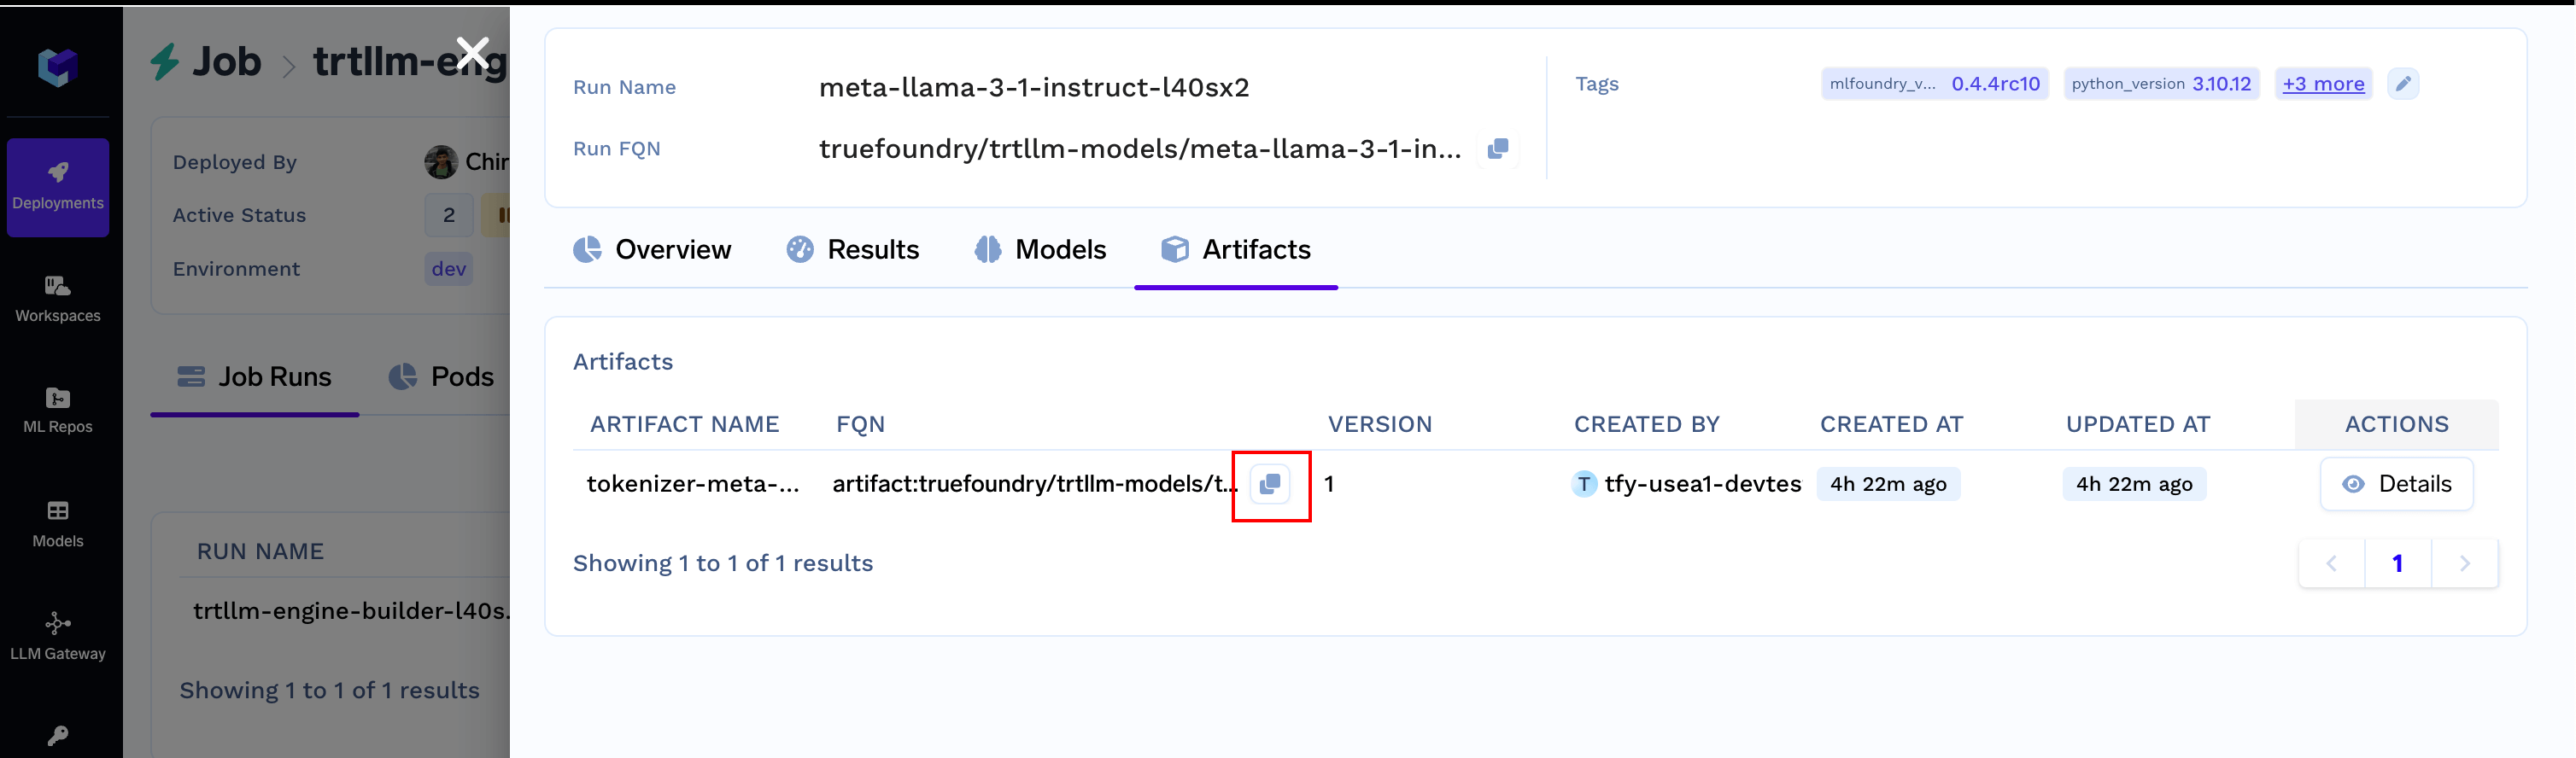
Deploy LLMs using Nvidia TensorRT LLM (TRT LLM) - TrueFoundry Docs
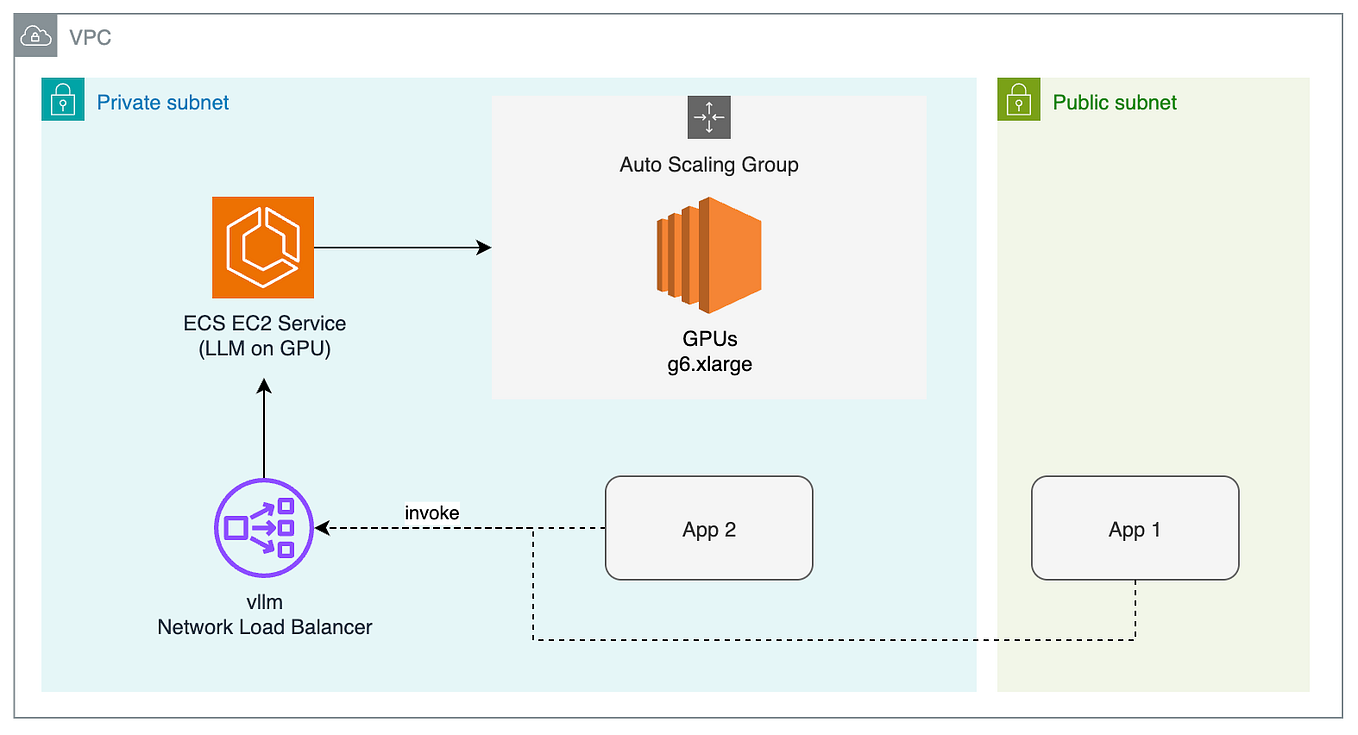
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
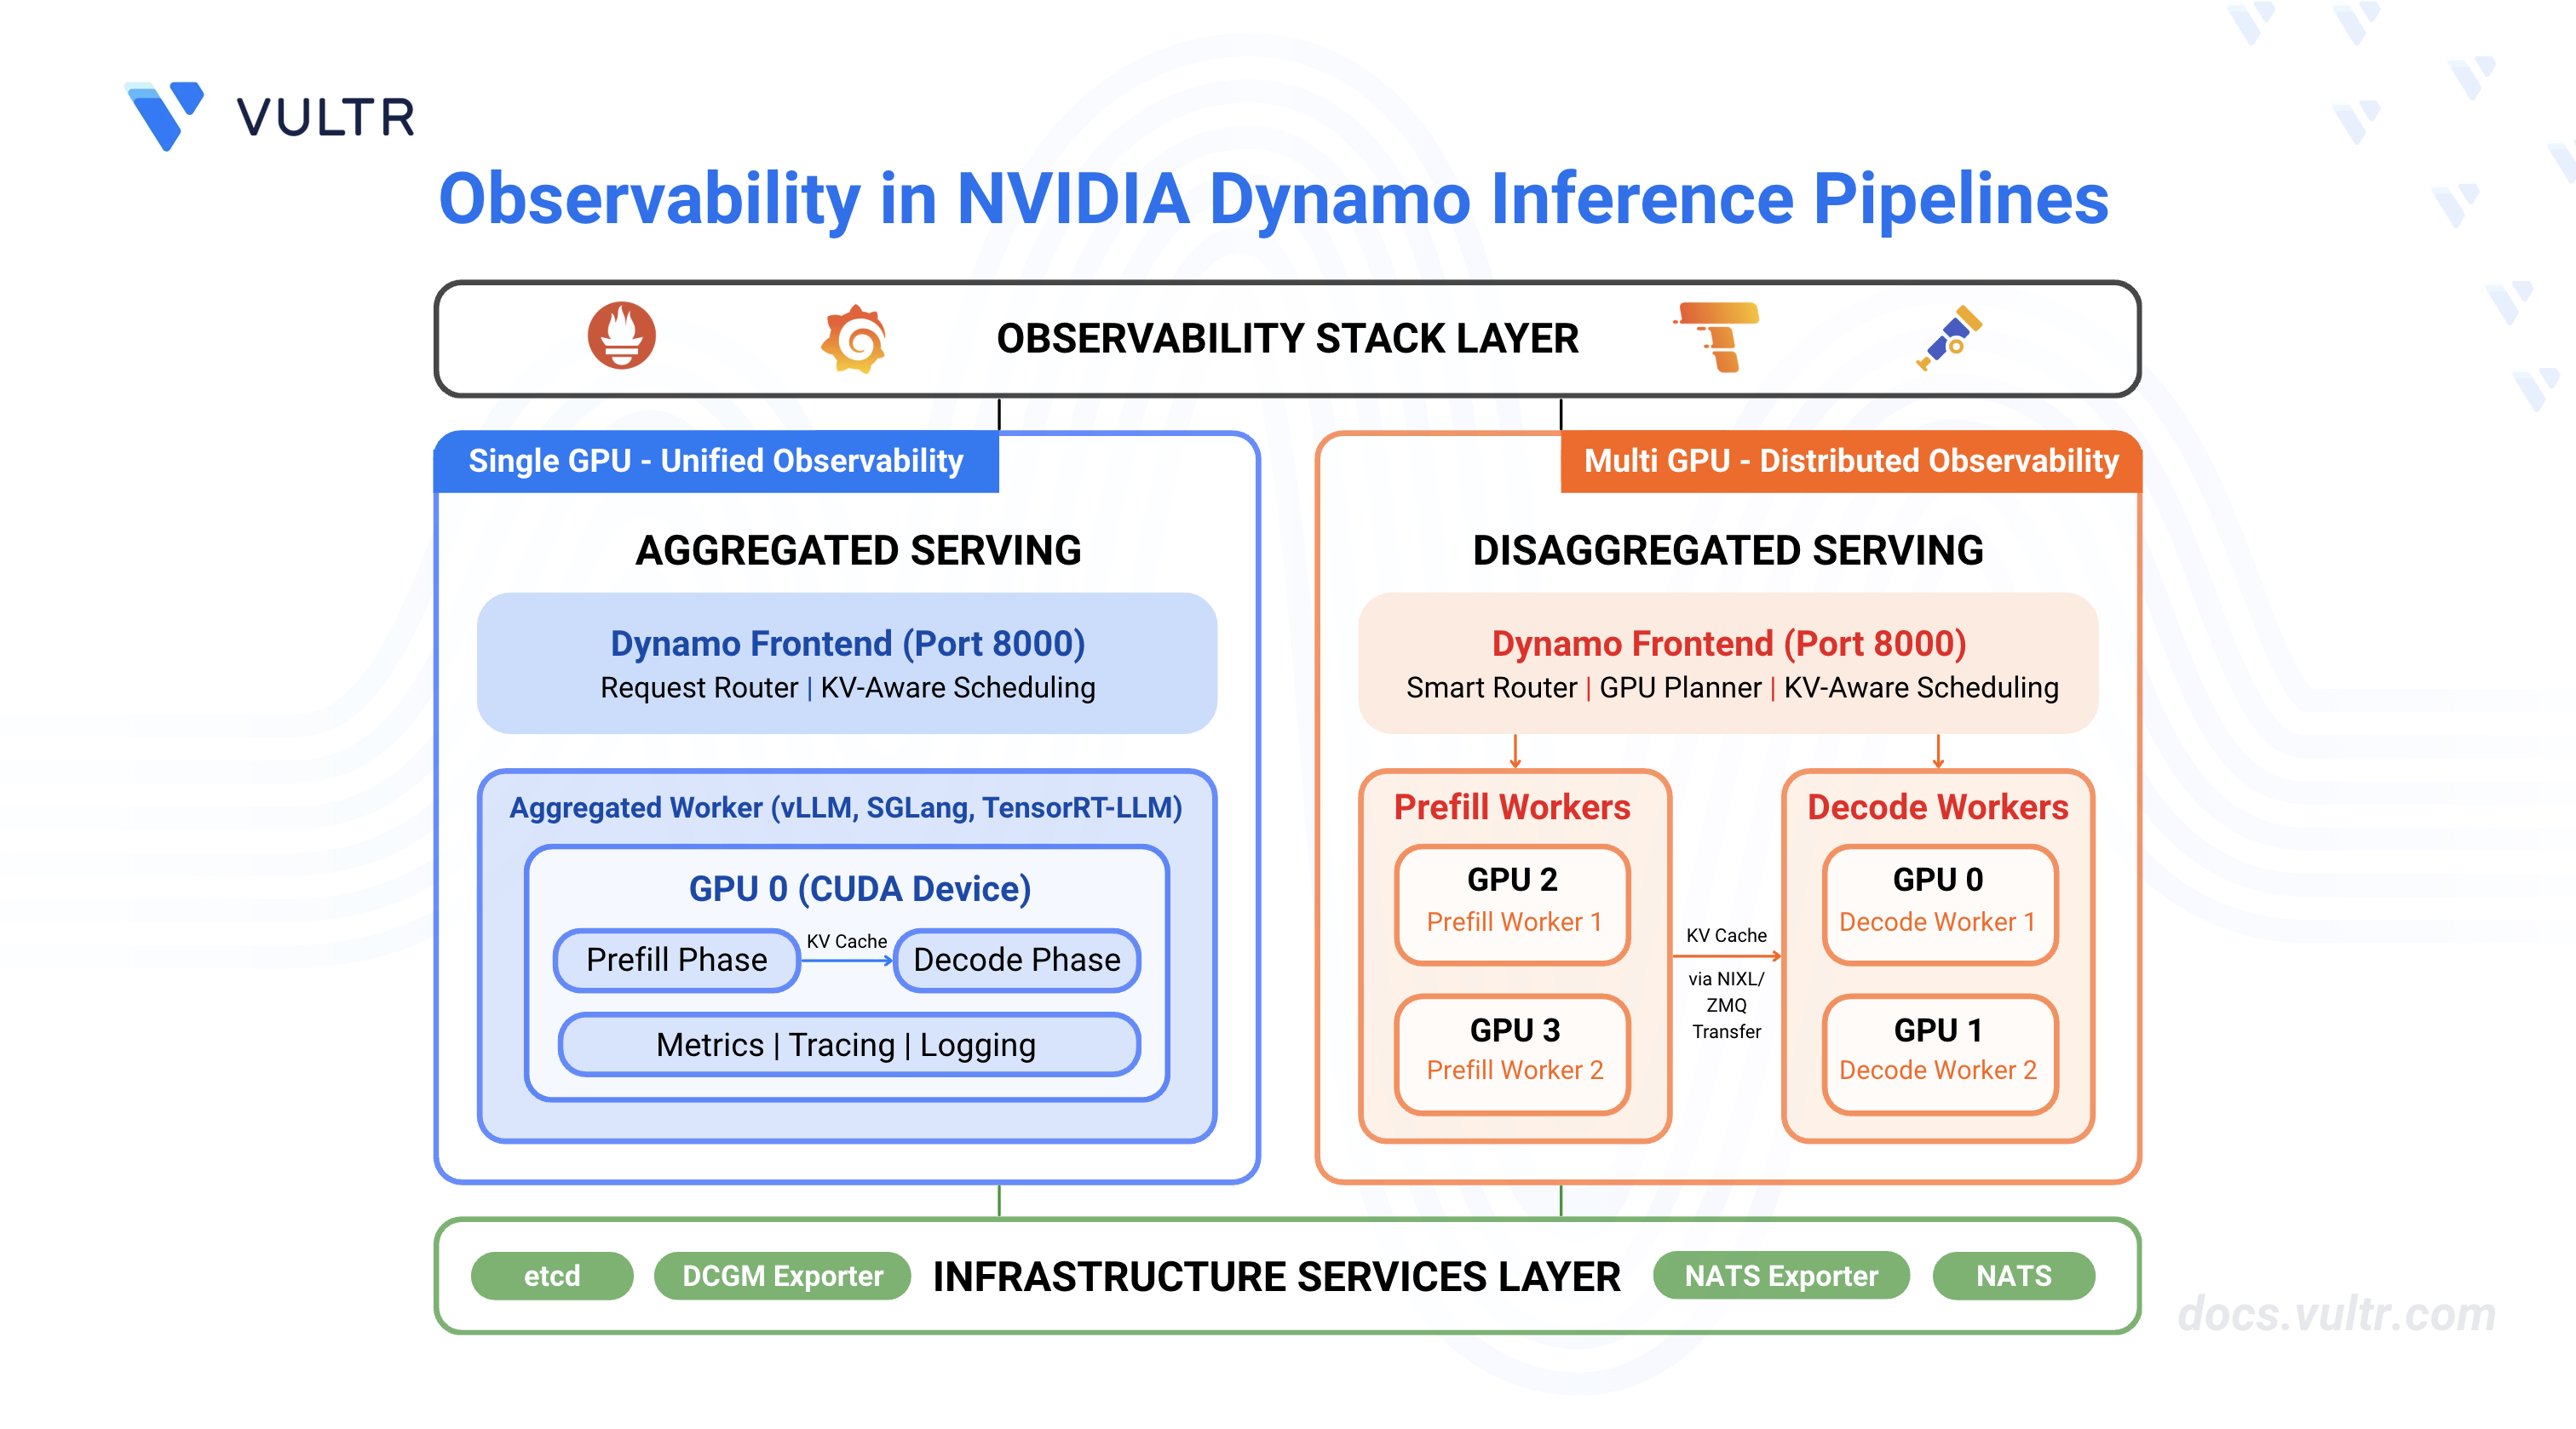
How to Enable Observability in NVIDIA Dynamo Inference Pipelines ...
Advertisement Space (300x250)
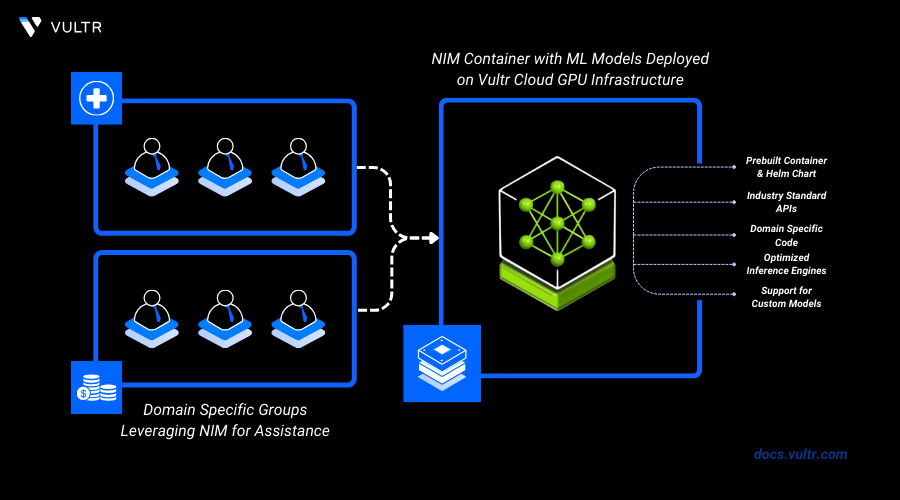
Deploy NVIDIA Inference Microservices on Vultr Platform | Vultr Docs
How to Deploy Dynamo Inference Pipelines | SaaS | Run:ai Documentation
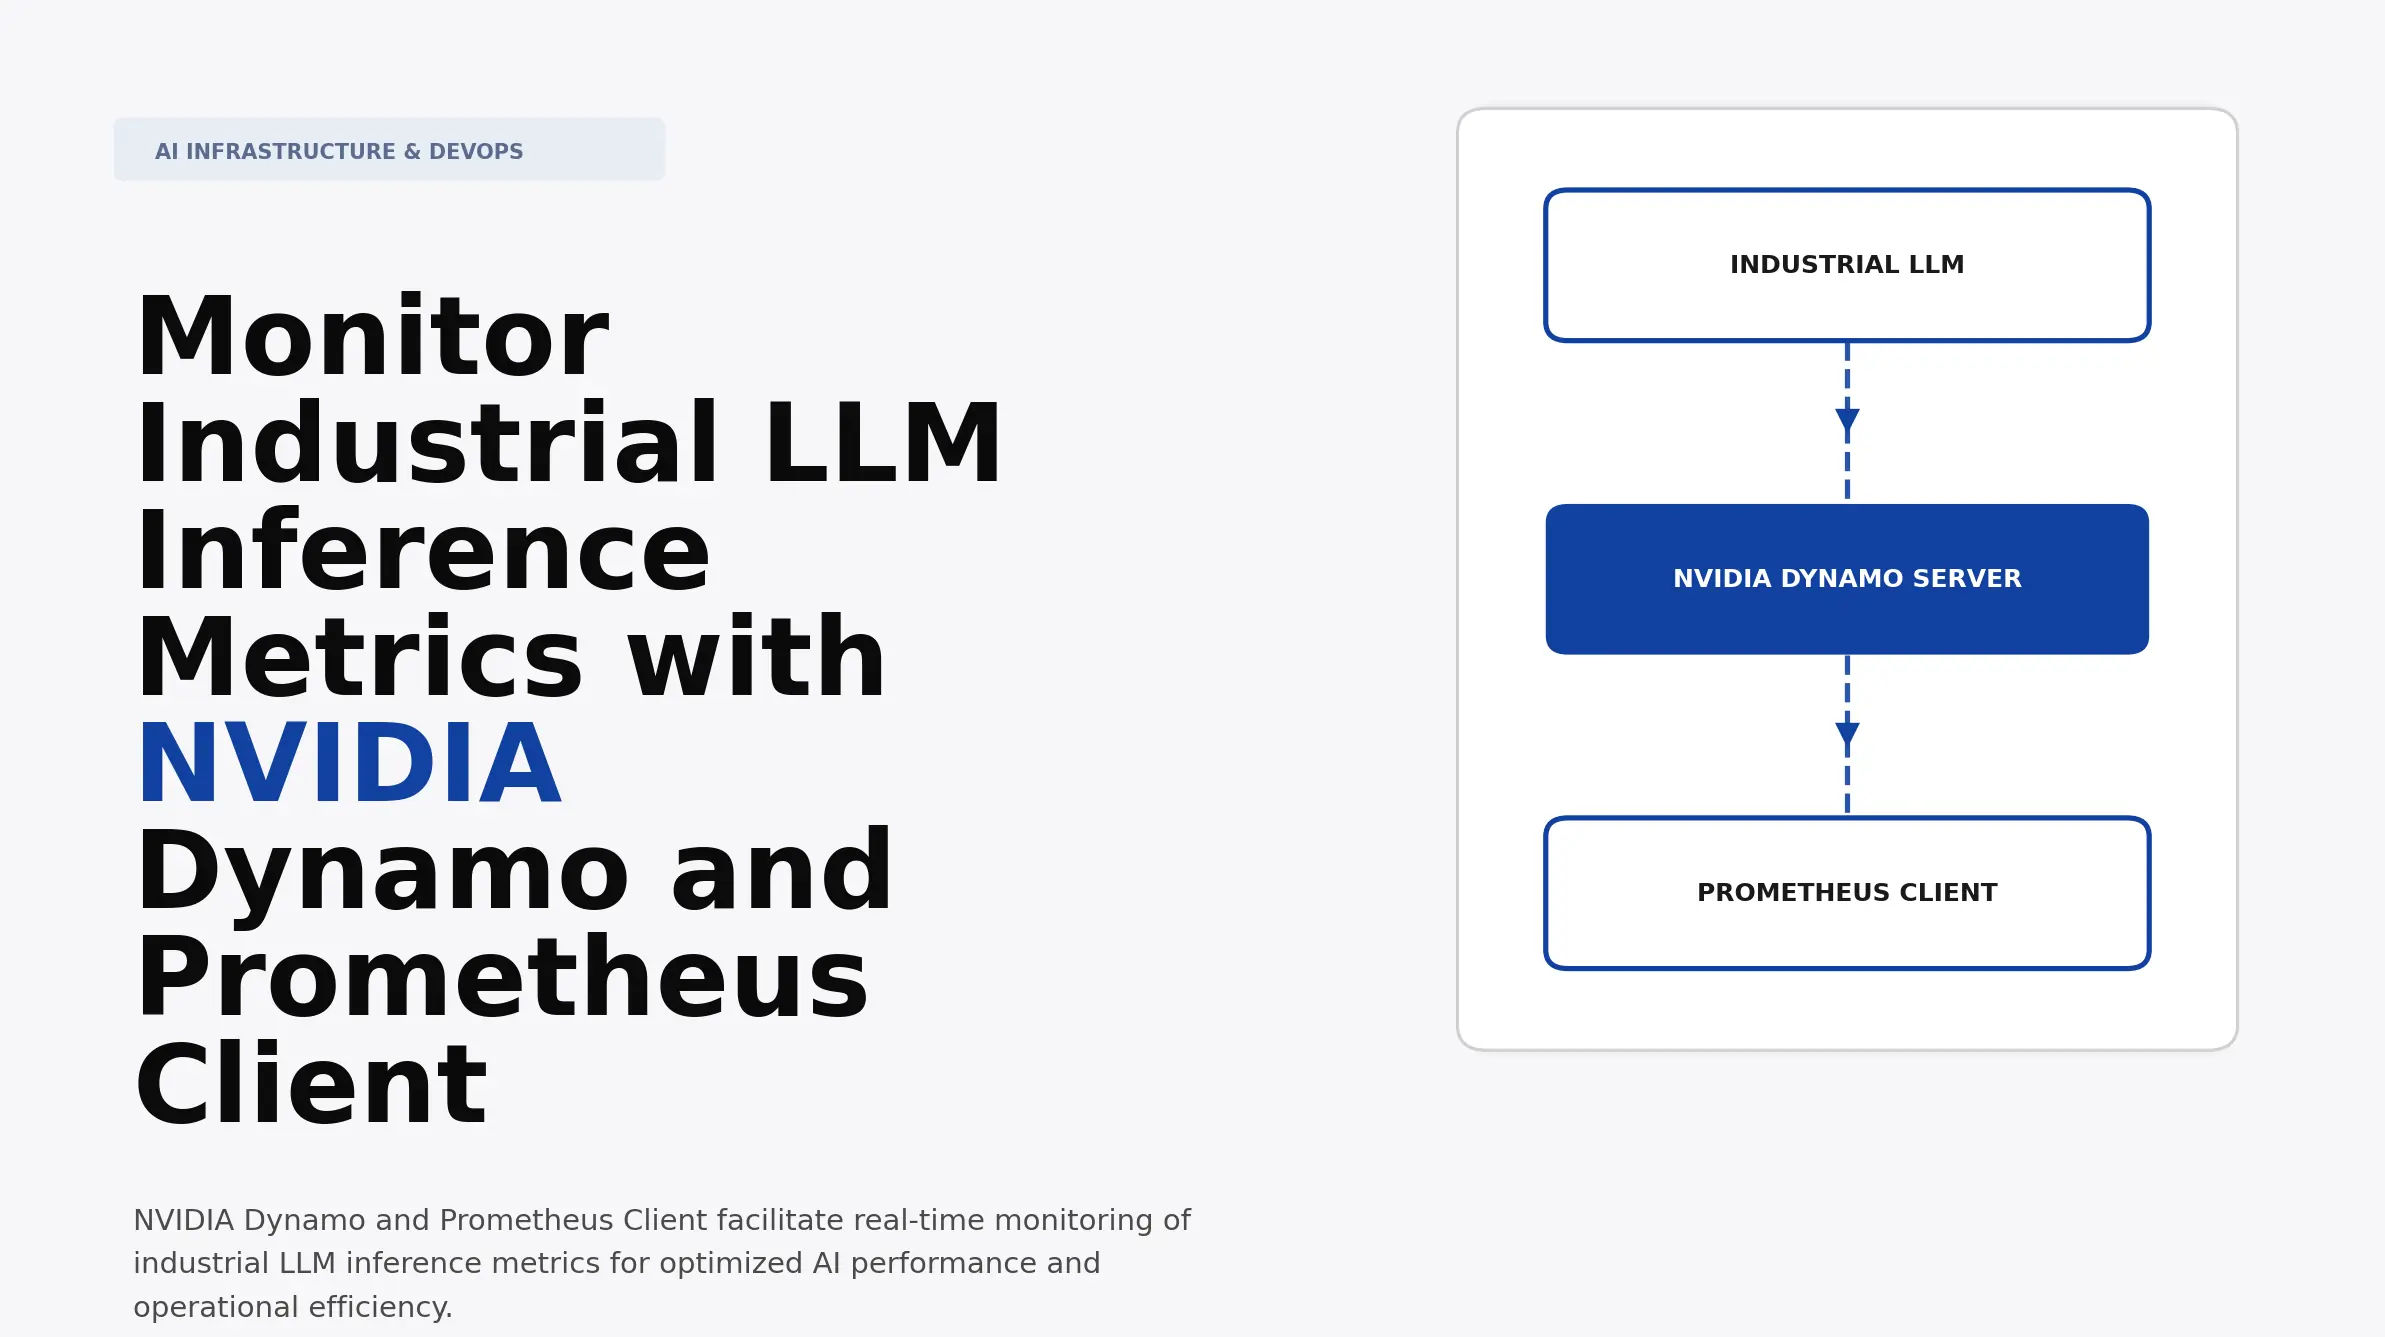
Monitor Industrial LLM Inference Metrics with NVIDIA Dynamo and ...

Tailoring LLM Inference with NVIDIA NIM using Key Features of TensorRT ...
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

How NVIDIA GB200 NVL72 and NVIDIA Dynamo Boost Inference Performance ...

Scaling multi-node LLM inference with NVIDIA Dynamo and NVIDIA GPUs on ...

Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

Tailoring LLM Inference with NVIDIA NIM using Key Features of TensorRT ...
Advertisement Space (336x280)

Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

NVIDIA Dynamo Addresses Multi-Node LLM Inference Challenges - InfoQ

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

Speeding Up Deep Learning Inference Using NVIDIA TensorRT (Updated ...
NVIDIA Dynamo 1.0: Disaggregated LLM Inference Deployment Guide (2026 ...
Optimizing LLM Inference: From TensorRT-LLM to Dynamo and NIM ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...
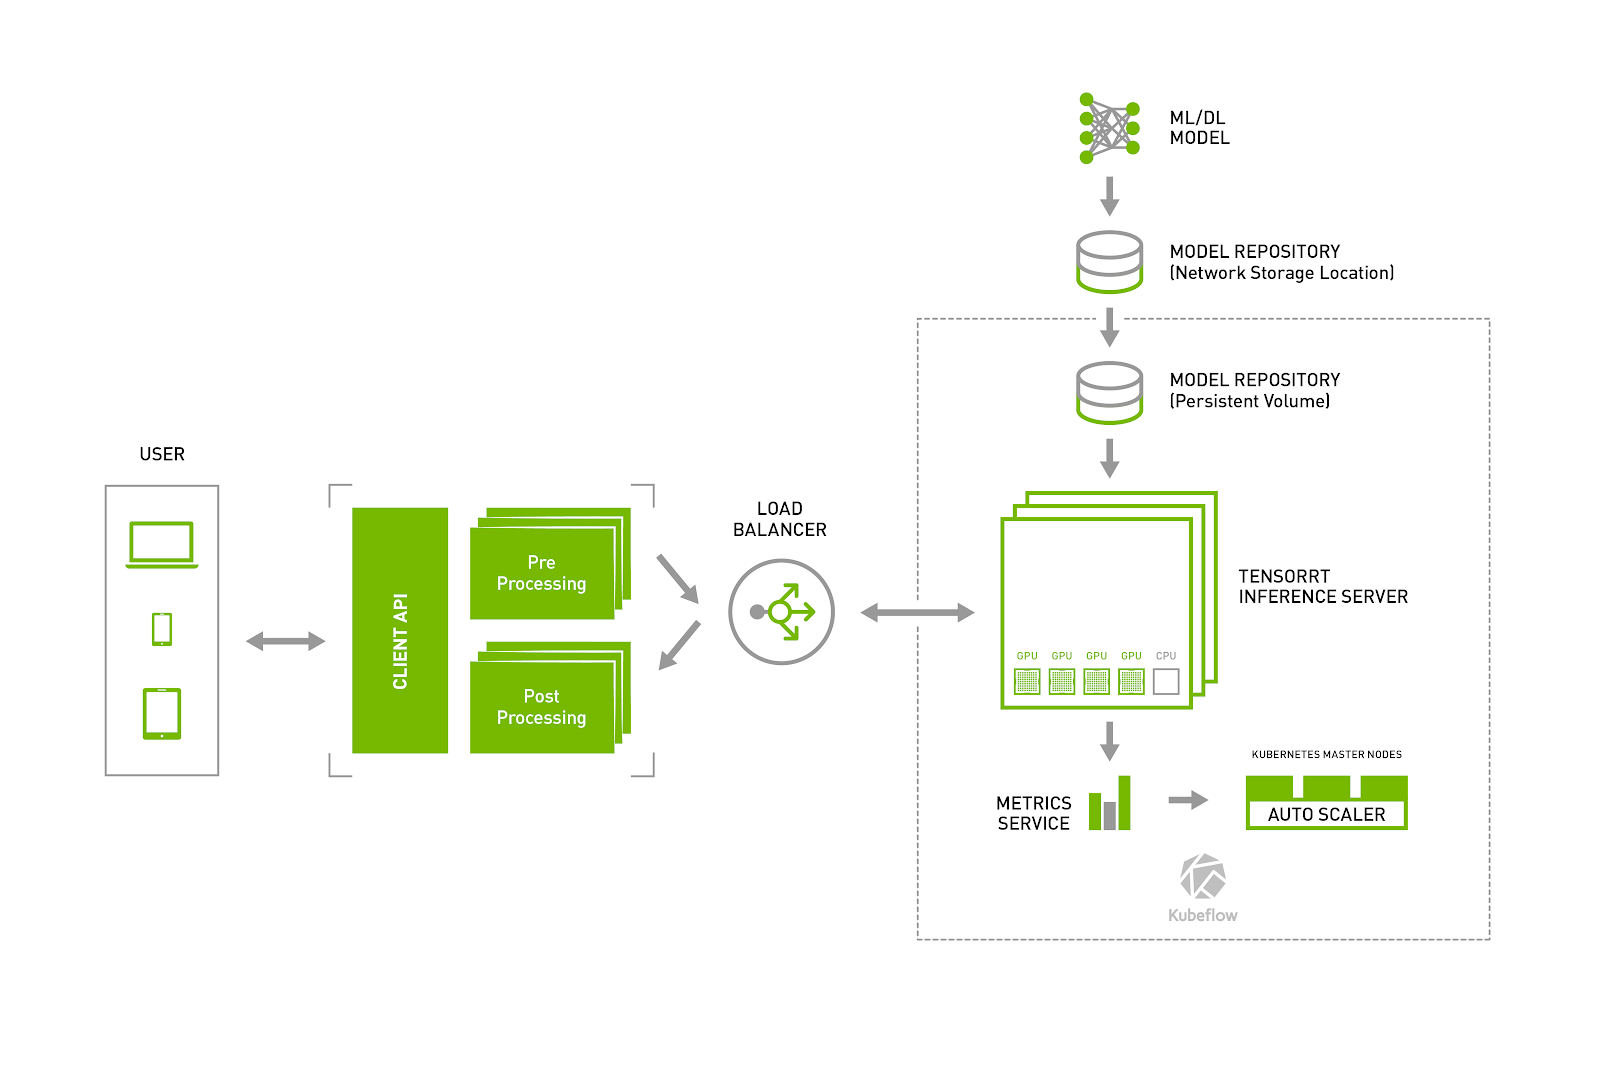
NVIDIA TensorRT Inference Server and Kubeflow Make Deploying Data ...
Advertisement Space (336x280)

TensorRT vs vLLM: The Complete Guide to LLM Inference Engines

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...
NVIDIA Dynamo Planner Brings SLO-Driven Automation to Multi-Node LLM ...

What is NVIDIA Dynamo LLM Inference Framework

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...