
Deploy Vllm For Inference Coreweave Docs
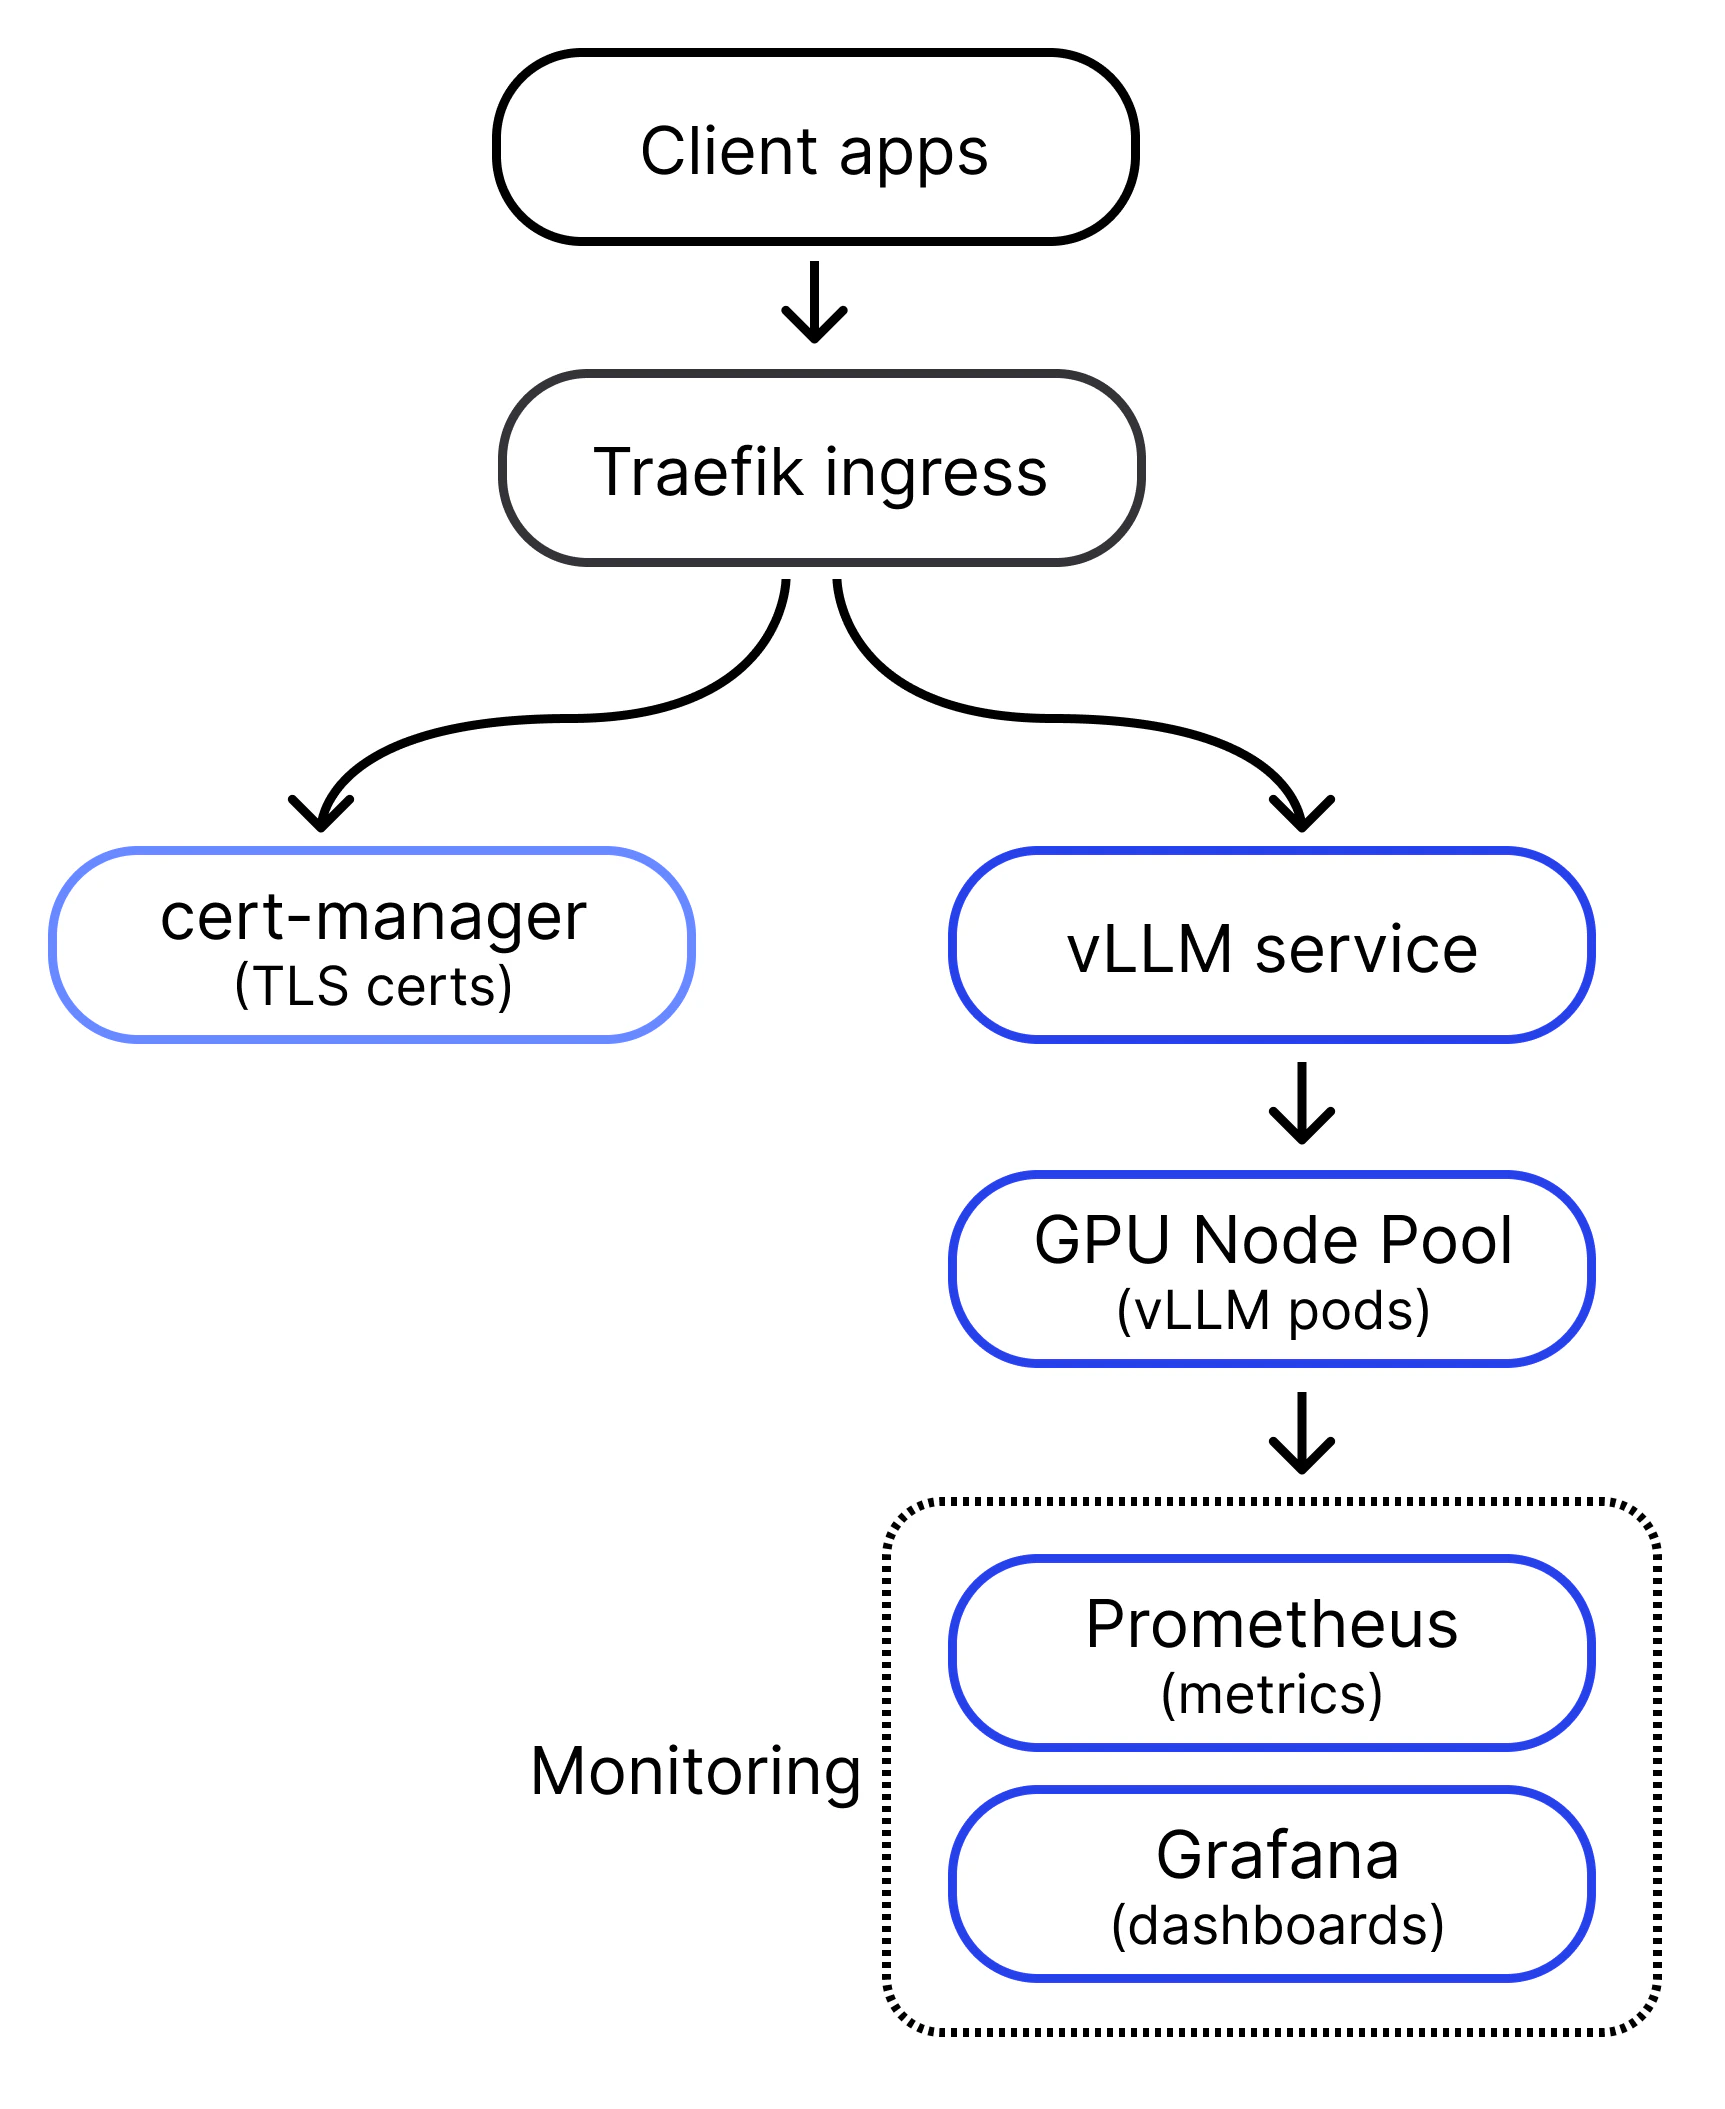
Deploy vLLM for inference - CoreWeave Docs

Deploy Red Hat AI inference and llm-d - CoreWeave Docs
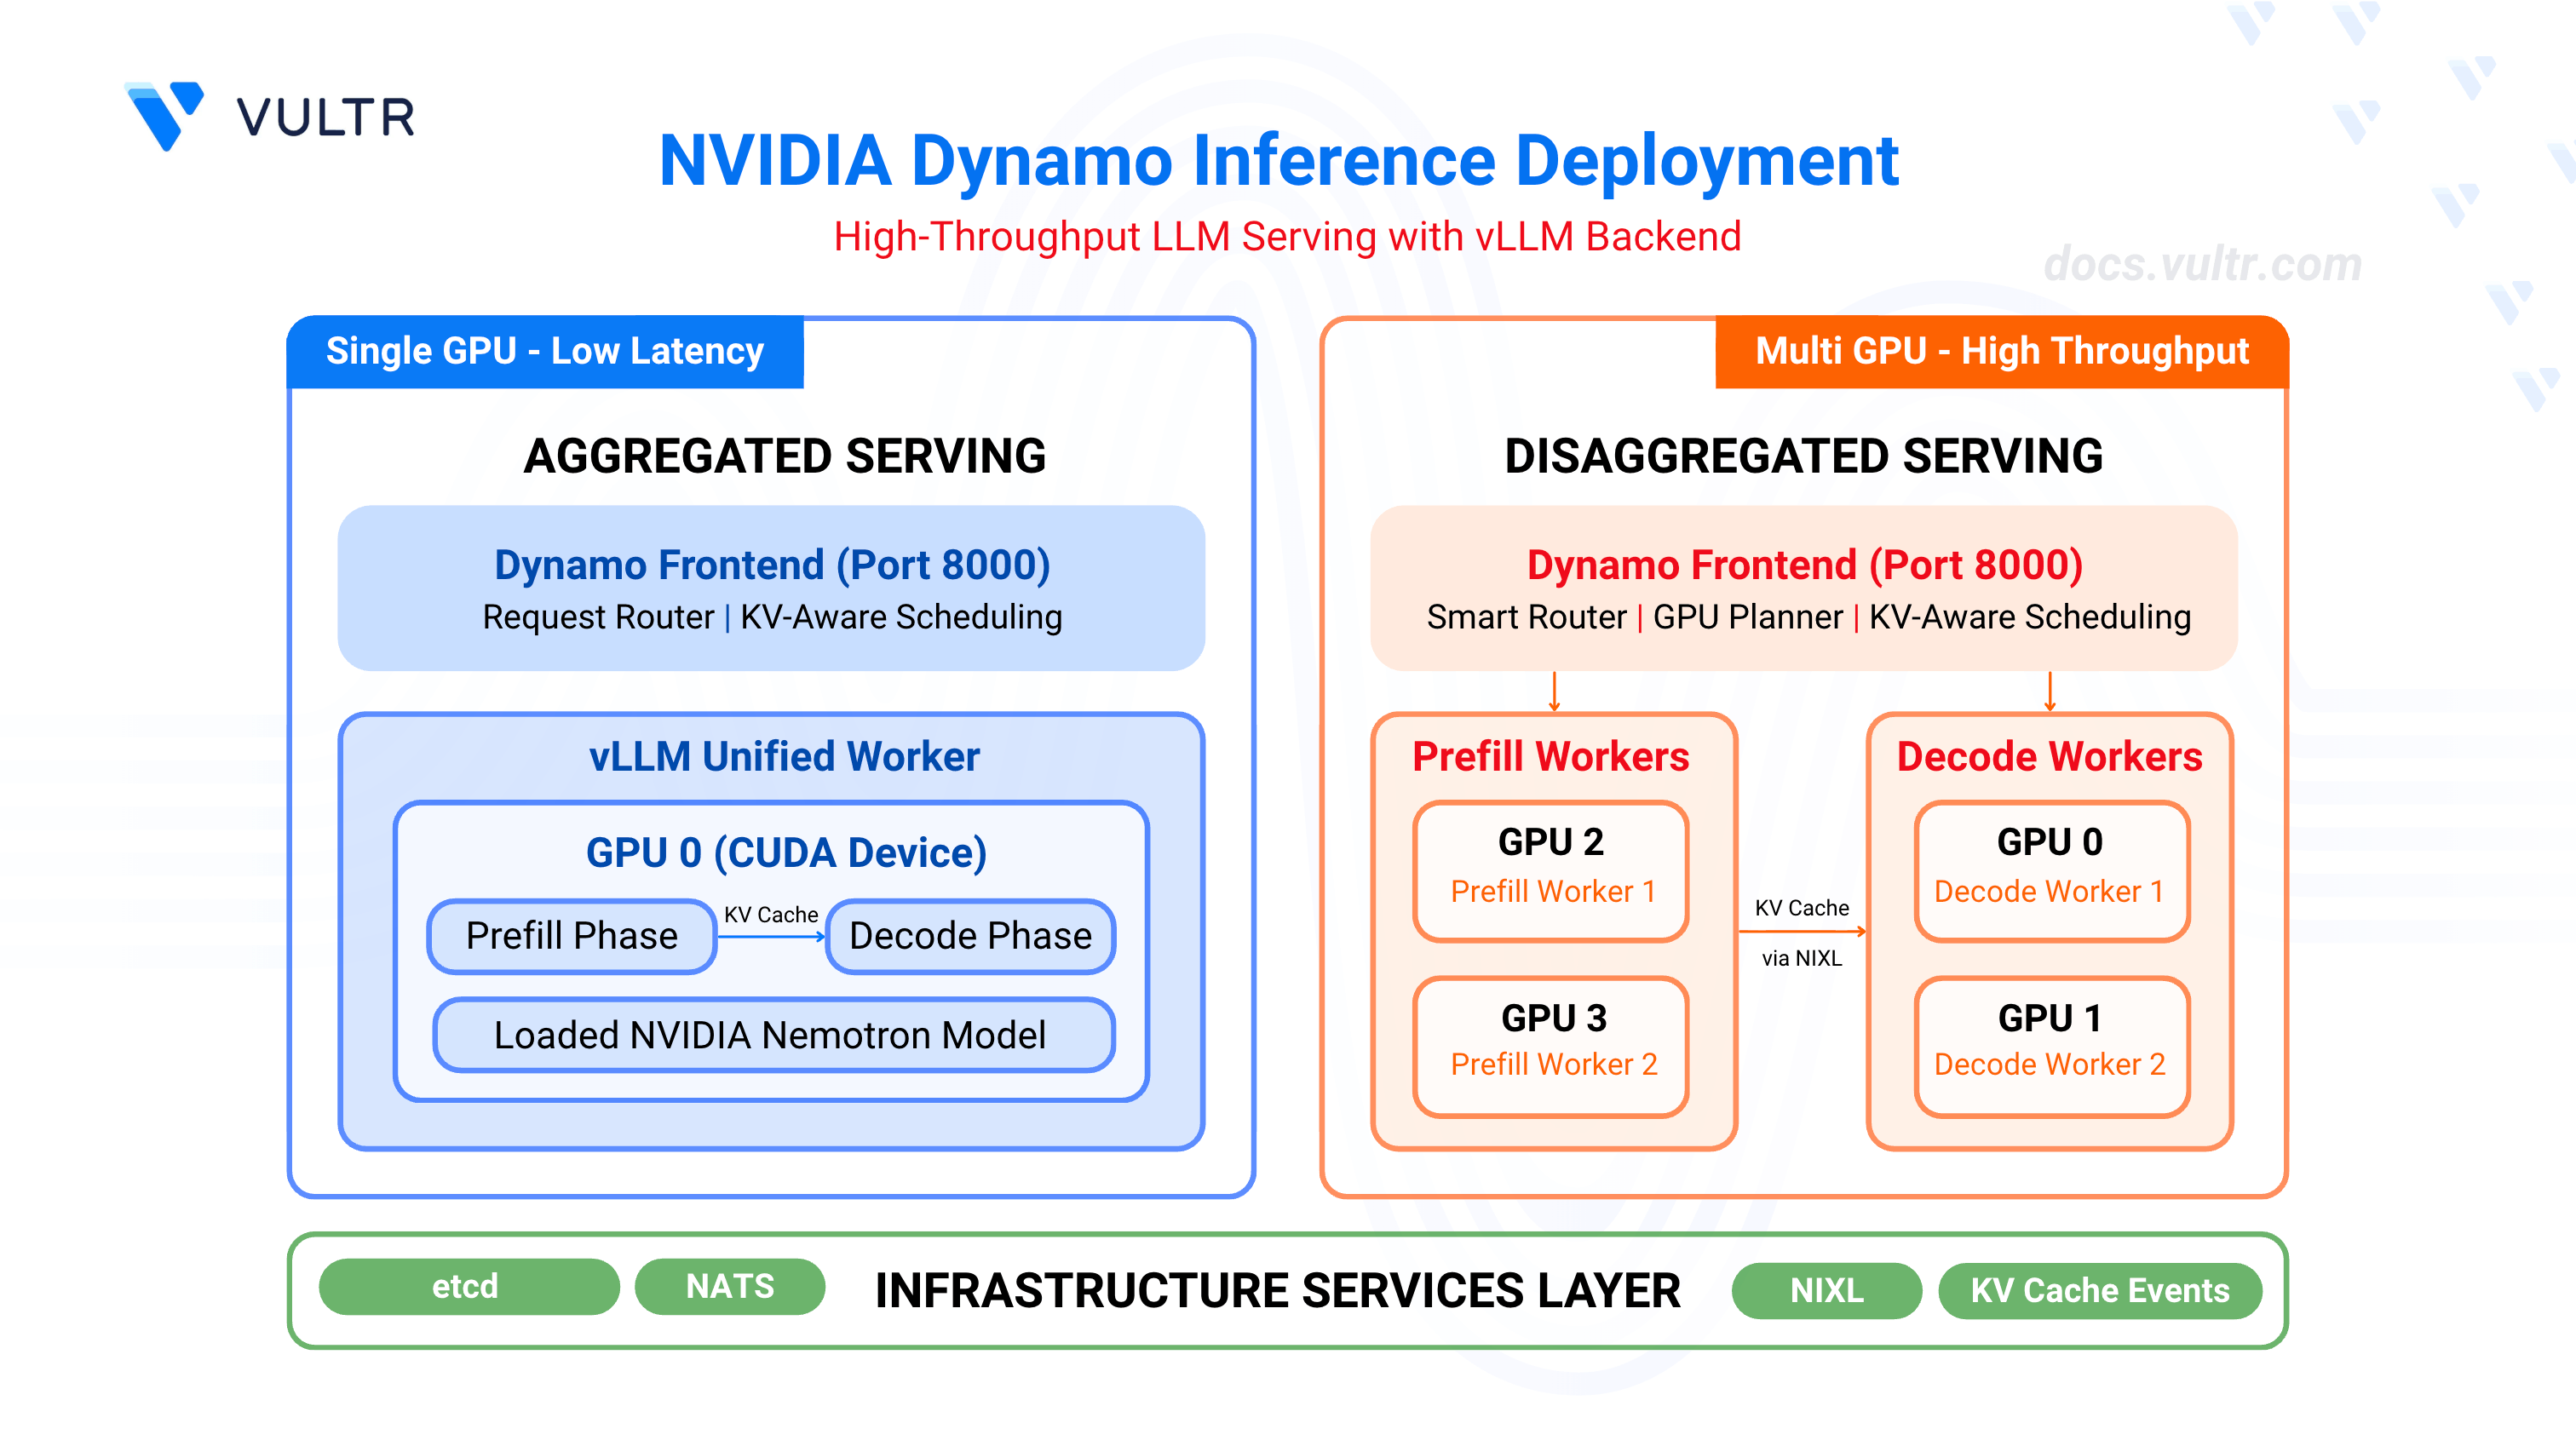
How to Deploy Inference Using NVIDIA Dynamo and vLLM | Vultr Docs
vLLM Model Runner V2 on GPU Cloud: Deploy MRV2 for Faster LLM Inference ...

Deploy the vLLM inference server | AIPerf Deployment Guide for Dell ...

Want to deploy open models using vLLM as the inference engine? We just ...
Deploy vLLM on Kubernetes for High-Throughput Large Language Model ...
Deploy Inference Workloads with vLLM | Self-hosted | Run:ai Documentation
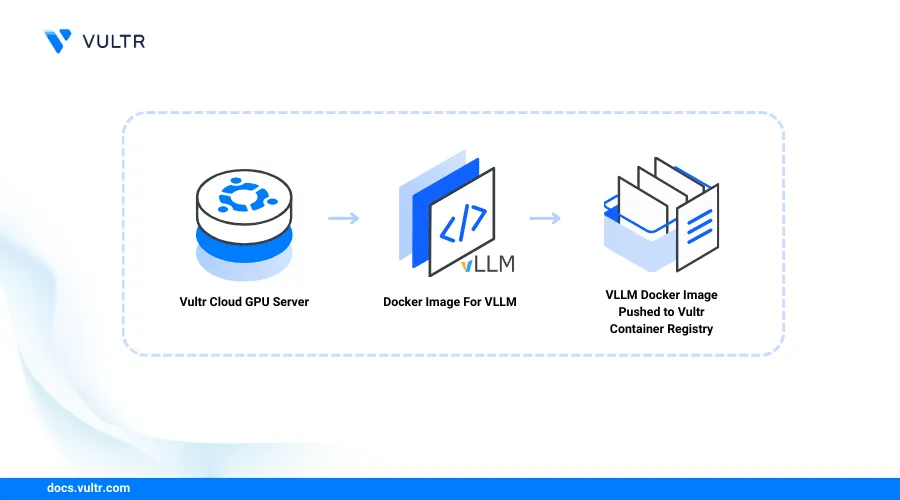
How to Build a vLLM Container Image for LLM Deployment | Vultr Docs
Run OpenAI-compatible LLM inference with Gemma and vLLM | Modal Docs
Advertisement Space (300x250)

vLLM V1: Accelerating multimodal inference for large language models ...
vLLM Review: High-Performance LLM Inference Engine for GPU ...

Serving Inference for LLMs: A Case Study | CoreWeave
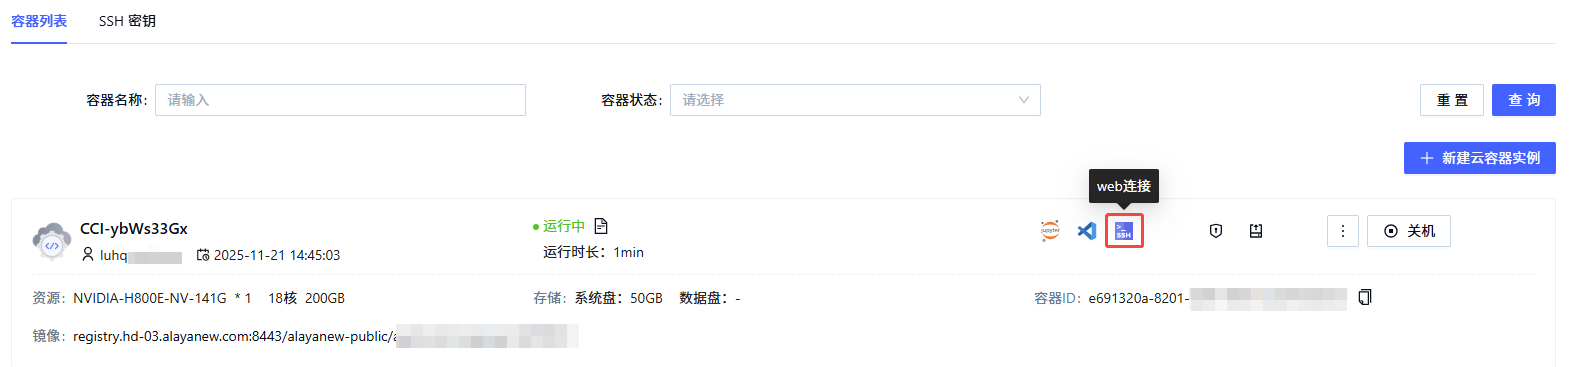
Deploy an OpenAI-compatible inference service with vLLM on CCI · Alaya ...

10 Best vLLM Alternatives for LLM Inference in Production (2026) - DEV ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
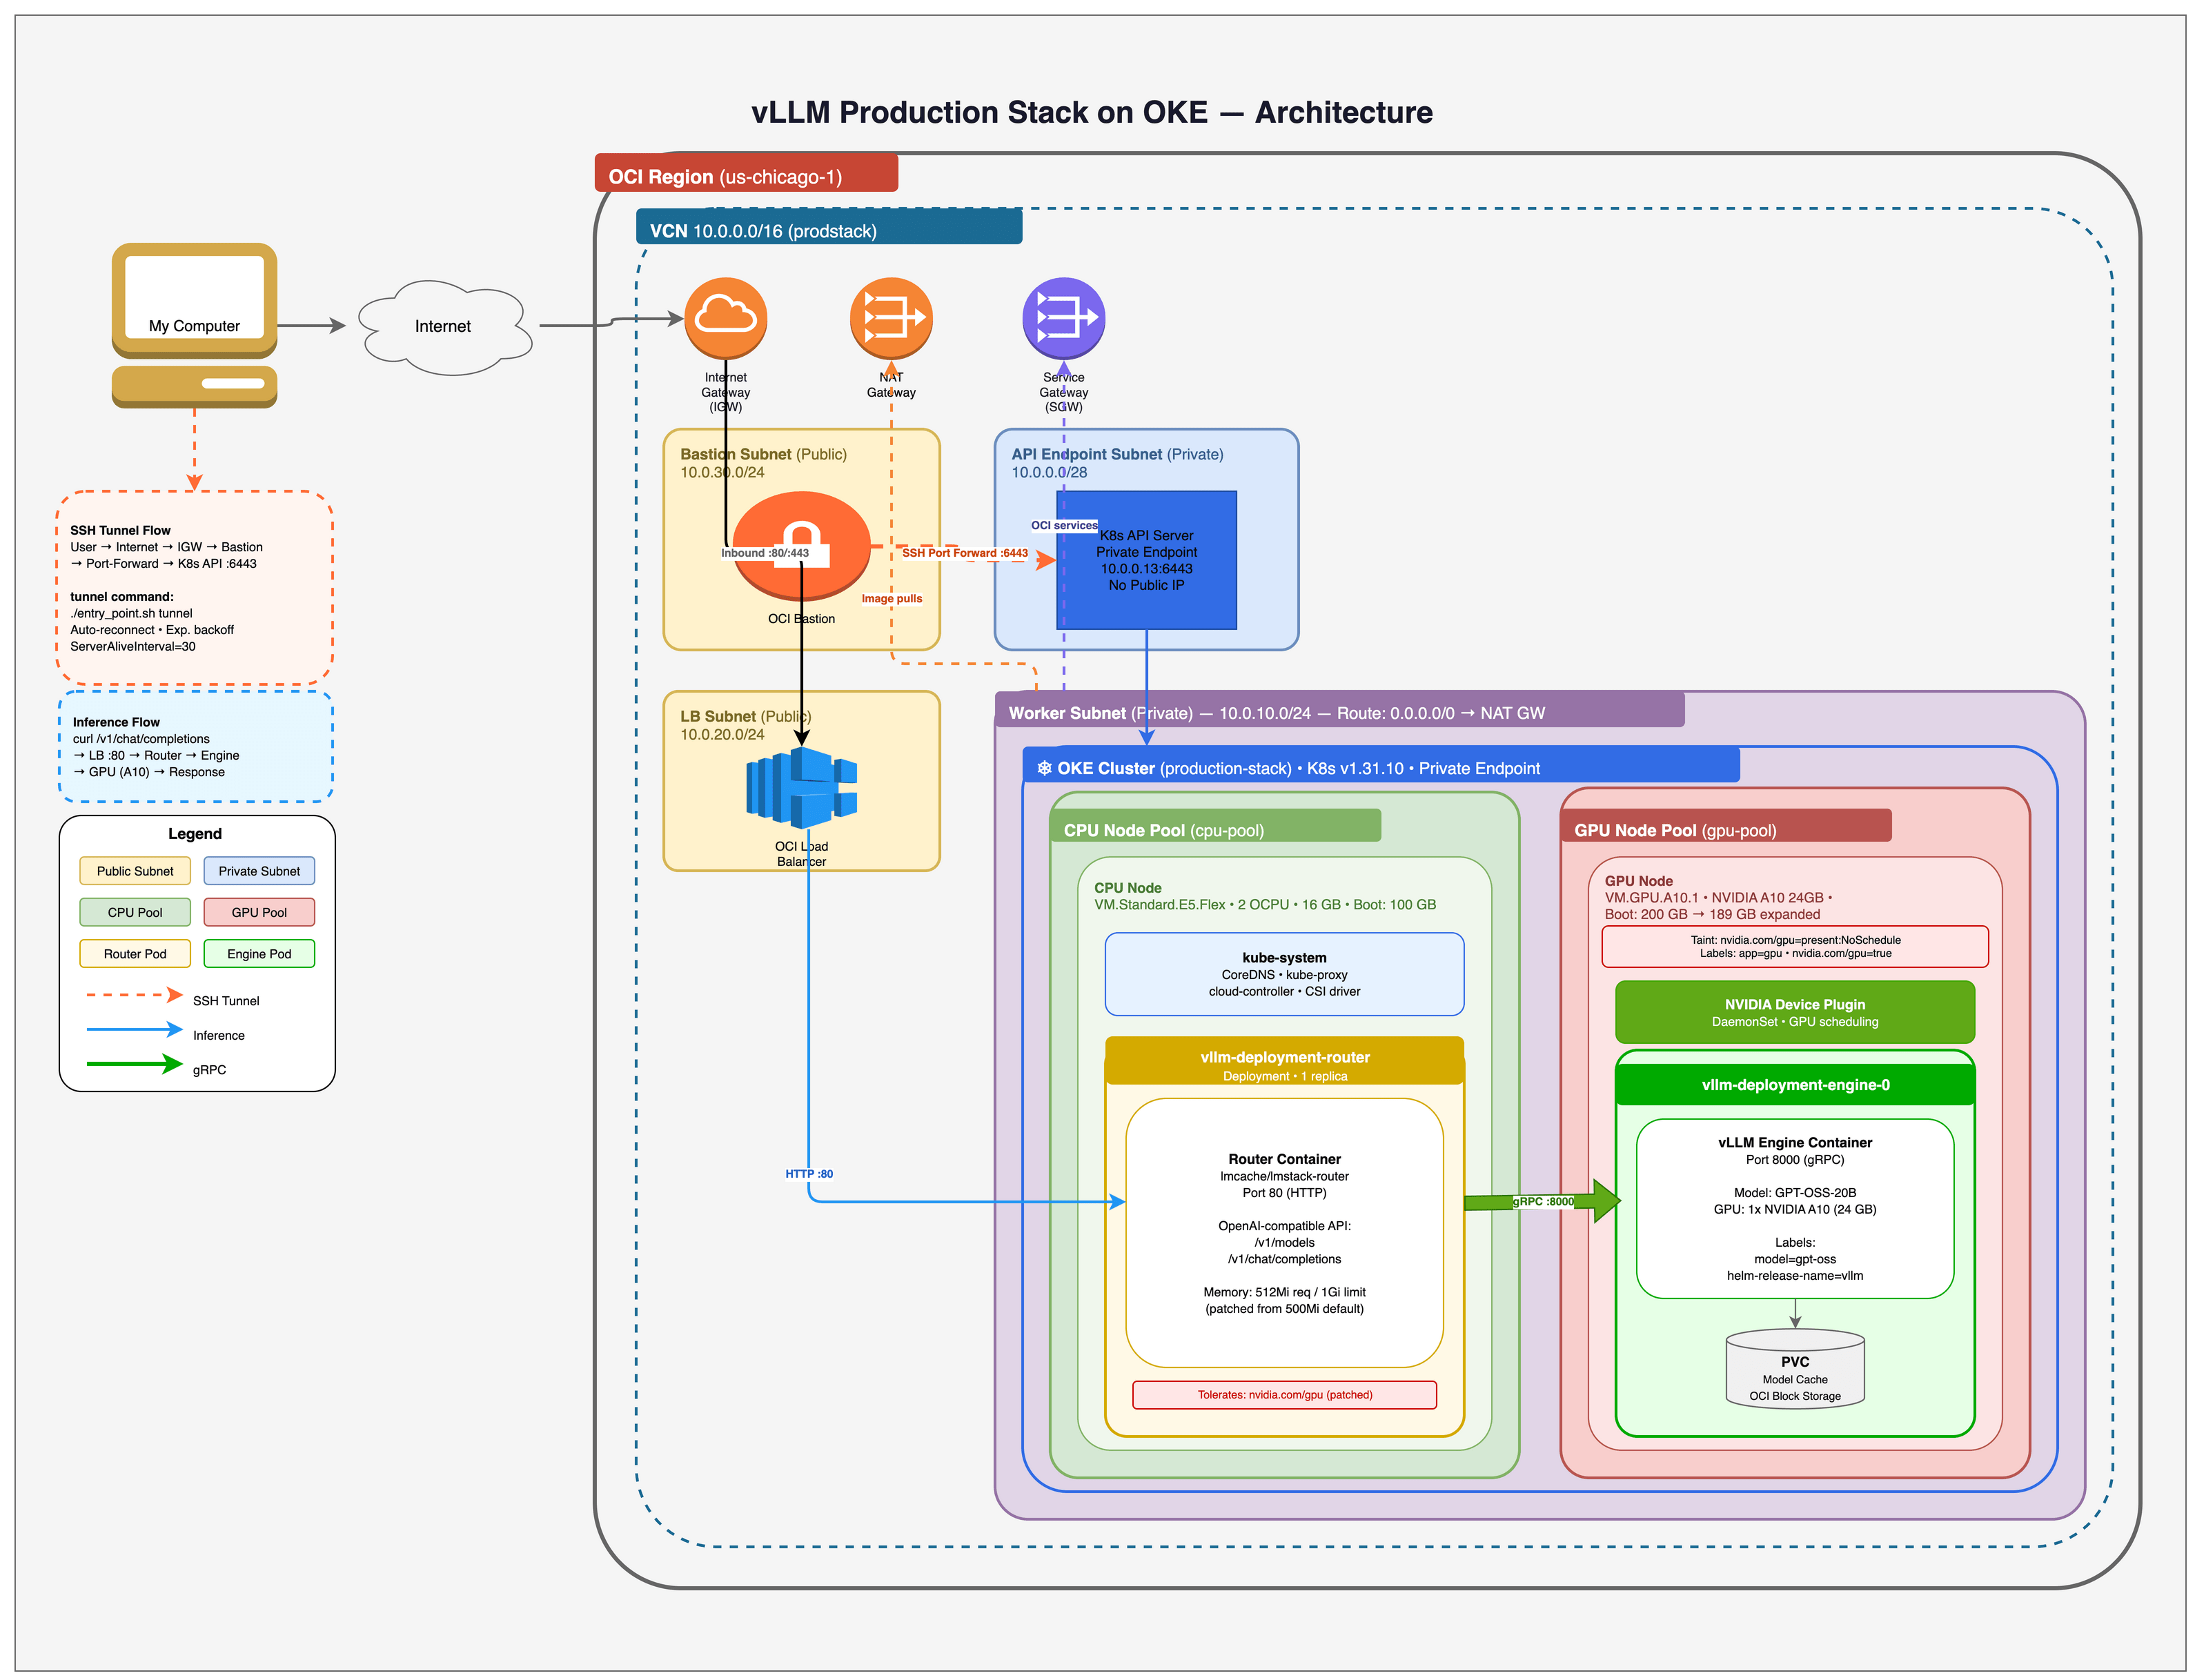
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)
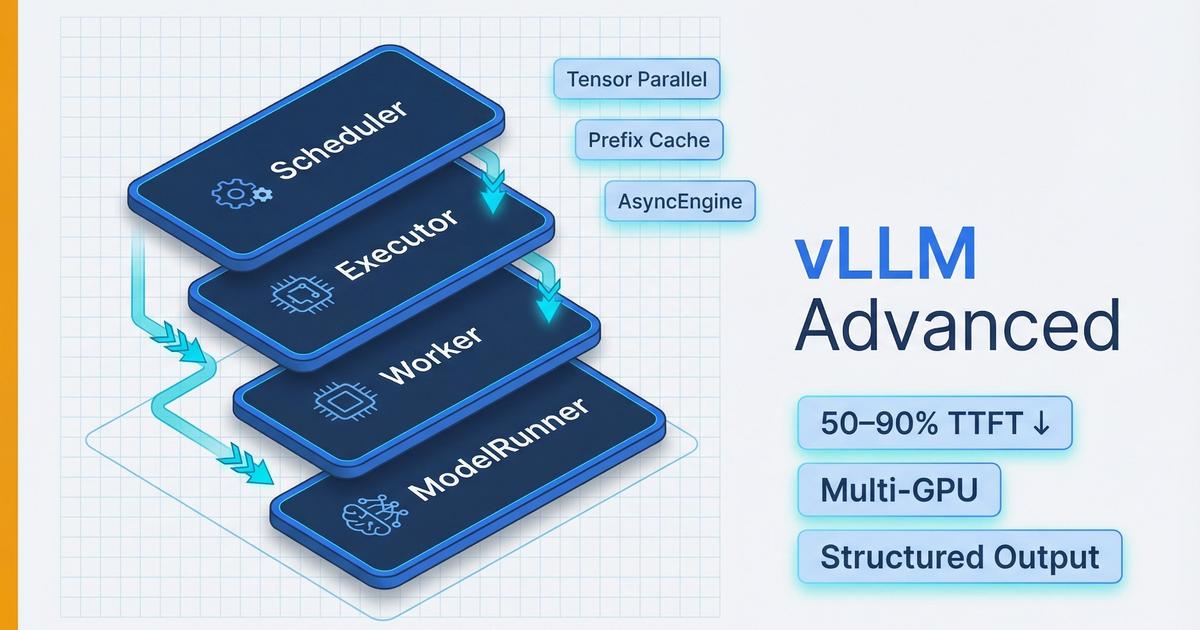
vLLM Advanced: Building Custom Inference Pipelines at Scale (2026 Guide ...

An End‑to‑End View of AI Inference Stacks with vLLM and Alternatives
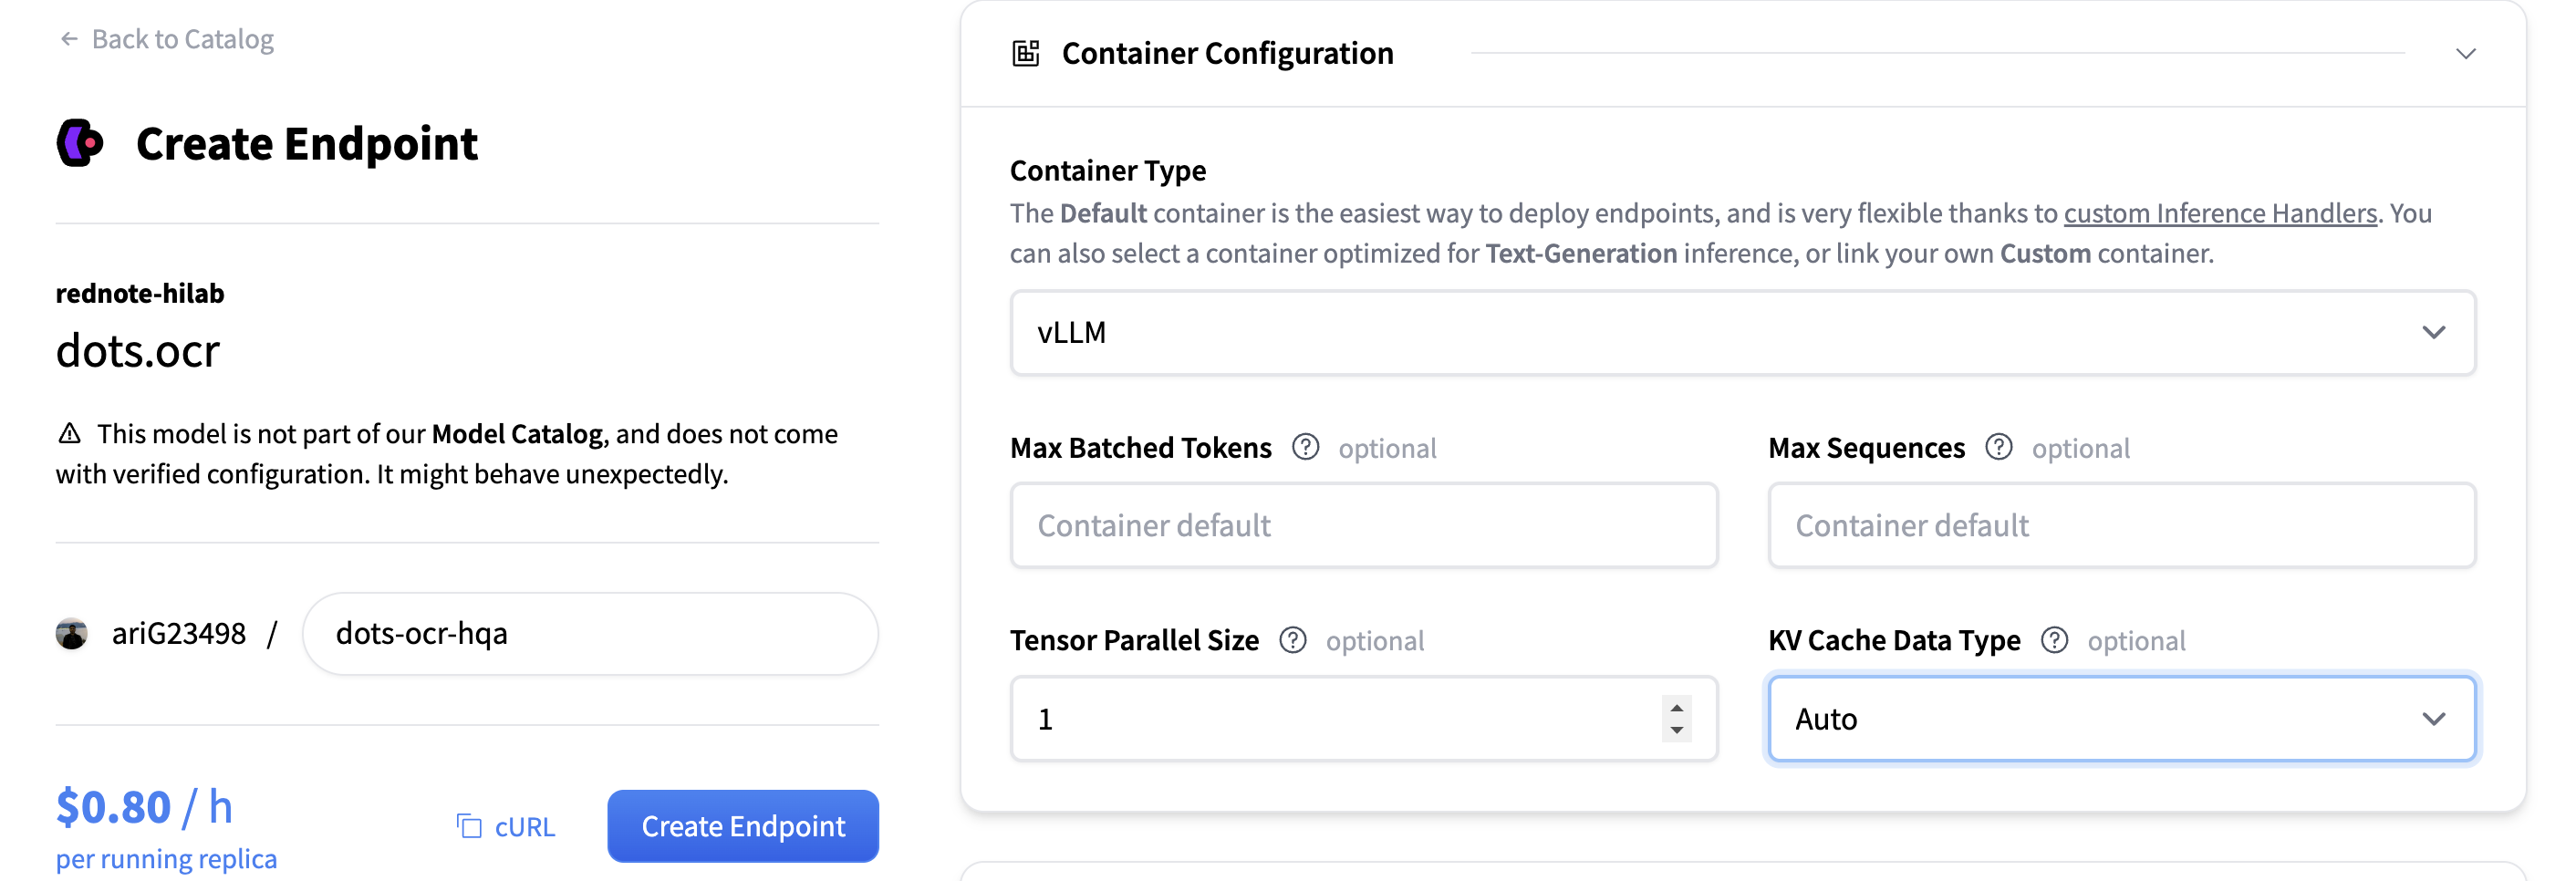
Hugging Face Inference Endpoints - vLLM
Advertisement Space (336x280)
How to deploy vLLM

How to Deploy vLLM in Production with Docker (2026) | Yotta Labs
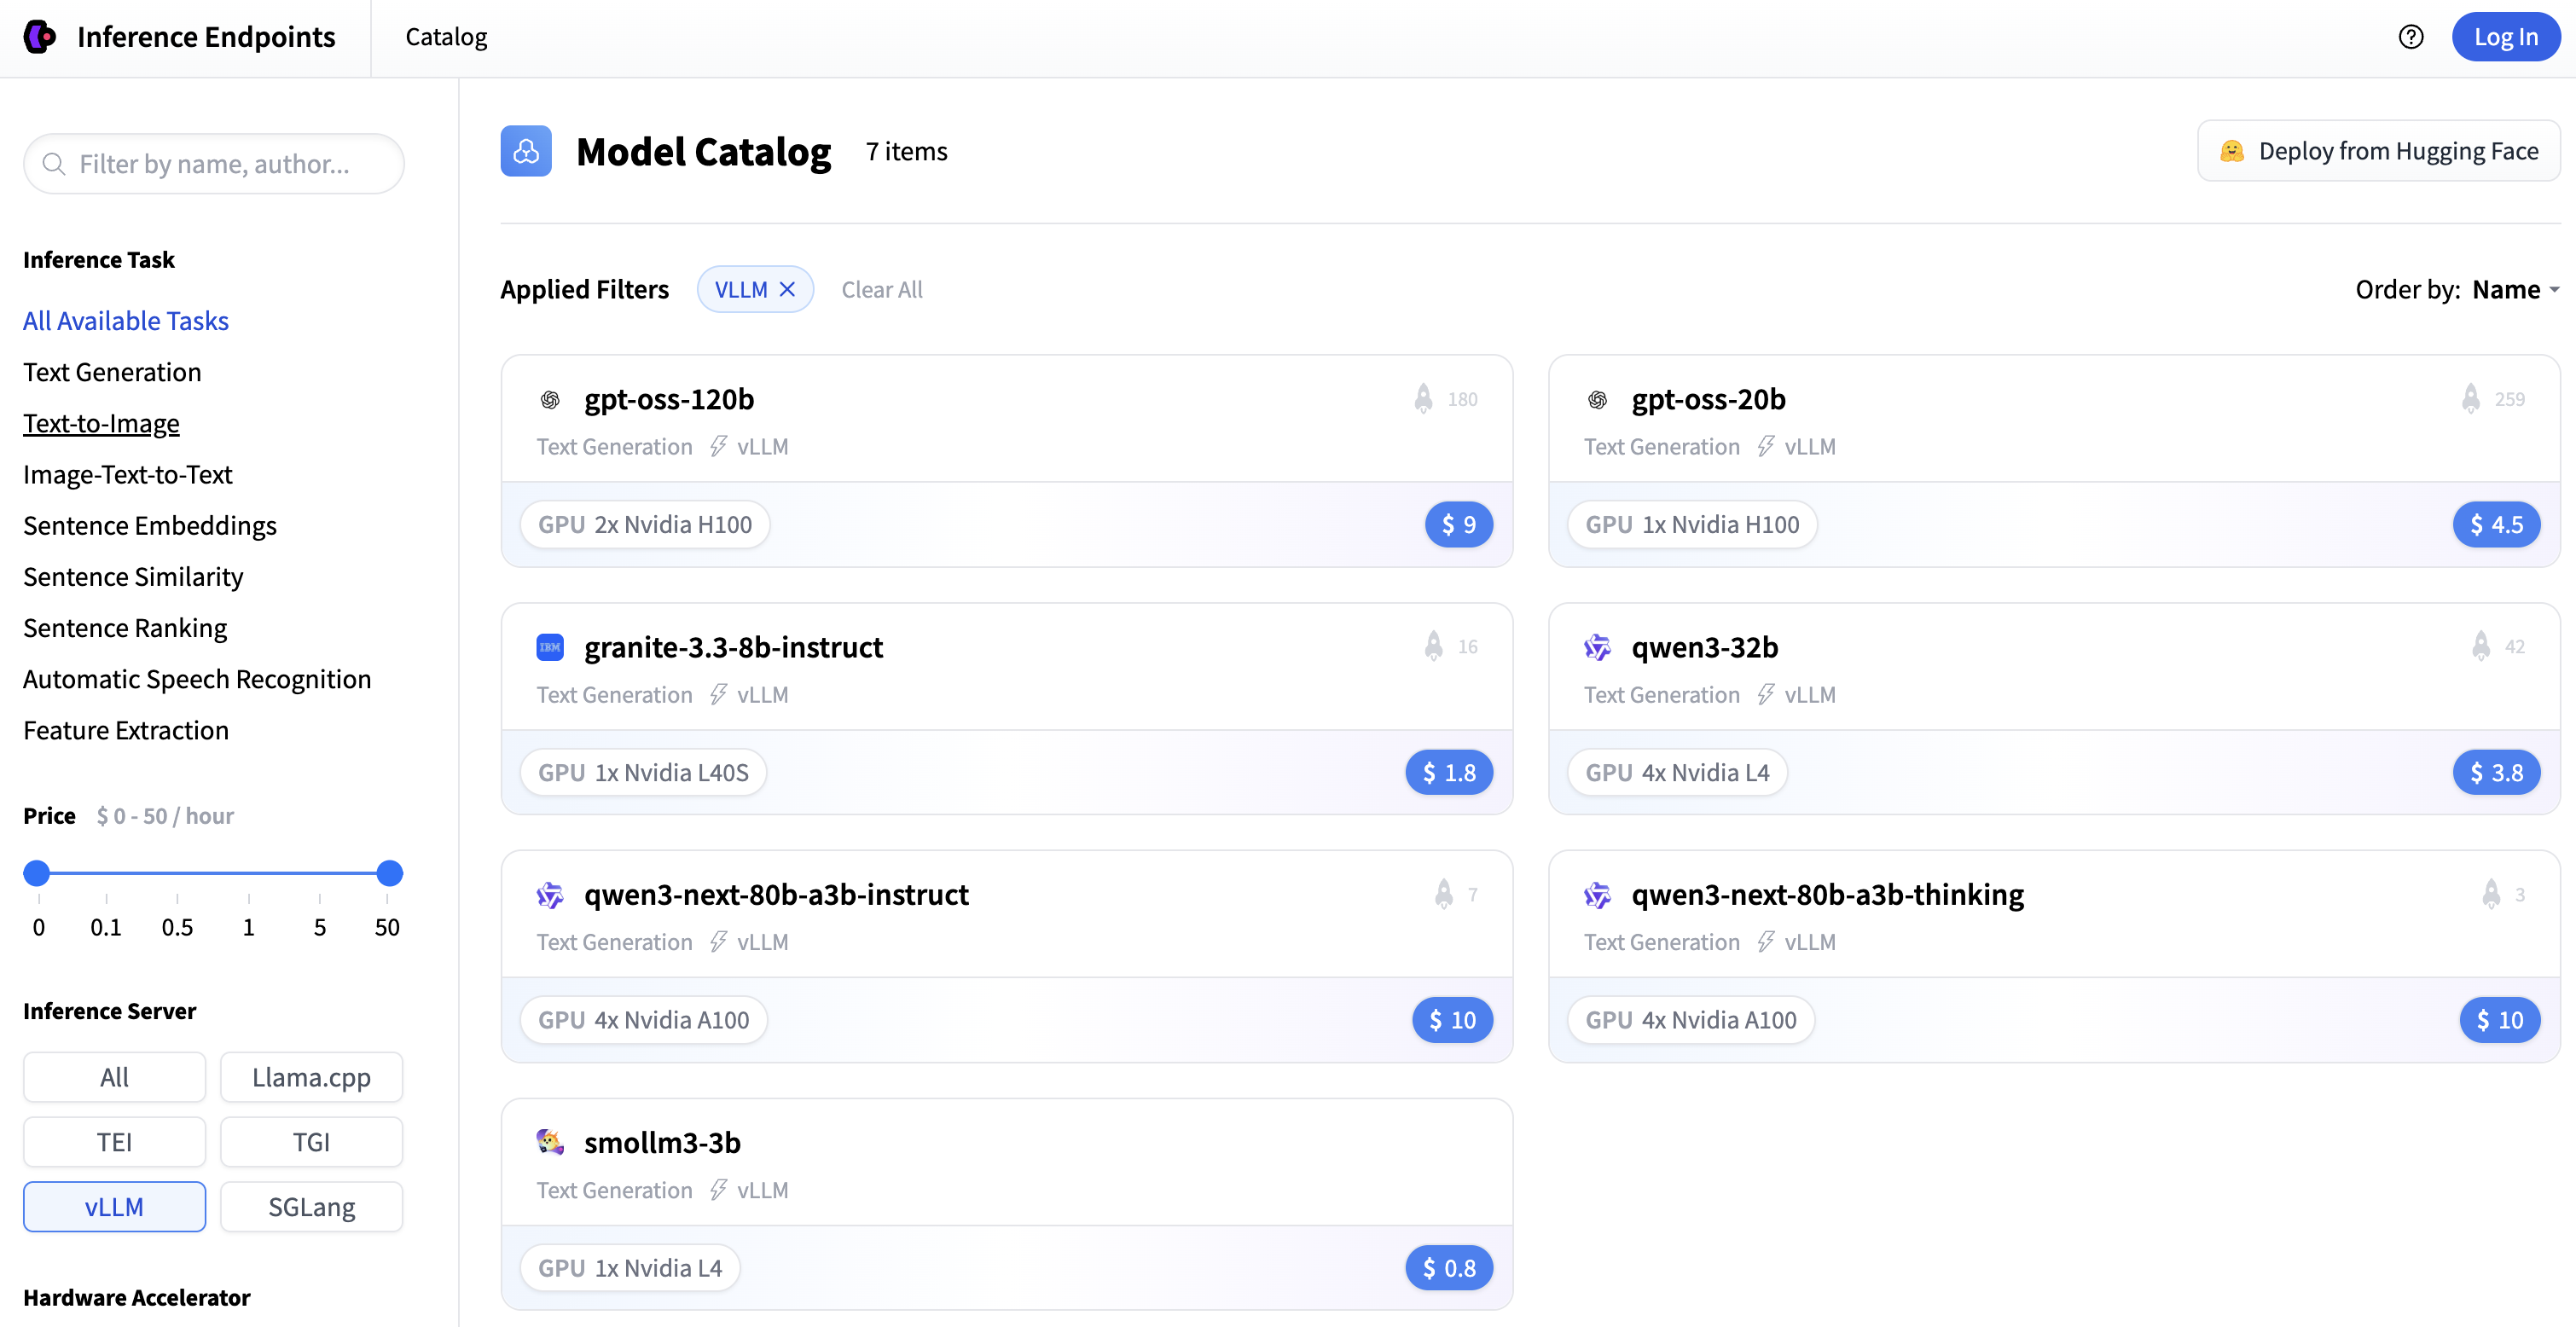
Hugging Face Inference Endpoints - vLLM

100+ vLLM Online Courses for 2026 | Explore Free Courses ...
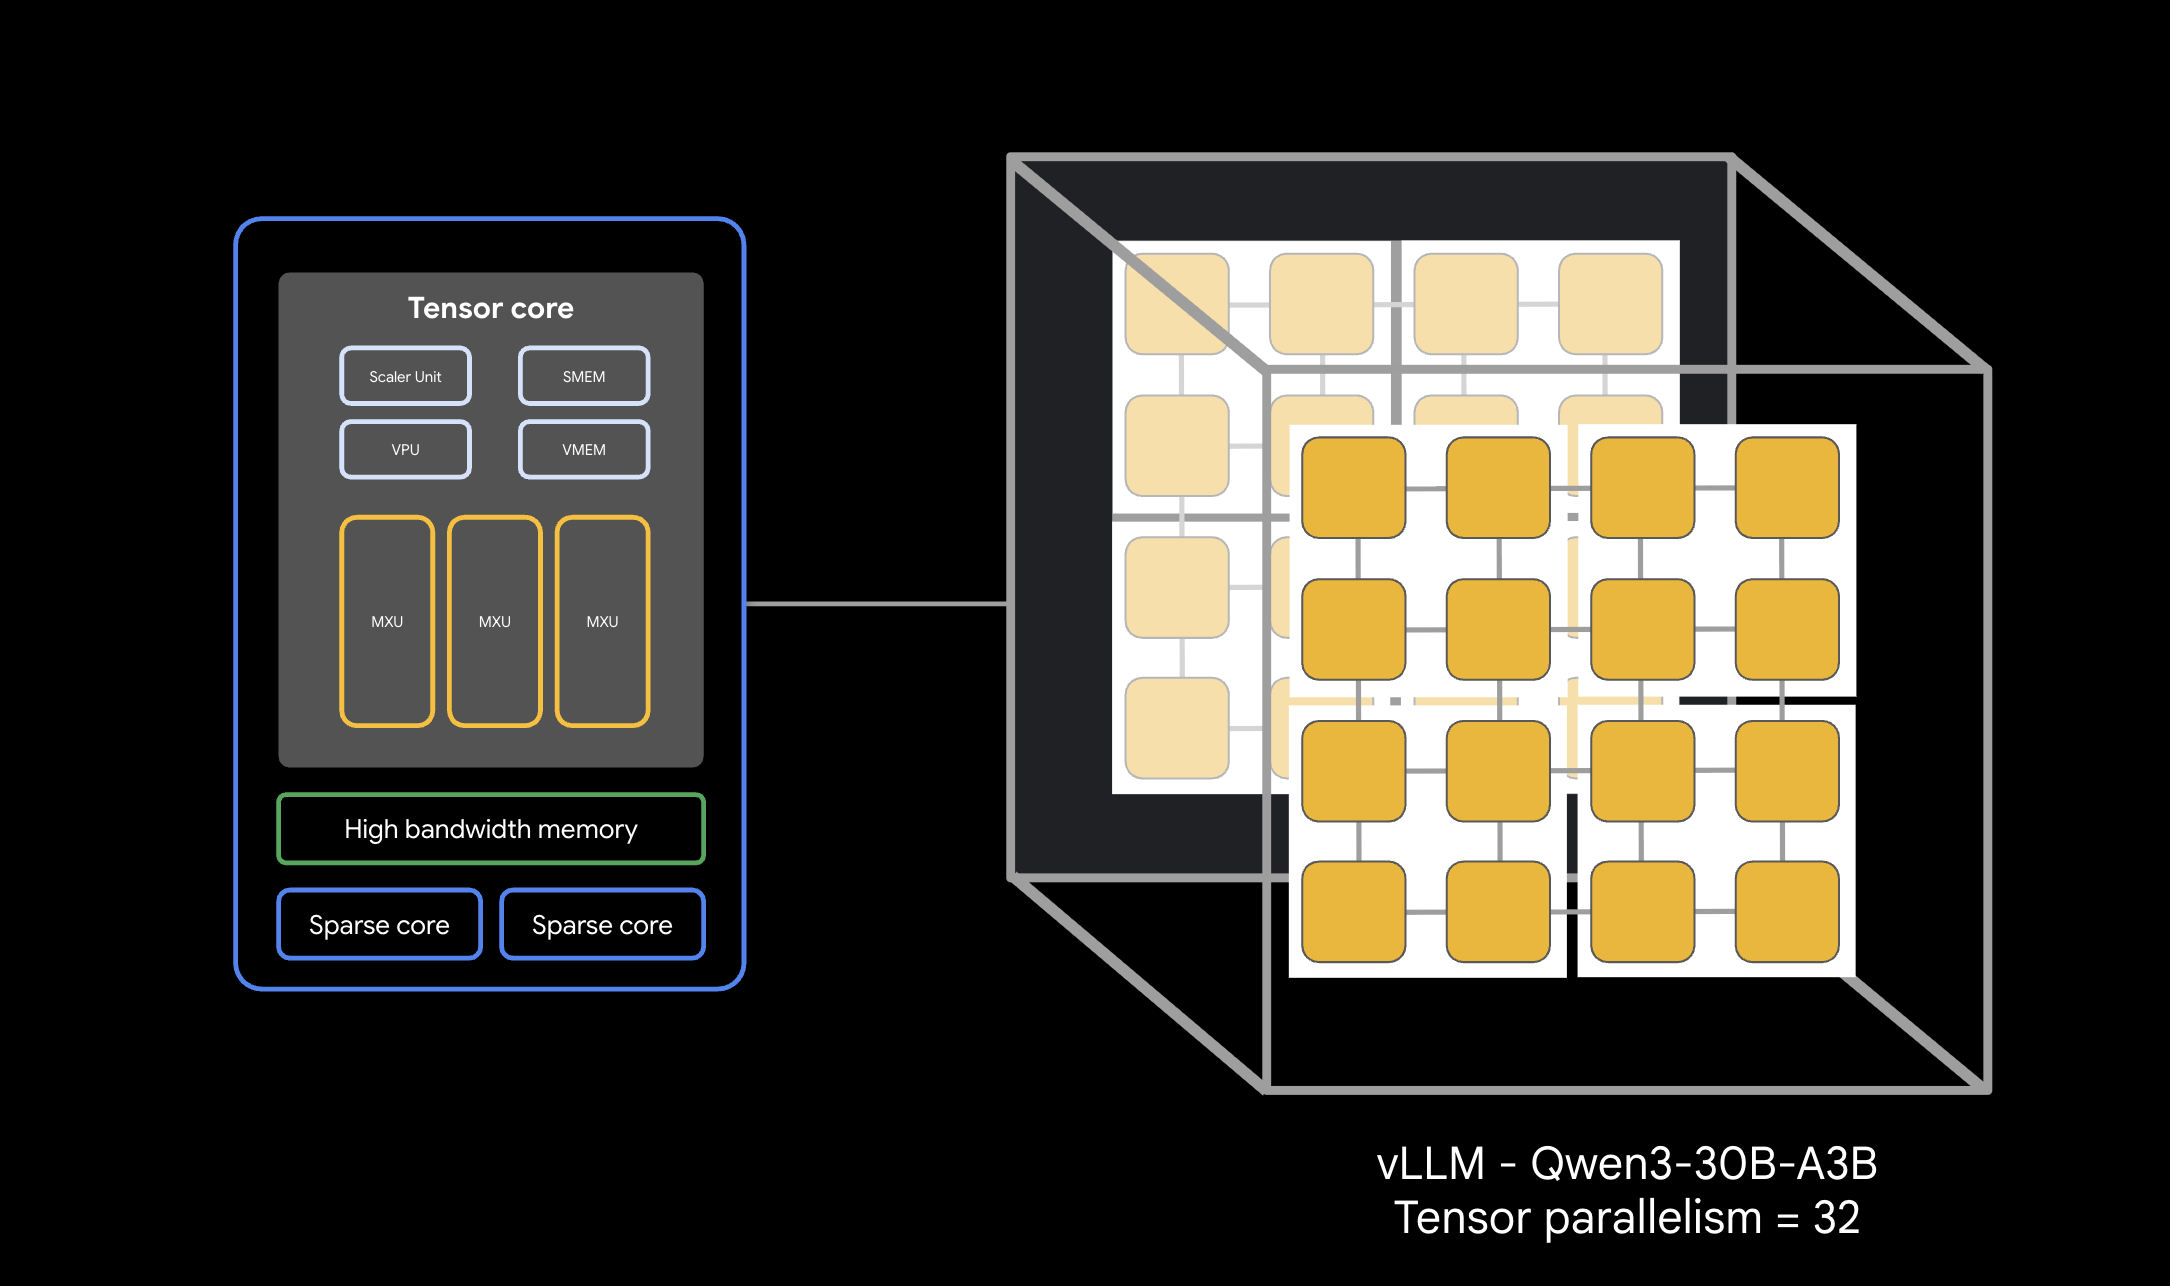
Deploy Multihost TPU vLLM Inferencing with Ray on GKE | Google Codelabs
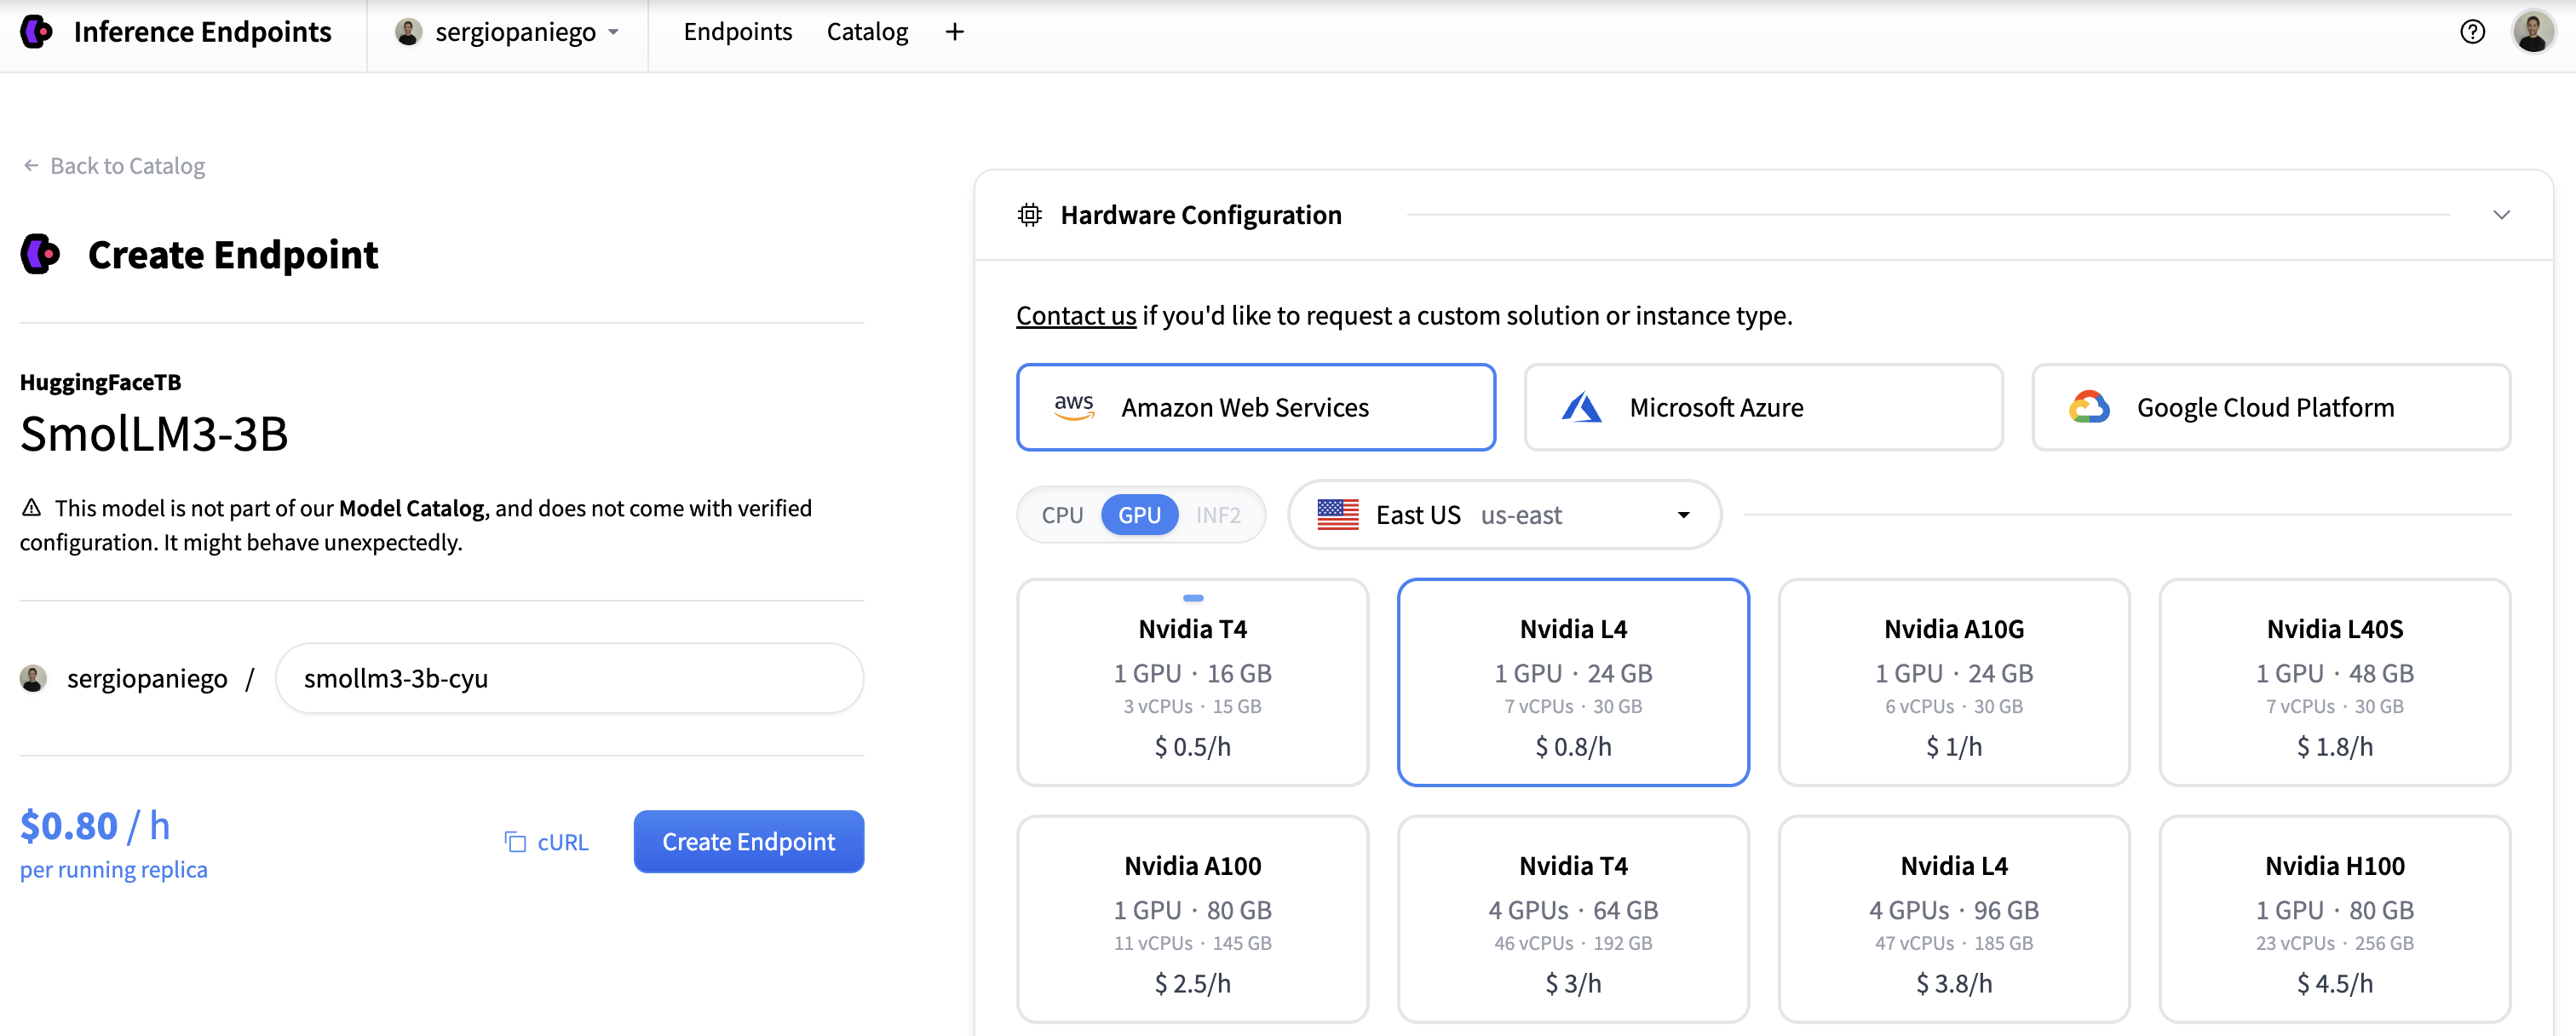
Hugging Face Inference Endpoints - vLLM
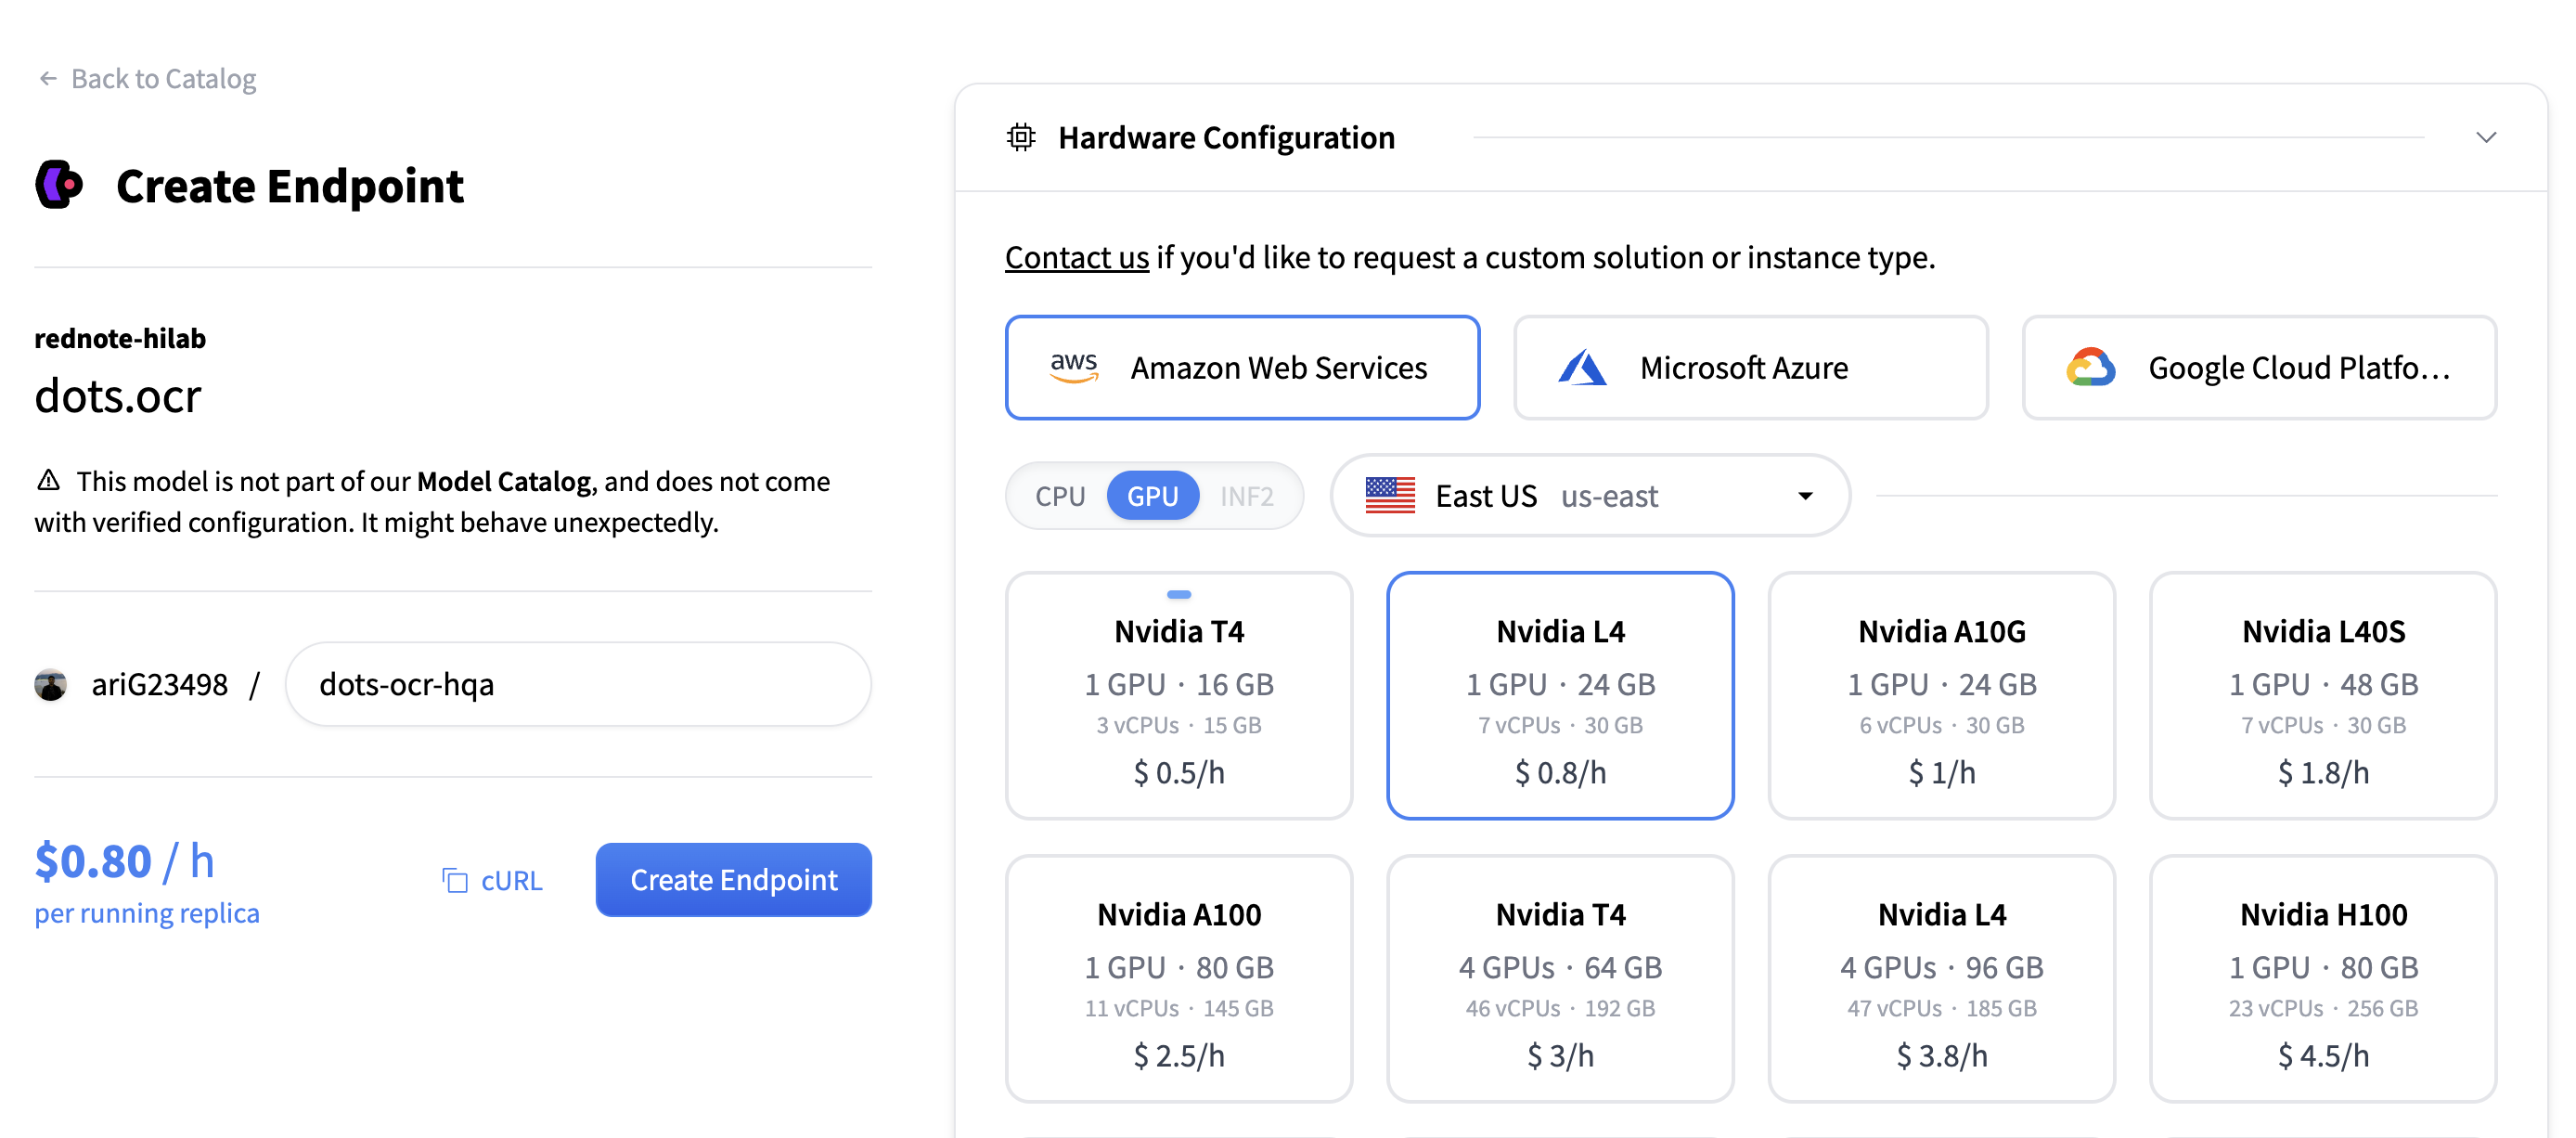
Hugging Face Inference Endpoints - vLLM
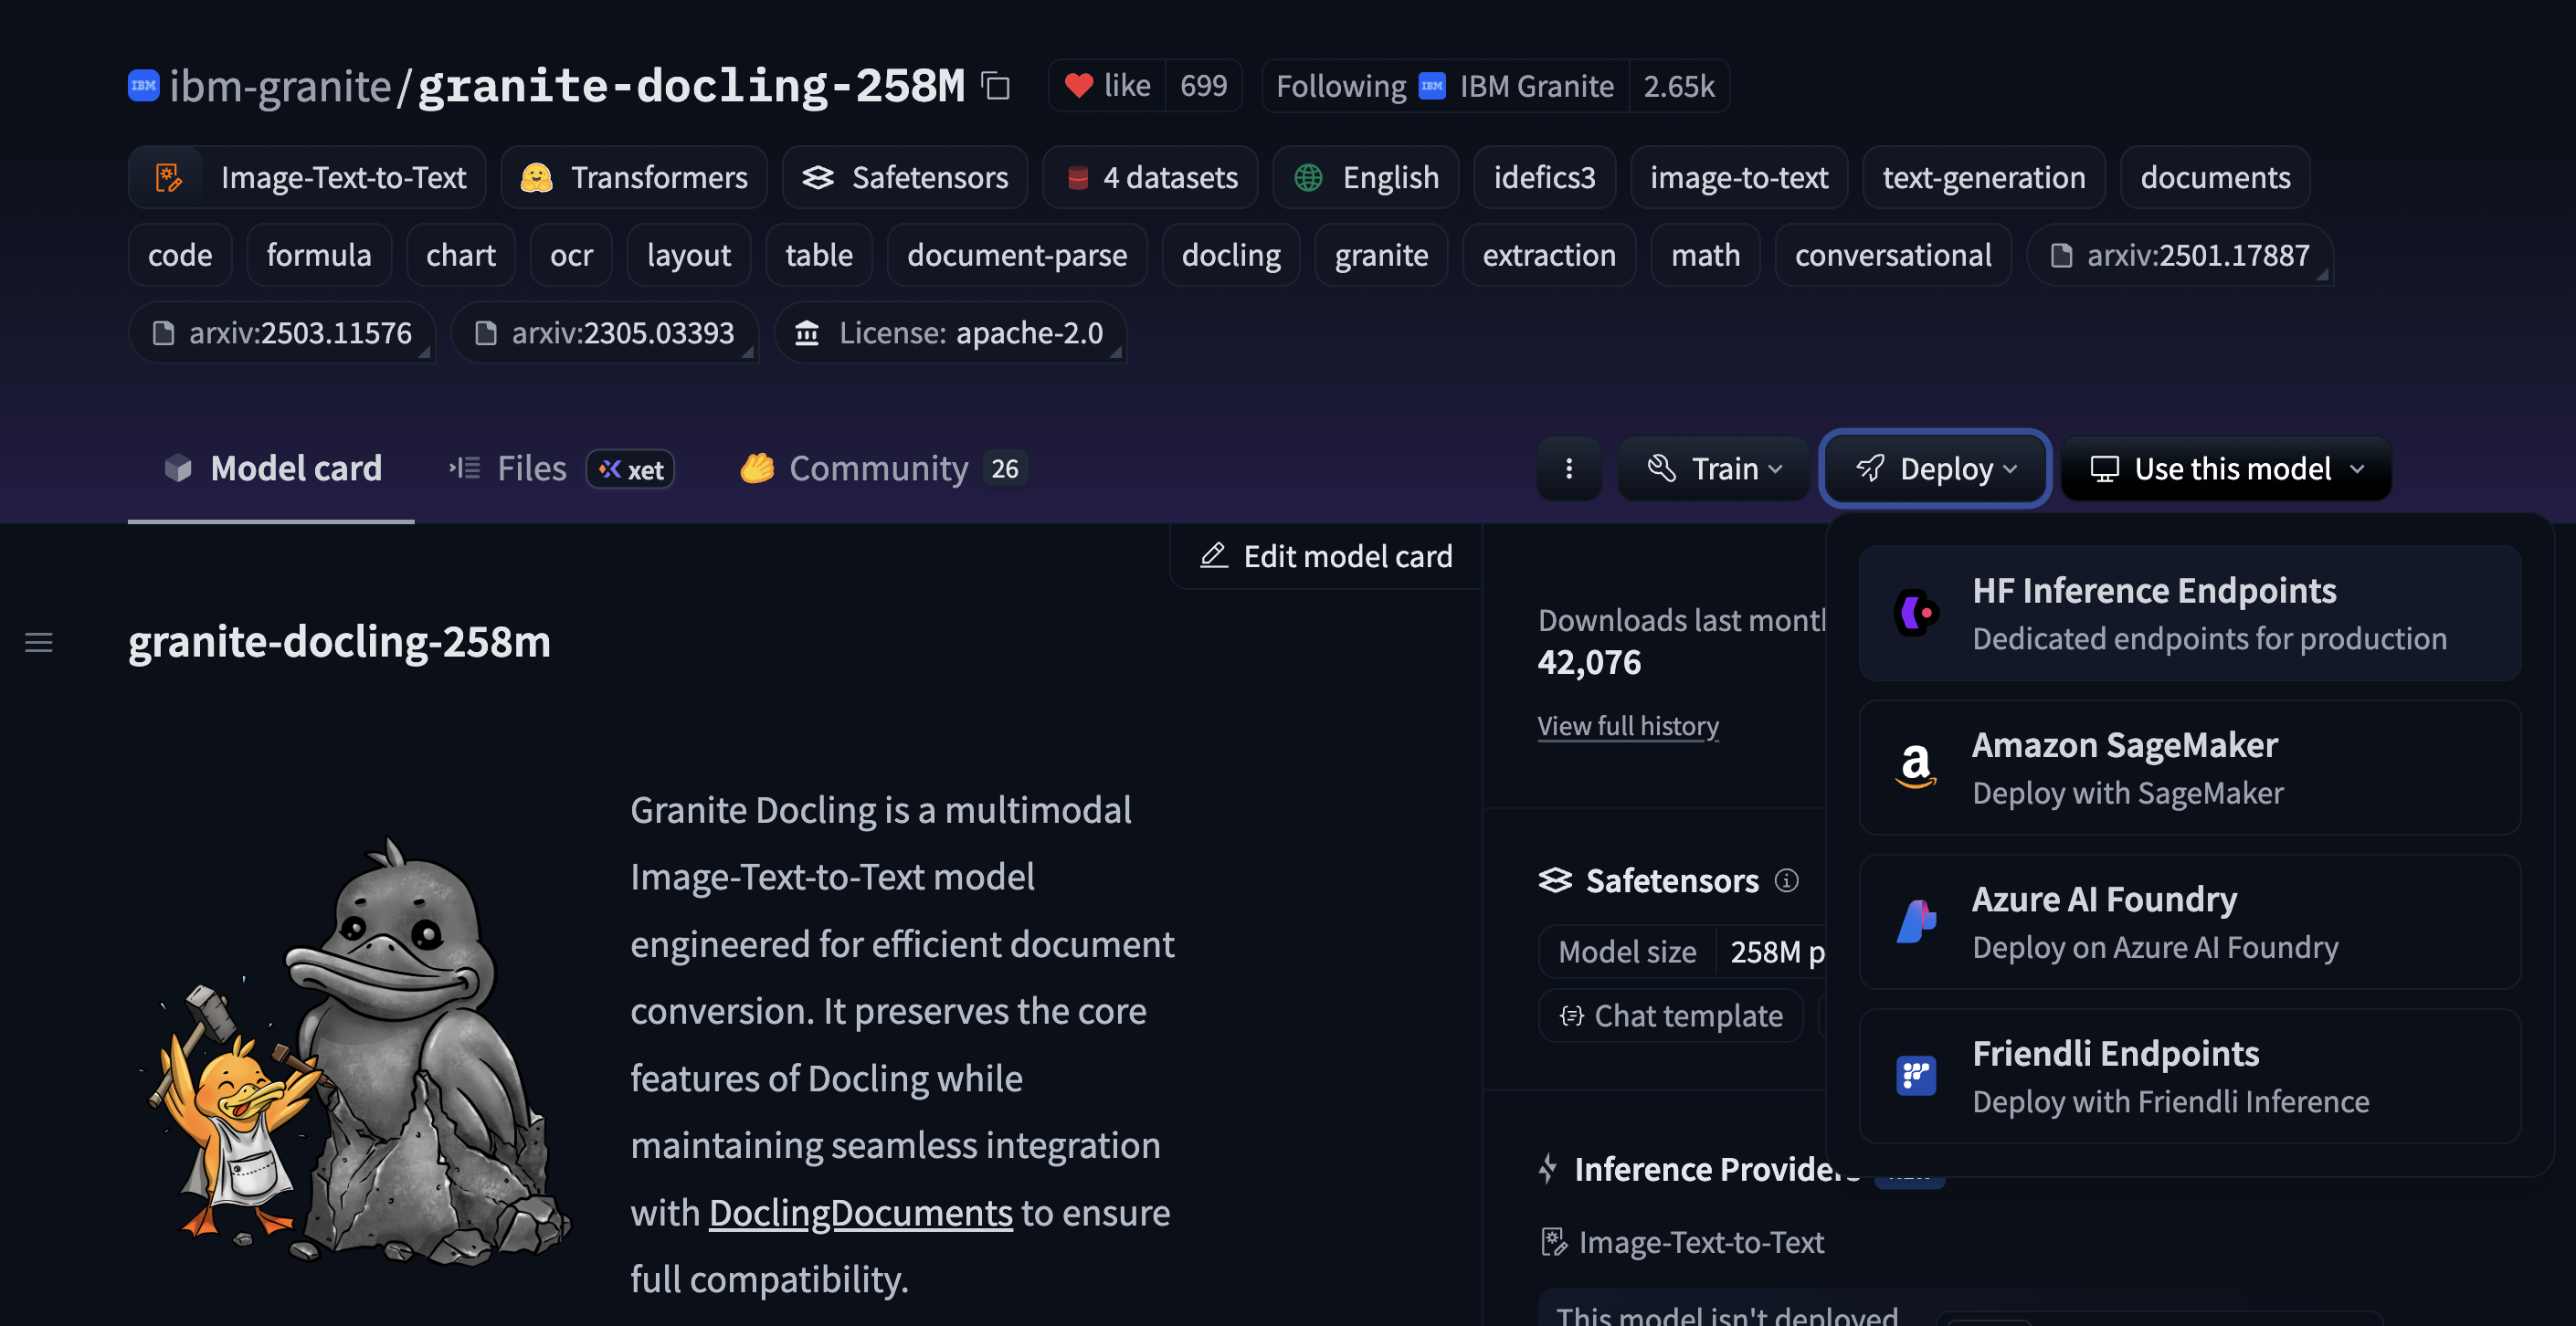
Hugging Face Inference Endpoints - vLLM

Hugging Face Inference Endpoints - vLLM
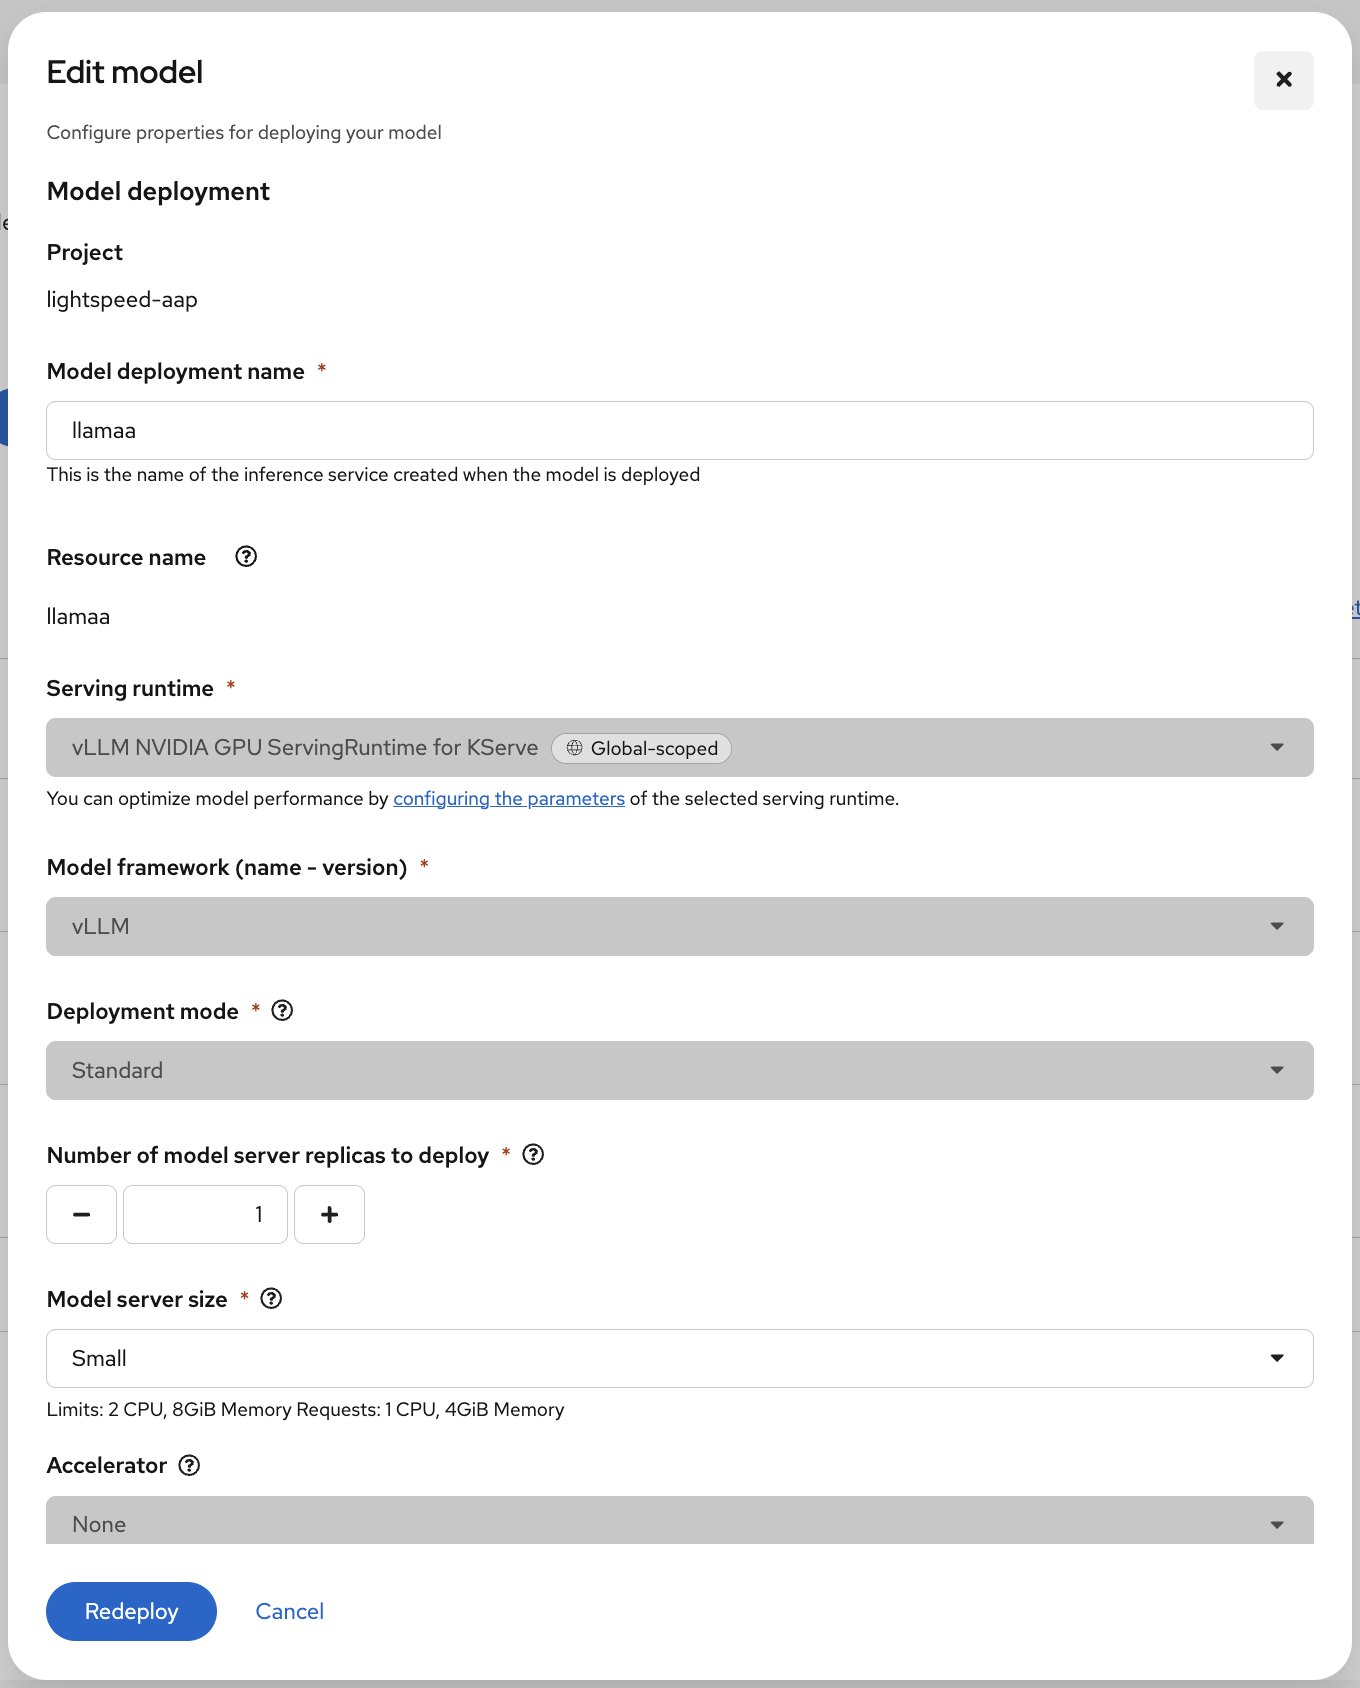
Deploy an LLM inference service on OpenShift AI | Red Hat Developer
Advertisement Space (336x280)
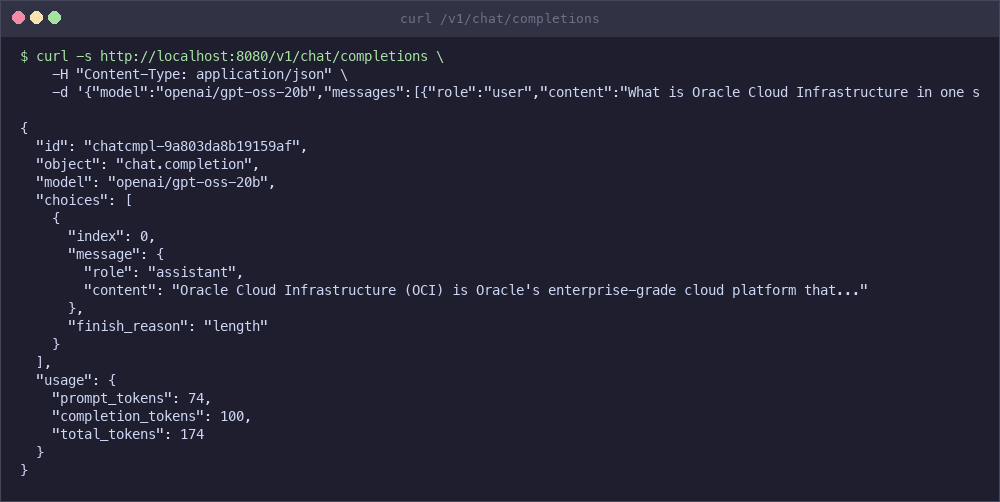
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)
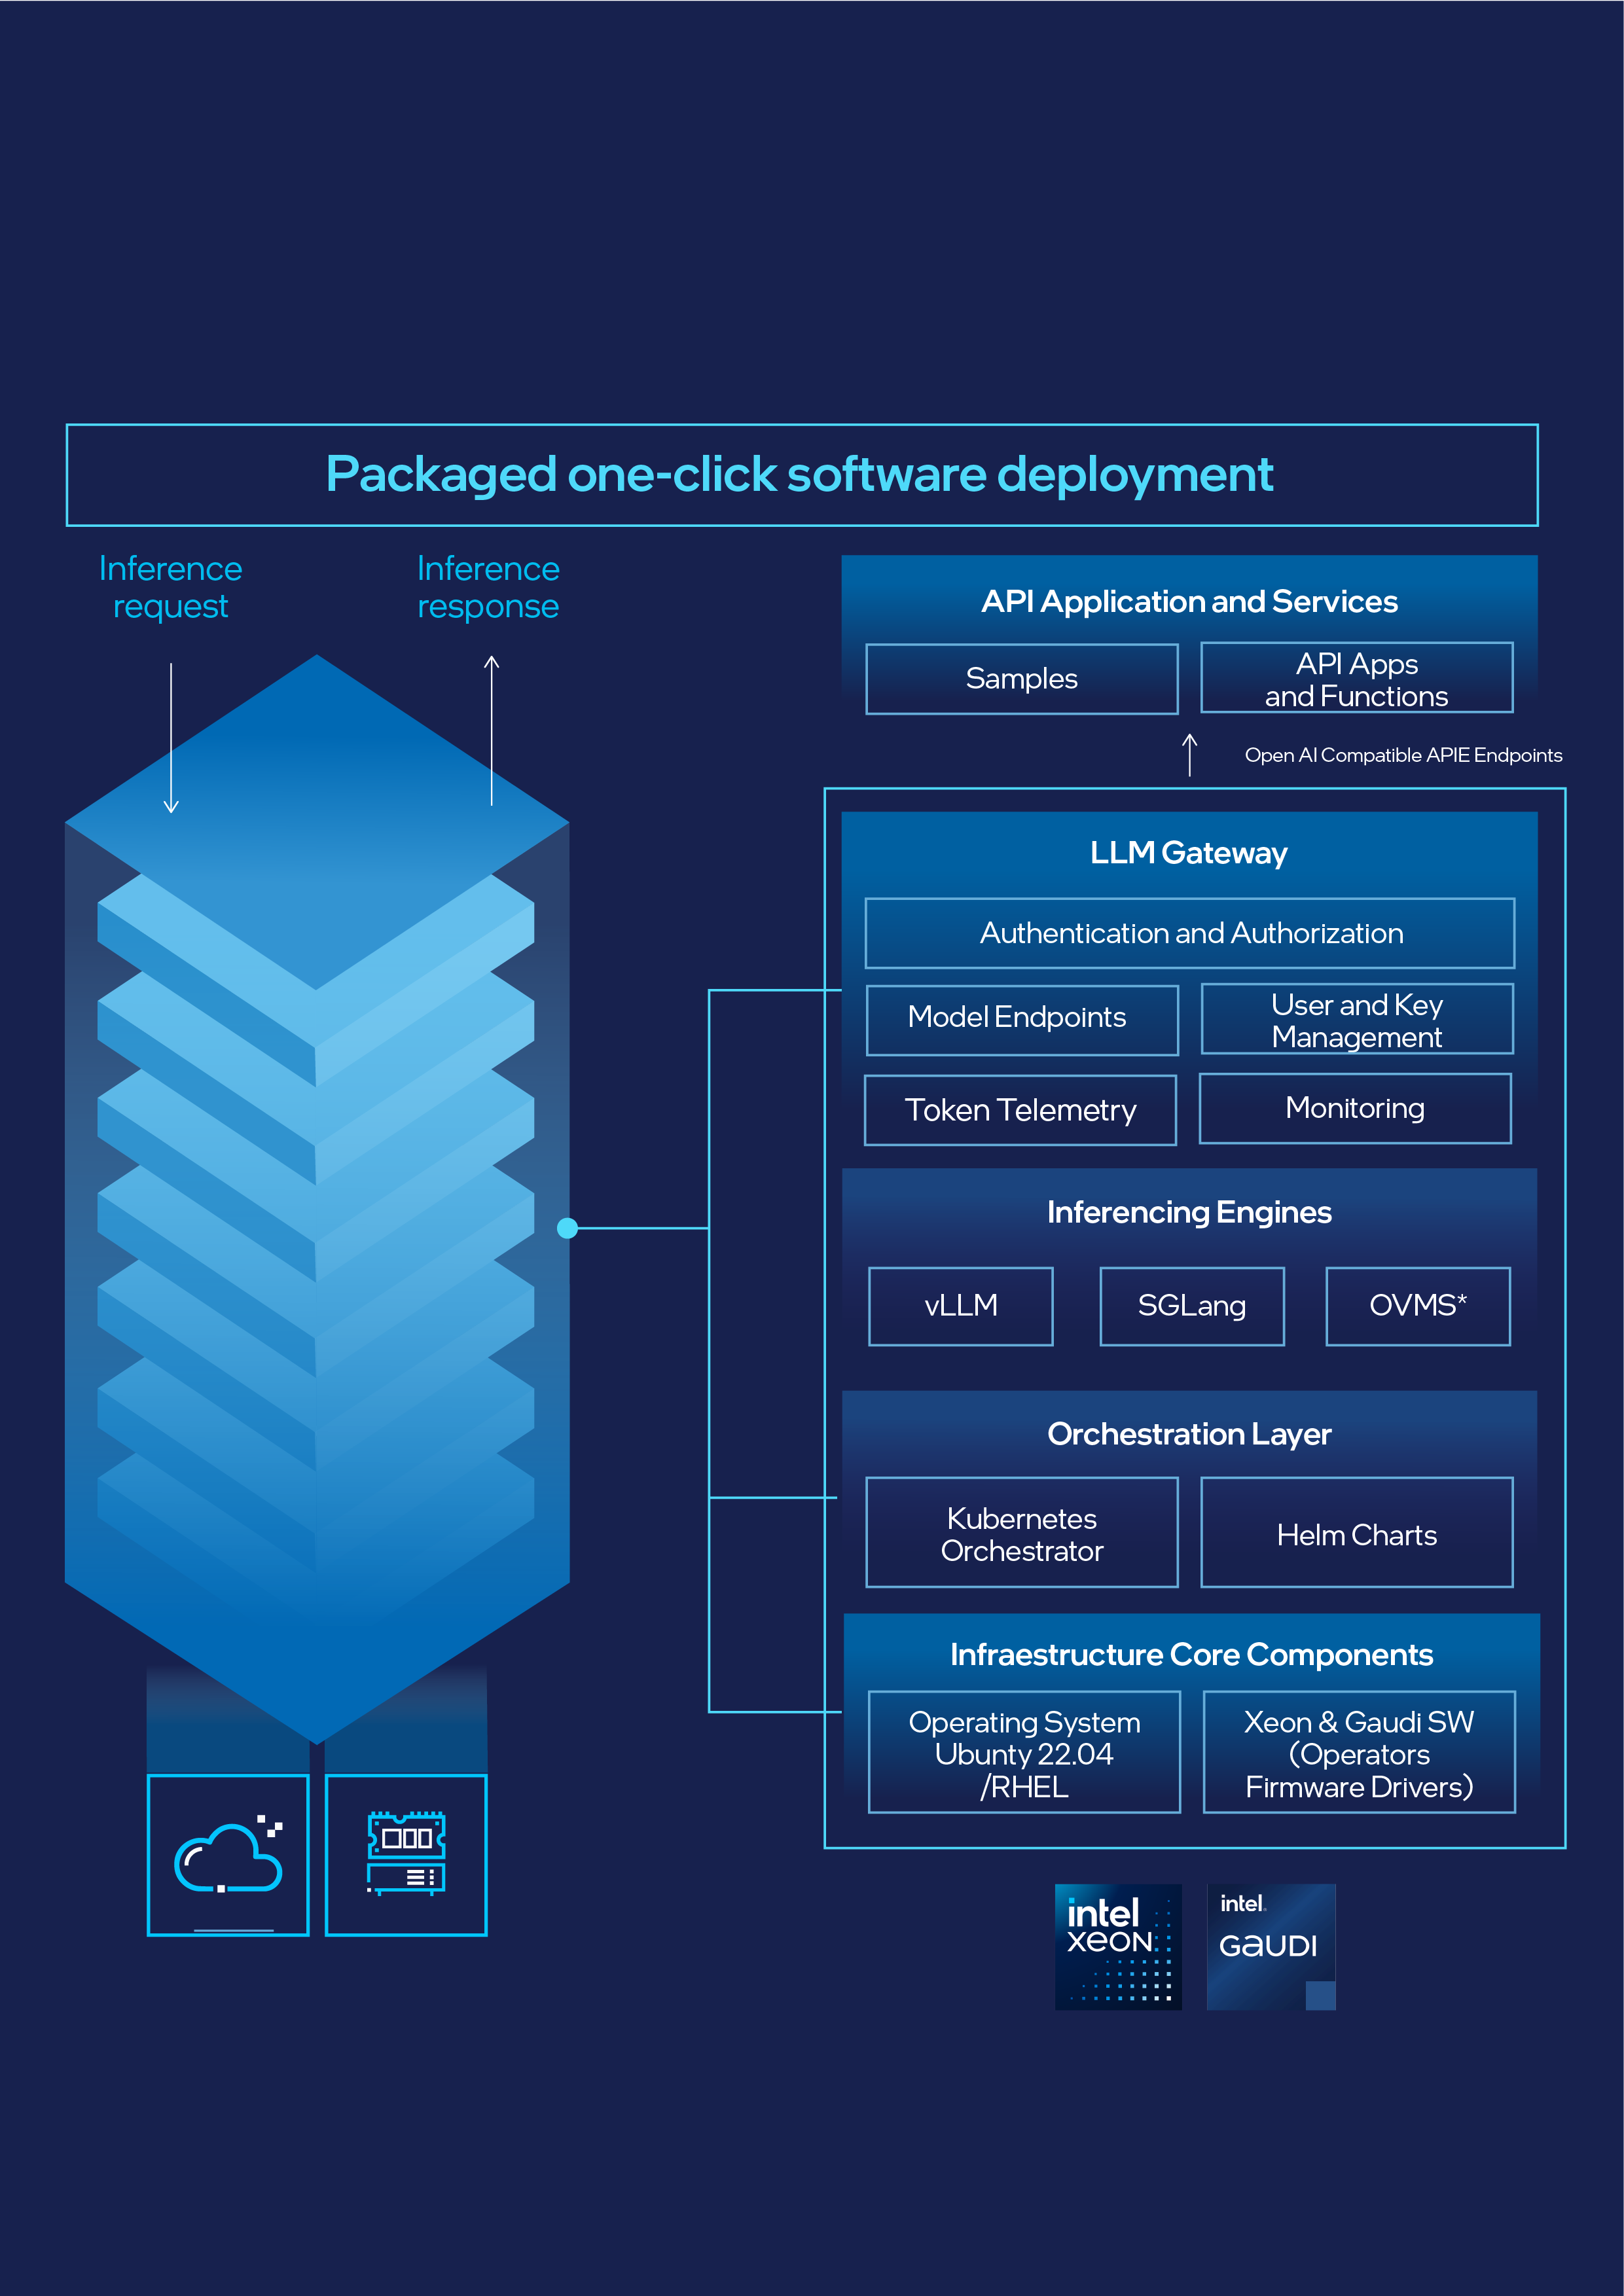
Intel® AI for Enterprise Inference
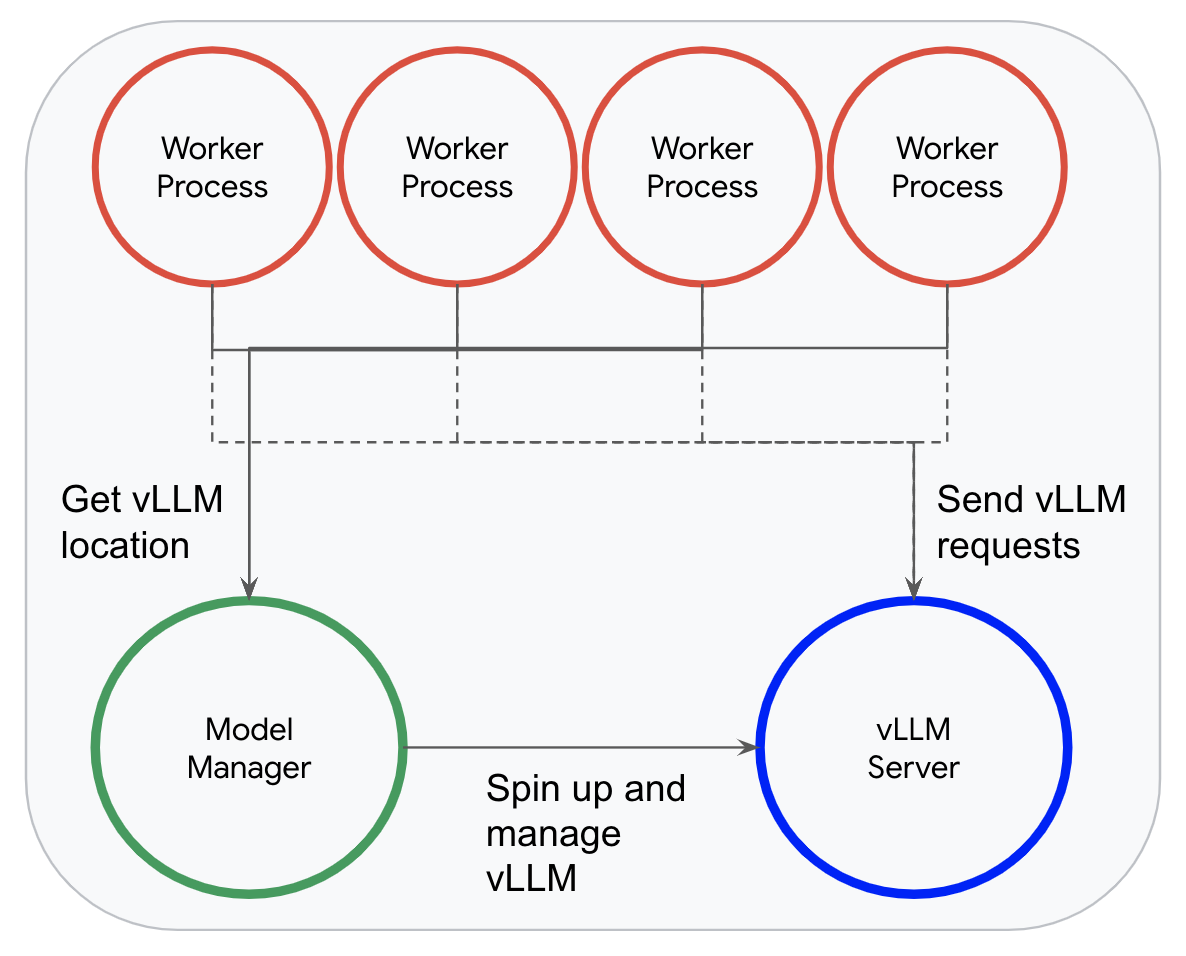
Inference with Gemma using Dataflow and vLLM - Google Developers Blog

vLLM High-Throughput LLM Inference Guide | PDF | Cache (Computing ...
Big Win for Secure AI Inference: vLLM Adds Prompt Embedding Support ...
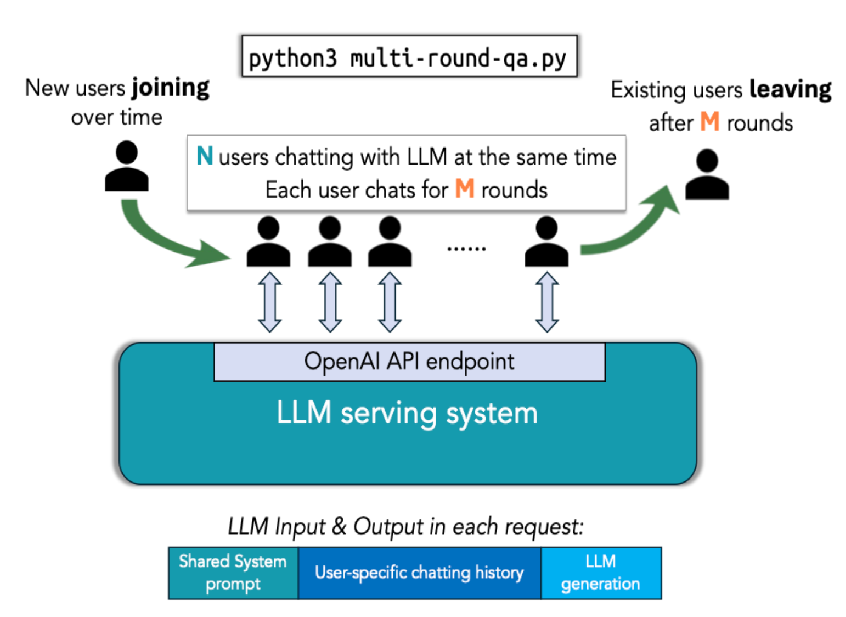
Deploy DeepSeek-R1 with the vLLM V1 engine and build an AI-powered ...