
Develop Ml And Ai With Metaflow And Deploy With Nvidia Triton Inference

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...
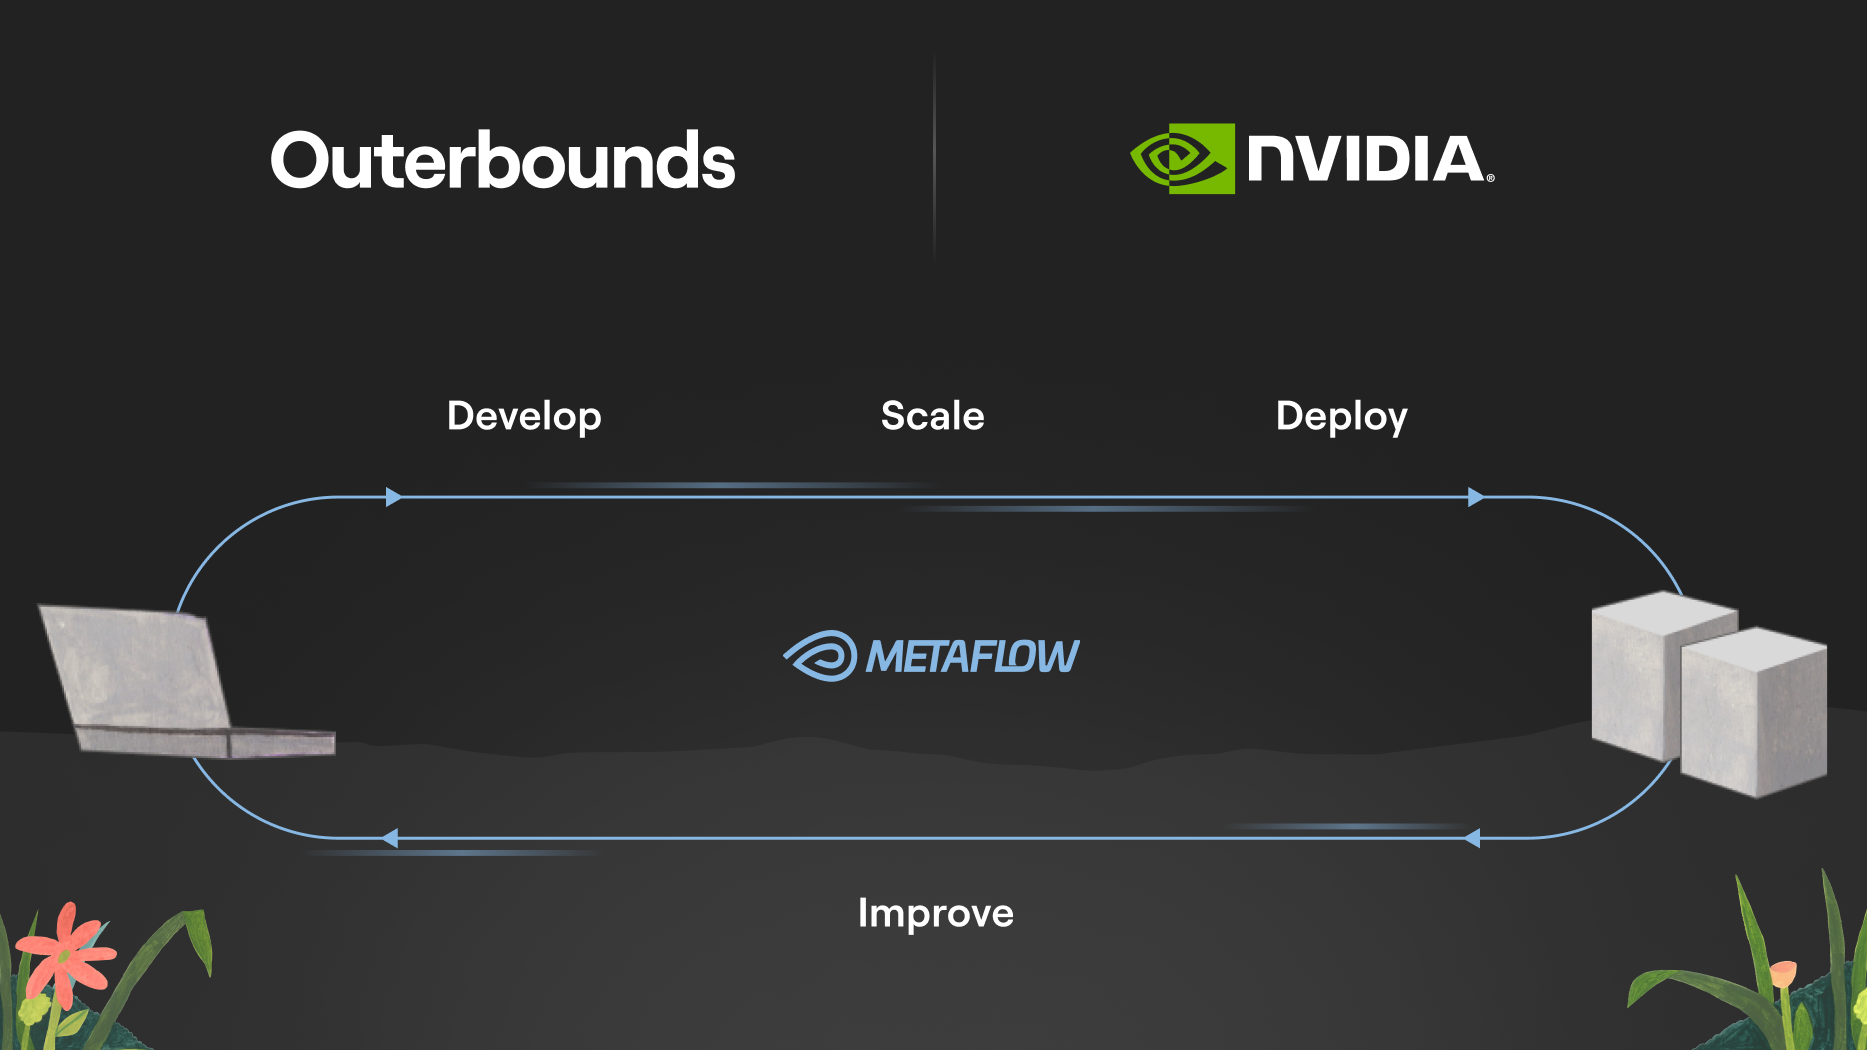
Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Deploy fast and scalable AI with NVIDIA Triton Inference Server in ...
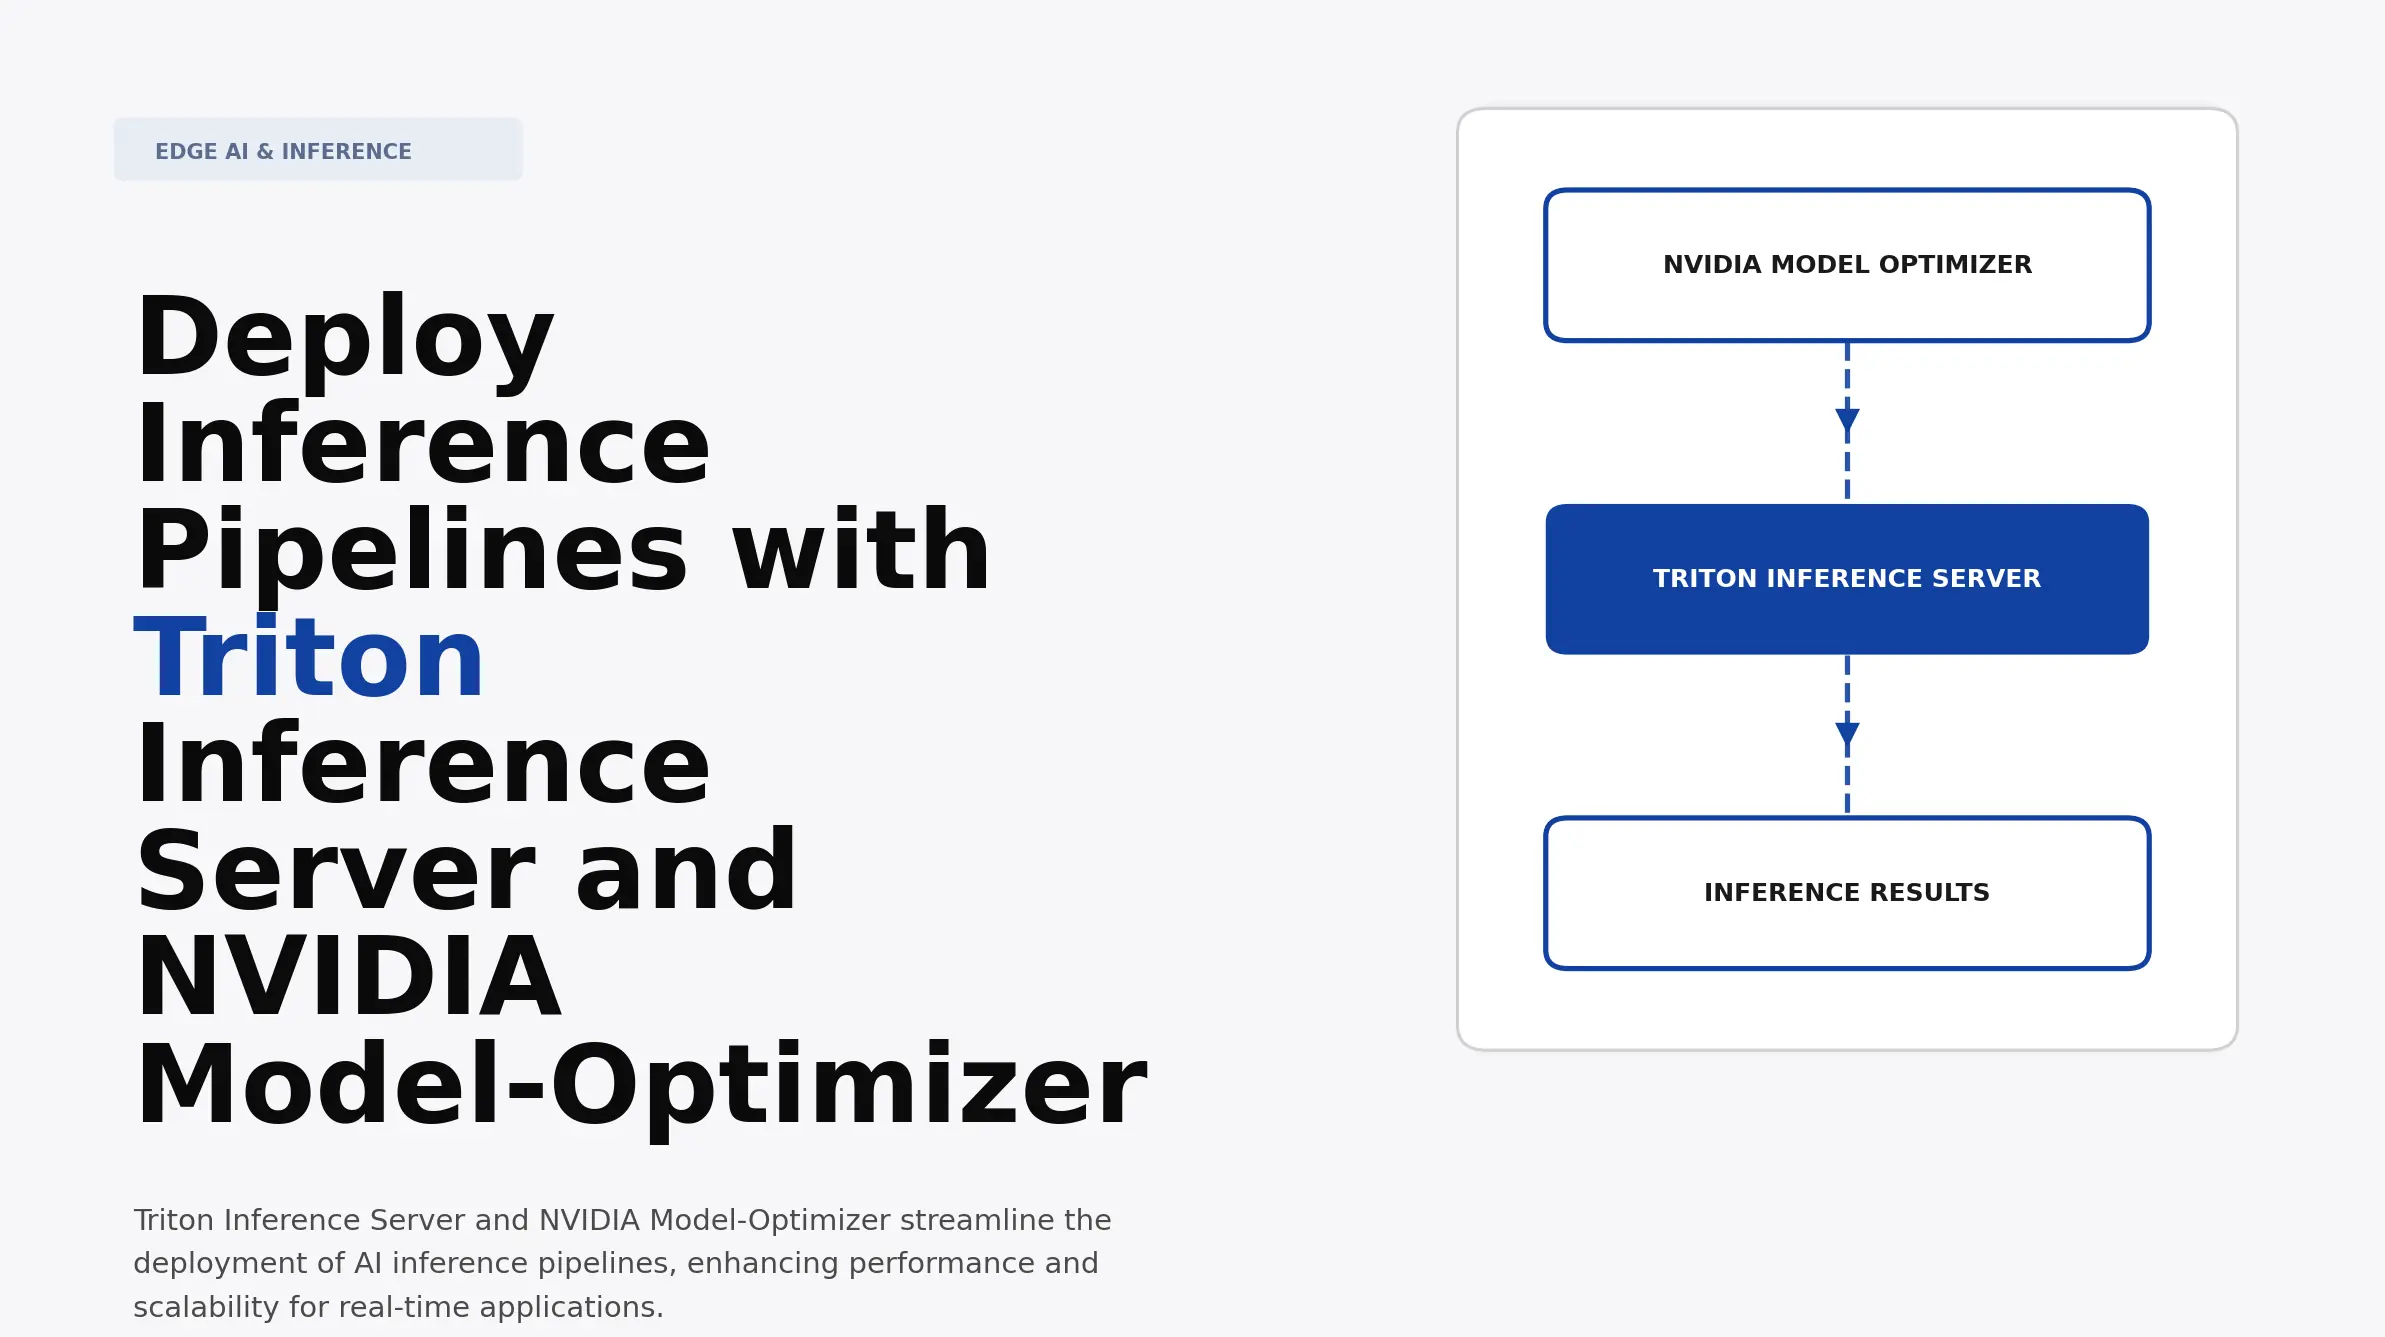
Deploy Inference Pipelines with Triton Inference Server and NVIDIA ...

Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...

Serving and Managing ML models with Mlflow and Nvidia Triton Inference ...
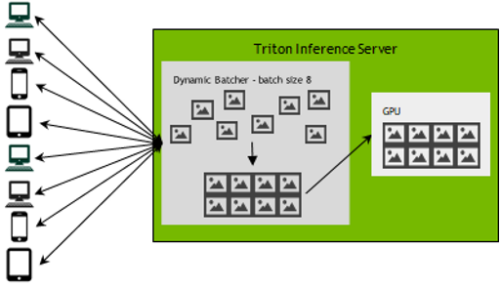
Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...
Advertisement Space (300x250)
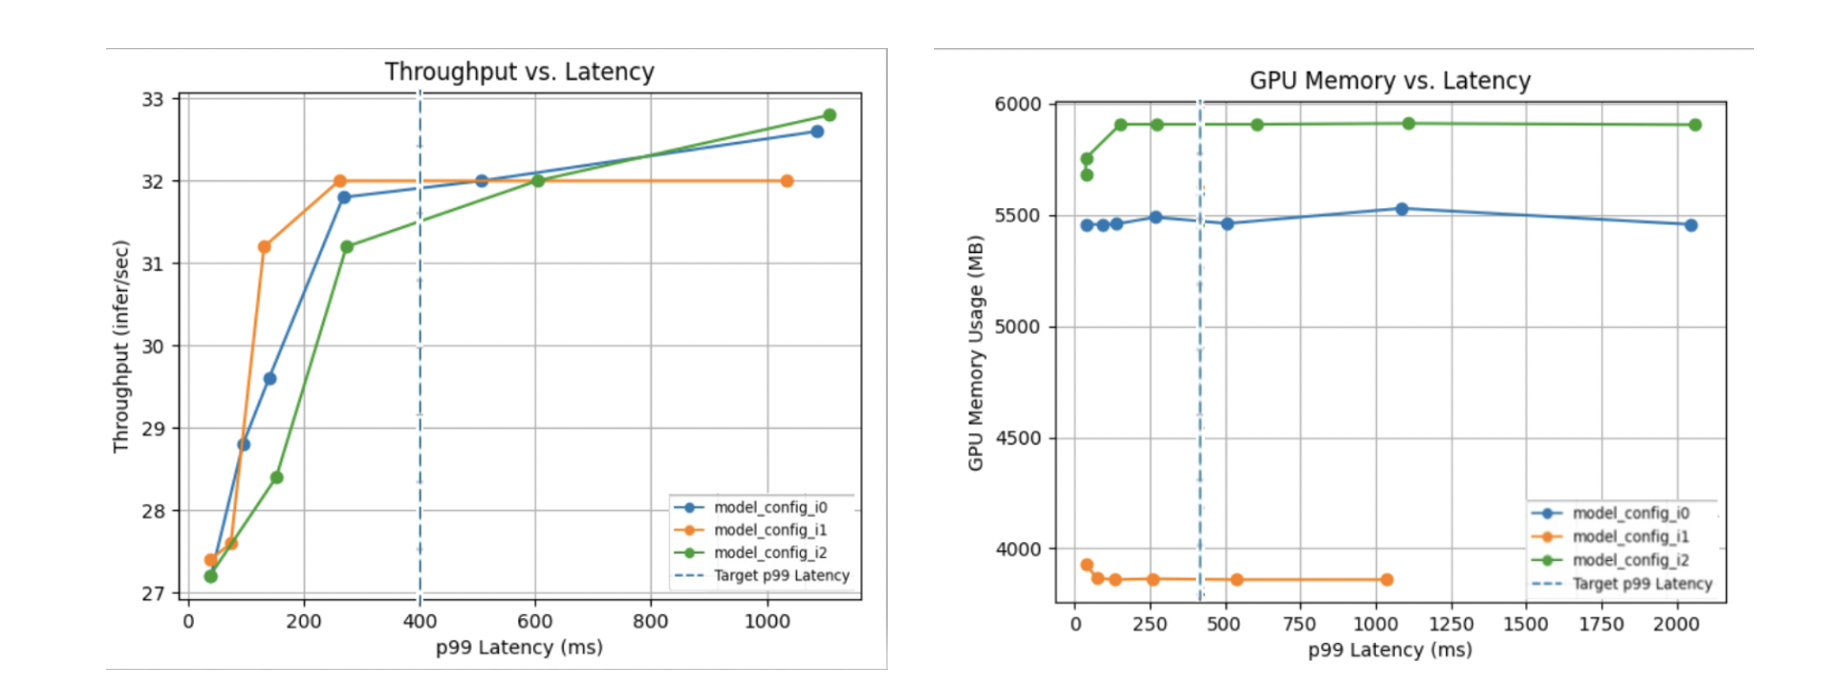
Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...

Free Video: Develop and Deploy ML Projects with Metaflow and Seldon ...
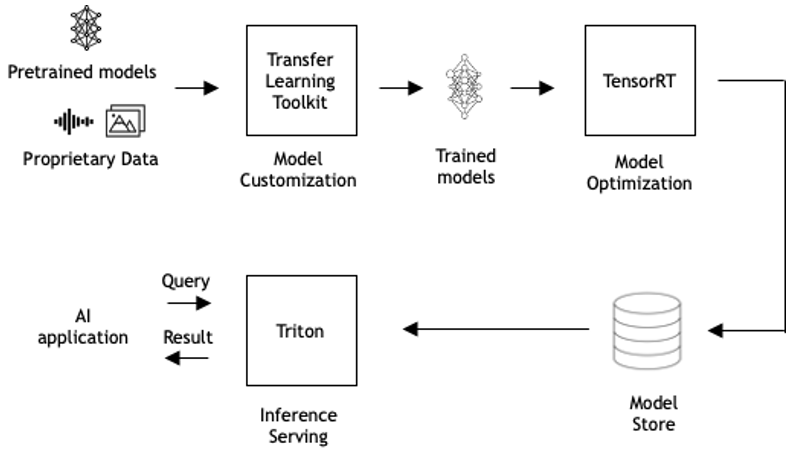
Simplifying and Scaling Inference Serving with NVIDIA Triton 2.3 ...
Deploying ML Models with NVIDIA Triton Inference Server | Rosepetal AI Blog

Train Your AI Model Once and Deploy on Any Cloud with NVIDIA and Run:ai ...

Deploy an AI Coding Assistant with NVIDIA TensorRT-LLM and NVIDIA ...
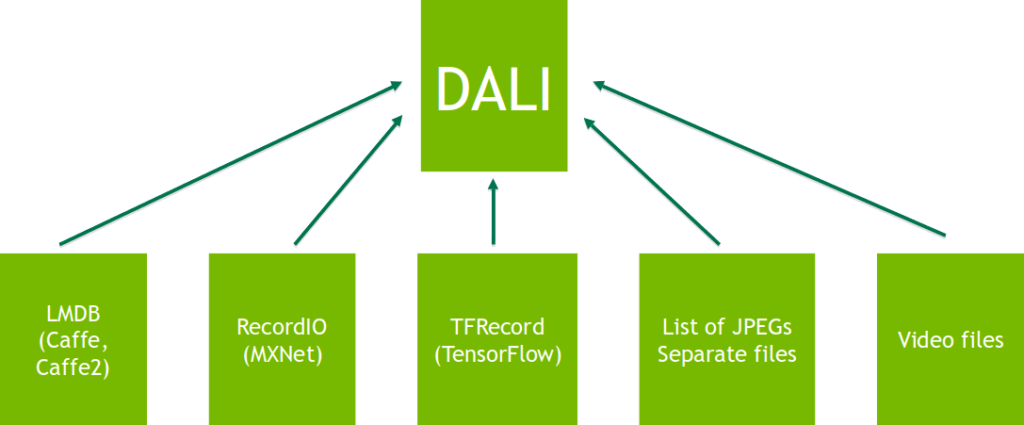
Accelerating Inference with NVIDIA Triton Inference Server and NVIDIA ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
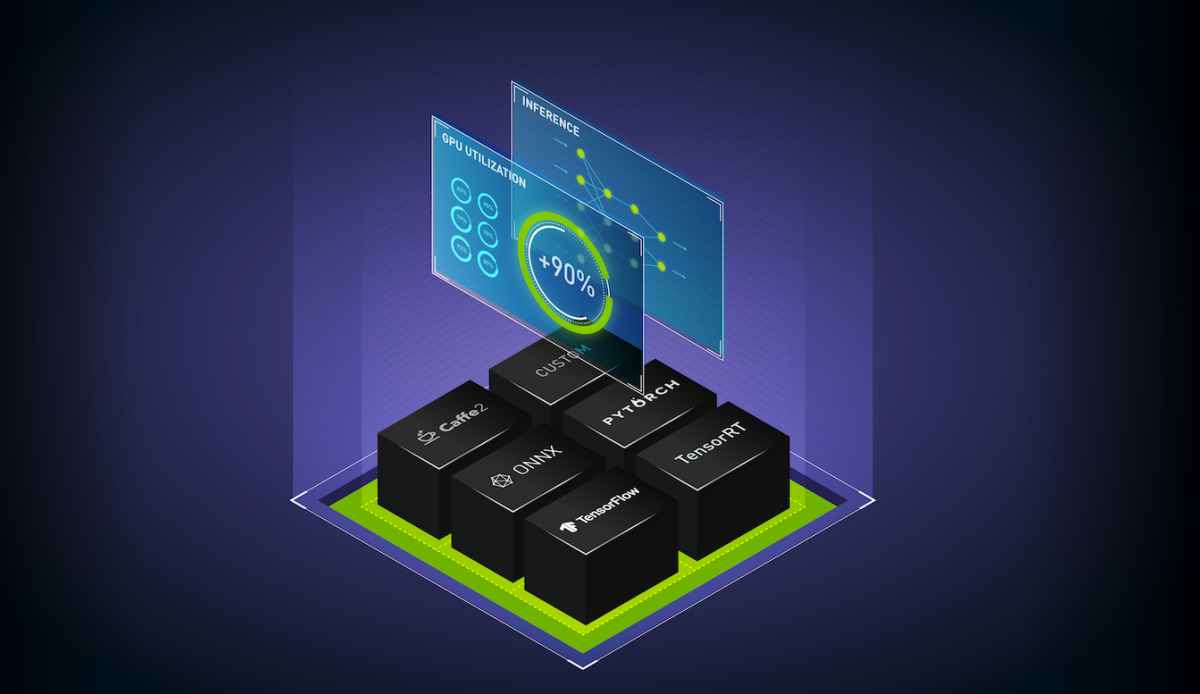
Deploying AI Deep Learning Models with NVIDIA Triton Inference Server ...
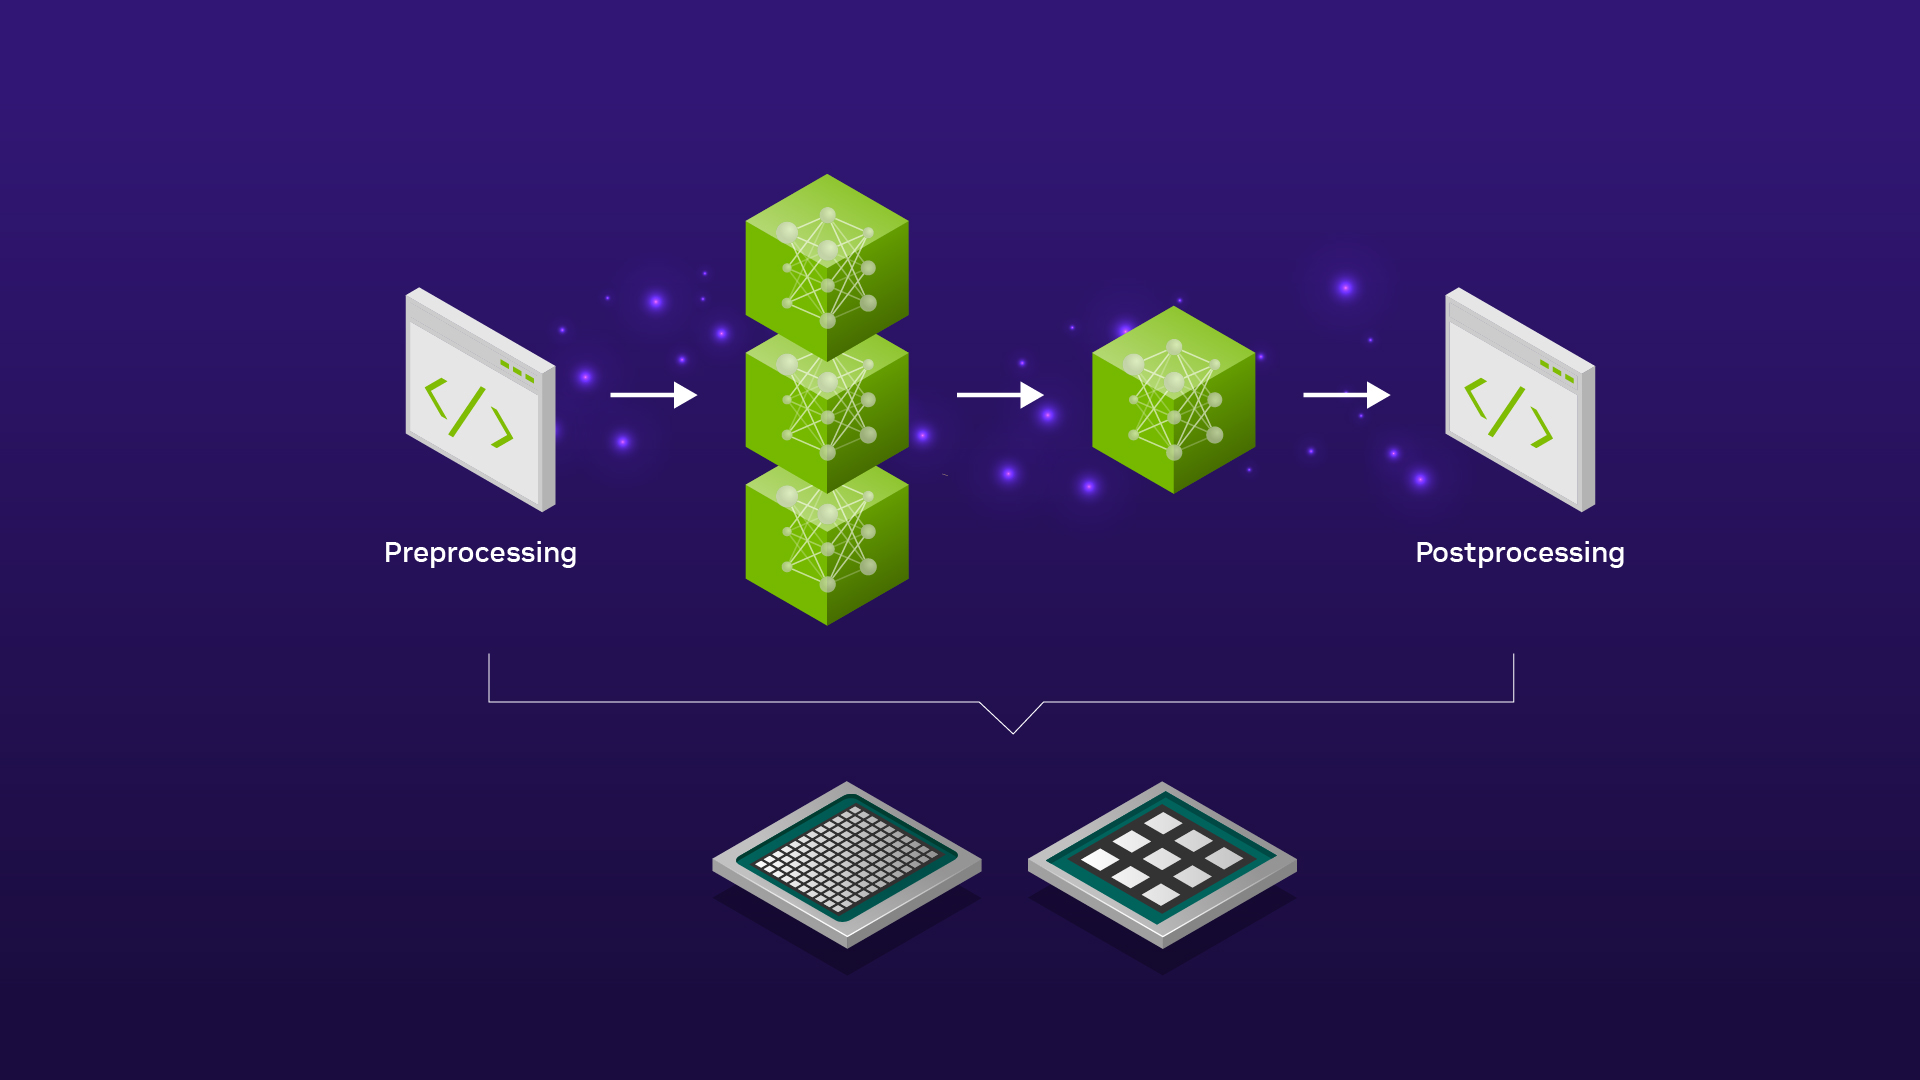
Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Advertisement Space (336x280)

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Easily Deploy AI Deep Learning Models at Scale with Triton Inference ...
Simplifying AI Inference with NVIDIA Triton Inference Server from ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Configure, Deploy and Operate Nvidia Triton Inference Server - Rafay ...

Accelerating Inference on End-to-End Workflows with H2O.ai and NVIDIA ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Simplifying AI Inference with NVIDIA Triton Inference Server from ...

Deploy Nvidia Triton Inference Server with MinIO as Model Store - The ...
Advertisement Space (336x280)

Optimizing Real-Time ML Inference with Nvidia Triton Inference Server ...
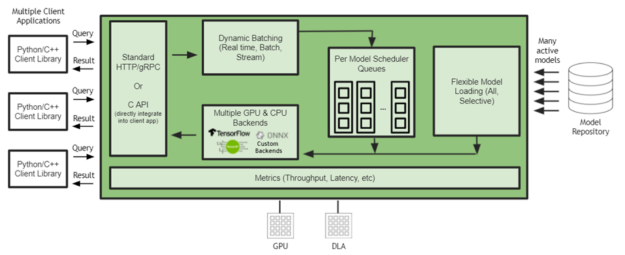
Simplifying AI Model Deployment at the Edge with NVIDIA Triton ...

Optimize AI Inference Performance with NVIDIA Full-Stack Solutions ...

Serving TensorRT Models with NVIDIA Triton Inference Server | by Tan ...
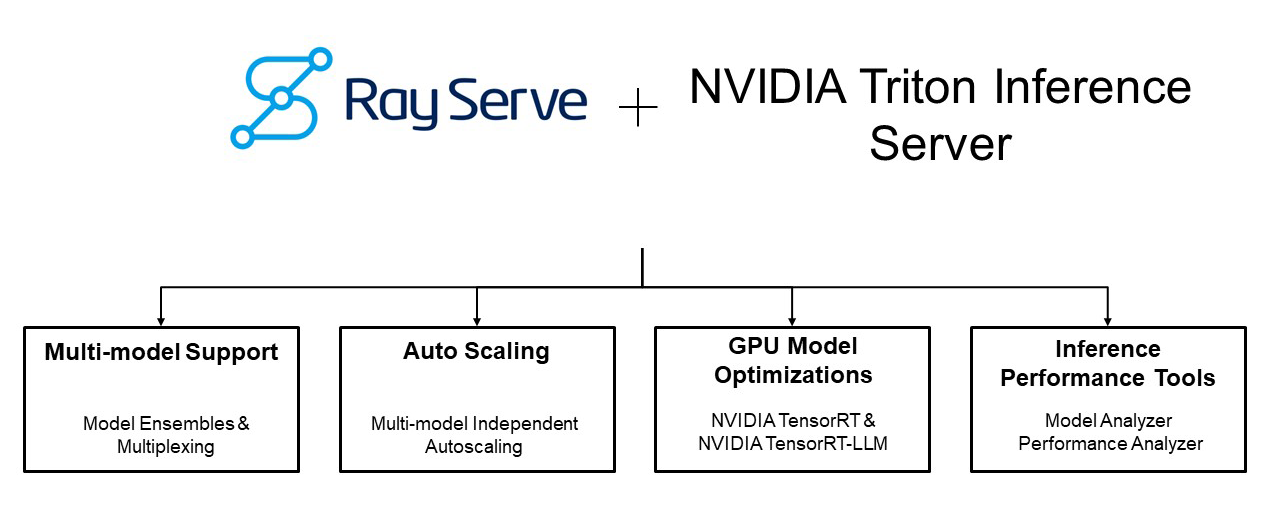
Low-latency Generative AI Model Serving with Ray, NVIDIA Triton ...
Taking AI Models to Production: Accelerated Inference with Triton ...