
Serving And Managing Ml Models With Mlflow And Nvidia Triton Inference

Serving and Managing ML models with Mlflow and Nvidia Triton Inference ...

Serving and Managing ML models with Mlflow and Nvidia Triton Inference ...

Serving and Managing ML models with Mlflow and Nvidia Triton Inference ...

Serving and Managing ML models with Mlflow and Nvidia Triton Inference ...

Optimizing and Serving Models with NVIDIA TensorRT and NVIDIA Triton ...
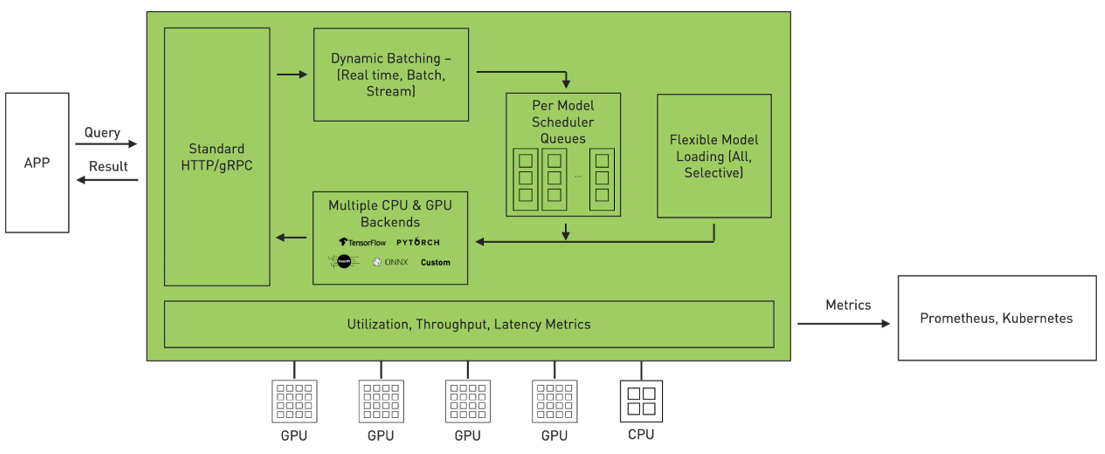
Simplifying and Scaling Inference Serving with NVIDIA Triton 2.3 ...

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Optimizing and Serving Models with NVIDIA TensorRT and NVIDIA Triton ...
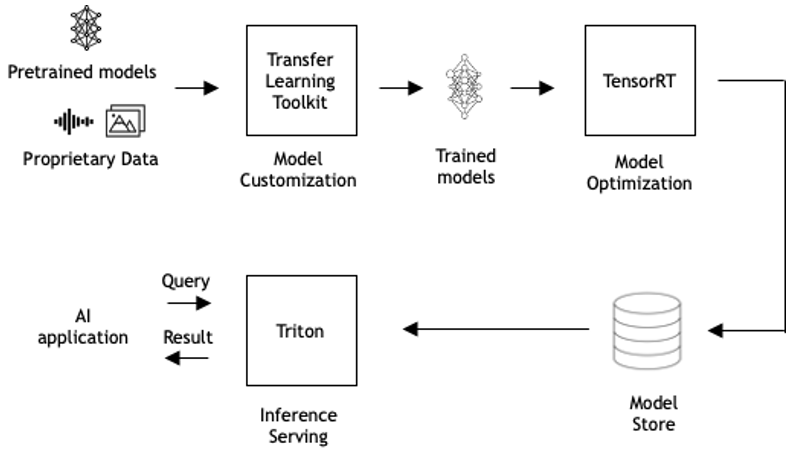
Simplifying and Scaling Inference Serving with NVIDIA Triton 2.3 ...
Advertisement Space (300x250)

Optimizing and Serving Models with NVIDIA TensorRT and NVIDIA Triton ...
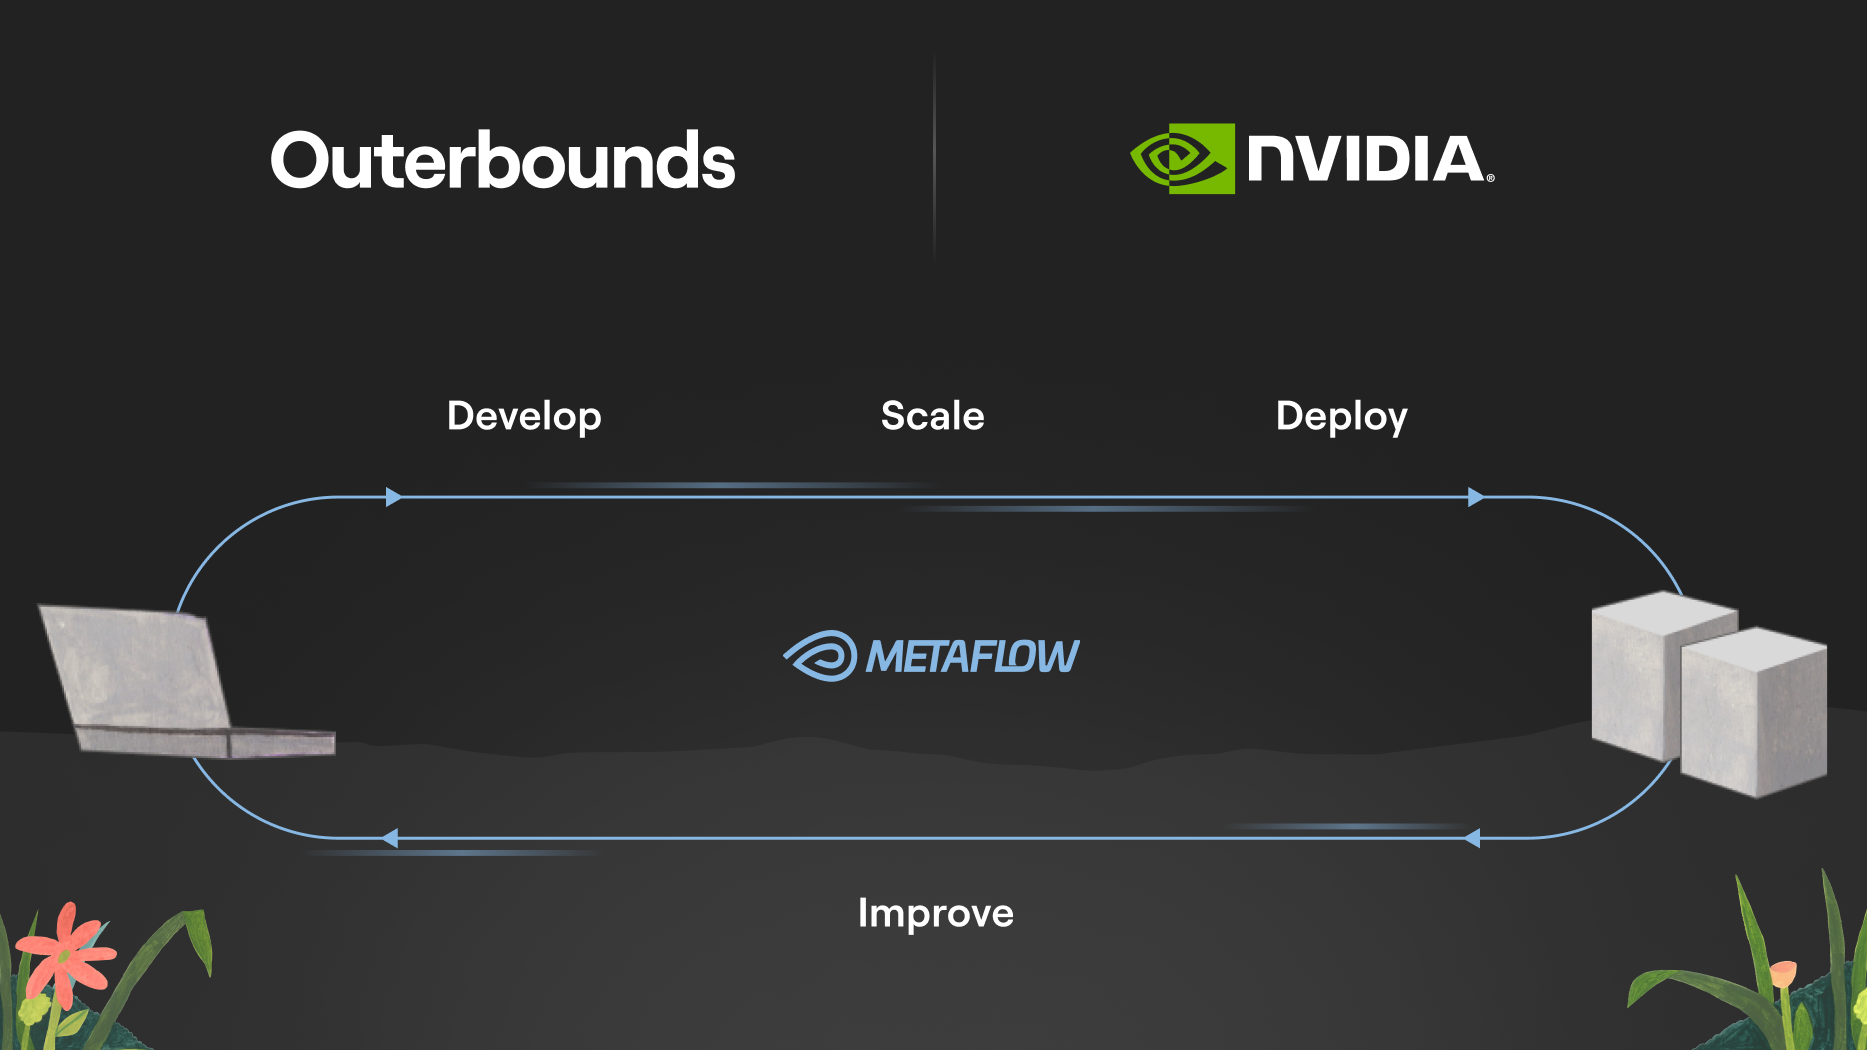
Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Develop ML and AI with Metaflow and Deploy with NVIDIA Triton Inference ...

Serving TensorRT Models with NVIDIA Triton Inference Server | by Tan ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
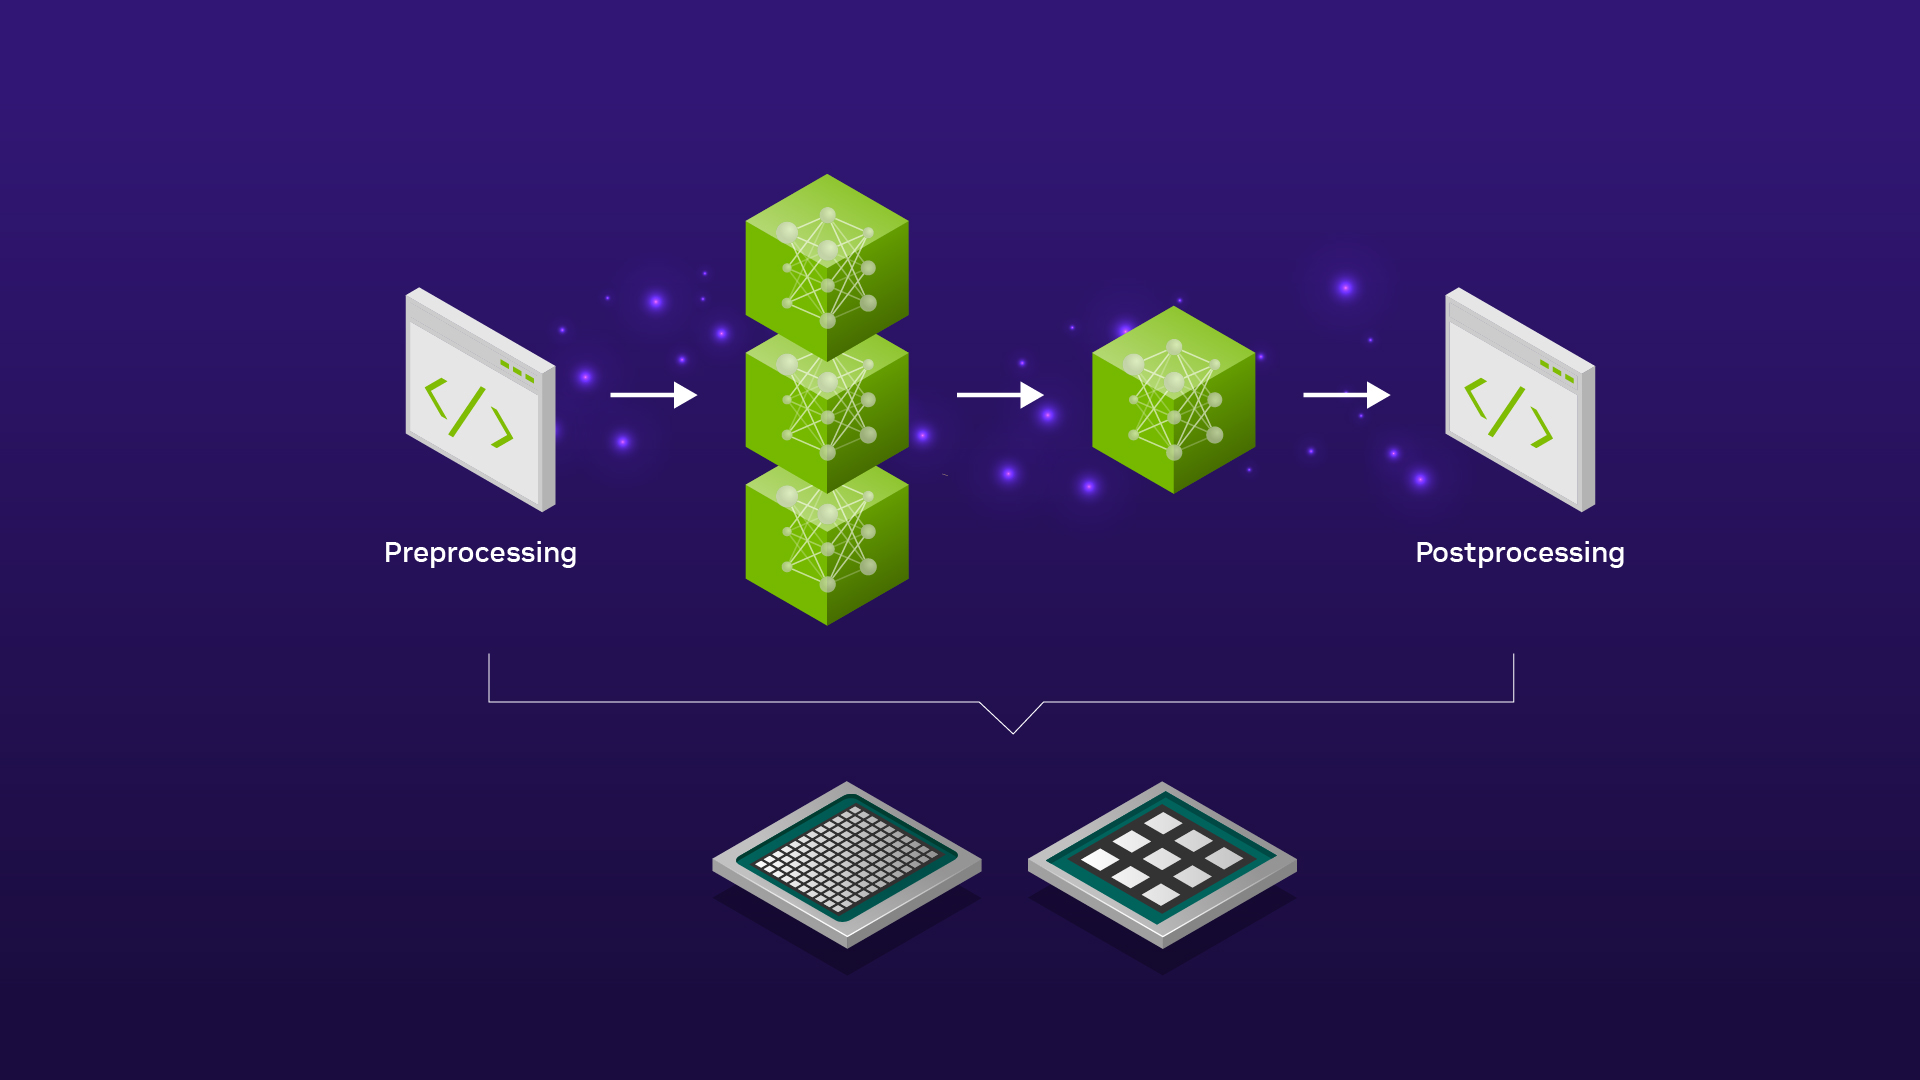
Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Serving Models with NVIDIA Triton Inference Server

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Advertisement Space (336x280)
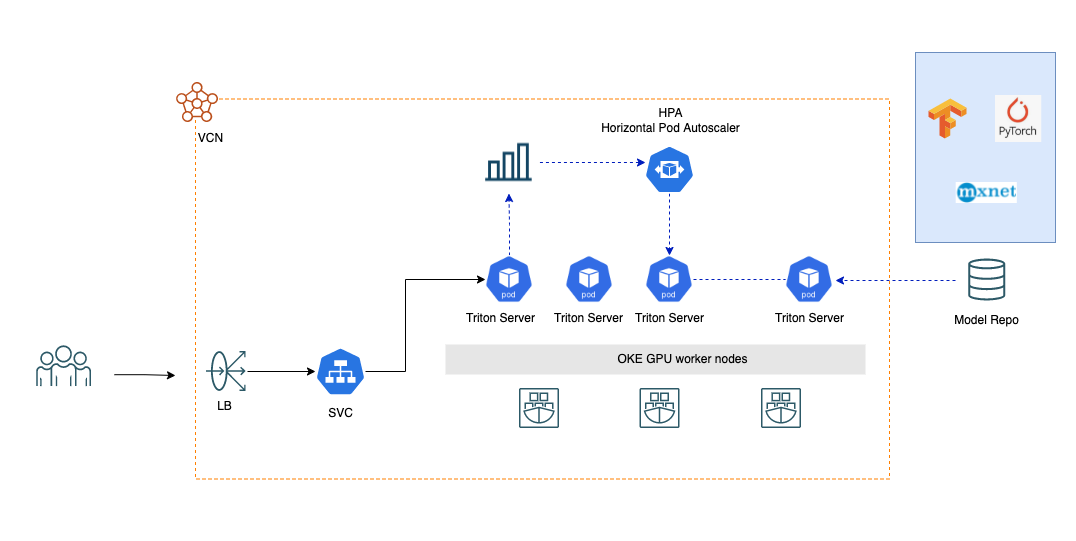
Serve ML models at scale with NVIDIA Triton Inference Server on OKE ...

Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...
Deploying ML Models with NVIDIA Triton Inference Server | Rosepetal AI Blog

Training & Serving ML Models on GPU with NVIDIA Triton - FuseML ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Training & Serving ML Models on GPU with NVIDIA Triton - FuseML ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
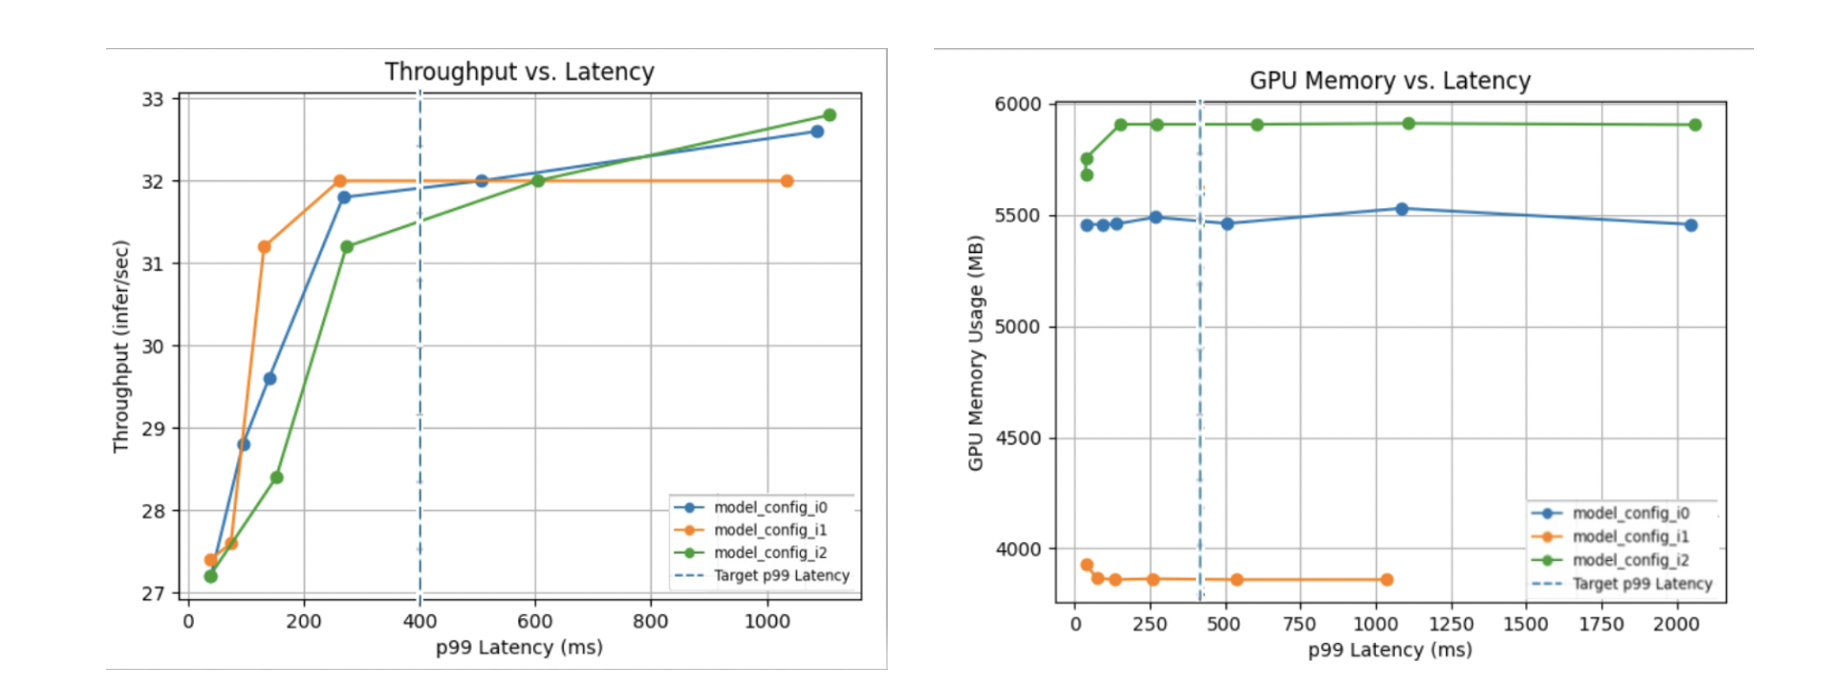
Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
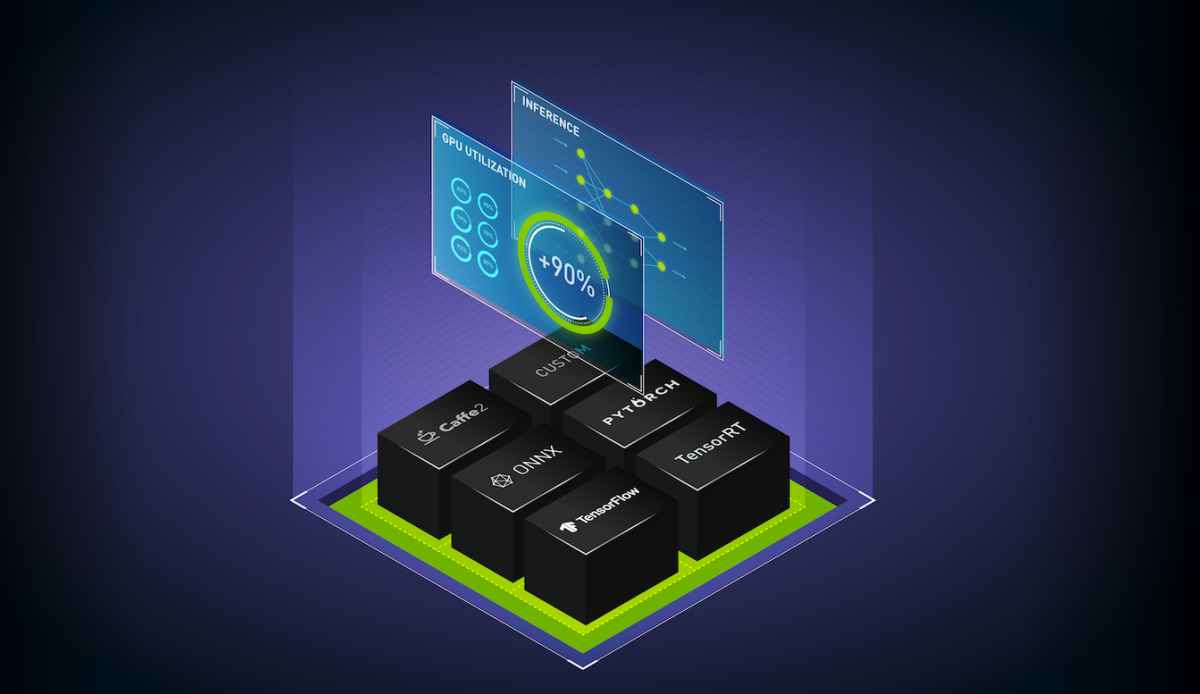
Deploying AI Deep Learning Models with NVIDIA Triton Inference Server ...
Advertisement Space (336x280)
Inference of Large Language Models with NVIDIA Triton Inference Server ...

Optimizing Real-Time ML Inference with Nvidia Triton Inference Server ...

DataHour: Optimizing Real-Time ML Inference with Nvidia Triton ...
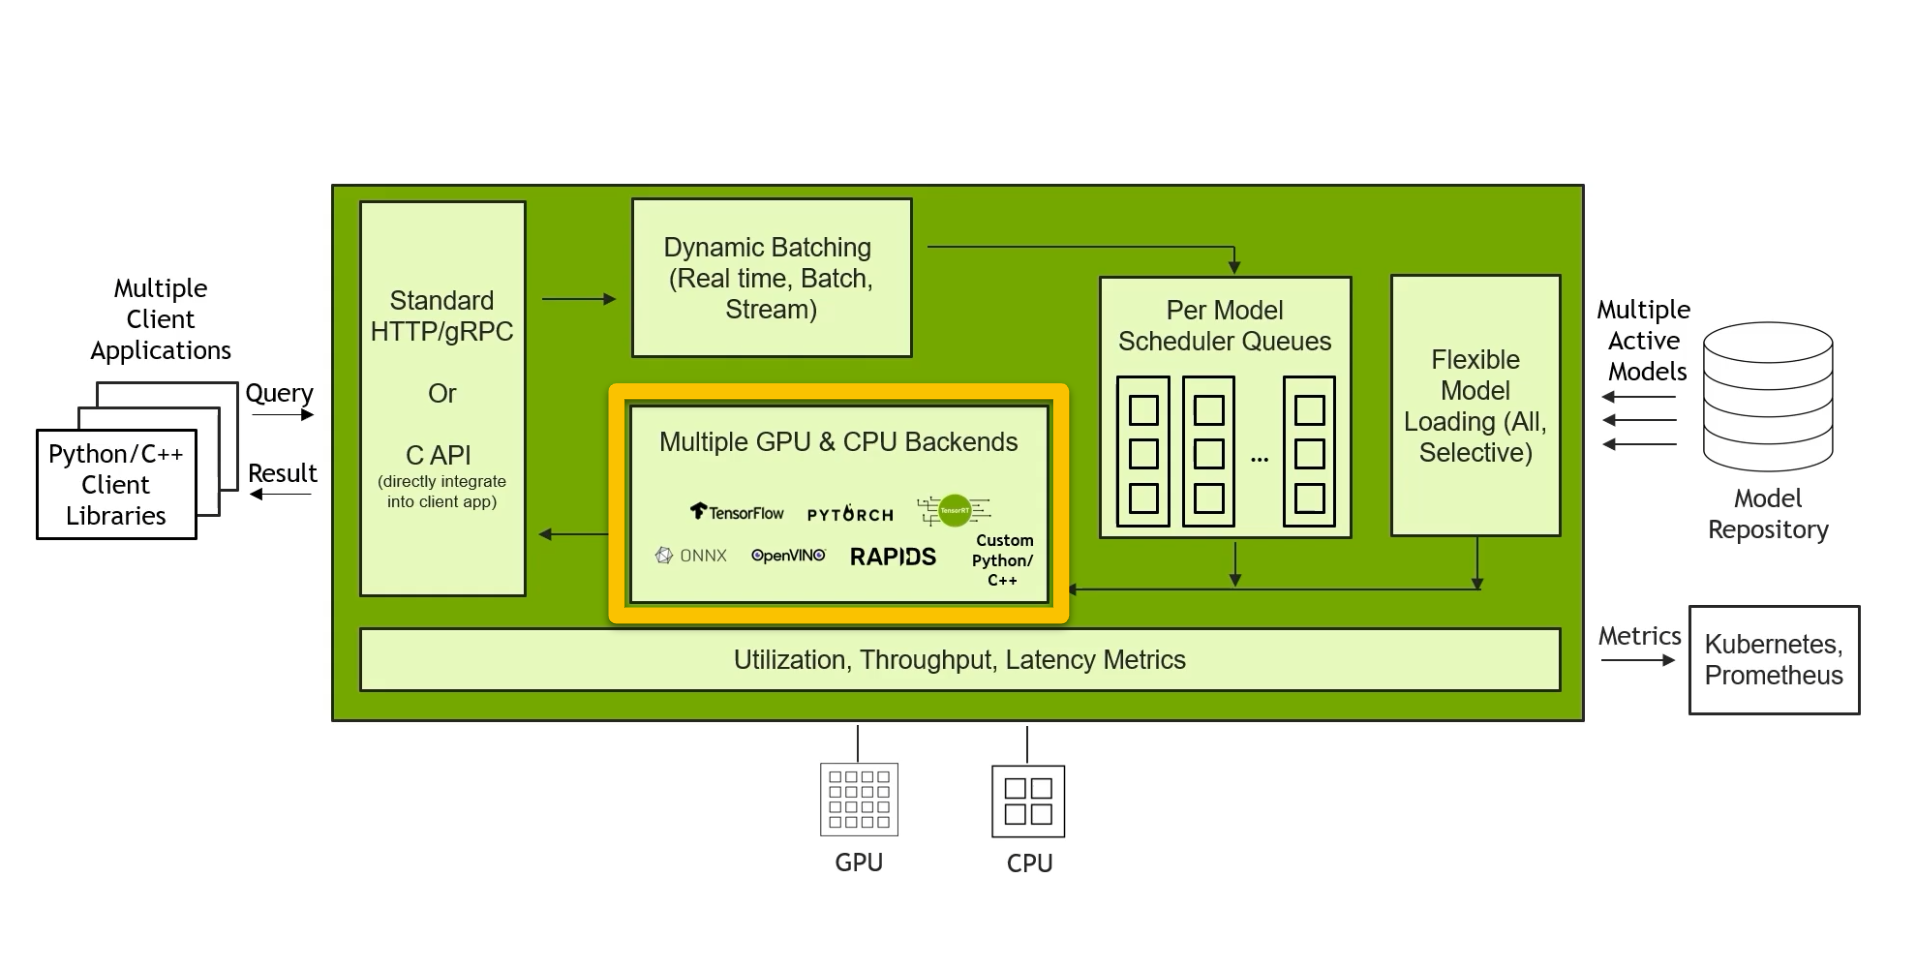
Accelerating Inference for Deep Learning Models — NVIDIA Triton ...

Accelerated Inference for Large Transformer Models Using NVIDIA Triton ...

Accelerating Inference for Deep Learning Models — NVIDIA Triton ...