
Distributed Inference With Vllm Red Hat Developer
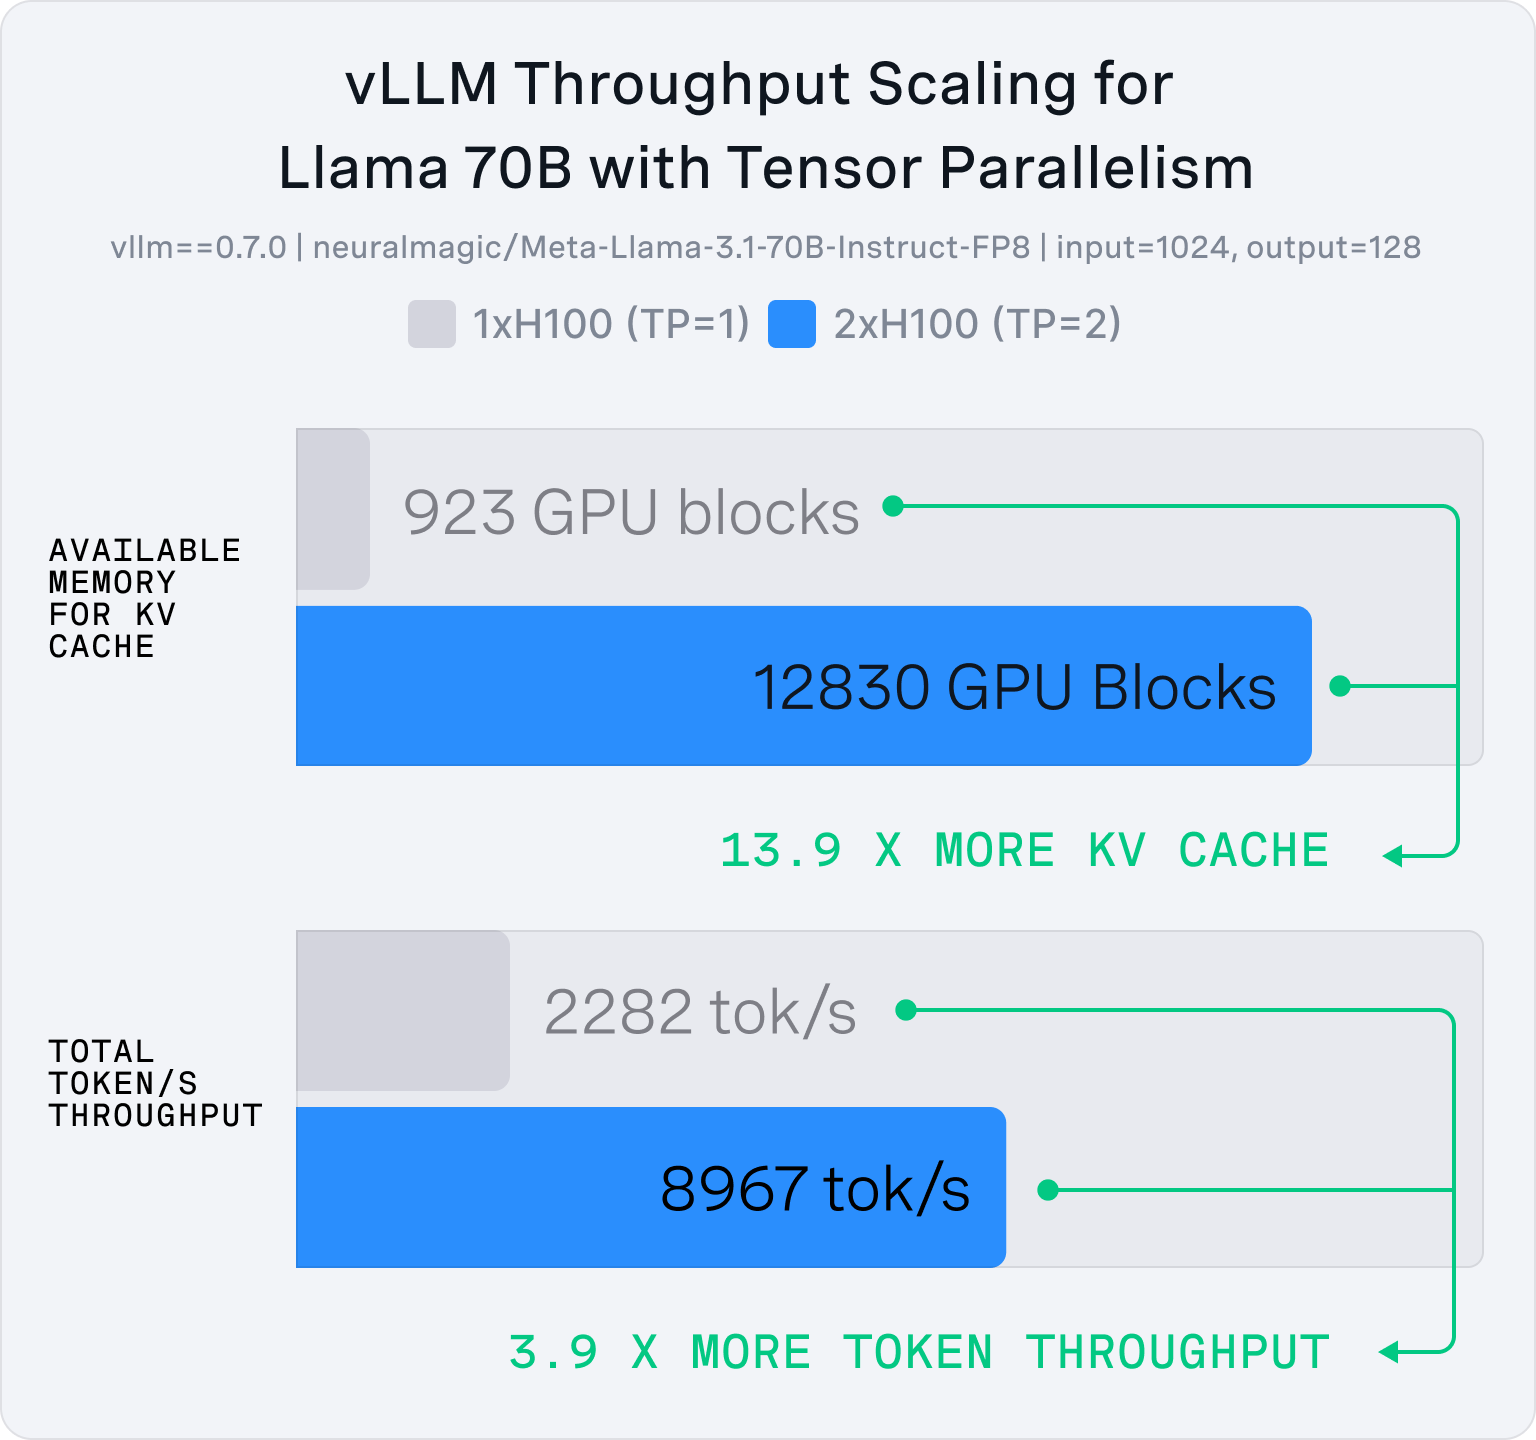
Distributed inference with vLLM | Red Hat Developer

Distributed inference with vLLM | Red Hat Developer
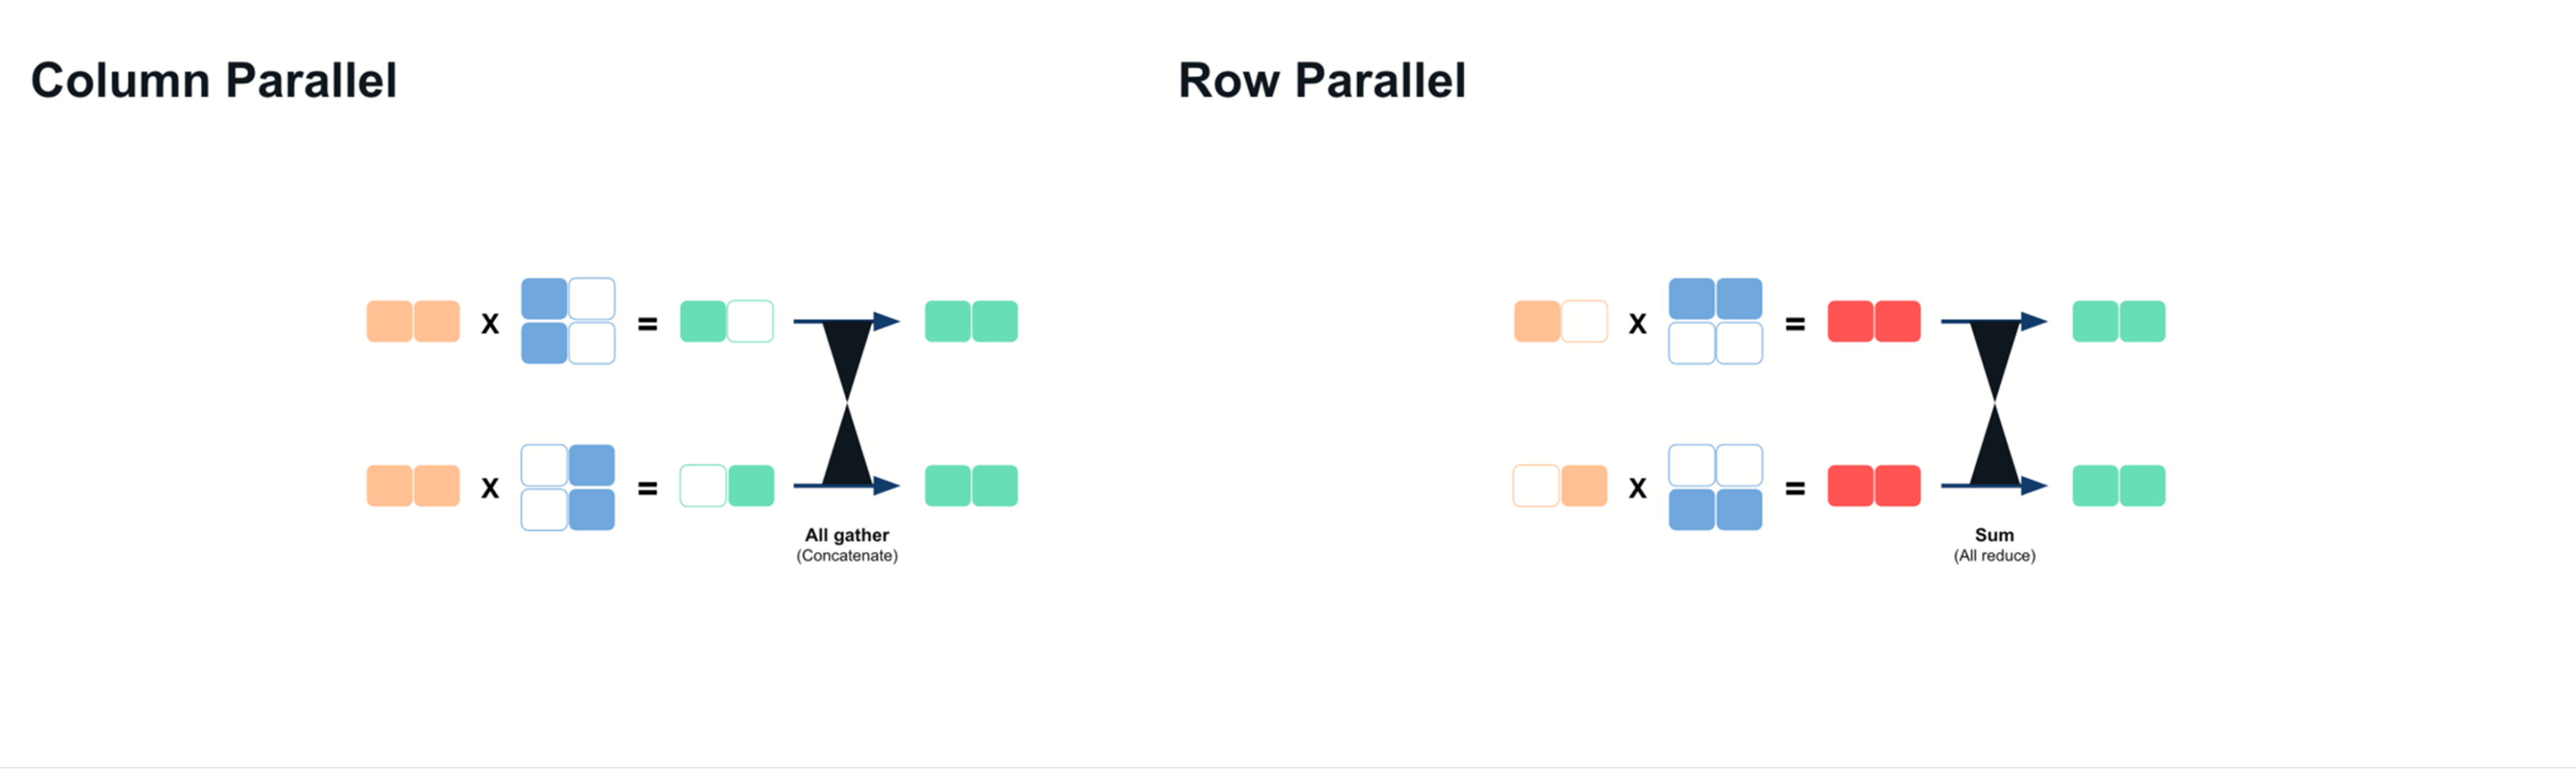
Distributed inference with vLLM | Red Hat Developer

Distributed inference with vLLM | Red Hat Developer
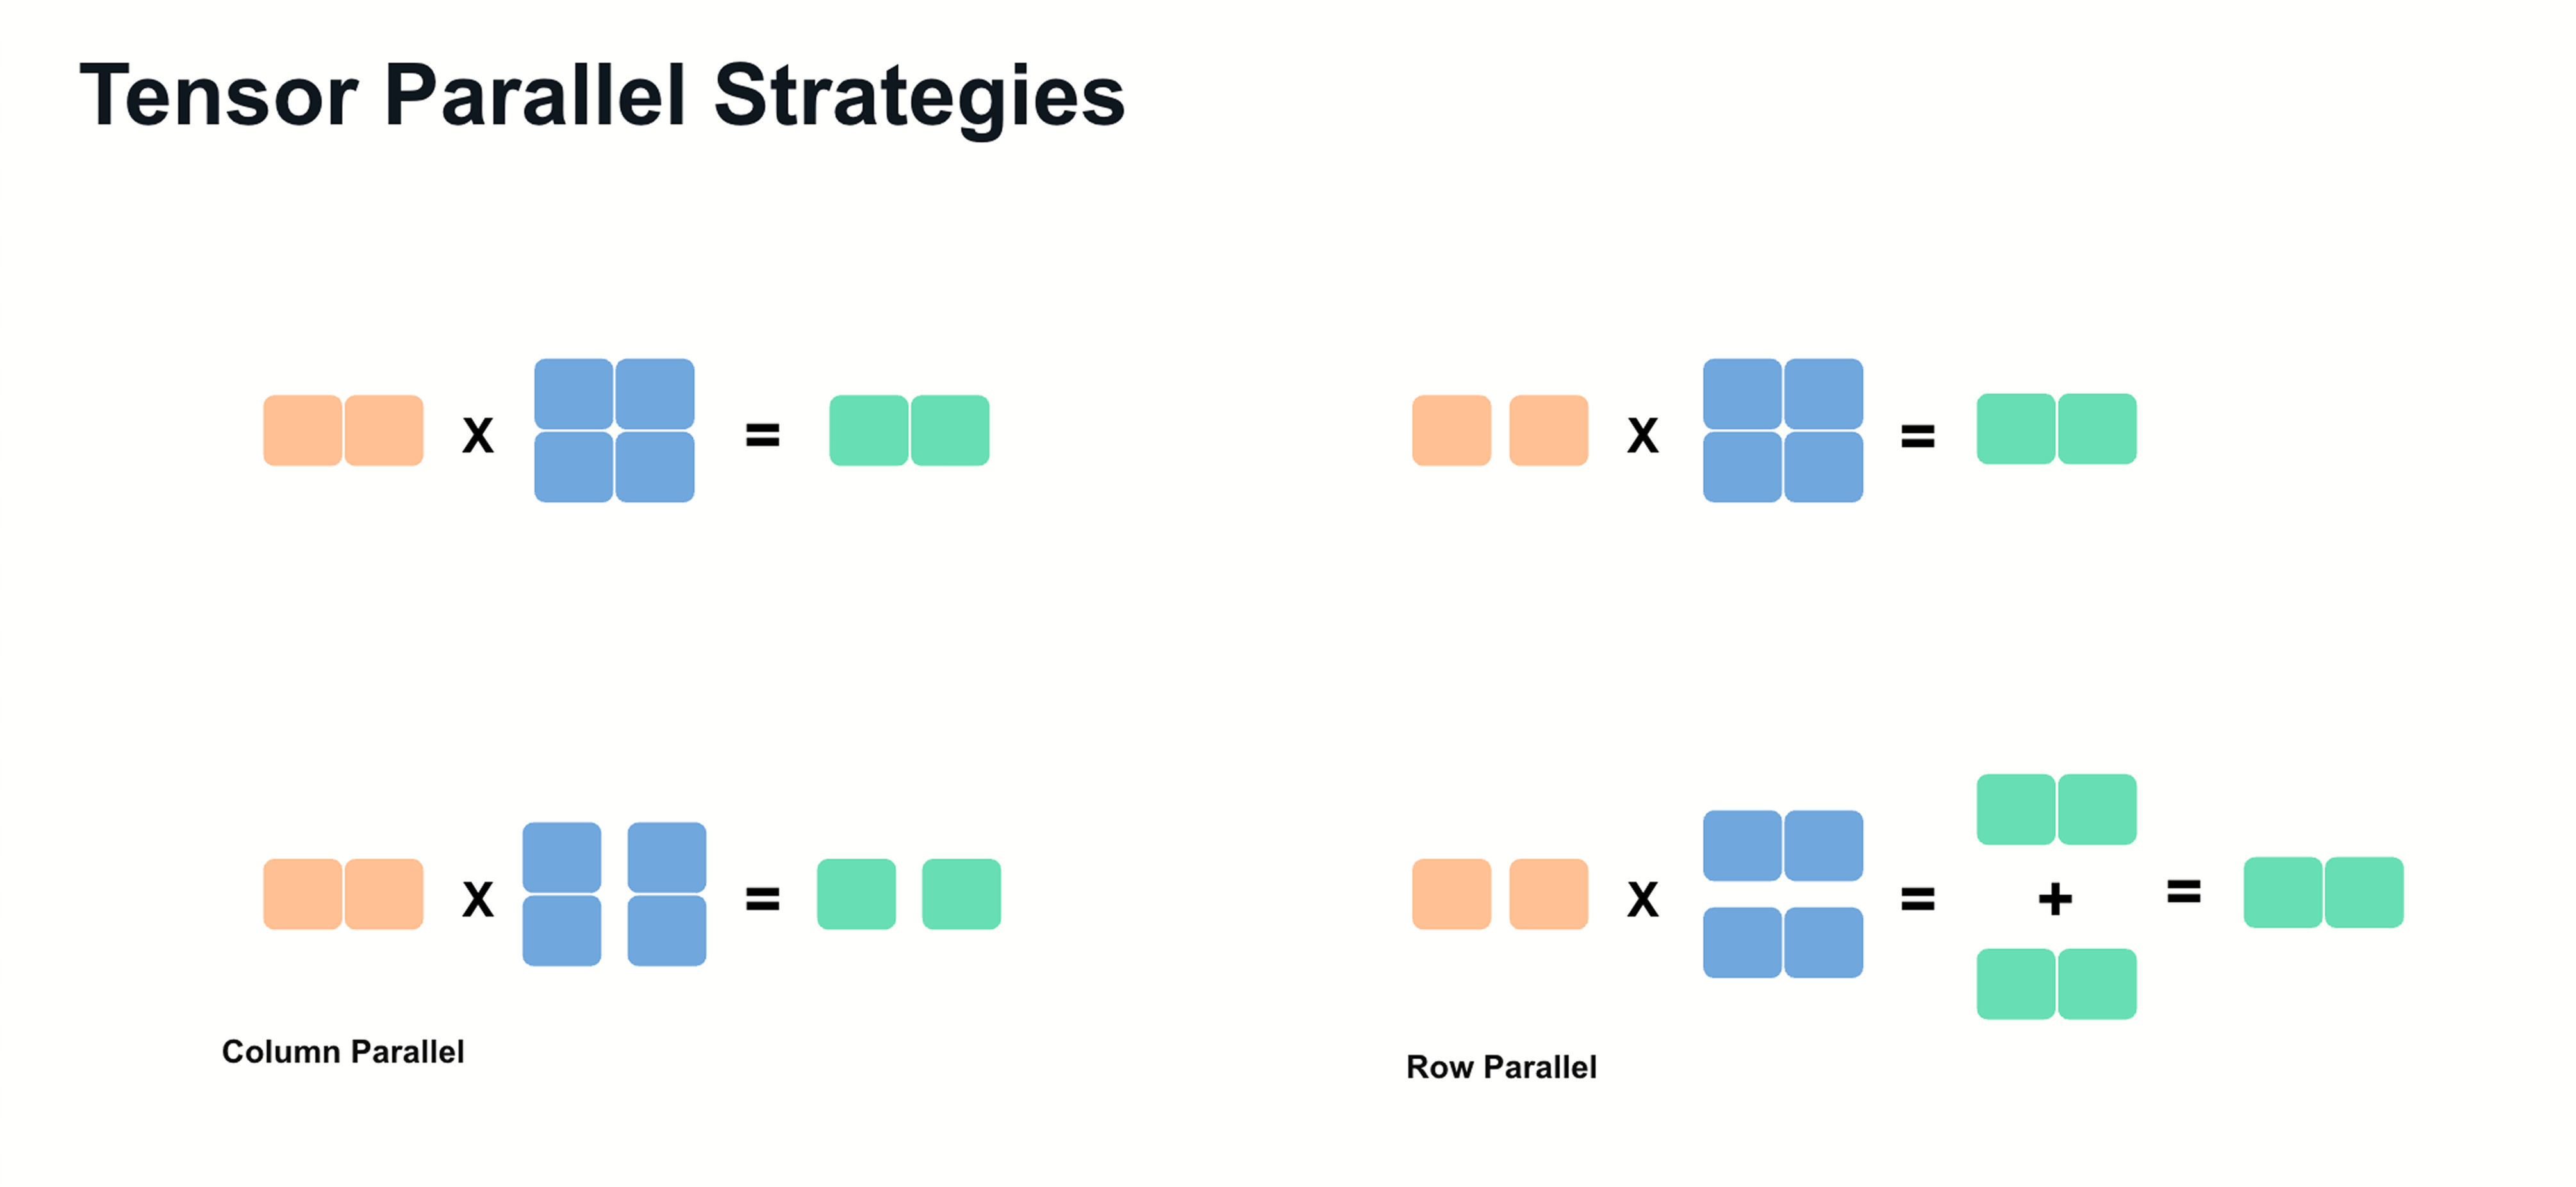
Distributed inference with vLLM | Red Hat Developer
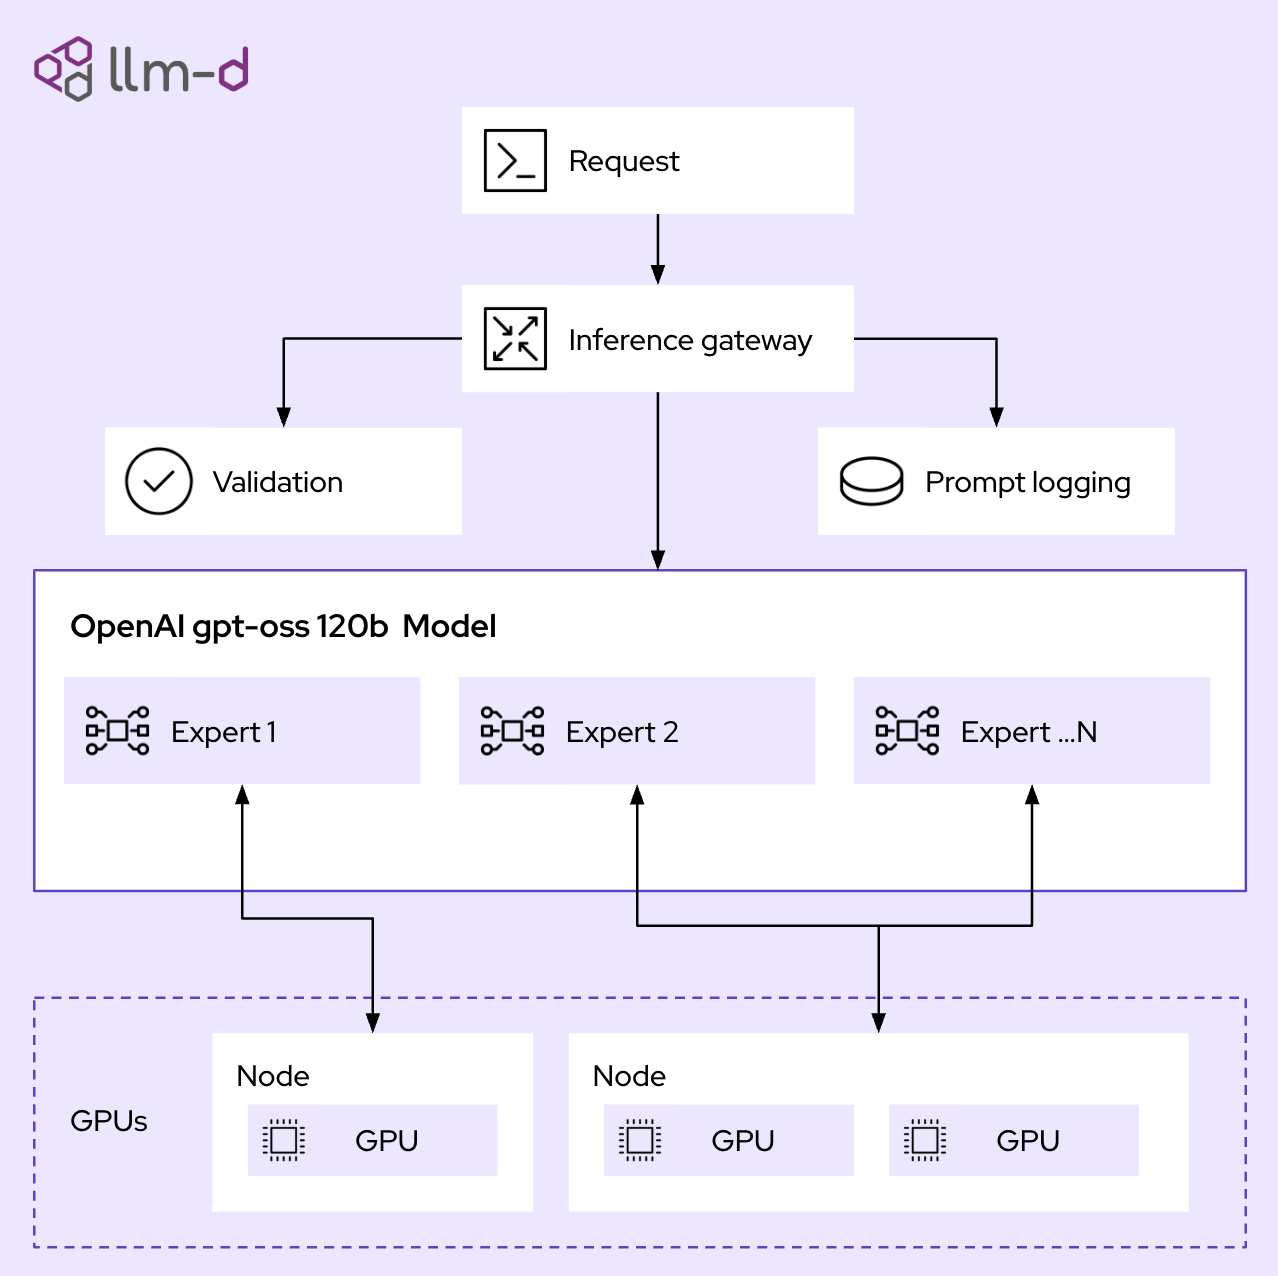
Introduction to distributed inference with llm-d | Red Hat Developer
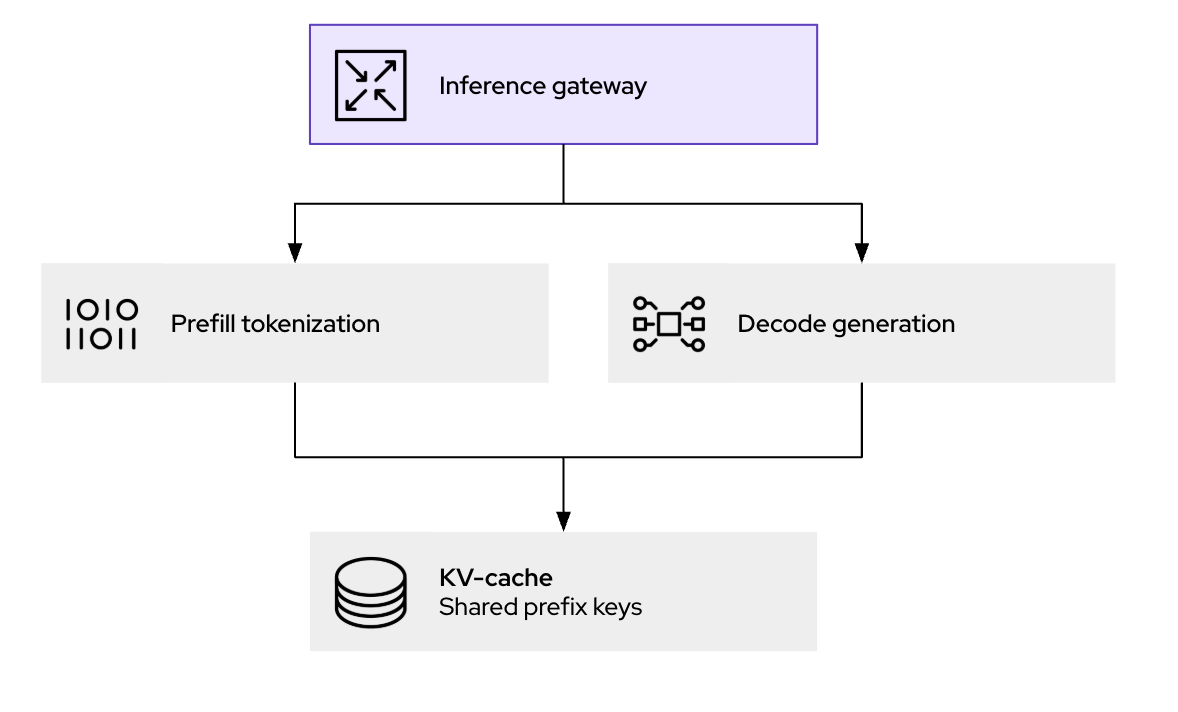
Introduction to distributed inference with llm-d | Red Hat Developer
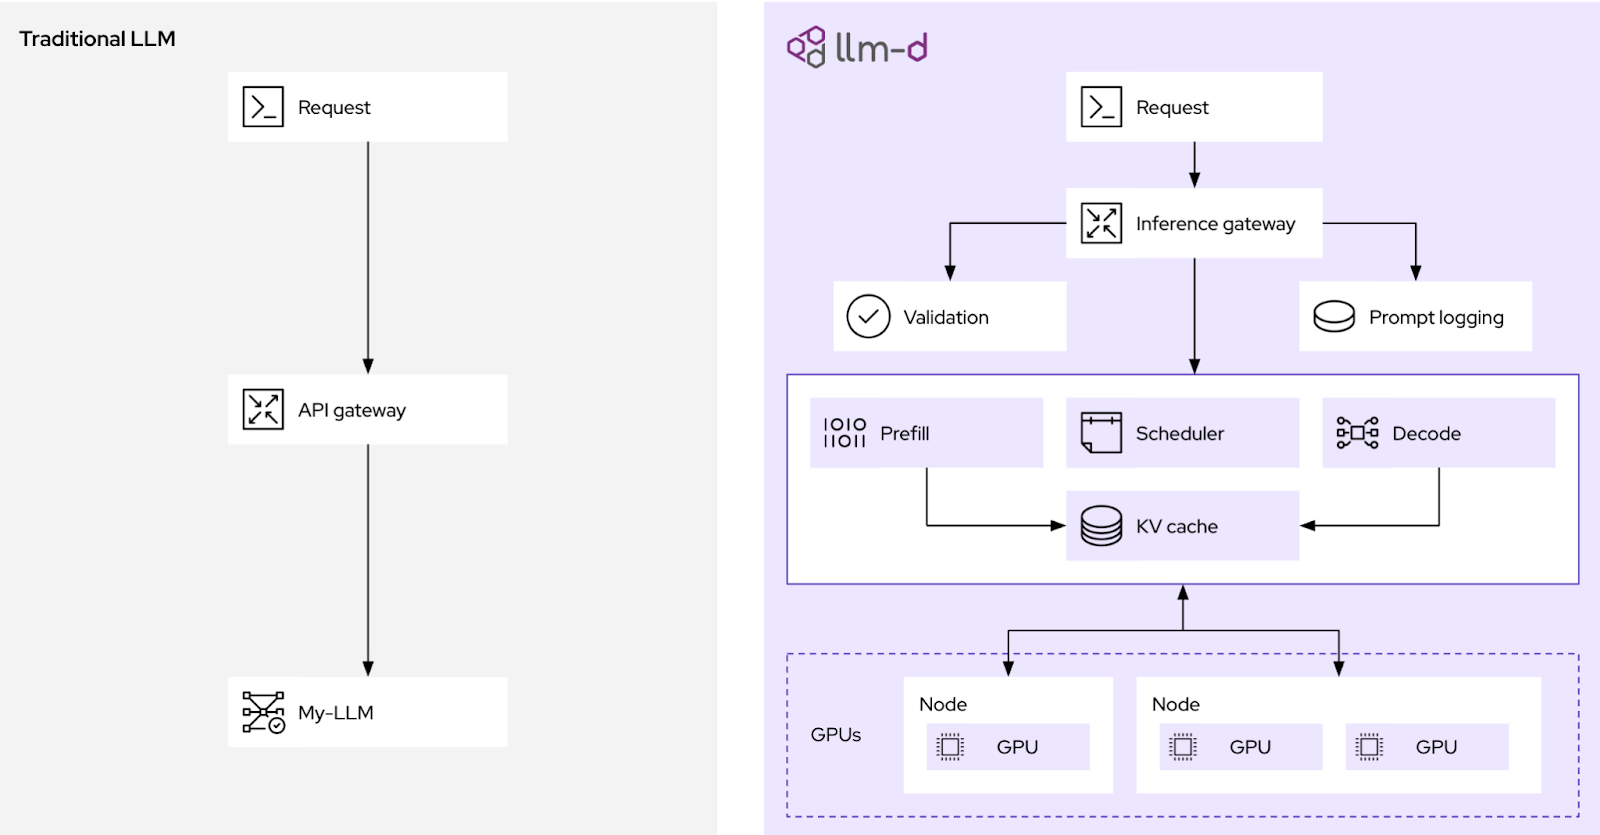
Introduction to distributed inference with llm-d | Red Hat Developer
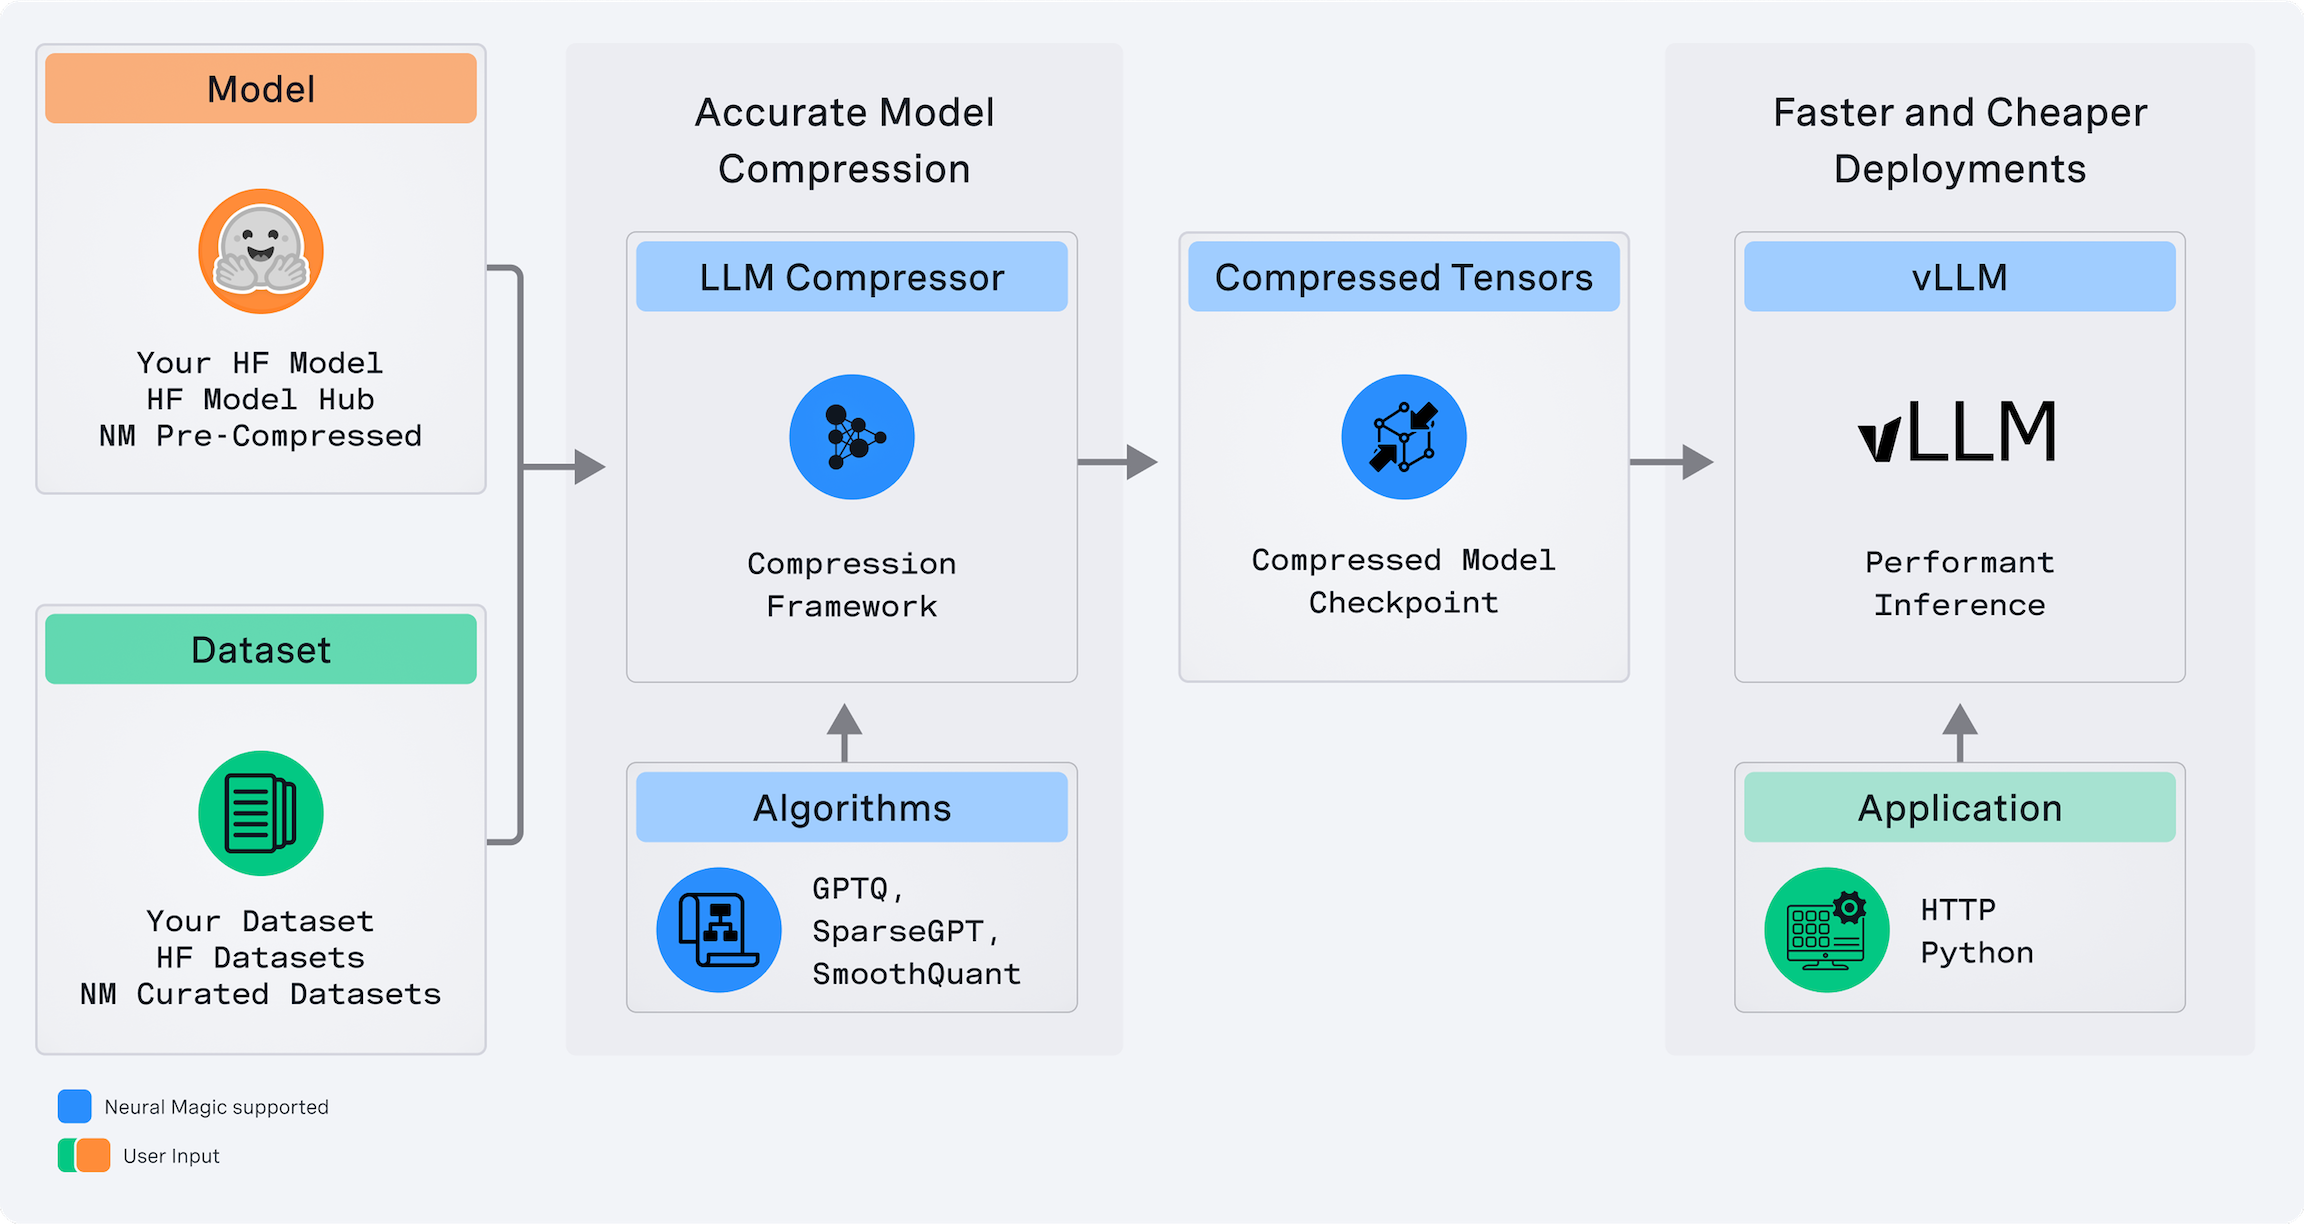
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
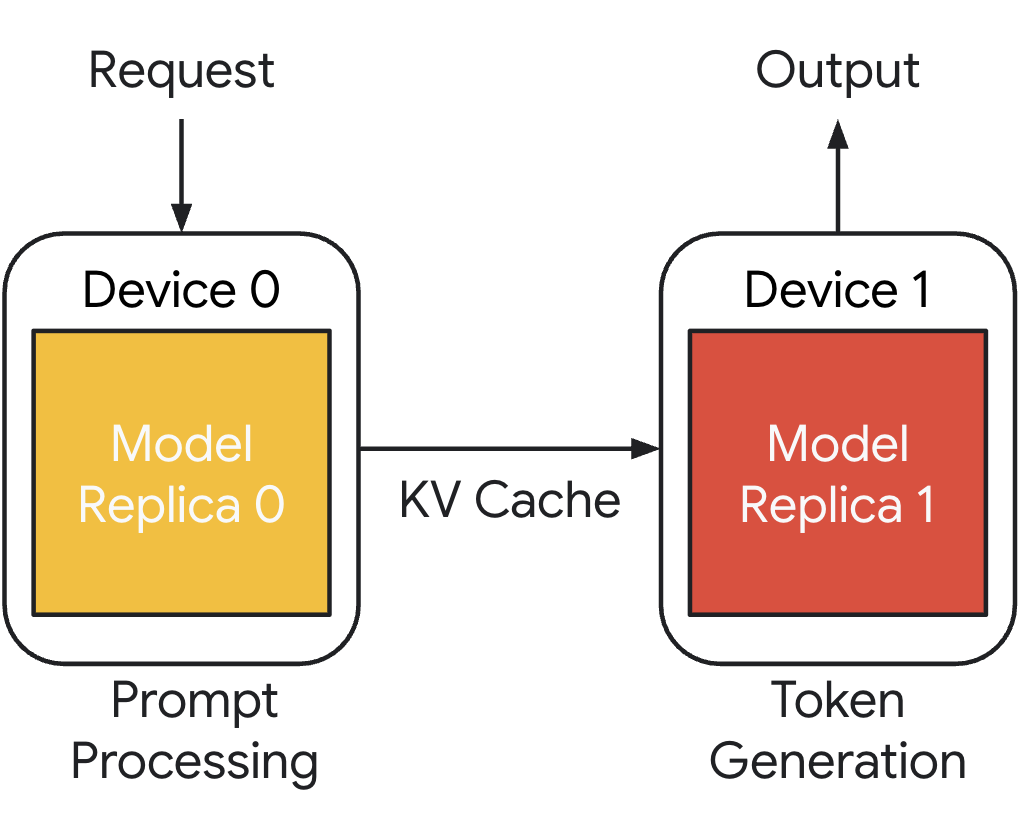
Introduction to distributed inference with llm-d | Red Hat Developer
Advertisement Space (300x250)

Introduction to distributed inference with llm-d | Red Hat Developer

Faster inference with vLLM & speculative decoding | Red Hat Developer
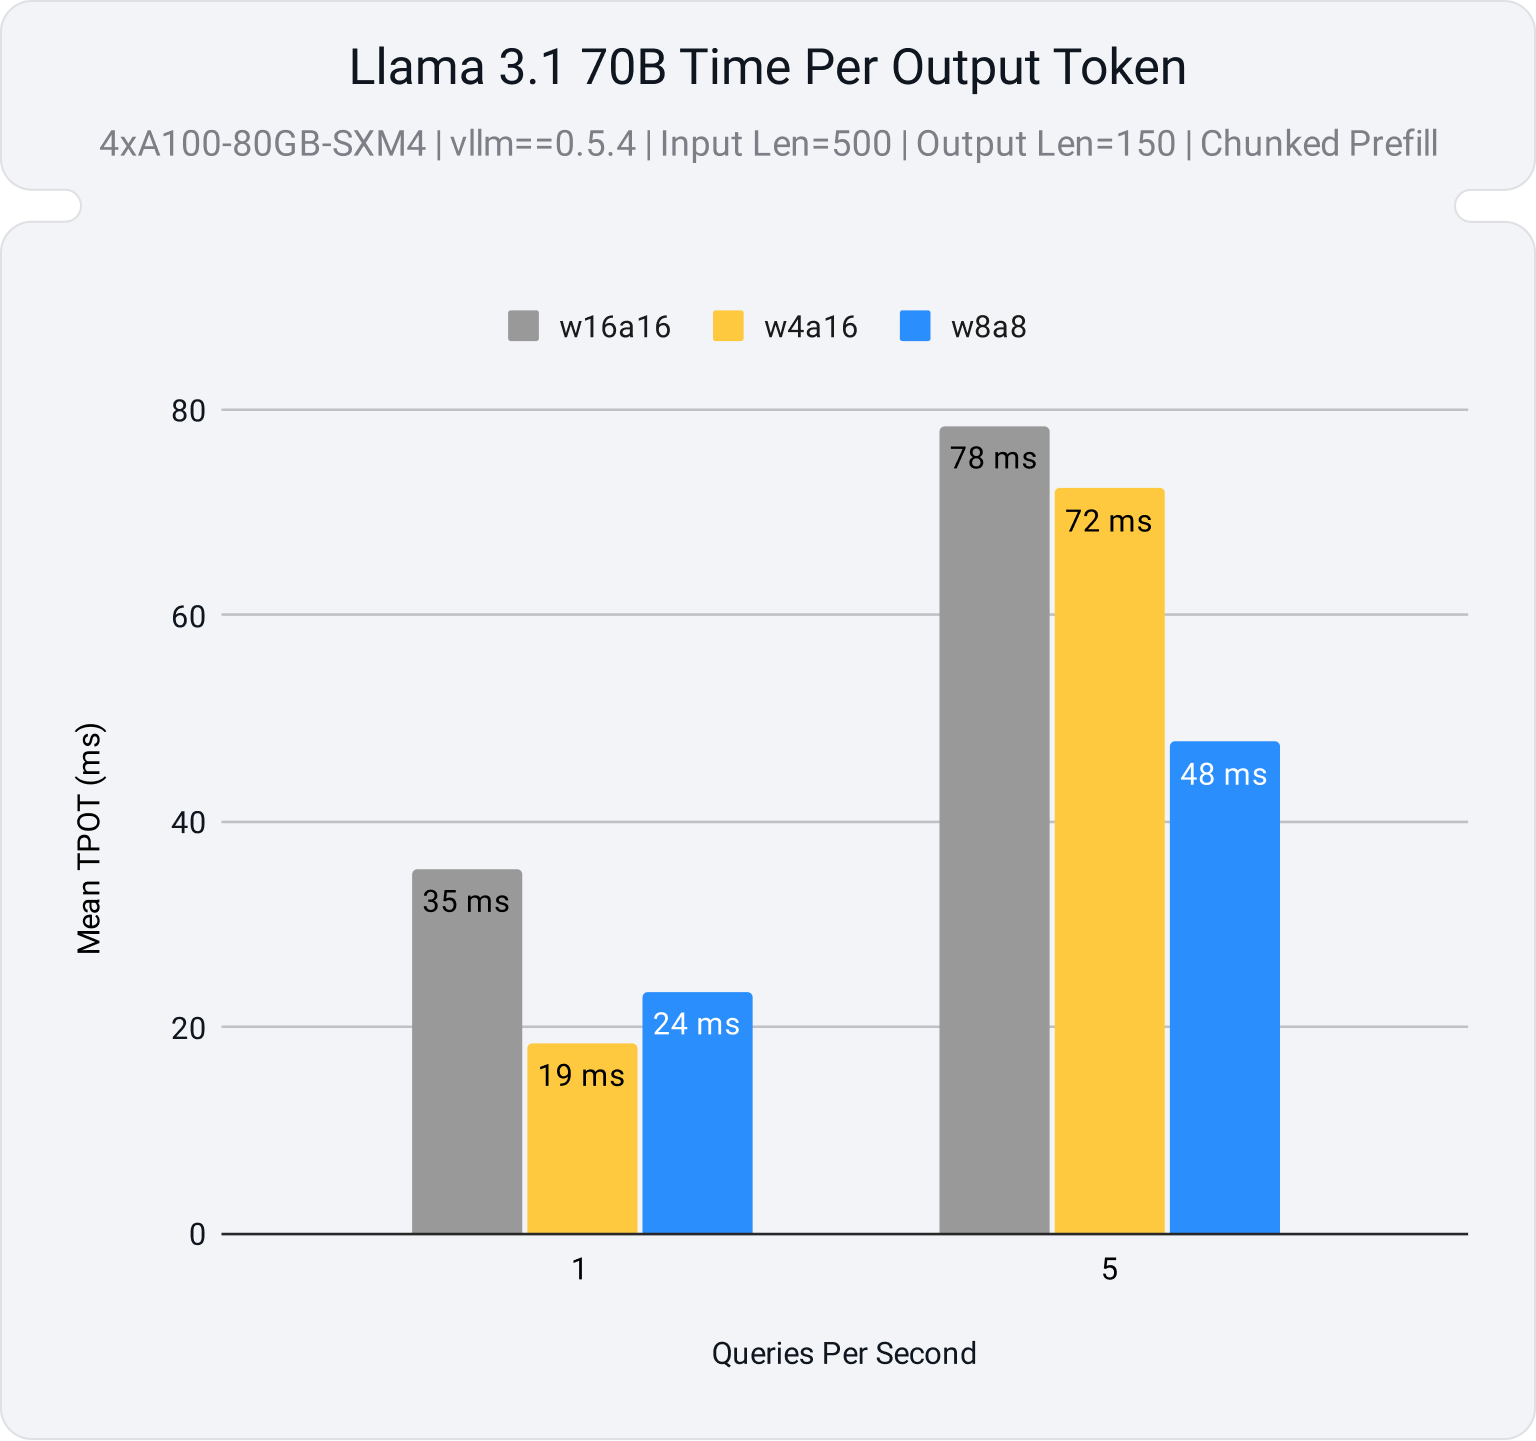
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

Red Hat AI tops MLPerf Inference v6.0 with vLLM on Qwen3-VL, Whisper ...
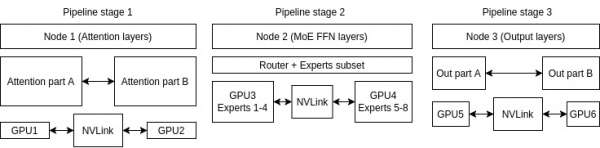
Why vLLM is the best choice for AI inference today | Red Hat Developer
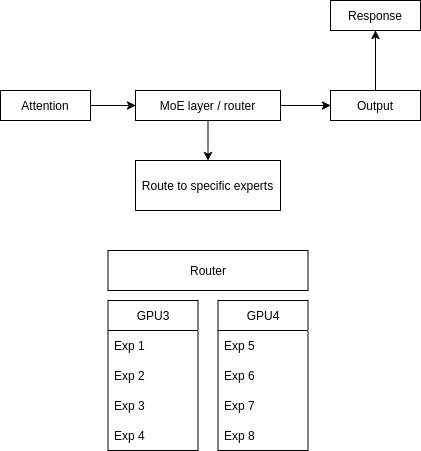
Why vLLM is the best choice for AI inference today | Red Hat Developer
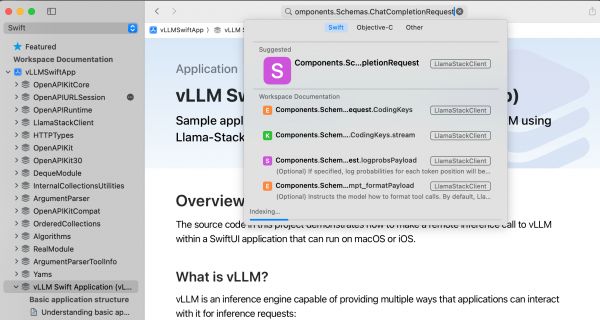
Integrate vLLM inference on macOS/iOS with Llama Stack APIs | Red Hat ...
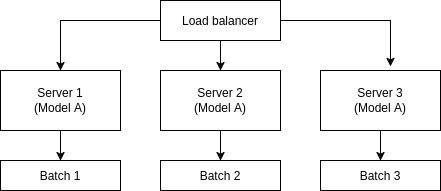
Why vLLM is the best choice for AI inference today | Red Hat Developer
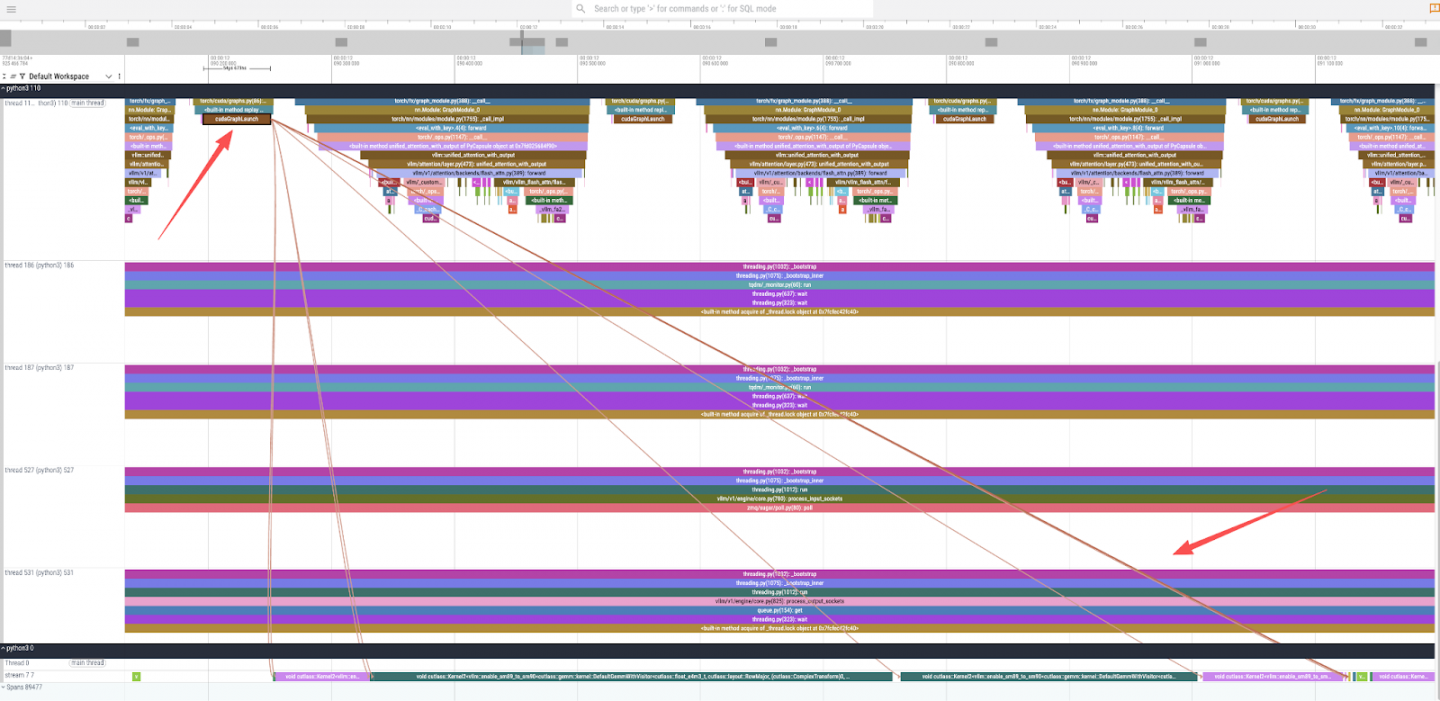
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
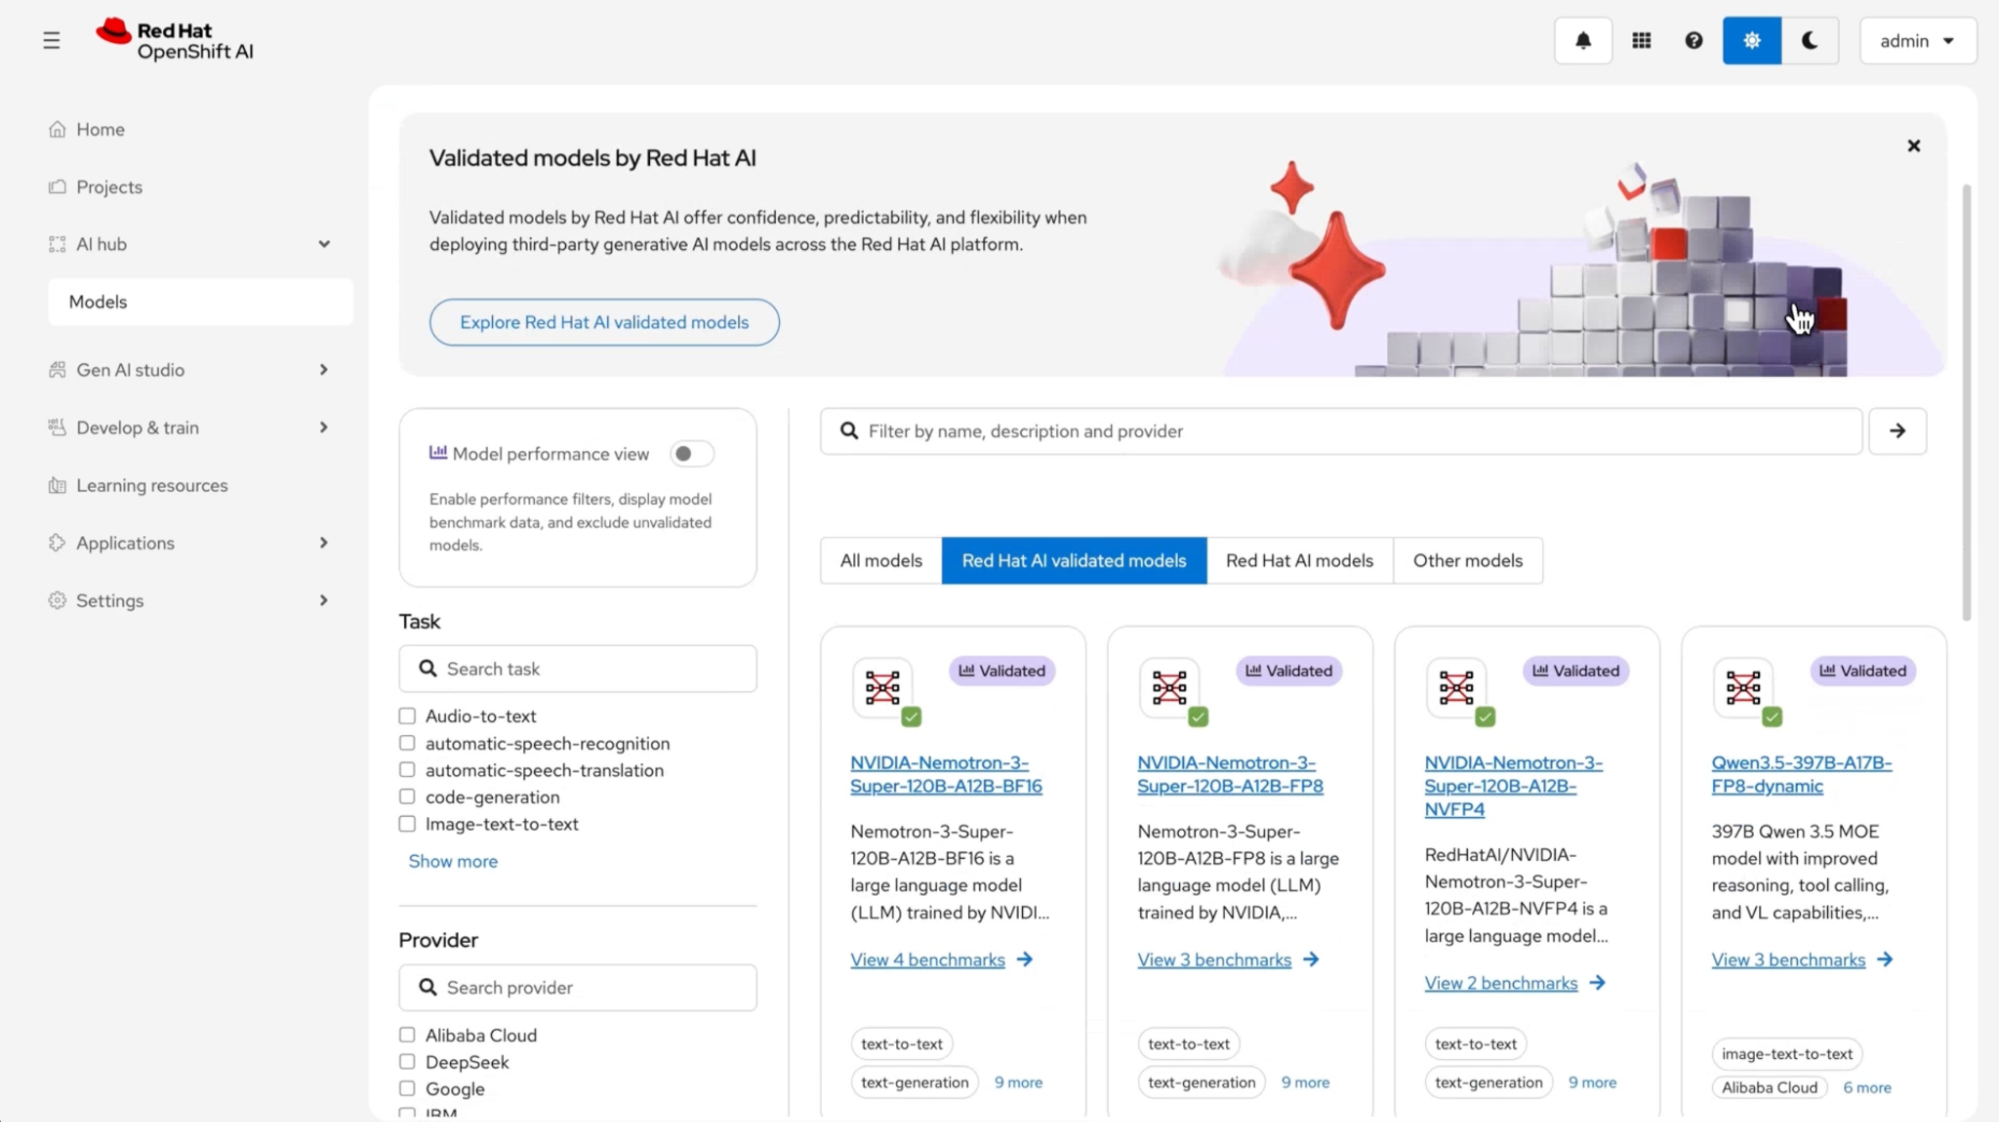
Run Claude Code locally with vLLM and OpenShift AI | Red Hat Developer
Advertisement Space (336x280)
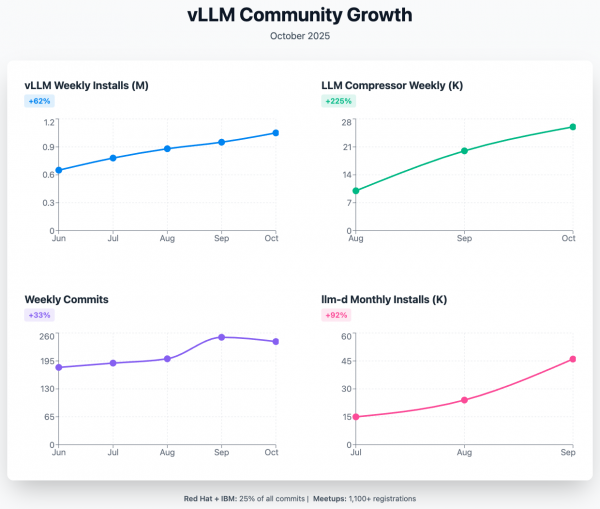
Why vLLM is the best choice for AI inference today | Red Hat Developer
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
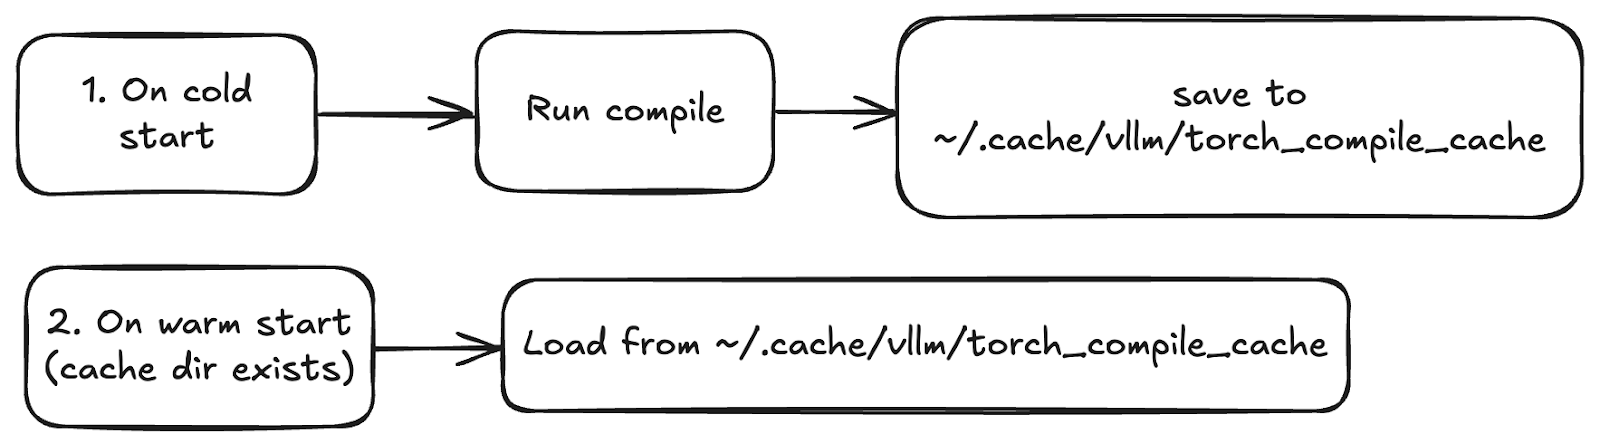
vLLM with torch.compile: Efficient LLM inference on PyTorch | Red Hat ...
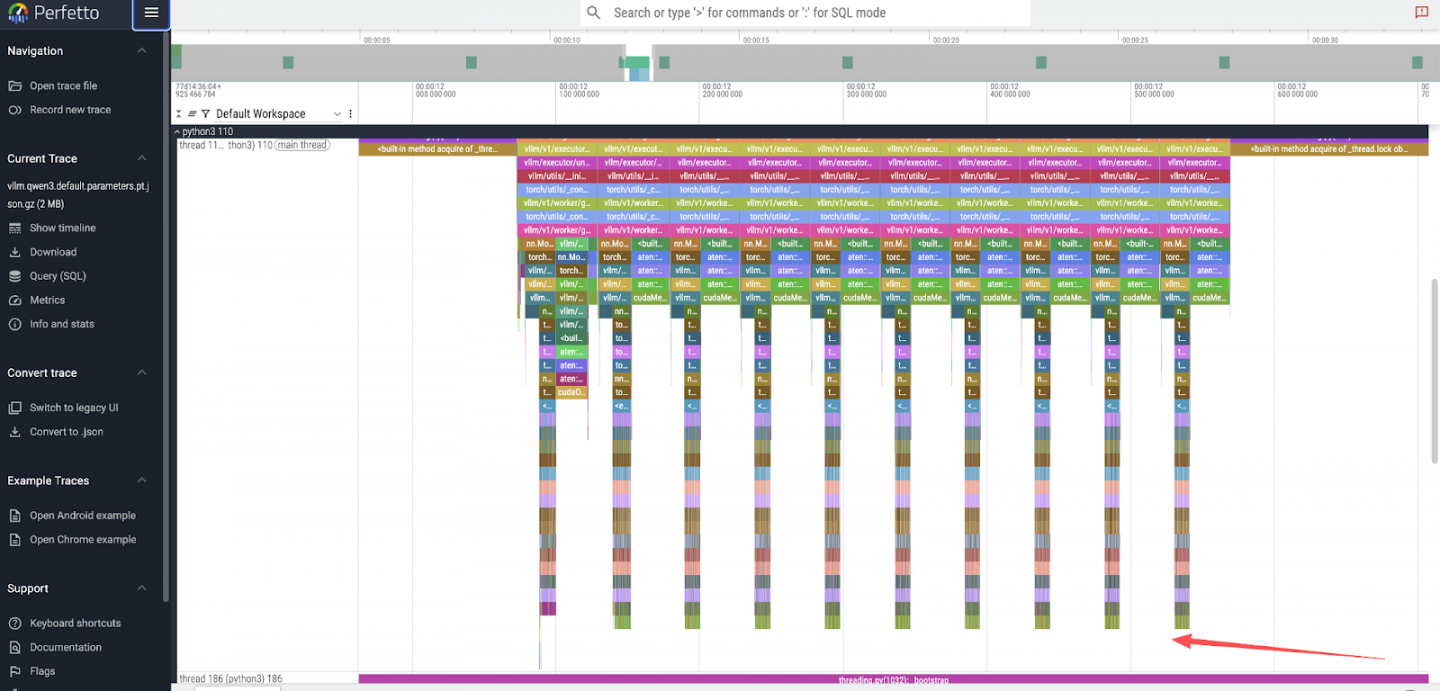
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
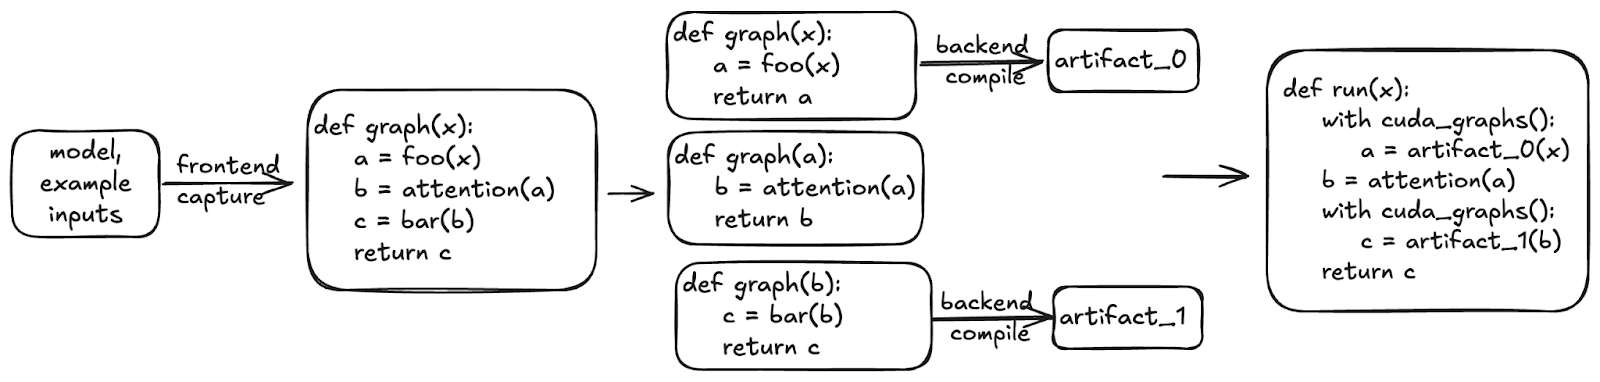
vLLM with torch.compile: Efficient LLM inference on PyTorch | Red Hat ...
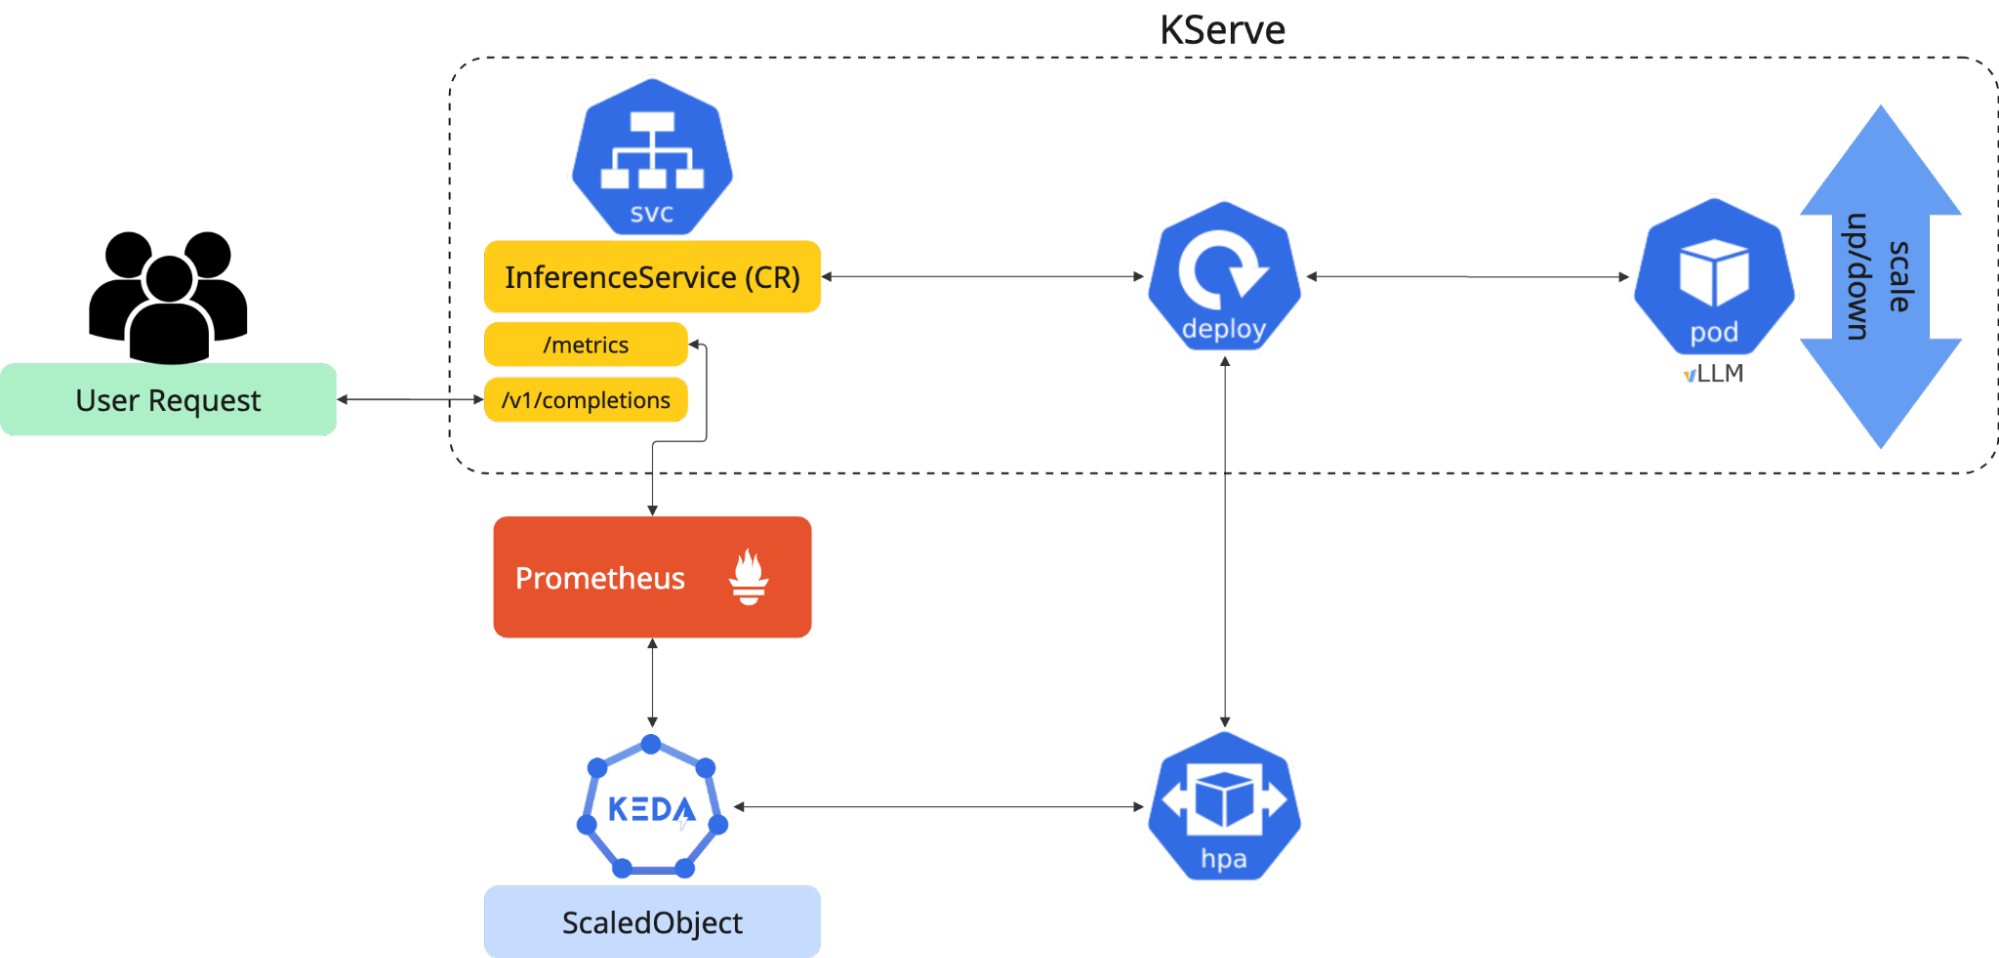
How to set up KServe autoscaling for vLLM with KEDA | Red Hat Developer
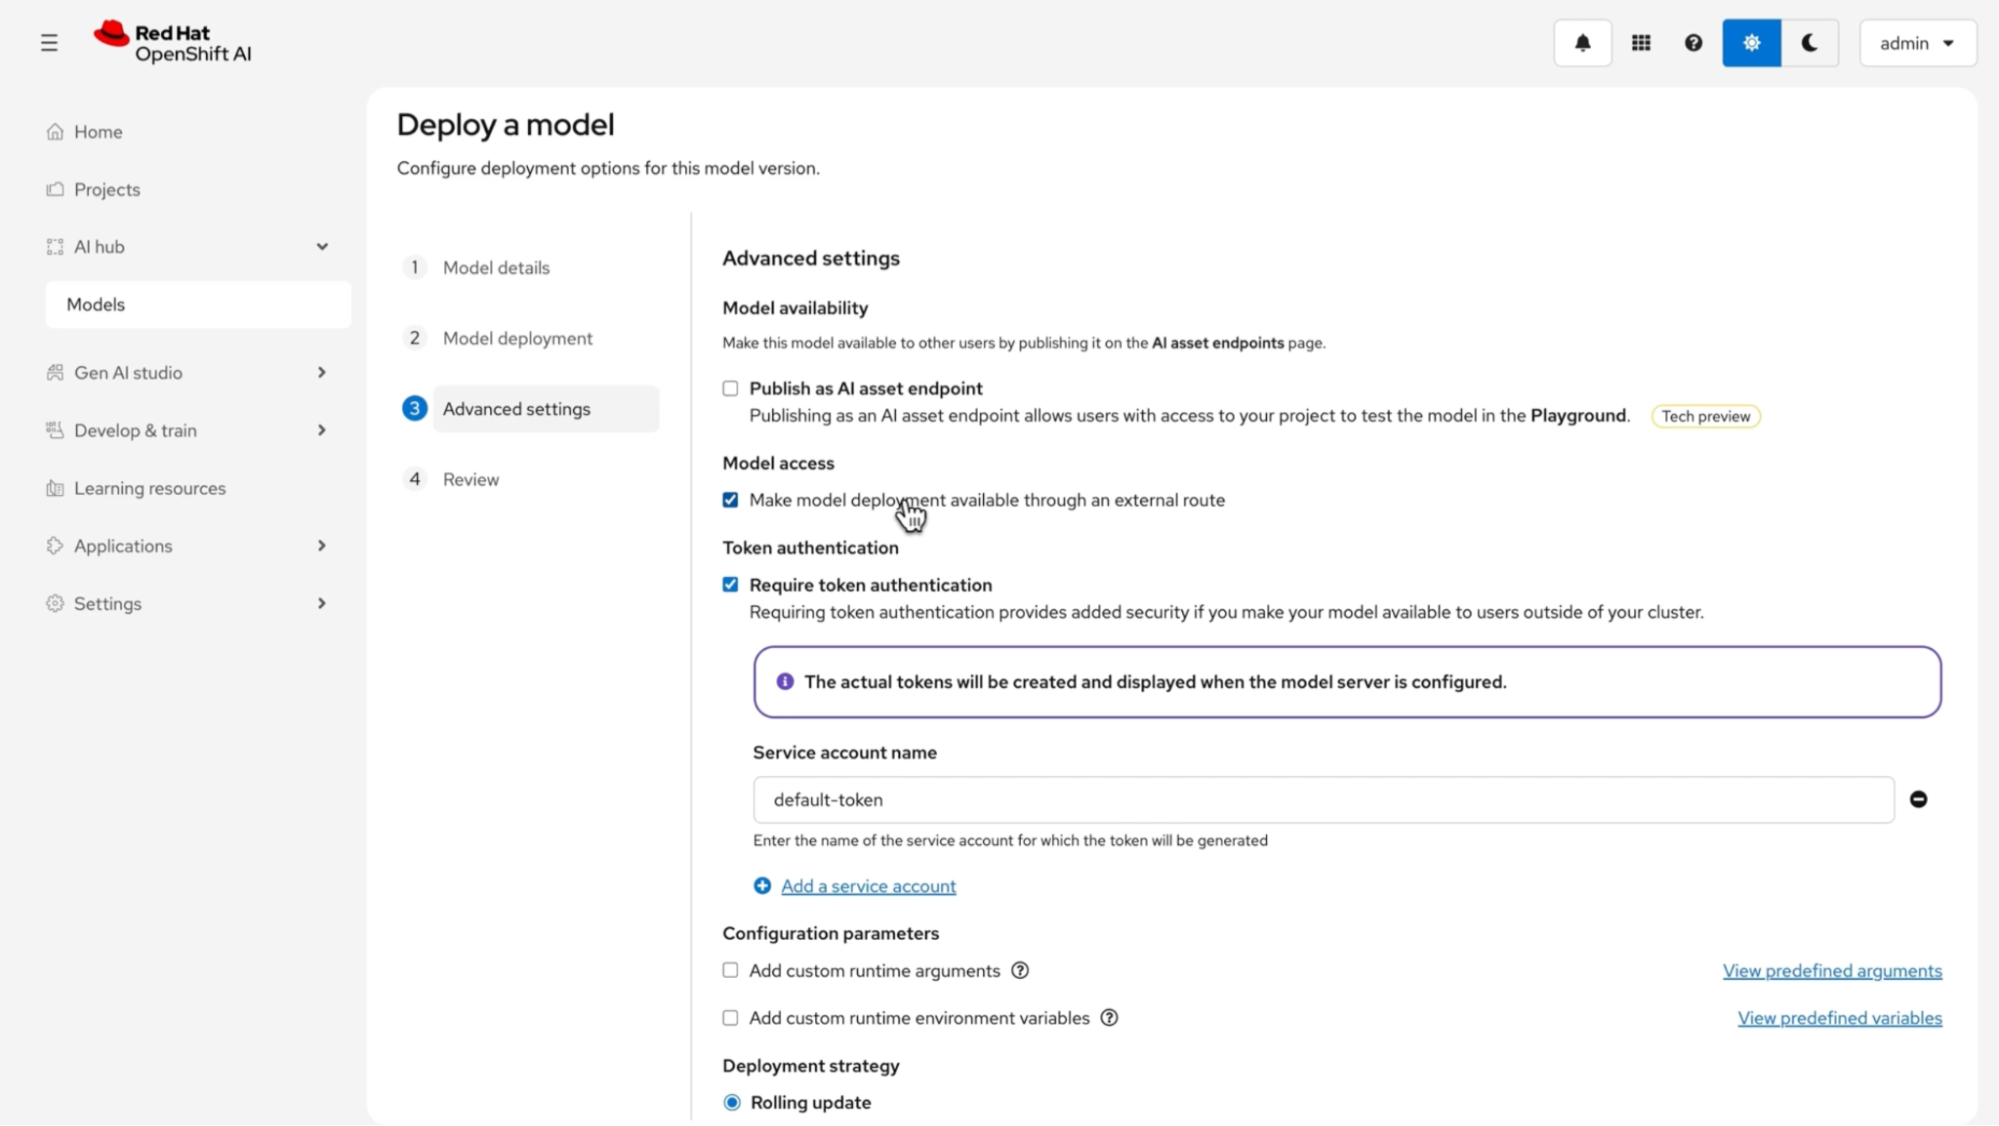
Run Claude Code locally with vLLM and OpenShift AI | Red Hat Developer

Integrate vLLM inference on macOS/iOS with Llama Stack APIs | Red Hat ...
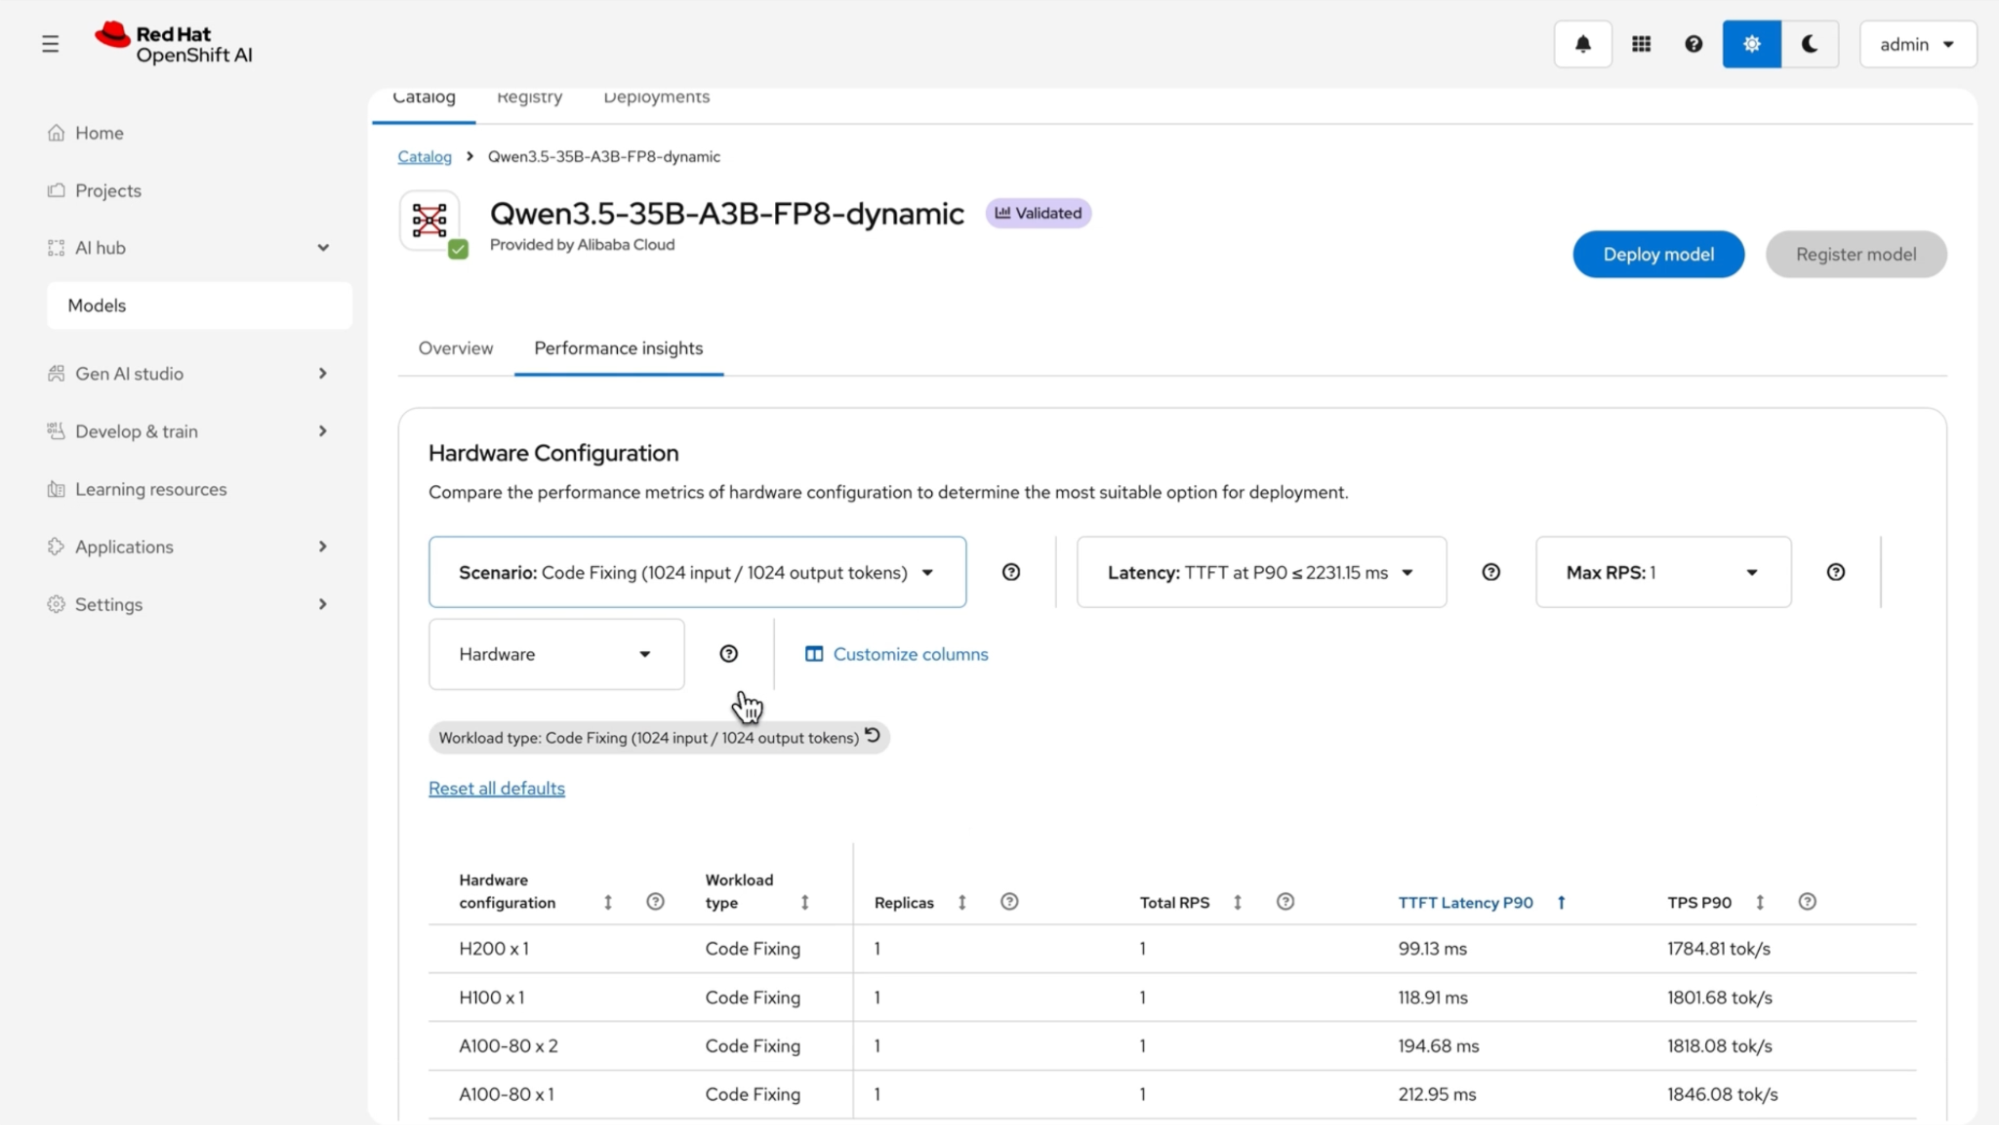
Run Claude Code locally with vLLM and OpenShift AI | Red Hat Developer
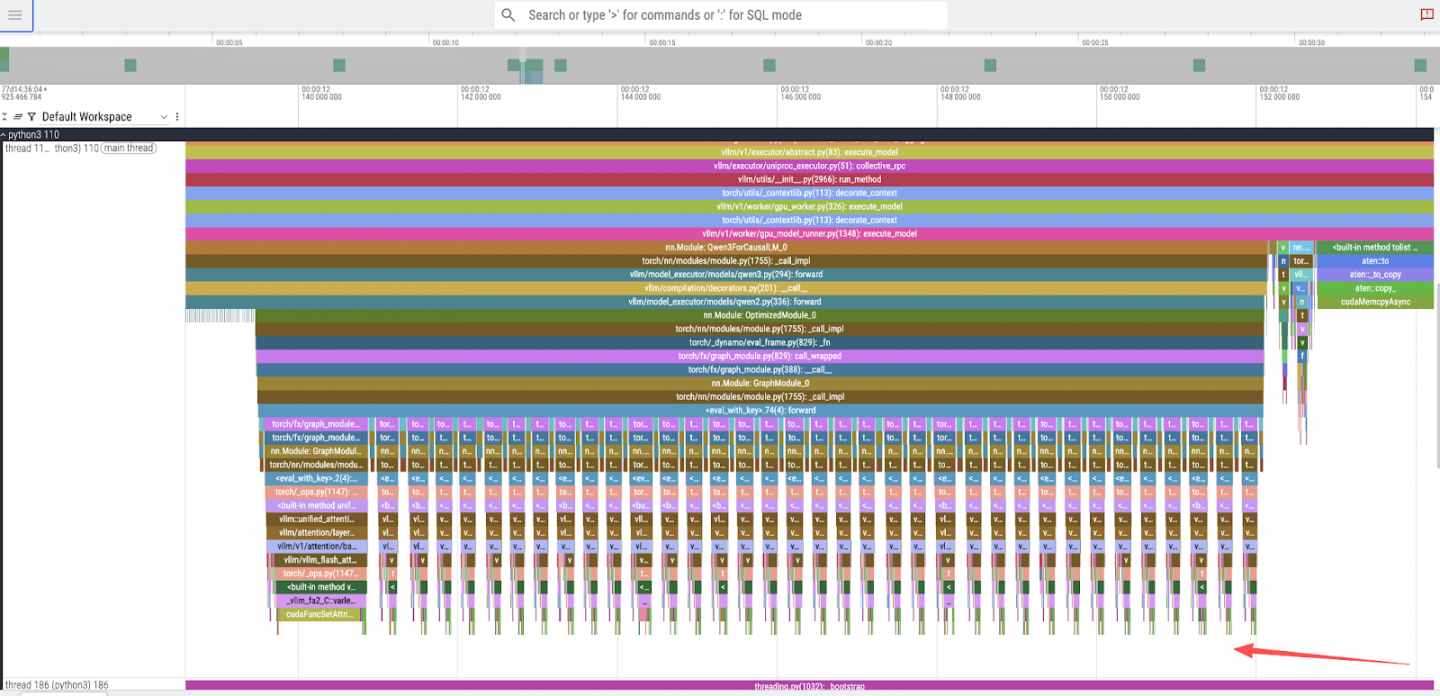
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
Advertisement Space (336x280)
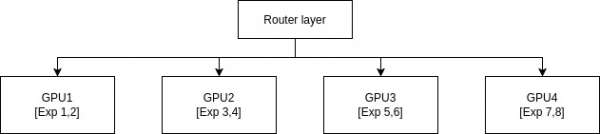
Why vLLM is the best choice for AI inference today | Red Hat Developer

Why vLLM is the best choice for AI inference today | Red Hat Developer

Red Hat AI tops MLPerf Inference v6.0 with vLLM on Qwen3-VL, Whisper ...
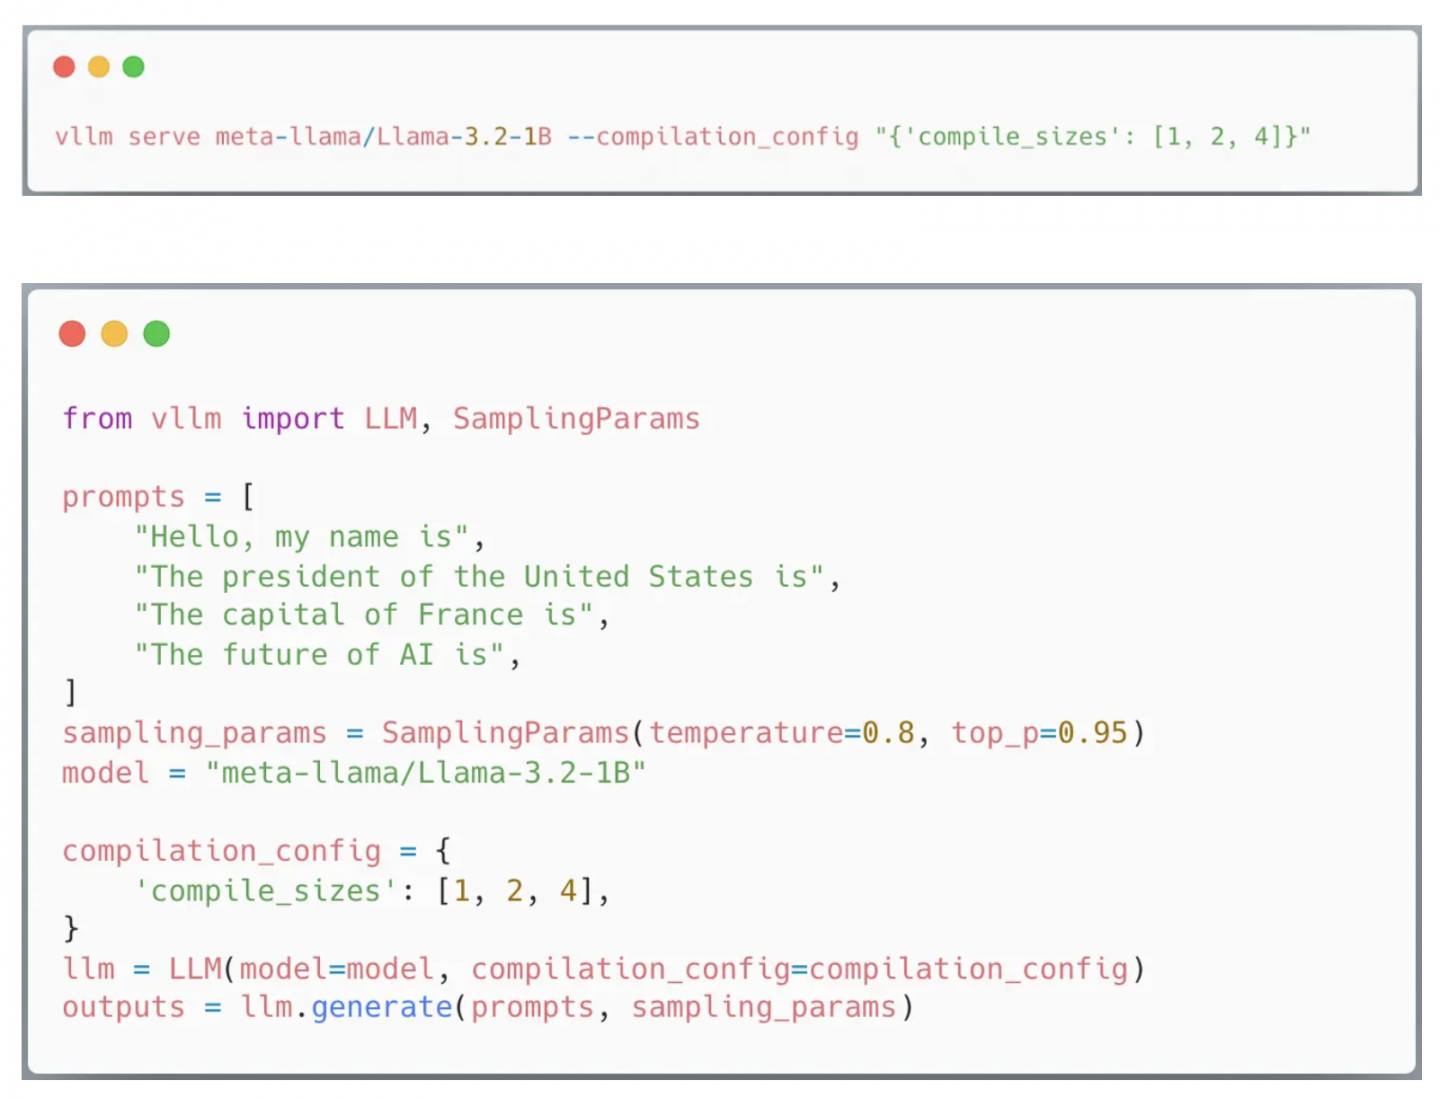
vLLM with torch.compile: Efficient LLM inference on PyTorch | Red Hat ...

vLLM brings FP8 inference to the open source community | Red Hat Developer
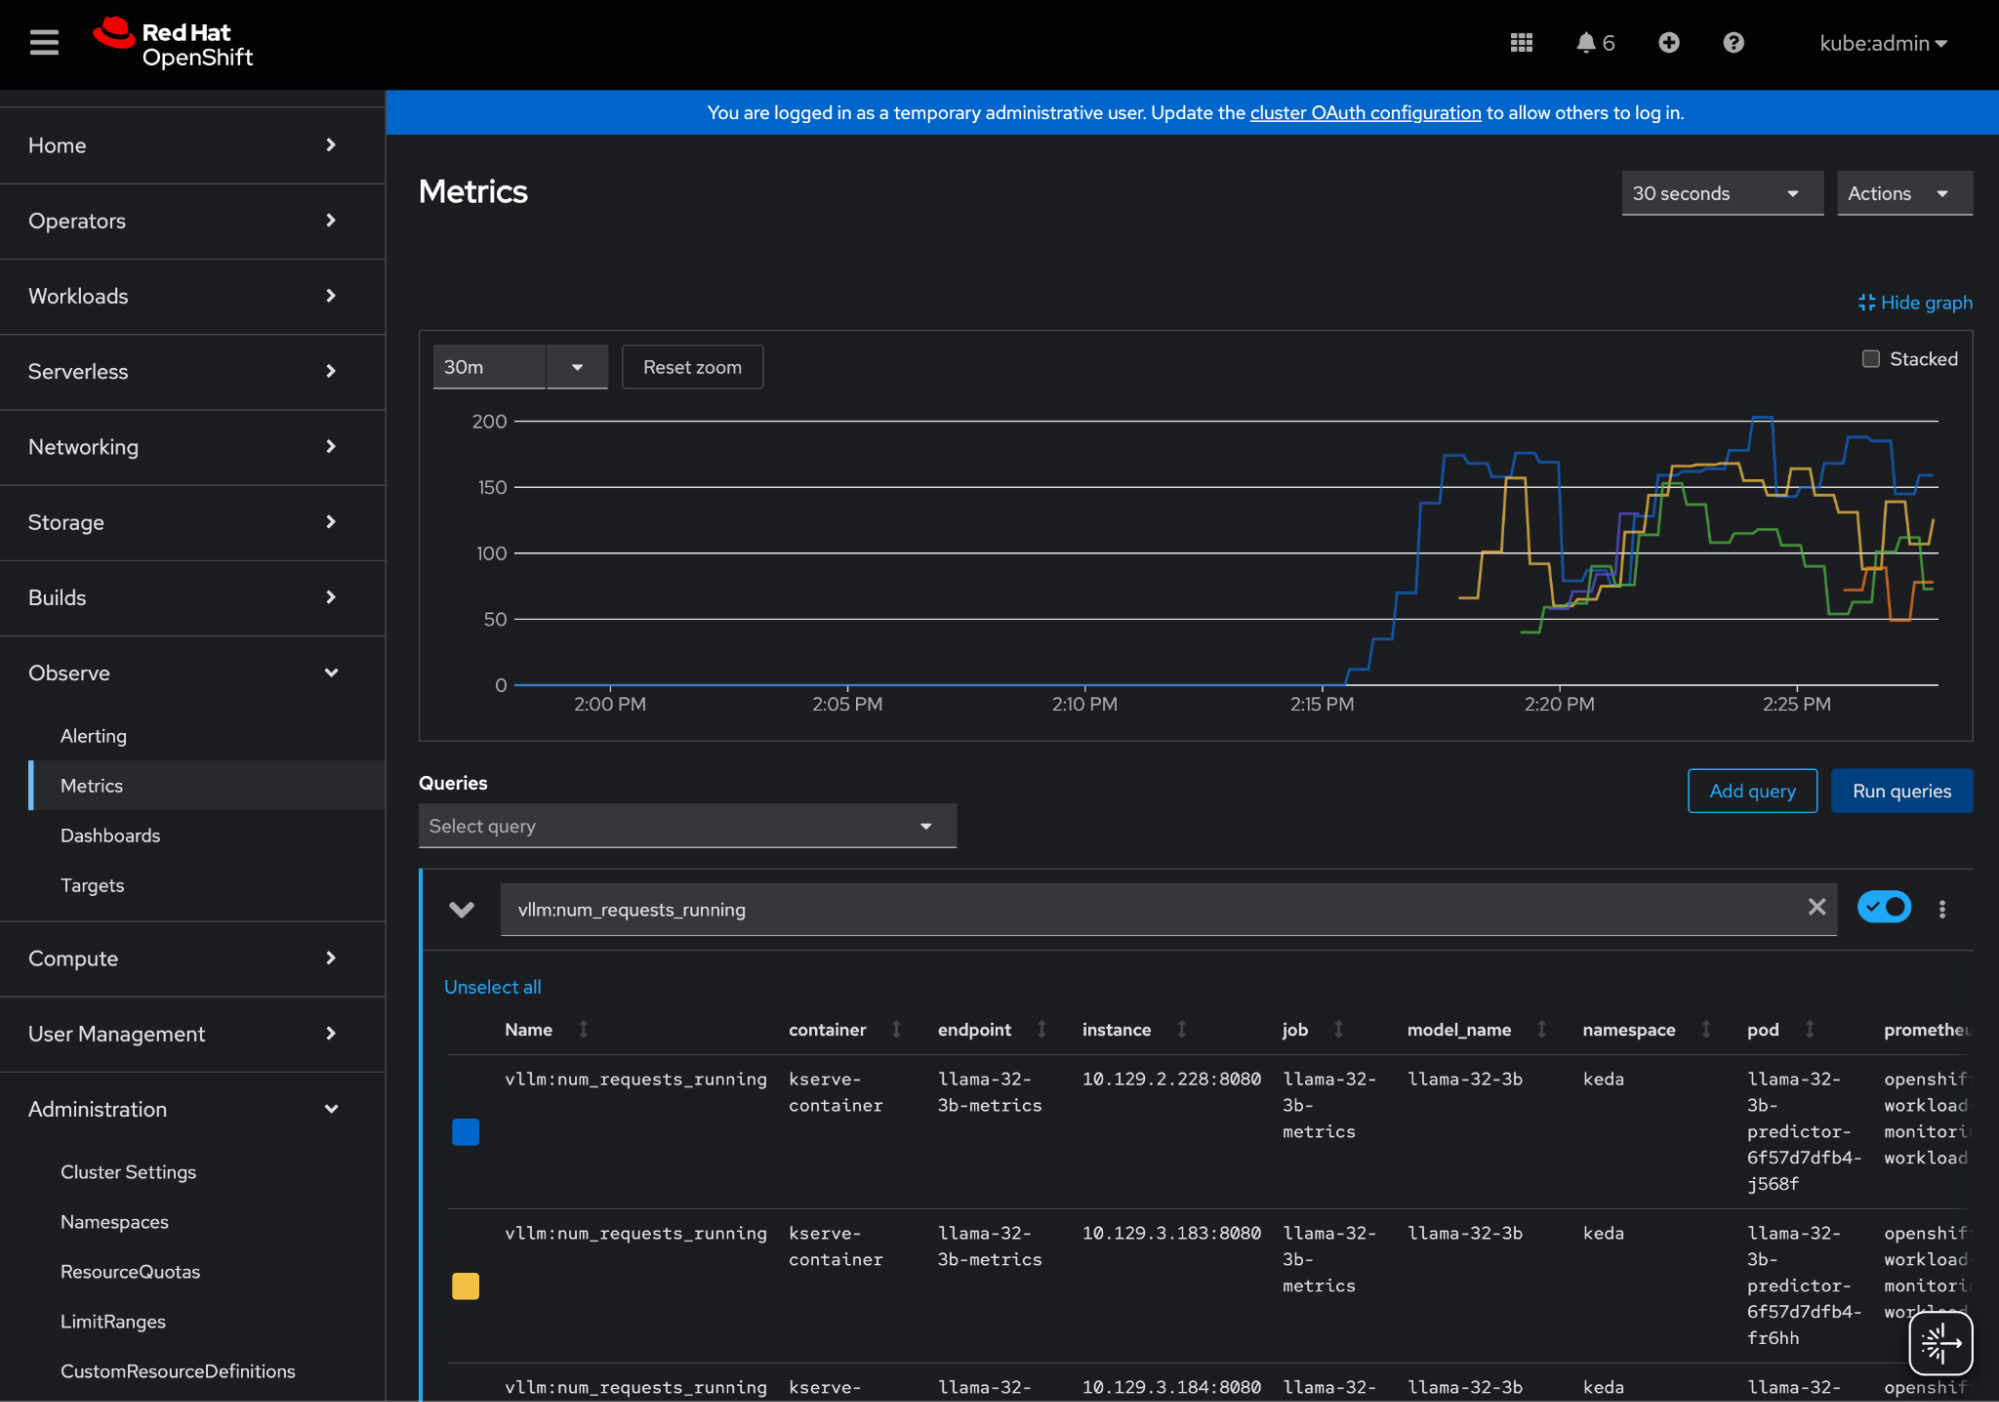
How to set up KServe autoscaling for vLLM with KEDA | Red Hat Developer