
Profiling Vllm Inference Server With Gpu Acceleration On Rhel Red Hat
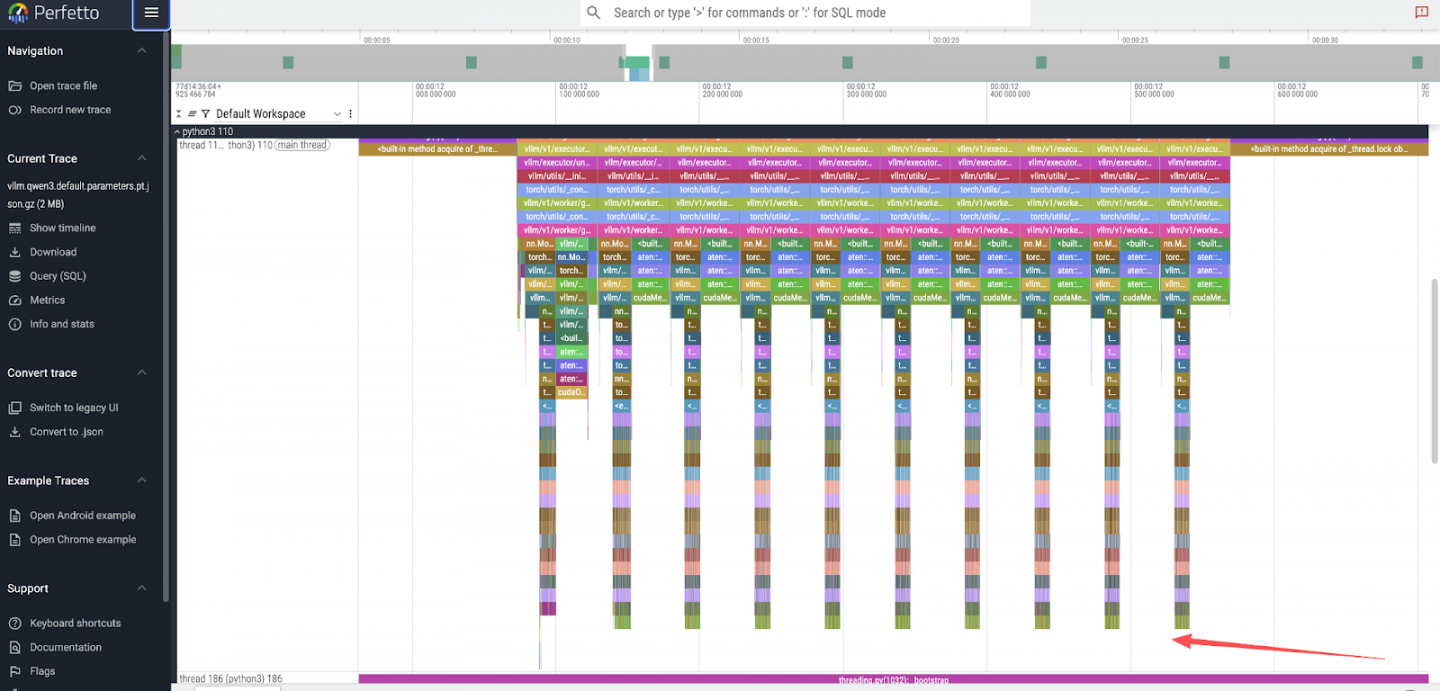
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
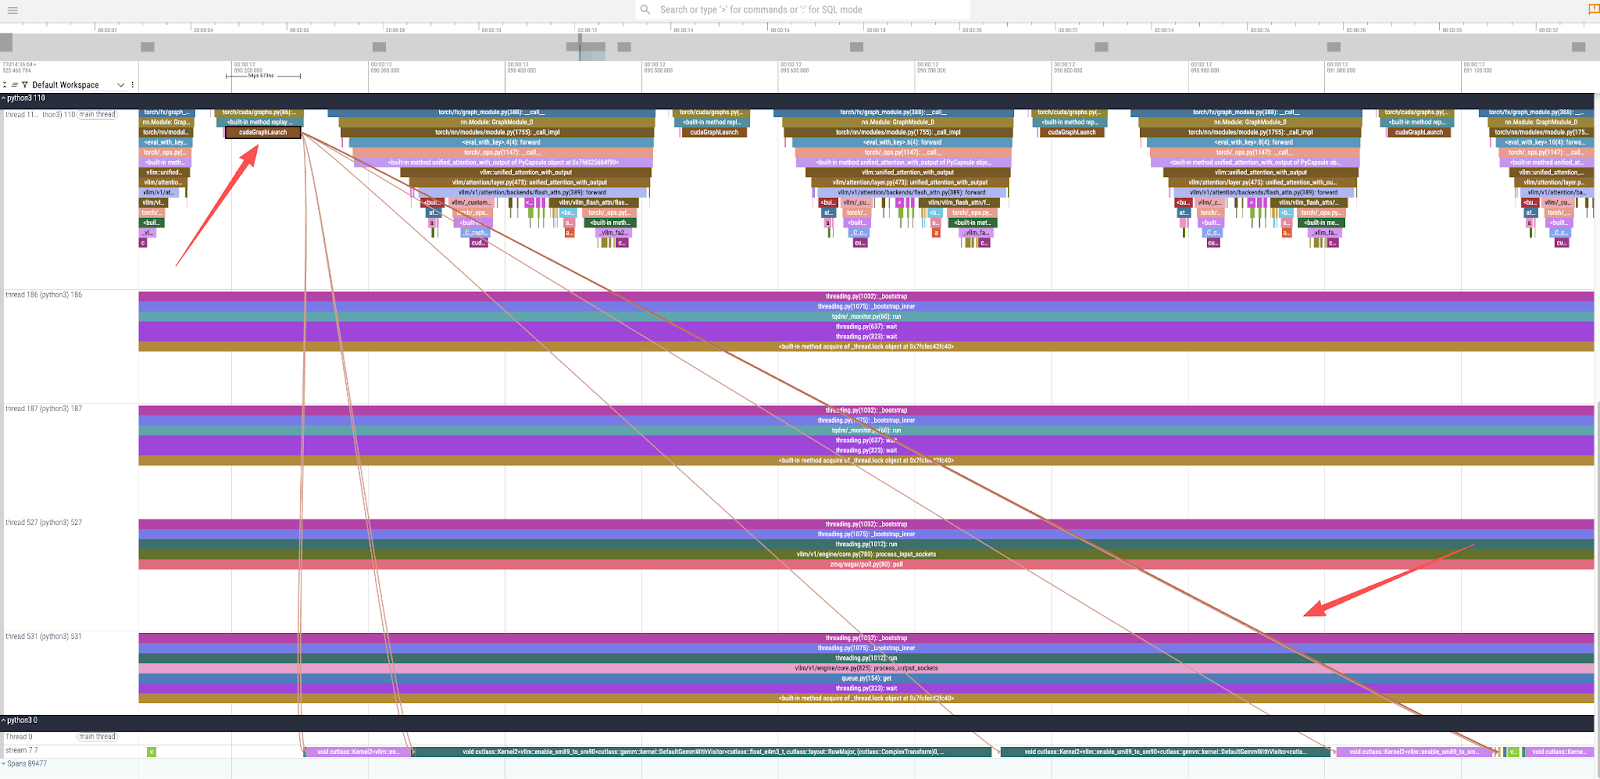
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
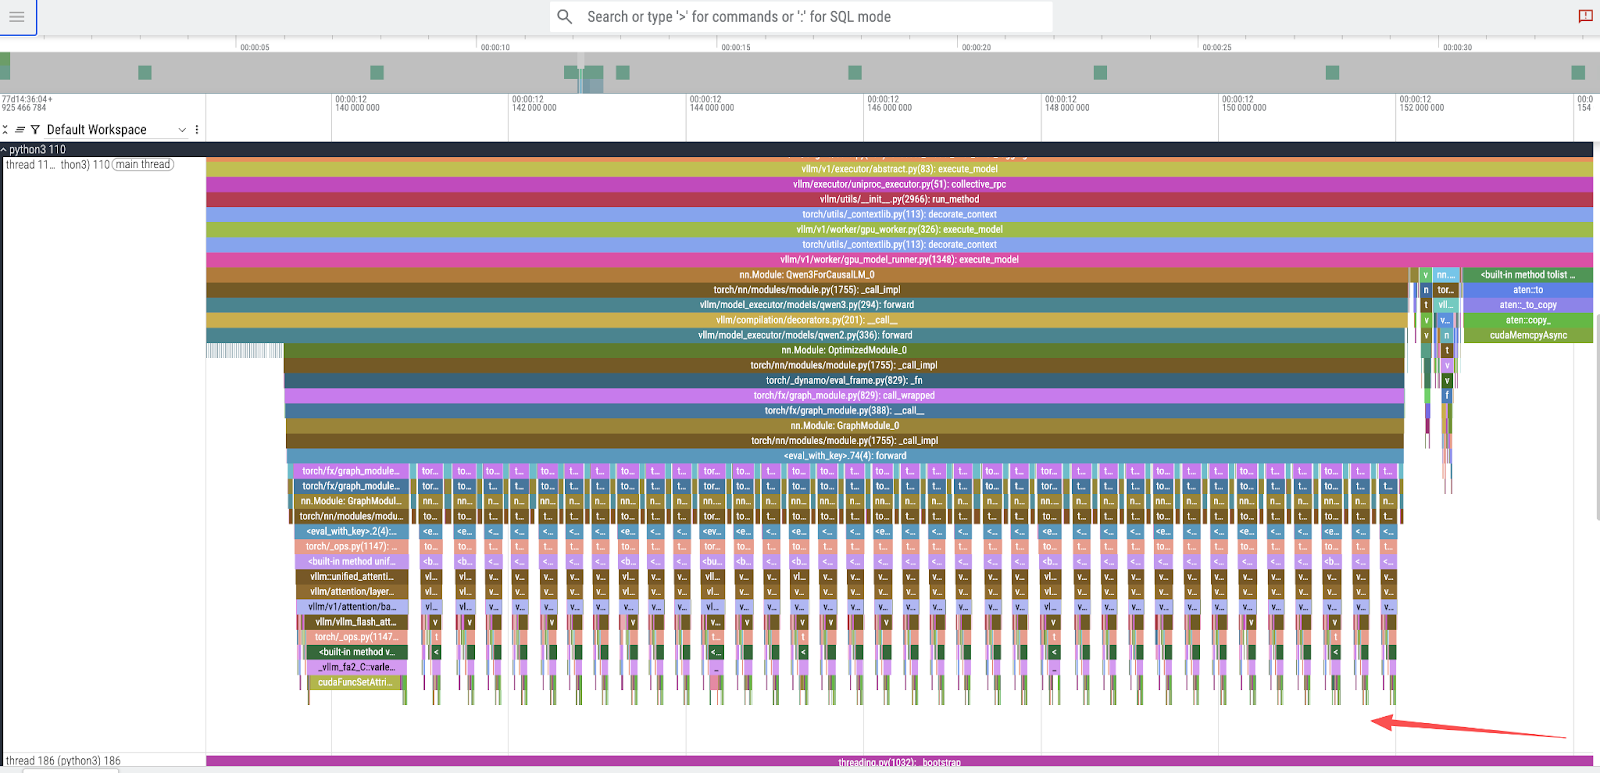
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
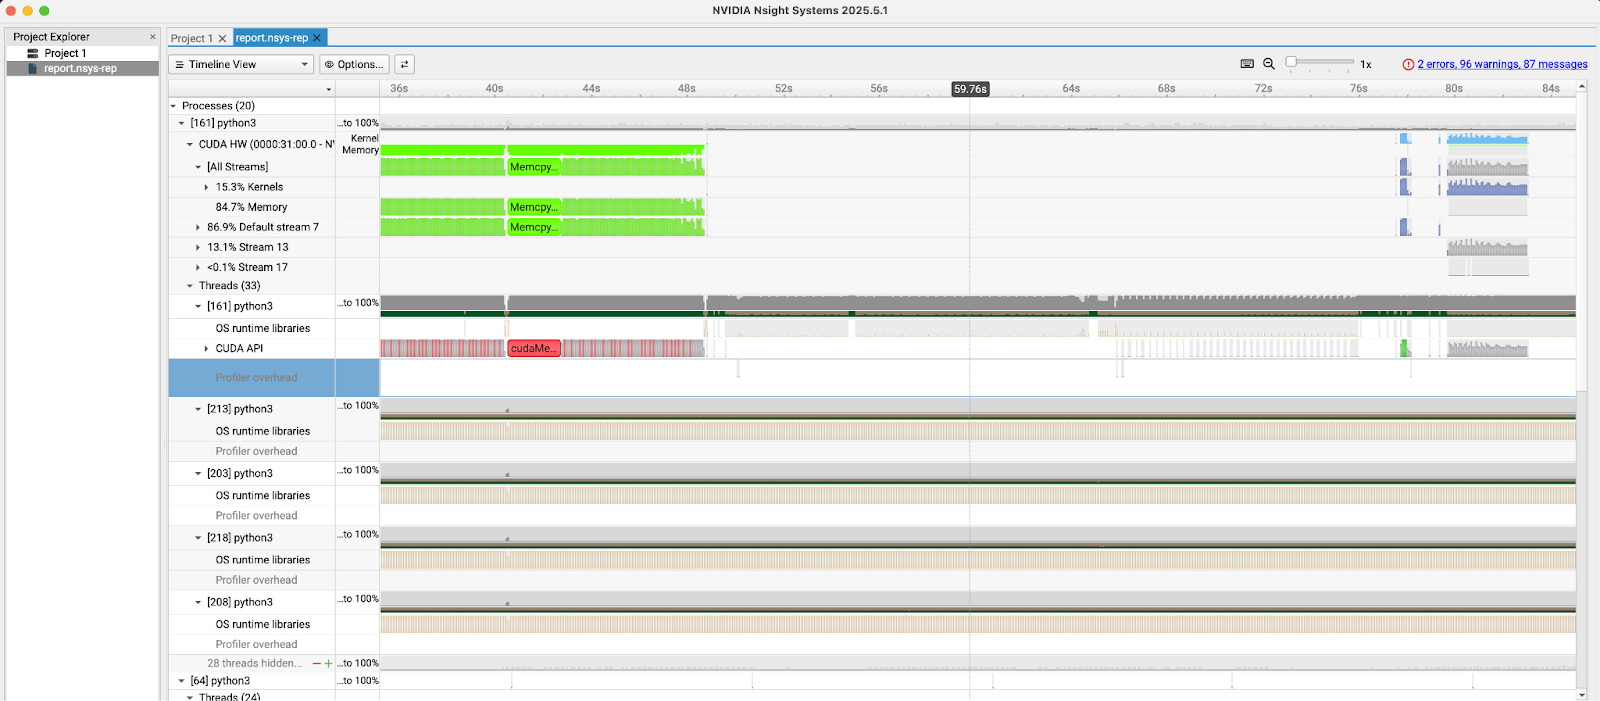
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...
Profiling vLLM Inference Server with GPU acceleration on RHEL | Red Hat ...

Red Hat AI tops MLPerf Inference v6.0 with vLLM on Qwen3-VL, Whisper ...

Red Hat AI tops MLPerf Inference v6.0 with vLLM on Qwen3-VL, Whisper ...

Red Hat AI tops MLPerf Inference v6.0 with vLLM on Qwen3-VL, Whisper ...

Red Hat AI tops MLPerf Inference v6.0 with vLLM on Qwen3-VL, Whisper ...
How to run vLLM on CPUs with OpenShift for GPU-free inference | Red Hat ...
Advertisement Space (300x250)
vLLM with torch.compile: Efficient LLM inference on PyTorch | Red Hat ...
How to run vLLM on CPUs with OpenShift for GPU-free inference | Red Hat ...

Distributed inference with vLLM | Red Hat Developer
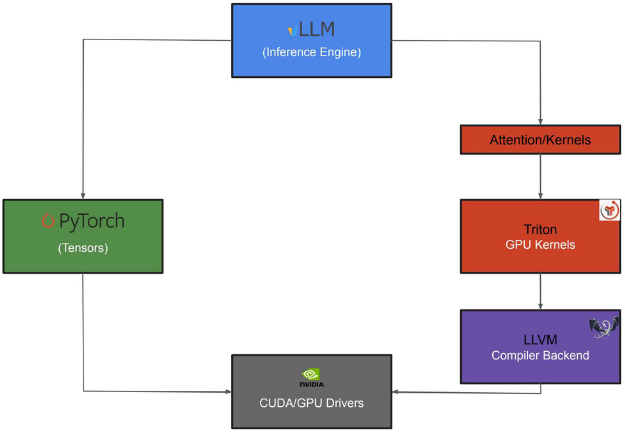
LLM Inference with vLLM Using GPU on Power9
How to deploy and benchmark vLLM with GuideLLM on Kubernetes | Red Hat ...
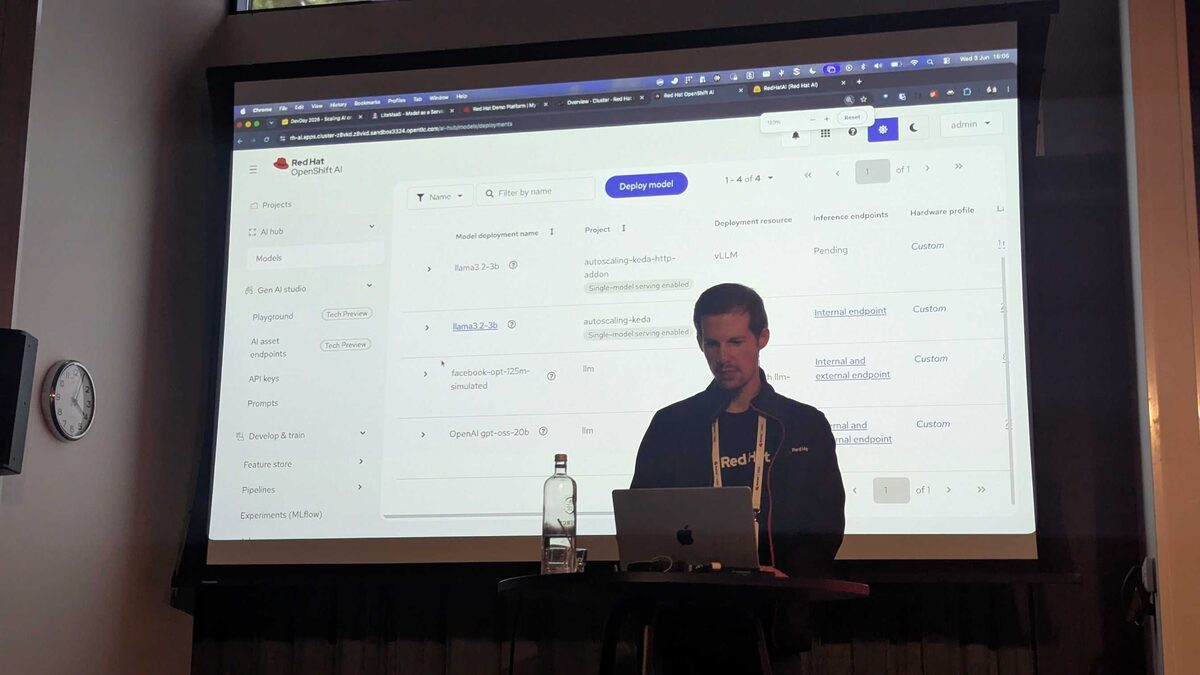
vLLM Inference Optimizations on Red Hat OpenShift AI
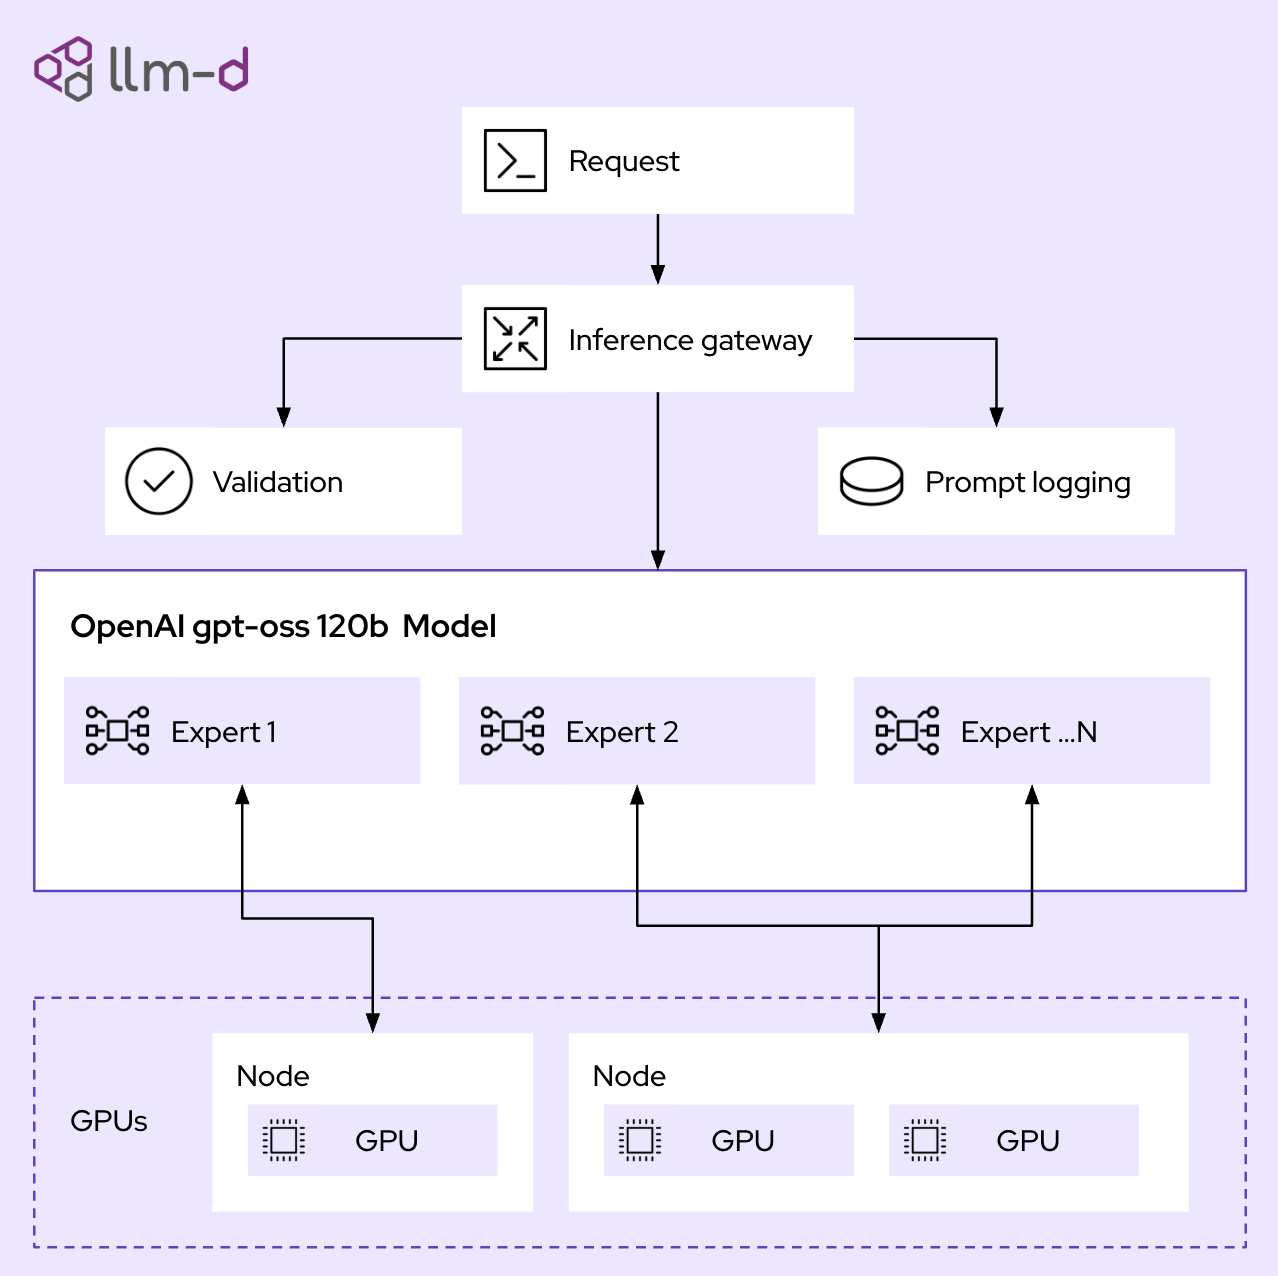
Introduction to distributed inference with llm-d | Red Hat Developer
Why vLLM is the best choice for AI inference today | Red Hat Developer

Red Hat AI Inference Server 소개: 어디서나 최적화된 고성능 LLM 서빙
Why vLLM is the best choice for AI inference today | Red Hat Developer
Advertisement Space (336x280)
vLLM Inference Optimization on RHEL AI | Luca Berton
How to enable NVIDIA GPU acceleration in OpenShift Local | Red Hat ...
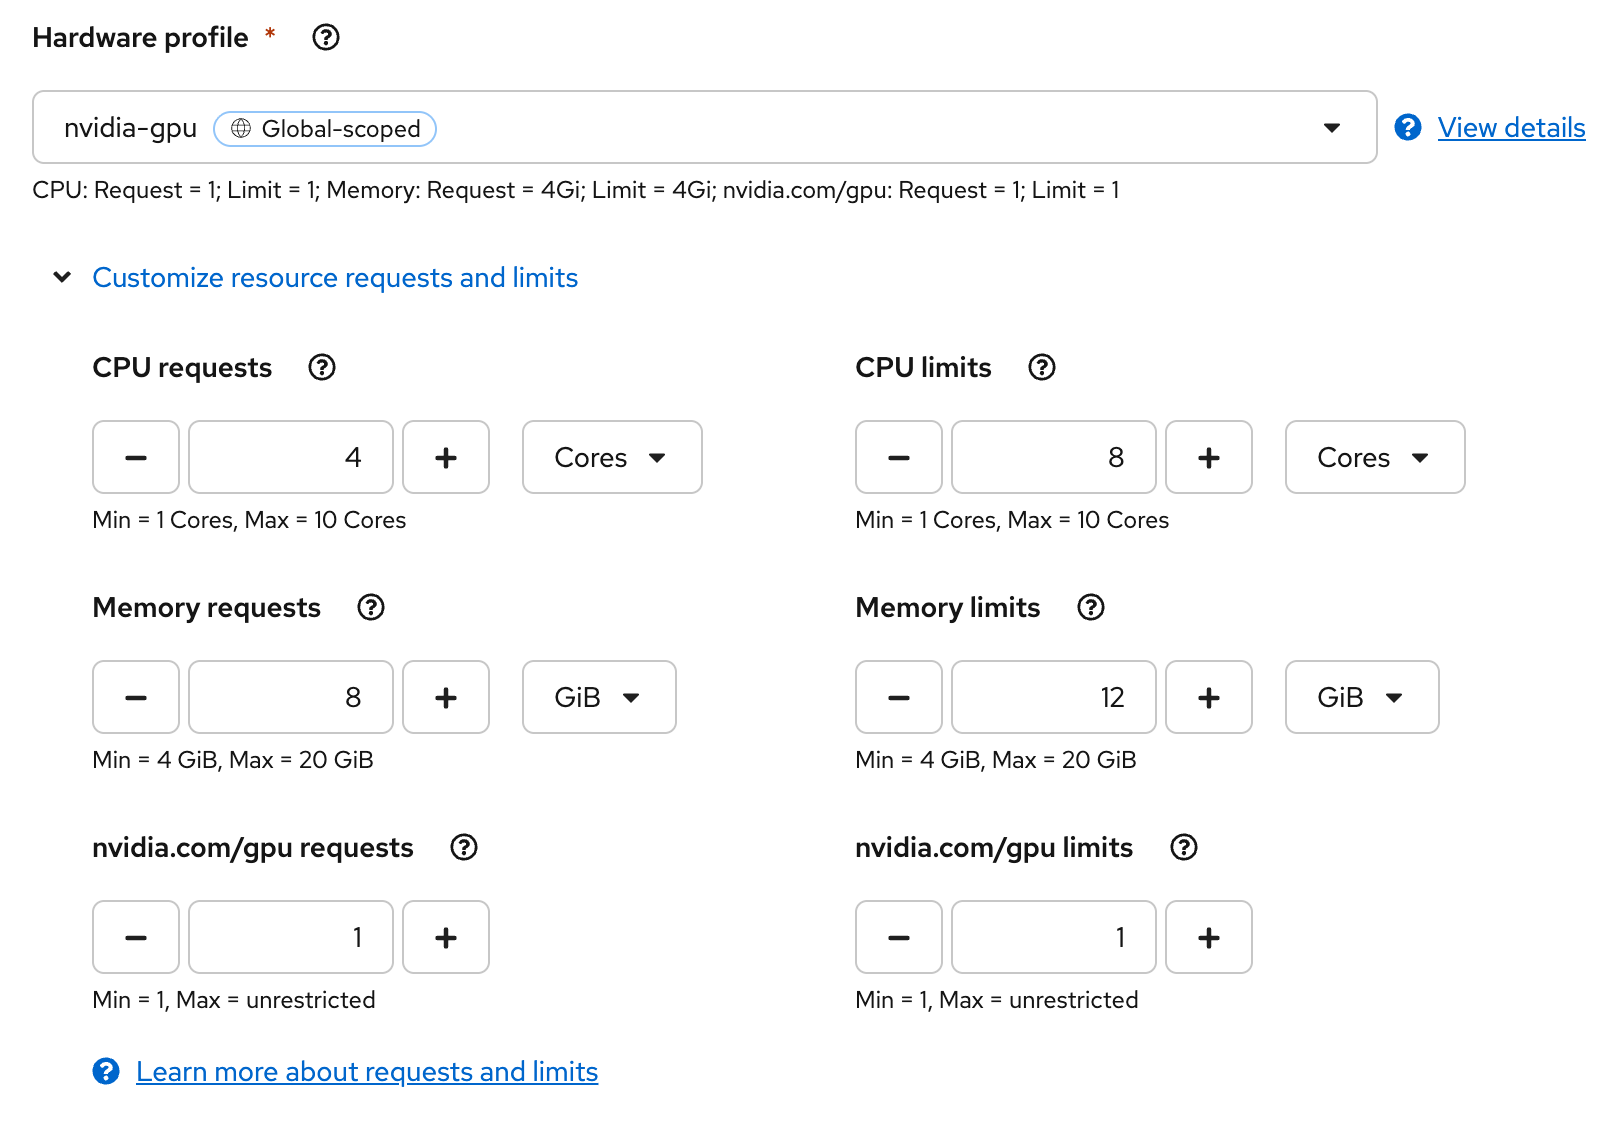
Autoscaling vLLM with OpenShift AI | Red Hat Developer
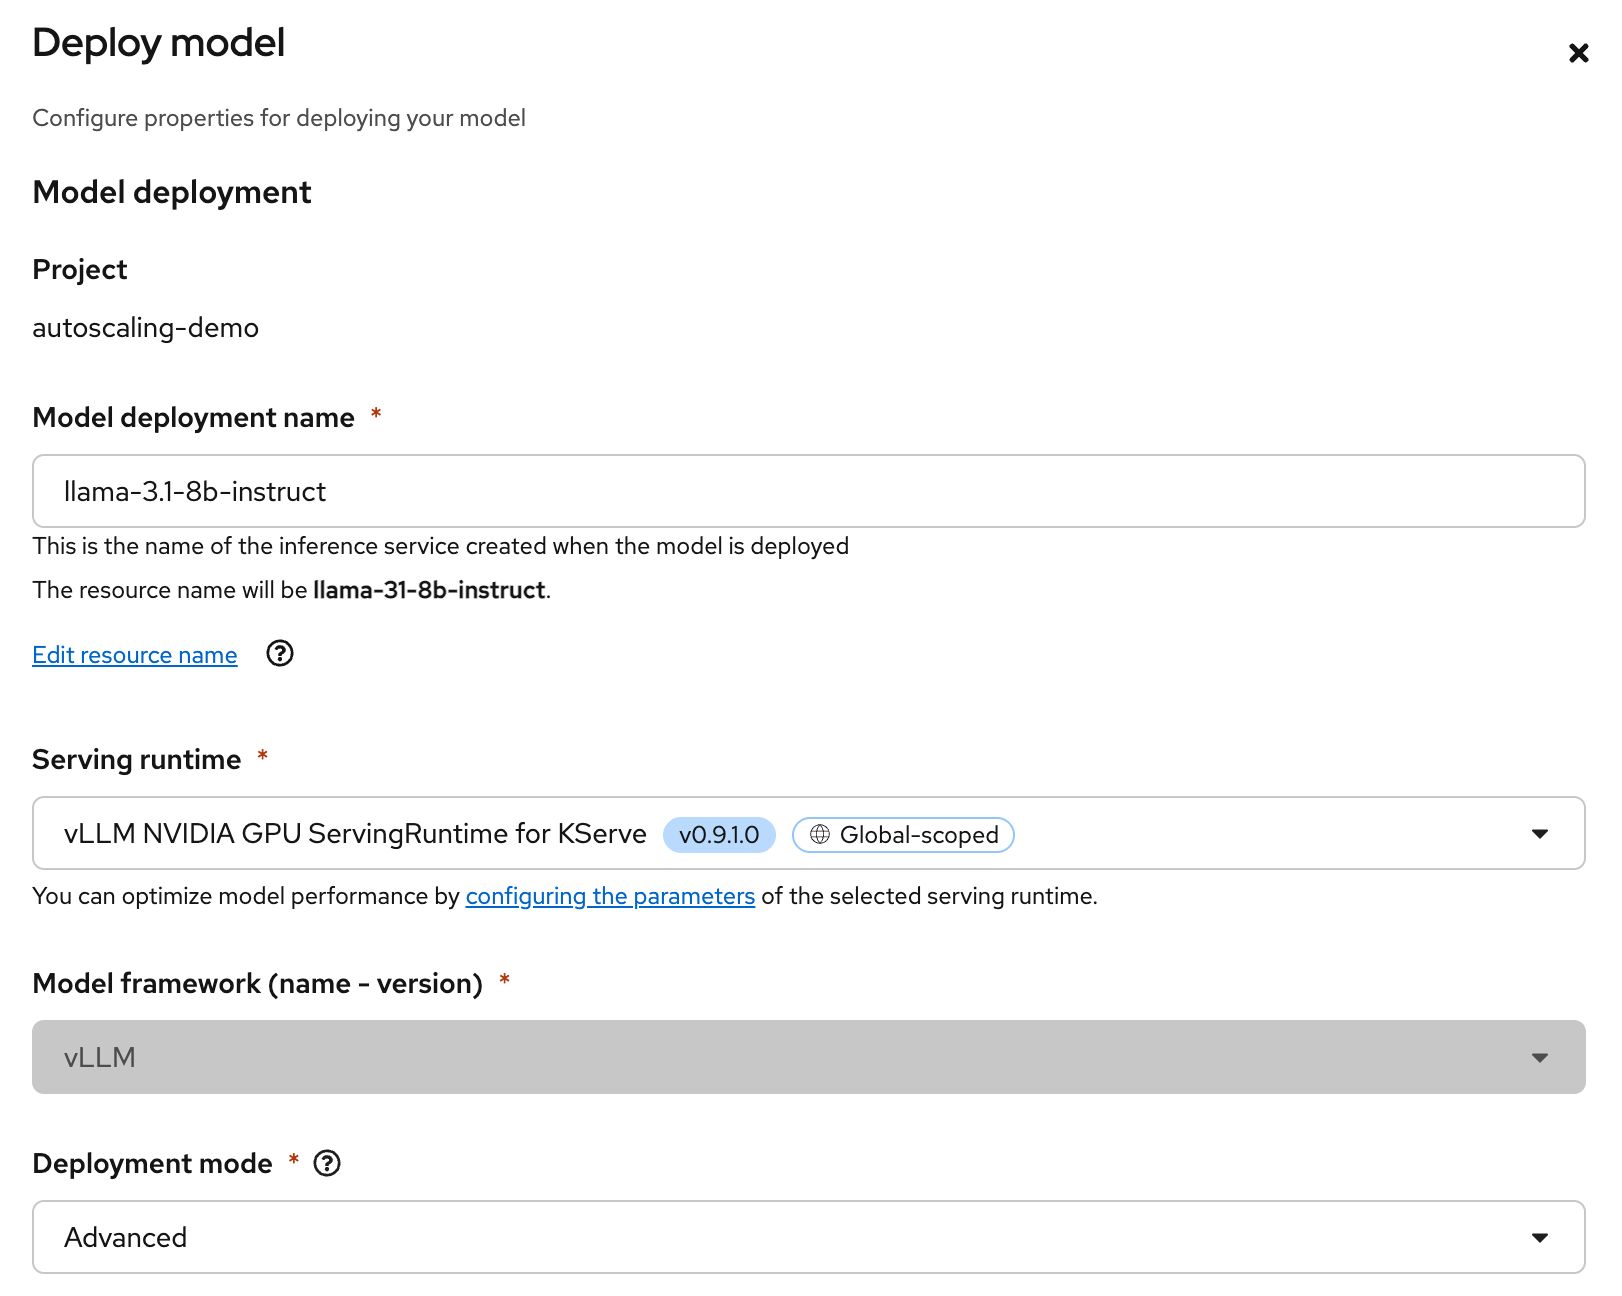
Autoscaling vLLM with OpenShift AI | Red Hat Developer

Red Hat Unveils “AI Inference Server” to Run Gen AI on Any Cloud – Use ...
How to Serve AI Models Using vLLM on RHEL for Production Inference
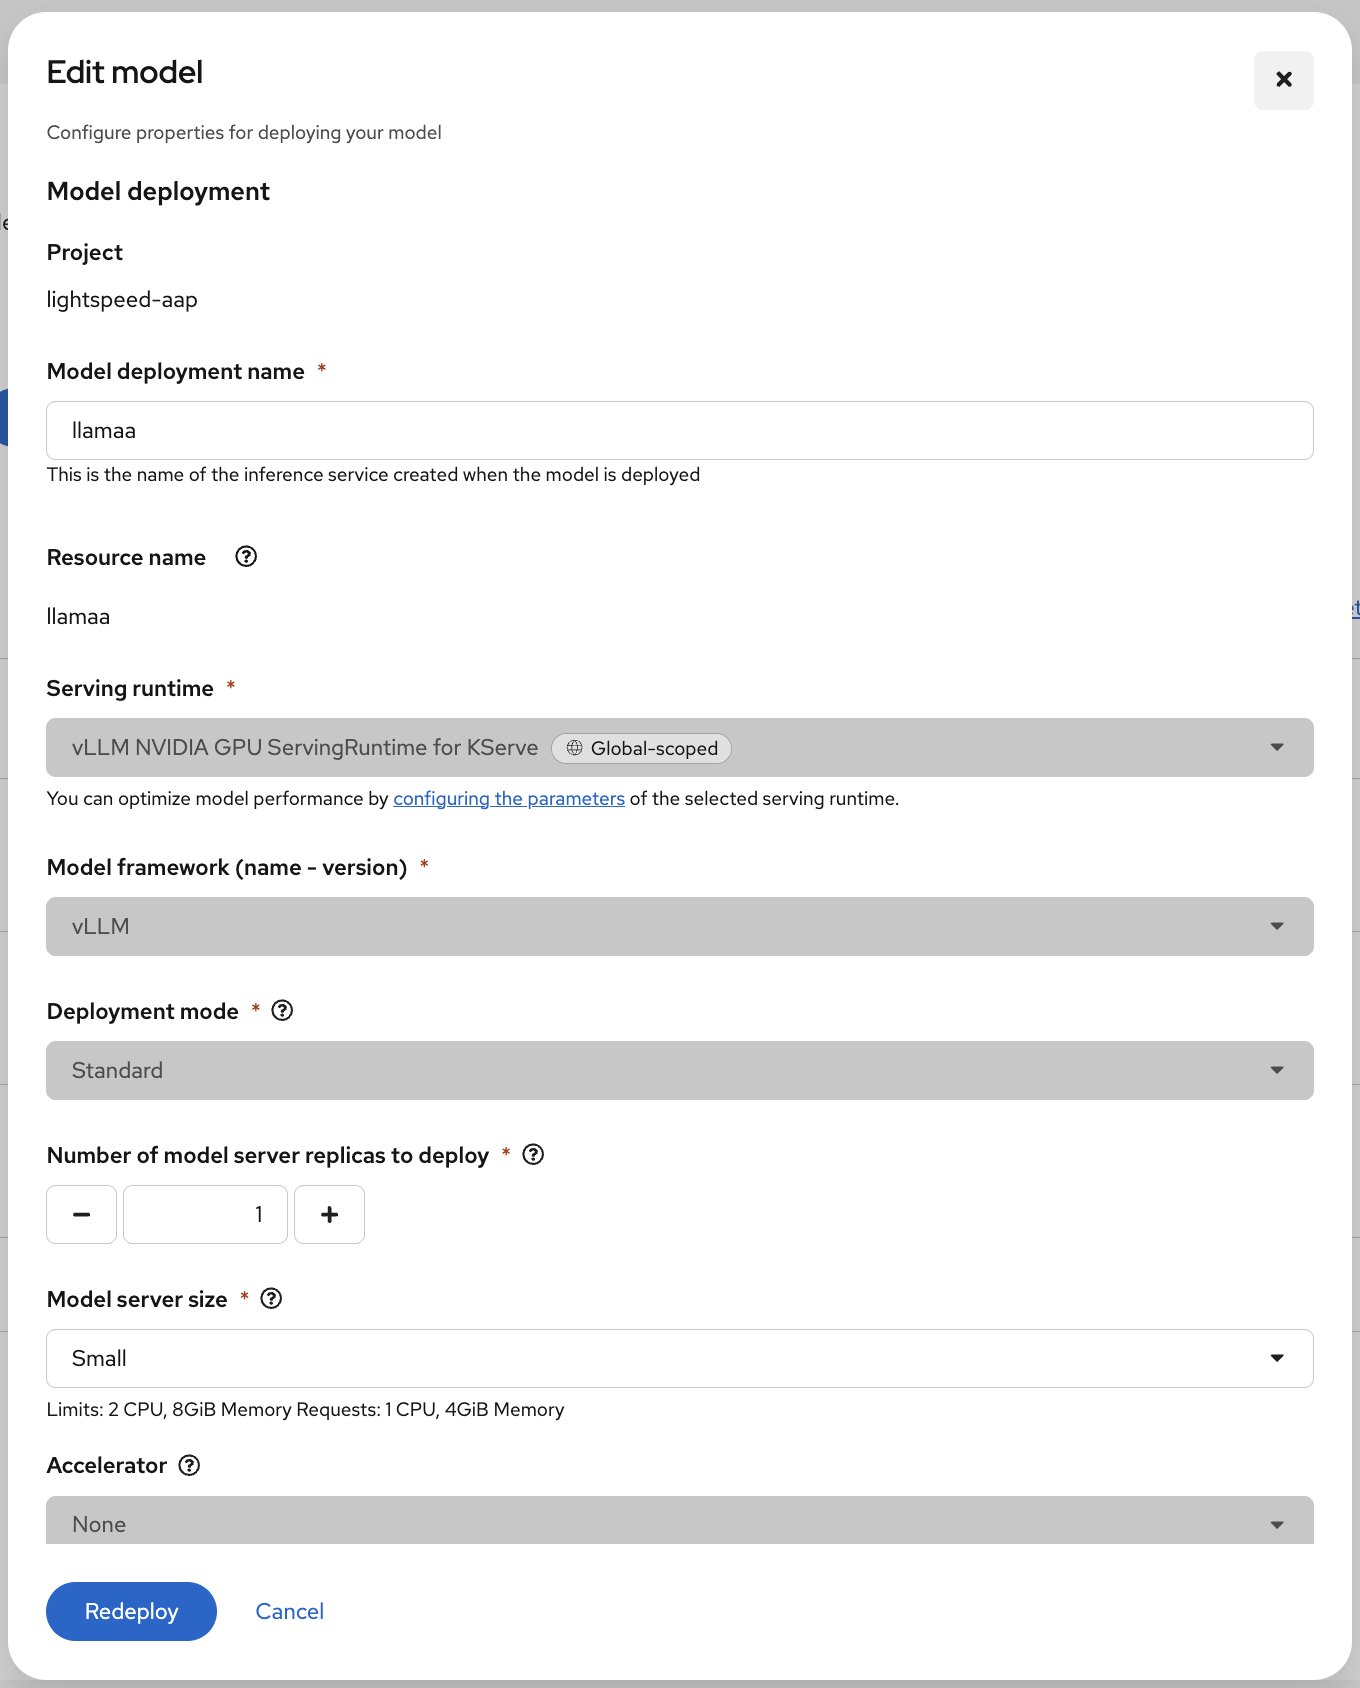
Deploy an LLM inference service on OpenShift AI | Red Hat Developer
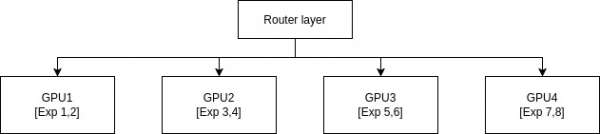
Why vLLM is the best choice for AI inference today | Red Hat Developer
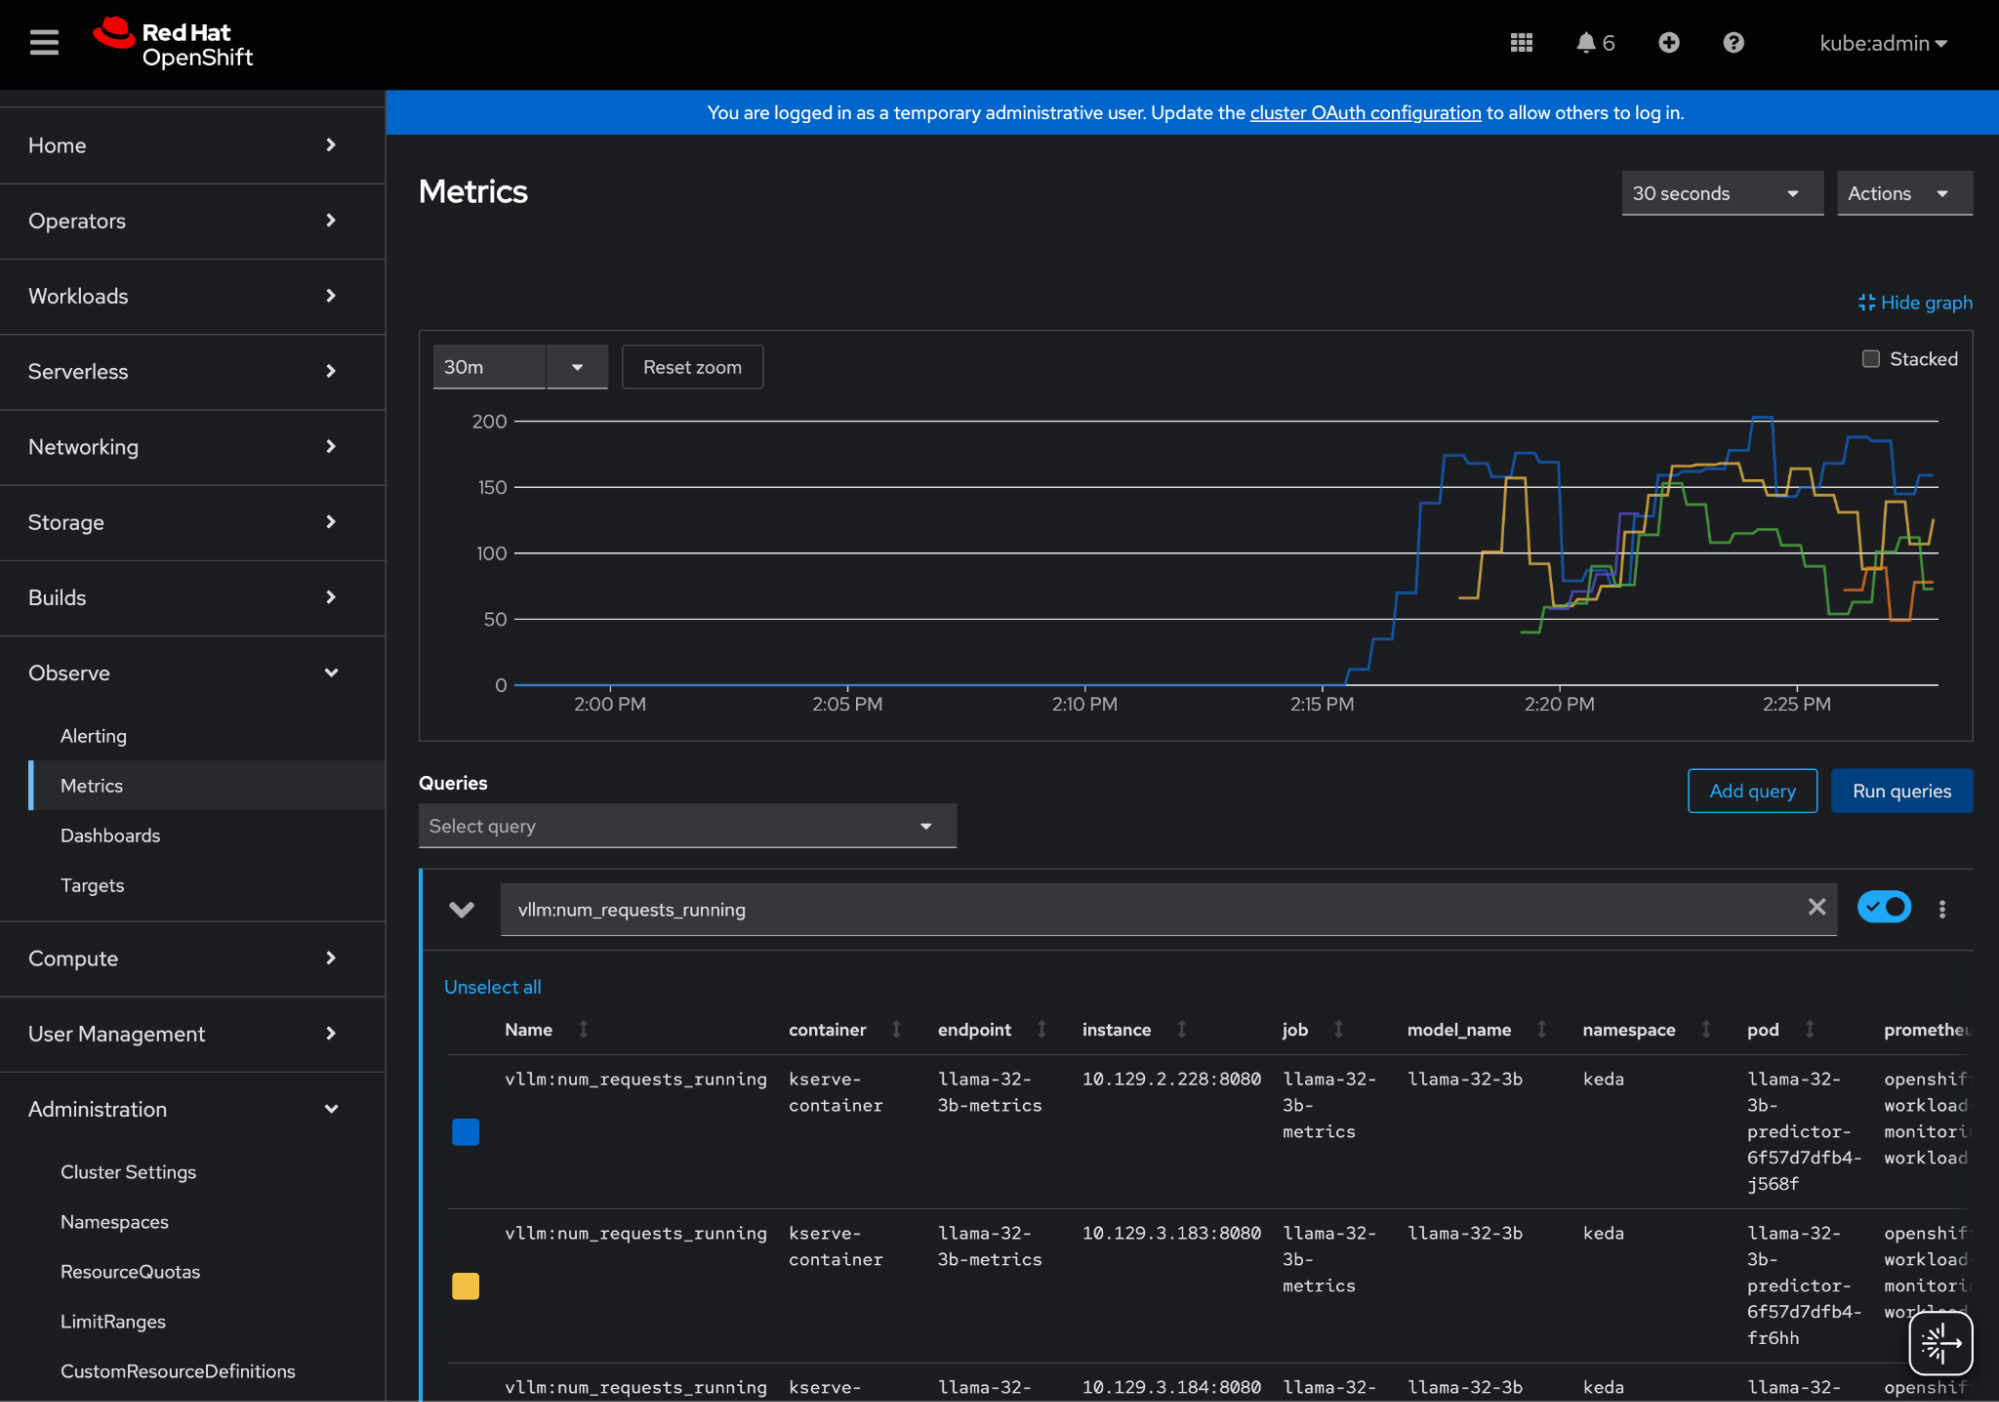
How to set up KServe autoscaling for vLLM with KEDA | Red Hat Developer

Le novità dal Red Hat Summit: RHEL 10, AI Inference Server, OpenShift ...
Advertisement Space (336x280)
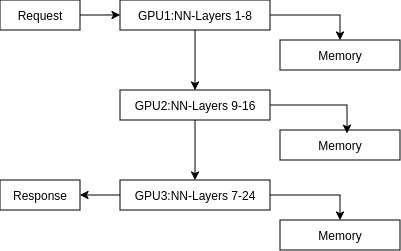
Why vLLM is the best choice for AI inference today | Red Hat Developer

Red Hat AI Inference Server - IstvanKerekes.tech
GitHub - anishgillella/vllm: Production-ready vLLM inference server on ...

Profiling Llama-4 inference with vLLM — Tutorials for AI developers 12.0
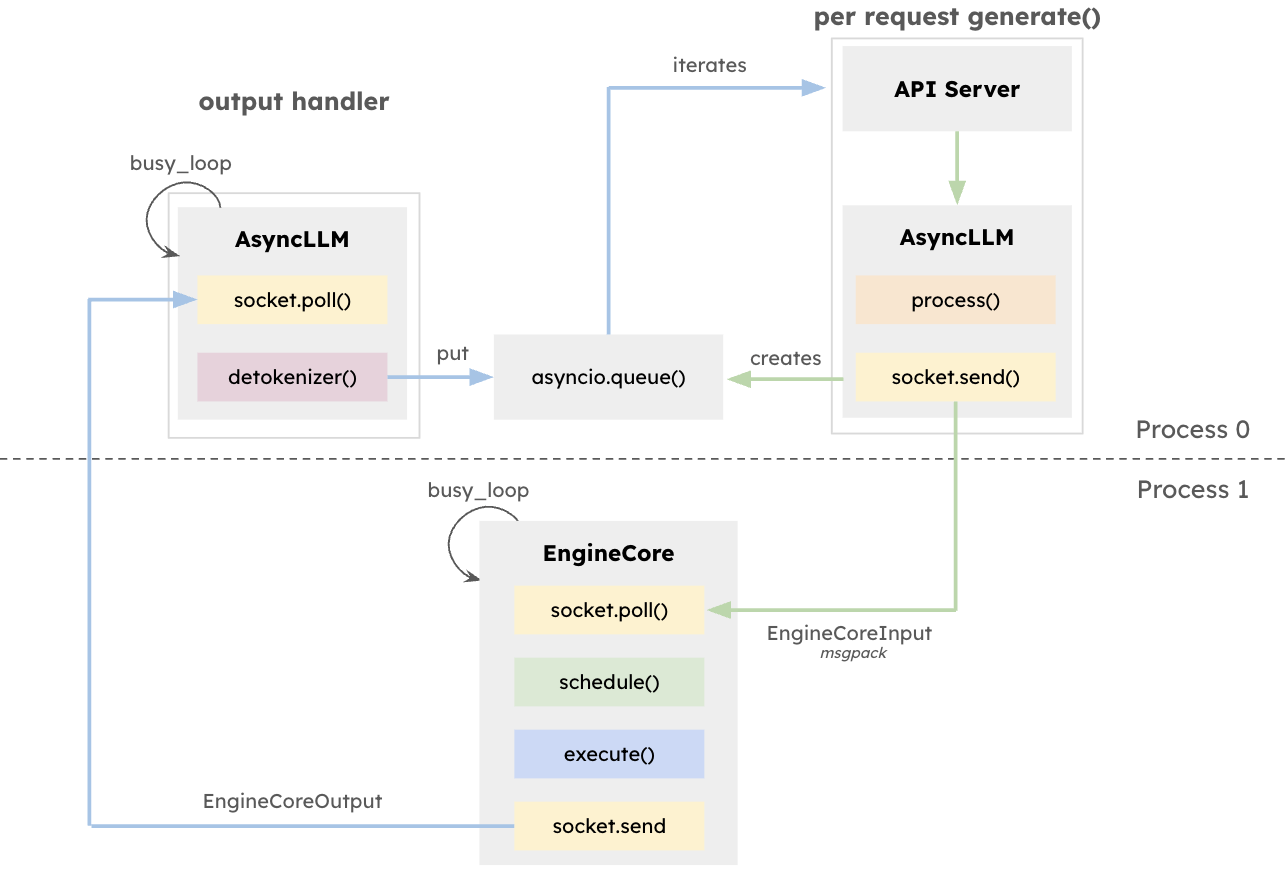
Introducing Red Hat AI Inference Server: High-performance, optimized ...

Efficient and reproducible LLM inference with Red Hat: MLPerf Inference ...