
Entropy Guided Kv Caching For Efficient Llm Inference
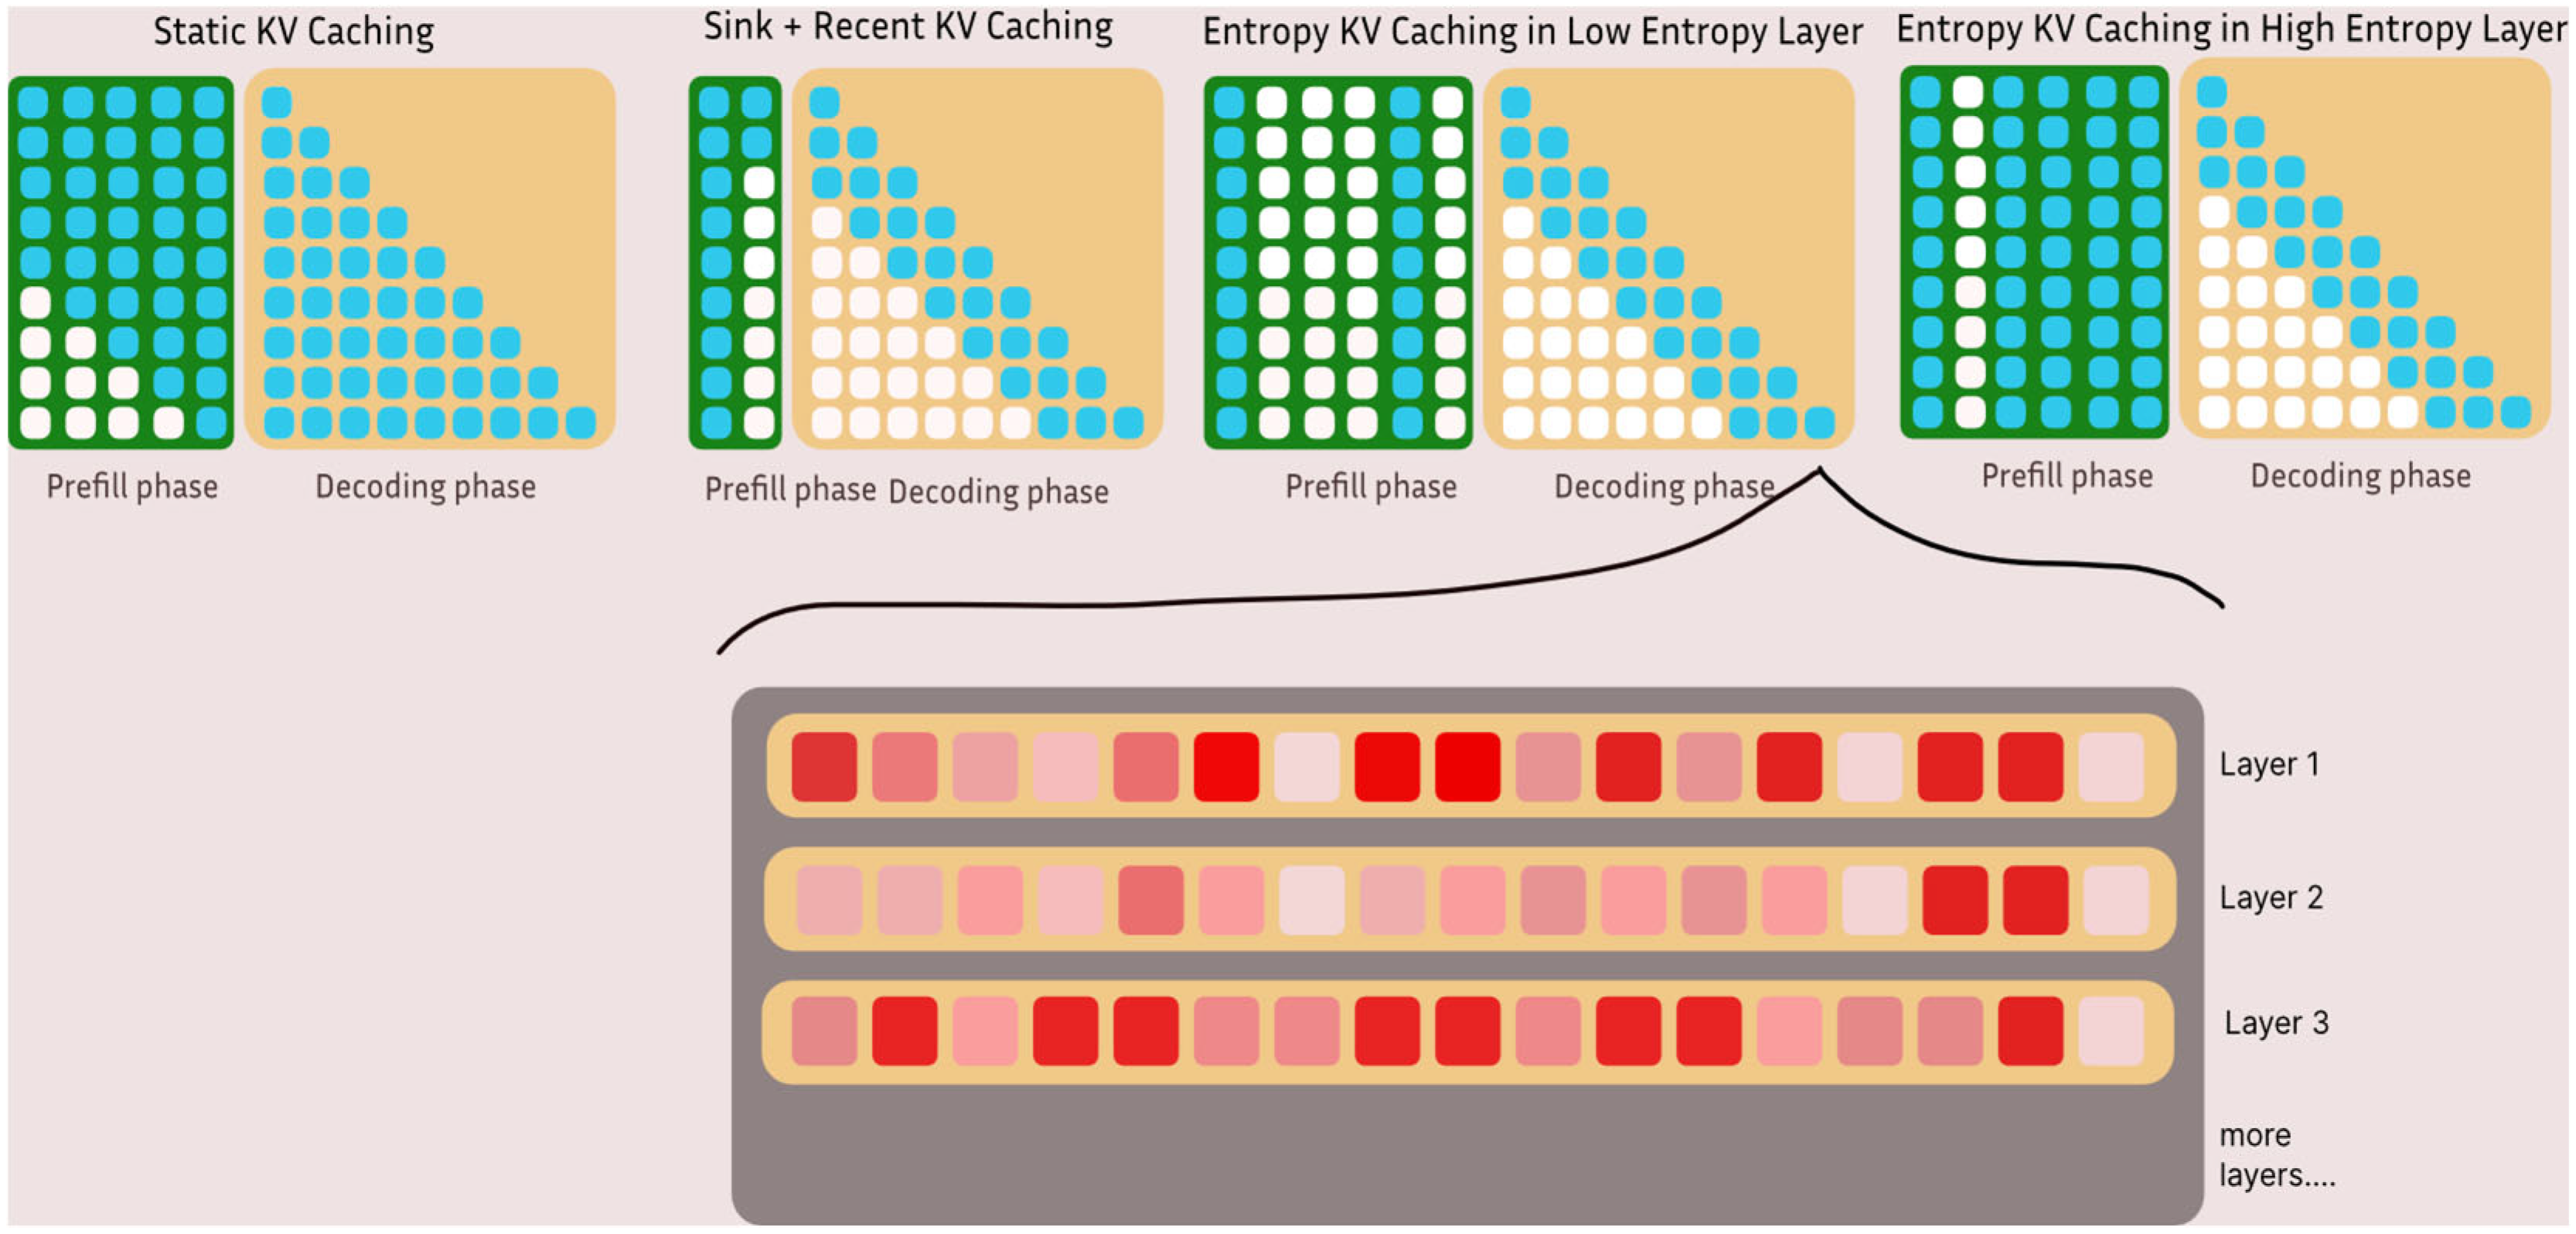
Entropy-Guided KV Caching for Efficient LLM Inference

Entropy-Guided KV Caching for Efficient LLM Inference

Entropy-Guided KV Caching for Efficient LLM Inference
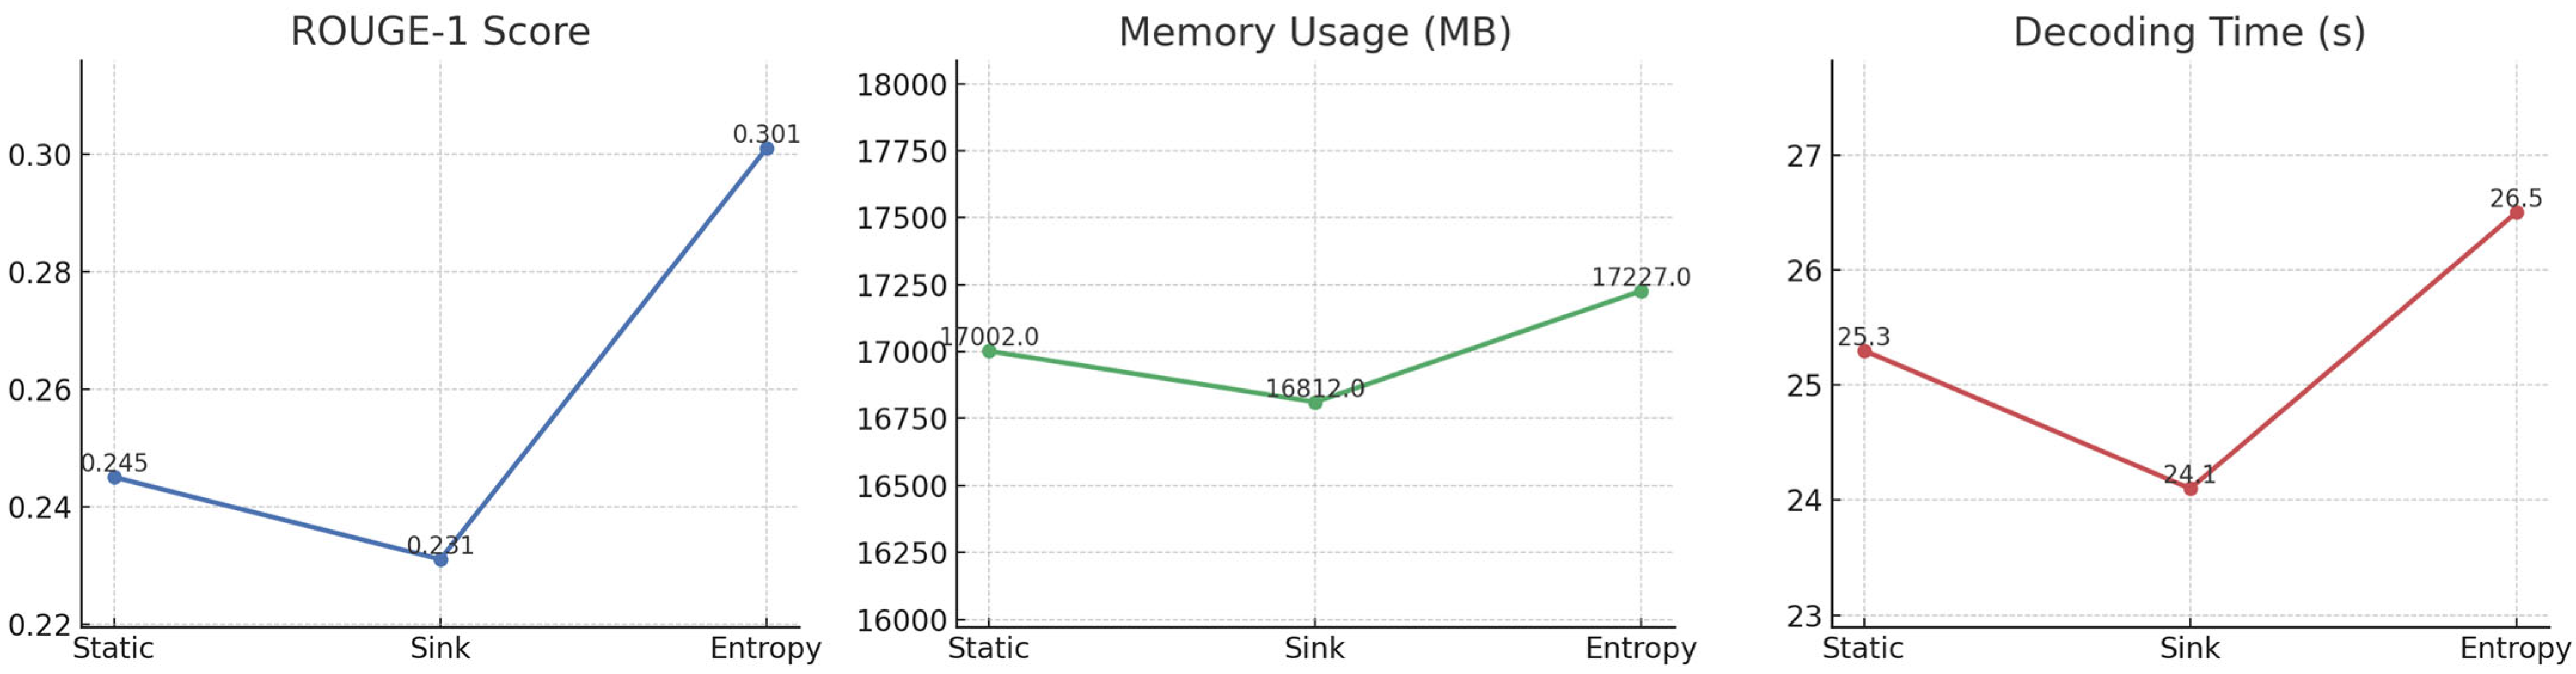
Entropy-Guided KV Caching for Efficient LLM Inference

Efficient KV Caching for LLM Inference | PDF | Cache (Computing ...

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
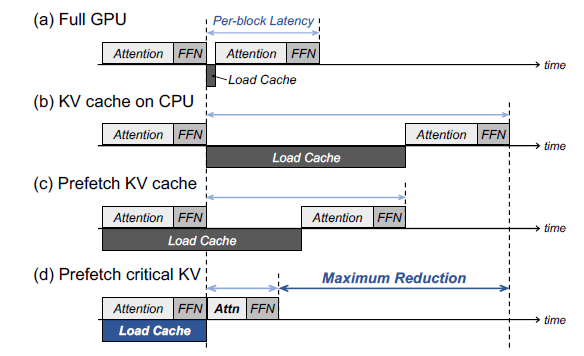
KVSharer: method for efficient LLM inference via dissimilar KV Cache ...

Kelle: Co-design KV Caching and eDRAM for Efficient LLM Serving in Edge ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
Advertisement Space (300x250)

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
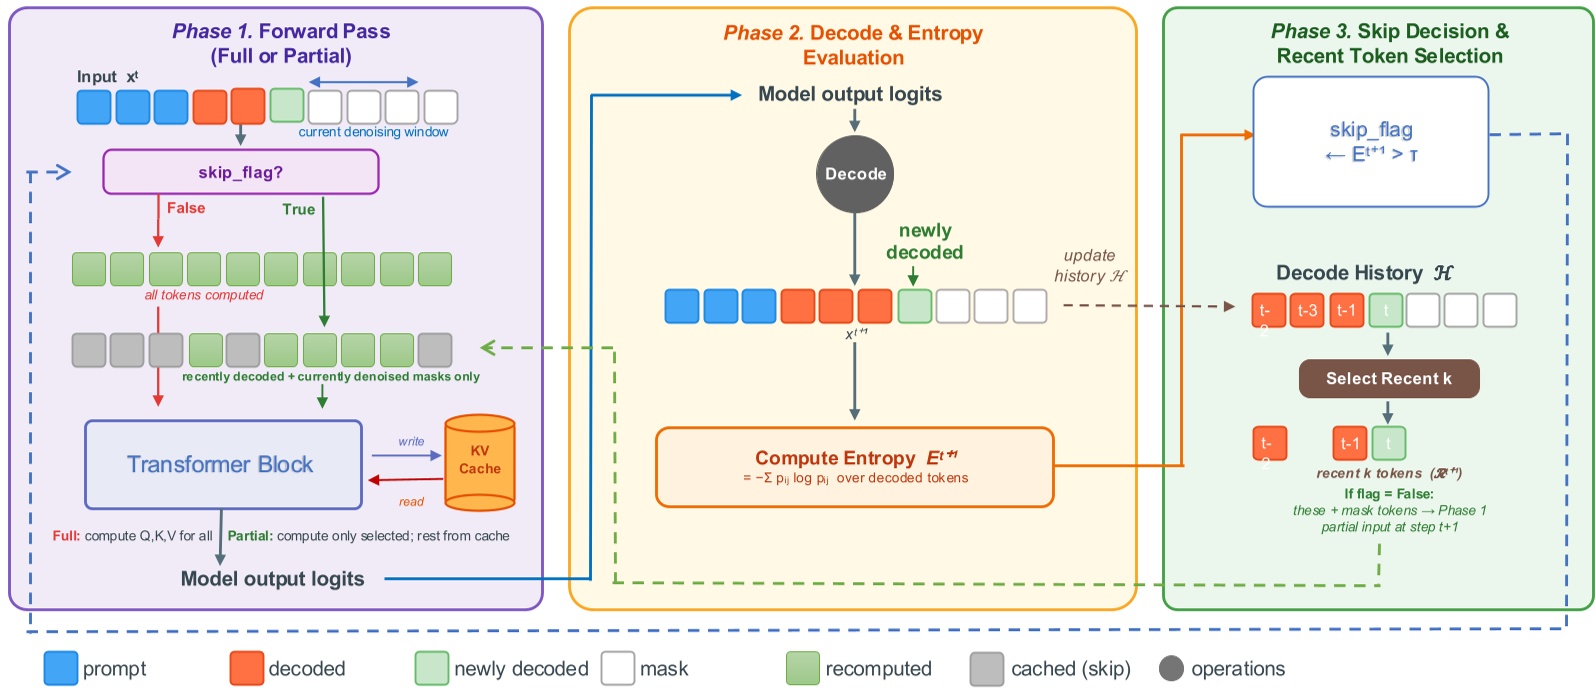
EntropyCache: Decoded Token Entropy Guided KV Caching for Diffusion ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
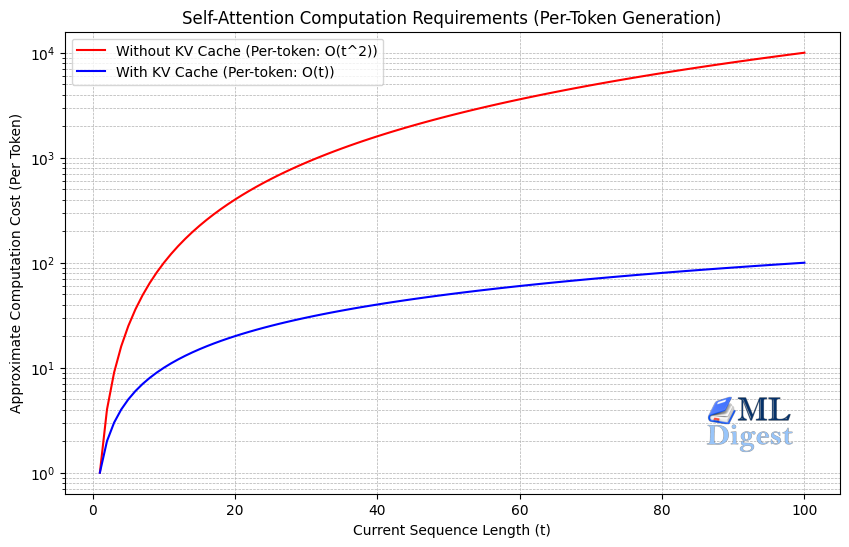
KV Caching Made Simple: The Key To Efficient LLM Inference - ML Digest

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
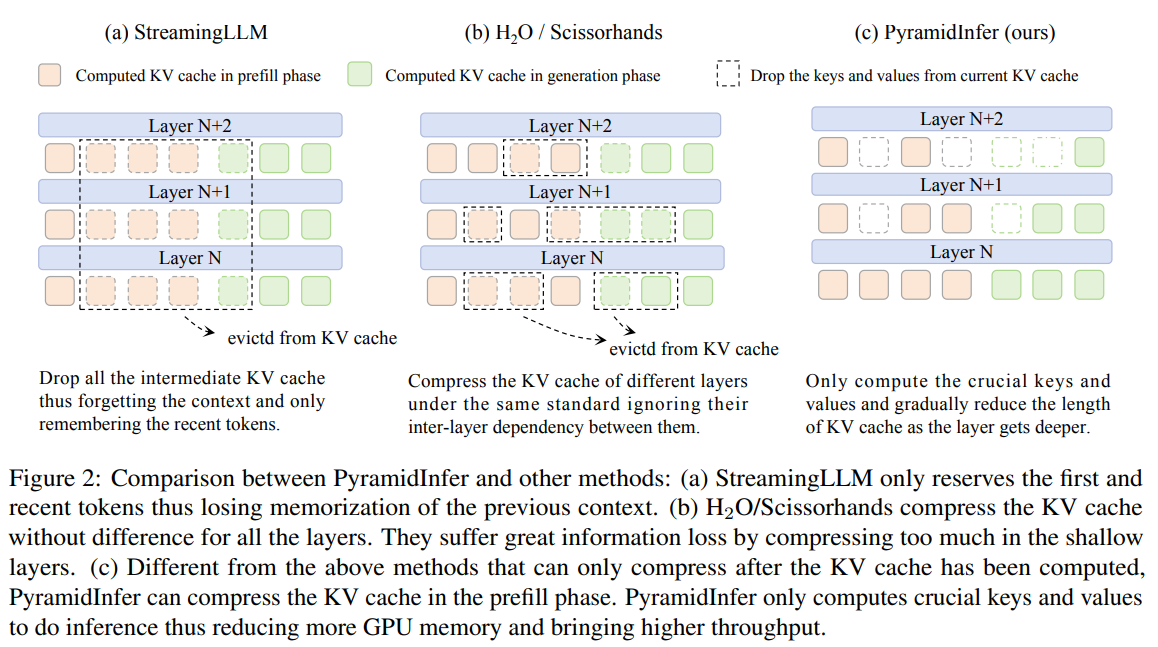
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
Advertisement Space (336x280)

KV Cache Transform Coding for Compact Storage in LLM Inference

Layer-Condensed KV Cache for Efficient Inference of Large Language ...
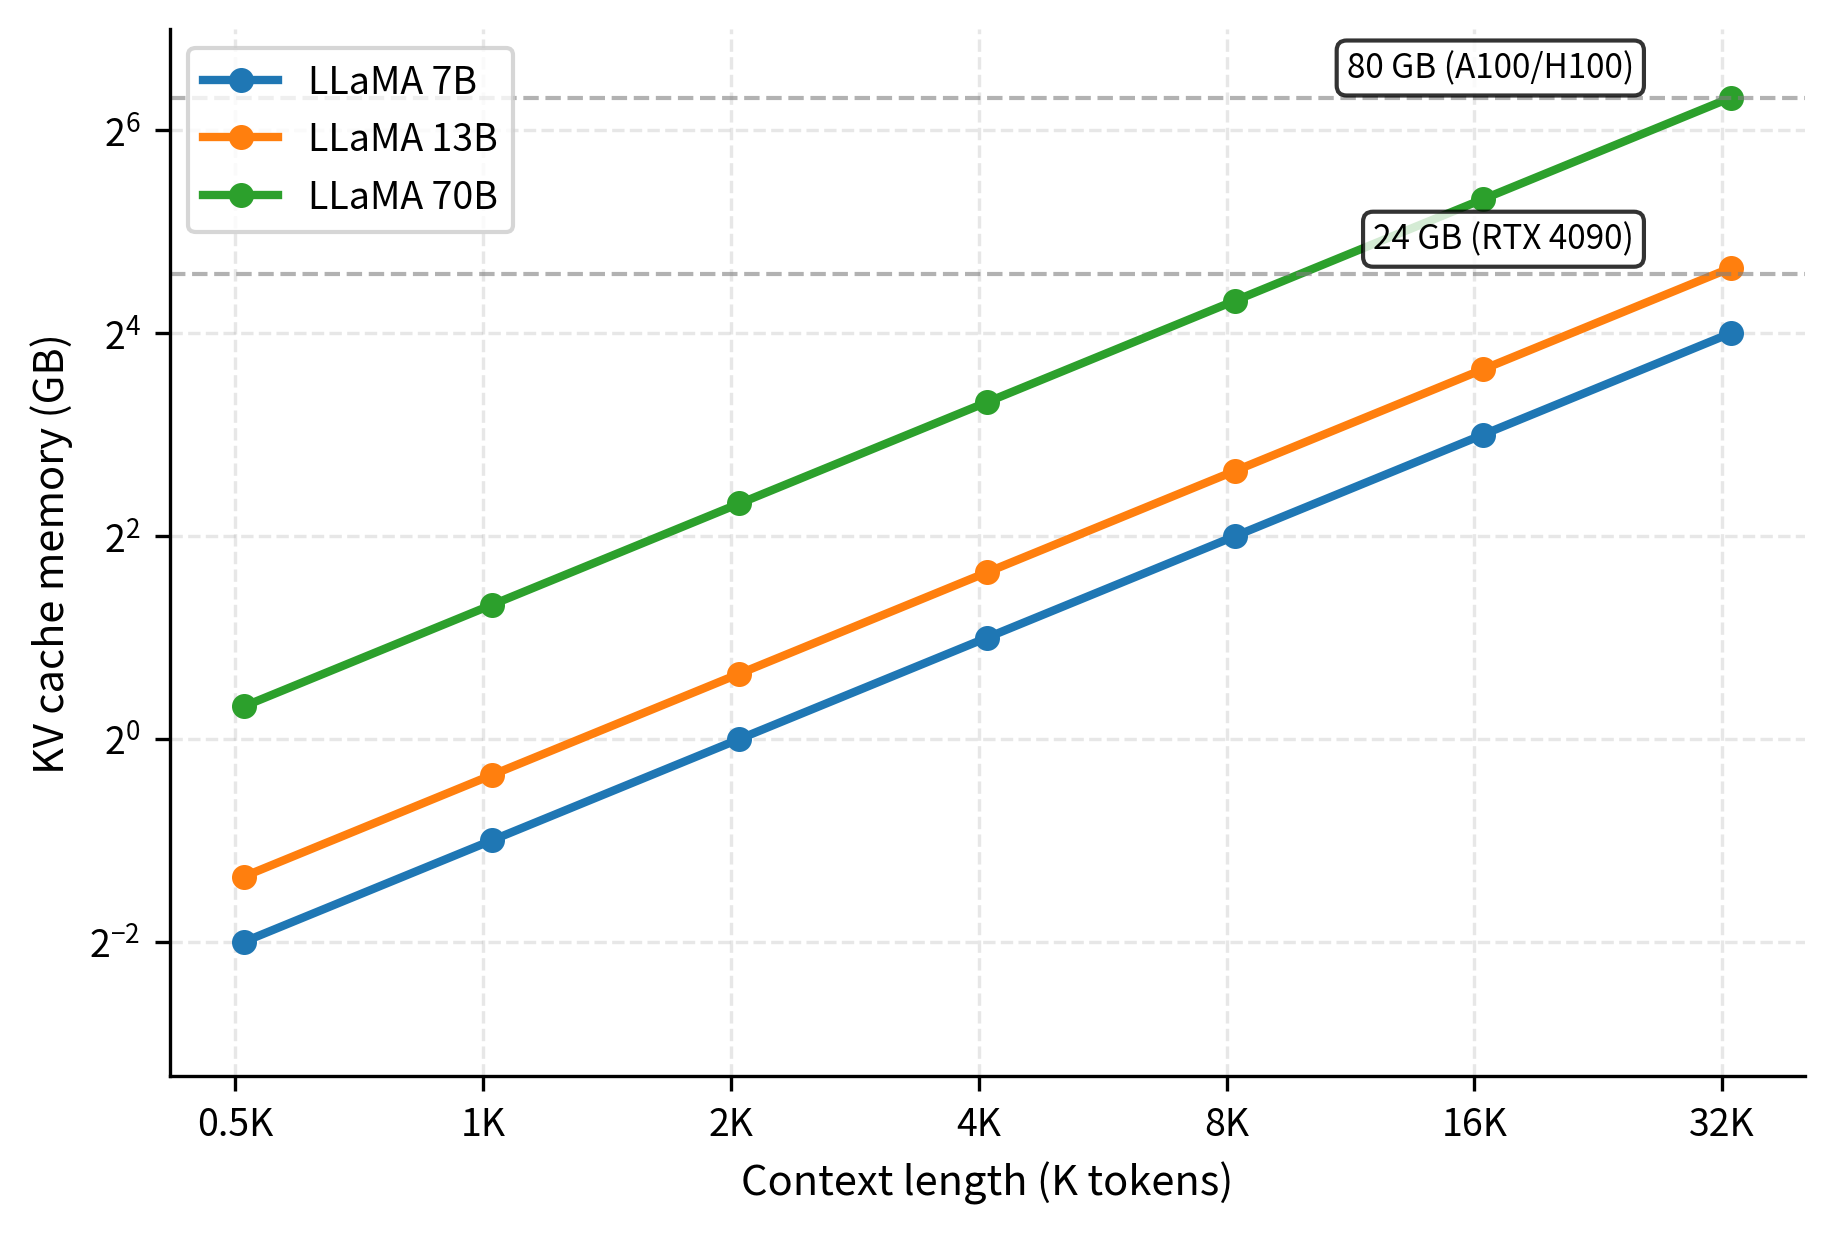
KV Cache Explained: Efficient Attention for LLM Generation ...

SparKV: Overhead-Aware KV Cache Loading for Efficient On-Device LLM ...
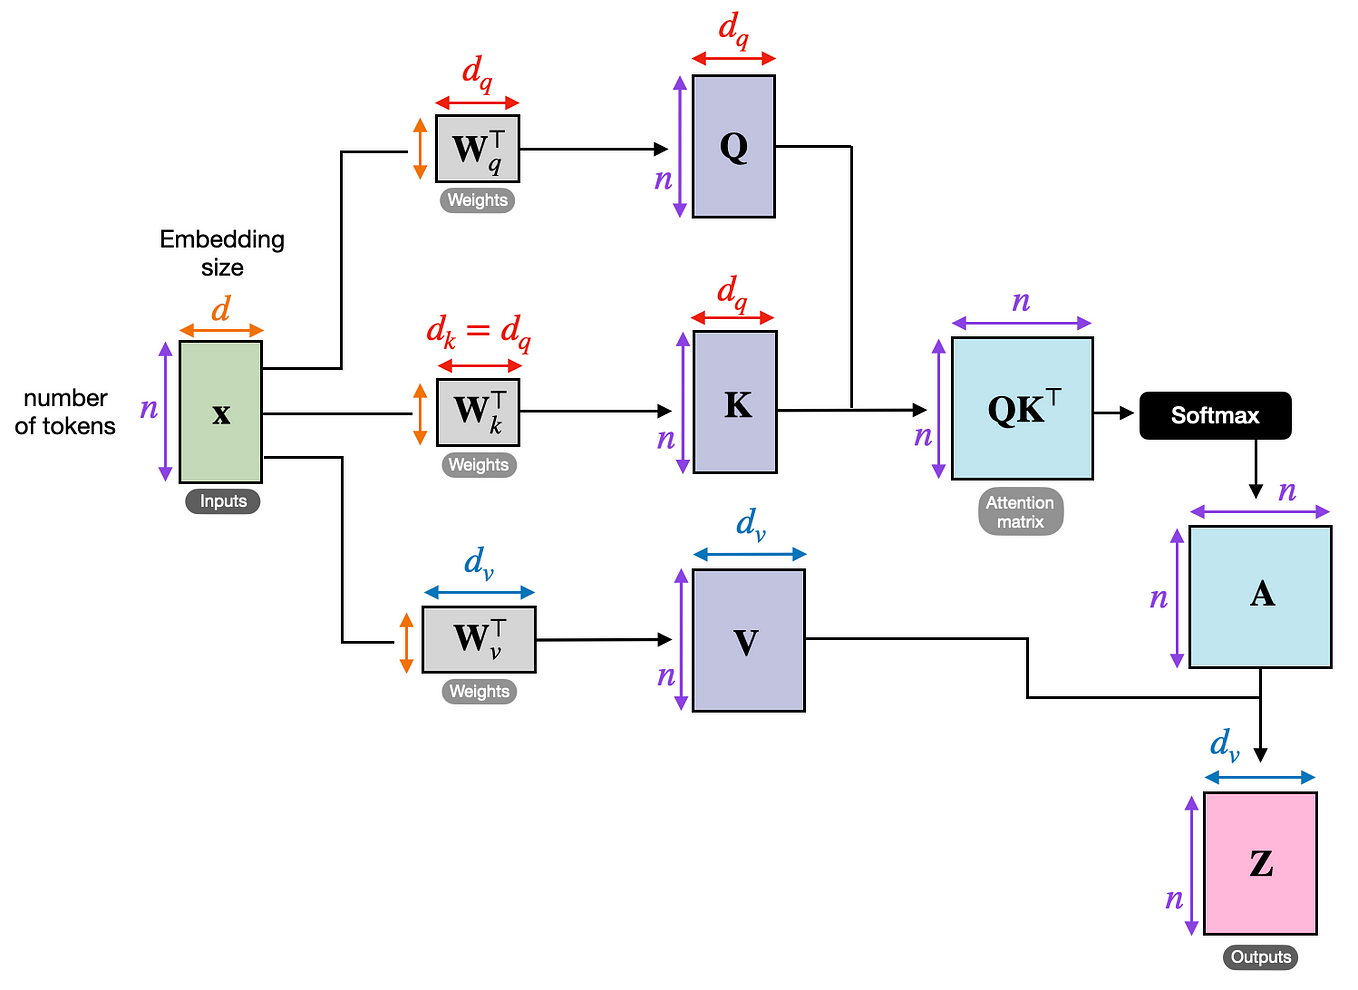
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

LLM Inference Optimization: KV Caching Bottleneck | Sanyam Sharma ...

(PDF) Efficient Long-Context LLM Inference via KV Cache Clustering
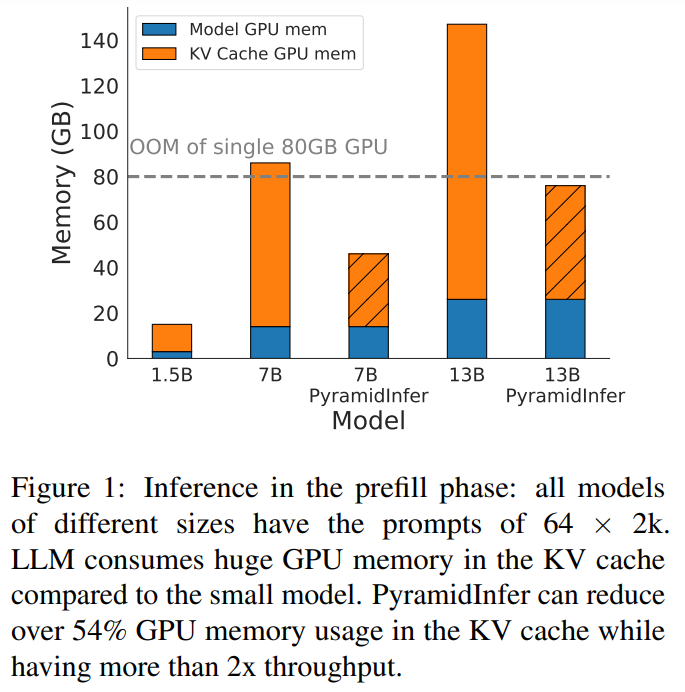
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
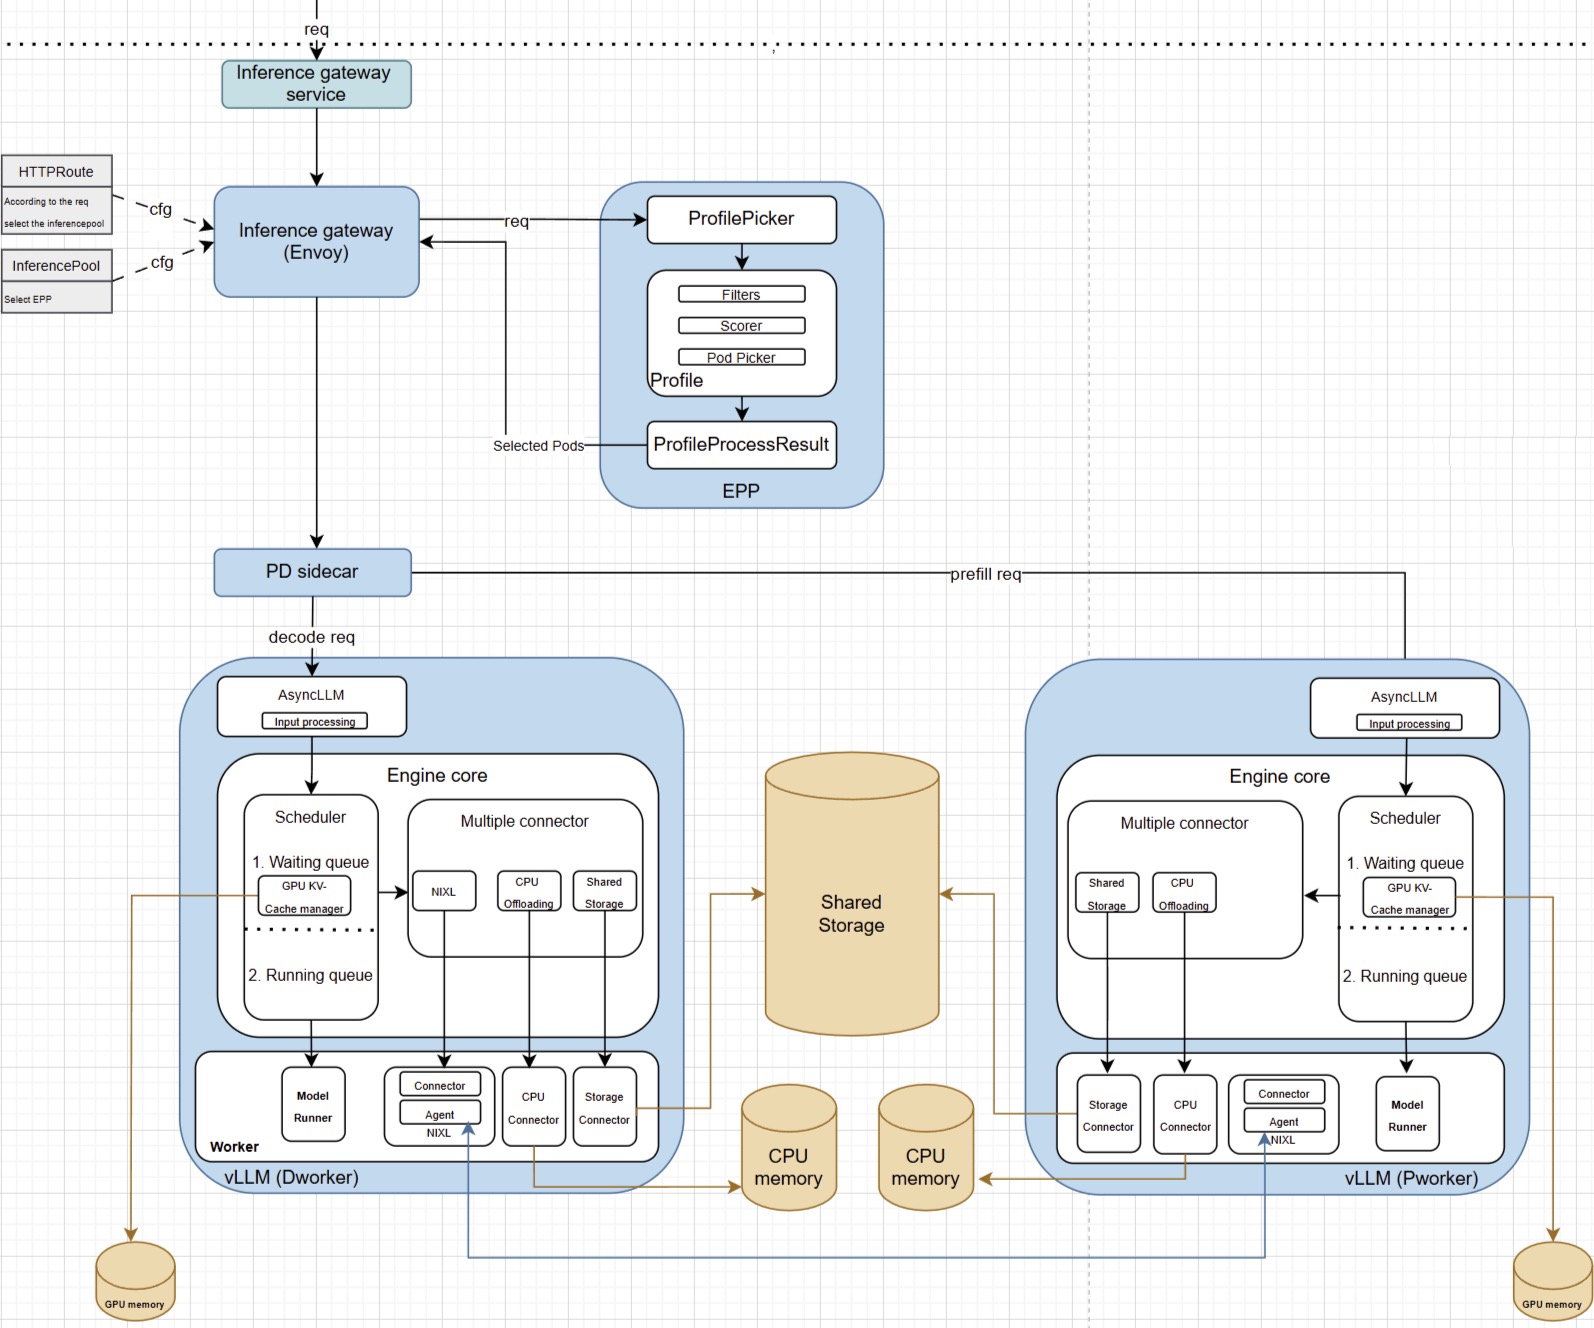
Master KV cache aware routing with llm-d for efficient AI inference ...

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...
Advertisement Space (336x280)

Paper page - Layer-Condensed KV Cache for Efficient Inference of Large ...

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
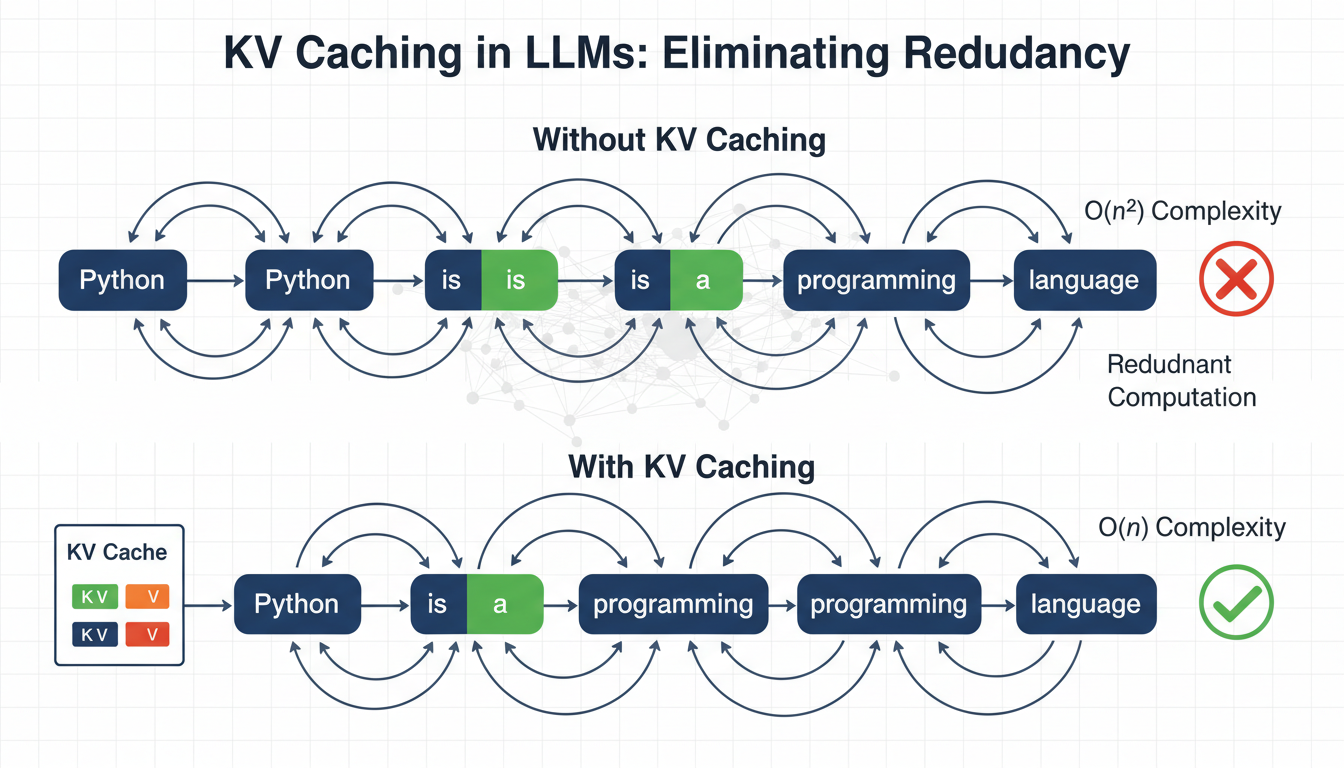
KV Caching in LLMs: A Guide for Developers - MachineLearningMastery.com
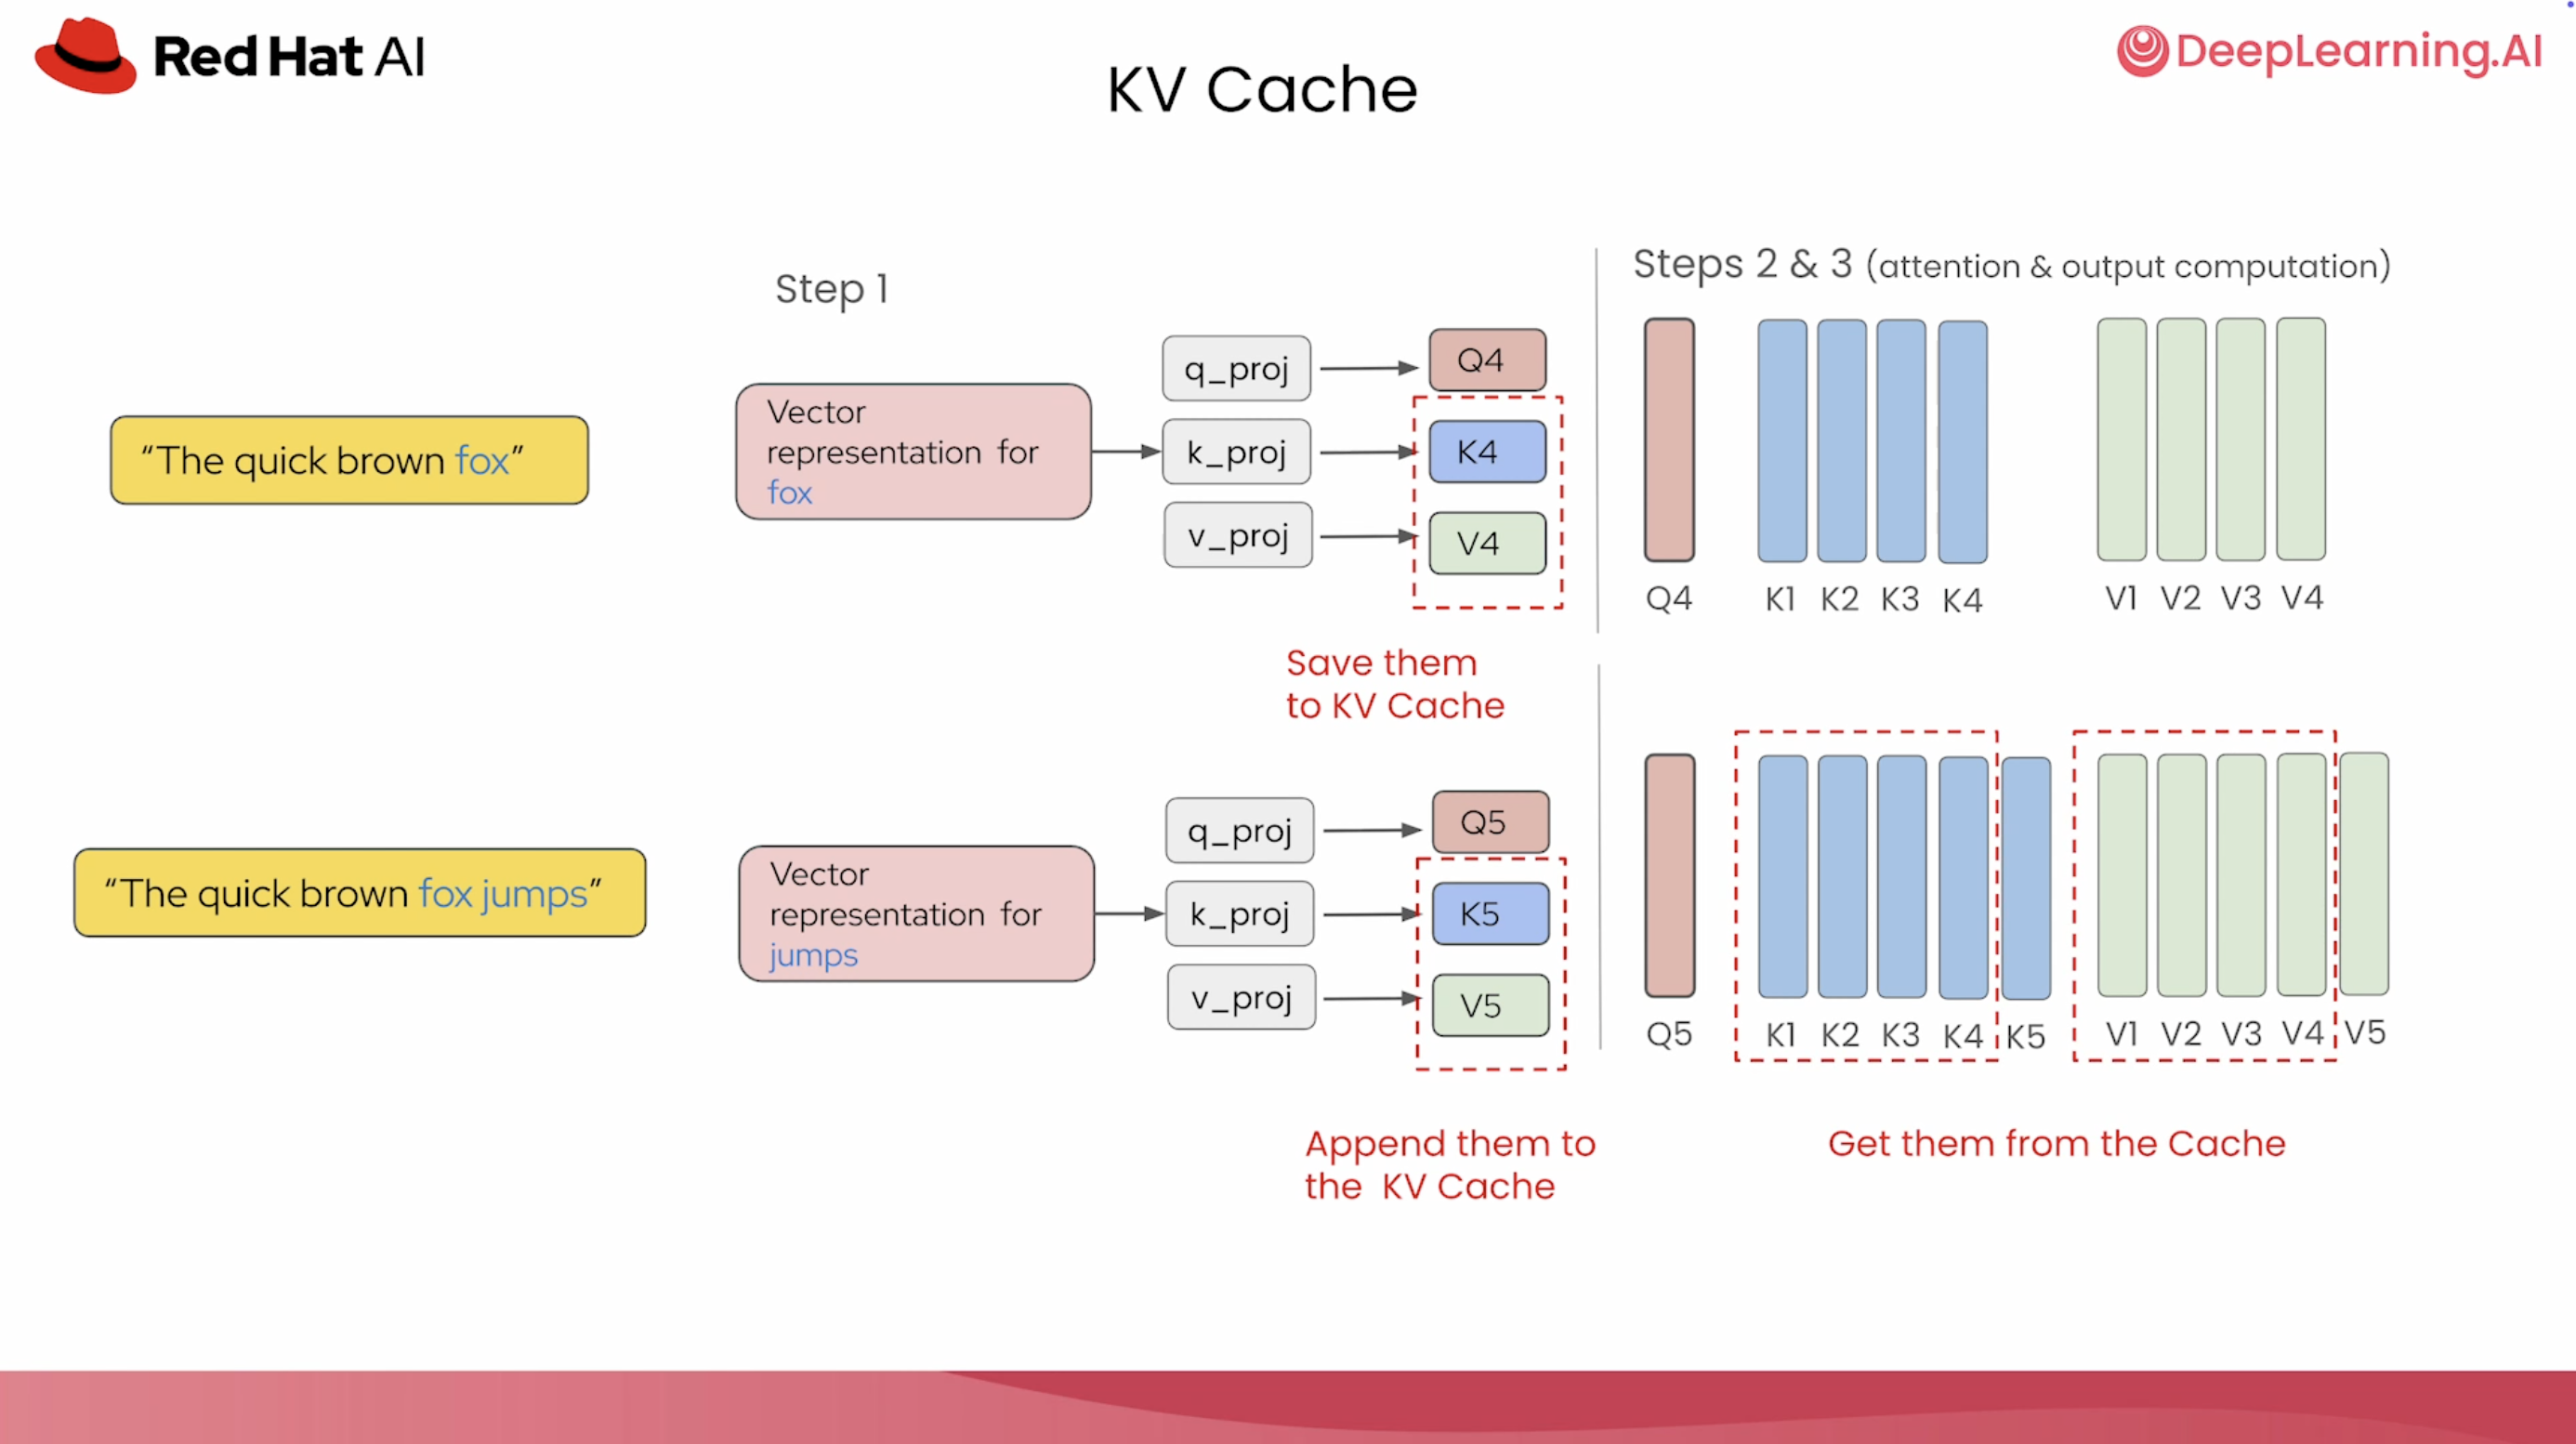
Fast & Efficient LLM Inference with vLLM: A New Course with ...
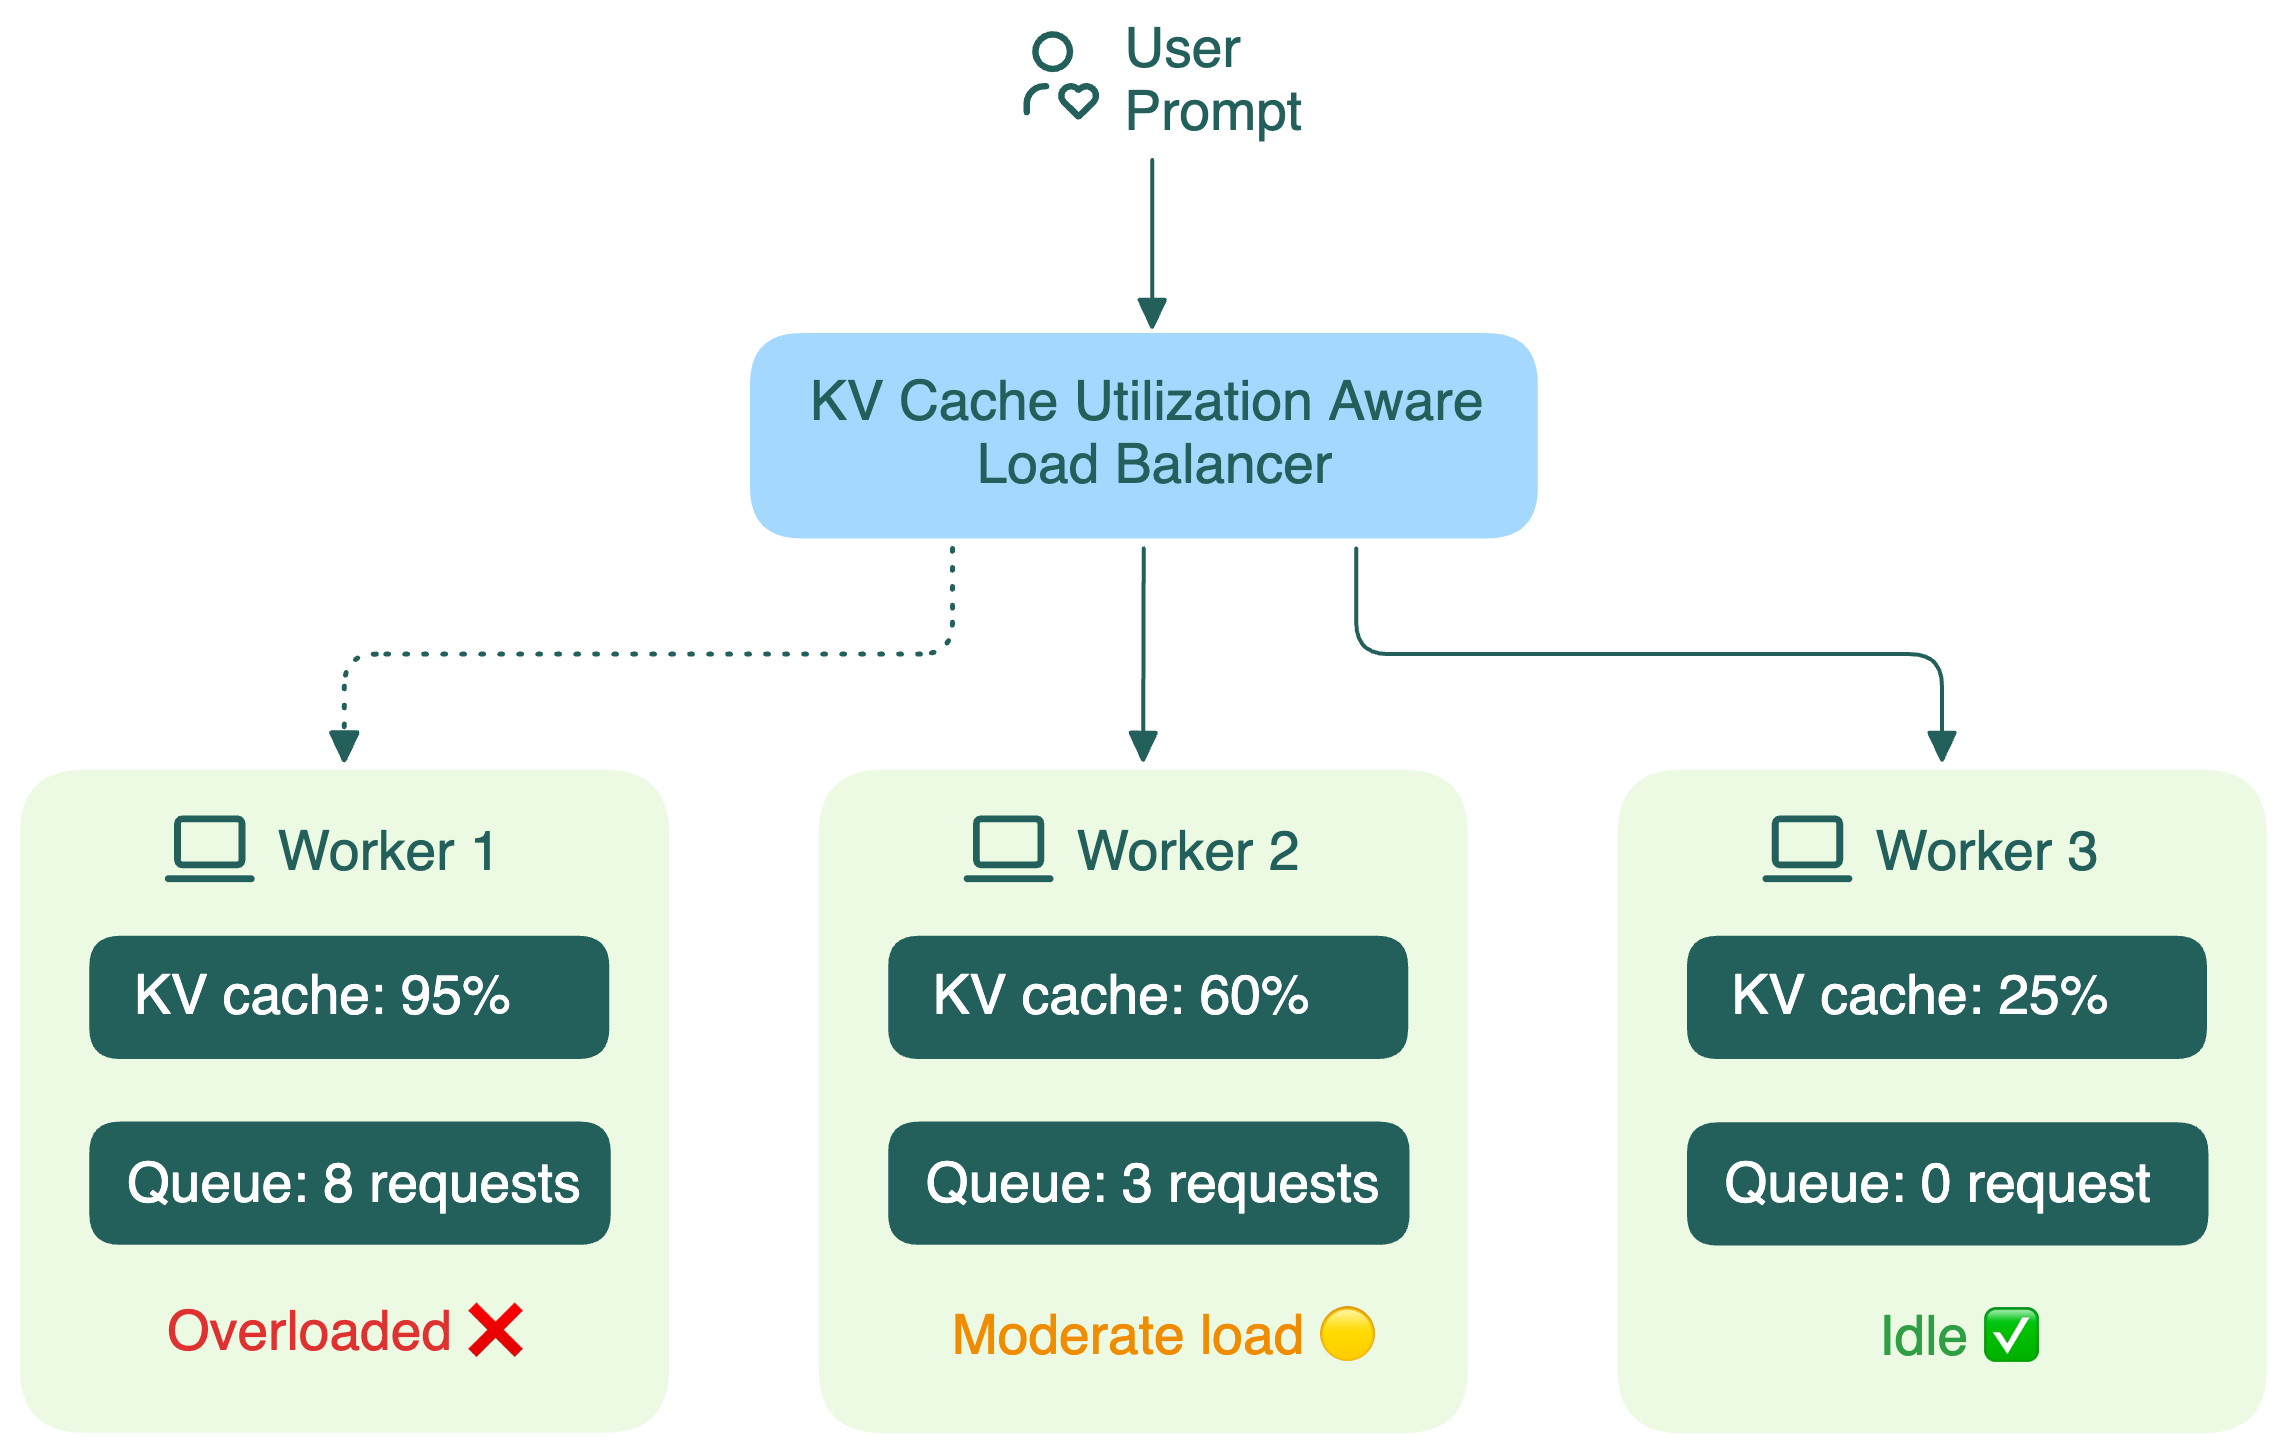
KV cache utilization-aware load balancing | LLM Inference Handbook

KV Caching in LLMs: A Guide for Developers - MachineLearningMastery.com