
Kv Caching Made Simple The Key To Efficient Llm Inference Ml Digest

KV Caching Made Simple: The Key To Efficient LLM Inference - ML Digest
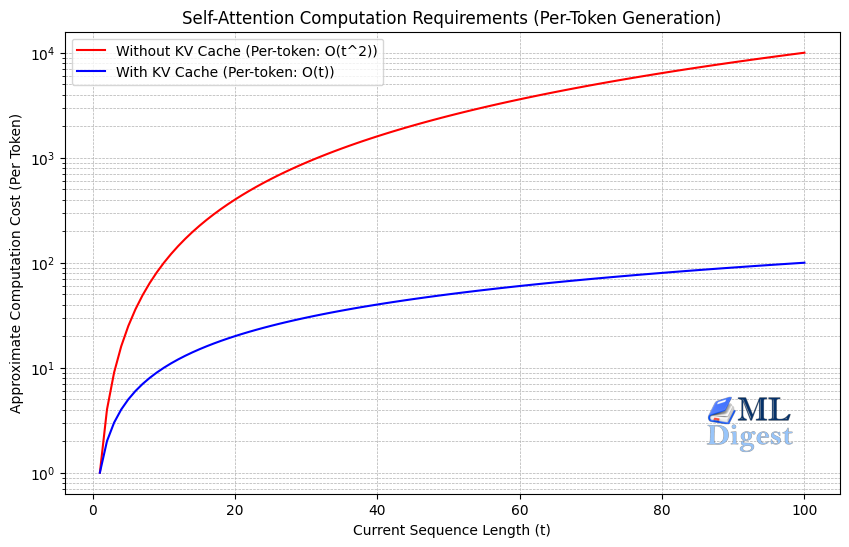
KV Caching Made Simple: The Key To Efficient LLM Inference - ML Digest
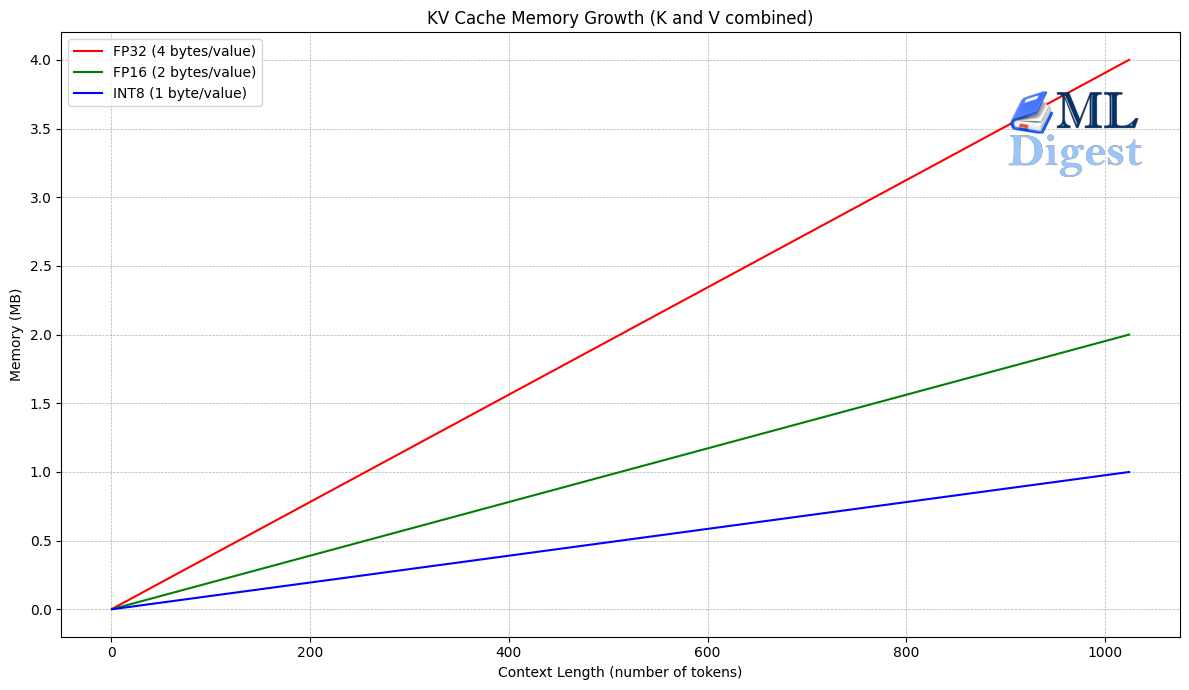
KV Caching Made Simple: The Key To Efficient LLM Inference - ML Digest
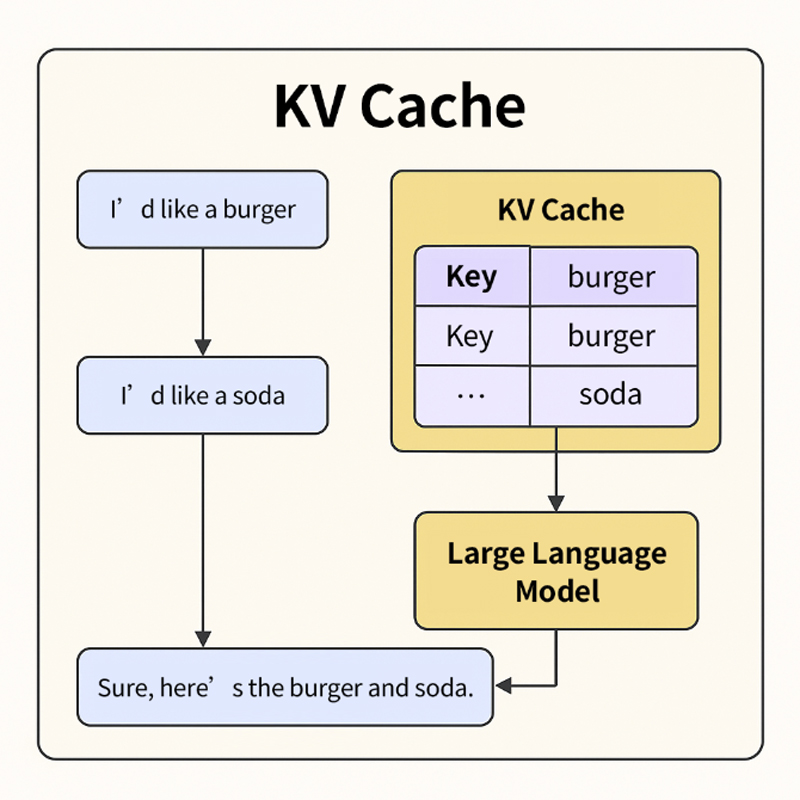
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

Entropy-Guided KV Caching for Efficient LLM Inference

Entropy-Guided KV Caching for Efficient LLM Inference

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...

Kelle: Co-design KV Caching and eDRAM for Efficient LLM Serving in Edge ...

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
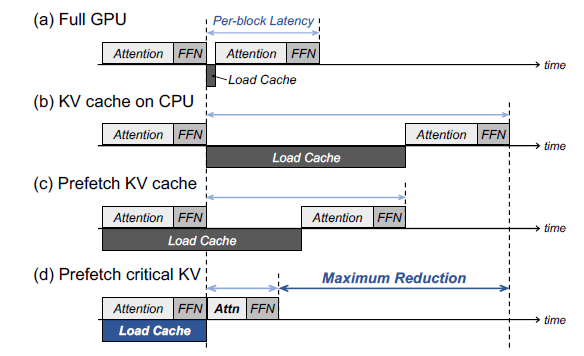
KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
Advertisement Space (300x250)
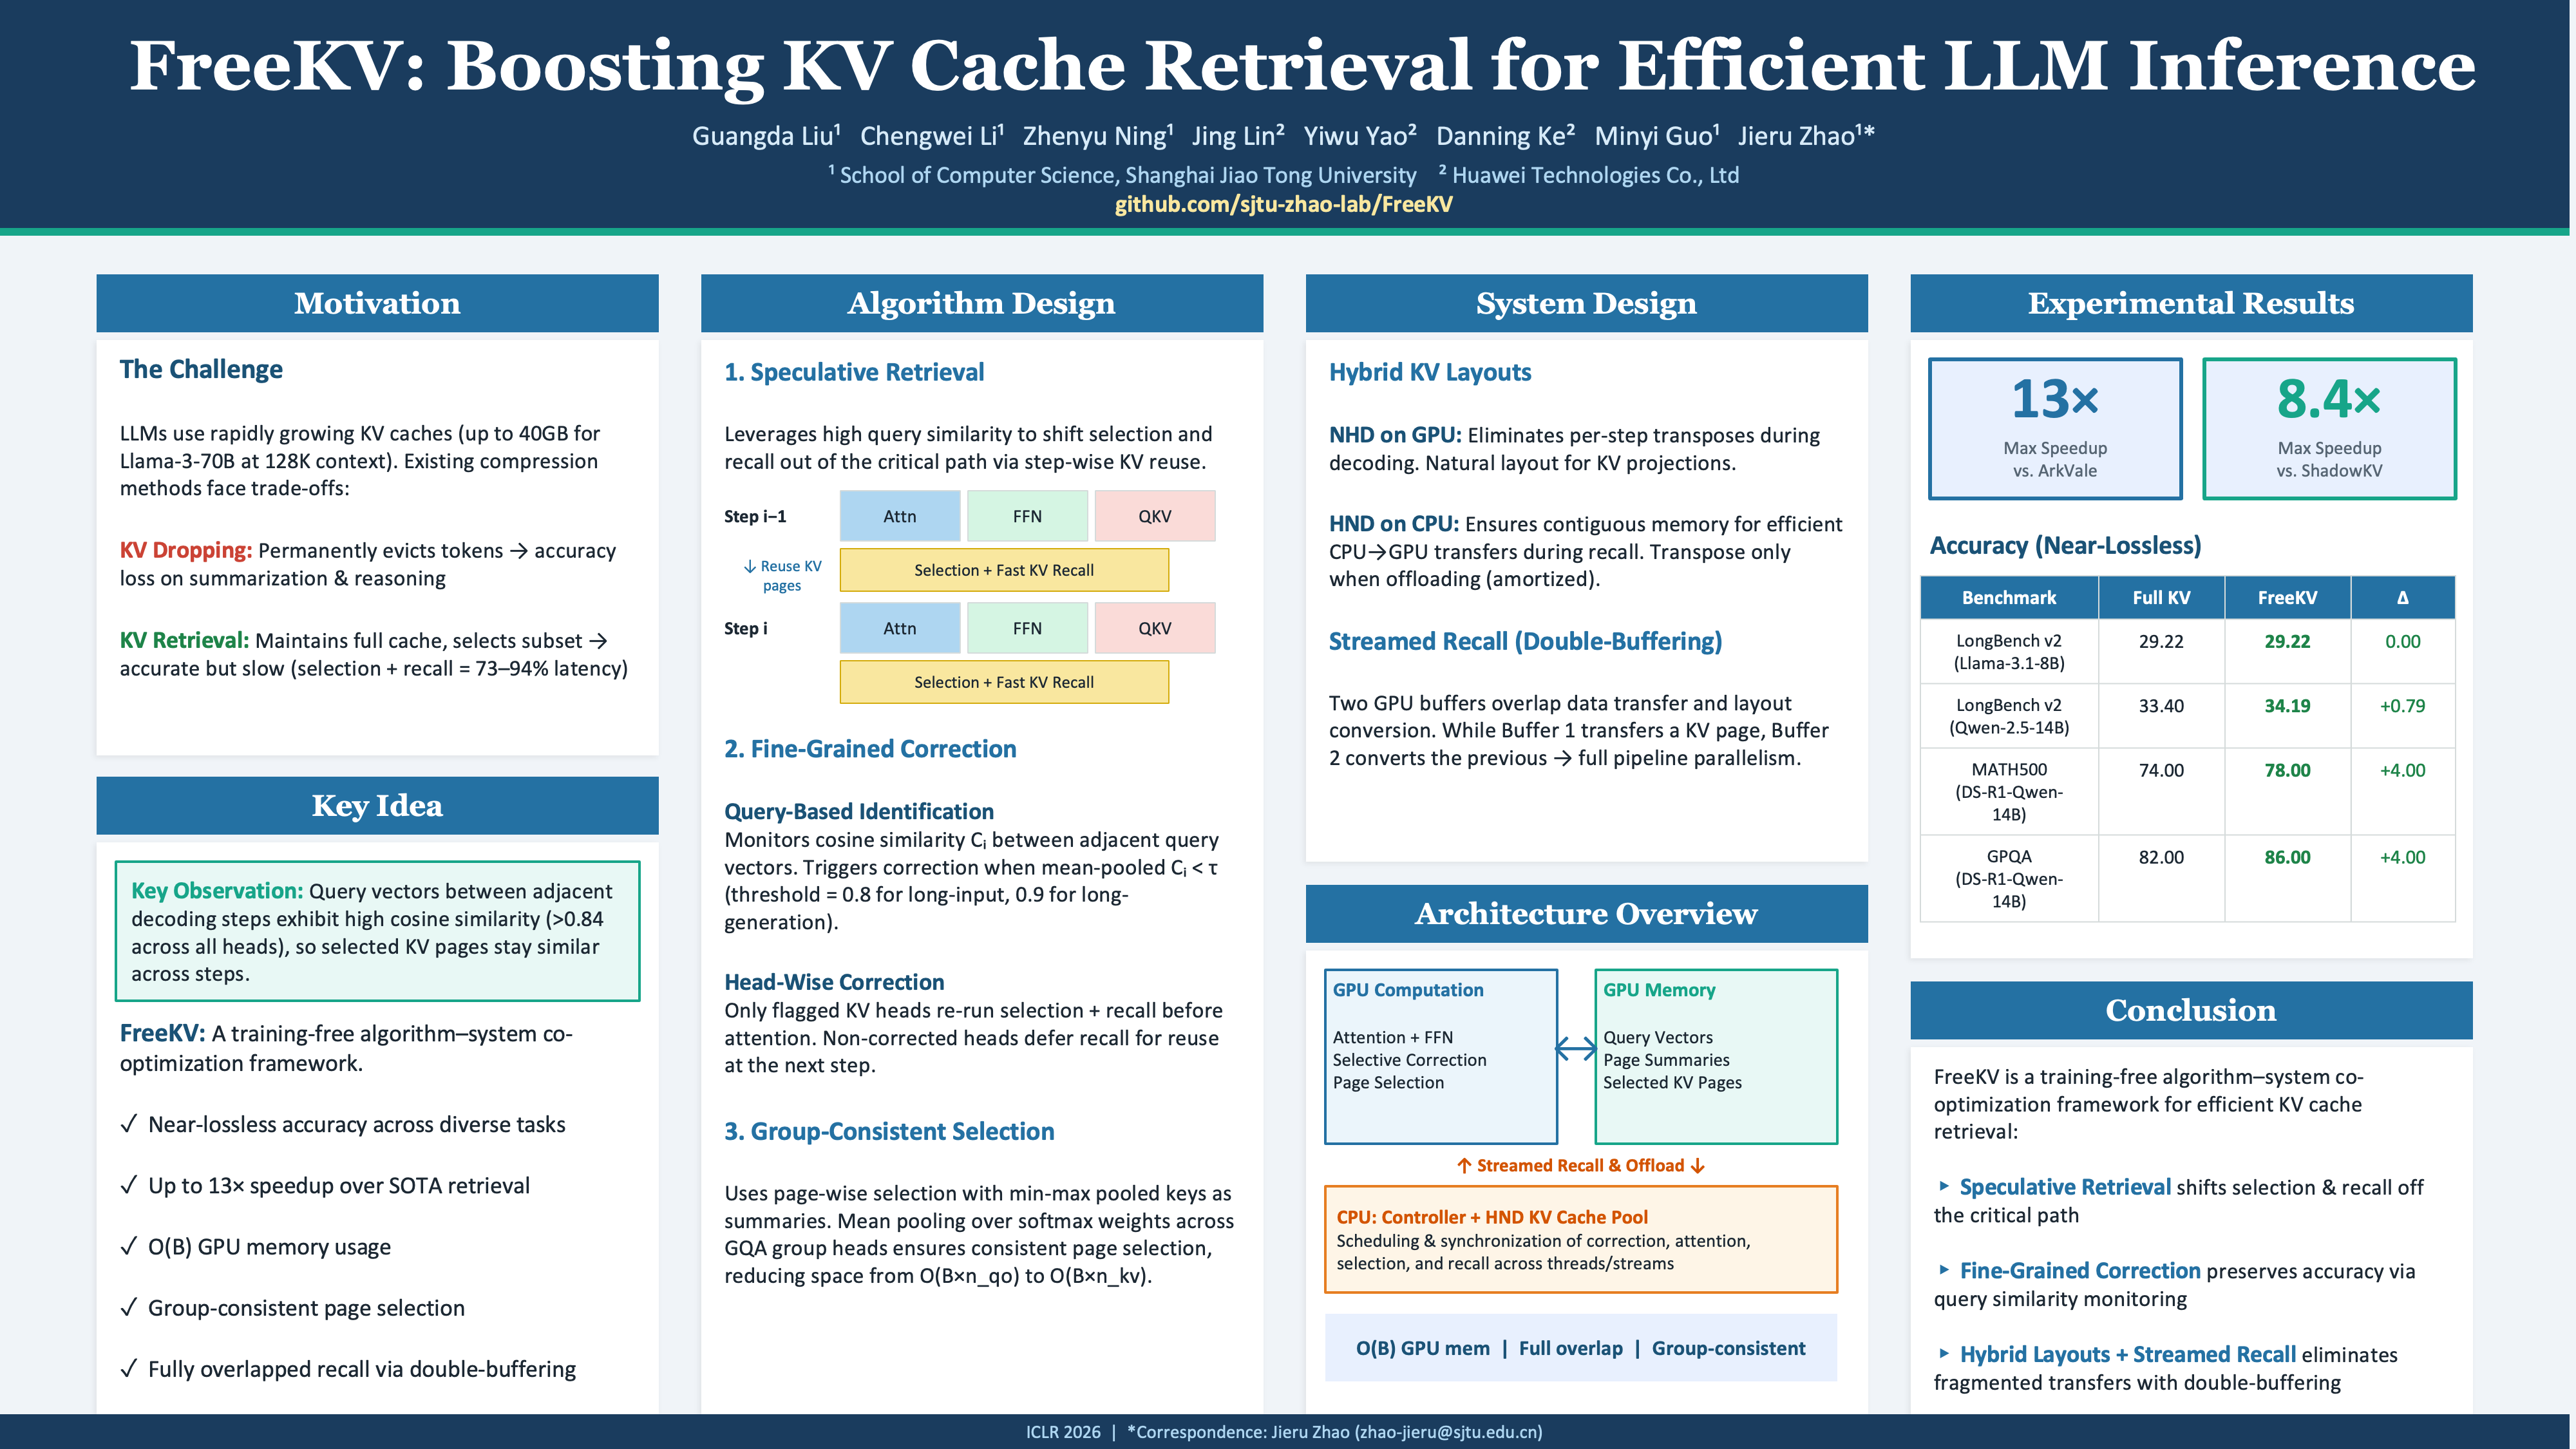
ICLR Poster FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference

Pushing the Limits of LLM Inference via 2-Bit Layer-Discriminative KV ...
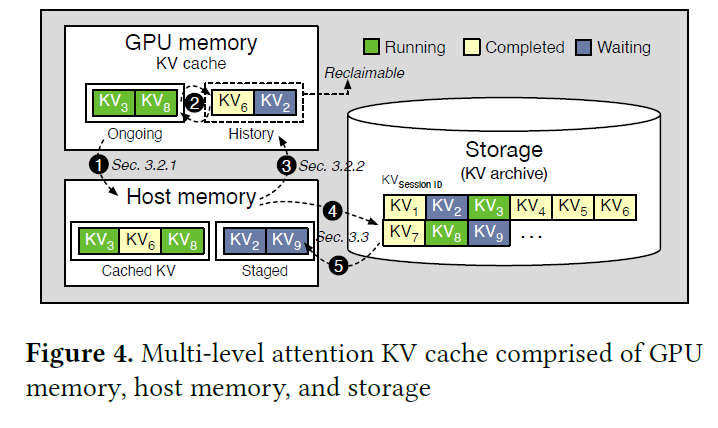
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference

(PDF) Efficient Long-Context LLM Inference via KV Cache Clustering

Efficient LLM Inference (vLLM KV Cache, Flash Decoding & Lookahead ...
Advertisement Space (336x280)

(PDF) Efficient LLM Inference with I/O-Aware Partial KV Cache Recomputation

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...
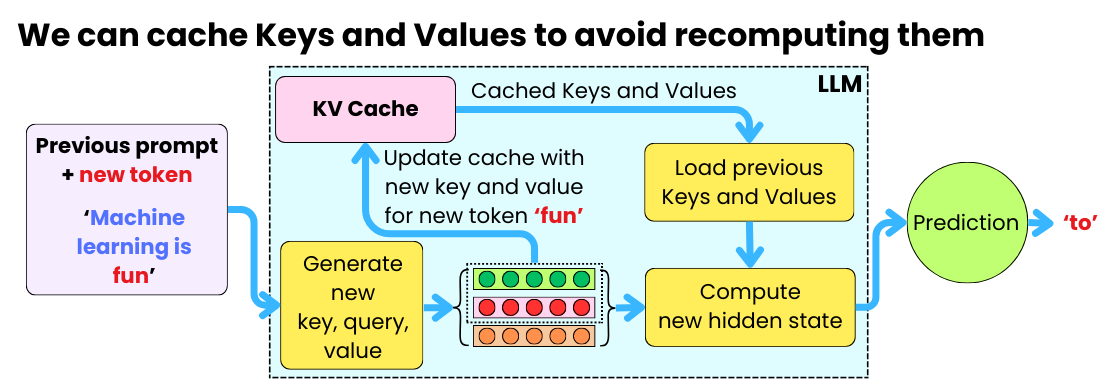
How to Scale LLM Inference - by Damien Benveniste
LLM Inference Guide: 12 Proven Ways To Speed Up AI Models

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
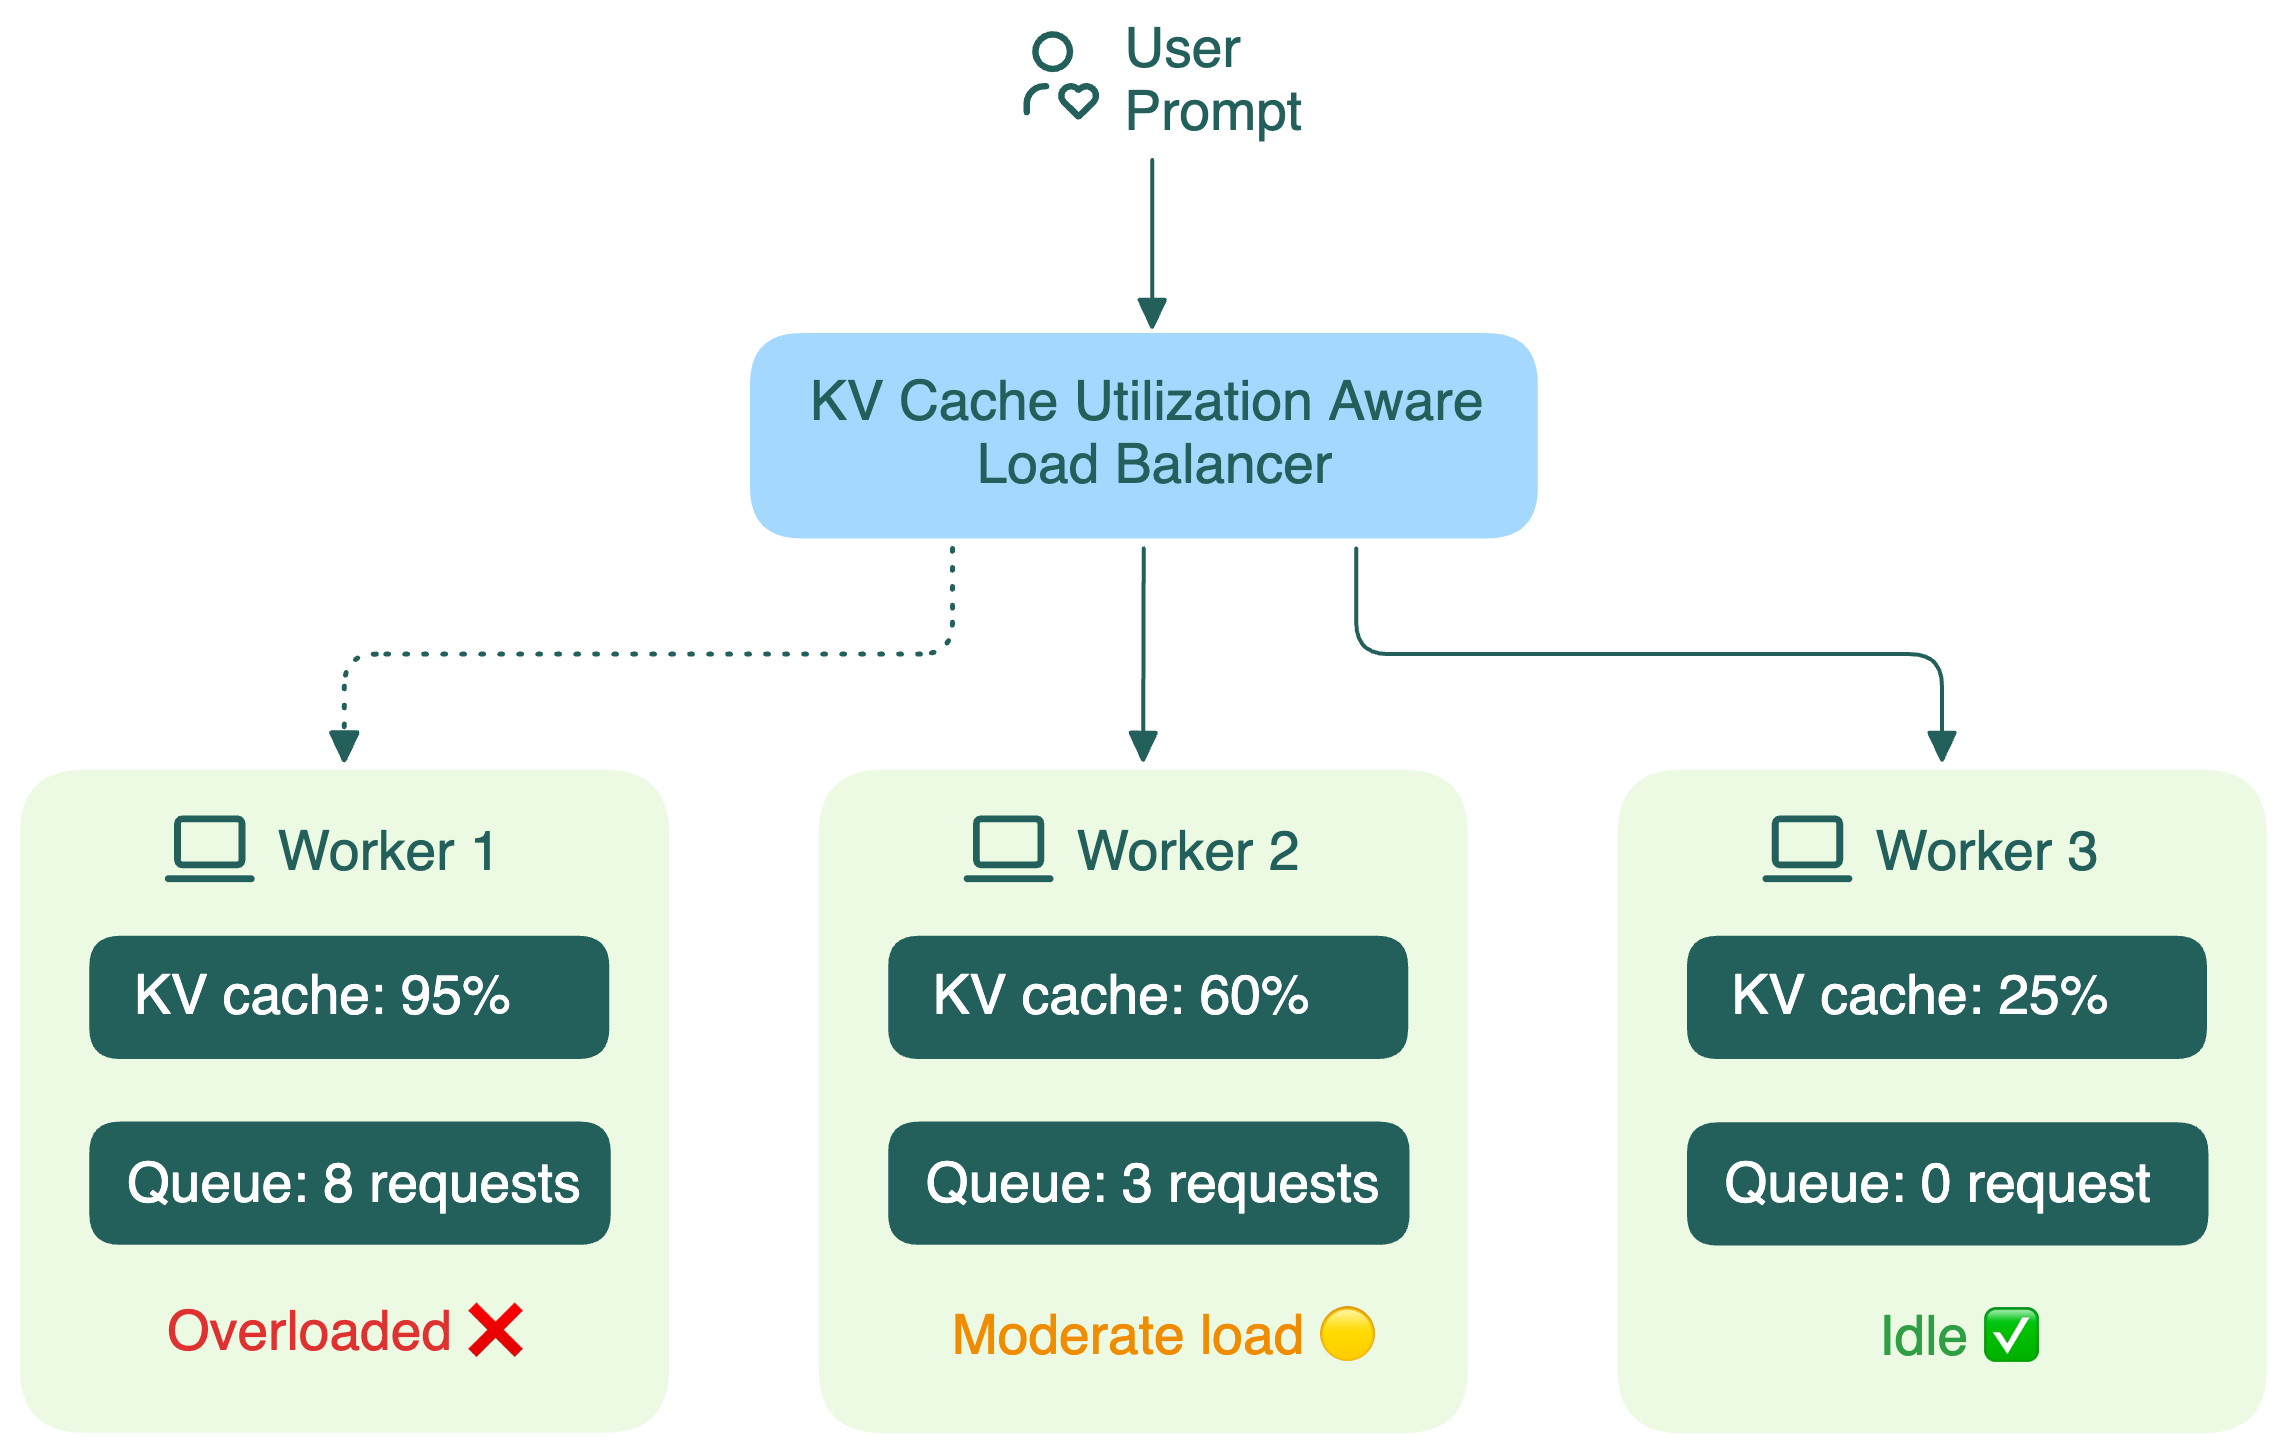
KV cache utilization-aware load balancing | LLM Inference Handbook

Figure 1 from Efficient LLM Inference with Kcache | Semantic Scholar

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...
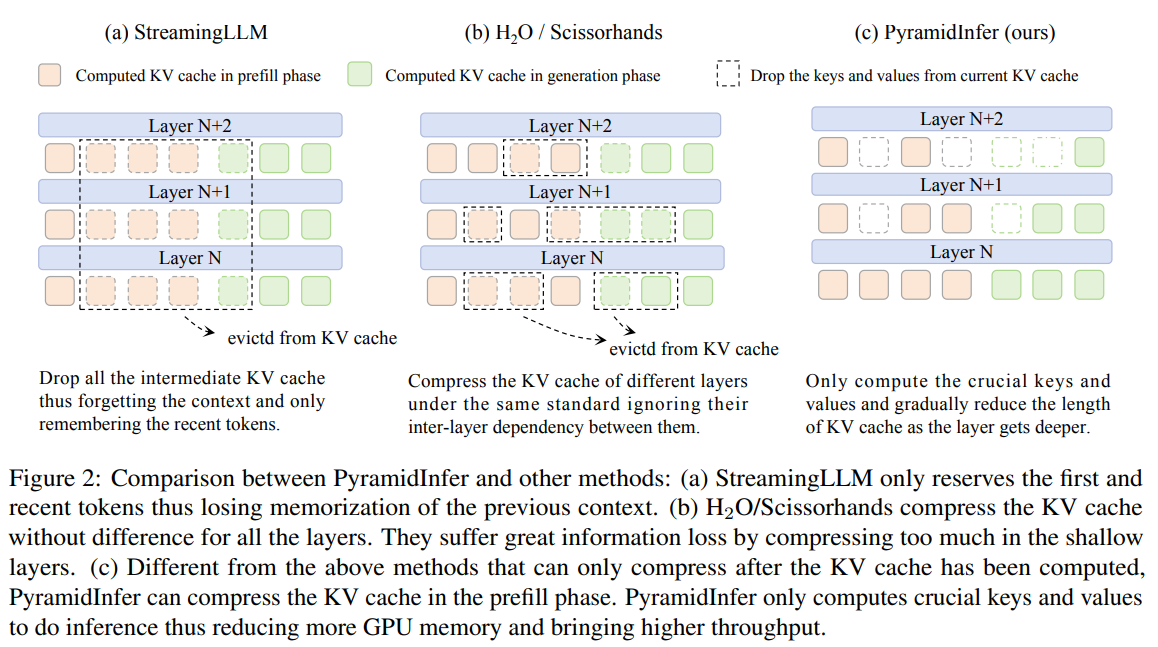
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
What is KV Cache? | LLM Inference Optimization | Inference Systems
Advertisement Space (336x280)
KV Cache Optimization Strategies for Scalable and Efficient LLM ...
KV Cache State: Definition & Role in LLM Inference | Inference Systems

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

LLM inference optimization: Architecture, KV cache and Flash attention ...
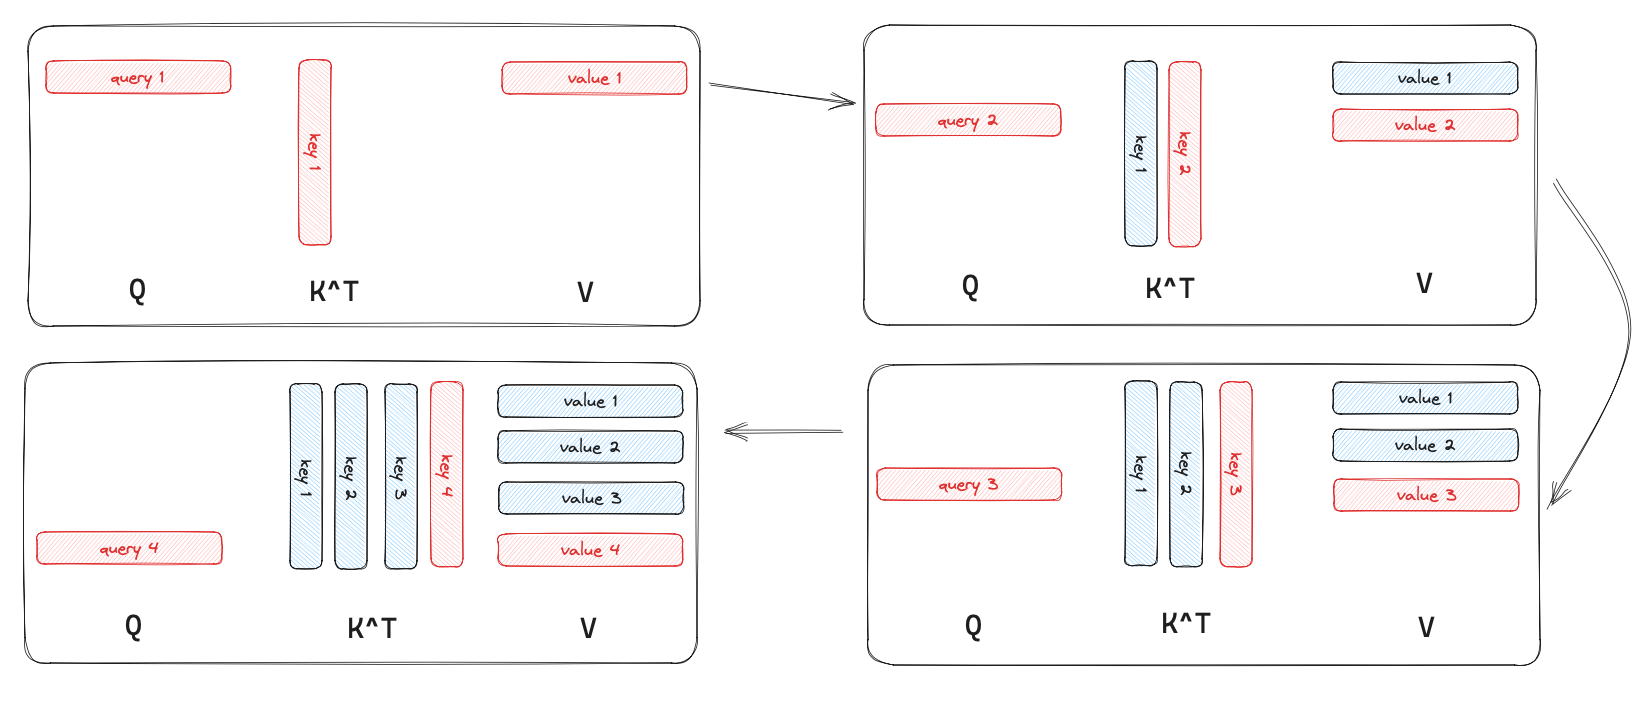
LLM inference optimization (1): KV Cache - MartinLwx's Blog

Paper page - Efficient LLM Inference with Kcache