
Faster Llms With Speculative Decoding And Aws Inferentia2 Artificial

Faster LLMs with speculative decoding and AWS Inferentia2 | Artificial ...

Faster LLMs with speculative decoding and AWS Inferentia2 | Artificial ...

Faster LLMs with speculative decoding and AWS Inferentia2

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...
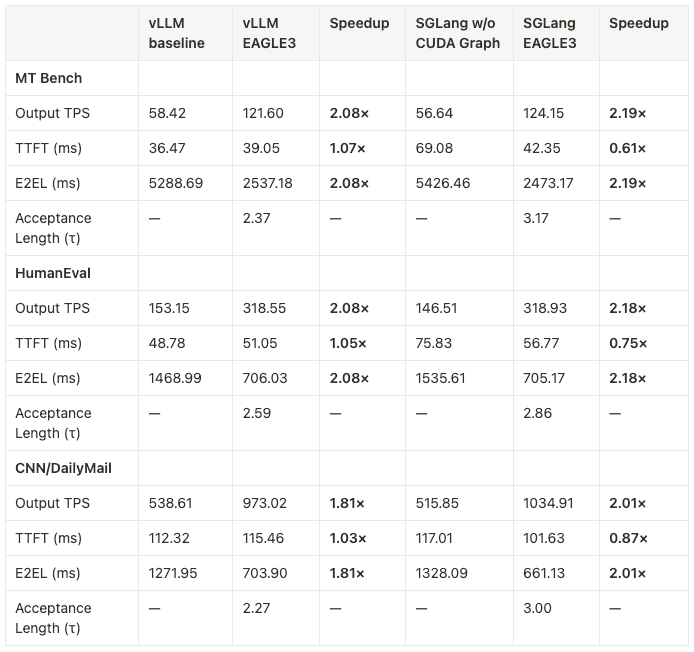
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Dynamic Depth Decoding: Faster Speculative Decoding for LLMs | AI ...
Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...

Speculative Decoding via Early-exiting for Faster LLM Inference with ...
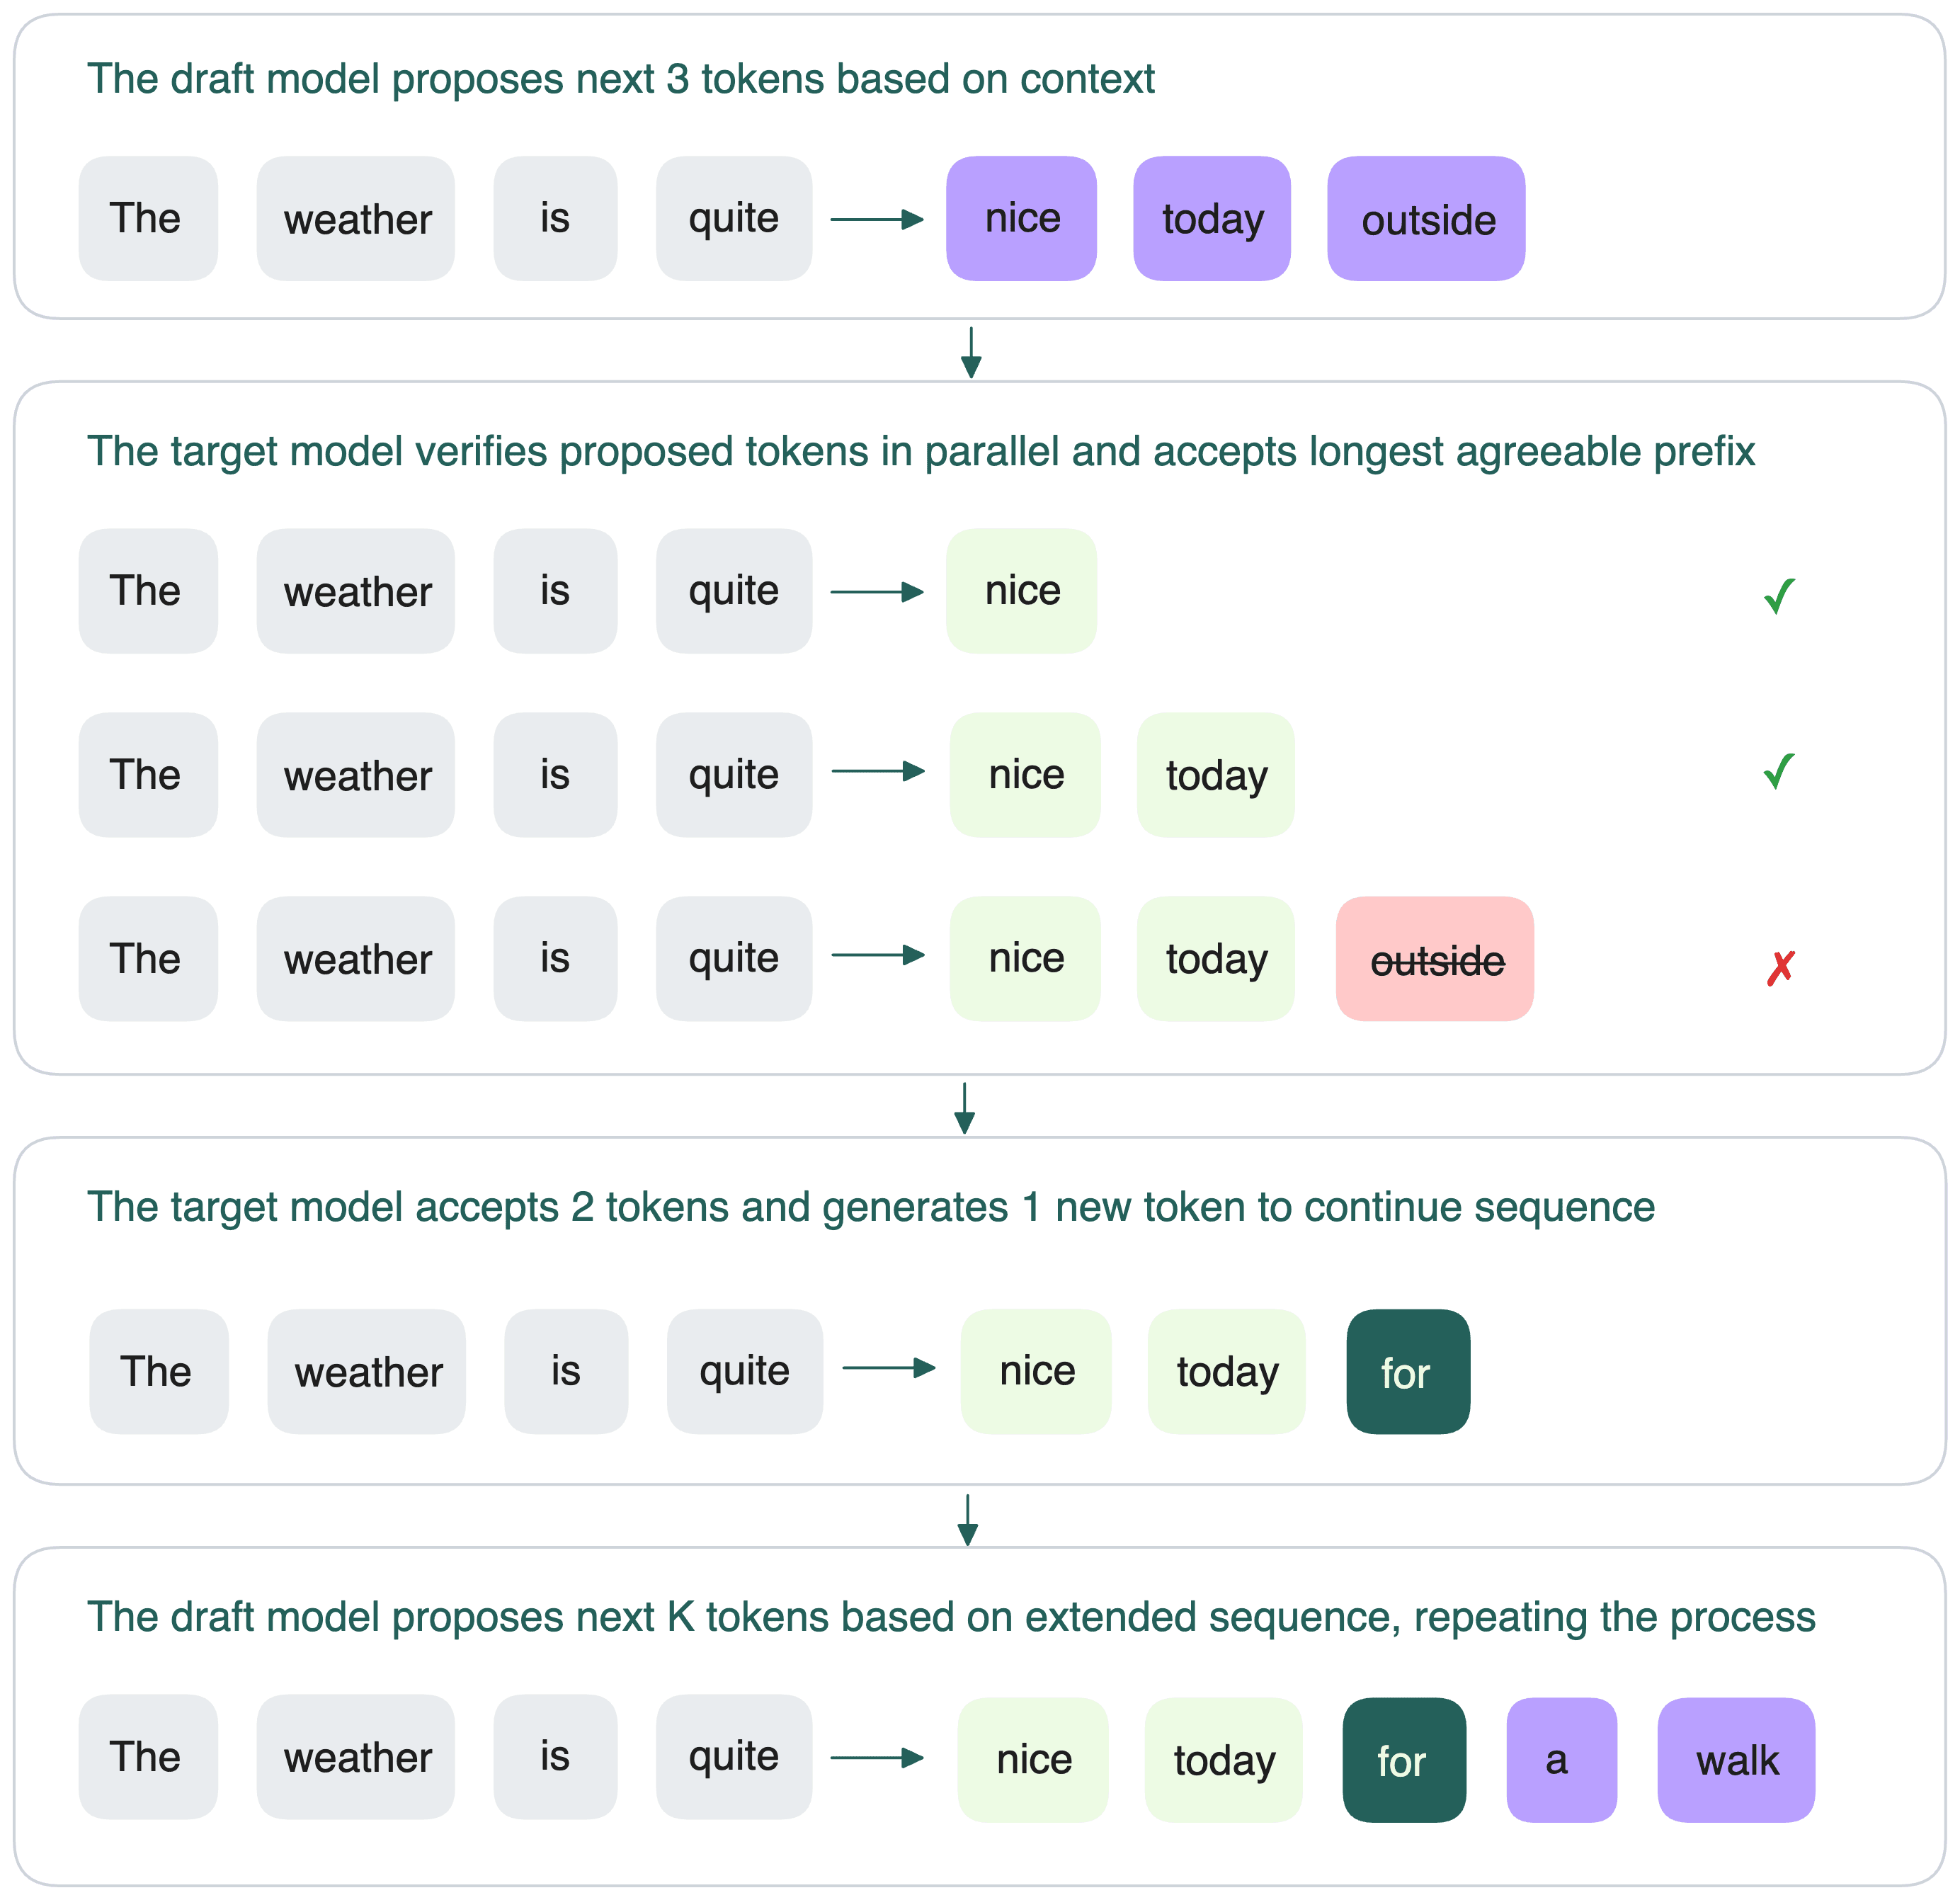
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
Advertisement Space (300x250)
How Speculative Decoding Makes LLMs 2.5x Faster (The Secret to Faster ...
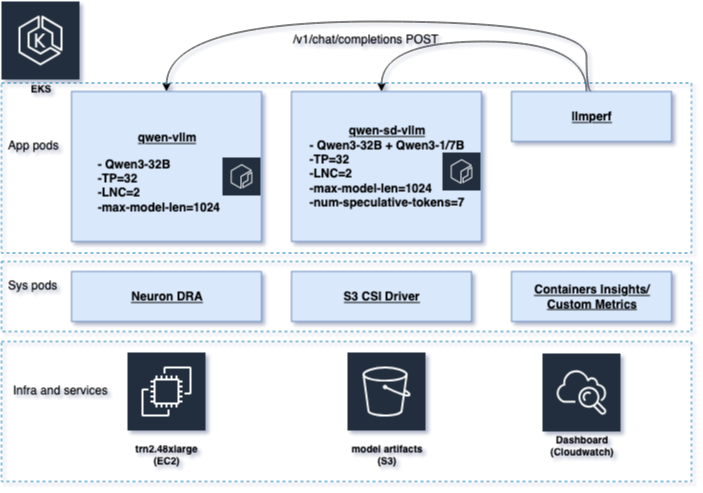
Accelerating decode-heavy LLM inference with speculative decoding on ...
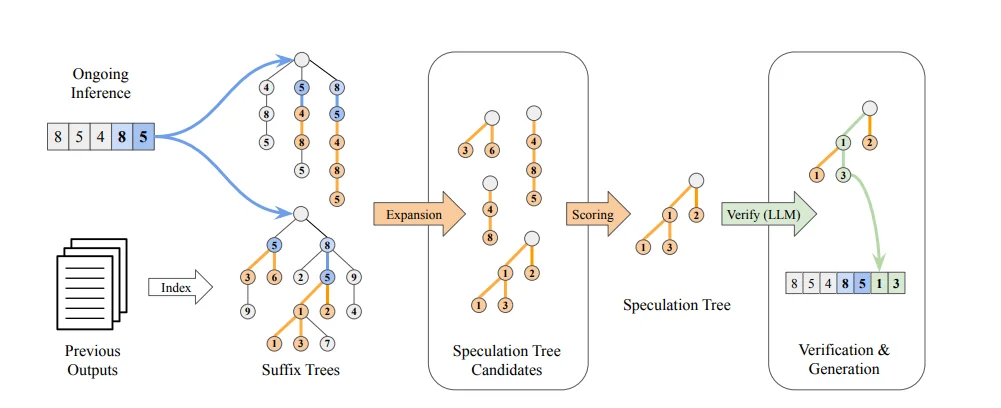
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...
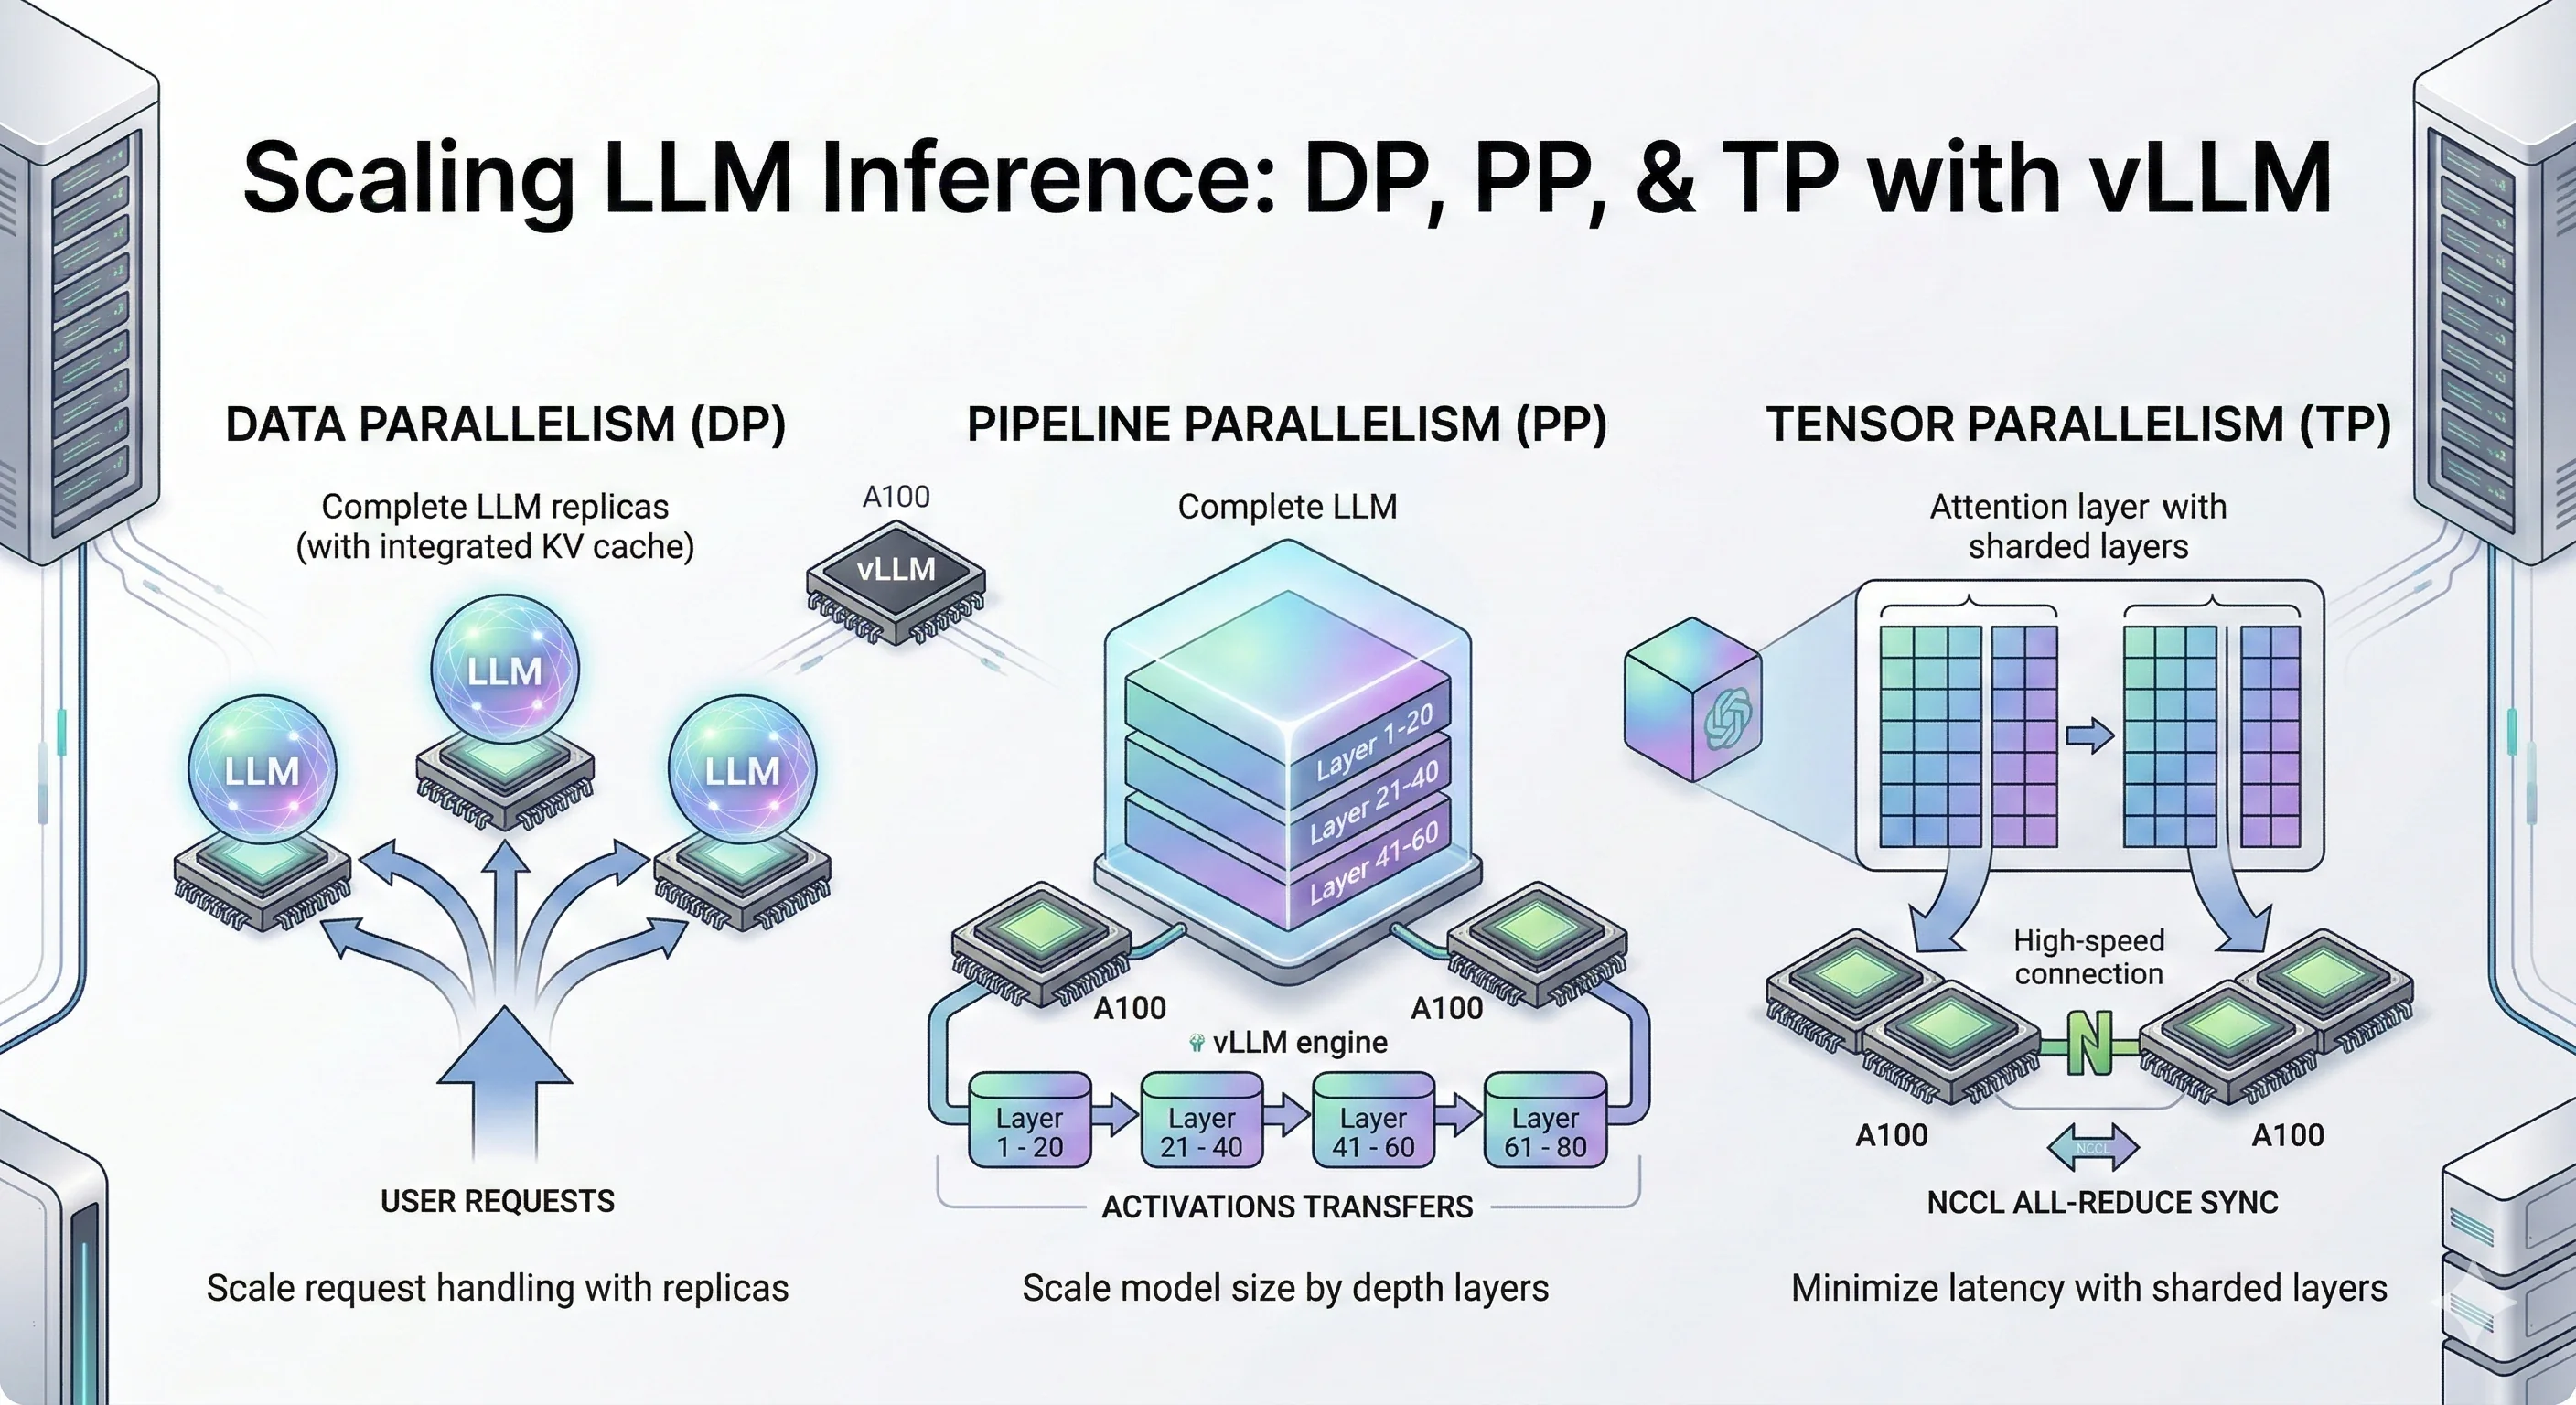
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Speculative Decoding Explained: Faster Inference Without Quality Loss
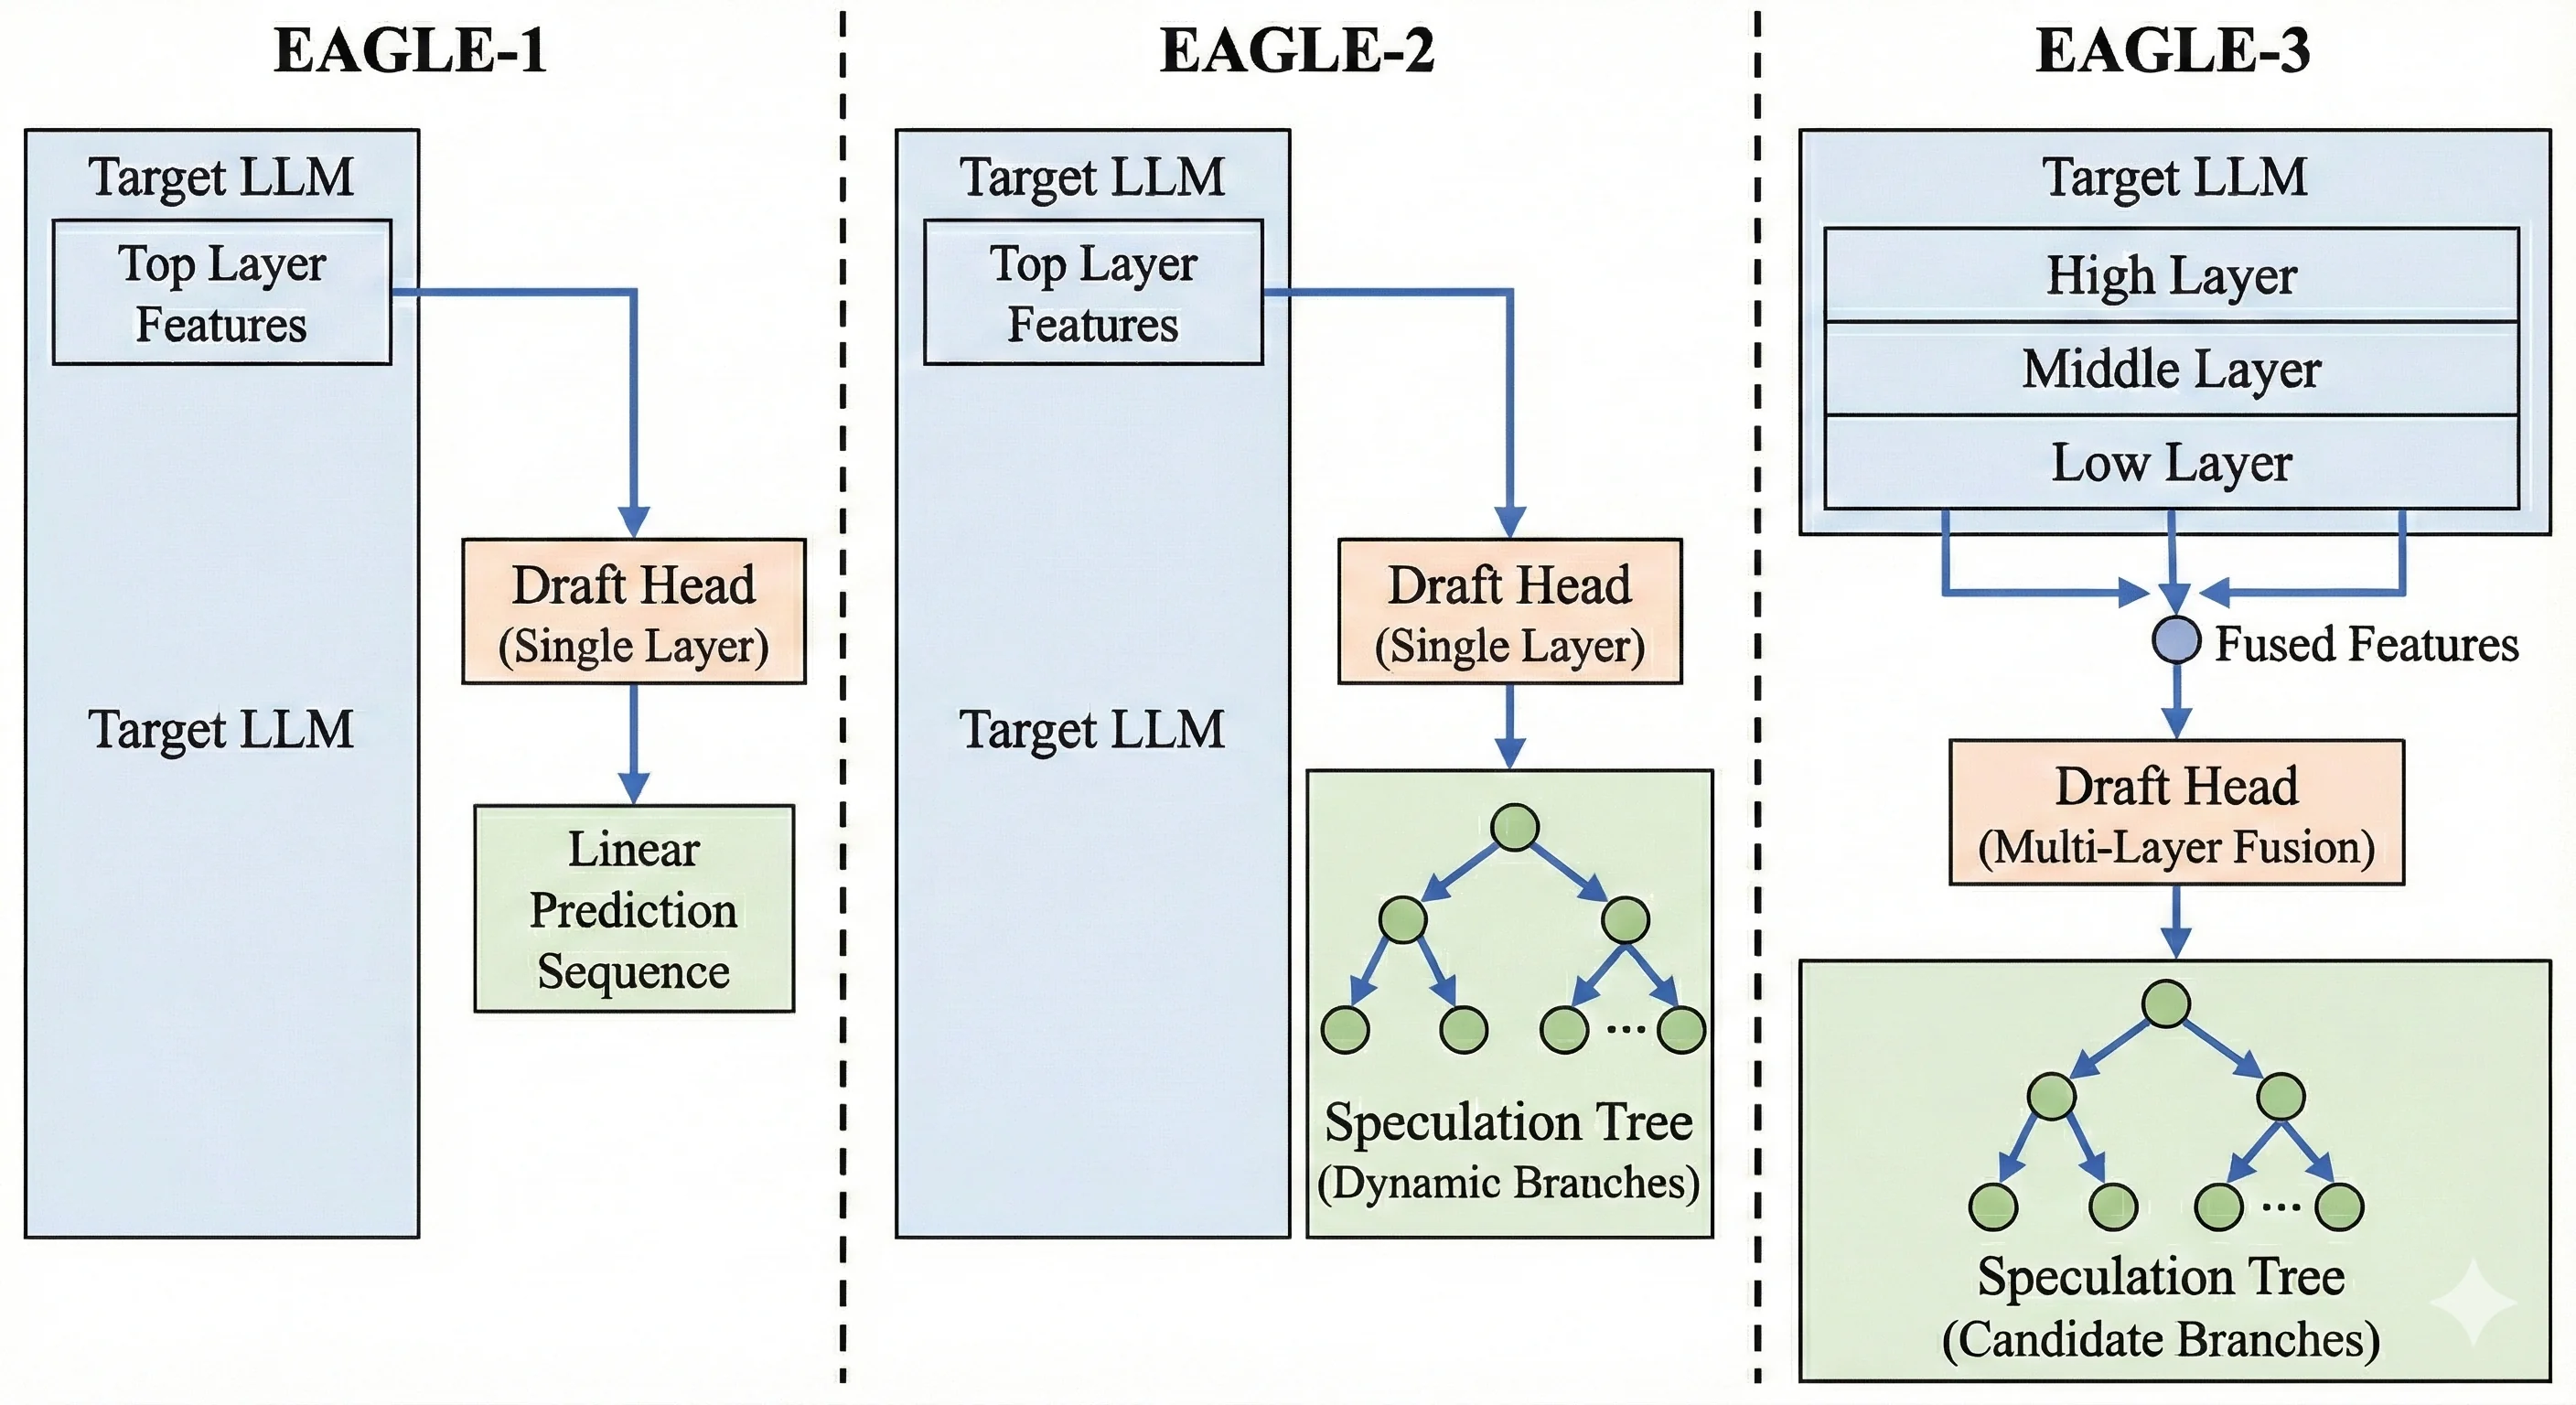
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
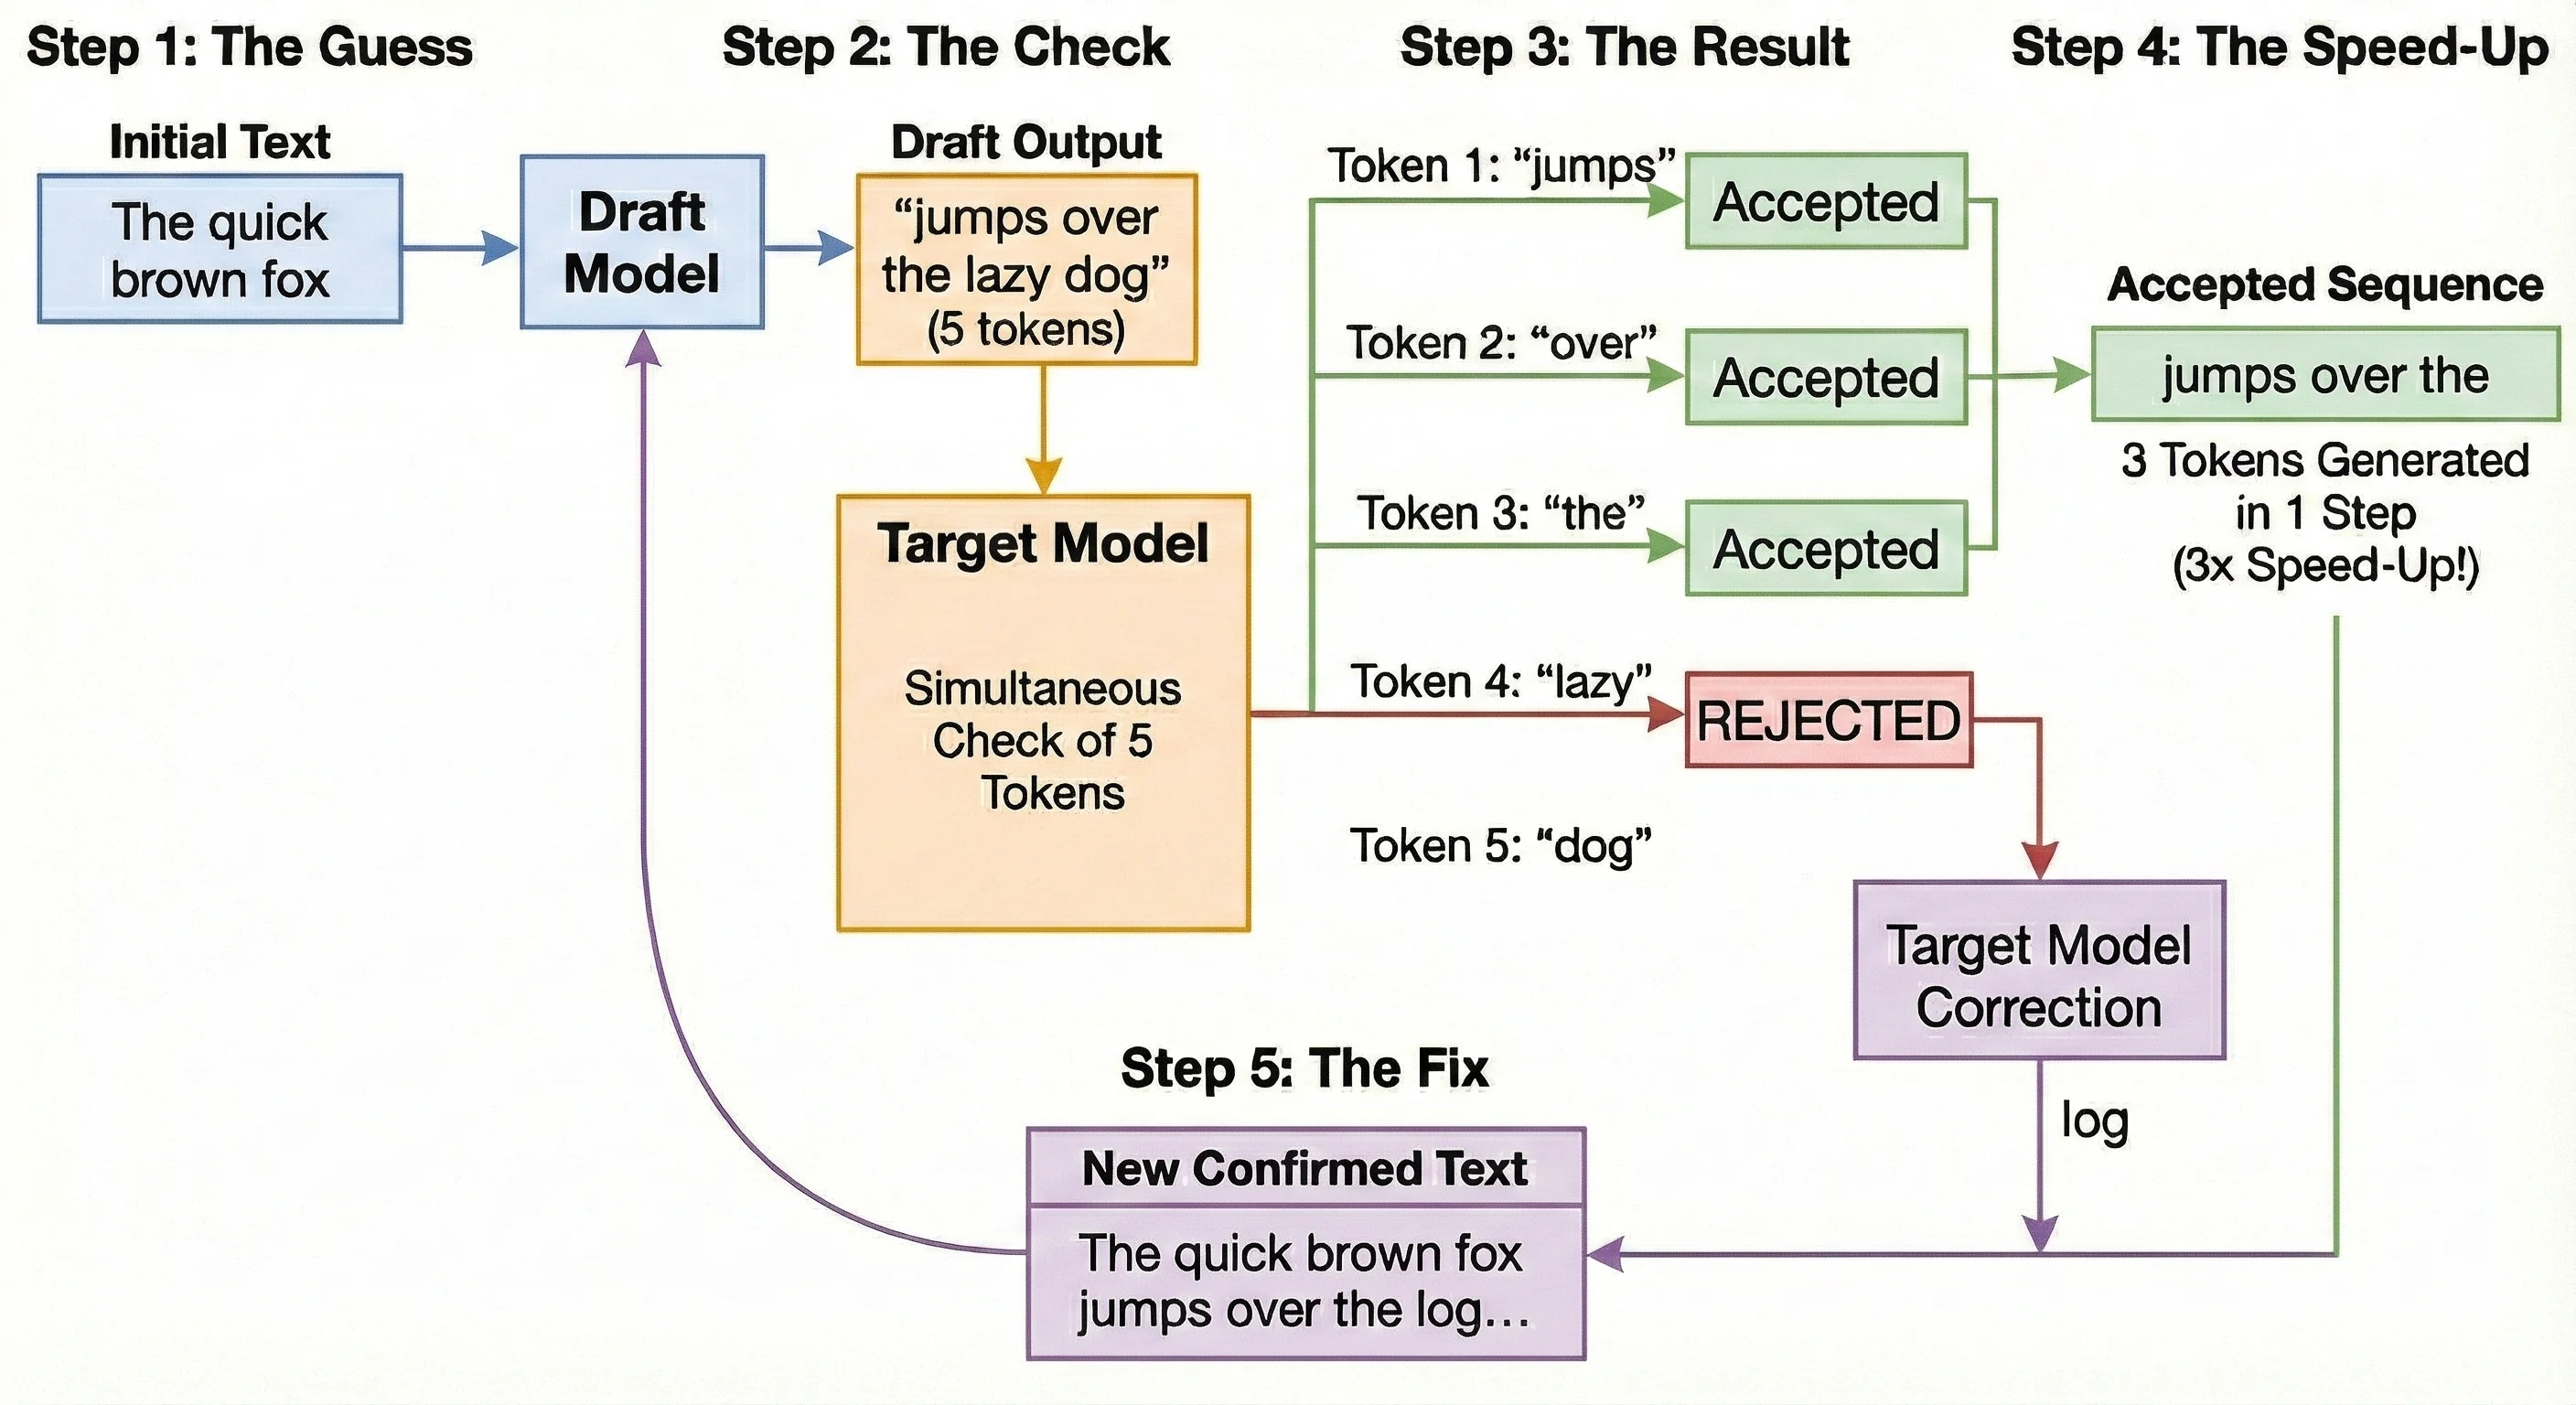
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
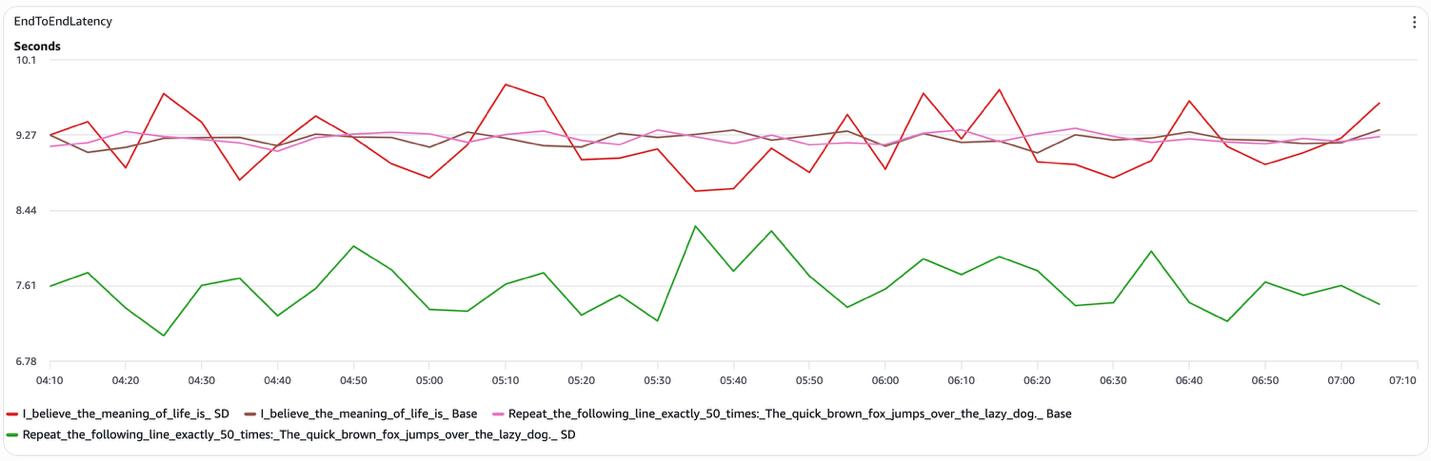
Accelerating decode-heavy LLM inference with speculative decoding on ...

Speculative Decoding - Making Language Models Generate Faster Without ...
Advertisement Space (336x280)
Accelerating decode-heavy LLM inference with speculative decoding on ...
Speculative decoding moves into production for decode-heavy LLMs | AI News
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
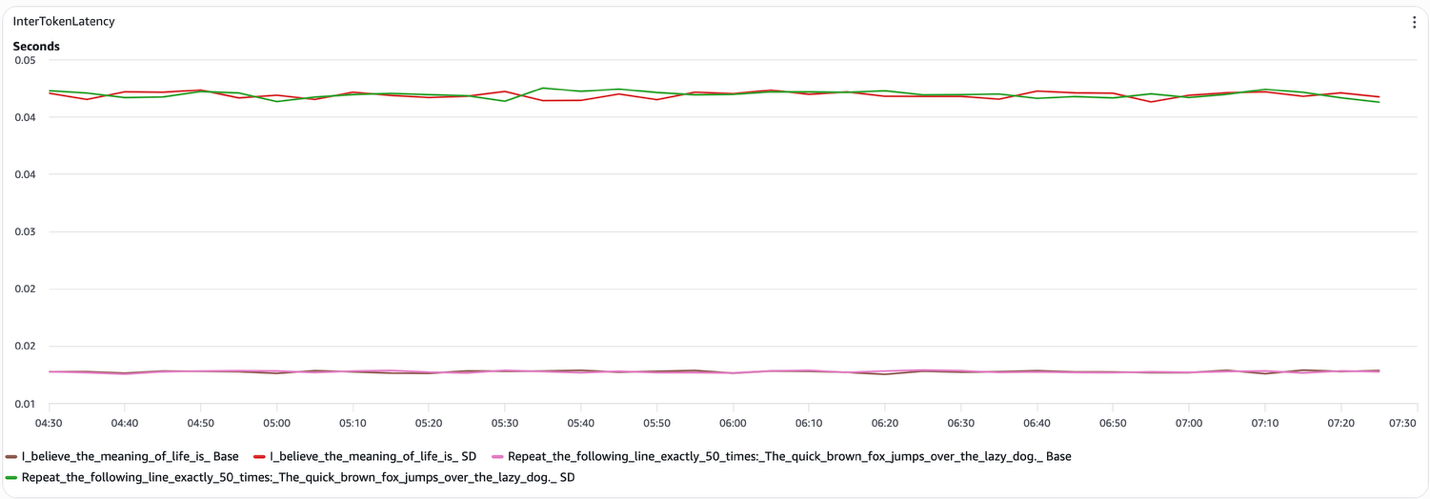
Accelerating decode-heavy LLM inference with speculative decoding on ...

This AI Paper Unveils the Potential of Speculative Decoding for Faster ...

re:Invent 2023 CMP319 Deploy LLMs with AWS Inferentia & Ray to optimize ...

Speculative Decoding with CTC-based Draft Model for LLM Inference ...

Scaling LLM Inference on EKS with AWS Inferentia and Trainium | by ...
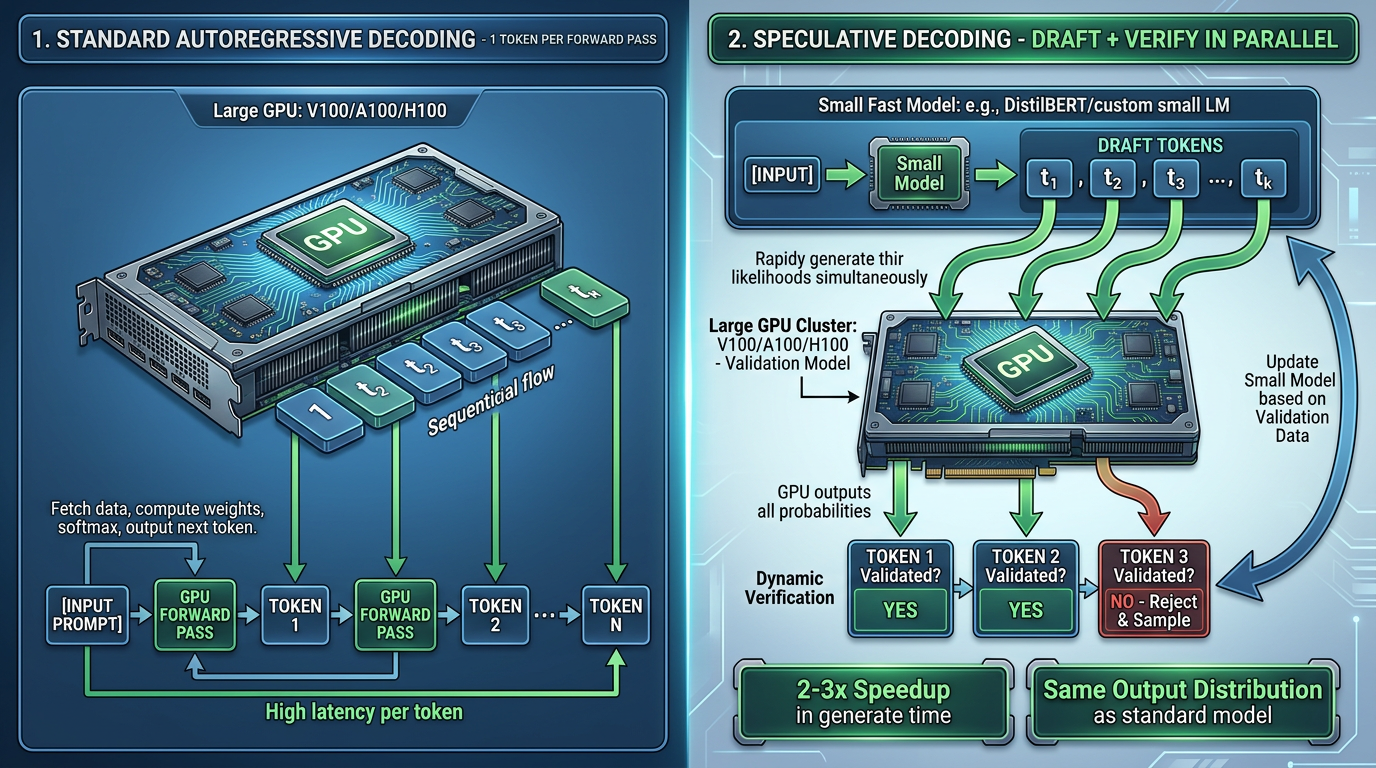
Speculative Decoding: Making LLMs 2–3x Faster Without Breaking Anything ...

Speculative Decoding: 3× Faster LLM Inference with Zero Quality Loss ...
Advertisement Space (336x280)

Scaling LLM Inference on EKS with AWS Inferentia and Trainium | by ...

Accelerating LLM Inference with Speculative Decoding - LinkedIn ...
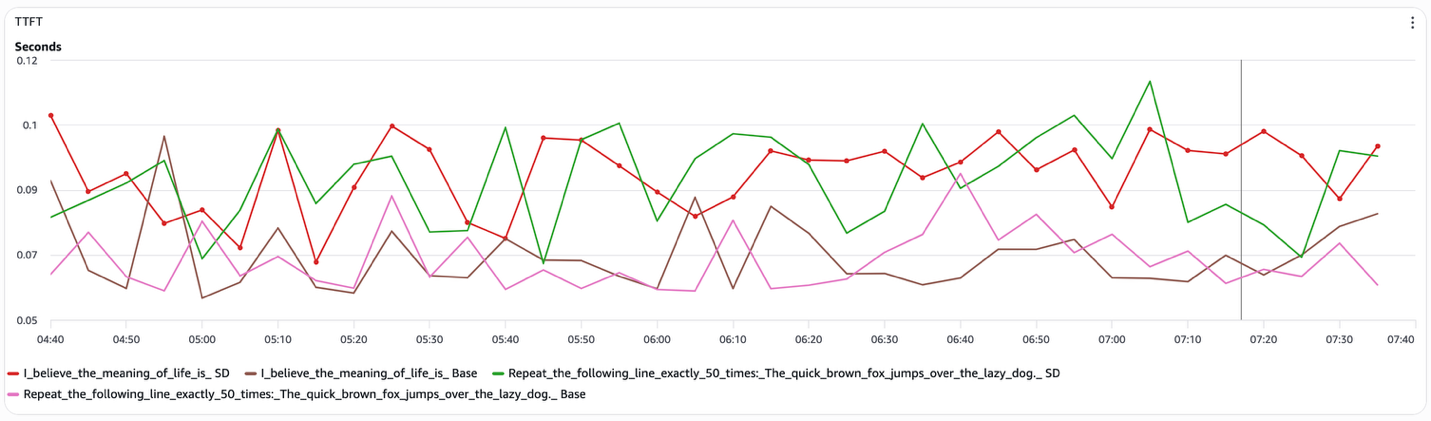
Accelerating decode-heavy LLM inference with speculative decoding on ...

(PDF) Accelerating LLM Inference with Staged Speculative Decoding

Speculative Decoding Explained: Faster Inference Without Quality Loss
Generate structured output from LLMs with Dottxt Outlines in AWS ...