
Speculative Decoding For Faster Llms By M Foundation Models Deep

Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...
Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...
Speculative Decoding for Faster LLMs | by M | Foundation Models Deep ...

Dynamic Depth Decoding: Faster Speculative Decoding for LLMs | AI ...
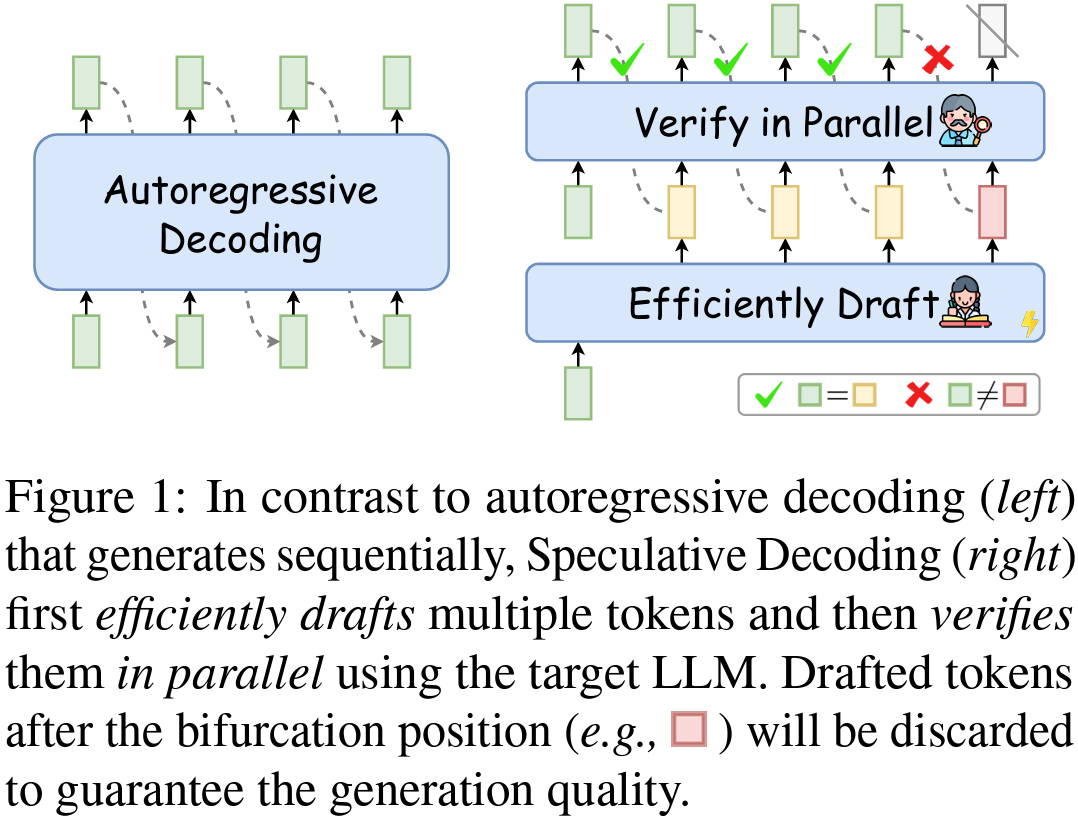
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...

Speculative Decoding - Making Language Models Generate Faster Without ...

Faster LLMs with speculative decoding and AWS Inferentia2
Making LLMs Faster: My Deep Dive into Speculative Decoding | Subhadip Mitra

Faster LLMs with speculative decoding and AWS Inferentia2 | Artificial ...

This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
Advertisement Space (300x250)
How Speculative Decoding Makes LLMs 2.5x Faster (The Secret to Faster ...

How speculative decoding speed up LLMs by 2x | Jon Salisbury posted on ...

Faster LLMs with speculative decoding and AWS Inferentia2

DFlash: block diffusion accelerates speculative decoding for faster LLM ...
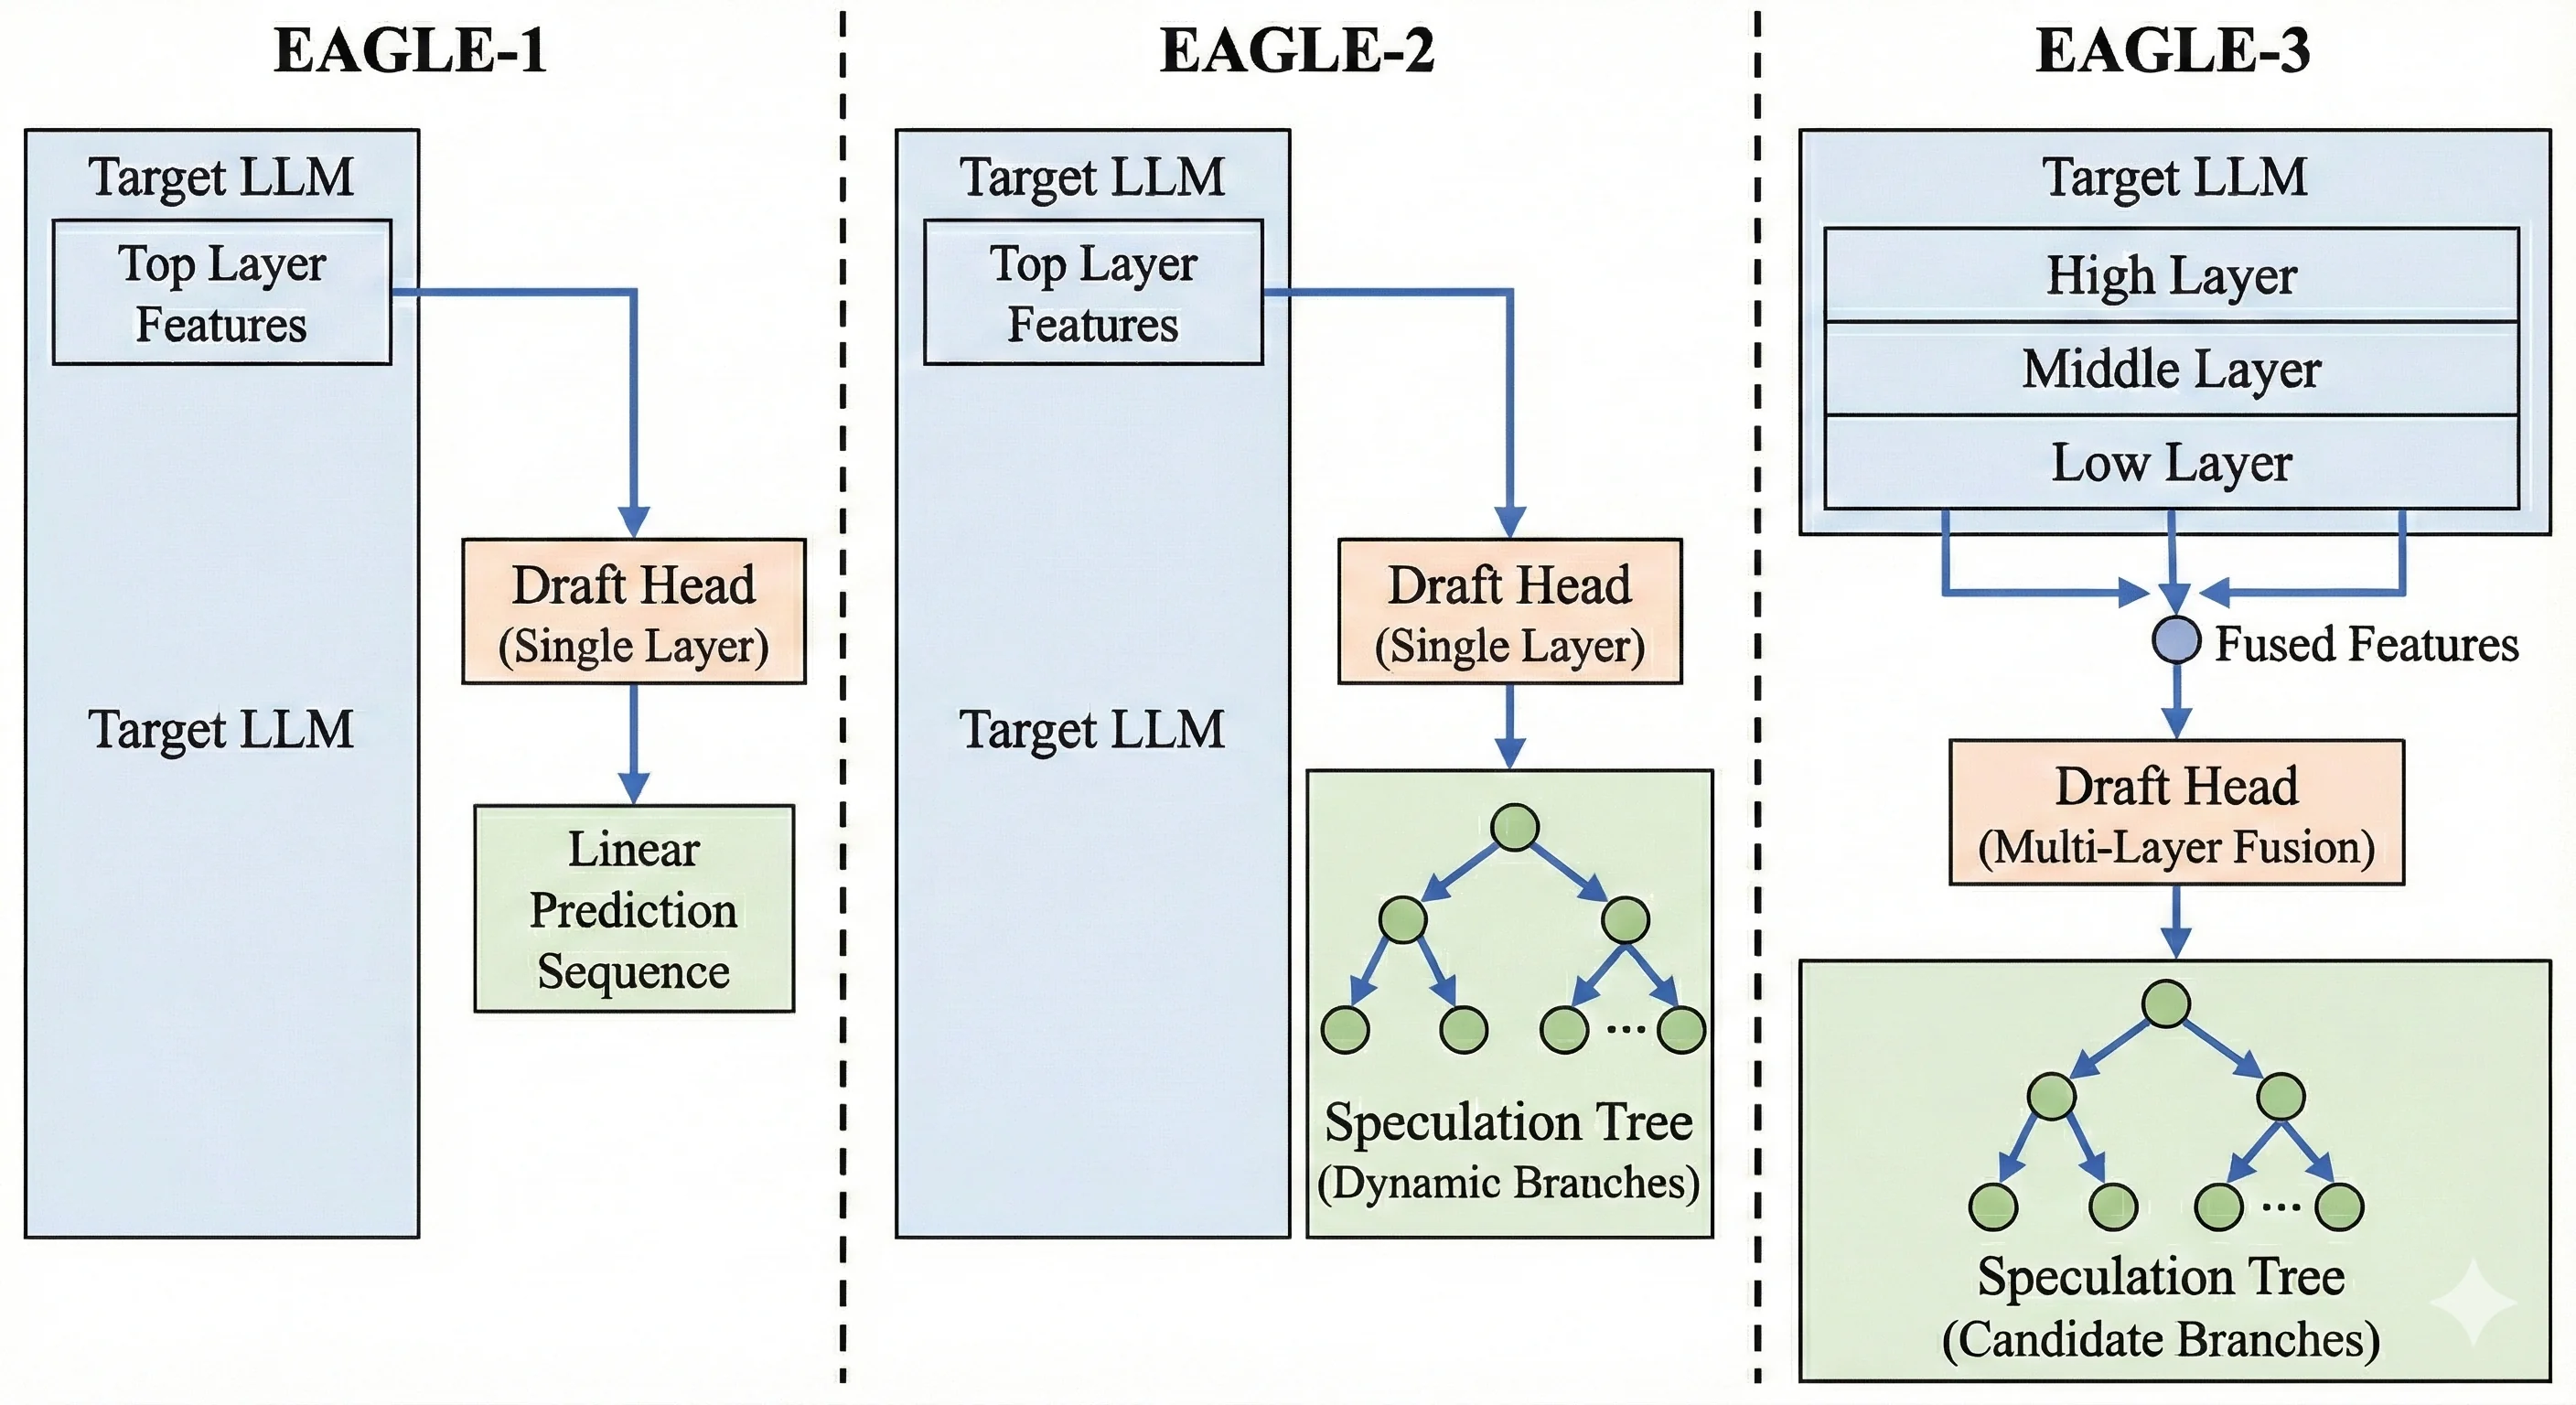
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
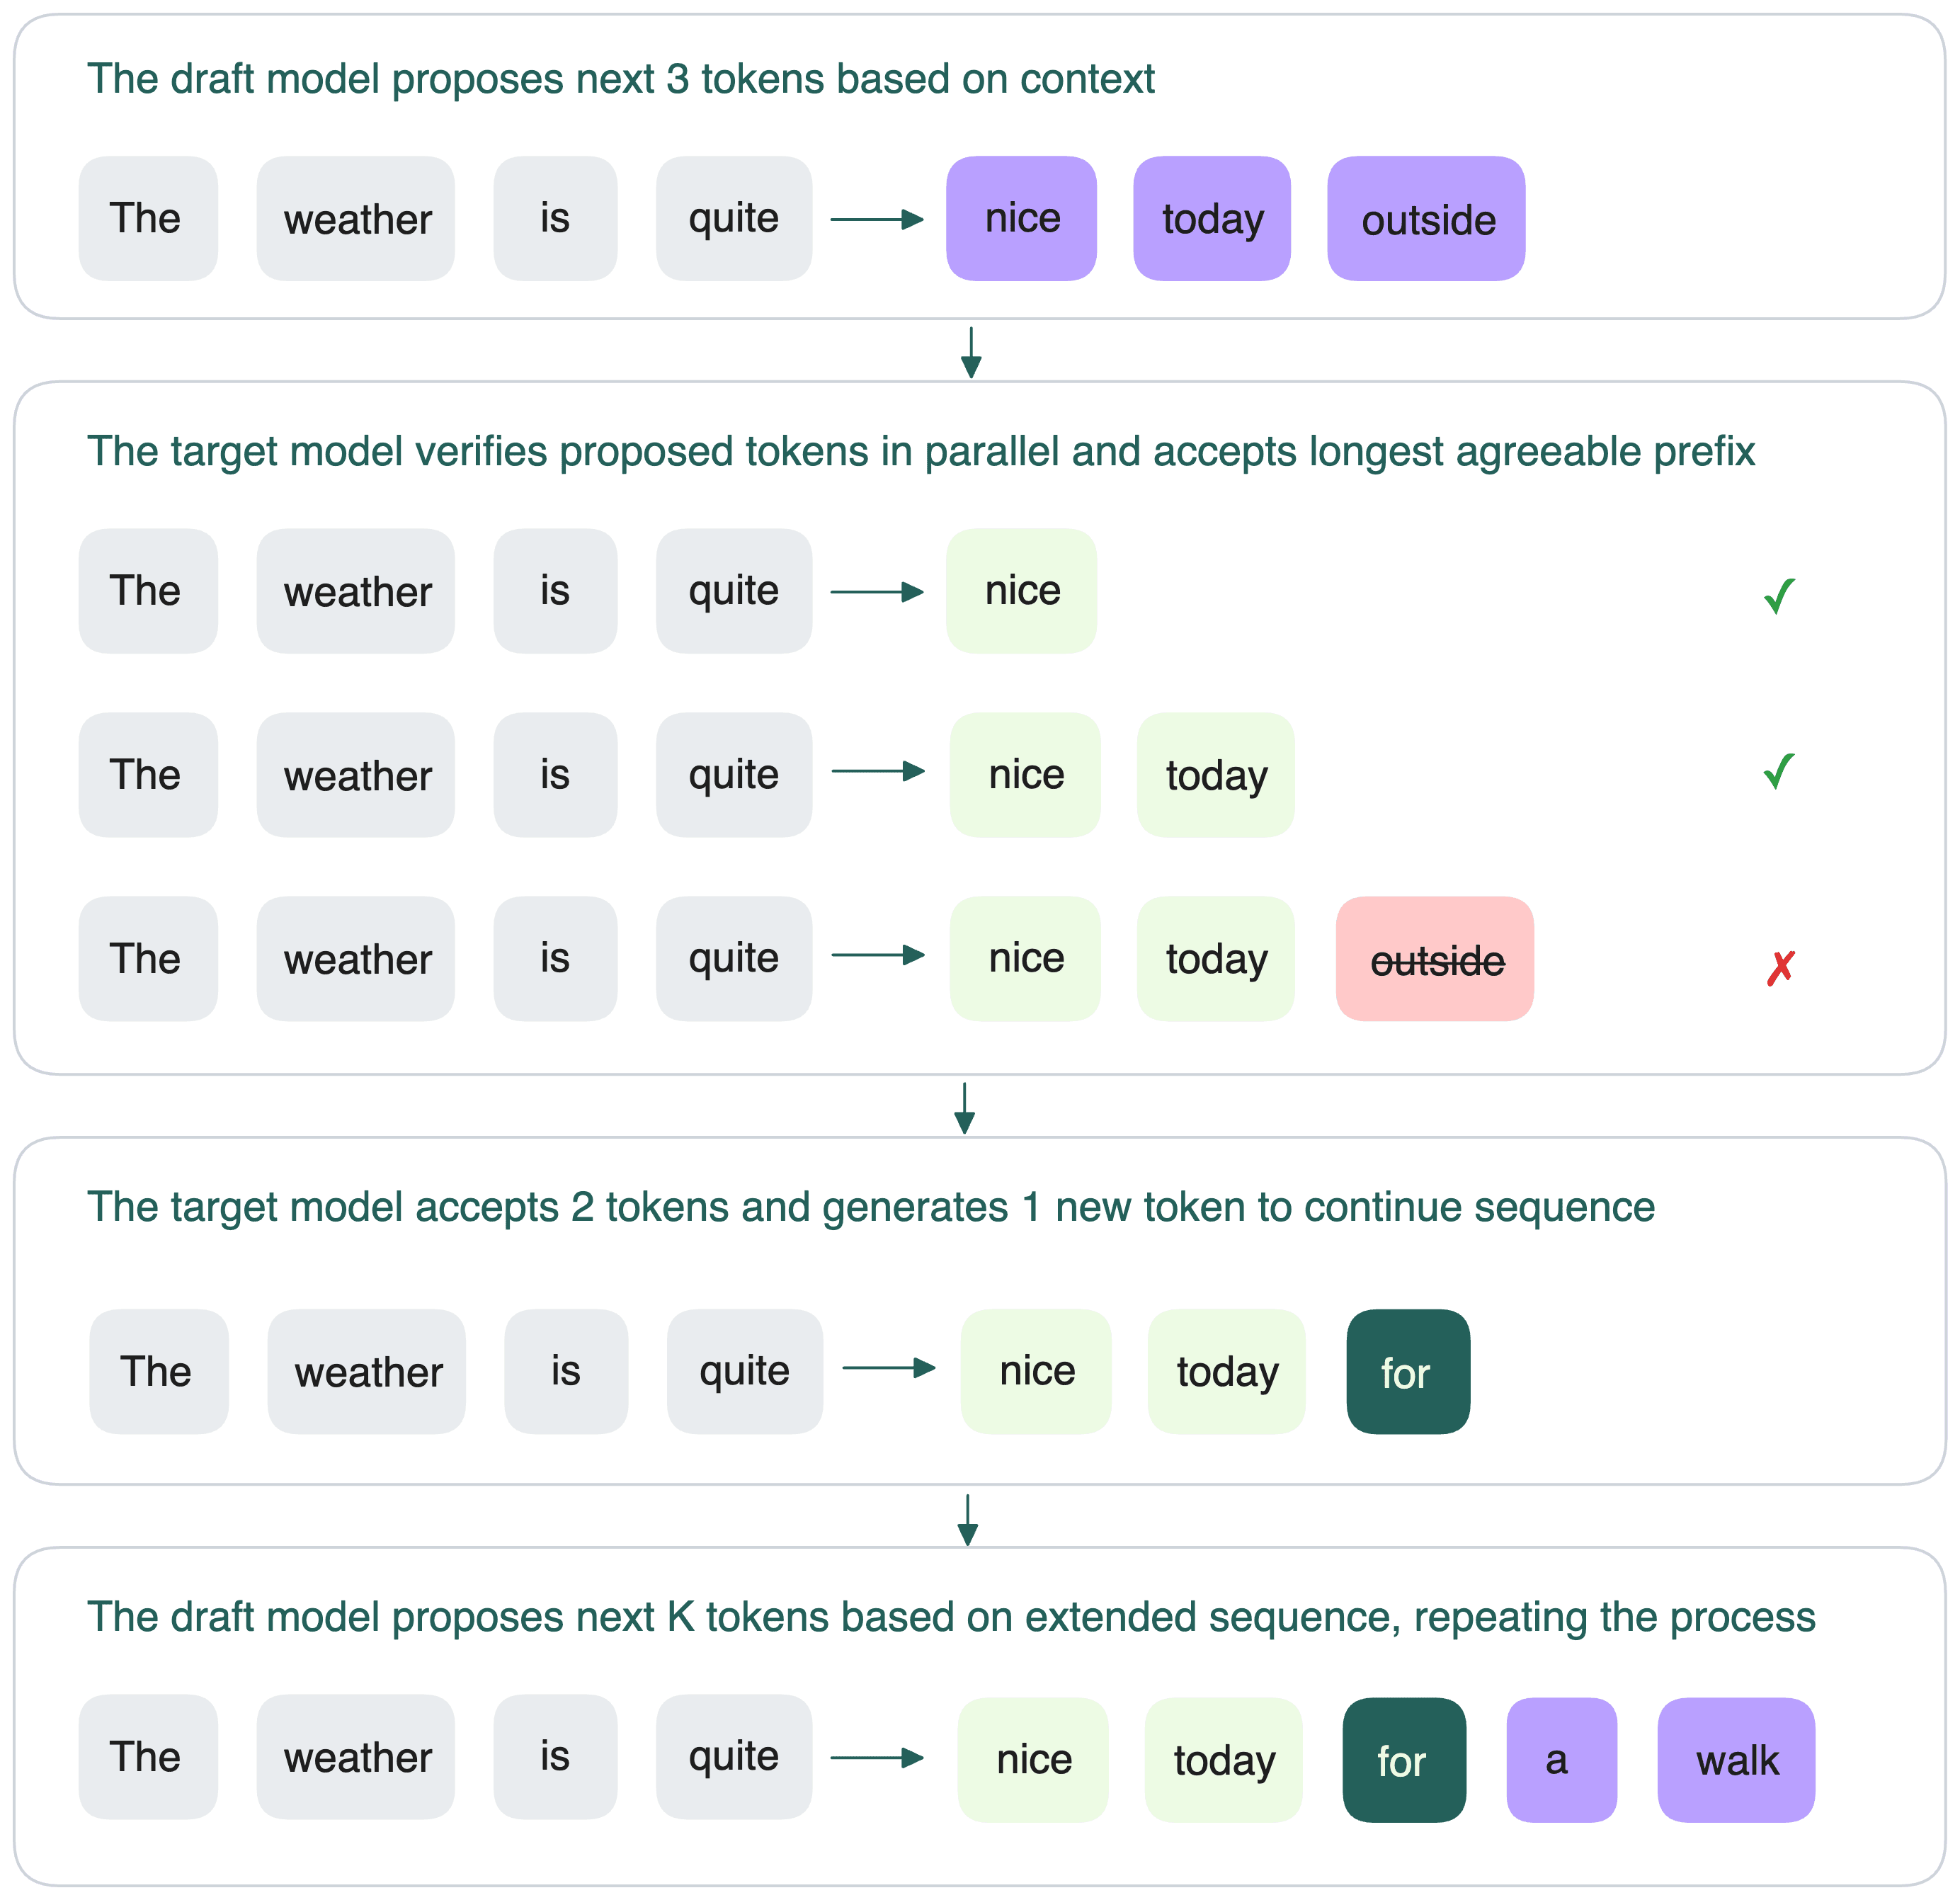
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
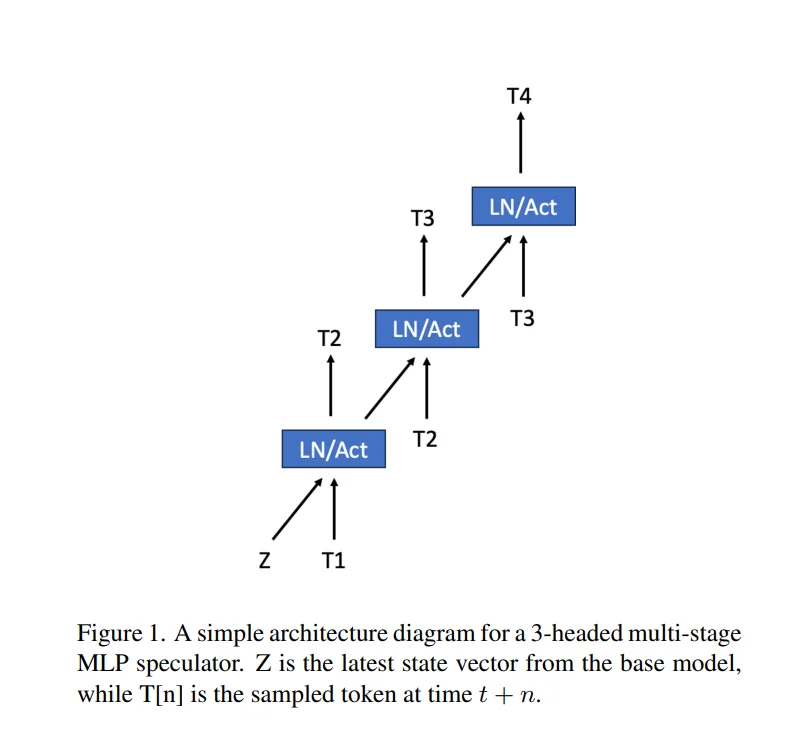
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Speculative Decoding Explained: Faster Inference Without Quality Loss
🚀 Speed Up LLM Inference with Speculative Decoding | by Generative AI ...

TensorRT-LLM Speculative Decoding Boosts Inference Throughput by up to ...
Advertisement Space (336x280)
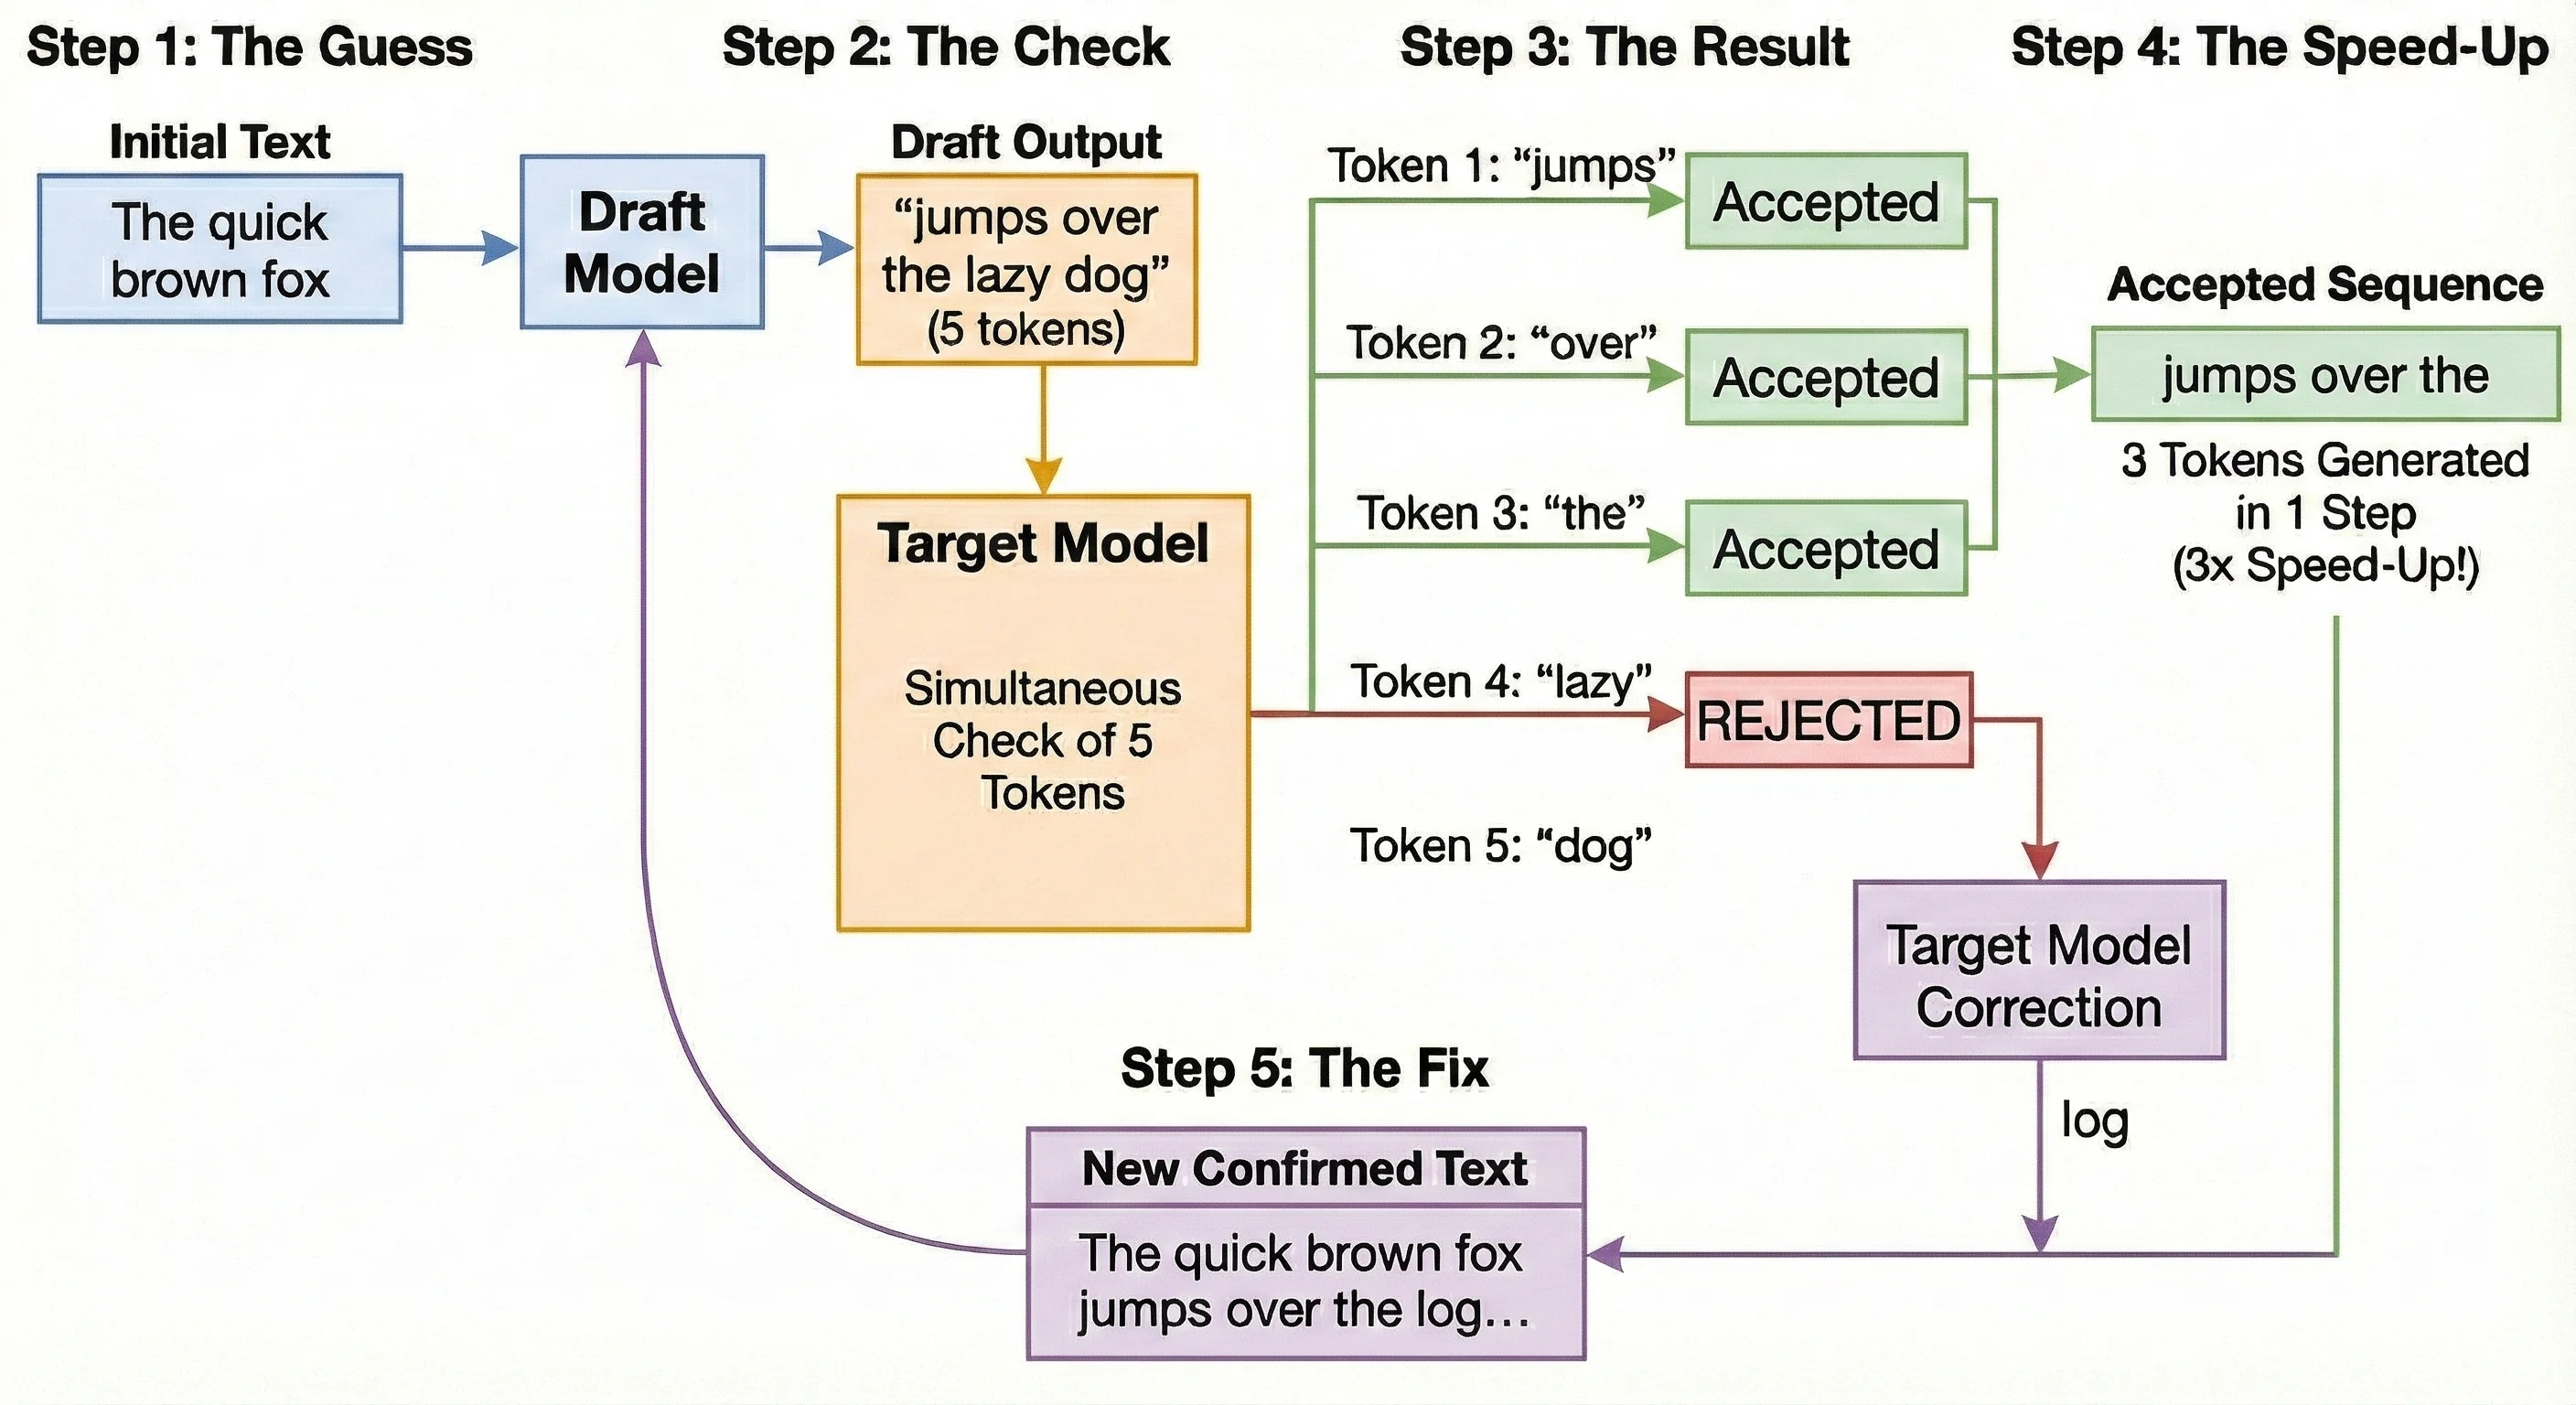
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
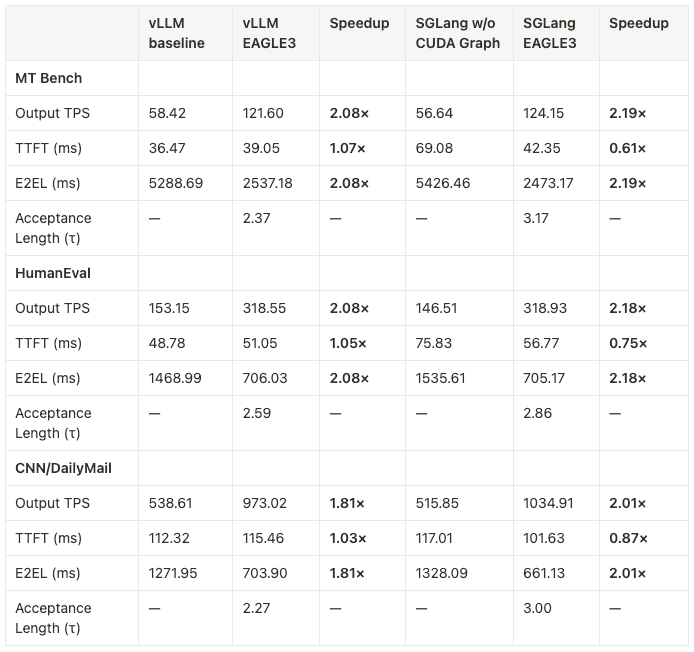
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...

Faster LLMs: Accelerate Inference with Speculative Decoding - YouTube

🚀 Speculative Decoding: Small Models Guess, Big Models 3× Faster ...

Survey of Speculative Decoding in LLMs | PDF
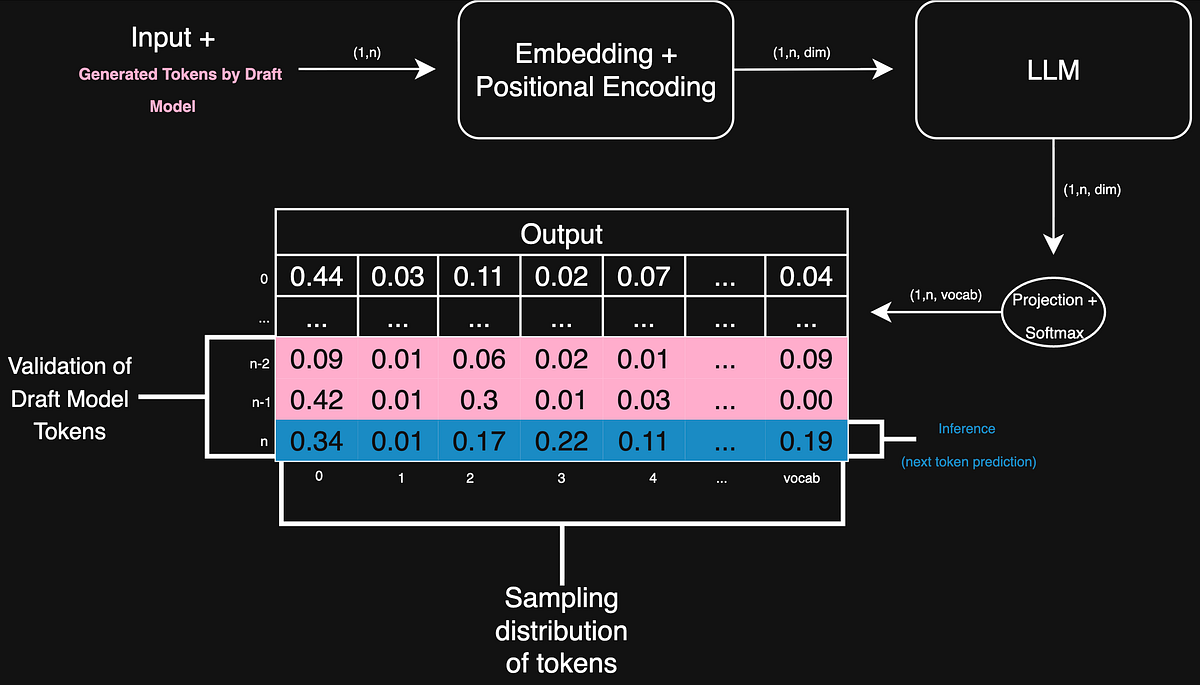
Speculative Decoding: How to Make Large Language Models Think Faster ...

Paper page - DART: Diffusion-Inspired Speculative Decoding for Fast LLM ...

Speculative Decoding: How AI Replies Faster Without Losing Quality | by ...

Speculative Decoding with CTC-based Draft Model for LLM Inference ...

Figure 1 from Nearest Neighbor Speculative Decoding for LLM Generation ...
Advertisement Space (336x280)
Speculative Decoding Production Guide: 2-5x Faster LLM Inference on GPU ...

[논문 리뷰] Reward-Guided Speculative Decoding for Efficient LLM Reasoning
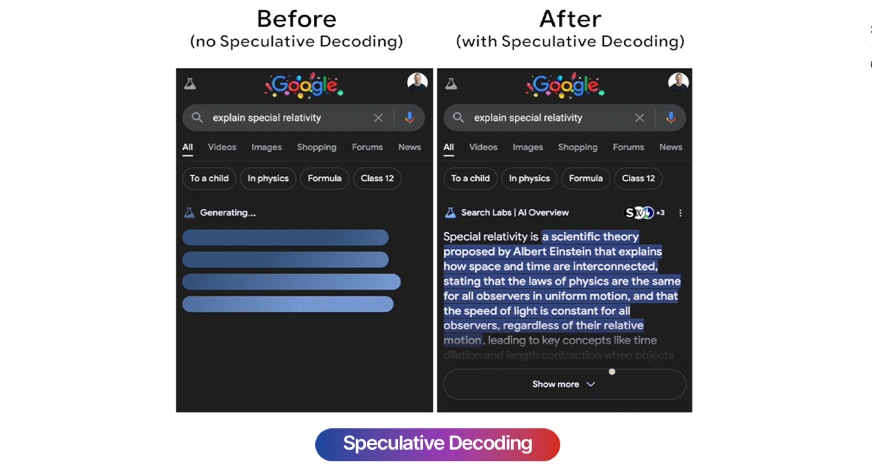
Speculative Decoding: How LLMs Generate Text 3x Faster

LLM推理加速: Speculative Decoding 概述 - 知乎

Why Your LLM Is Wasting 90% of Its GPU — And How Speculative Decoding ...