
Feature Batch Inference For Llmchat Api Issue 8481 Vllm
[Feature]: Batch inference for `llm.chat()` API · Issue #8481 · vllm ...
[Usage]: vllm OpenAI API Offline Batch Inference · Issue #8567 · vllm ...
[Usage]: How to use vllm serve for batch inference? · Issue #16494 ...

vLLM V1: Accelerating multimodal inference for large language models ...
[Feature]: continuous batching for vllm.LLM · Issue #7353 · vllm ...
Batch Inference for LLMs: Cutting Cost 70 Percent in 2026 — Swfte AI
vLLM Installation for High-Performance LLM Inference - CubePath Docs ...
"llm.generate()" API support Continuous Batching? · Issue #684 · vllm ...

Serving Online Inference with vLLM API on Vast.ai - YouTube
vLLM Distributed Inference stuck when using multi -GPU · Issue #2466 ...
Advertisement Space (300x250)
[Feature]: Add OpenTelemetry (trace) API to v1 · Issue #17794 · vllm ...
[Feature]: Support openai responses API interface · Issue #14721 · vllm ...
[Bug]: Can't use offline inference embedding · Issue #4908 · vllm ...

Free Video: vLLM Inference and LLM Server Engine for Machine Learning ...

Offline LLM Inference with the Bedrock Batch API - YouTube
API Server batch request issue · Issue #2441 · vllm-project/vllm · GitHub

vLLM V1: Accelerating multimodal inference for large language models ...
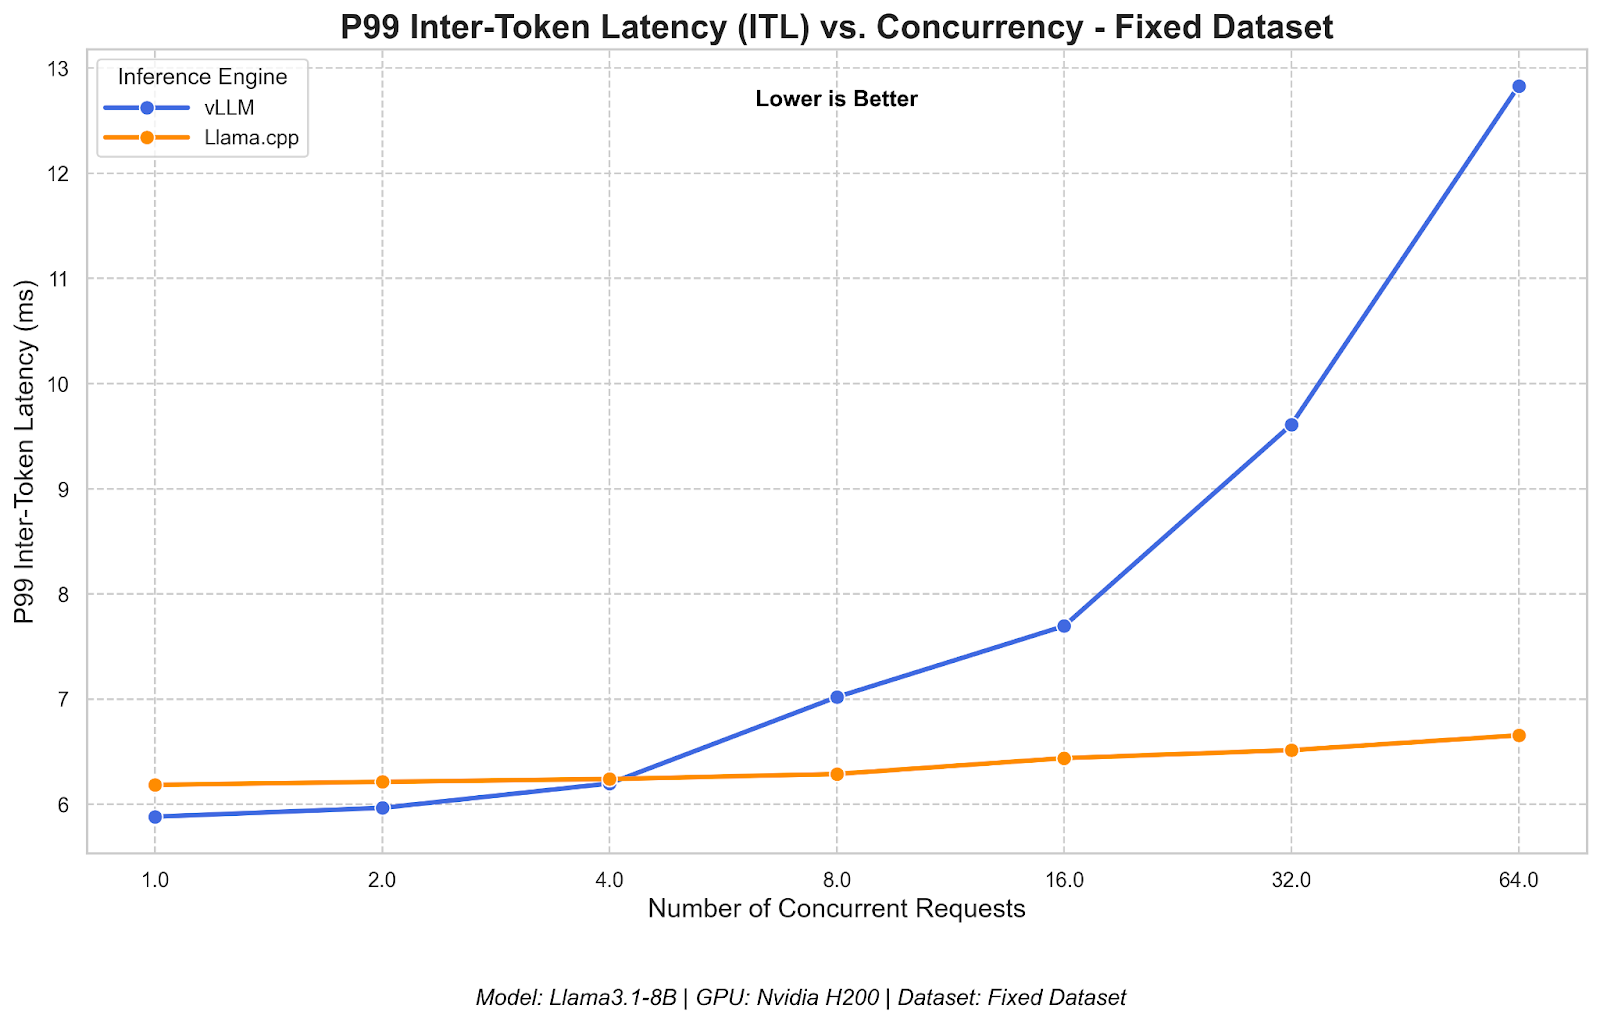
vLLM or llama.cpp: Choosing the right LLM inference engine for your use ...

Meet vLLM: For faster, more efficient LLM inference and serving
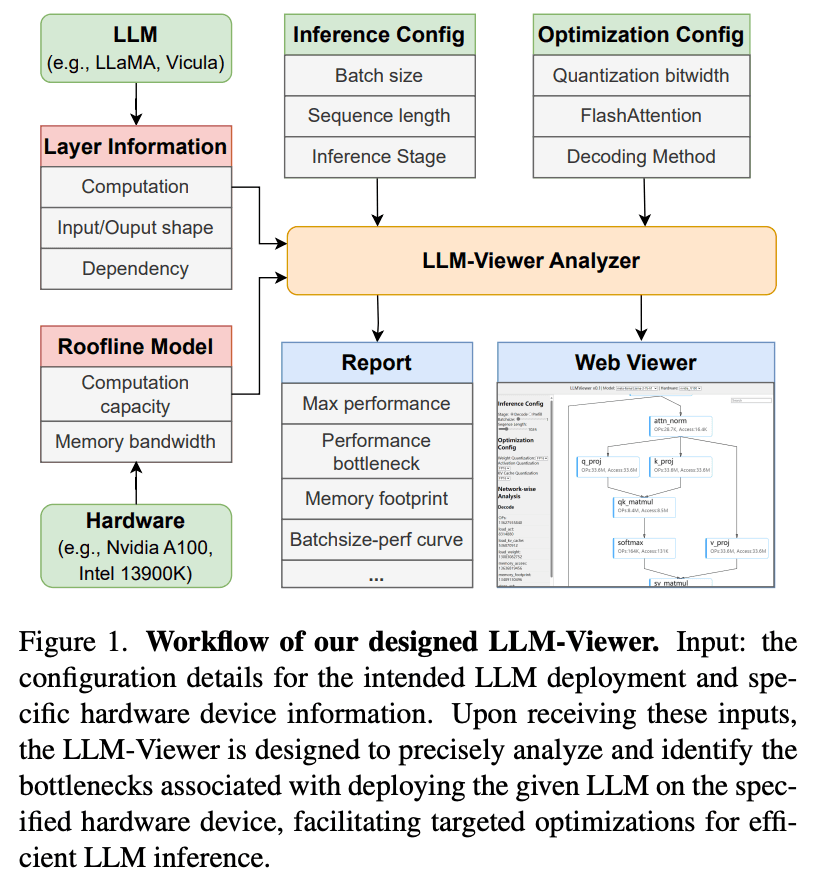
Understanding LLM Batch Inference | Adaline
Advertisement Space (336x280)
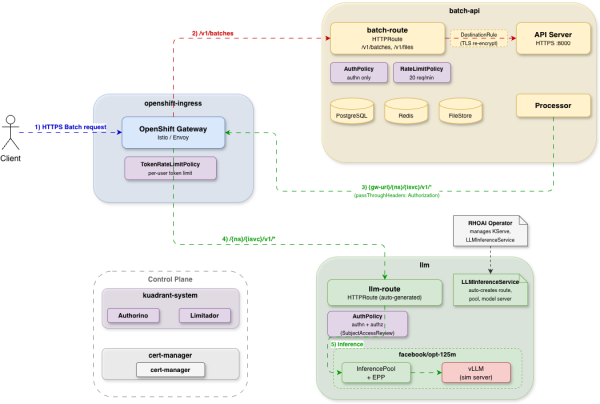
Batch inference on OpenShift AI with llm-d: Architecture, integration ...
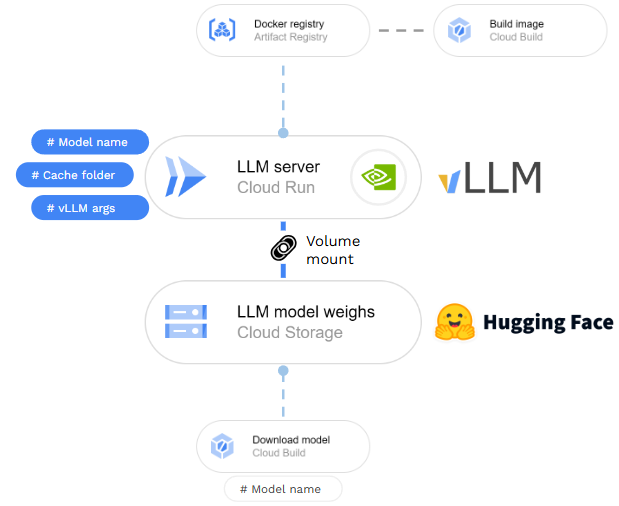
A Brief Introduction to Optimized Batched Inference with vLLM | by ...

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...
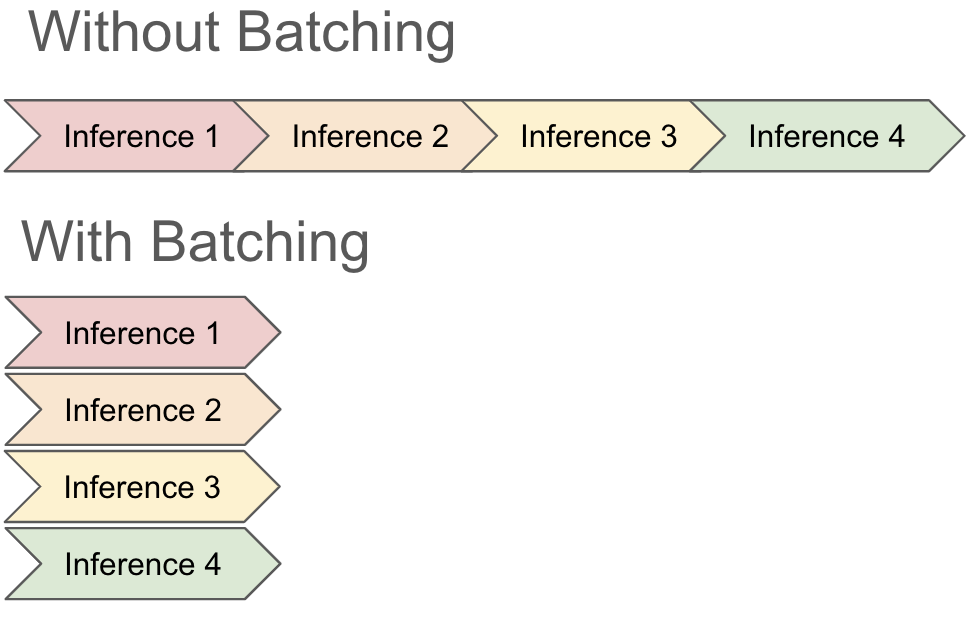
Inference with Gemma using Dataflow and vLLM | Google Engineering Blog ...
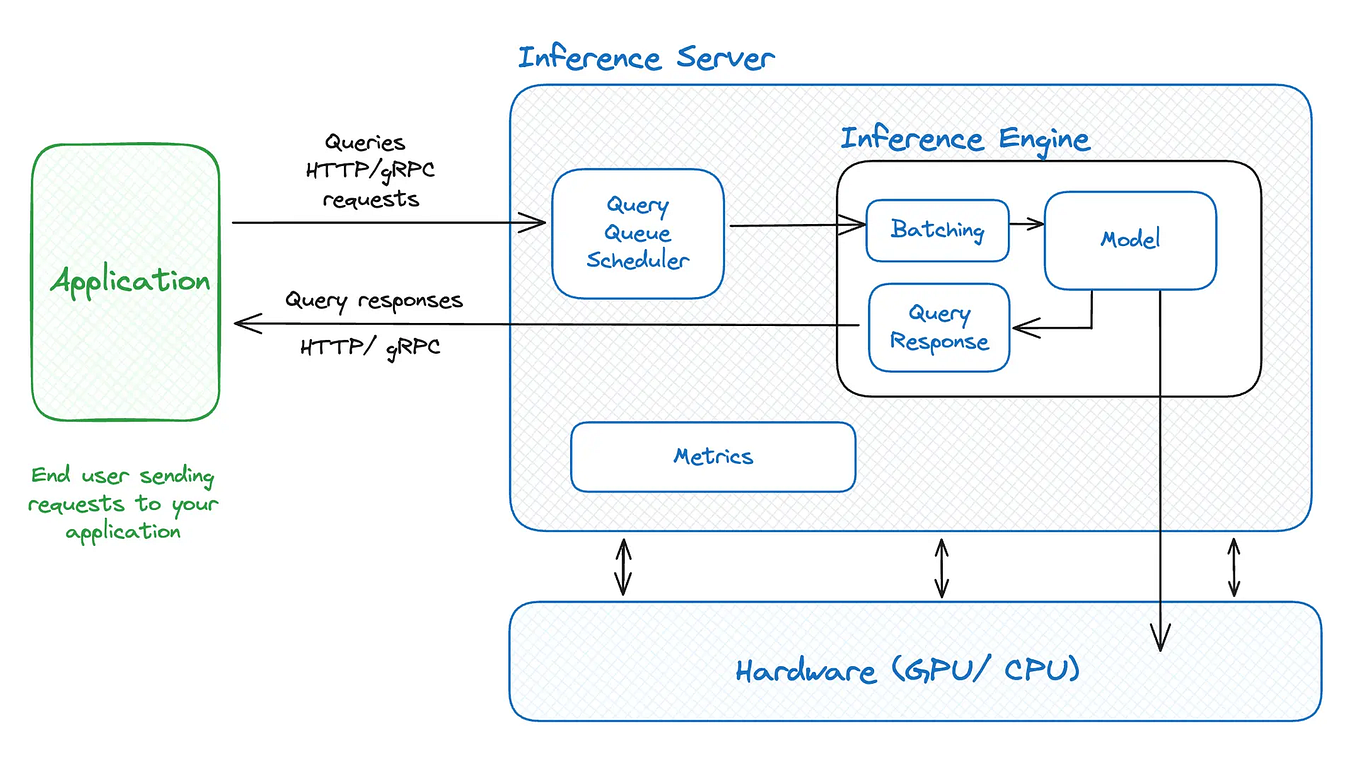
A Brief Introduction to Optimized Batched Inference with vLLM | by ...

Caching Strategies for VLM Inference: vLLM APC vs LangChain Cache | by ...
[Usage]: Batching in online inference · Issue #8441 · vllm-project/vllm ...
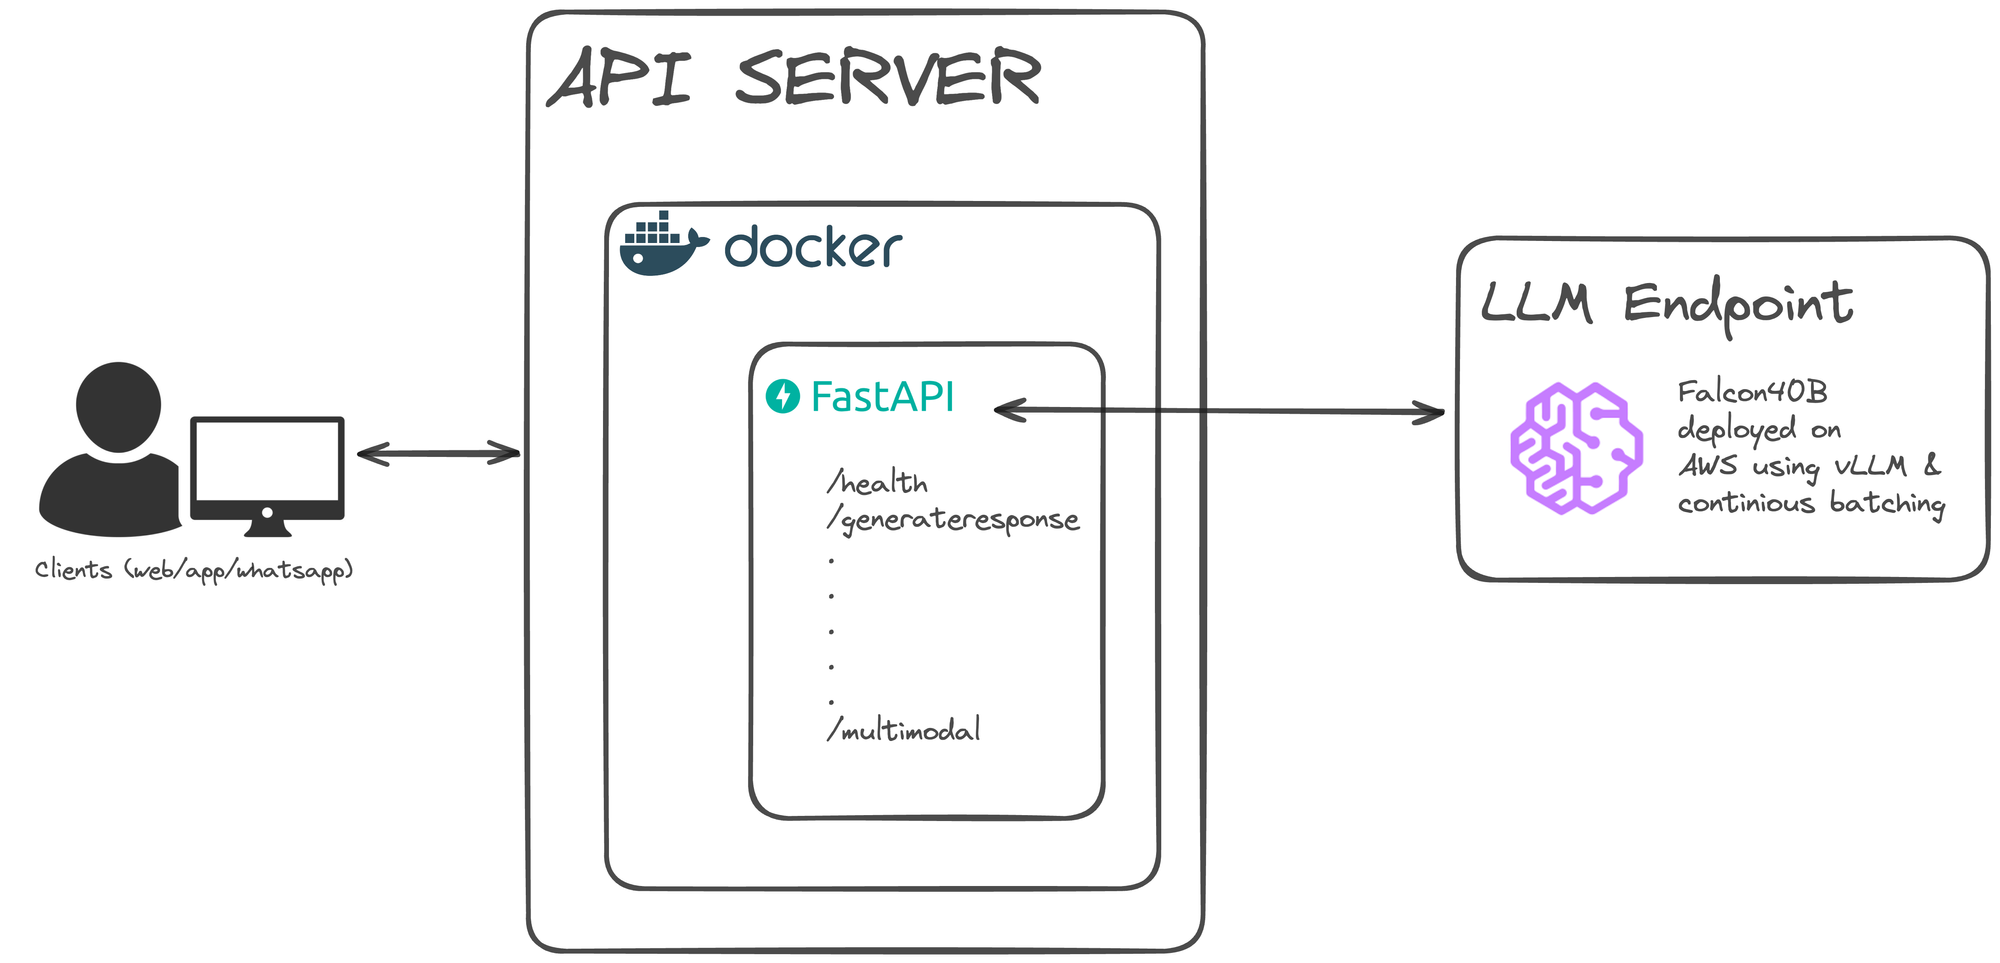
Scaling LLM inference with Ray and vLLM
[Feature]: Apply chat template through `LLM` class · Issue #6416 · vllm ...
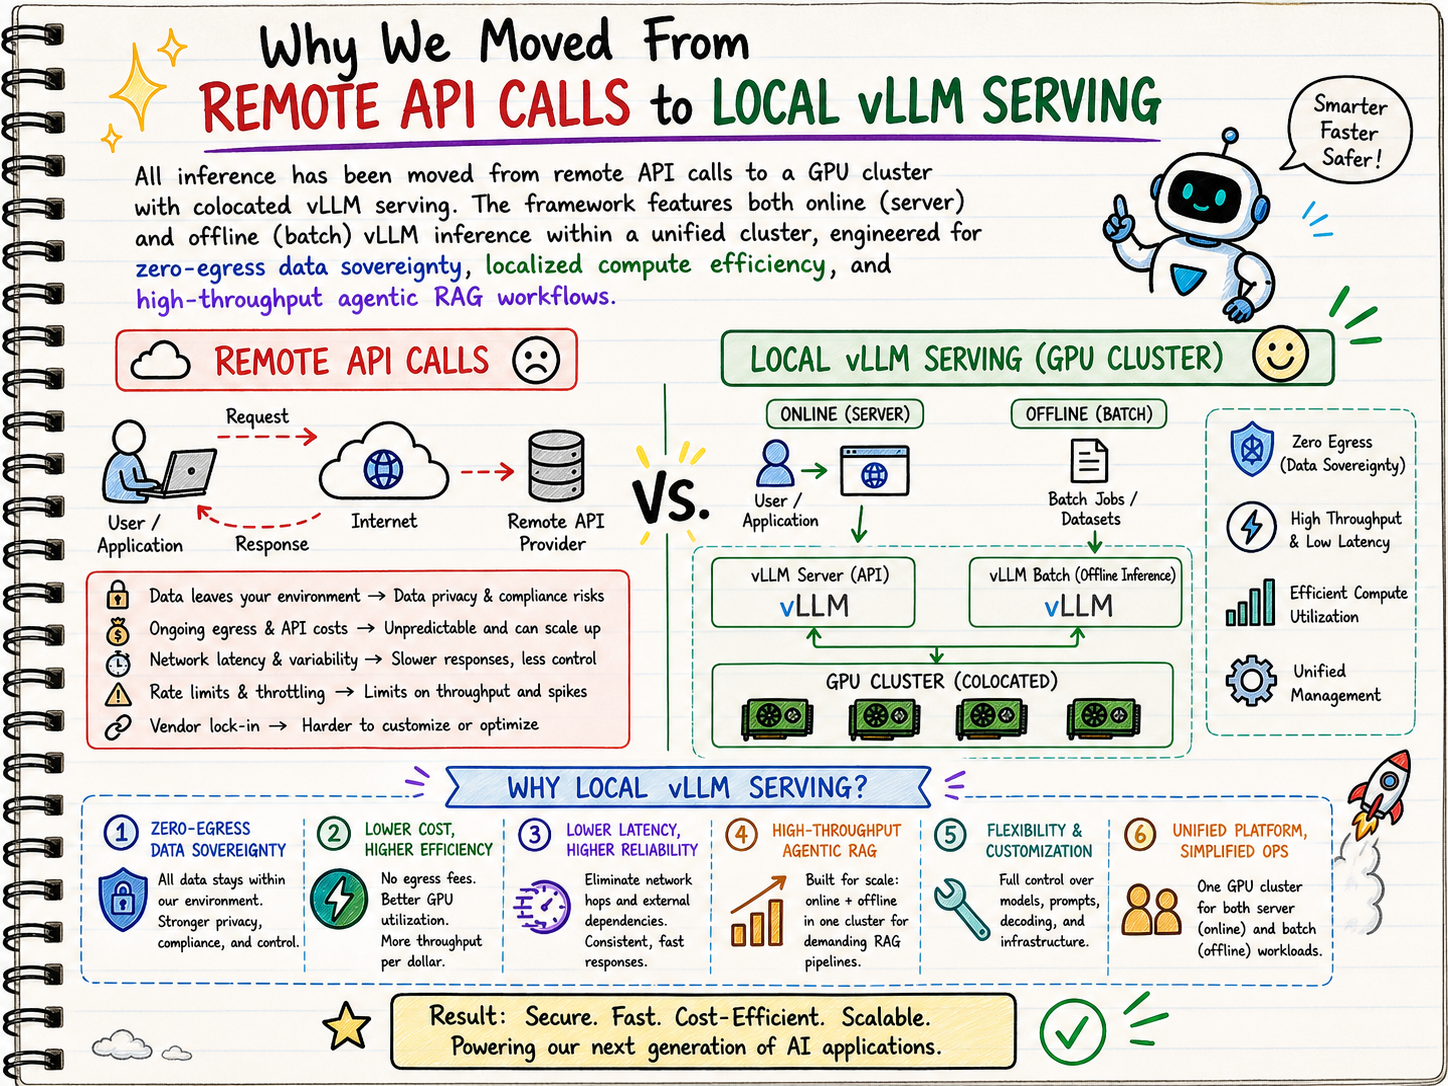
Agentic RAG with Colocated vLLM Inference | Agentic-RAG-vLLM-inference
Advertisement Space (336x280)
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...
Low VRAM batch processing mode · Issue #1297 · vllm-project/vllm · GitHub
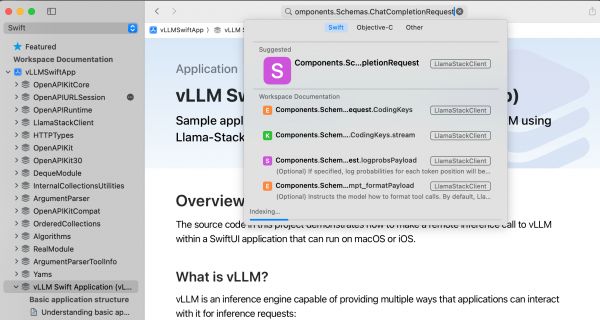
Integrate vLLM inference on macOS/iOS with Llama Stack APIs | Red Hat ...
Can't launch OpenAI API server on newly installed vLLM in Docker ...
chatglm3 inference results are inconsistent with huggingface · Issue ...