
Usage Vllm Openai Api Offline Batch Inference Issue 8567 Vllm
[Usage]: vllm OpenAI API Offline Batch Inference · Issue #8567 · vllm ...
[Usage]: OpenAI-like API in offline inference · Issue #6191 · vllm ...
[Feature]: Batch inference for `llm.chat()` API · Issue #8481 · vllm ...
How to Achieve Data-Parallel Offline Batch Inference Using vLLM? · vllm ...
[Usage]: vllm openai api server never ends in most cases · Issue #6228 ...
[Feature]: Support openai responses API interface · Issue #14721 · vllm ...
Update documentation for OpenAI API > 1.0.0 · Issue #1875 · vllm ...
No response from OpenAI Chat API with vLLM · Issue #1879 · vllm-project ...
[Bug]: OpenAI API Server always reports 0 tokens/s · Issue #4209 · vllm ...
How to use vllm openai api server for video reasoning ? · Issue #540 ...
Advertisement Space (300x250)
Open WebUI has problems with VLLM OpenAI compatible API · open-webui ...
Can't launch OpenAI API server on newly installed vLLM in Docker ...
GitHub - GreatJambo/vLLM-demo: Offline Batched Inference using vLLM ...
(Async) Batch request, OpenAI API server · Issue #1636 · vllm-project ...

Serving Online Inference with vLLM API on Vast.ai - YouTube

baidu/Qianfan-VL-8B · VLLM offline inference raise except when using ...
vLLM Distributed Inference stuck when using multi -GPU · Issue #2466 ...
Is vllm support stream chat in offline inference? · Issue #2083 · vllm ...

Use cli to batch download the usage data of openai api - Community ...
vllm serve 开启openAI API 总是报Engine core initialization failed · Issue ...
Advertisement Space (336x280)
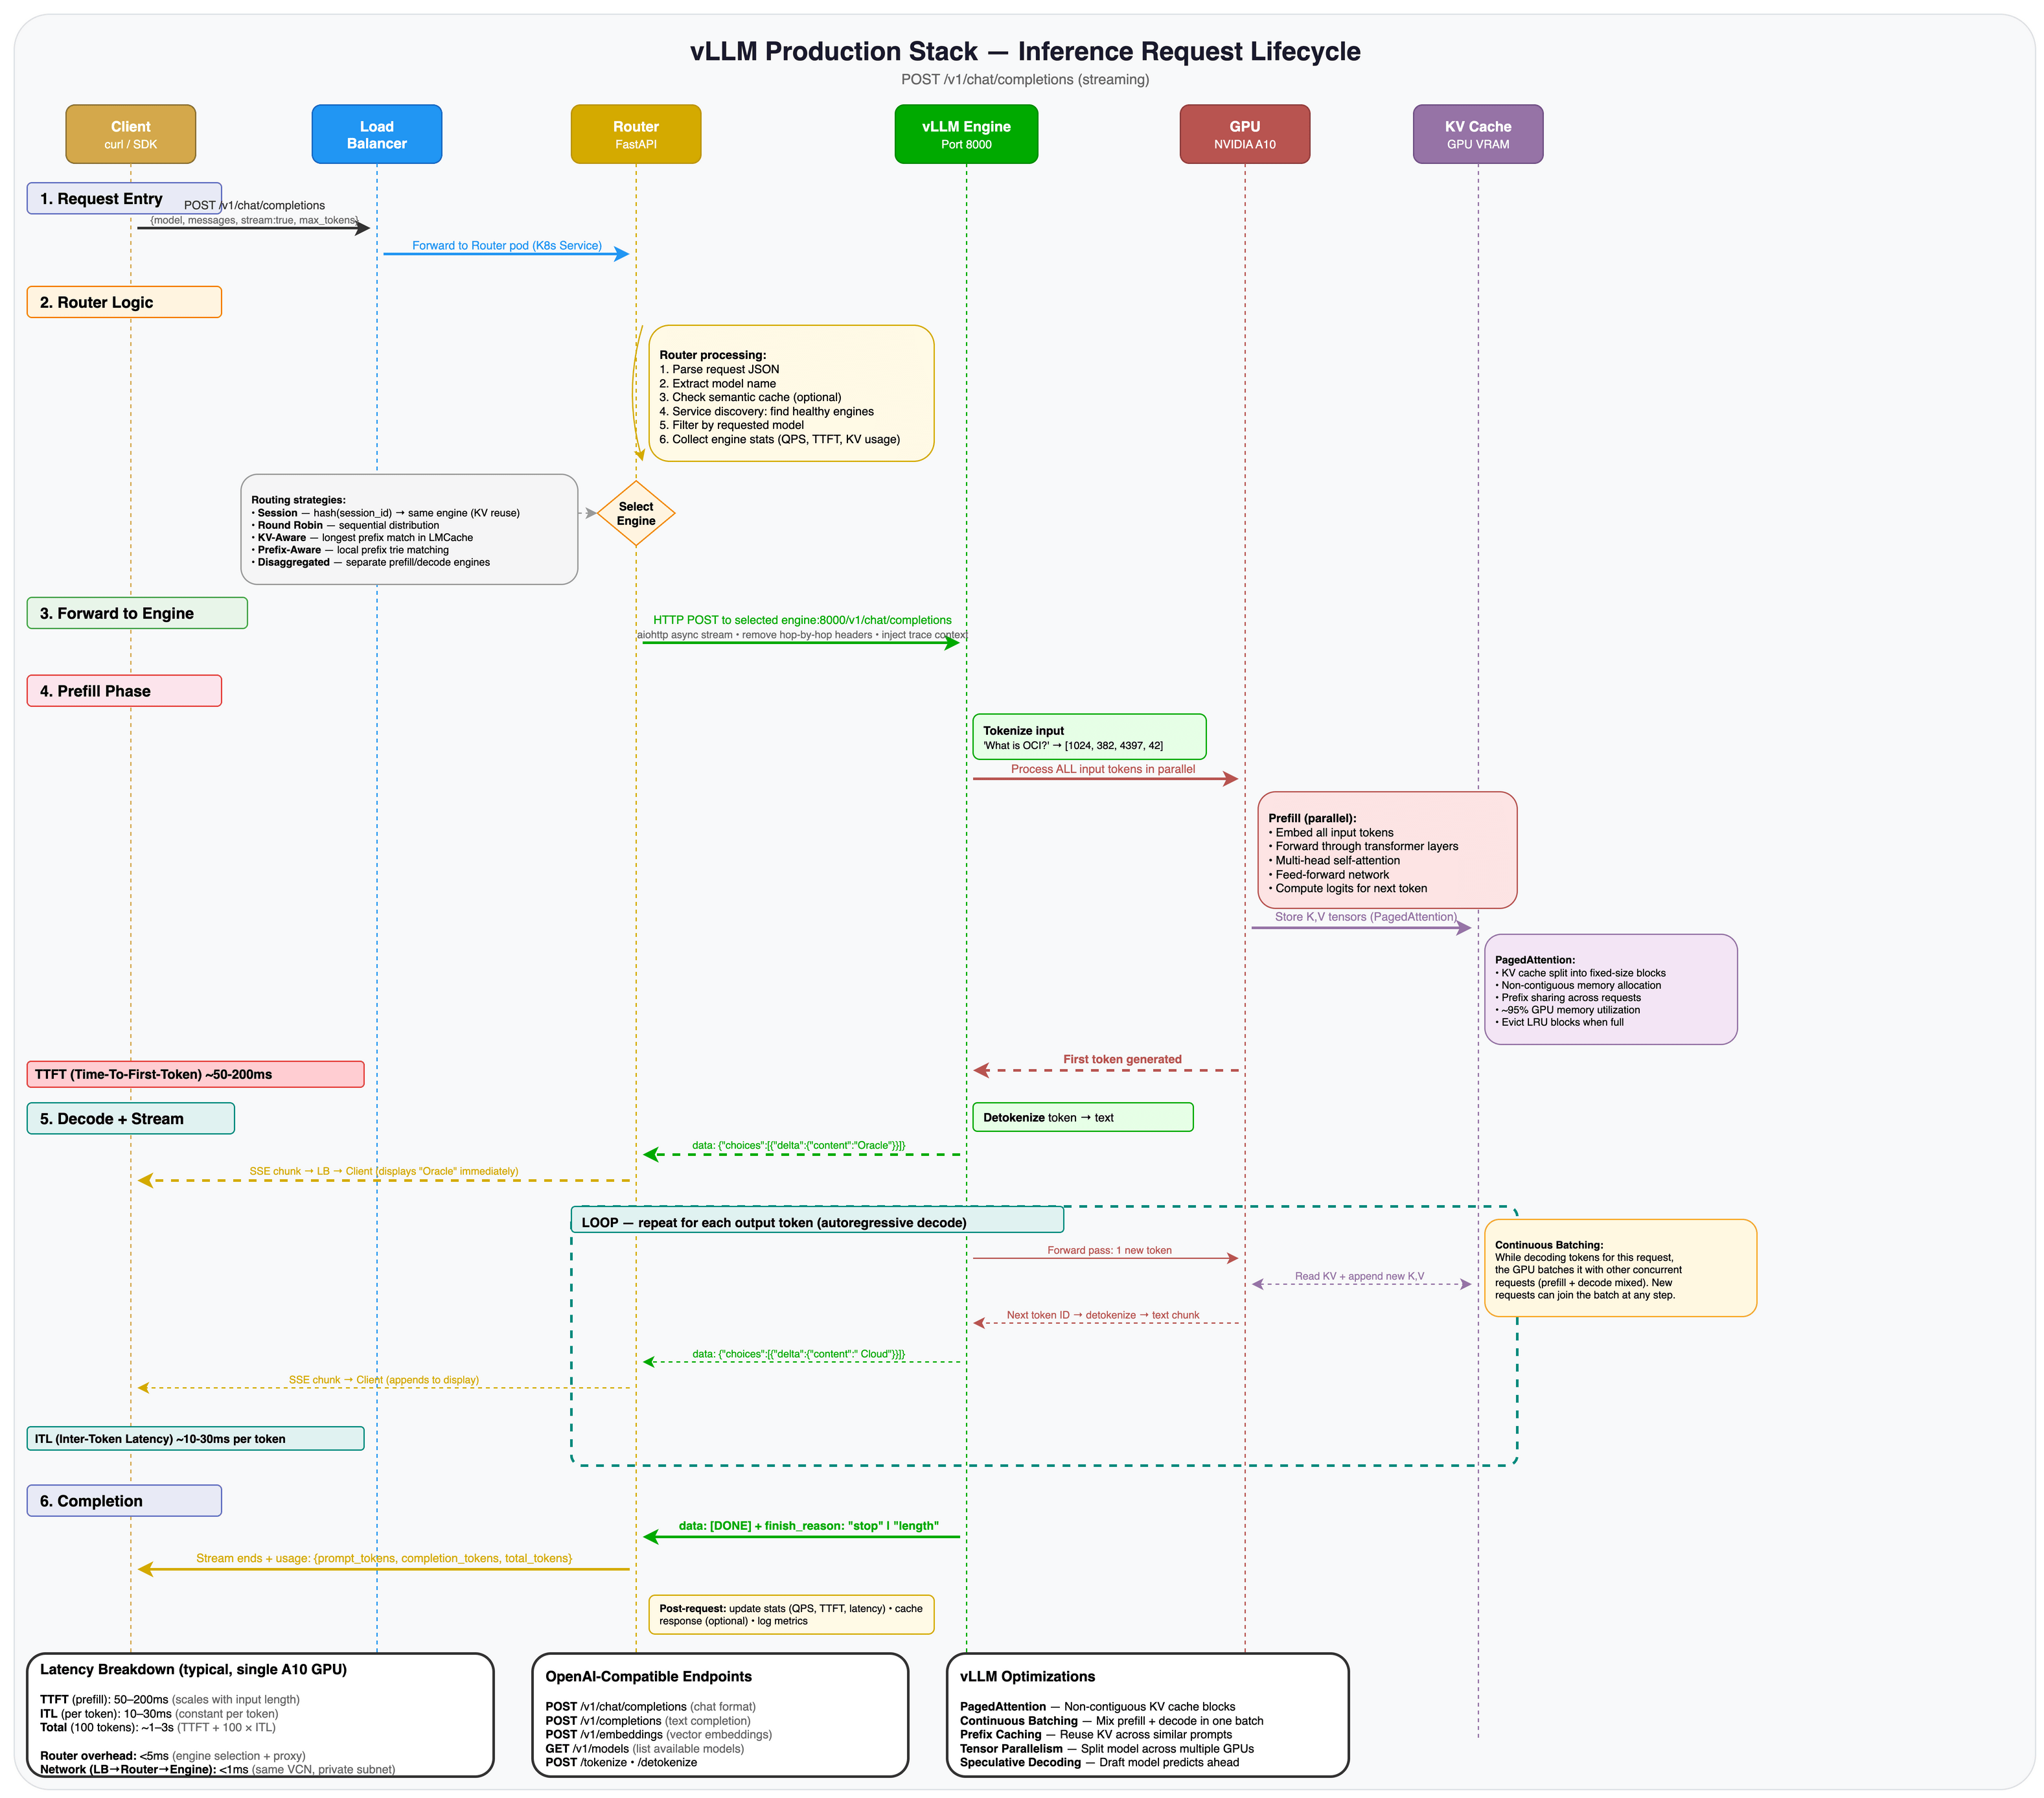
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)
Install vLLM on Gigabyte AI TOP ATOM: High-Performance LLM Inference ...
How to Implement vLLM with OpenAI-Compatible API
GitHub - anishgillella/vllm: Production-ready vLLM inference server on ...
Run OpenAI-compatible LLM inference with Gemma and vLLM | Modal Docs
How to batch using the OpenAI api? · Issue #2999 · vllm-project/vllm ...
Offline Batch Inference | vllm-project/tpu-inference | DeepWiki
vLLM Installation for High-Performance LLM Inference - CubePath Docs ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...
[Usage]: how to use openai compatible api to run GGUF model? · Issue ...
Advertisement Space (336x280)
[Bug]: When using multi-node offline distributed inference, VLLM gets ...
Build a Self-Hosted OpenAI-Compatible API with vLLM in 2026 | Spheron Blog

vLLM V1: Accelerating multimodal inference for large language models ...
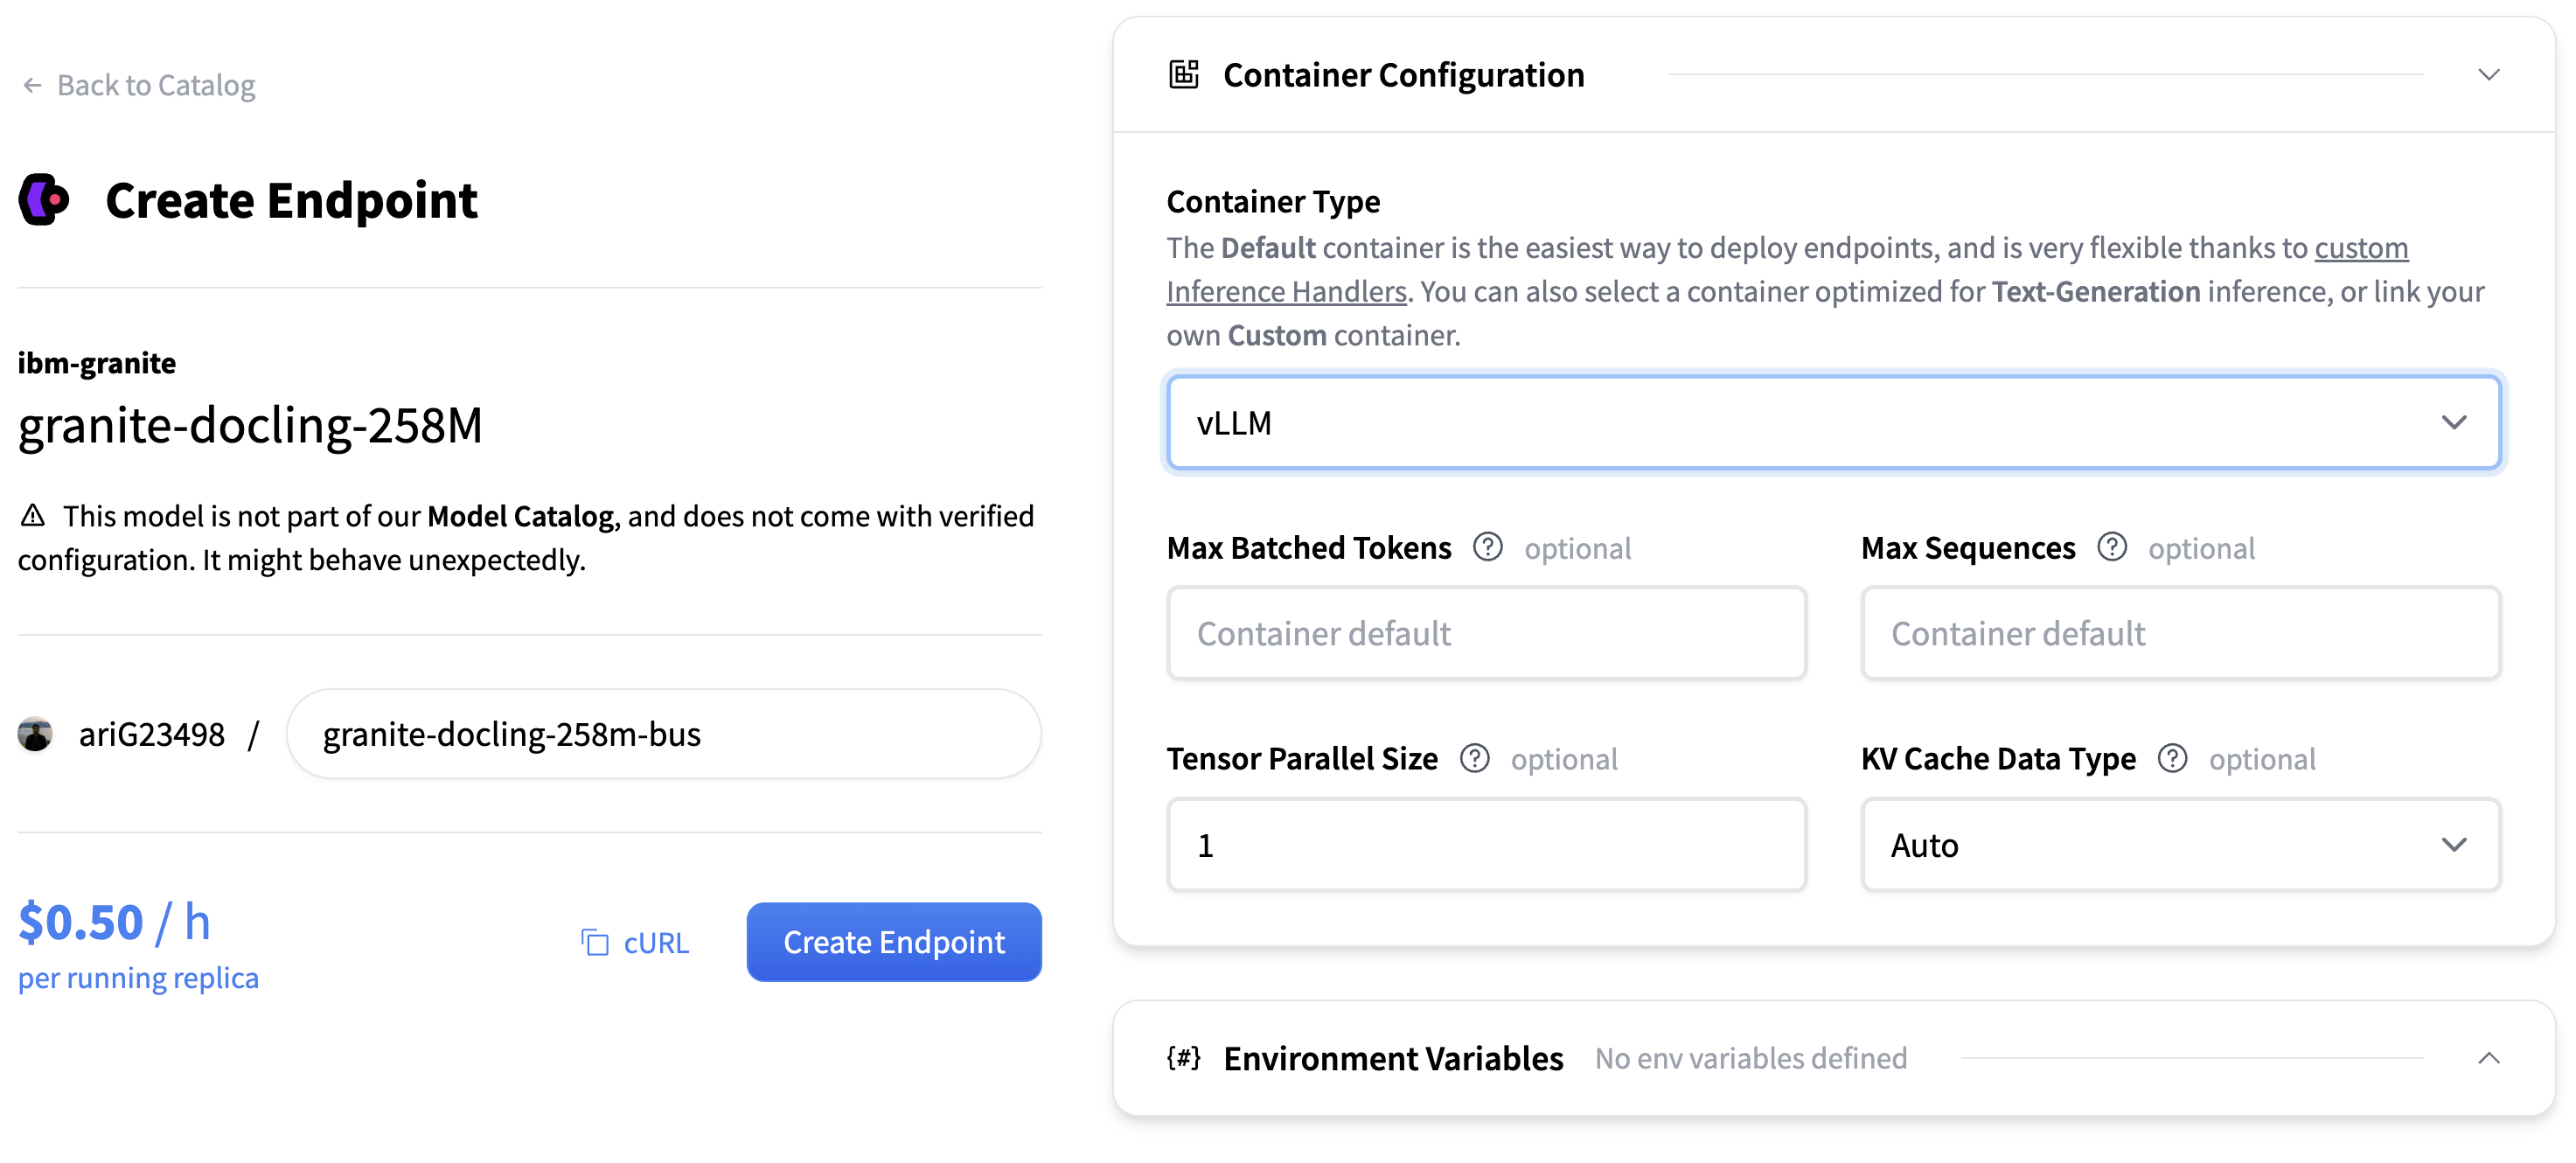
Hugging Face Inference Endpoints - vLLM
[Bug]: Gemma3 Batch Offline Inference Error: Cascade attention does not ...

Accelerating LLM Inference with vLLM - APC 技術ブログ