
Feature Is Vllm Support Sequence Parallel Issue 3940 Vllm
[Feature]: is vllm support sequence-parallel? · Issue #3940 · vllm ...
[Bug]: vLLM 0.5.1 tensor parallel 2 hang · Issue #6370 · vllm-project ...
[Usage]: Does vLLM support multi-task · Issue #13390 · vllm-project ...
[Misc]: How is the continous batching feature of vLLM implemented ...
[Feature]: vLLM does not support torch 2.7.1 · Issue #20566 · vllm ...
the output of the vLLM is different from that of HF · Issue #2196 ...
[Usage]: Does vllm support mix deploy on GPU+CPU? · Issue #13517 · vllm ...
Is vLLM single-threaded? · Issue #640 · vllm-project/vllm · GitHub

Context Parallel - vLLM Ascend - vLLM 文档

Context Parallel - vLLM Ascend - vLLM 文档
Advertisement Space (300x250)

vLLM (3) - Sequence & SequenceGroup - 知乎

Context Parallel - vLLM Ascend - vLLM 文档
vLLM Production Deployment 2026: Multi-GPU Tensor Parallel + FP8 Docker ...
[Feature]: Will future versions of vllm support FlashMLA, the inference ...

vLLM 05 - vLLM multi-modal support - gdymind's Blog
[Feature]: vLLM ResponsesAPI & Tool Calling H1 2026 lookahead · Issue ...
VLLM tensor-parallel and RegexLogitsProcessor · Issue #524 · dottxt-ai ...
[Feature]: When vllm plan to support AMD APU - AMD Ryzen AI Max 395 ...
Big Win for Secure AI Inference: vLLM Adds Prompt Embedding Support ...

vLLM 05 - vLLM multi-modal support - gdymind's Blog
Advertisement Space (336x280)
Max prompt tokens/sequence length limit in vllm core scheduler · Issue ...
[Usage]: How to start vLLM on a particular GPU? · Issue #4981 · vllm ...
pipeline parallel support in the future? · Issue #387 · vllm-project ...
[Question][Schedule] vLLM cannot schedule a whole sequence group but ...

vLLM 05 - vLLM multi-modal support - gdymind's Blog
[Feature]: continuous batching for vllm.LLM · Issue #7353 · vllm ...
how can vllm support function_call · vllm-project vllm · Discussion ...
AssertionError: data parallel group is already initialized · Issue #549 ...
[RFC]: Pipeline-Parallelism for vLLM V1 · Issue #11945 · vllm-project ...
[Usage]: Does vLLM support deploying the speculative model on a second ...
Advertisement Space (336x280)
Serving multiple models in vLLM with single or multiple engines · Issue ...
vLLM Distributed Inference stuck when using multi -GPU · Issue #2466 ...
[Feature]: ROPE scaling supported by vLLM gemma2 · Issue #6175 · vllm ...

Data Parallel Deployment - vLLM
Will vLLM supports Self-Speculative Decoding ? · Issue #2559 · vllm ...
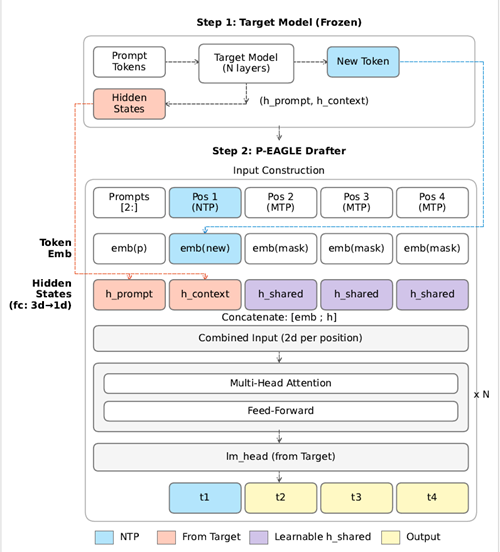
P-EAGLE: Accelerating Parallel Inference for vLLM - Acloud Blog!