
Figure 1 From A Target Speaker Separation Neural Network With Joint
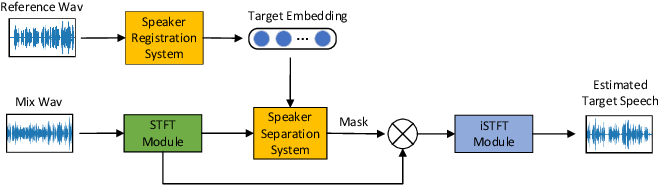
Figure 1 from A Target Speaker Separation Neural Network with Joint ...
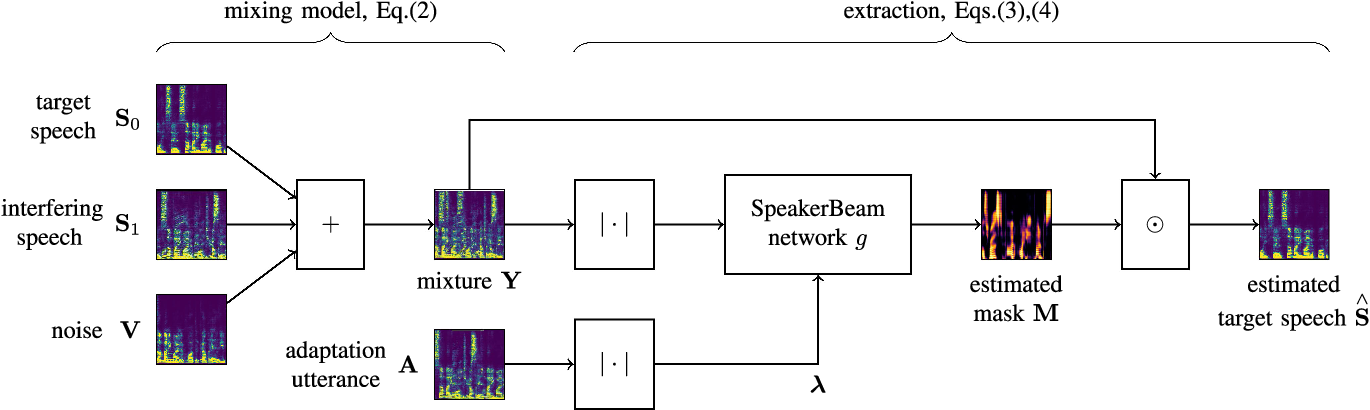
Figure 1 from SpeakerBeam: Speaker Aware Neural Network for Target ...
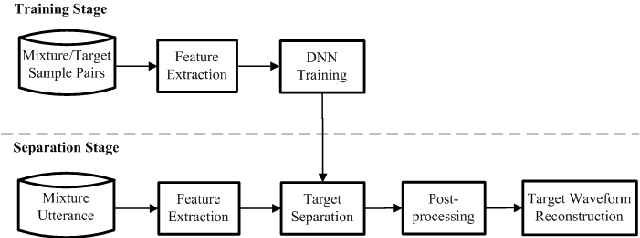
Figure 1 from Speech separation of a target speaker based on deep ...

Figure 1 from Single-Channel Target Speaker Separation Using Joint ...
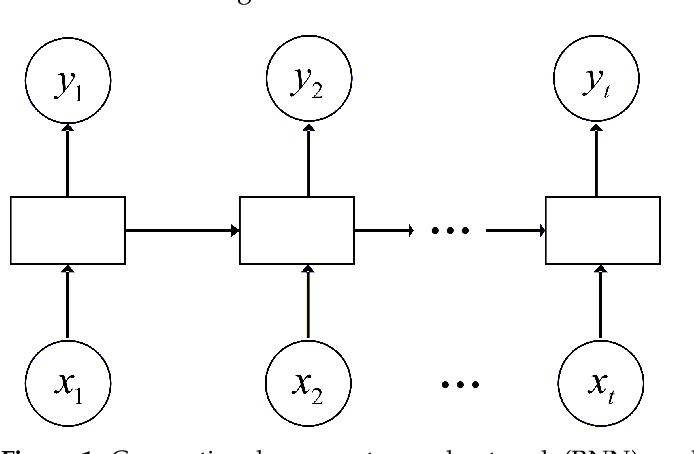
Figure 1 from A Deep Neural Network Model for Speaker Identification ...
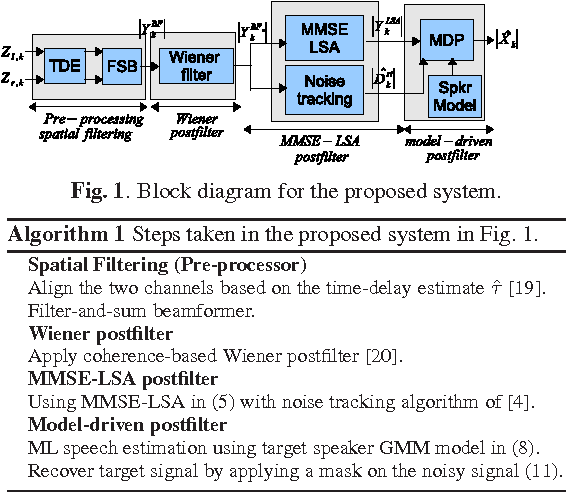
Figure 1 from Target speaker separation in a multisource environment ...

Figure 1 from Joint single-channel speech separation and speaker ...

Figure 1 from Target Speaker Voice Activity Detection with Transformers ...
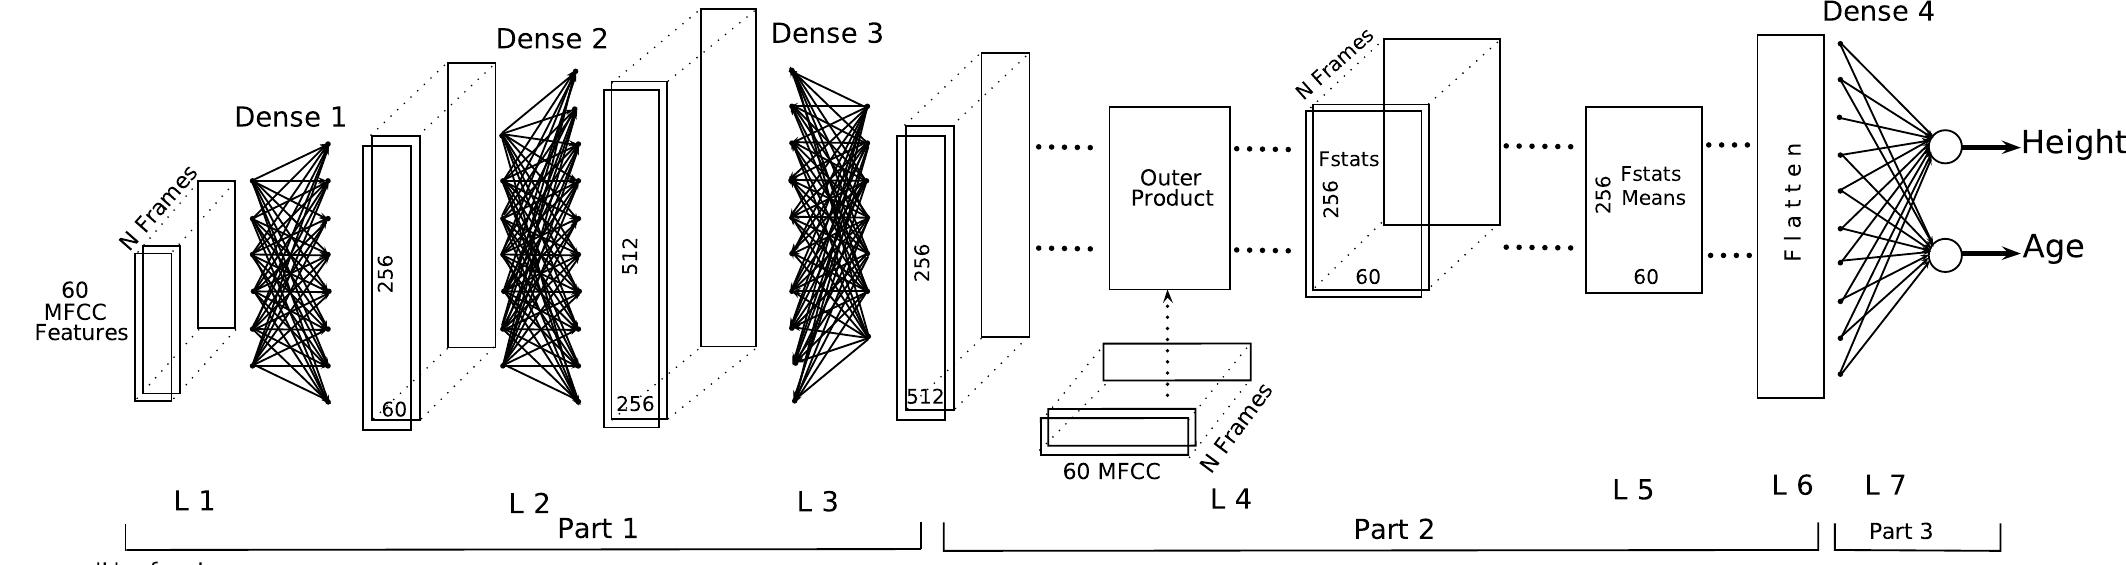
Figure 1 - from A Deep Neural Network Based End to End Model
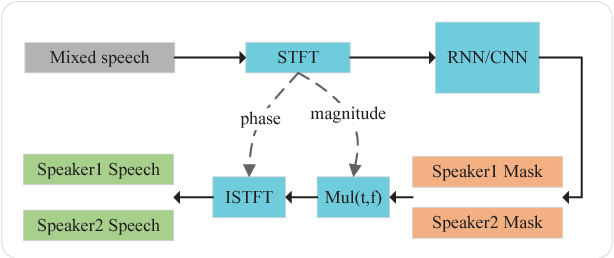
Figure 1 from Improving Speech Separation with Adversarial Network and ...
Advertisement Space (300x250)
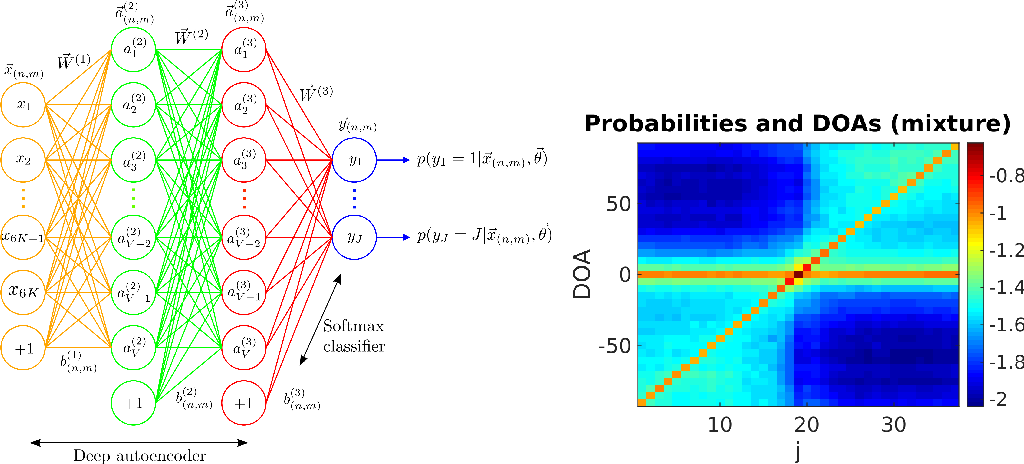
Figure 1 from Deep neural network based audio source separation ...
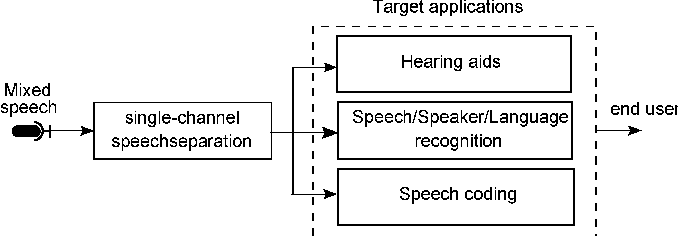
Figure 1 from A Joint Approach for Single-Channel Speaker ...

Figure 1 from Target Speaker Extraction with Curriculum Learning ...

Figure 3 from Monaural Speech Separation Joint With Speaker Recognition ...

Figure 1 from Target Speaker Extraction with Attention Enhancement and ...

Figure 1 from TS-SEP: Joint Diarization and Separation Conditioned on ...
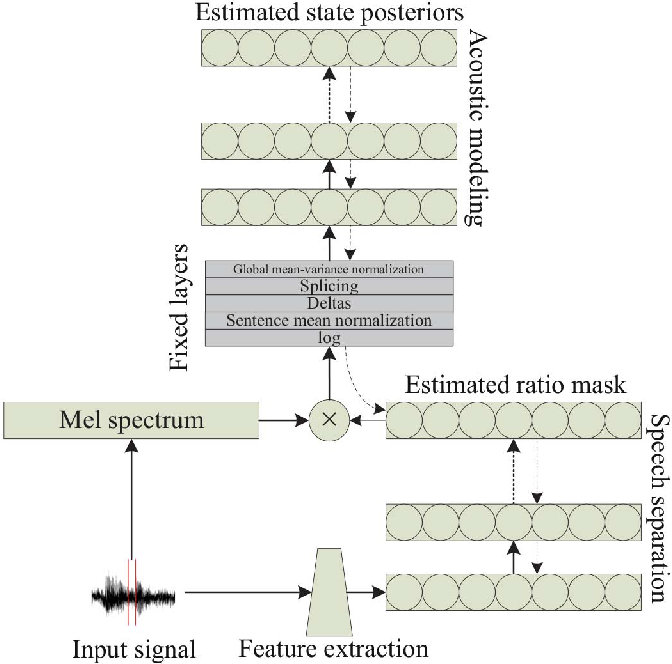
Figure 1 from Improving Robustness of Deep Neural Network Acoustic ...

Figure 1 from Hierarchical Speaker Representation for Target Speaker ...

Neural Spatial Filter: Target Speaker Speech Separation Assisted with ...
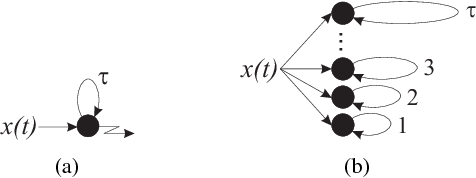
Figure 1 from Recurrent Timing Neural Networks for Joint F0 ...
Advertisement Space (336x280)
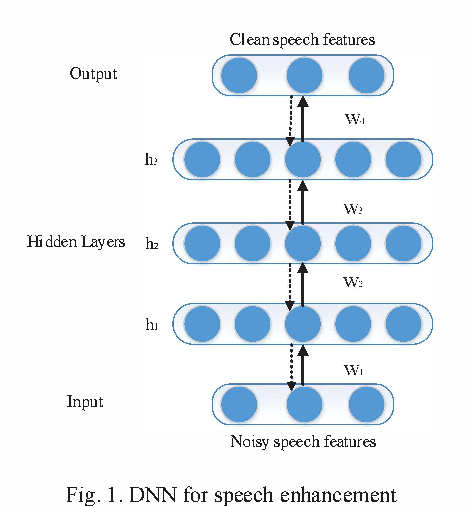
Figure 1 from A novel single channel speech enhancement based on joint ...
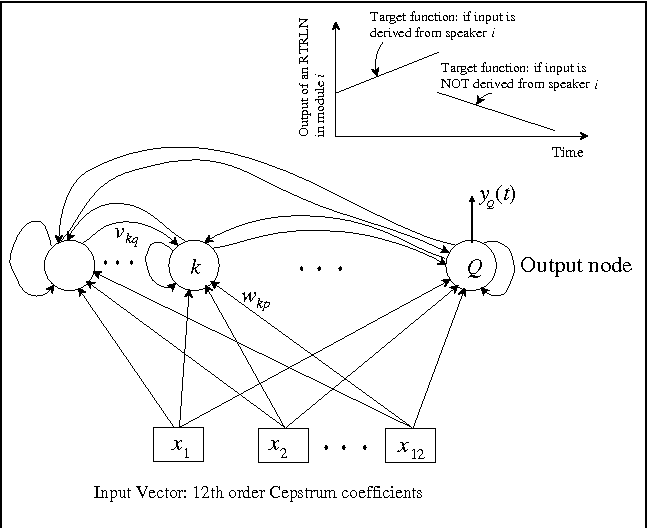
Figure 1 from Speaker identification using modular recurrent neural ...
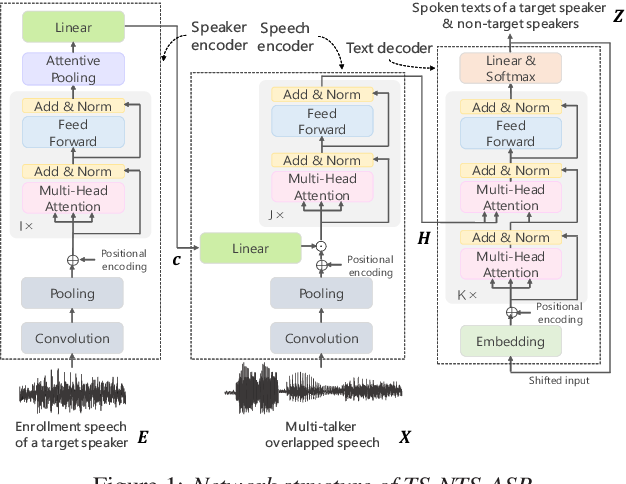
Figure 1 from End-to-End Joint Target and Non-Target Speakers ASR ...
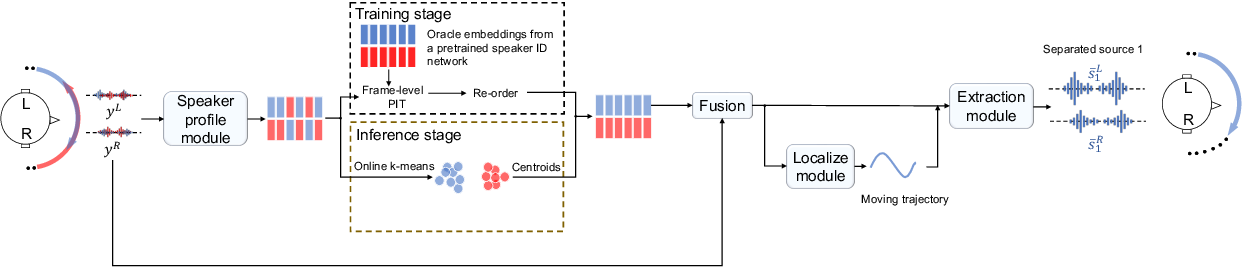
Figure 1 from Online Binaural Speech Separation Of Moving Speakers With ...

Figure 1 from Knowledge Distillation for Neural Transducer-based Target ...
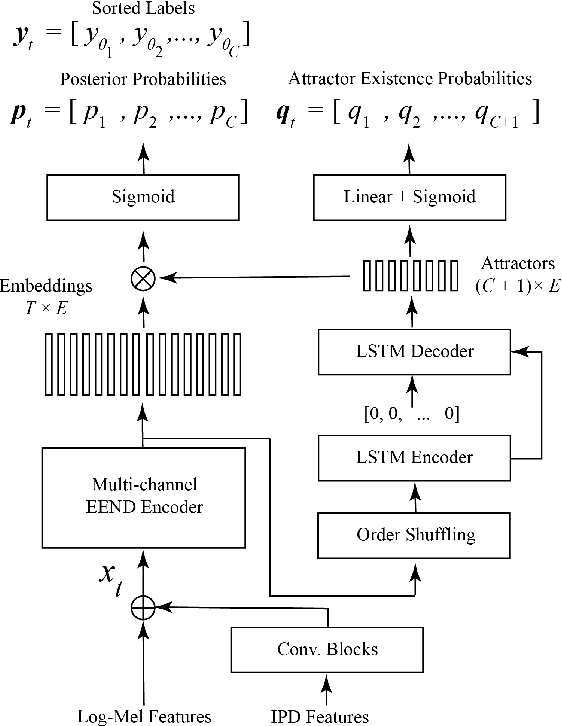
Figure 1 from Multi-Channel Conversational Speaker Separation via ...

(PDF) Speech separation of a target speaker based on deep neural networks
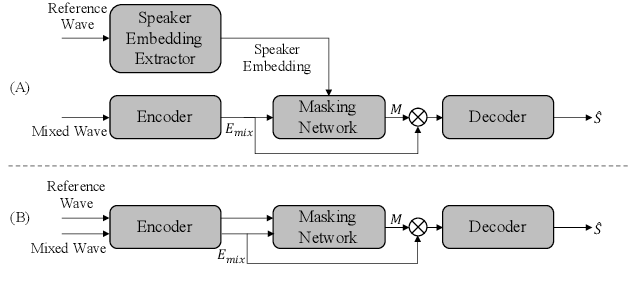
Figure 1 from SEF-Net: Speaker Embedding Free Target Speaker Extraction ...

Figure 1 from An Efficient Speech Separation Network Based on Recurrent ...
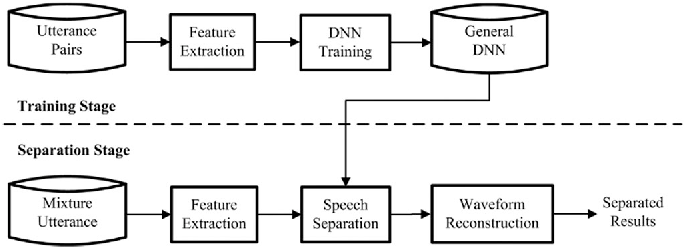
Figure 1 from A Regression Approach to Single-Channel Speech Separation ...
Advertisement Space (336x280)
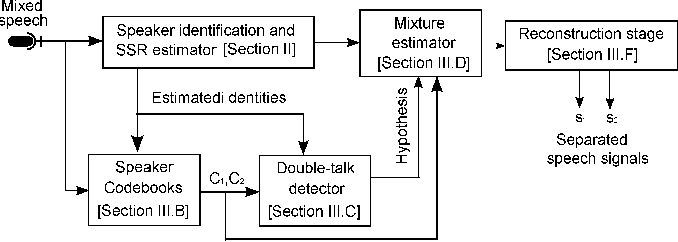
Figure 2 from A Joint Approach for Single-Channel Speaker ...
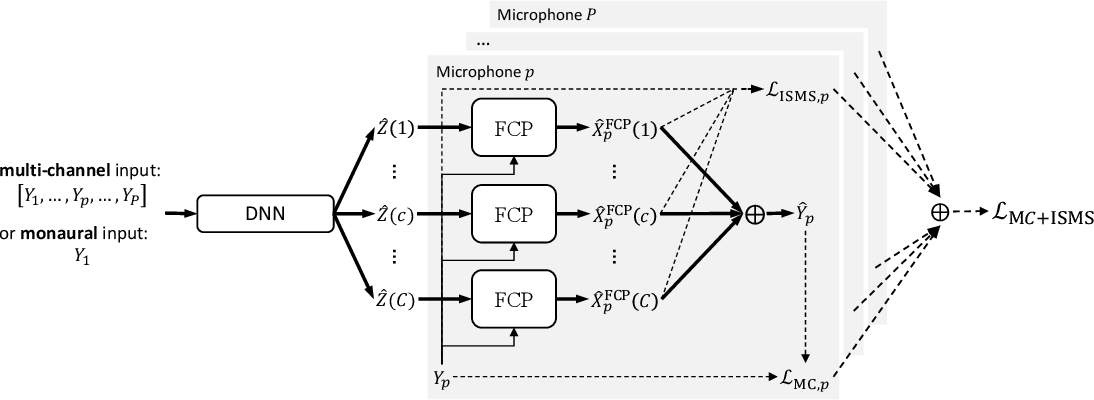
Figure 1 from UNSSOR: Unsupervised Neural Speech Separation by ...

Figure 1 from Audio-visual speech separation based on joint feature ...
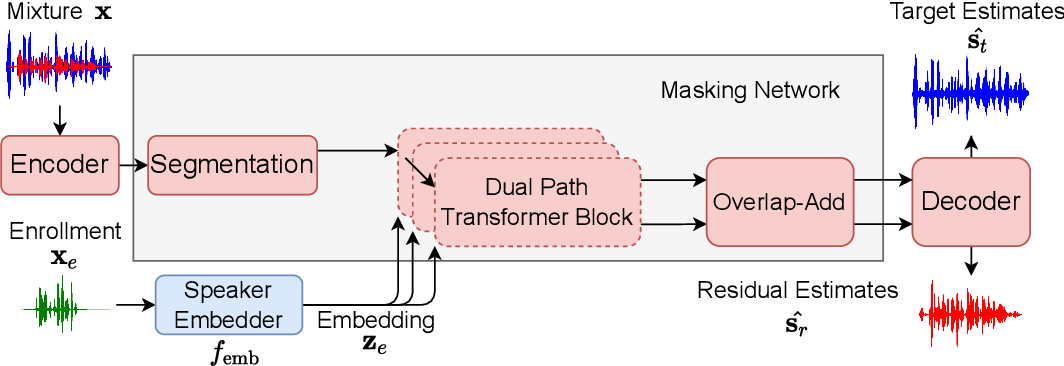
Figure 1 from Semi-supervised Time Domain Target Speaker Extraction ...

Figure 1 from Deep Neural Networks for Joint Voice Activity Detection ...

Figure 1 from Speaker-Independent Speech Separation With Deep Attractor ...