
Figure 1 From Single Channel Target Speaker Separation Using Joint

Figure 1 from Single-Channel Target Speaker Separation Using Joint ...
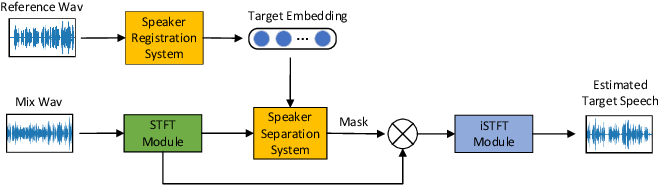
Figure 1 from A Target Speaker Separation Neural Network with Joint ...

Figure 1 from Single Channel Speech Separation Using Source-Filter ...

Figure 1 from Single Channel Target Speaker Extraction Based on Deep ...

Figure 1 from Joint single-channel speech separation and speaker ...
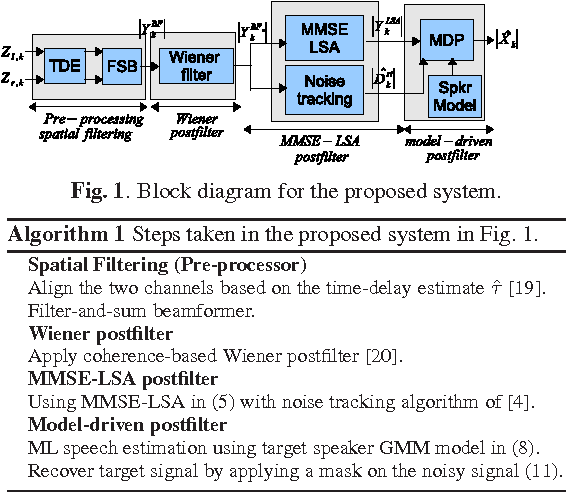
Figure 1 from Target speaker separation in a multisource environment ...
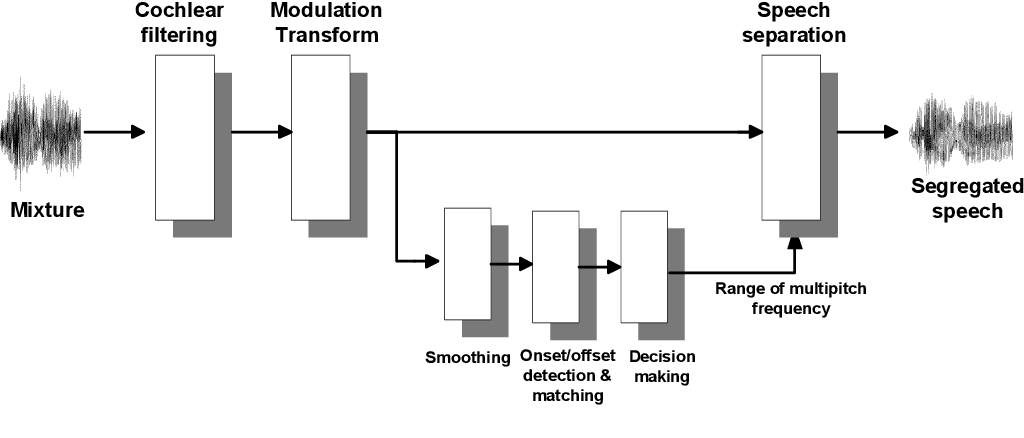
Figure 1 from Single channel speech separation with a frame-based pitch ...
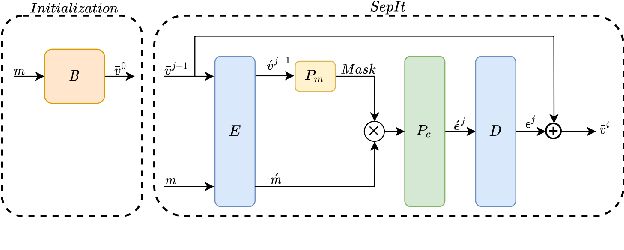
Figure 1 from SepIt: Approaching a Single Channel Speech Separation ...
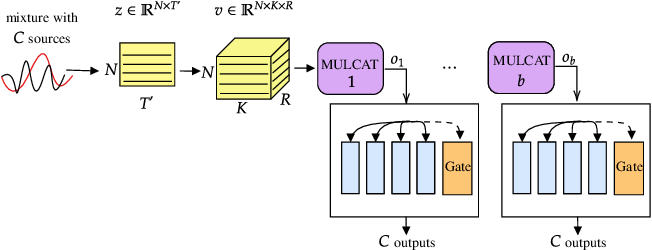
Figure 1 from Single Channel Voice Separation for Unknown Number of ...

Figure 3 from Single Channel Target Speaker Extraction and Recognition ...
Advertisement Space (300x250)
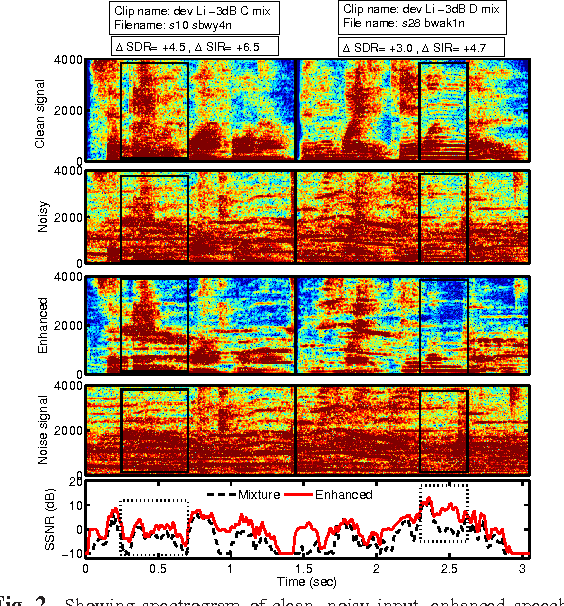
Figure 1 from Target speaker separation in a multisource environment ...

Figure 3 from Single Channel Source Separation using Short-time ...
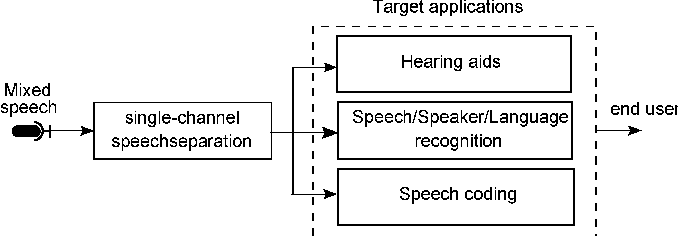
Figure 1 from A Joint Approach for Single-Channel Speaker ...

(PDF) Single-Channel Target Speaker Separation Using Joint Training ...
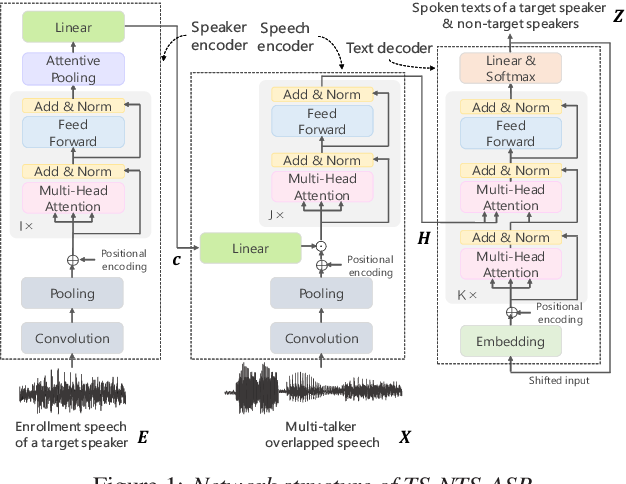
Figure 1 from End-to-End Joint Target and Non-Target Speakers ASR ...

Figure 1 from Speaker-conditioning Single-channel Target Speaker ...
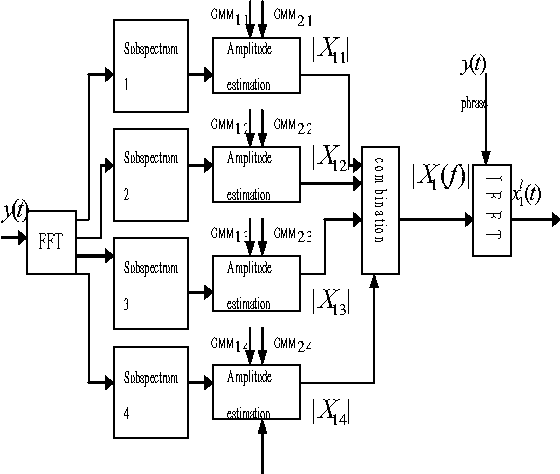
Figure 1 from Single-channel speaker separation based on sub-spectrum ...

Figure 1 from Audio-visual speech separation based on joint feature ...

Figure 1 from Single-channel speech separation using phase-based ...

Figure 1 from TS-SEP: Joint Diarization and Separation Conditioned on ...
Advertisement Space (336x280)
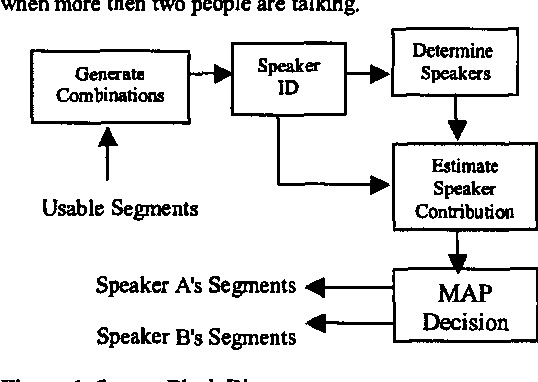
Figure 1 from Co-channel speaker segment separation | Semantic Scholar
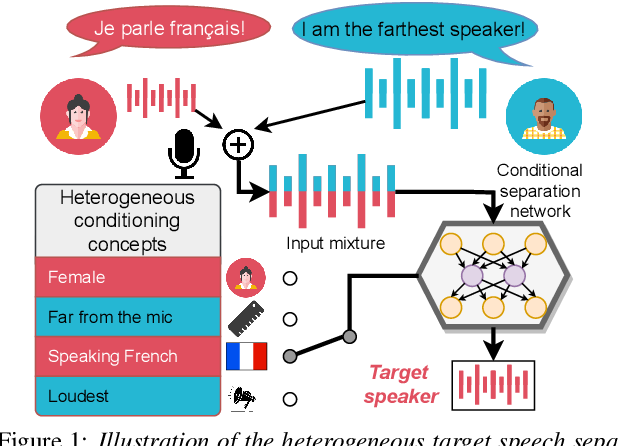
Figure 1 from Heterogeneous Target Speech Separation | Semantic Scholar
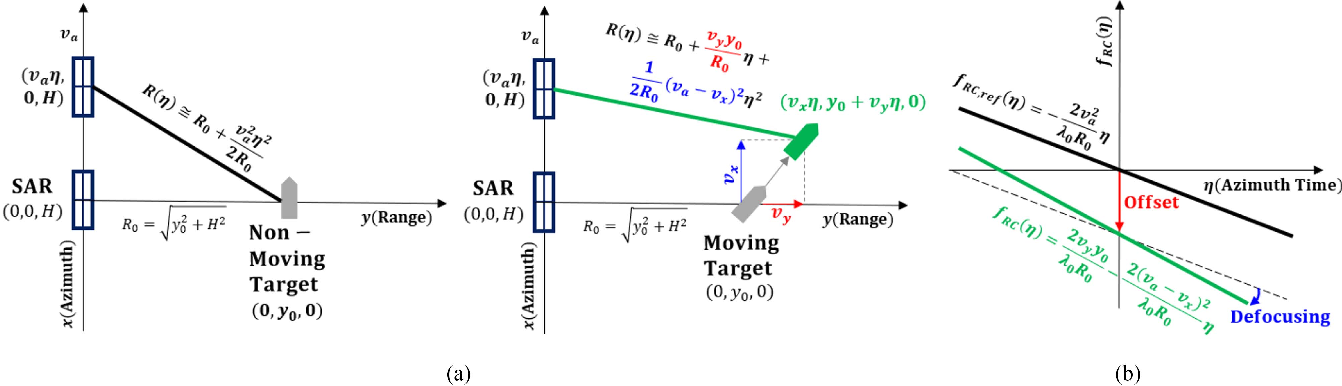
Figure 1 from Single-Channel SAR Moving Target Indication Using ...

Figure 1 from Binaural Selective Attention Model for Target Speaker ...

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...
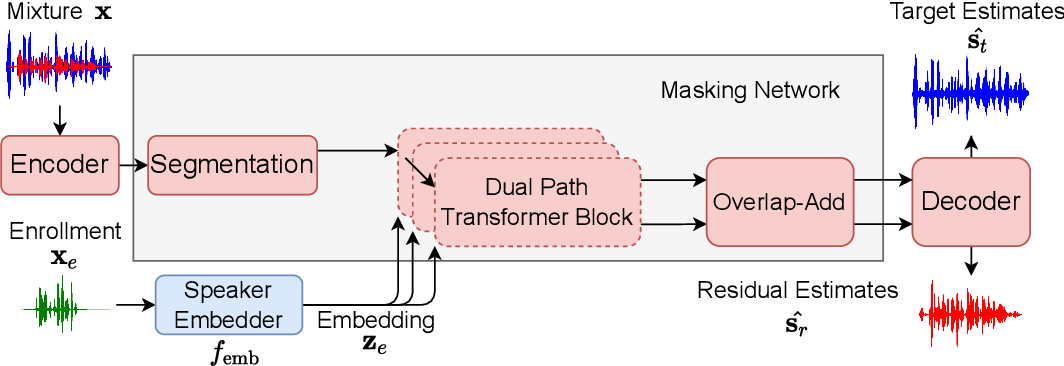
Figure 1 from Semi-supervised Time Domain Target Speaker Extraction ...
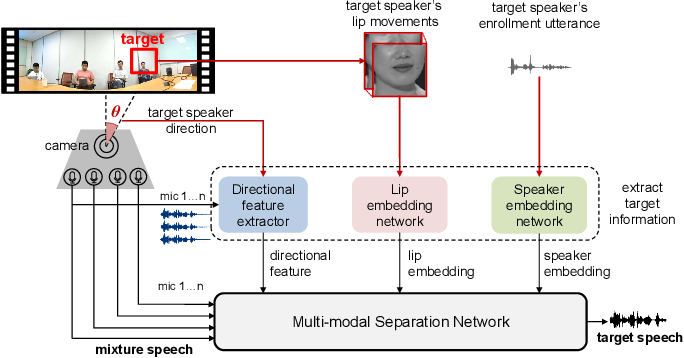
Figure 1 from Multi-Modal Multi-Channel Target Speech Separation ...
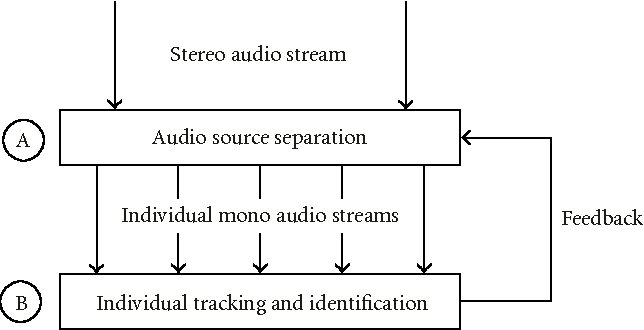
Figure 1 from Speaker Separation and Tracking System | Semantic Scholar

Figure 1 from Hierarchical Speaker Representation for Target Speaker ...
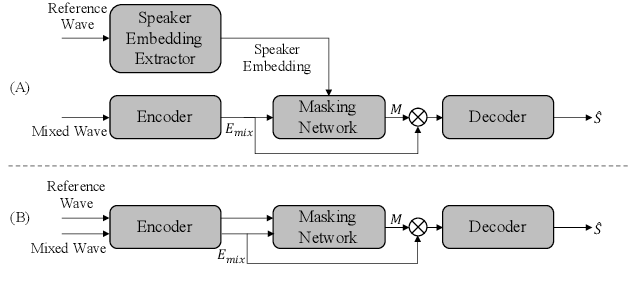
Figure 1 from SEF-Net: Speaker Embedding Free Target Speaker Extraction ...
Advertisement Space (336x280)

Figure 1 from Audio-Visual Target Speaker Extraction with Reverse ...

Figure 1 from Target Speaker Voice Activity Detection with Transformers ...

Figure 1 from Target Active Speaker Detection with Audio-visual Cues ...

Figure 1 from Single-Channel Muti-speaker Separation via Discriminative ...

Figure 1 from Multi-Cue Guided Semi-Supervised Learning Toward Target ...
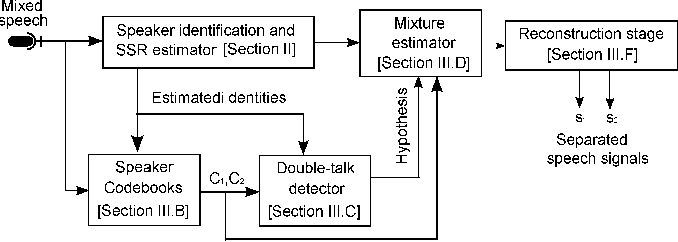
Figure 2 from A Joint Approach for Single-Channel Speaker ...