
Figure 1 From A Word Axis Speaker Embedding Trained With Multi Speaker

Figure 1 from A Word-axis Speaker Embedding Trained with Multi-Speaker ...

Figure 1 from Channel Invariant Speaker Embedding Learning with Joint ...

Figure 1 from Speaker Embedding Extraction with Phonetic Information ...

Figure 1 from Speaker Embedding Extraction with Phonetic Information ...
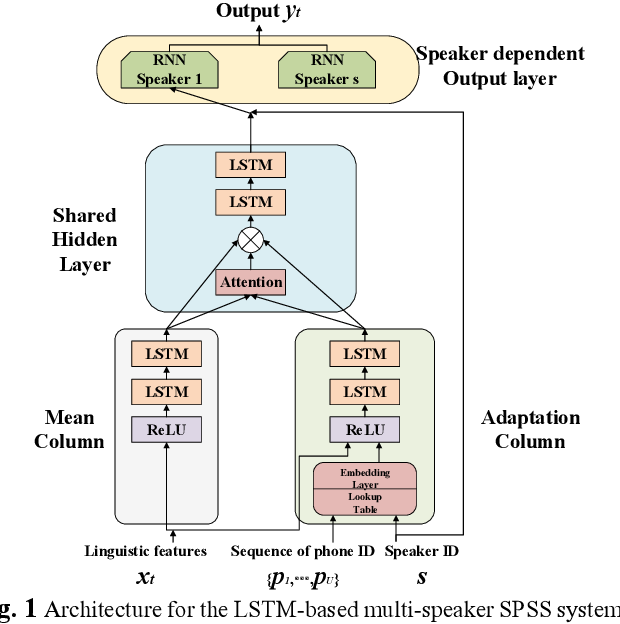
Figure 1 from Phoneme Dependent Speaker Embedding and Model ...
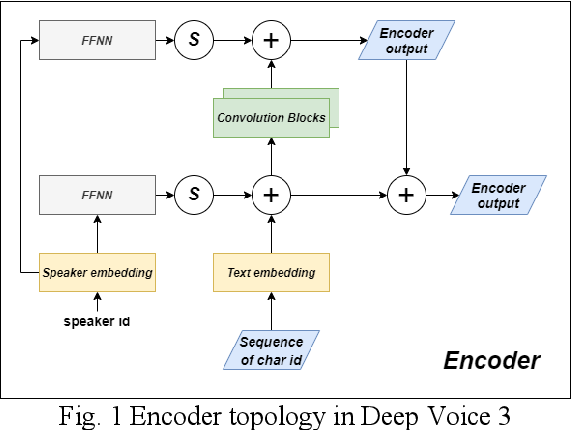
Figure 1 from Multi Speaker Speech Synthesis System for Indonesian ...

Figure 1 from Multi-Stage Speaker Extraction with Utterance and Frame ...
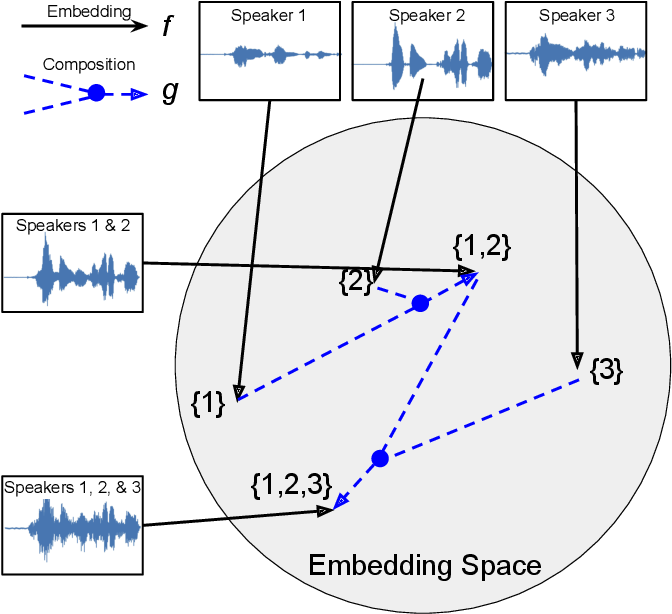
Figure 1 from Compositional Embedding Models for Speaker Identification ...
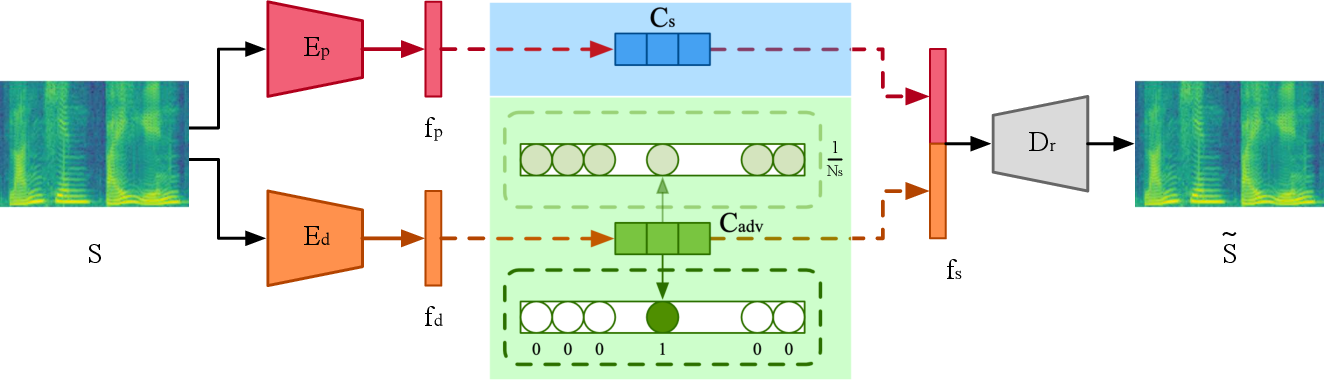
Figure 1 from Powerful Speaker Embedding Training Framework by ...

Figure 1 from Vision-Guided Speaker Embedding Based Speech Separation ...
Advertisement Space (300x250)

Figure 1 from Joint Training of Speaker Embedding Extractor, Speech and ...

Figure 1 from Low-complexity Multi-Channel Speaker Extraction with Pure ...
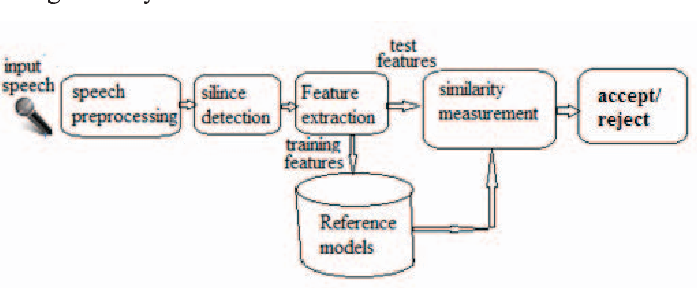
Figure 1 from An isolated word speaker recognition system | Semantic ...

Figure 1 from What Does the Speaker Embedding Encode? | Semantic Scholar

Figure 1 from Investigation on Deep Speaker Embedding Extraction ...

Table 1 from MC-SpEx: Towards Effective Speaker Extraction with Multi ...

Figure 1 from Joint Speech-Text Embeddings with Disentangled Speaker ...
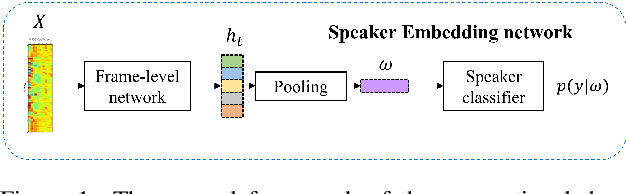
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
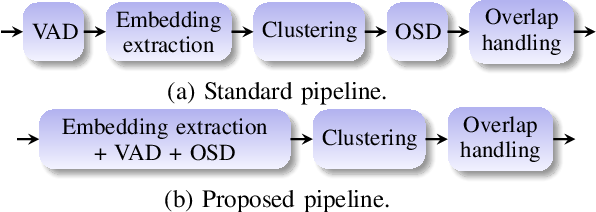
Figure 1 from Joint Training of Speaker Embedding Extractor, Speech and ...
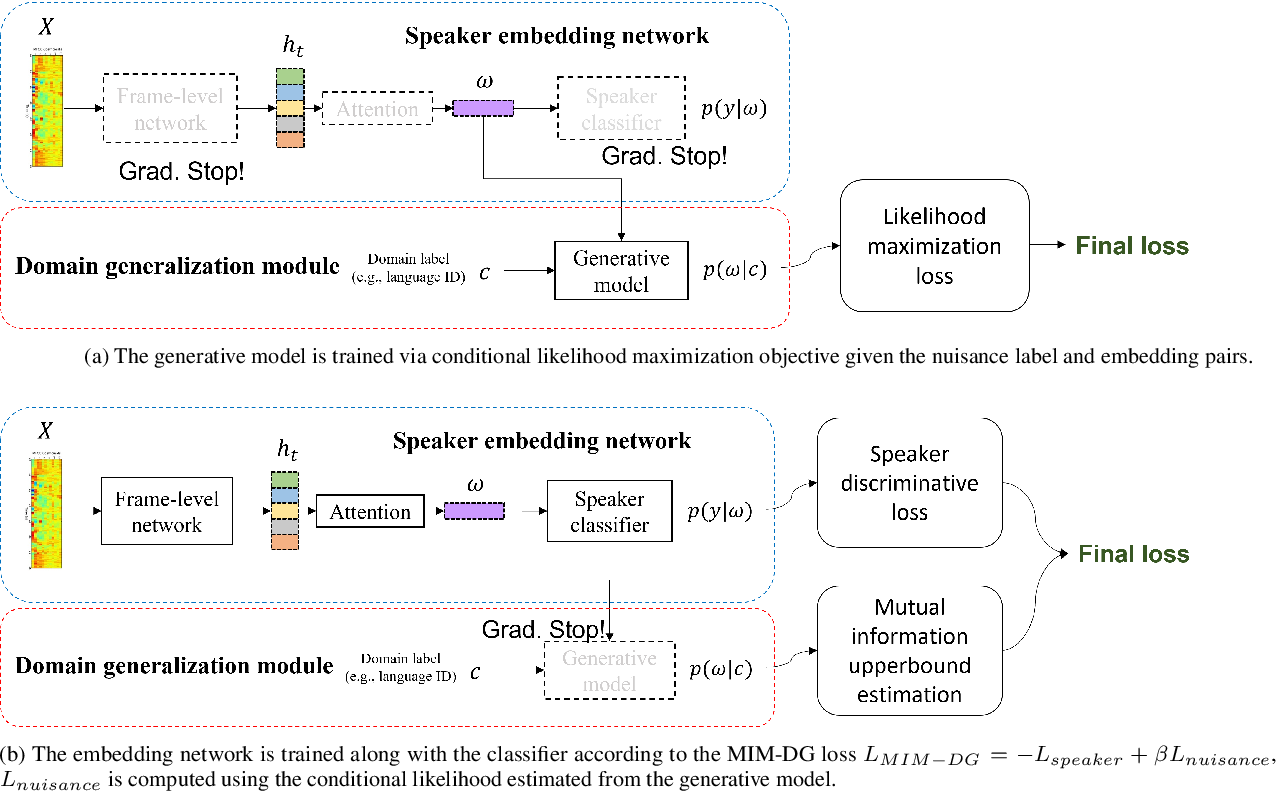
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
Advertisement Space (336x280)

Figure 1 from High-Resolution Embedding Extractor for Speaker ...

Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from End-to-End Multi-Speaker Speech Recognition using Speaker ...

Figure 1 from Multi-Scale Speaker Embedding-Based Graph Attention ...
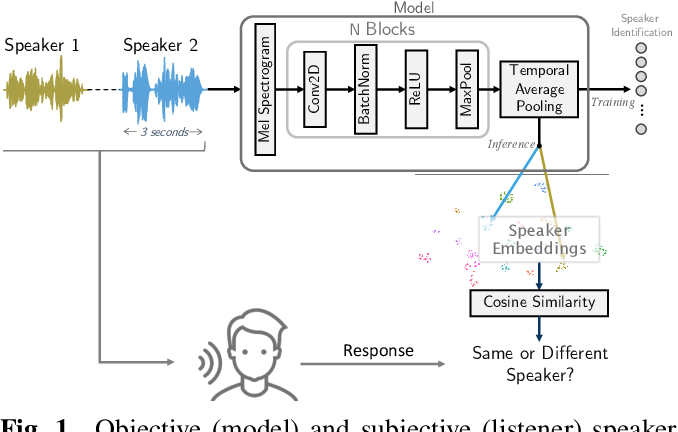
Figure 1 from Perceptual Analysis of Speaker Embeddings for Voice ...

Figure 1 from Face-Conditioned Large-Scale Text-to-Speech via Speaker ...

Figure 1 from Deeply Fused Speaker Embeddings for Text-Independent ...
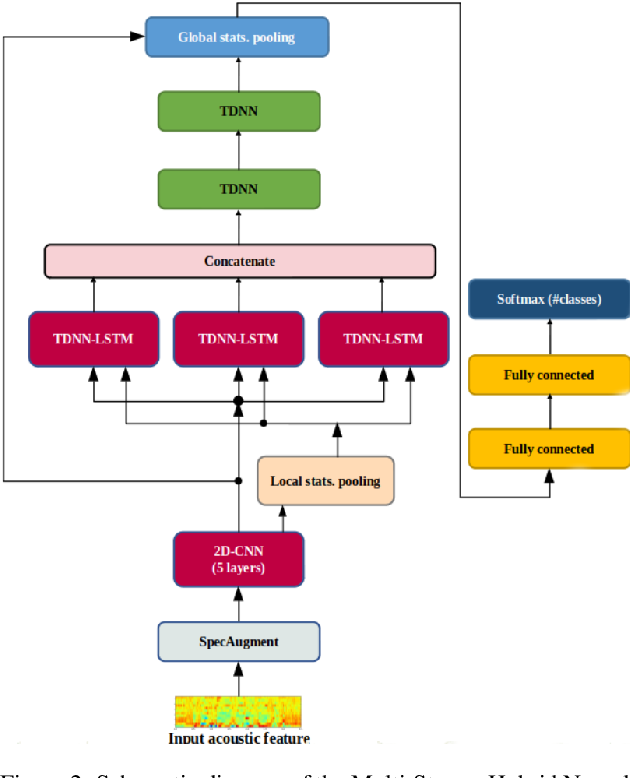
Figure 2 from Investigation on Deep Speaker Embedding Extraction ...

Figure 1 from Acoustic Word Embedding System for Code-Switching Query ...
Advertisement Space (336x280)

Figure 2 from Joint Speech-Text Embeddings with Disentangled Speaker ...
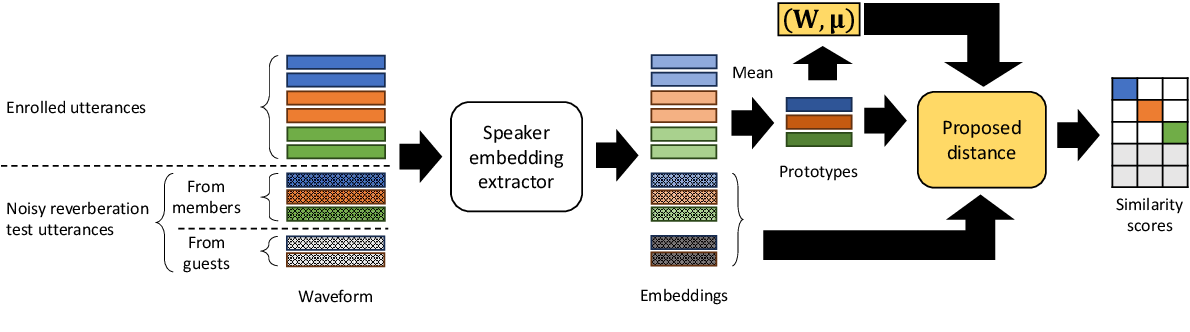
Figure 1 from Speaker Verification Using Distance Based on Principal ...
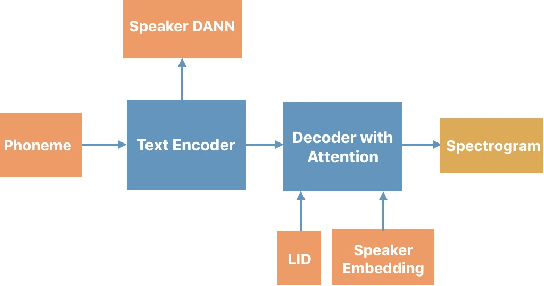
Figure 1 from Generating Multilingual Voices Using Speaker Space ...
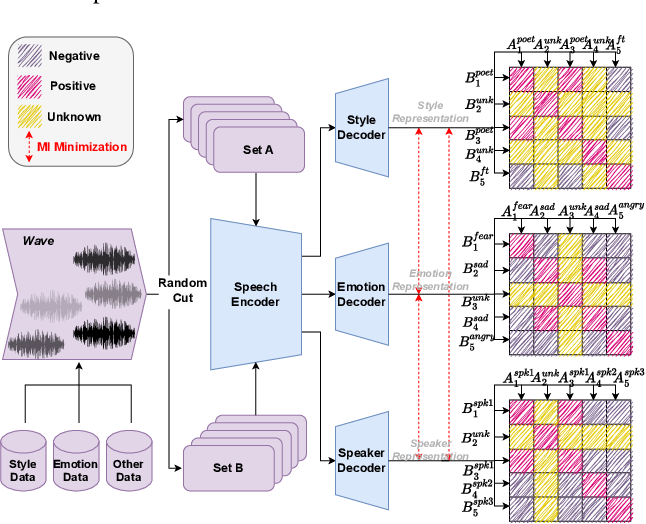
Figure 1 from Boosting Multi-Speaker Expressive Speech Synthesis with ...
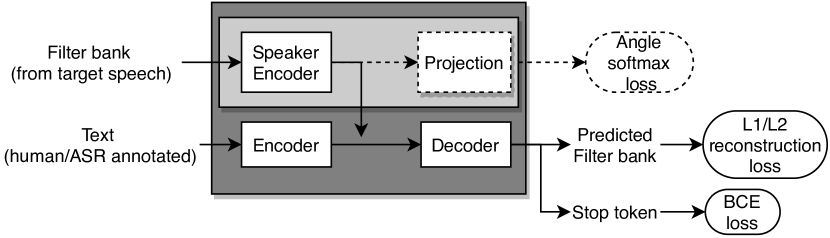
[2010.11221] Learning Speaker Embedding from Text-to-Speech
Proposed method to weakly supervised training of a speaker embedding ...