
Figure 1 From Compositional Embedding Models For Speaker Identification
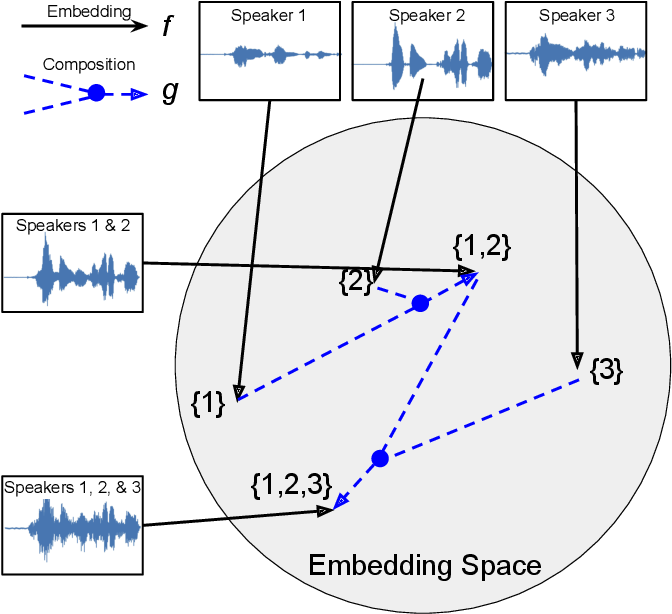
Figure 1 from Compositional Embedding Models for Speaker Identification ...
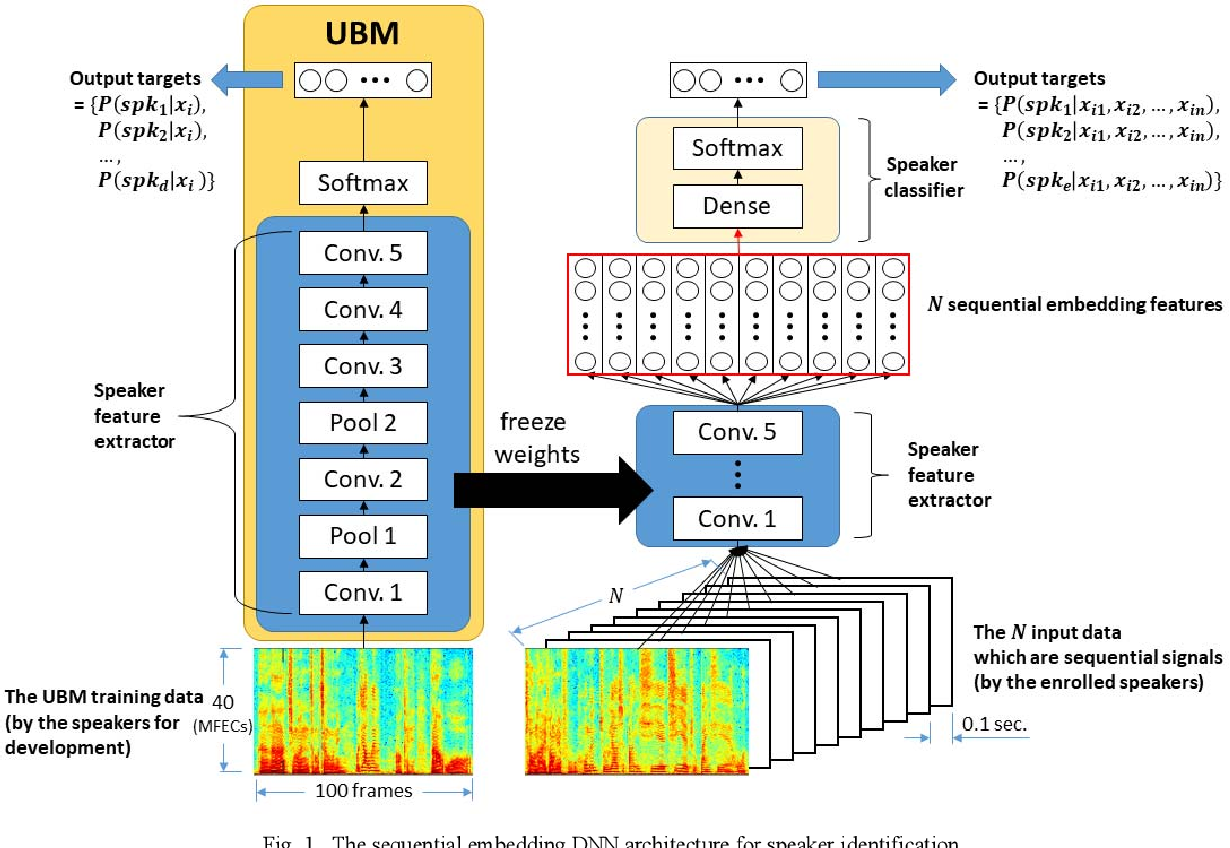
Figure 1 from Sequential Speaker Embedding and Transfer Learning for ...

Figure 1 from Unsupervised Arabic Speech Embedding Model for Speaker ...

Compositional embedding models for speaker identification and ...

Compositional Embedding Models For Speaker Identification And ...

Compositional embedding models for speaker identification and ...
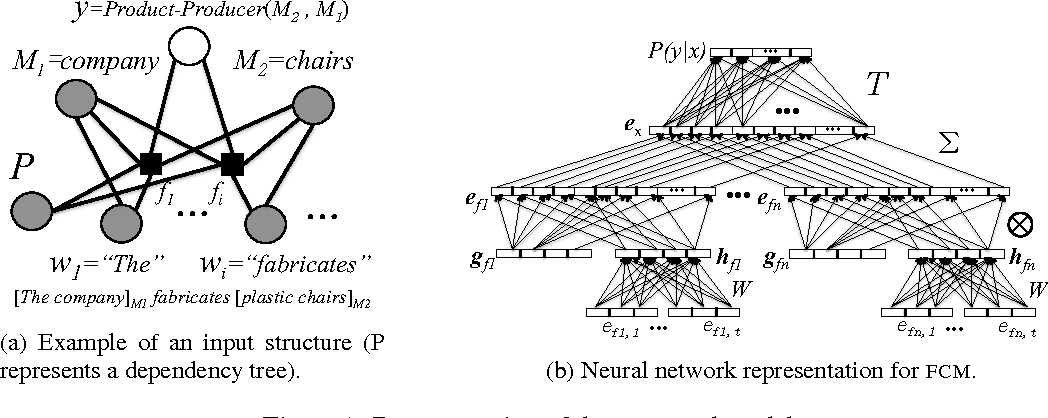
Figure 1 from Factor-based Compositional Embedding Models | Semantic ...
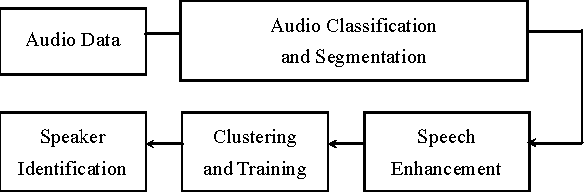
Figure 1 from A Speaker Identification System for Video Content ...

Figure 1 from Speaker Embedding-aware Neural Diarization for Flexible ...
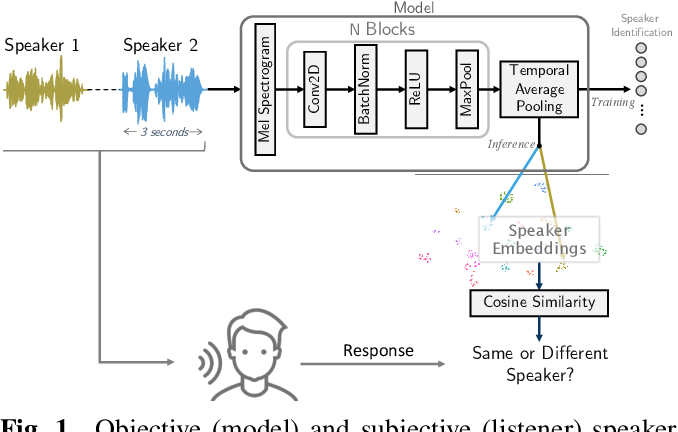
Figure 1 from Perceptual Analysis of Speaker Embeddings for Voice ...
Advertisement Space (300x250)
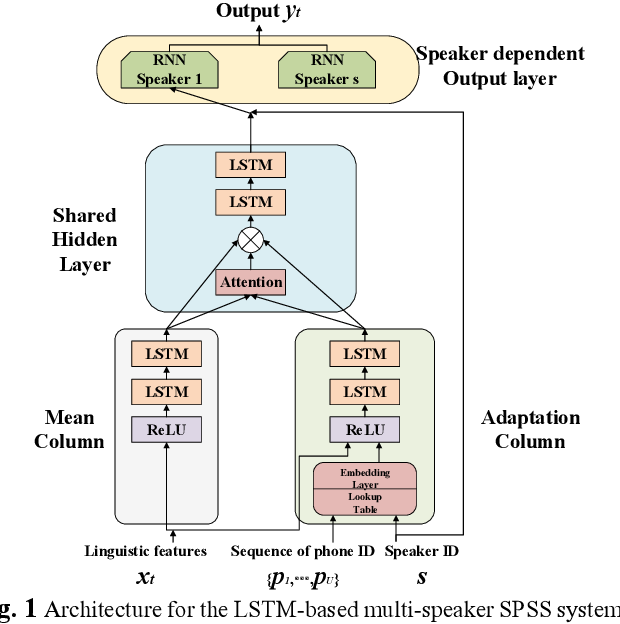
Figure 1 from Phoneme Dependent Speaker Embedding and Model ...

Figure 1 from Deeply Fused Speaker Embeddings for Text-Independent ...
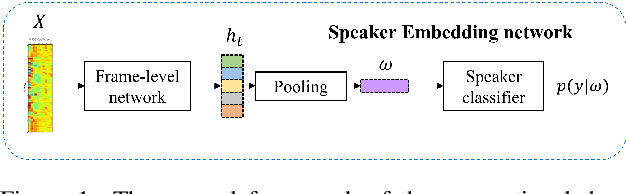
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from Vision-Guided Speaker Embedding Based Speech Separation ...

Figure 1 from Hardware Architectures for Embedded Speaker Recognition ...
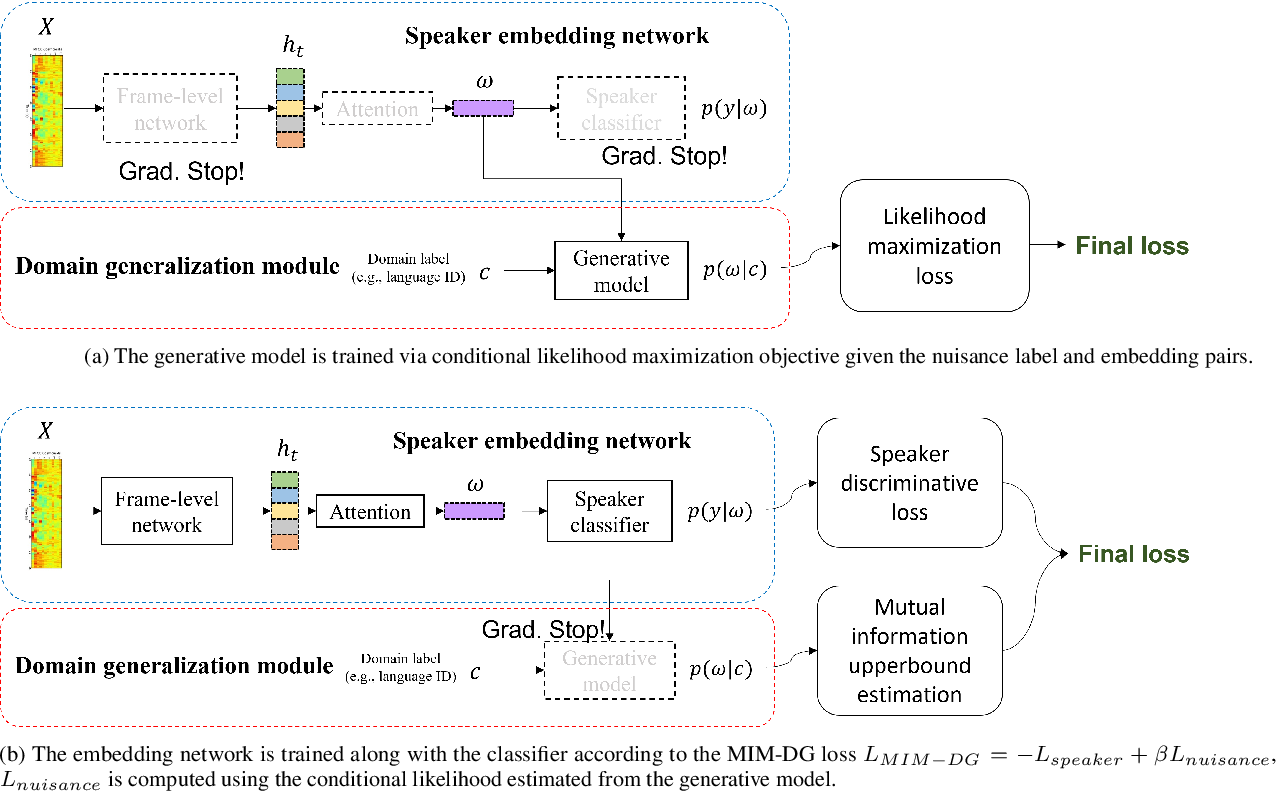
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
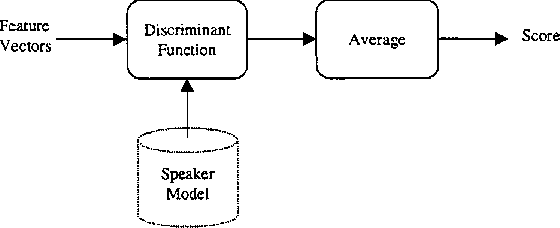
Figure 1 from Speaker identification using a polynomial-based ...

Figure 1 from Emotion Invariant Speaker Embeddings for Speaker ...
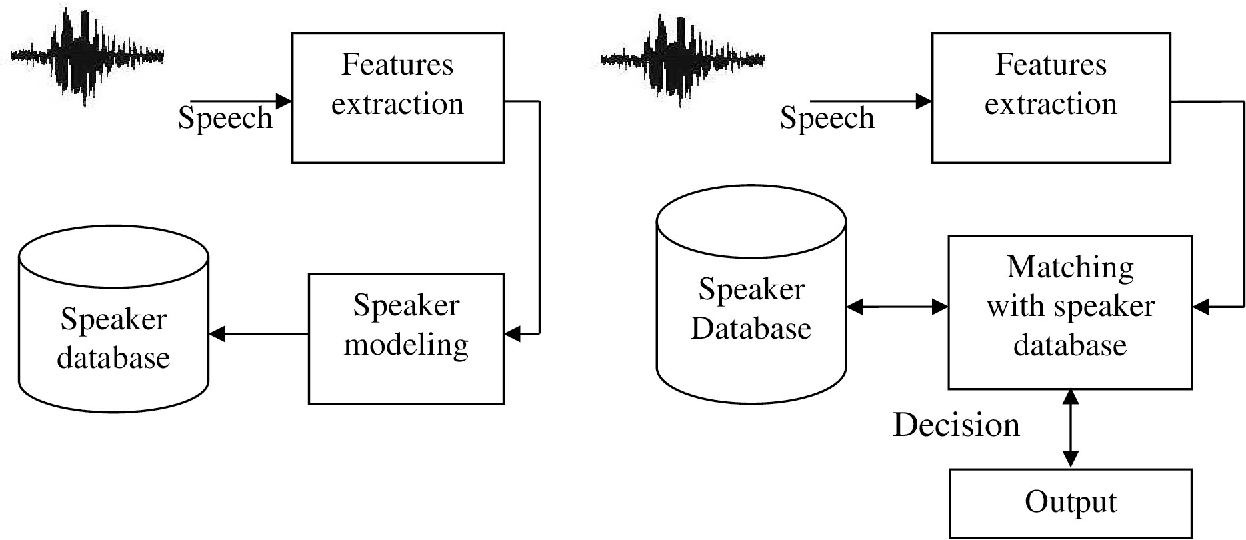
Figure 1 from Enhancing speaker identification through reverberation ...
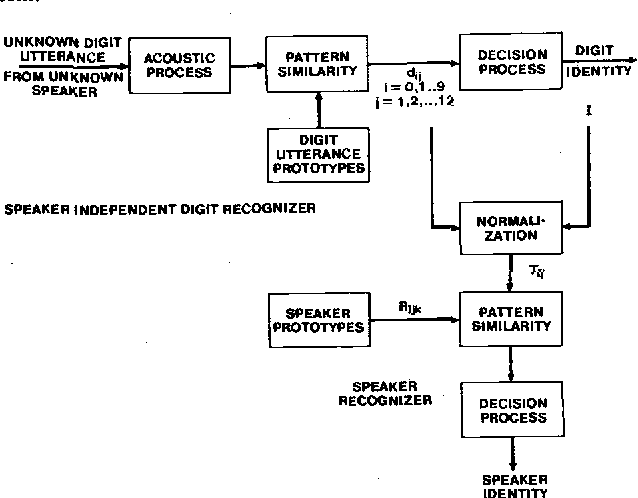
Figure 1 from Speaker identification and verification combined with ...
Advertisement Space (336x280)

Figure 1 from Learning Graph Embeddings for Open World Compositional ...

Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from Interpretable Partitioned Embedding for Customized Multi ...

Figure 1 from Automatic Speaker Recognition: Current Approaches and ...

An Ensemble Approach for Speaker Identification from Audio Files in ...

Figure1. Proposed Speech Enhancement for Speaker identification Figure ...

Figure 2 from Mutual Information-based Embedding Decoupling for ...

Figure 1 from Text Independent Speaker Recognition System | Semantic ...
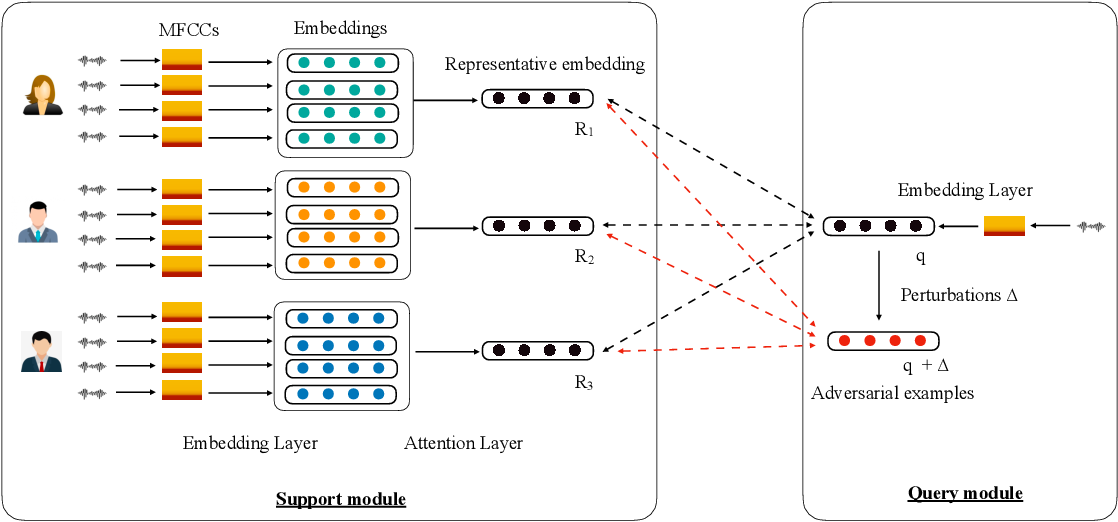
Figure 1 from Automatic Speaker Recognition with Limited Data ...
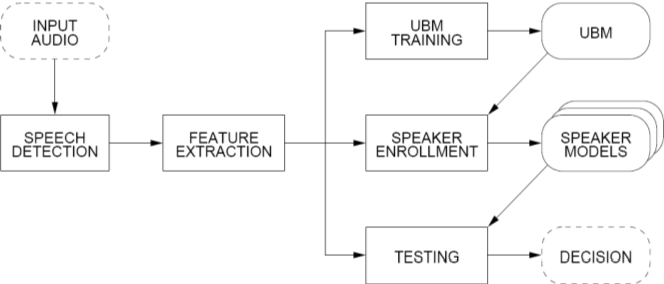
Figure 1 from Speaker de-identification via voice transformation ...
Advertisement Space (336x280)

Figure 1 from Multimodal Speaker Adaptation of Acoustic Model and ...

Figure 1 from Improved Closed Set Text-Independent Speaker ...

Figure 1 from Speech Rhythm-Based Speaker Embeddings Extraction from ...
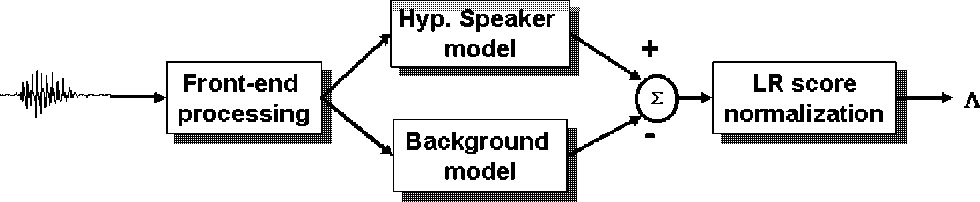
Figure 1 from Approaches to Speaker Detection and Tracking in ...
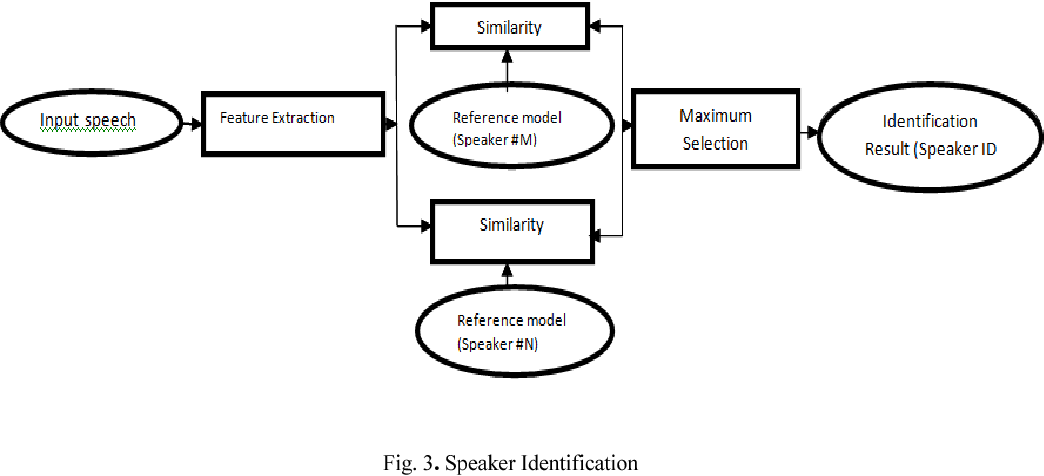
Figure 1 from A Review on Speaker Recognition | Semantic Scholar
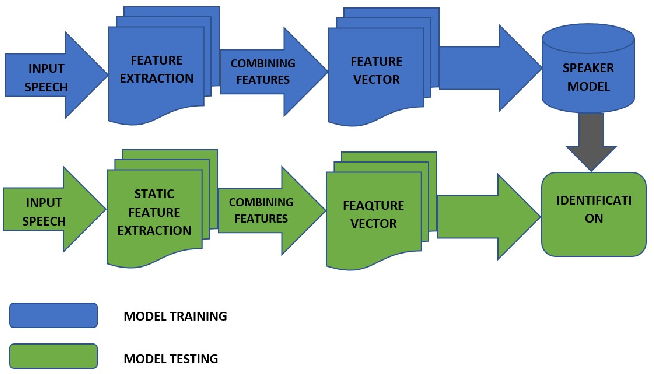
Figure 1 from Effectiveness of Feature Collaboration in Speaker ...