
Figure 1 From Alo Vc Any To Any Low Latency One Shot Voice Conversion

Figure 1 from ALO-VC: Any-to-any Low-latency One-shot Voice Conversion ...
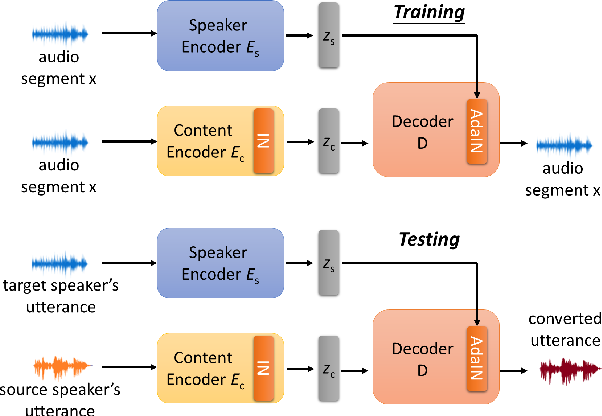
Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from Any-to-One Sequence-to-Sequence Voice Conversion Using ...
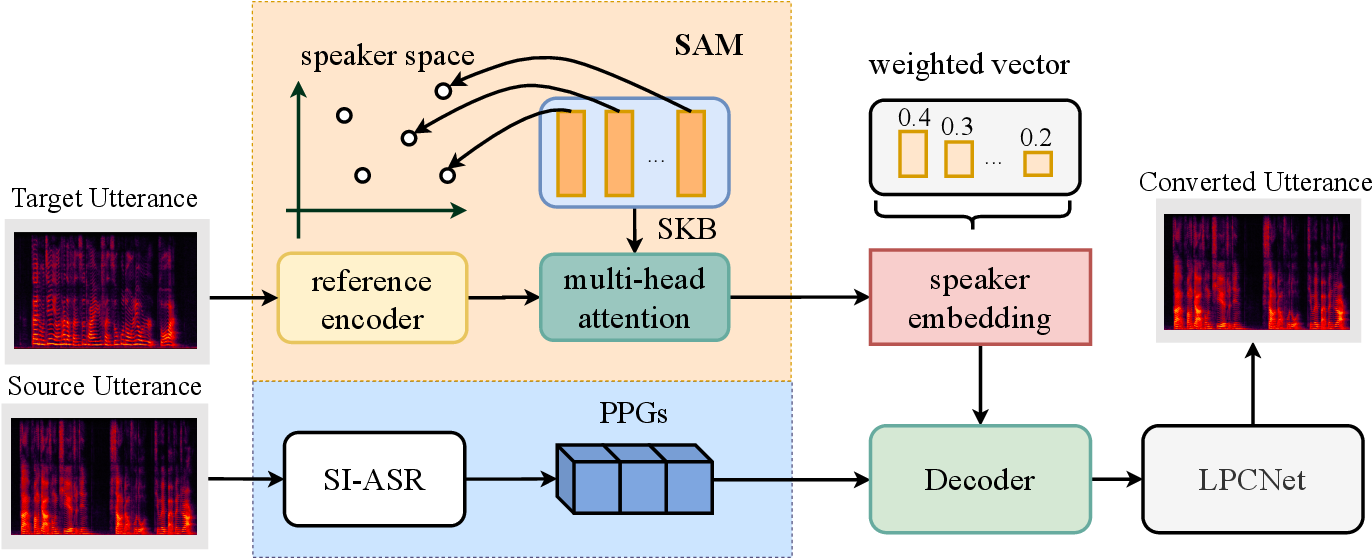
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from Low-latency Real-time Voice Conversion on CPU | Semantic ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...
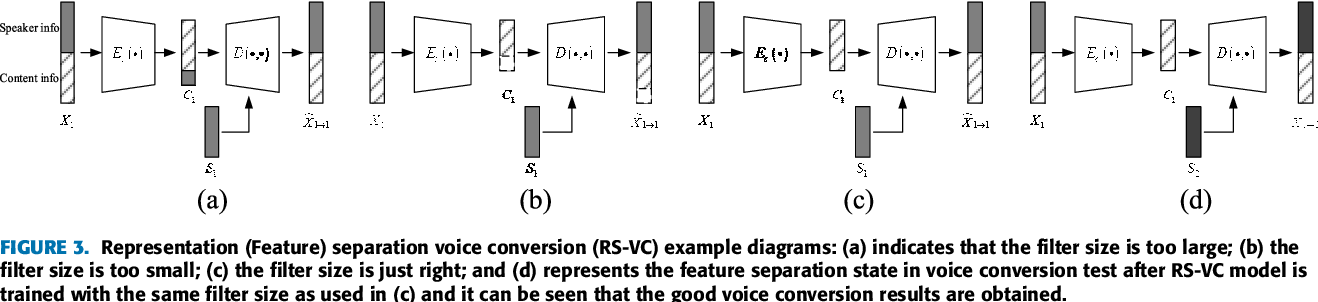
Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

Figure 1 from An Evaluation of Three-Stage Voice Conversion Framework ...

Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

Figure 1 from A Comparative Study of Voice Conversion Models with Large ...
Advertisement Space (300x250)

Figure 1 from ATTS2S-VC: Sequence-to-sequence Voice Conversion with ...

Figure 1 from CASIA Voice Conversion System for the Voice Conversion ...
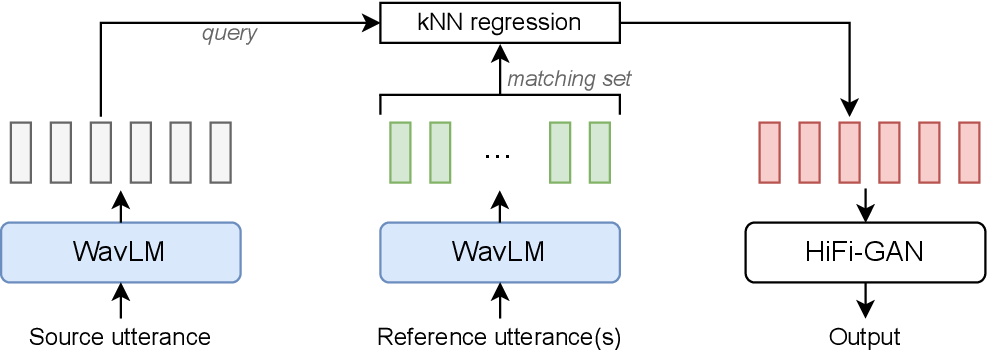
Figure 1 from Voice Conversion With Just Nearest Neighbors | Semantic ...

Figure 1 from End-to-End Zero-Shot Voice Conversion with Location ...
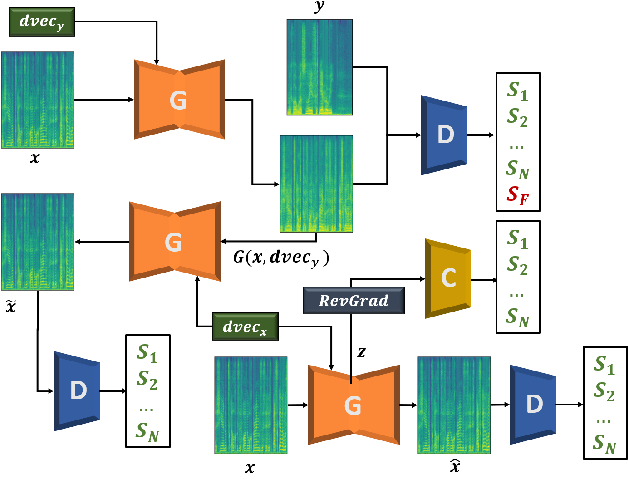
Figure 1 from One-Shot Voice Conversion with Speaker-Agnostic StarGAN ...
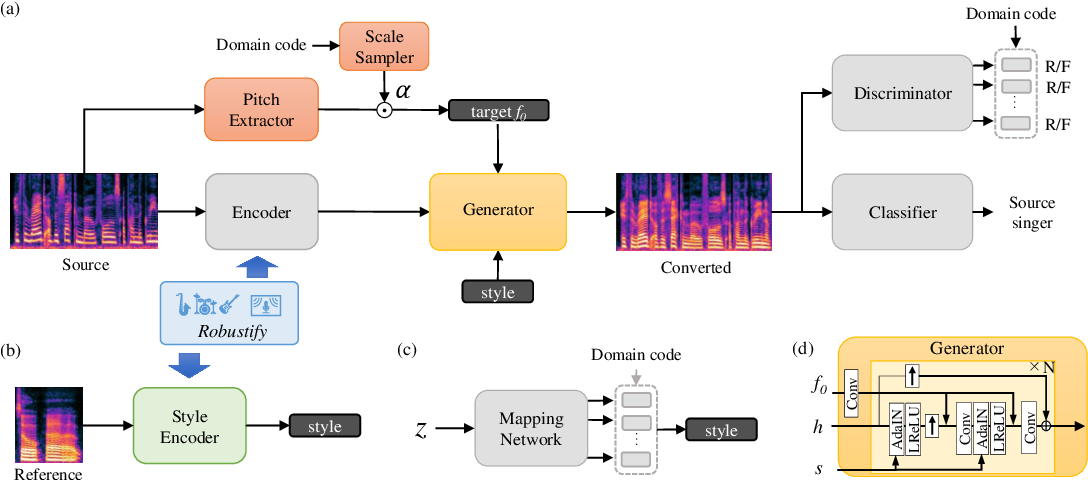
Figure 1 from Robust One-Shot Singing Voice Conversion | Semantic Scholar

Figure 1 from An evaluation of many-to-one voice conversion algorithms ...
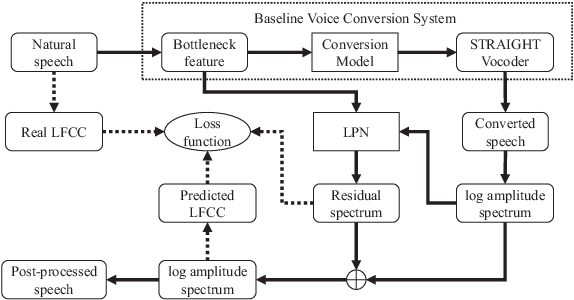
Figure 1 from Adversarial Post-Processing of Voice Conversion against ...

Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...
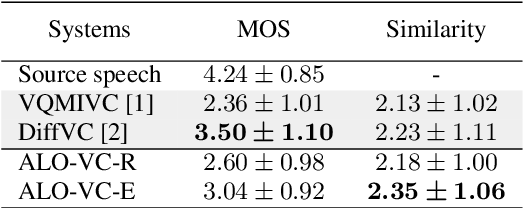
Table 1 from ALO-VC: Any-to-any Low-latency One-shot Voice Conversion ...
Advertisement Space (336x280)

Figure 1 from Jointly Trained Conversion Model With LPCNet for Any-to ...
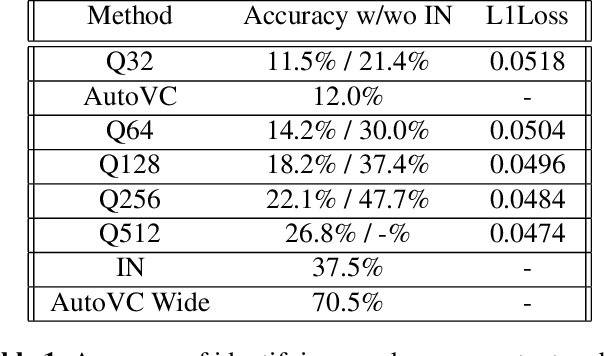
Table 1 from One-Shot Voice Conversion by Vector Quantization ...
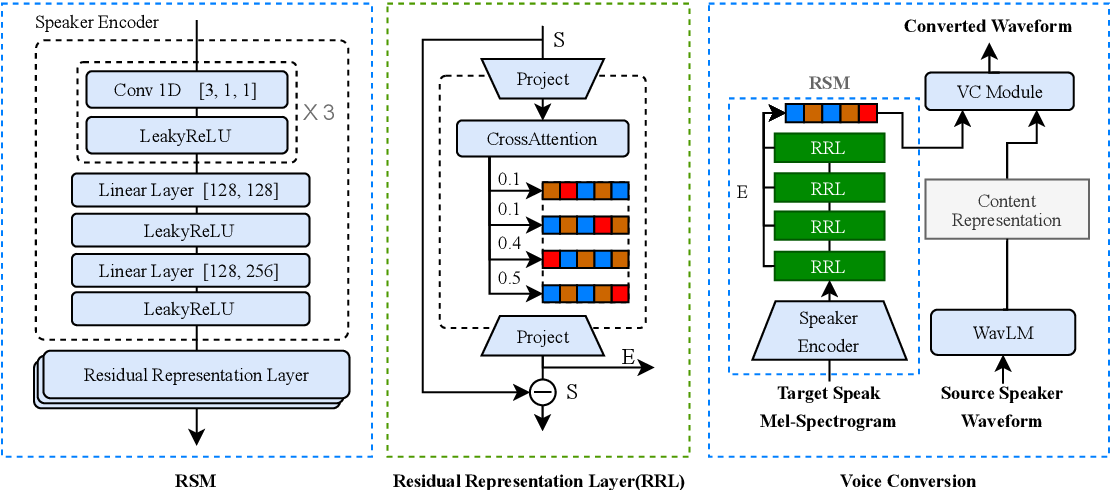
Figure 1 from Residual Speaker Representation for One-Shot Voice ...
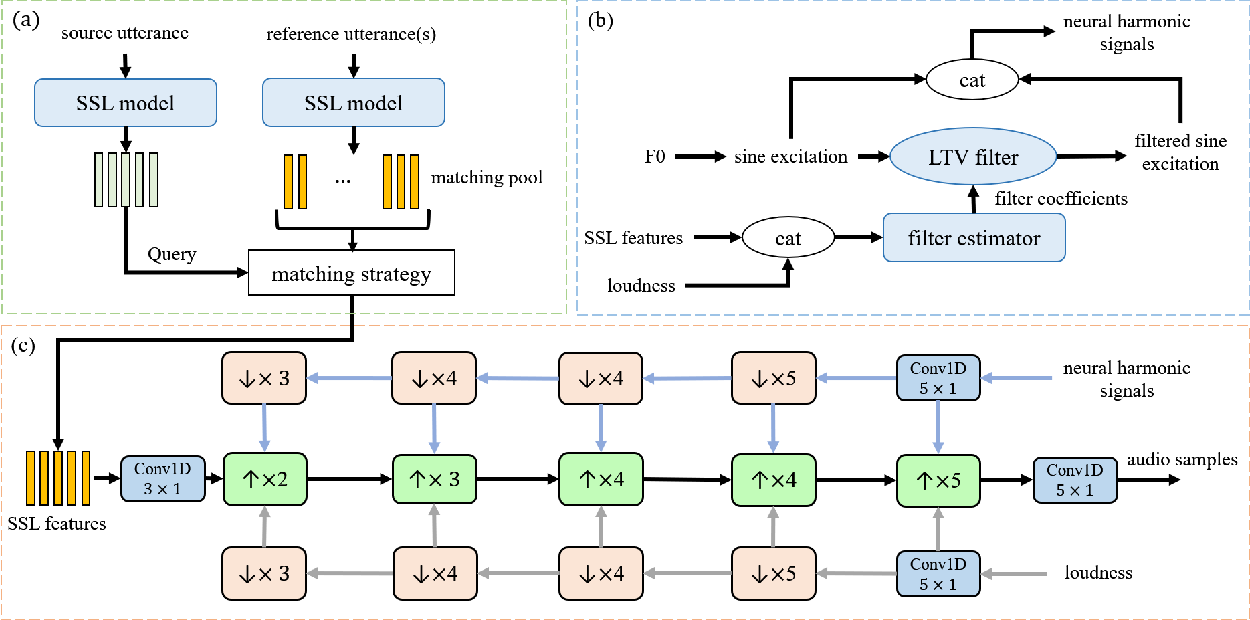
Figure 1 from Neural Concatenative Singing Voice Conversion: Rethinking ...

Table 1 from DRVC: A Framework of Any-to-Any Voice Conversion with Self ...

Figure 1 from A Unified One-Shot Prosody and Speaker Conversion System ...
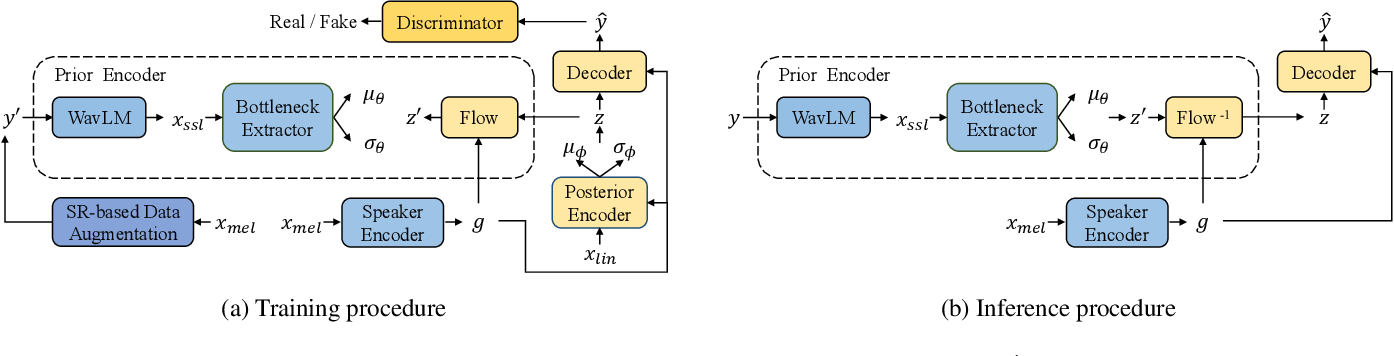
Figure 1 from Freevc: Towards High-Quality Text-Free One-Shot Voice ...
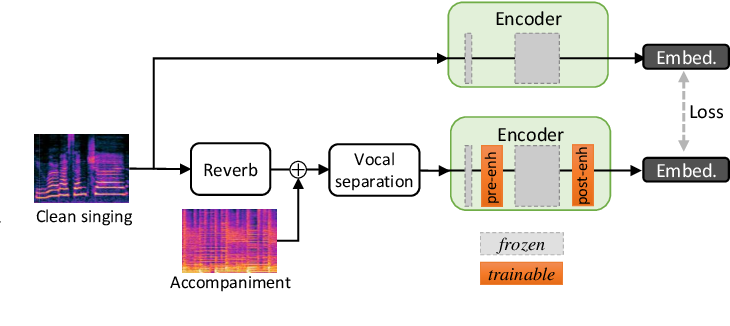
Figure 2 from Robust One-Shot Singing Voice Conversion | Semantic Scholar

Figure 1 from Speech Representation Disentanglement with Adversarial ...

StyleTTS-VC: One-Shot Voice Conversion by Knowledge Transfer from Style ...
Advertisement Space (336x280)

Figure 1 from LDM-SVC: Latent Diffusion Model Based Zero-Shot Any-to ...

Figure 1 from GR0: Self-Supervised Global Representation Learning for ...

Figure 1 from Speech Representation Disentanglement with Adversarial ...

Table 2 from ACE-VC: Adaptive and Controllable Voice Conversion Using ...

AC-VC: Non-parallel Low Latency Phonetic Posteriorgrams Based Voice ...
Build Low Latency Voice Agent: A Production Architecture Guide