
Figure 1 From One Shot Voice Conversion Based On Speaker Aware Module
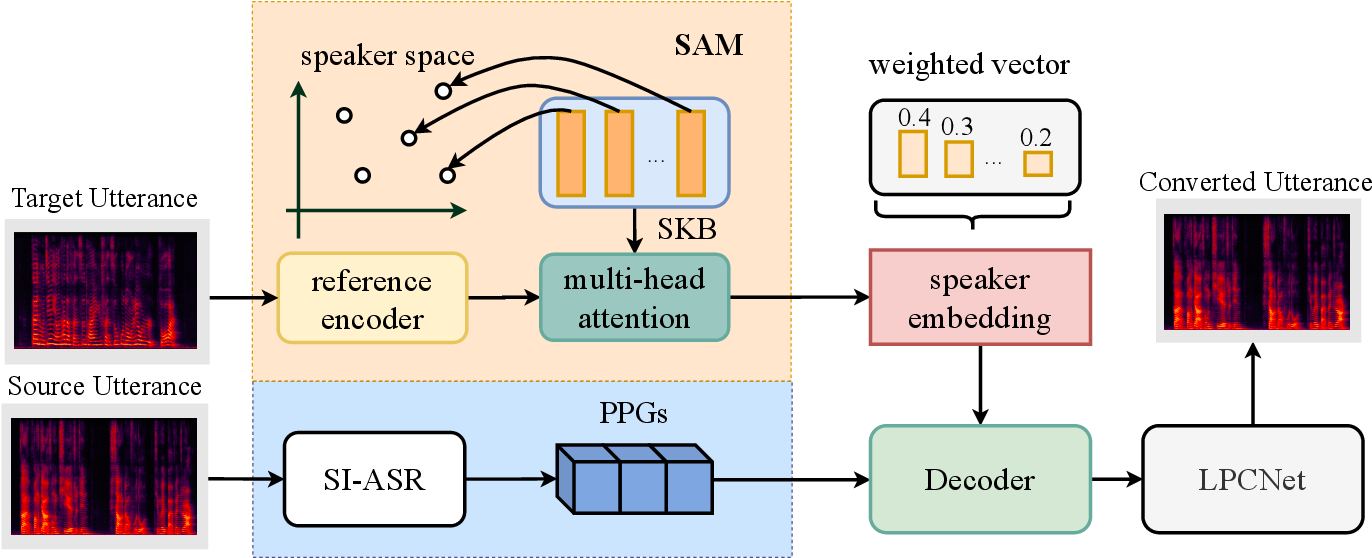
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from One-Shot Voice Conversion Algorithm Based on ...
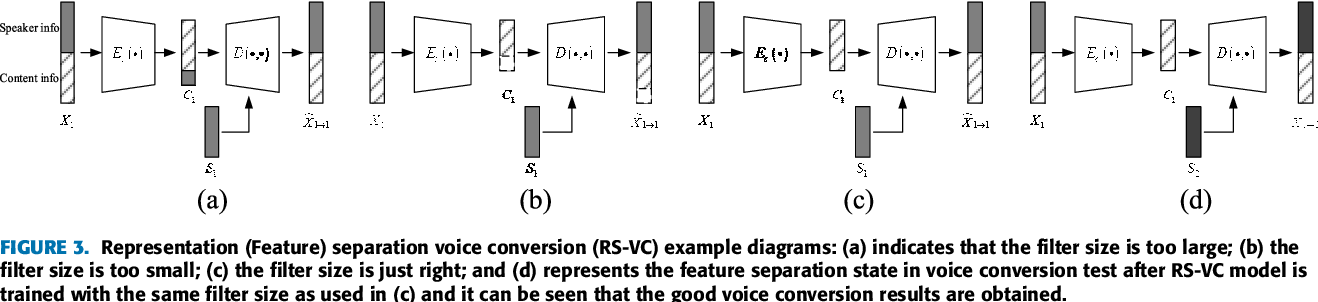
Figure 1 from One-Shot Voice Conversion Algorithm Based on ...

Figure 1 from Voice Conversion Augmentation for Speaker Recognition on ...
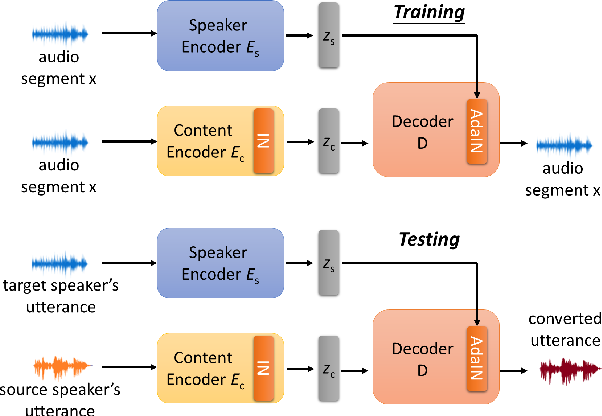
Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...

Figure 1 from One-shot Voice Conversion by Separating Speaker and ...
Advertisement Space (300x250)
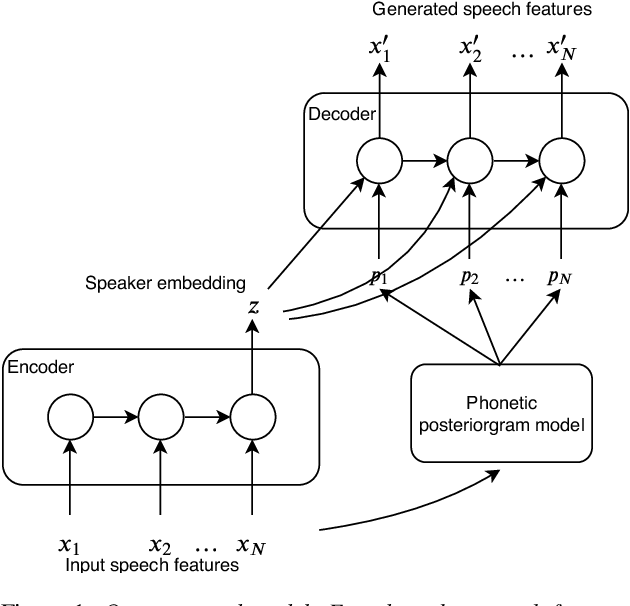
Figure 1 from One-Shot Voice Conversion with Disentangled ...
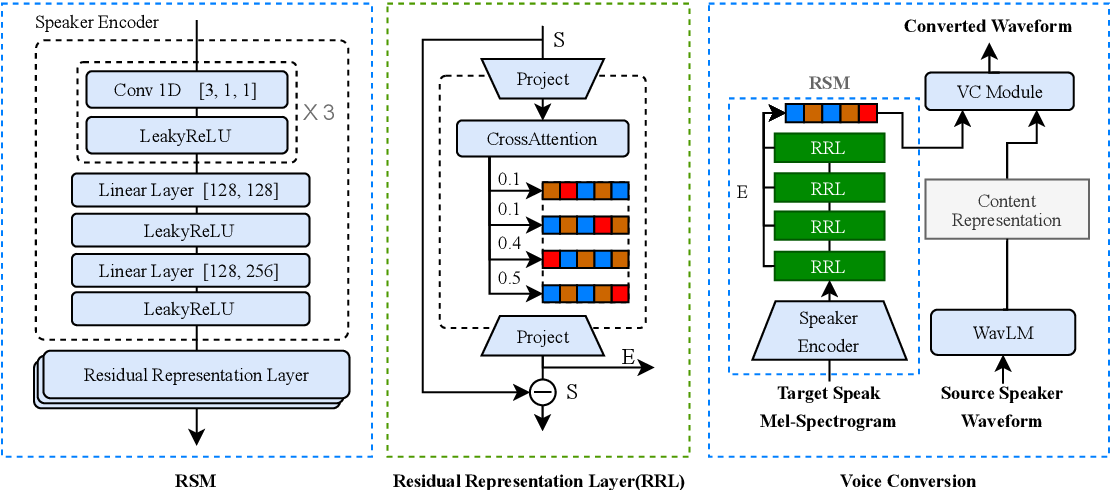
Figure 1 from Residual Speaker Representation for One-Shot Voice ...
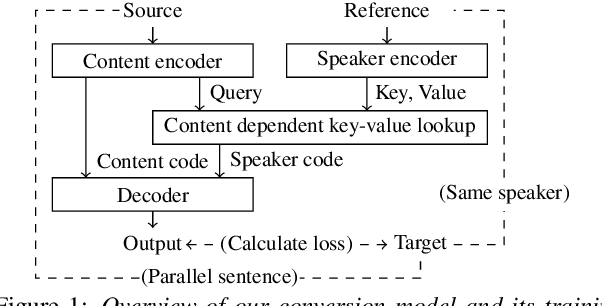
Figure 1 from Attention-Based Speaker Embeddings for One-Shot Voice ...

Figure 1 from ALO-VC: Any-to-any Low-latency One-shot Voice Conversion ...
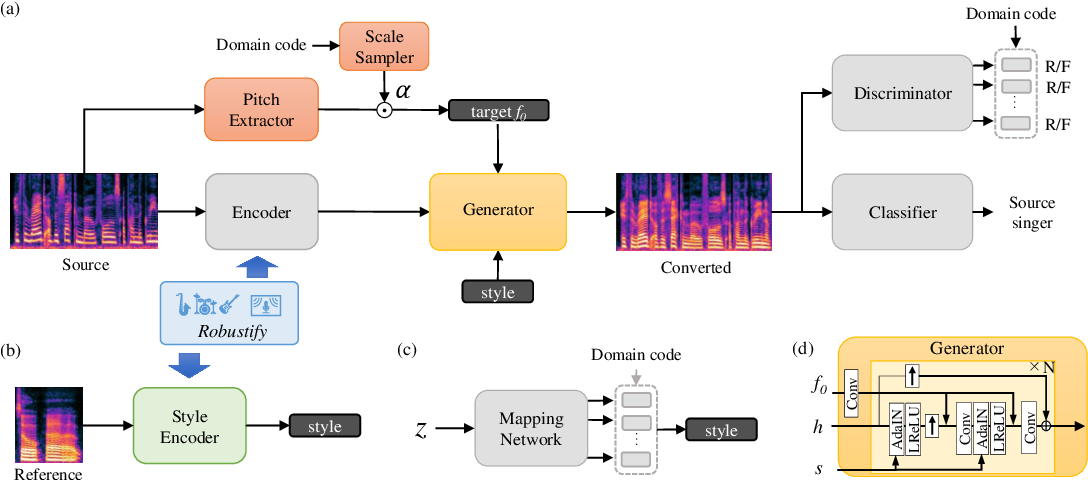
Figure 1 from Robust One-Shot Singing Voice Conversion | Semantic Scholar

Figure 1 from Improving robustness of one-shot voice conversion with ...

Figure 1 from A Unified One-Shot Prosody and Speaker Conversion System ...

Figure 1 from One-Shot Voice Conversion Using Star-Gan | Semantic Scholar
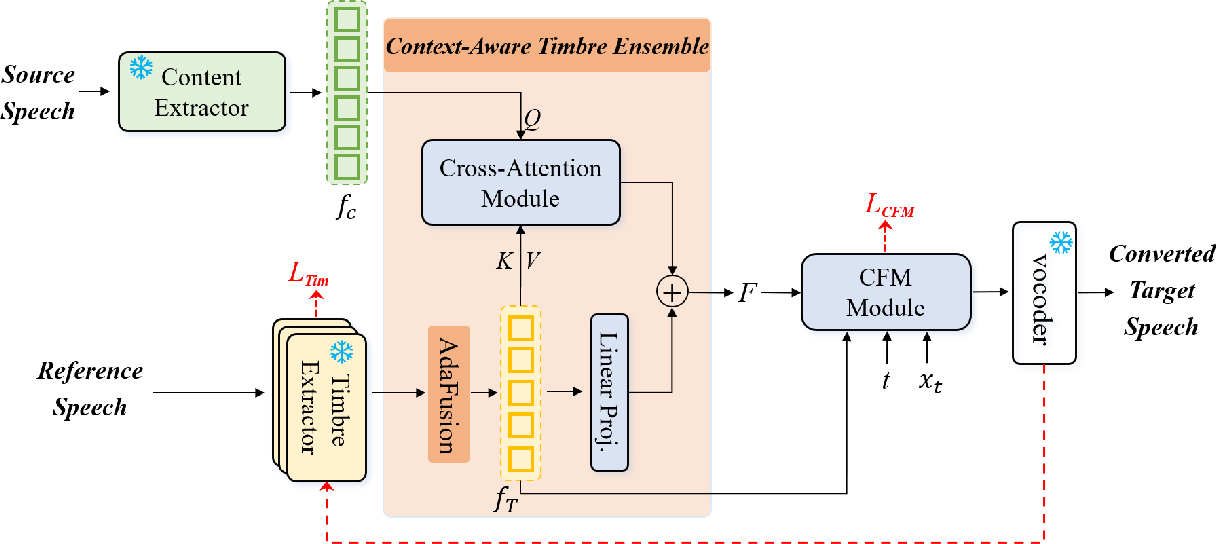
Figure 1 from Zero-Shot Voice Conversion via Content-Aware Timbre ...
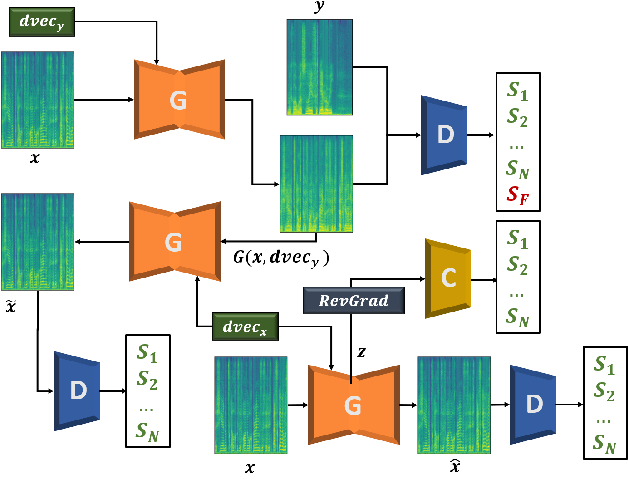
Figure 1 from One-Shot Voice Conversion with Speaker-Agnostic StarGAN ...
Advertisement Space (336x280)

Figure 1 from An evaluation of many-to-one voice conversion algorithms ...

Figure 1 from Residual Speaker Representation for One-Shot Voice ...

Figure 1 from One-Shot Voice Conversion Using Star-Gan | Semantic Scholar
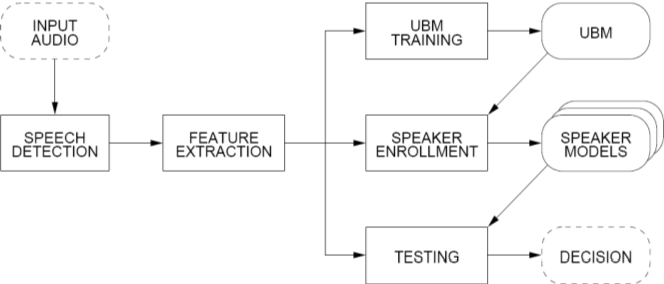
Figure 1 from Speaker de-identification via voice transformation ...
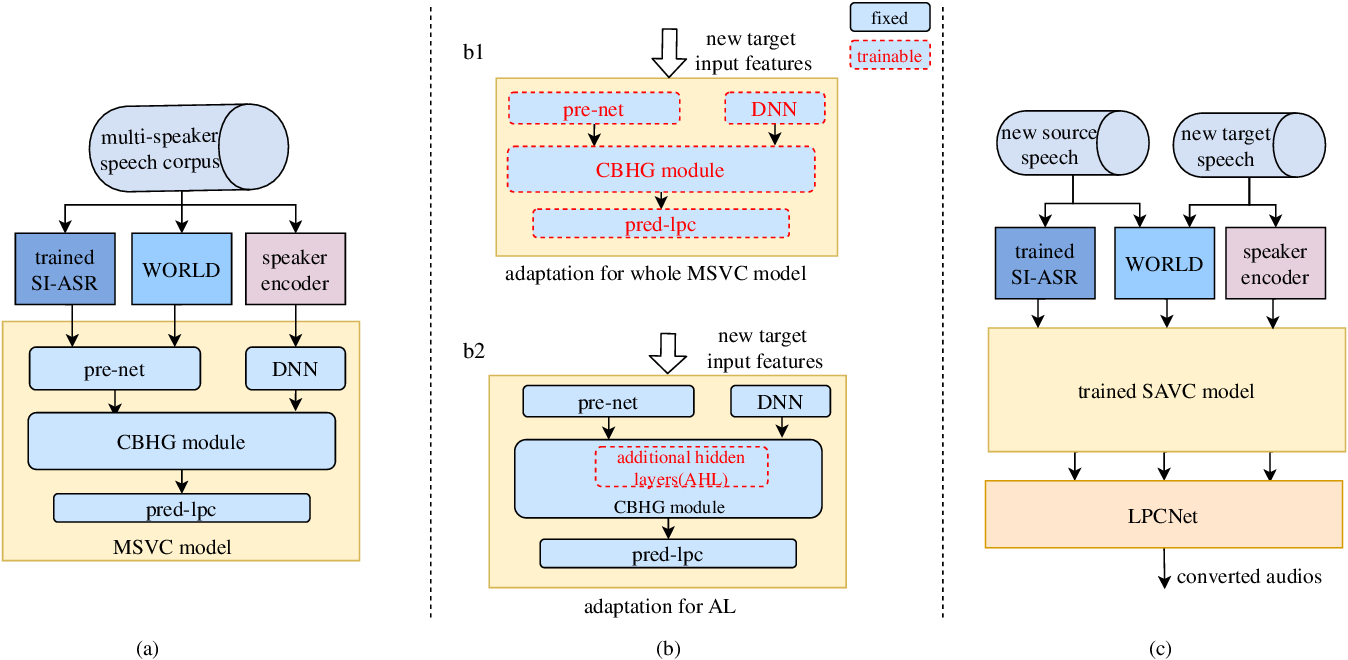
Figure 1 from Voice Conversion towards Arbitrary Speakers With Limited ...
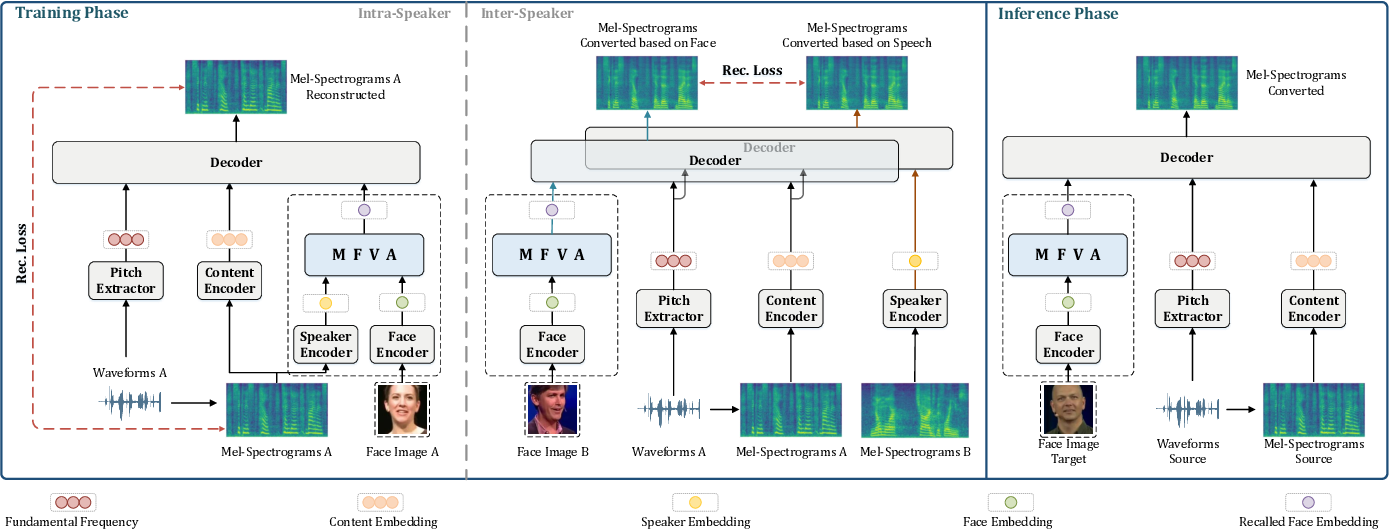
Figure 1 from Face-Driven Zero-Shot Voice Conversion with Memory-based ...

Figure 1 from Target Speaker Voice Activity Detection with Transformers ...

Figure 1 from DVQVC: An Unsupervised Zero-Shot Voice Conversion ...

Table 1 from One-shot Voice Conversion by Separating Speaker and ...
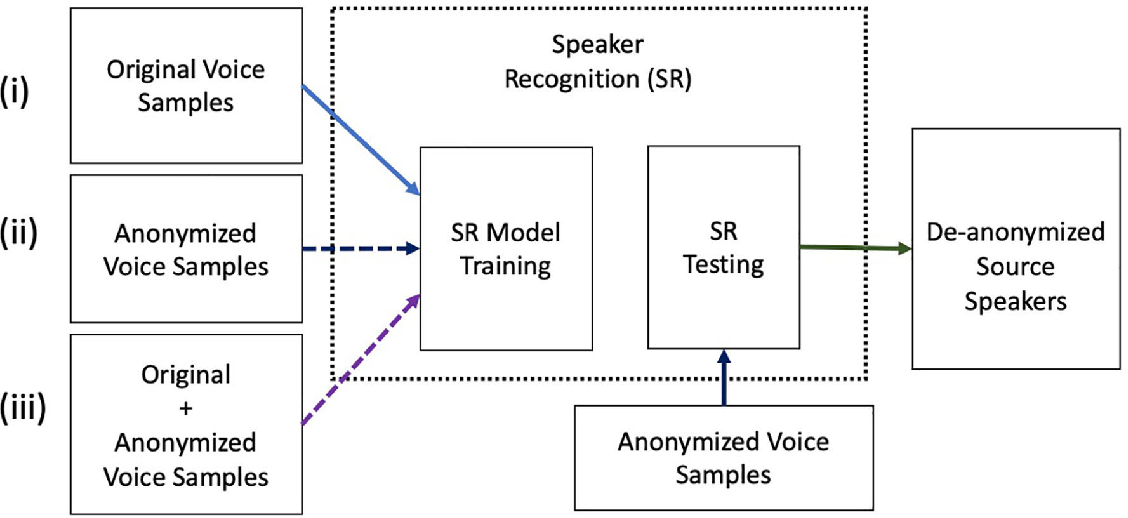
Figure 3 from Speaker Anonymity and Voice Conversion Vulnerability: A ...
Advertisement Space (336x280)

One-Shot Voice Conversion For Style Transfer Based On Speaker ...

[2111.12277] One-shot voice conversion for style transfer based on ...
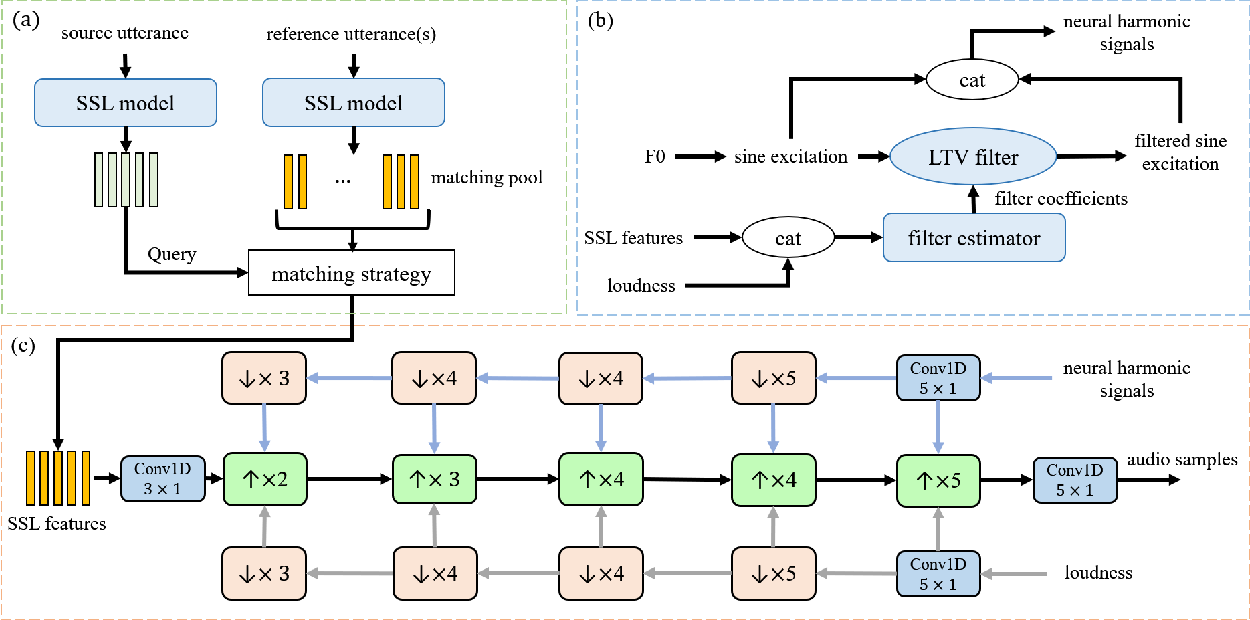
Figure 1 from Neural Concatenative Singing Voice Conversion: Rethinking ...
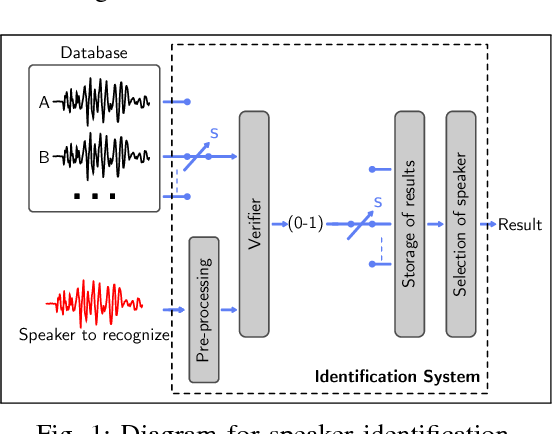
Figure 1 from One-Shot Speaker Identification for a Service Robot using ...

One-Shot Voice Conversion Based on Style Generative Adversarial ...

Overview of Voice Conversion Methods Based on Deep Learning