
Figure 1 From An Overview Of Voice Conversion Systems Semantic Scholar

Figure 1 from An overview of voice conversion systems | Semantic Scholar

Figure 1 from An overview of voice conversion systems | Semantic Scholar
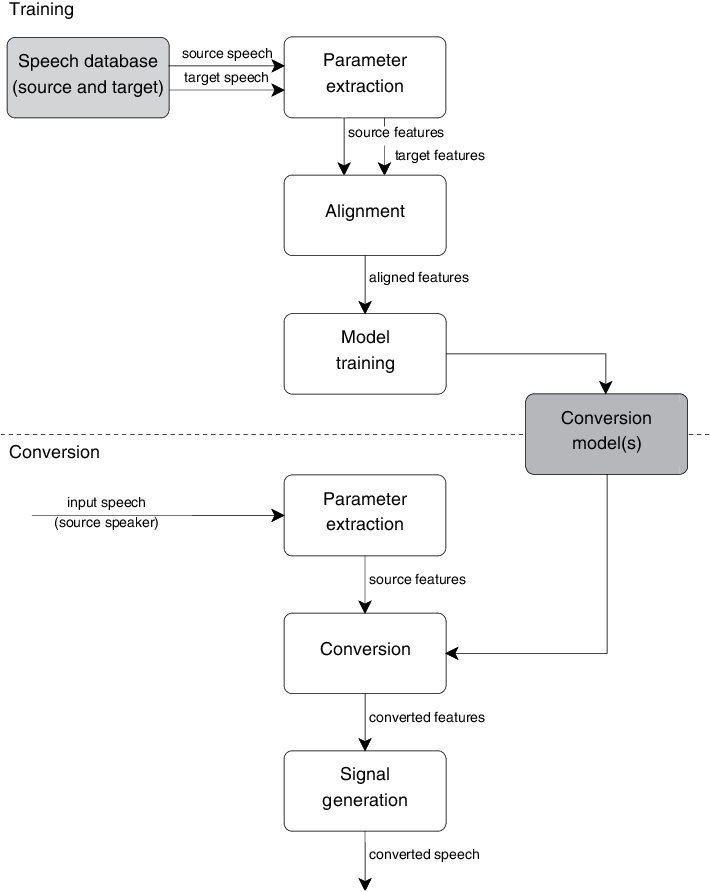
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from An Evaluation of Three-Stage Voice Conversion Framework ...
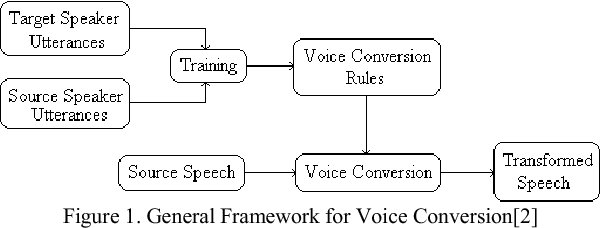
Figure 1 from Voice conversion application (VOCAL) | Semantic Scholar

Figure 1 from DeepGen Network based Voice Conversion | Semantic Scholar

Figure 1 from An overview of text-to-speech systems and media ...
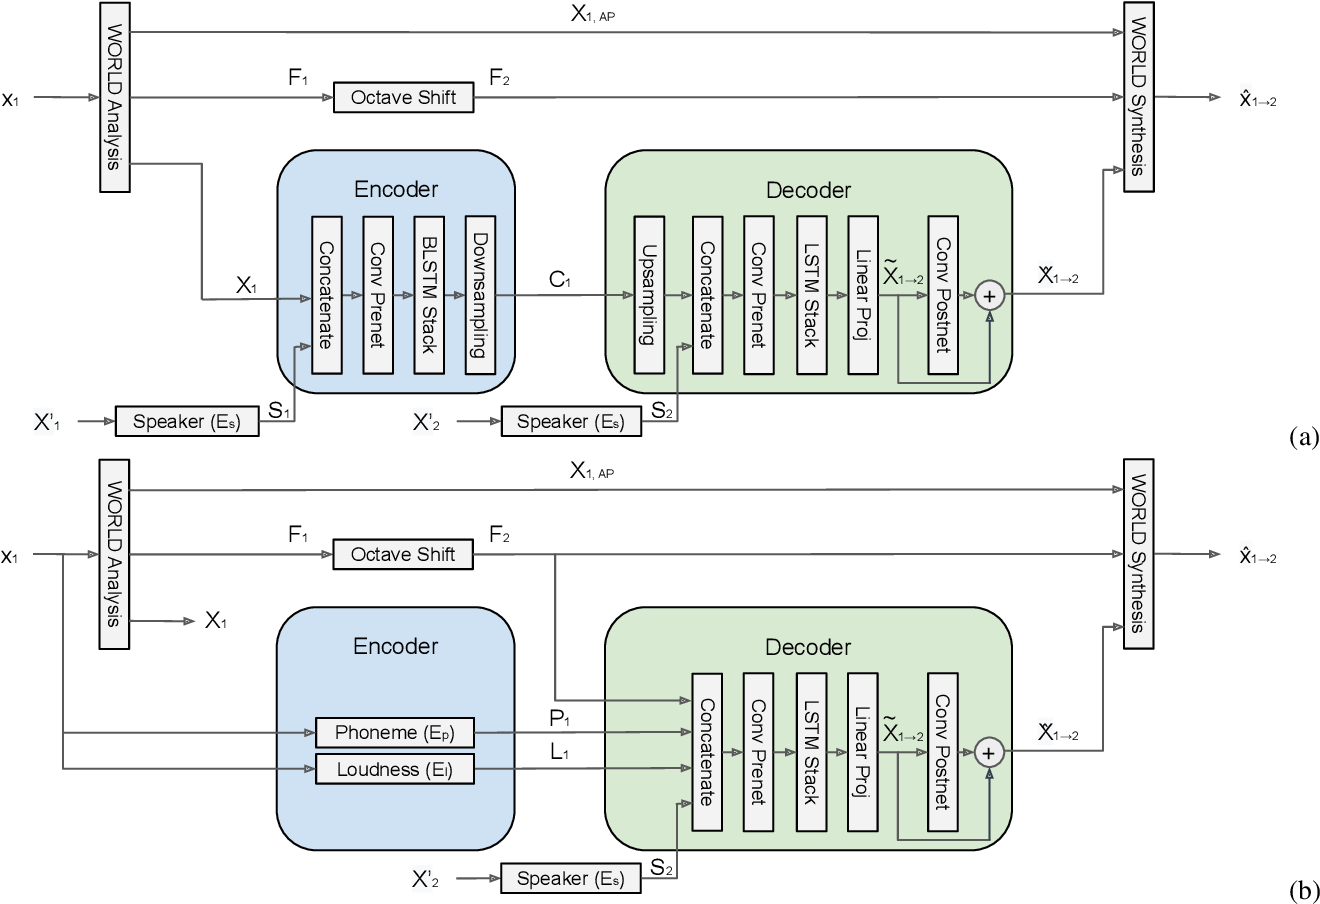
Figure 1 from Zero-Shot Singing Voice Conversion | Semantic Scholar

Figure 1 from Non-Parallel Voice Conversion System Using An Auto ...
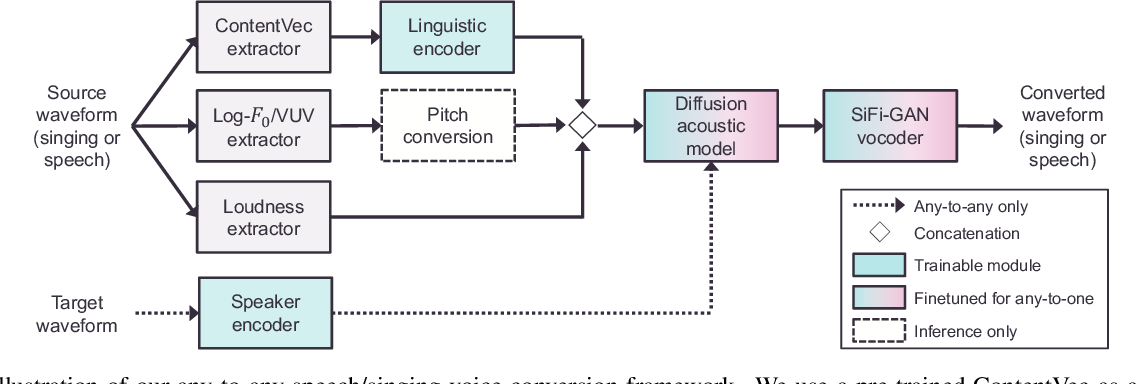
Figure 1 from A Comparative Study of Voice Conversion Models with Large ...
Advertisement Space (300x250)

Figure 1 from DVQVC: An Unsupervised Zero-Shot Voice Conversion ...

Figure 1 from An Improved Frame-Unit-Selection Based Voice Conversion ...
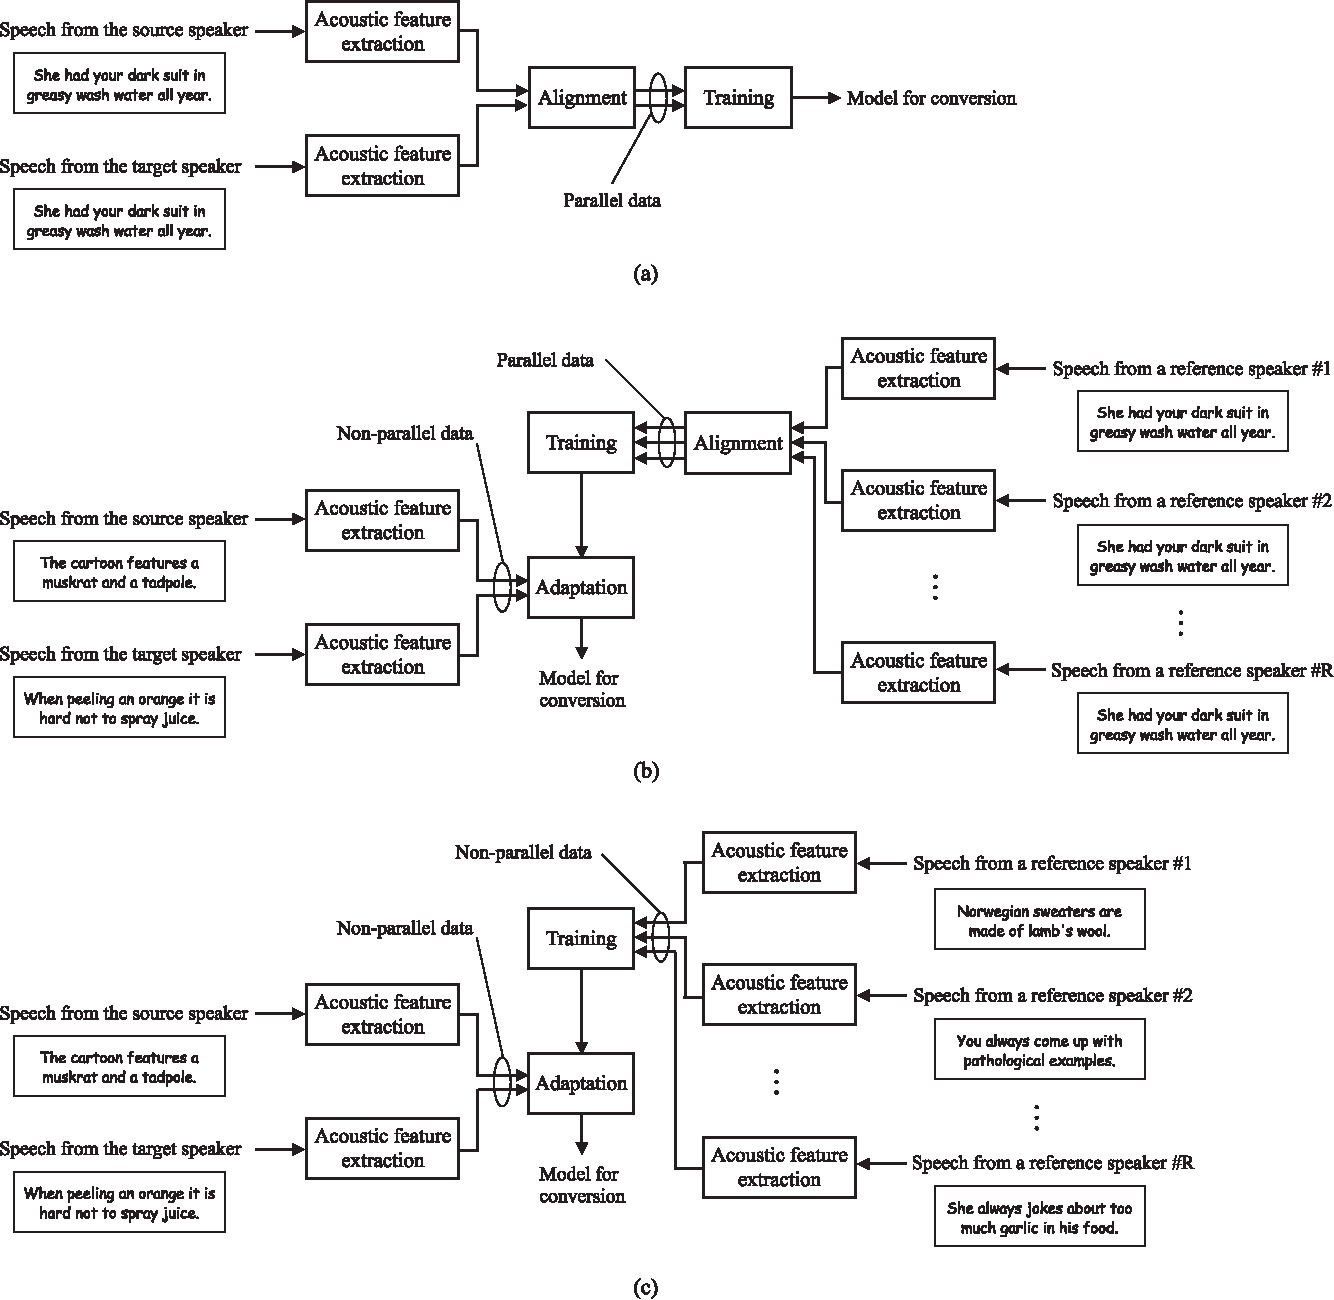
Figure 1 from Non-Parallel Training in Voice Conversion Using an ...

Figure 1 from Voice Authentication System | Semantic Scholar

Figure 1 from Statistical Voice Conversion Based on Wavenet | Semantic ...
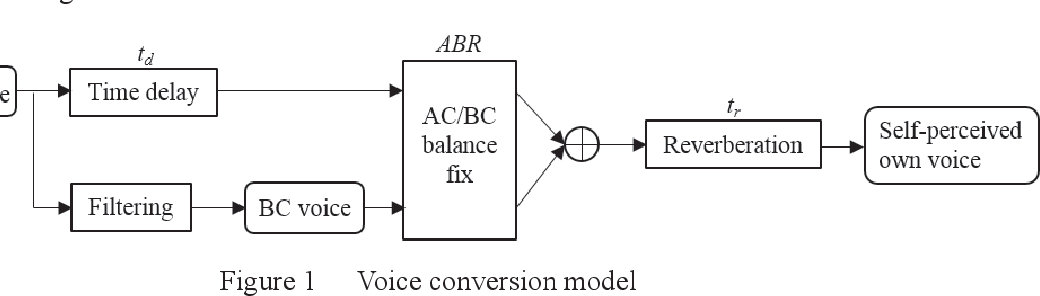
Figure 1 from Voice conversion model for estimation of transfer ...

Figure 1 from Overview and Analysis of Speech Recognition | Semantic ...

Figure 1 from Analysis of Voice Conversion and Code-Switching Synthesis ...
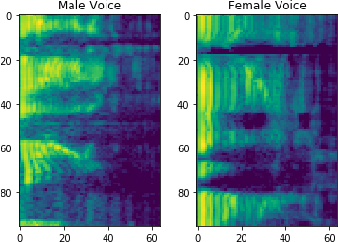
Figure 1 from Voice Conversion using Generative Techniques | Semantic ...

Figure 1 from Low-latency Real-time Voice Conversion on CPU | Semantic ...
Advertisement Space (336x280)

Figure 1 from Voice Conversion Using a Perceptual Criterion | Semantic ...

Figure 1 from Voice Conversion With Just Nearest Neighbors | Semantic ...
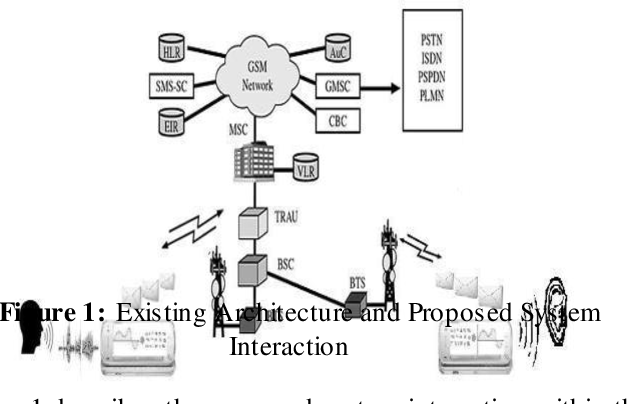
Figure 1 from CONVERSION OF VOICE SIGNAL INTO CHARACTERS USING ...

Figure 1 from Any-to-One Sequence-to-Sequence Voice Conversion Using ...
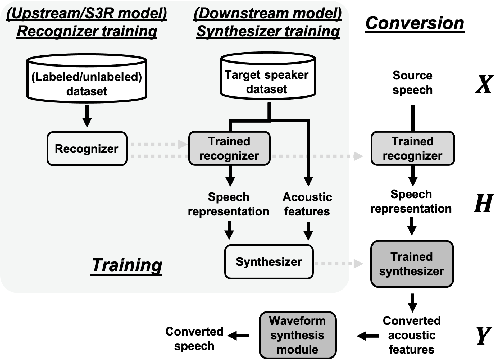
Figure 1 from S3PRL-VC: Open-Source Voice Conversion Framework with ...

Figure 1 from CASIA Voice Conversion System for the Voice Conversion ...

Figure 1 from The NU Non-Parallel Voice Conversion System for the Voice ...

Figure 1 from A Voice Conversion Framework with Tandem Feature Sparse ...
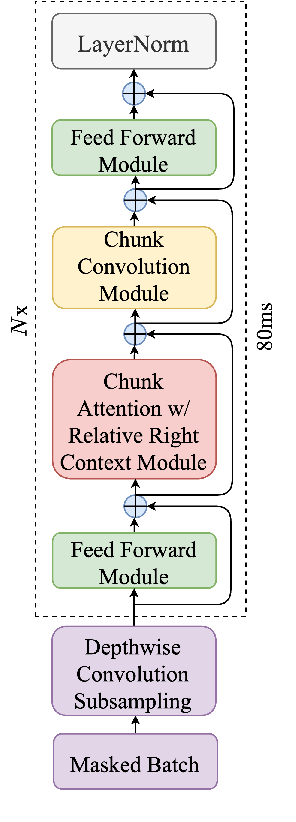
Figure 1 from ViettelRoar: Voice conversion approach for VLSP 2025 ...
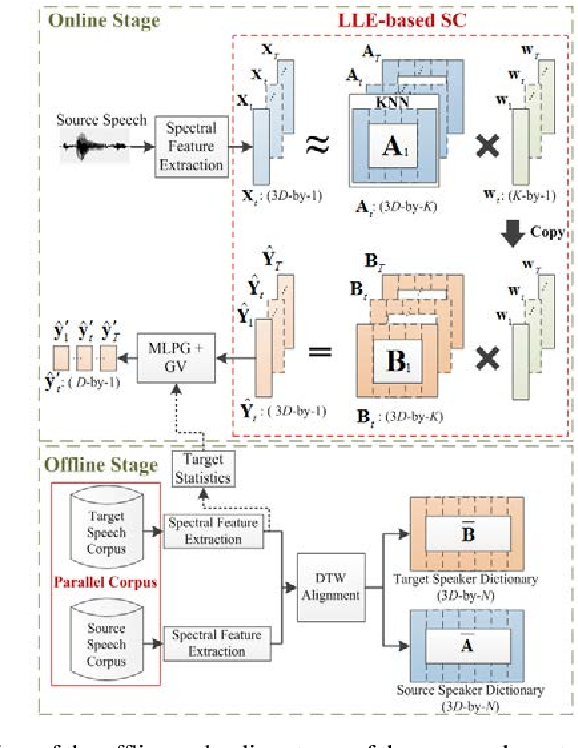
Figure 1 from Voice Conversion Based on Locally Linear Embedding ...
Advertisement Space (336x280)

Figure 1 from ATTS2S-VC: Sequence-to-sequence Voice Conversion with ...
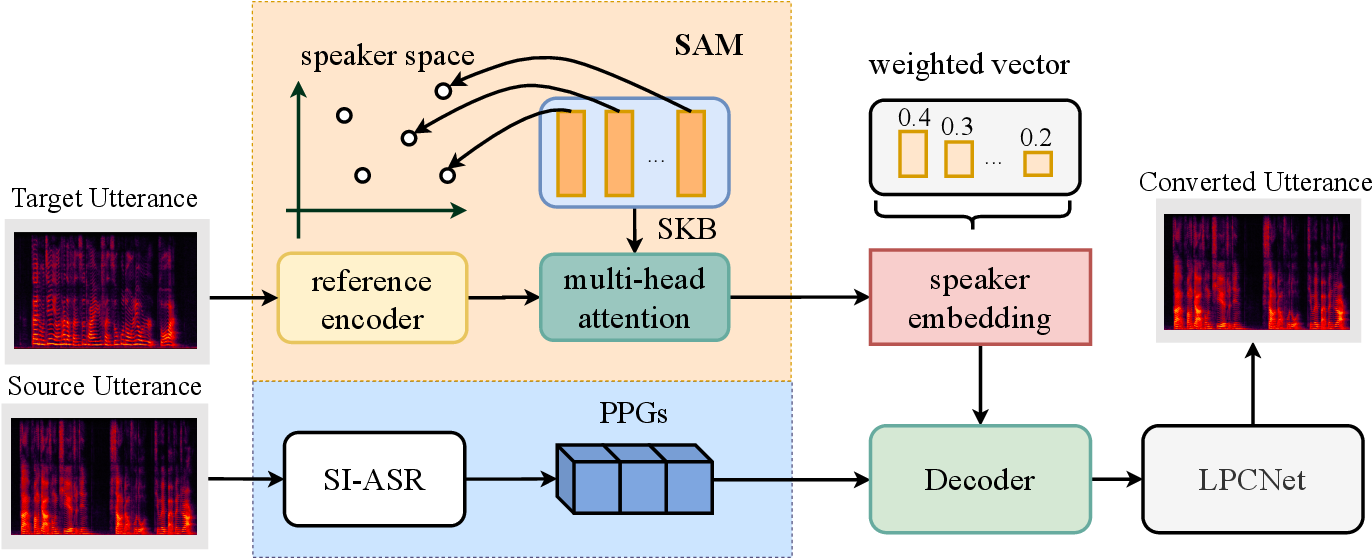
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...
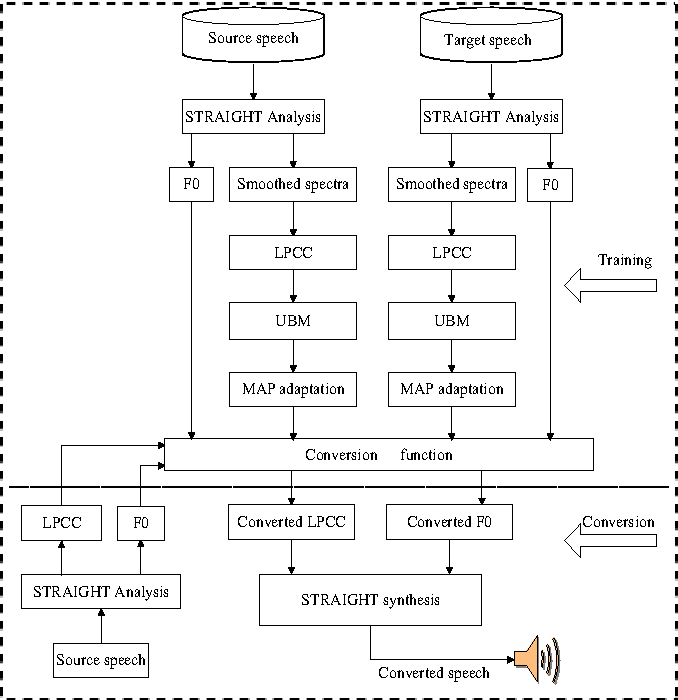
Figure 1 from Voice conversion with UBM and speaker-specific model ...
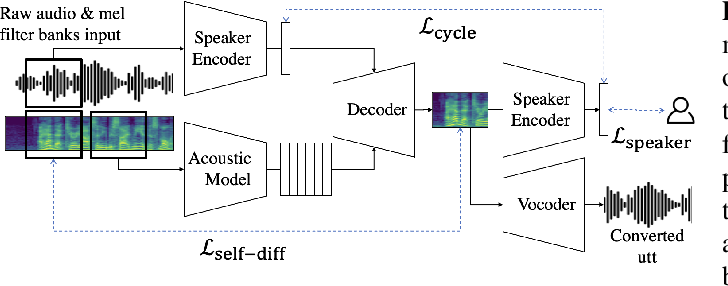
Figure 1 from Training Robust Zero-Shot Voice Conversion Models with ...
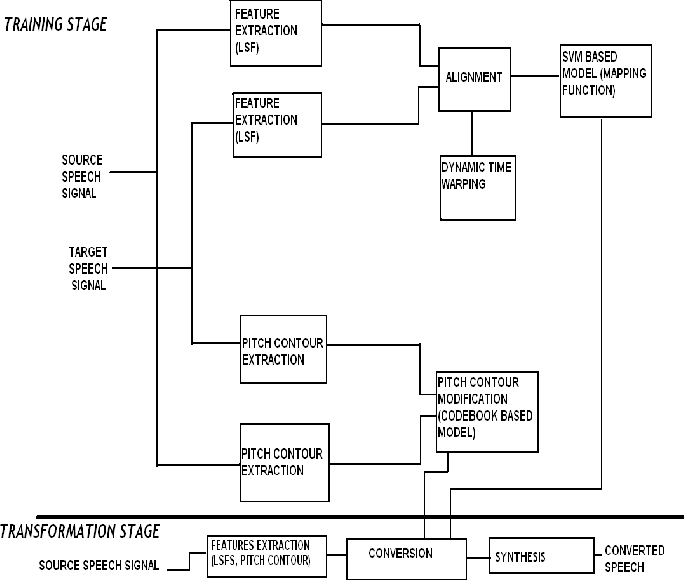
Figure 1 from Voice conversion system using SVM for vocal tract ...

Figure 1 from Real-Time, Full-Band, Online DNN-Based Voice Conversion ...