
Figure 1 From Voice Conversion Semantic Scholar

Figure 1 from An overview of voice conversion systems | Semantic Scholar

Figure 1 from Voice conversion | Semantic Scholar
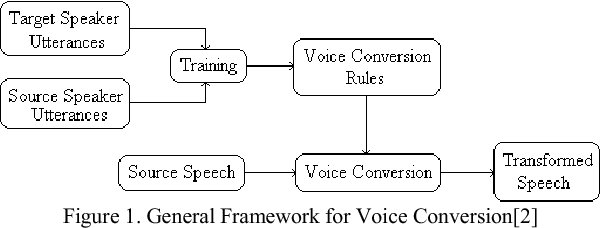
Figure 1 from Voice conversion application (VOCAL) | Semantic Scholar

Figure 1 from DeepGen Network based Voice Conversion | Semantic Scholar
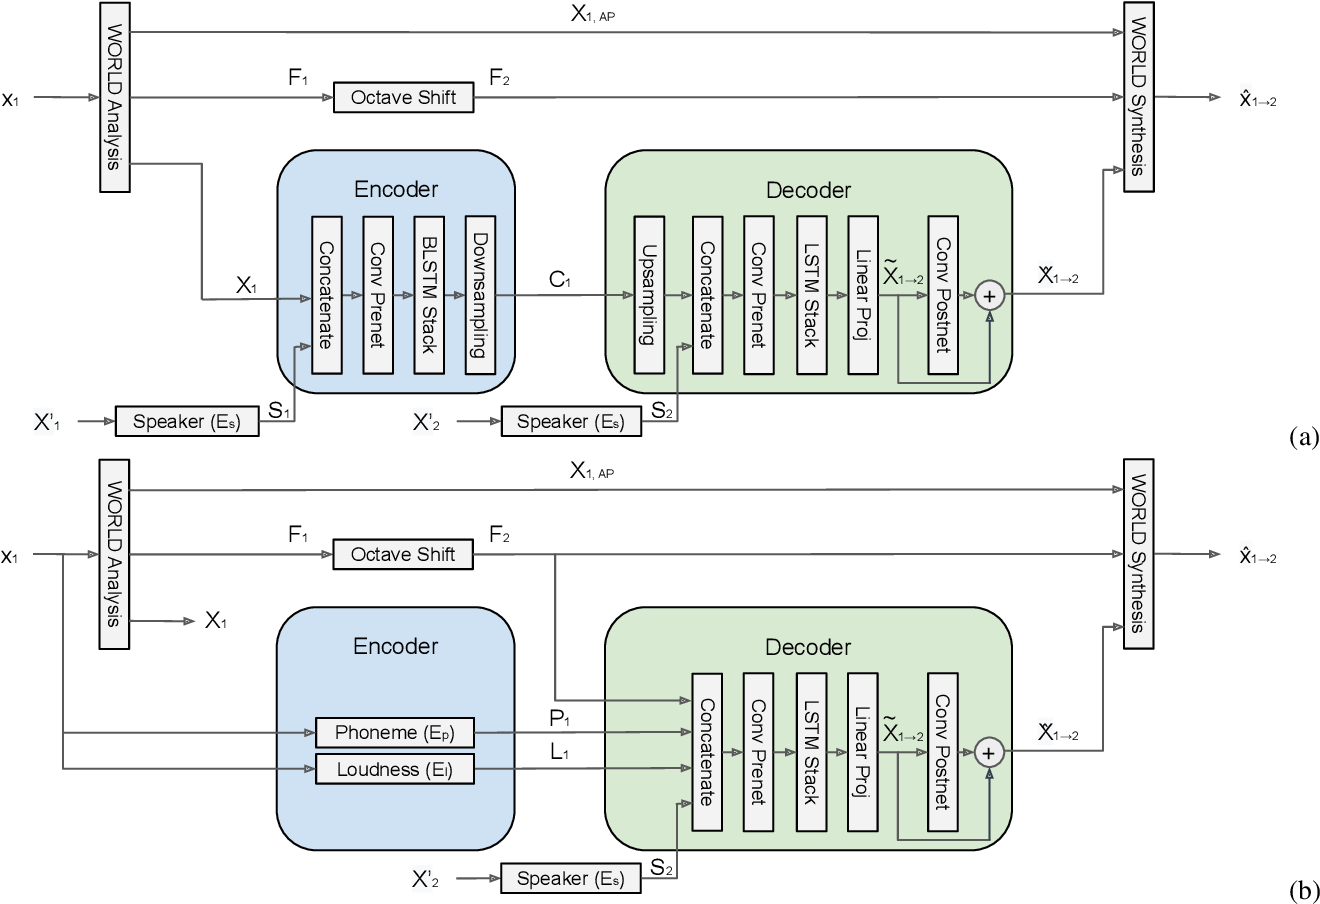
Figure 1 from Zero-Shot Singing Voice Conversion | Semantic Scholar
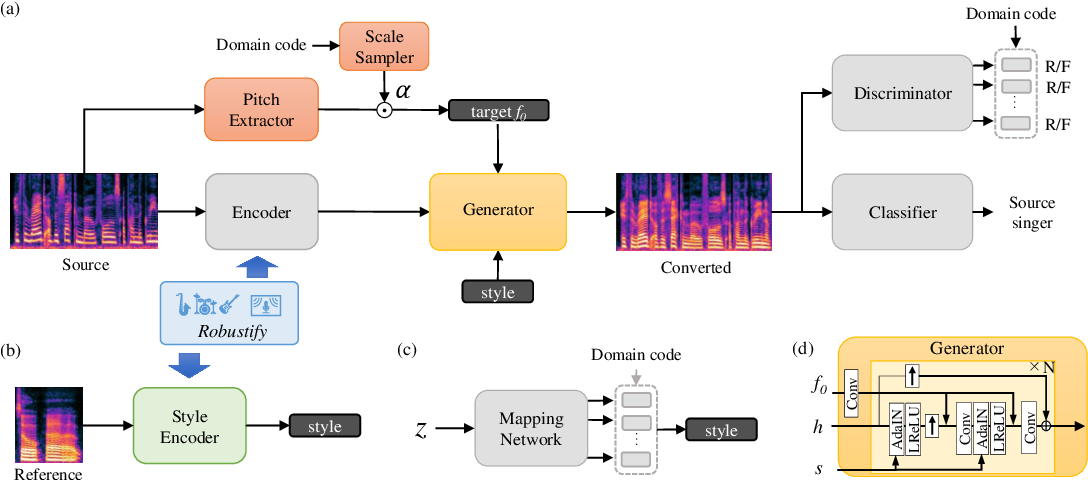
Figure 1 from Robust One-Shot Singing Voice Conversion | Semantic Scholar

Figure 1 from Rhythm Modeling for Voice Conversion | Semantic Scholar
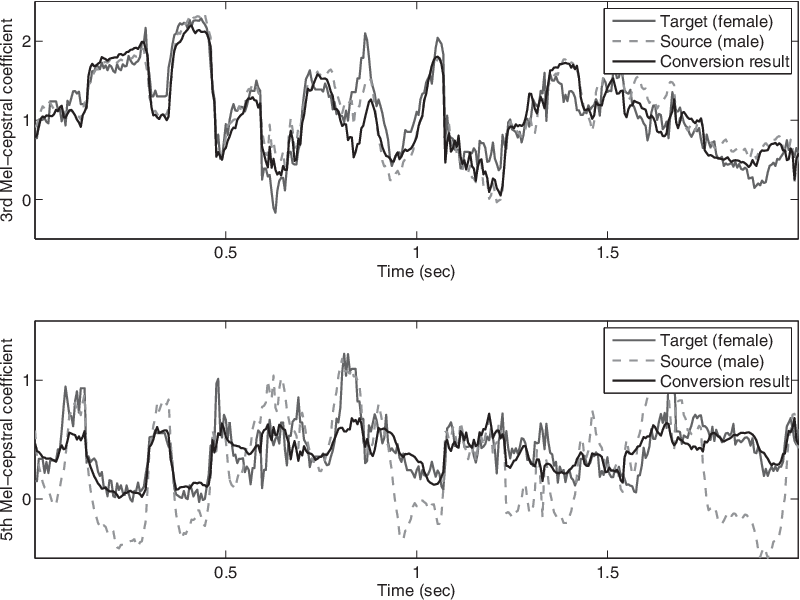
Figure 1 from Voice conversion | Semantic Scholar

Figure 1 from Statistical Voice Conversion Based on Wavenet | Semantic ...
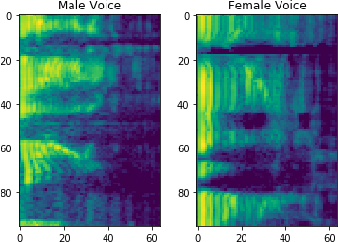
Figure 1 from Voice Conversion using Generative Techniques | Semantic ...
Advertisement Space (300x250)
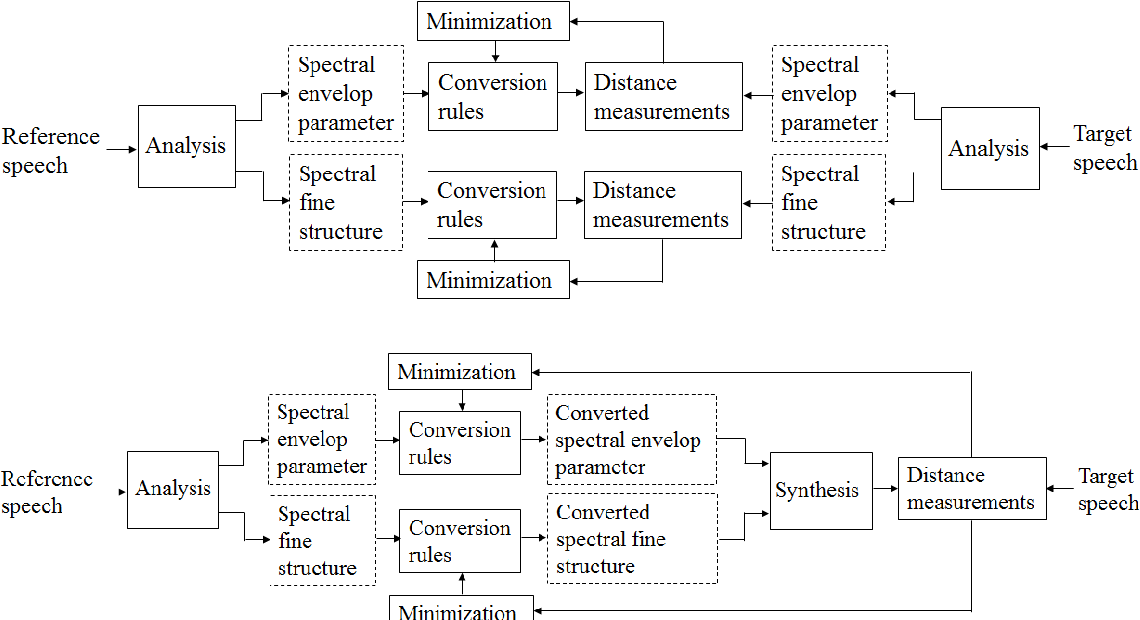
Figure 1 from Voice Conversion Using a Perceptual Criterion | Semantic ...
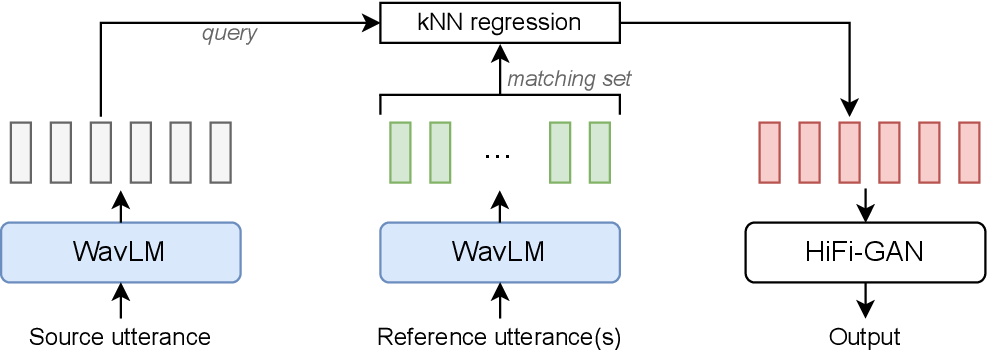
Figure 1 from Voice Conversion With Just Nearest Neighbors | Semantic ...
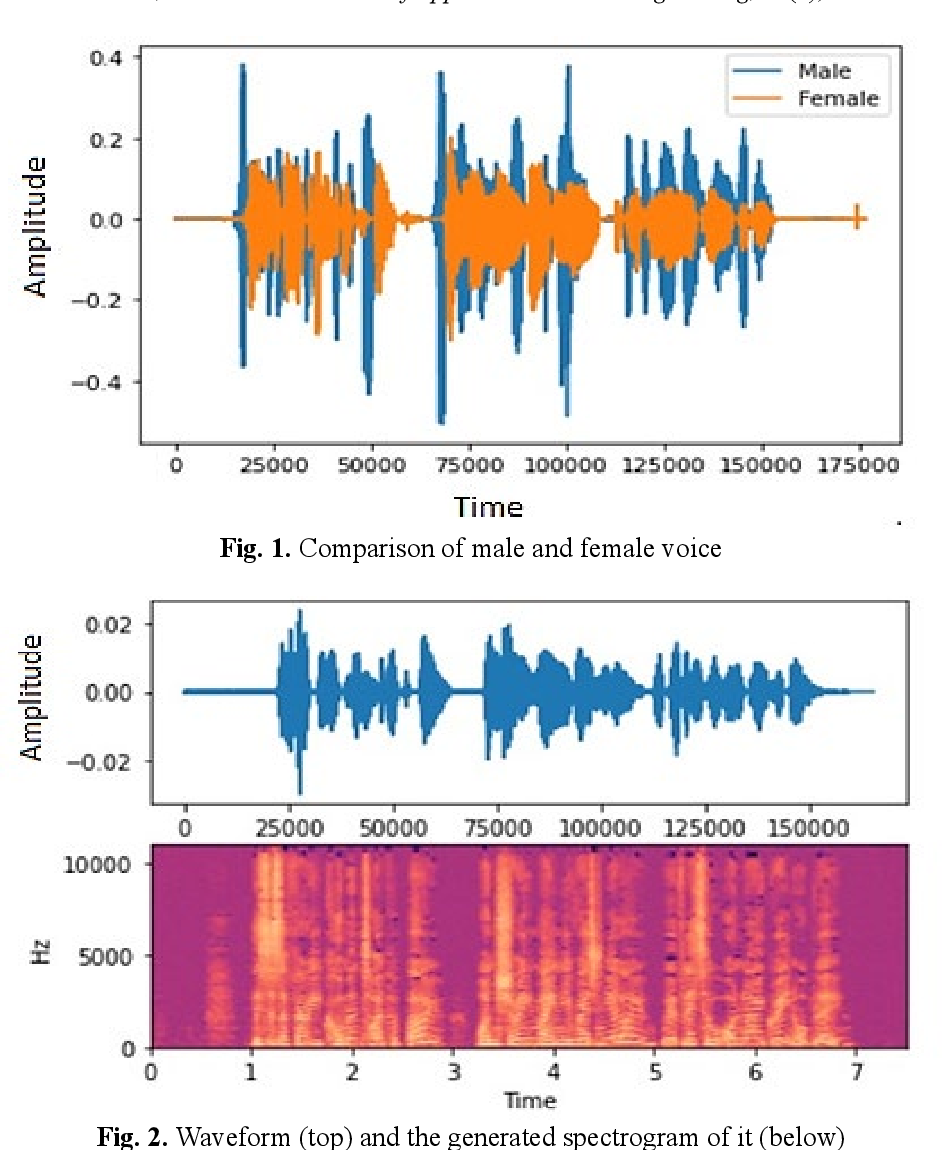
Figure 1 from Audio style conversion using deep learning | Semantic Scholar

Figure 1 from Low-latency Real-time Voice Conversion on CPU | Semantic ...
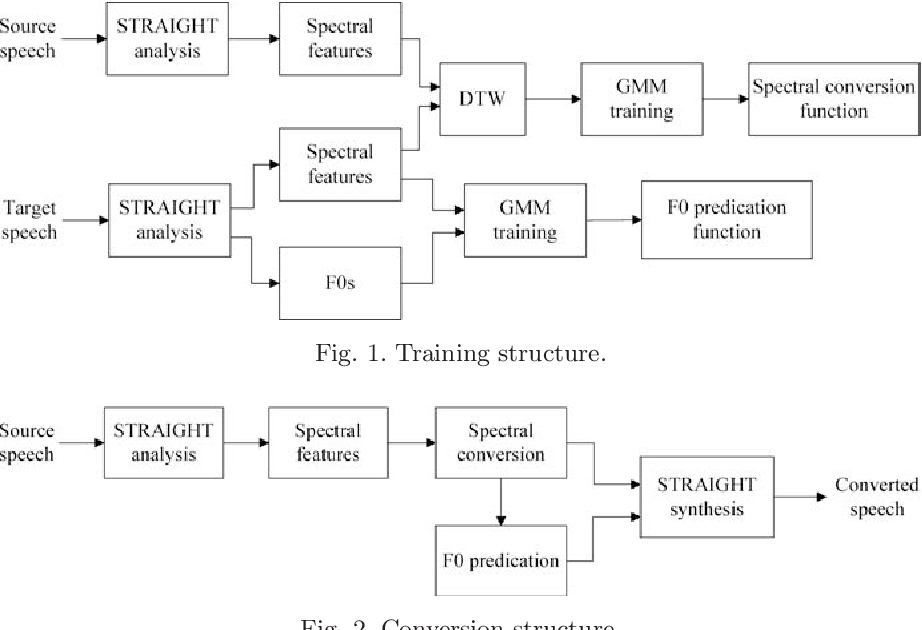
Figure 1 from Voice Conversion Based on Hybrid SVR and GMM | Semantic ...

Figure 1 from Any-to-One Sequence-to-Sequence Voice Conversion Using ...
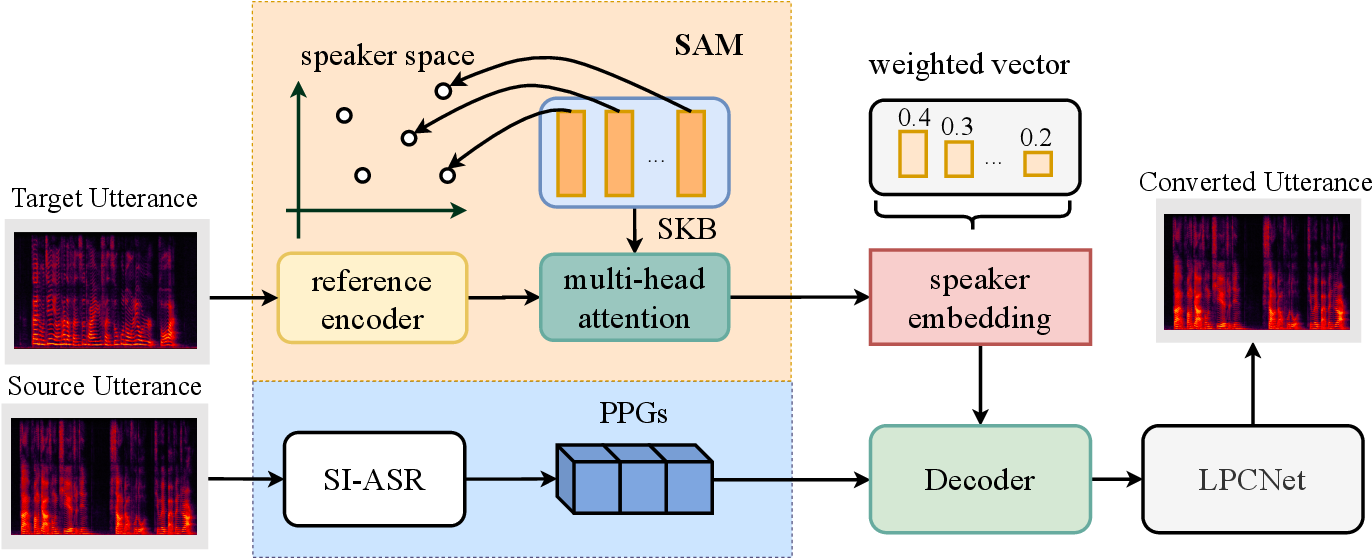
Figure 1 from One-Shot Voice Conversion Based on Speaker Aware Module ...

Figure 1 from A Voice Conversion Framework with Tandem Feature Sparse ...
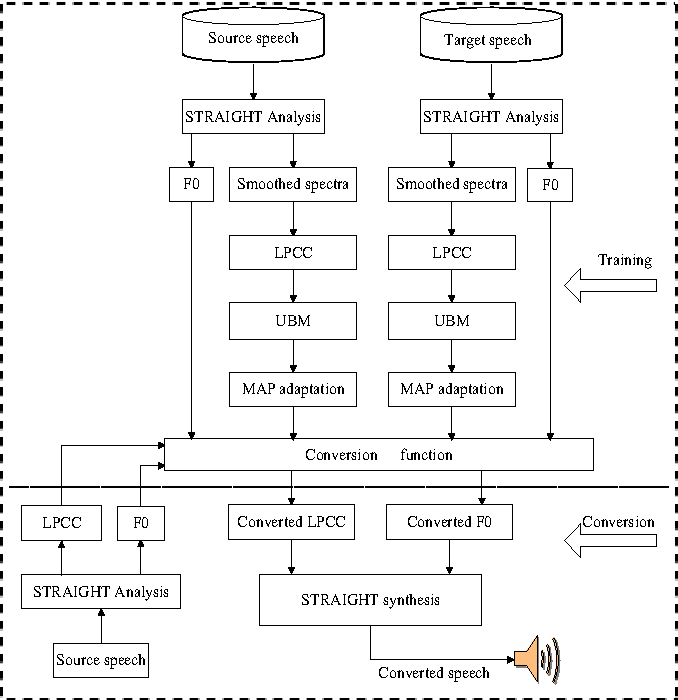
Figure 1 from Voice conversion with UBM and speaker-specific model ...
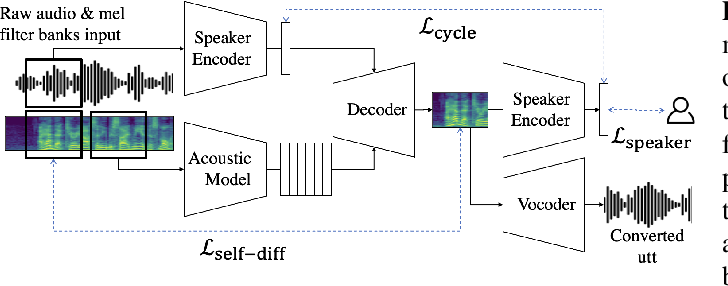
Figure 1 from Training Robust Zero-Shot Voice Conversion Models with ...
Advertisement Space (336x280)
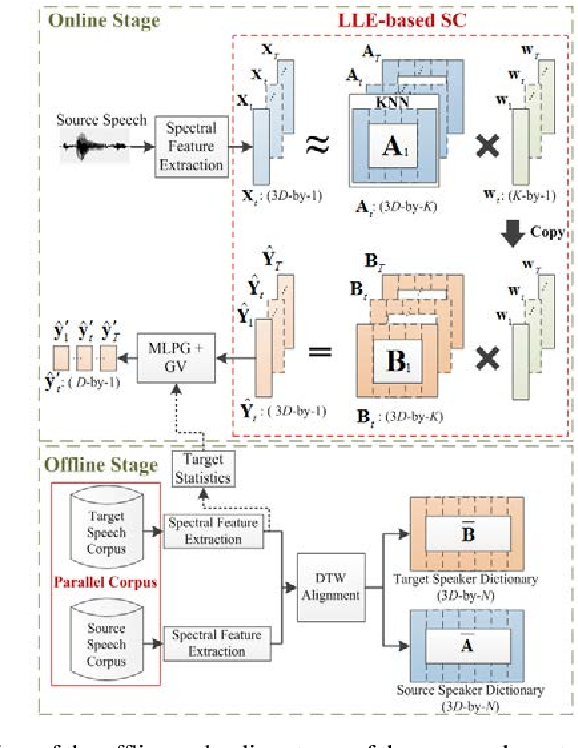
Figure 1 from Voice Conversion Based on Locally Linear Embedding ...

Figure 1 from An Evaluation of Three-Stage Voice Conversion Framework ...

Figure 1 from DVQVC: An Unsupervised Zero-Shot Voice Conversion ...

Figure 1 from Non-Autoregressive Sequence-To-Sequence Voice Conversion ...

Figure 1 from The NU Non-Parallel Voice Conversion System for the Voice ...

Figure 1 from SelfVC: Voice Conversion With Iterative Refinement using ...

Figure 1 from CASIA Voice Conversion System for the Voice Conversion ...
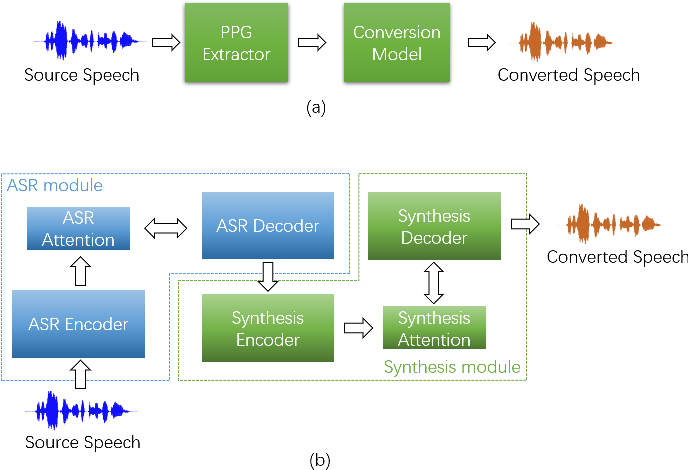
Figure 1 from Any-to-Many Voice Conversion With Location-Relative ...

Figure 1 from Towards Fine-Grained Prosody Control for Voice Conversion ...

Figure 1 from GMM-Based Emotional Voice Conversion Using Spectrum and ...
Advertisement Space (336x280)

Figure 1 from Statistical Voice Conversion with Quasi-Periodic WaveNet ...

Figure 1 from ATTS2S-VC: Sequence-to-sequence Voice Conversion with ...

Figure 1 from Voice Conversion Augmentation for Speaker Recognition on ...
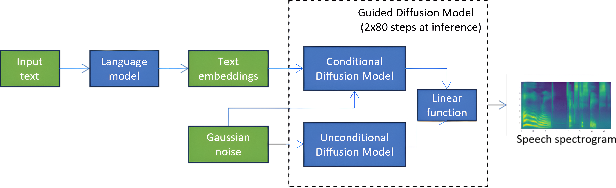
Figure 1 from Text-to-Voice Conversion for Indic Languages | Semantic ...
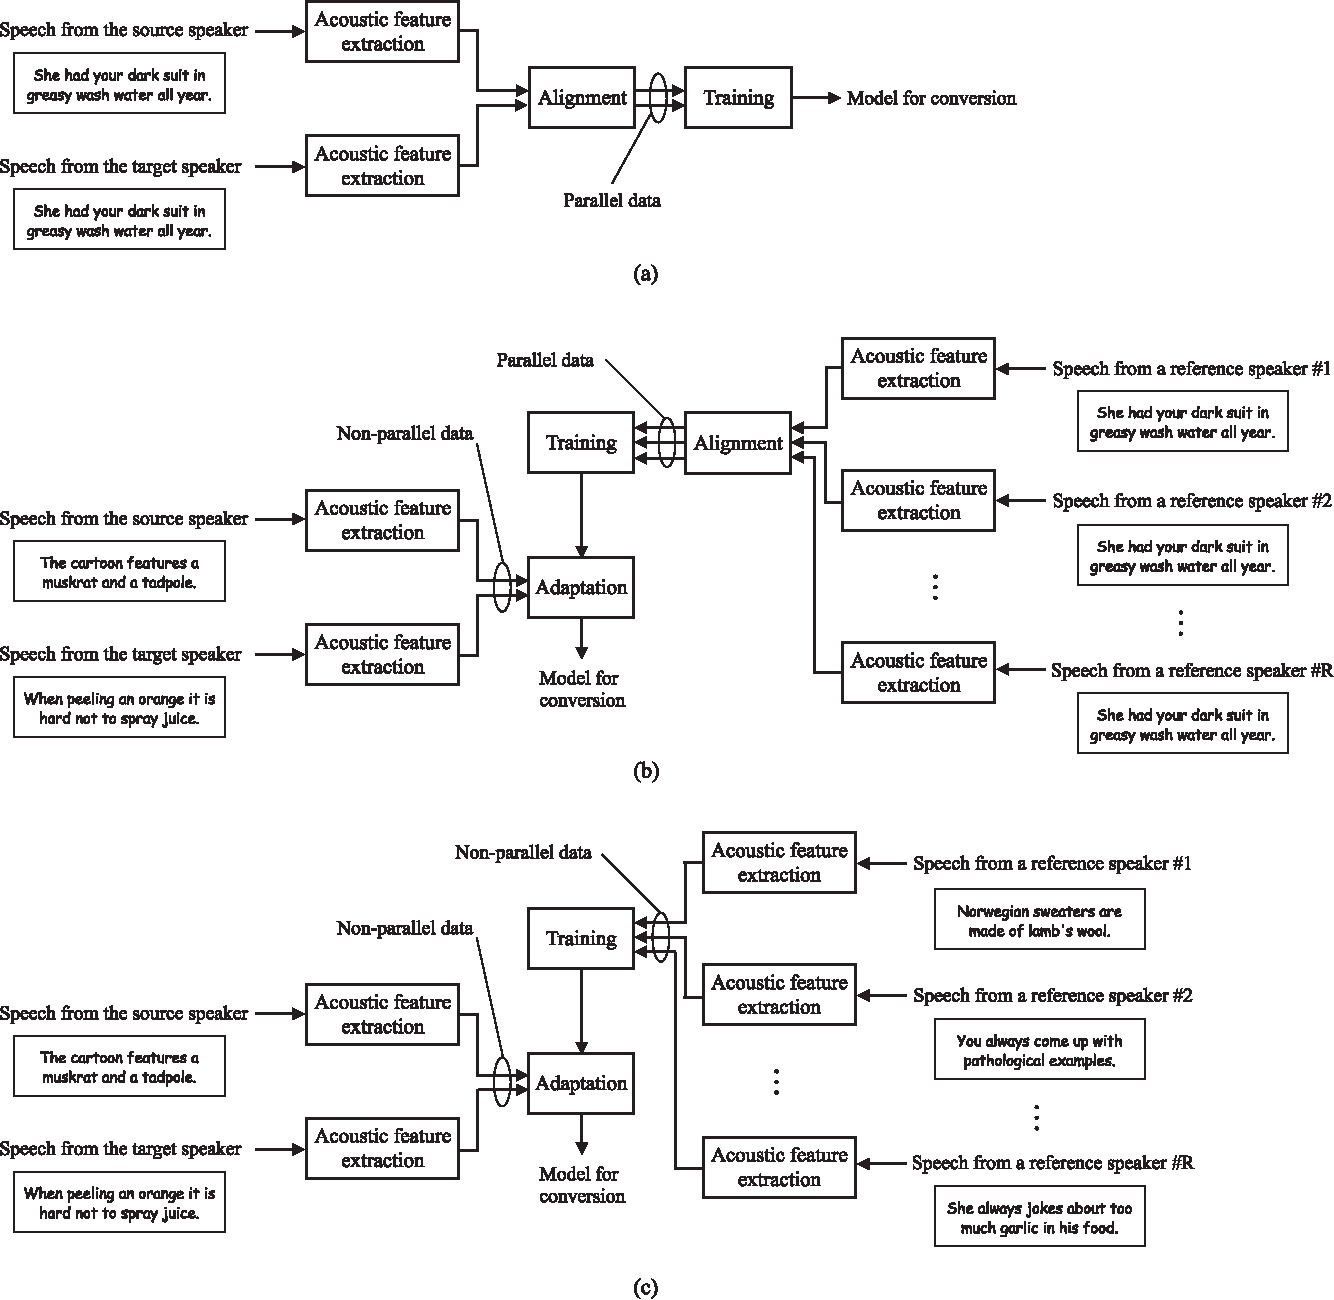
Figure 1 from Non-Parallel Training in Voice Conversion Using an ...
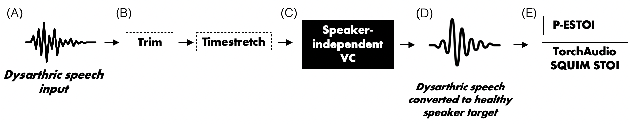
Figure 1 from Towards Speaker-Independent Voice Conversion for ...