
Figure 1 From Contrastive Self Supervised Speaker Embedding With

Figure 1 from Contrastive Self-Supervised Speaker Embedding With ...
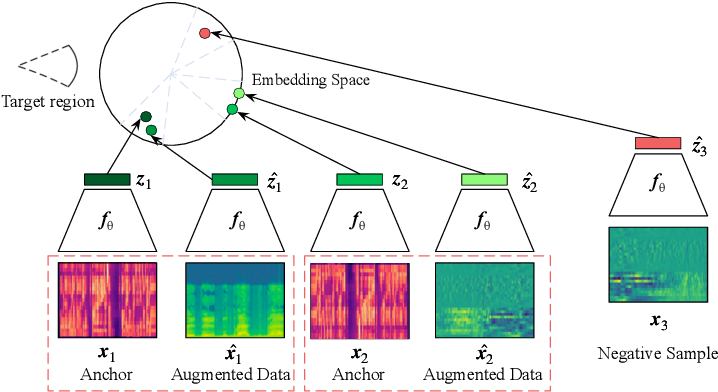
Figure 1 from Speaker Representation Learning via Contrastive Loss with ...

Figure 1 from Label-Efficient Self-Supervised Speaker Verification With ...
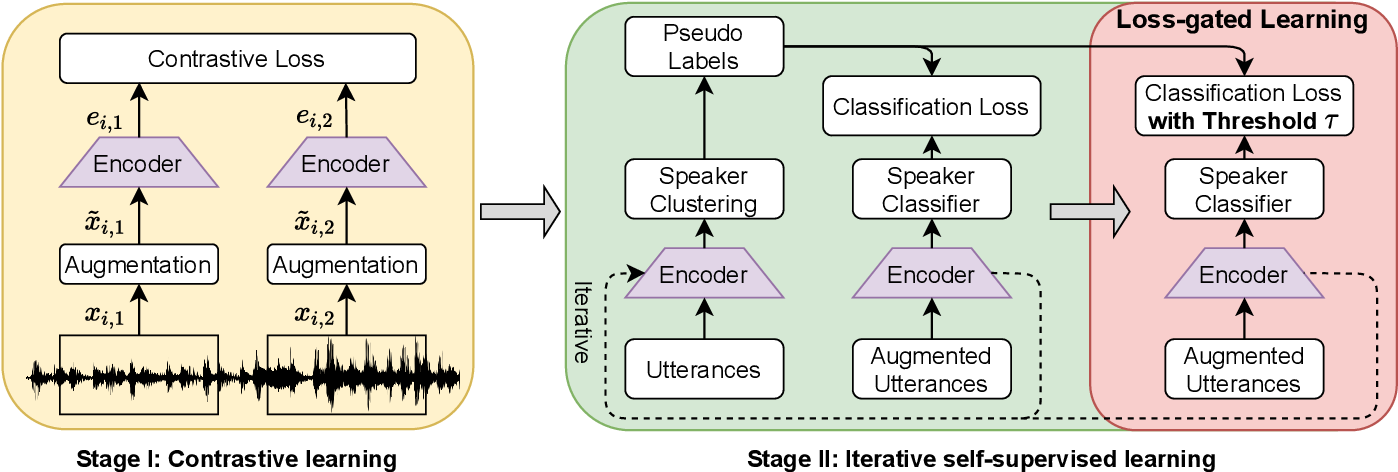
Figure 1 from Self-Supervised Speaker Recognition with Loss-Gated ...

Figure 1 from On Higher Adversarial Susceptibility of Contrastive Self ...

Figure 1 from Self-Supervised Open-Set Speaker Recognition with ...
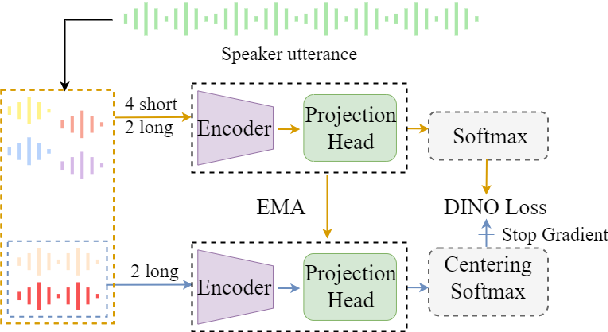
Figure 1 from Self-Supervised Speaker Verification with Mini-Batch ...

Figure 1 from Self-Supervised Speaker Verification with Adaptive ...
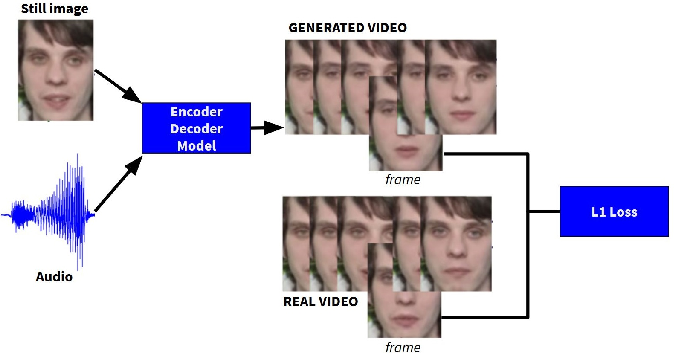
Figure 1 from Visually Guided Self Supervised Learning of Speech ...

Figure 1 from Vision-Guided Speaker Embedding Based Speech Separation ...
Advertisement Space (300x250)
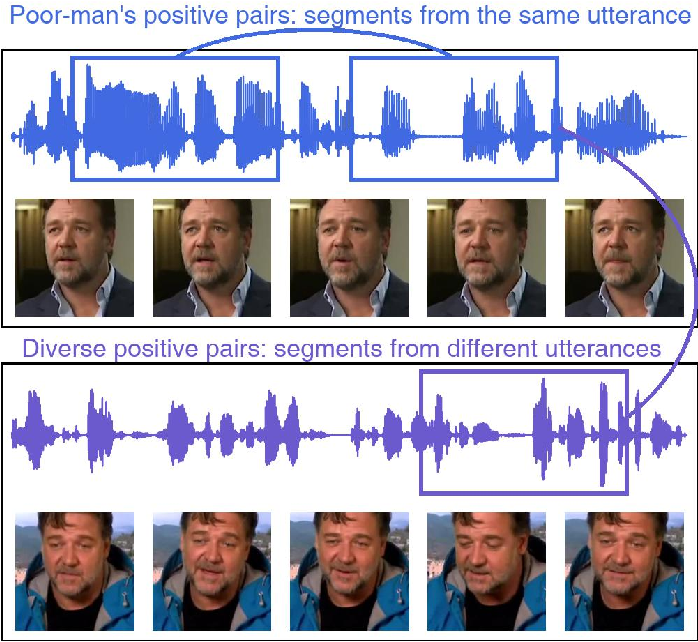
Figure 1 from Self-Supervised Training of Speaker Encoder With Multi ...

Figure 1 from Self-Supervised Audio-Visual Speaker Representation with ...
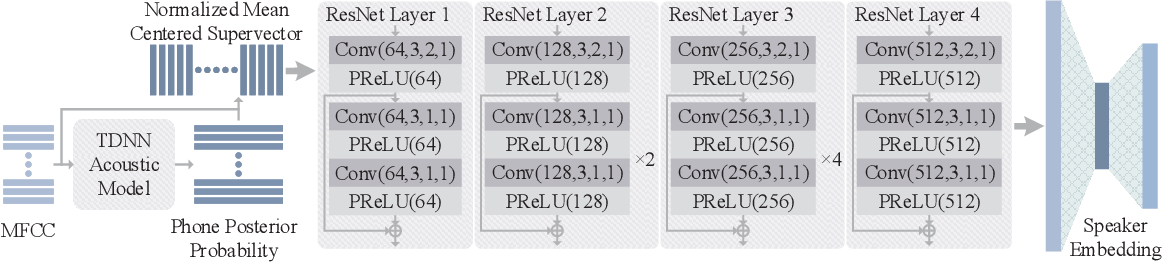
Figure 1 from Deep Speaker Embeddings with Convolutional Neural Network ...
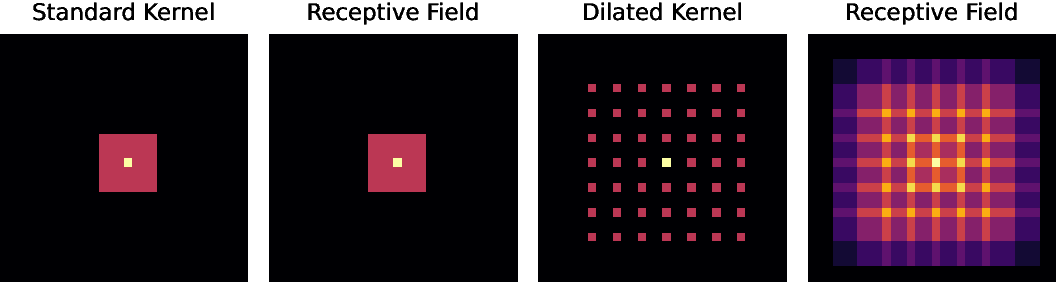
Figure 1 from Self-Supervised Open-Set Speaker Recognition with ...

Figure 1 from Label-Efficient Self-Supervised Speaker Verification With ...
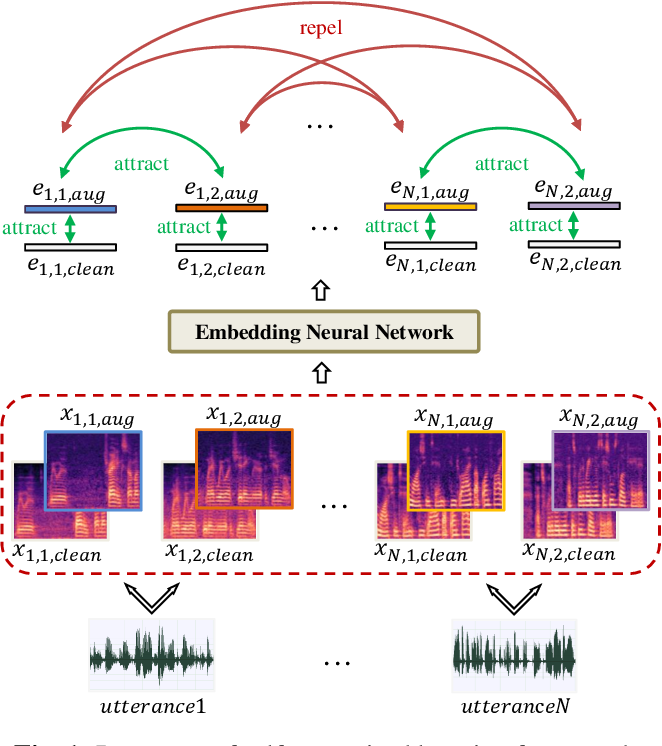
Figure 1 from Contrastive Self-Supervised Learning for Text-Independent ...

Figure 1 from Self-Supervised Text-Independent Speaker Verification ...
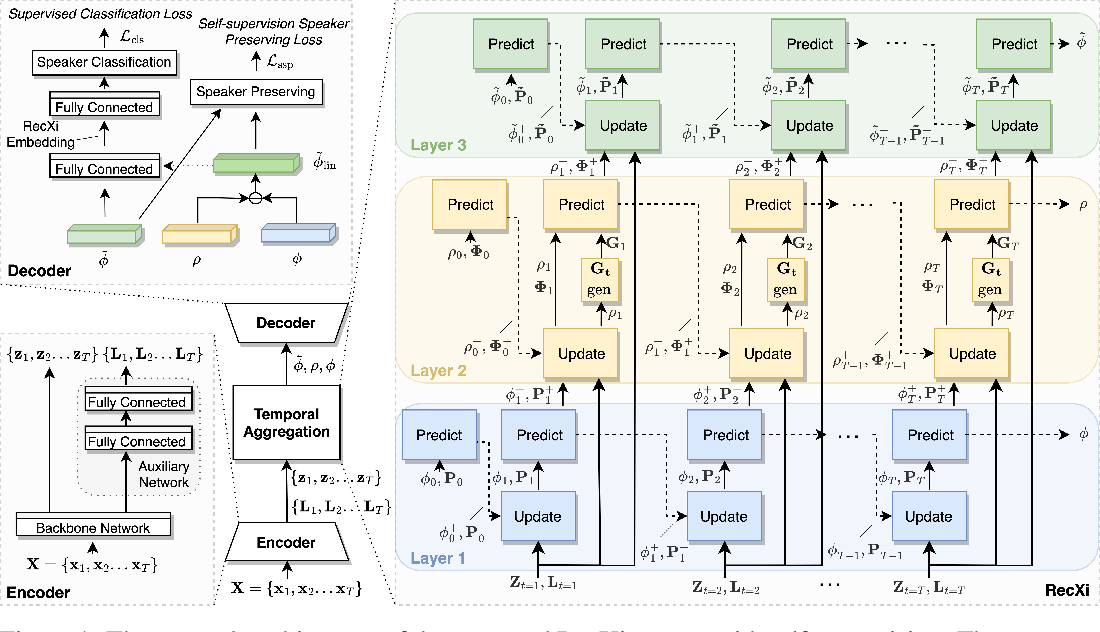
Figure 1 from Disentangling Voice and Content with Self-Supervision for ...
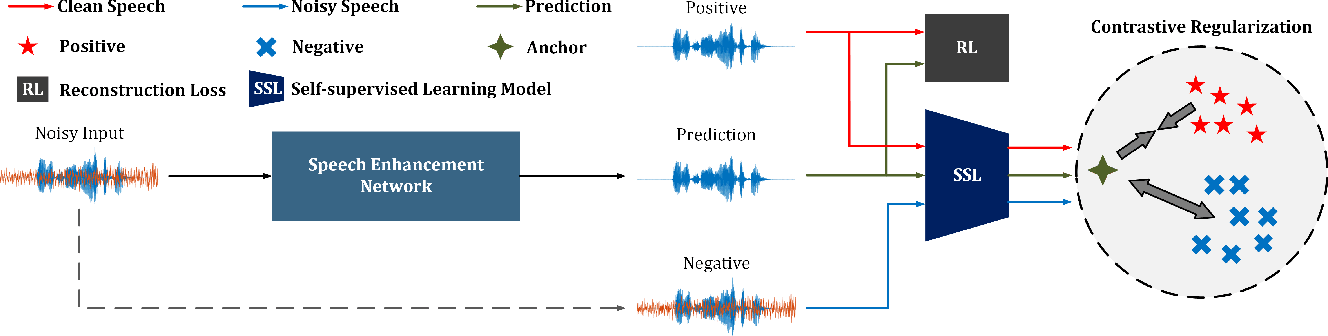
Figure 1 from Curricular Contrastive Regularization for Speech ...
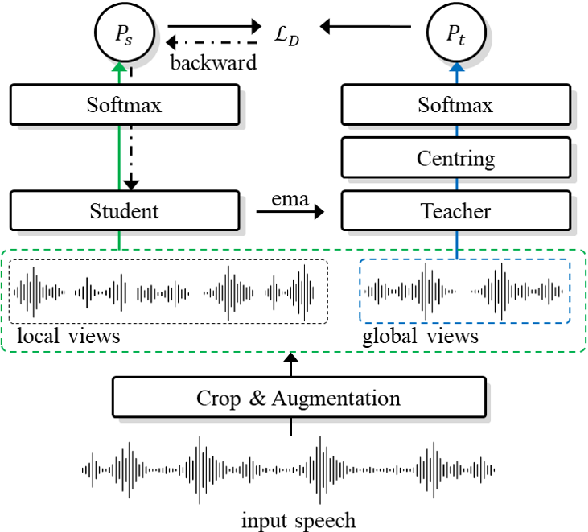
Figure 1 from Self-supervised curriculum learning for speaker ...
Advertisement Space (336x280)
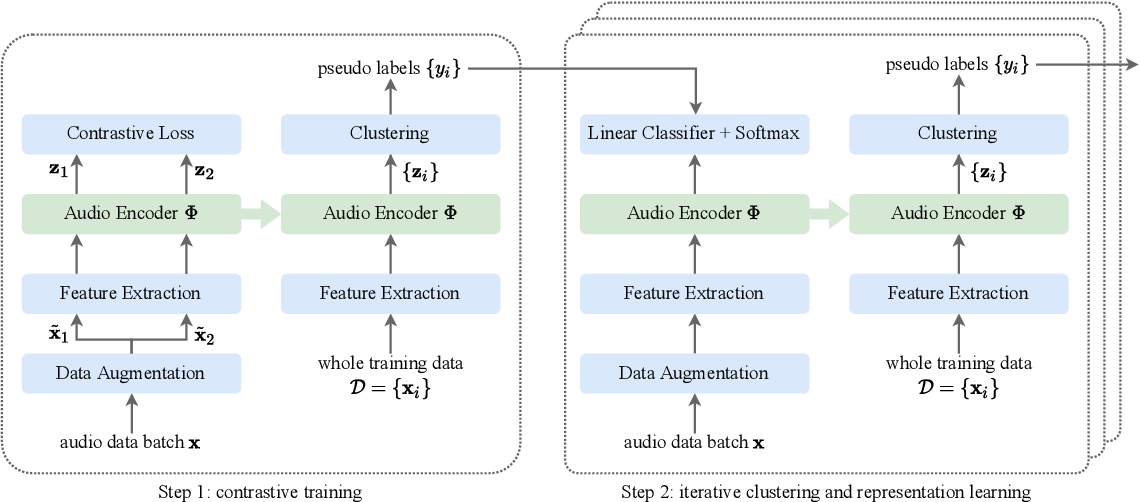
Figure 1 from Incorporating Visual Information in Audio Based Self ...

Figure 1 from Self-Supervised Speaker Verification Using Dynamic Loss ...

Figure 1 from Enhanced Self-Supervised Speaker Diarization Framework ...
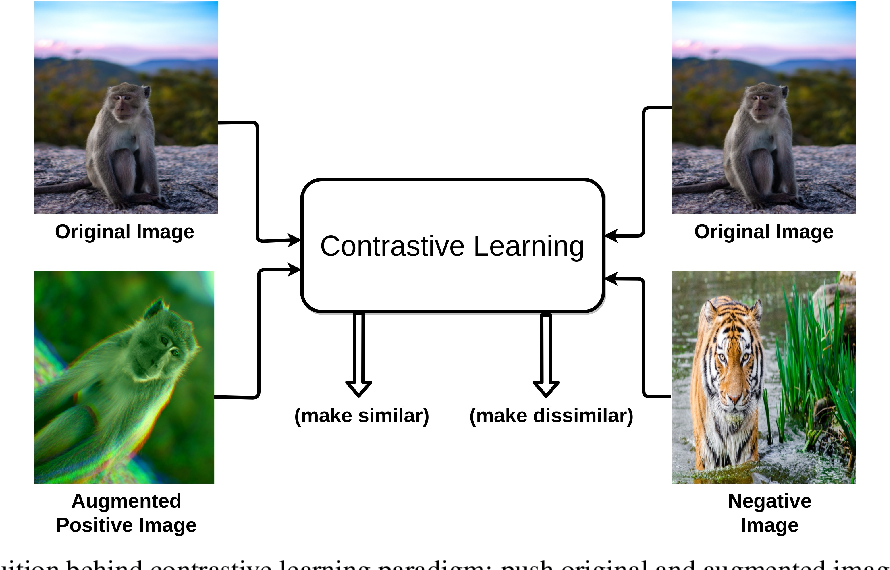
Figure 1 from A Survey on Contrastive Self-supervised Learning ...
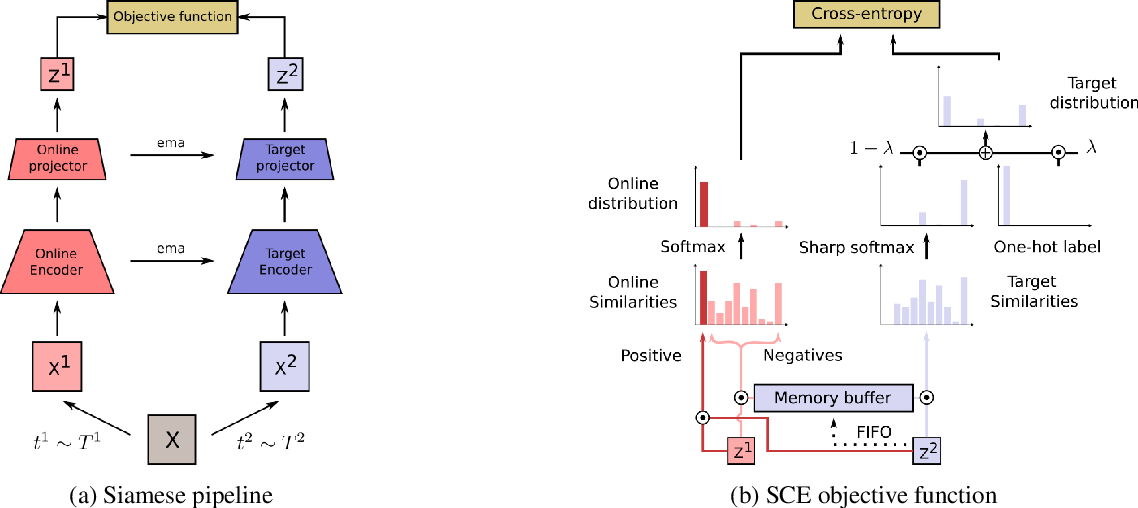
Figure 1 from Similarity Contrastive Estimation for Self-Supervised ...
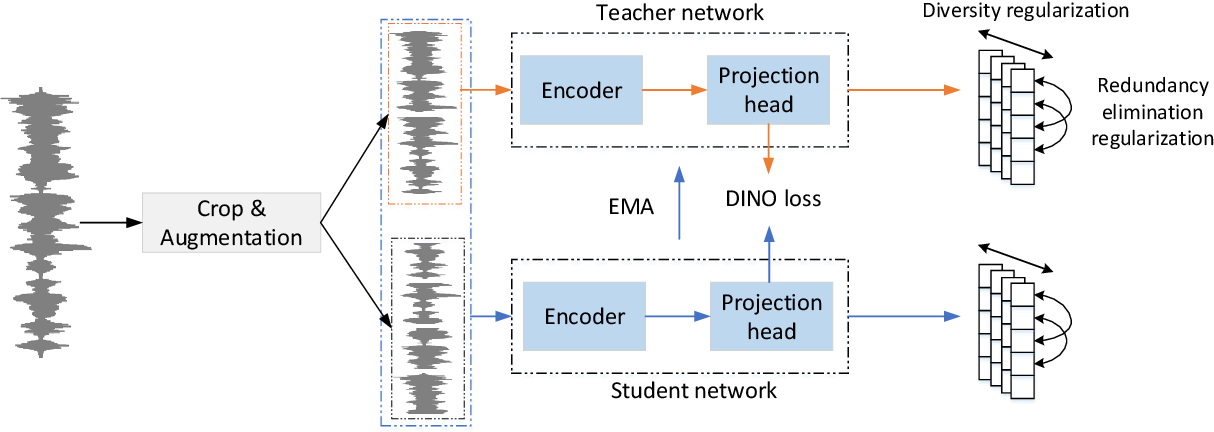
Figure 1 from Pushing the Limits of Self-Supervised Speaker ...

Figure 1 from What Do Self-Supervised Speech and Speaker Models Learn ...
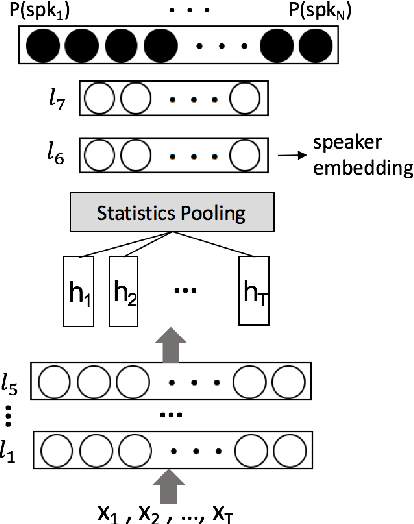
Figure 1 from Self-Attentive Speaker Embeddings for Text-Independent ...
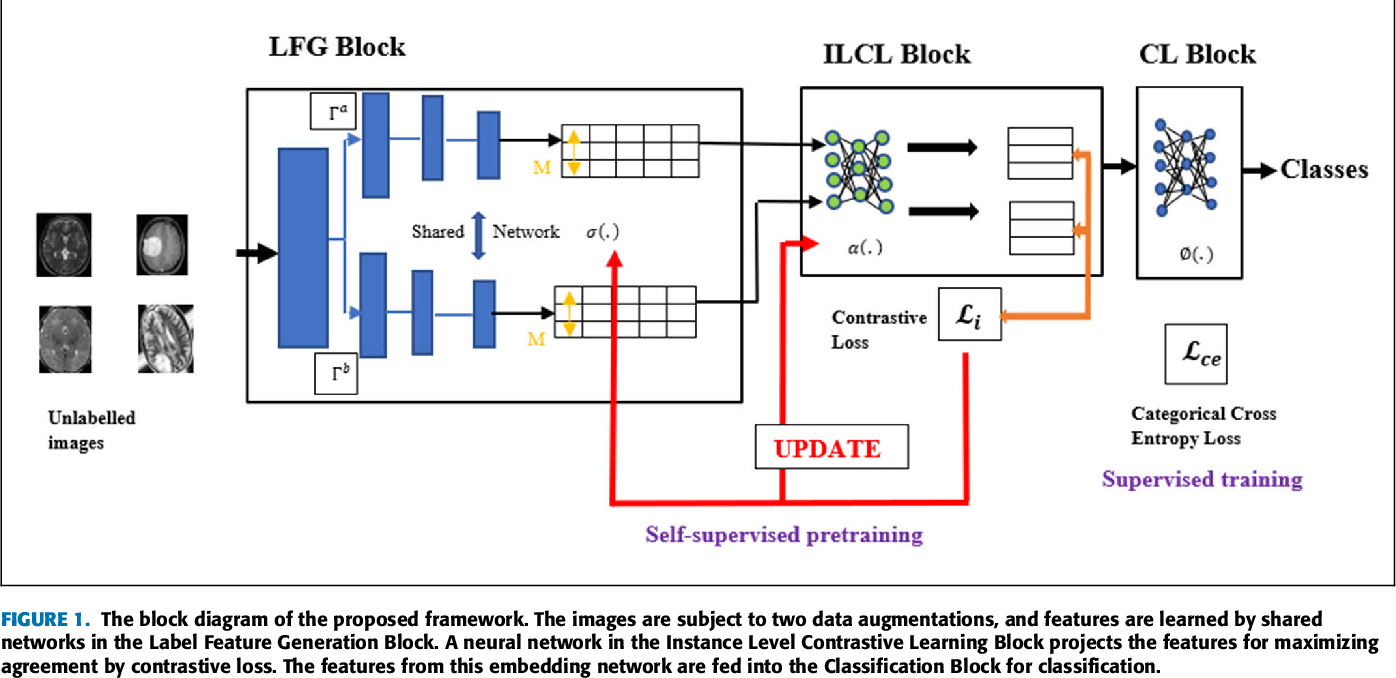
Figure 1 from SSCLNet: A Self-Supervised Contrastive Loss-Based Pre ...
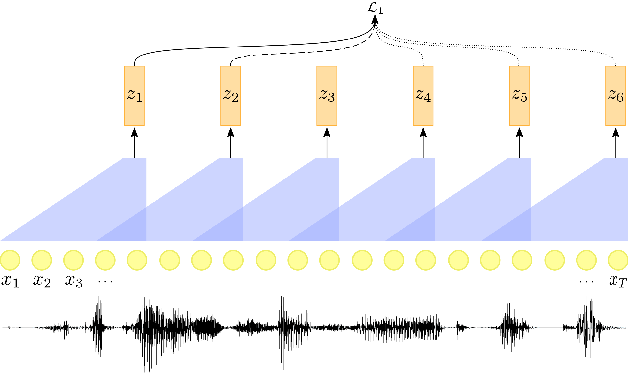
Figure 1 from Self-Supervised Contrastive Learning for Unsupervised ...
Advertisement Space (336x280)

Figure 1 from Self-Supervised Triplet Contrastive Learning for ...
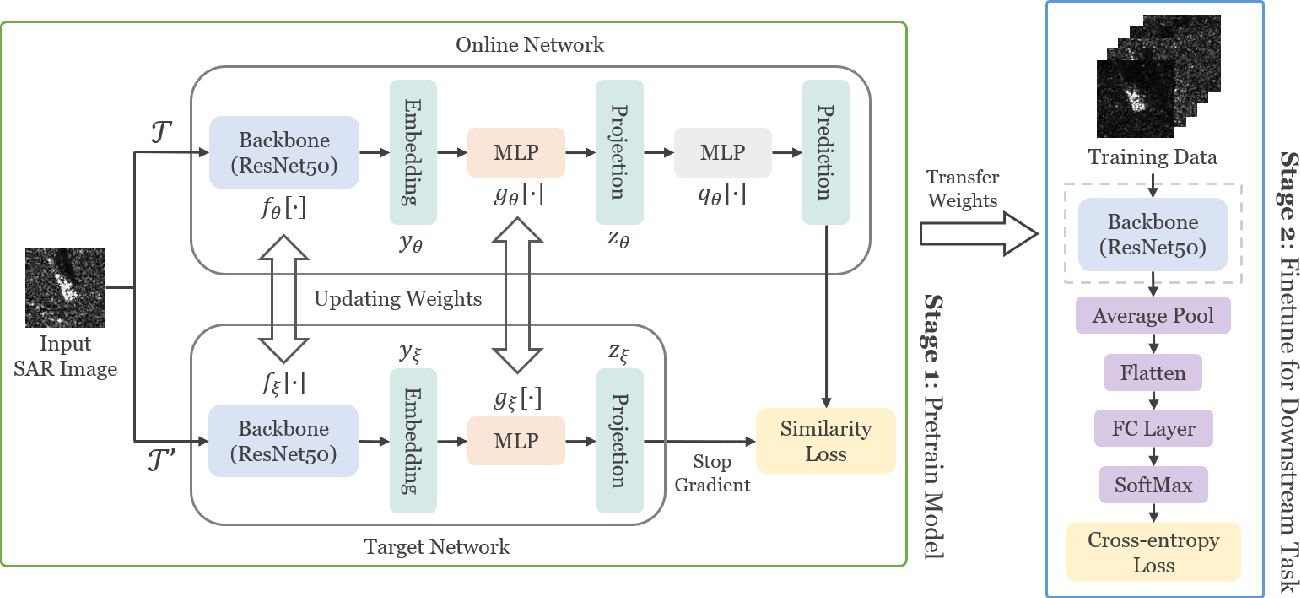
Figure 1 from Self-Supervised Contrastive Learning on Cross-Augmented ...
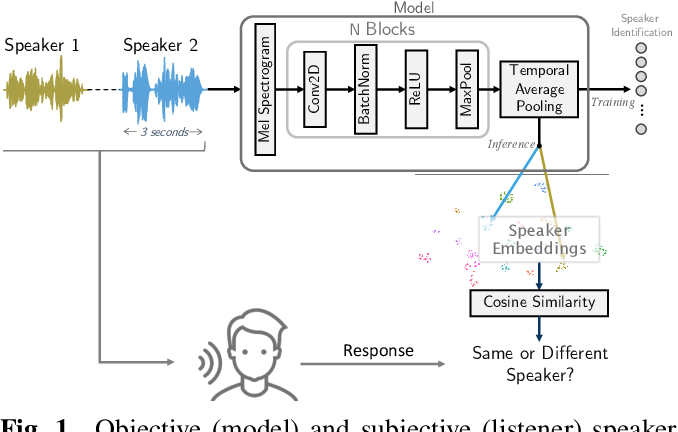
Figure 1 from Perceptual Analysis of Speaker Embeddings for Voice ...
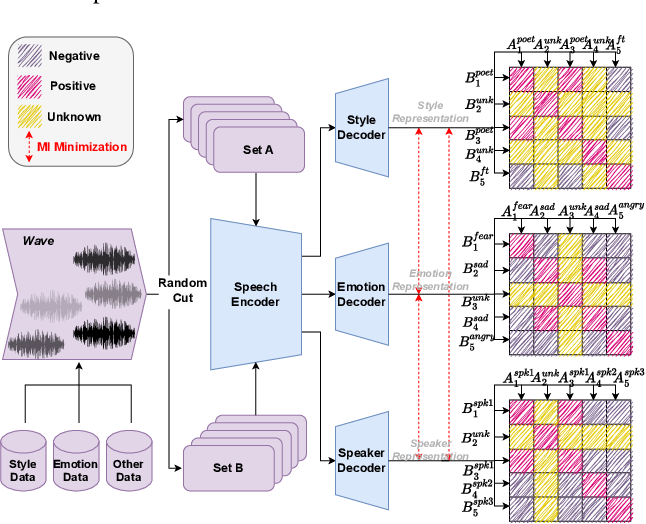
Figure 1 from Boosting Multi-Speaker Expressive Speech Synthesis with ...

Figure 1 from Self-Supervised Learning from Contrastive Mixtures for ...
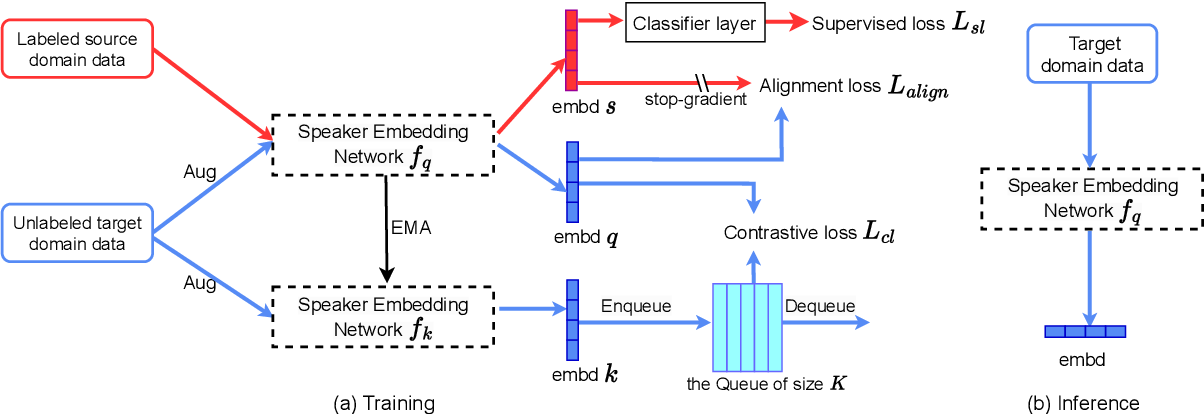
Figure 1 from Contrastive Learning and Inter-Speaker Distribution ...