
Figure 1 From Diffvoice Text To Speech With Latent Diffusion
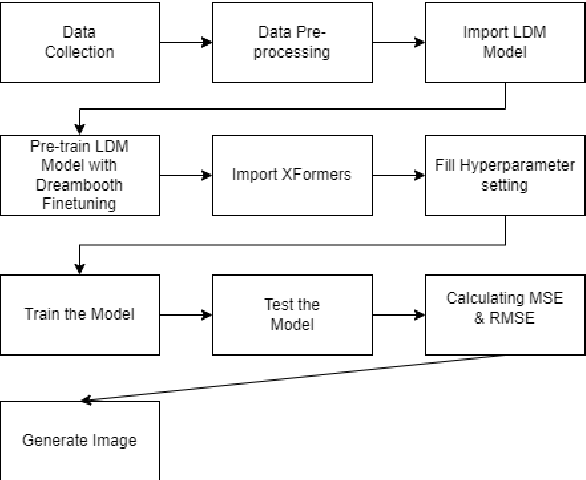
Figure 1 from Text to Image Latent Diffusion Model with Dreambooth Fine ...

Figure 1 from High-Resolution Speech Restoration with Latent Diffusion ...

Figure 1 from High-Resolution Speech Restoration with Latent Diffusion ...

Figure 1 from High-Resolution Speech Restoration with Latent Diffusion ...

Figure 1 from DiffVoice: Text-to-Speech with Latent Diffusion ...

Figure 1 from AudioLDM: Text-to-Audio Generation with Latent Diffusion ...

Figure 1 from Target Speech Extraction with Conditional Diffusion Model ...
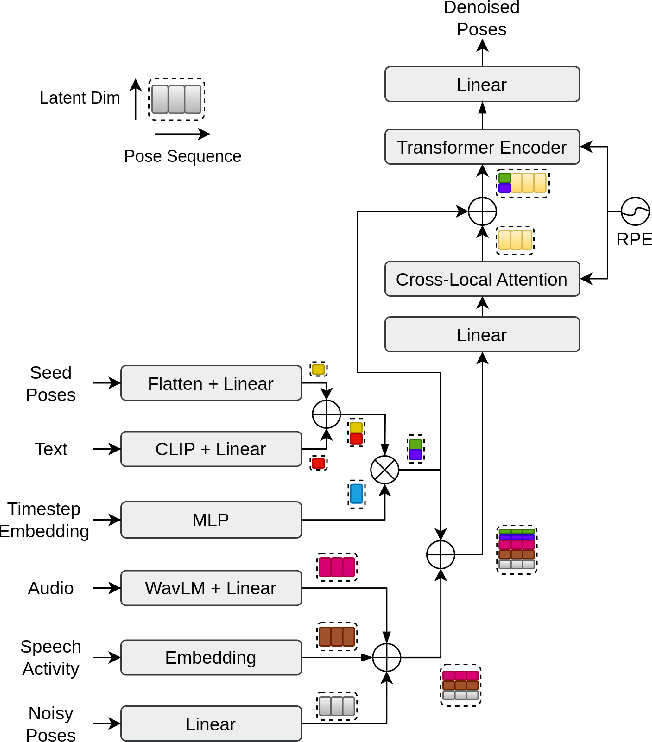
Figure 1 from Gesture Generation with Diffusion Models Aided by Speech ...

Figure 1 from Enhancing Unsupervised Speech Recognition with Diffusion ...

Figure 1 from LDM-SVC: Latent Diffusion Model Based Zero-Shot Any-to ...
Advertisement Space (300x250)

Figure 1 from Self-Discovering Interpretable Diffusion Latent ...

Figure 1 from Latent Diffusion Models for Structural Component Design ...

Figure 1 from LSegDiff: A Latent Diffusion Model for Medical Image ...

Figure 1 from A Latent Diffusion Model for Protein Structure Generation ...

Figure 1 from ViT-TTS: Visual Text-to-Speech with Scalable Diffusion ...

Figure 1 from Improving End-to-End Speech Processing by Efficient Text ...
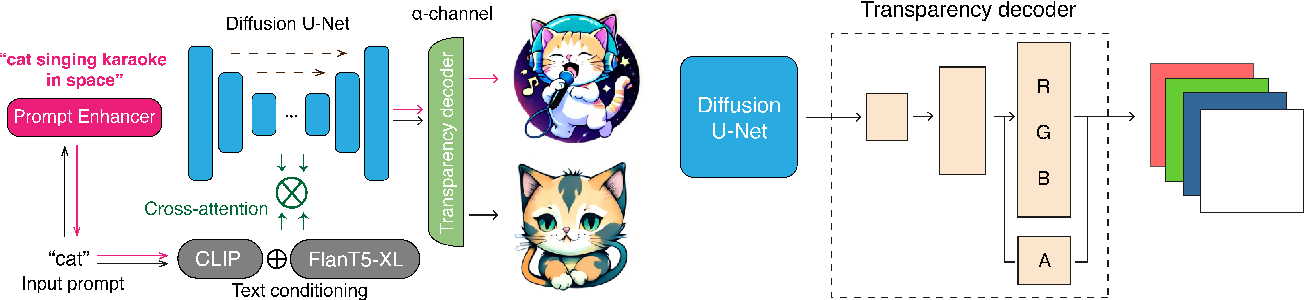
Figure 1 from Text-to-Sticker: Style Tailoring Latent Diffusion Models ...

Figure 1 from Continuous Speech Synthesis using per-token Latent ...

Figure 3 from Text-driven Visual Synthesis with Latent Diffusion Prior ...

Figure 1 from Text-To-Speech Synthesis Based on Latent Variable ...
Advertisement Space (336x280)

Figure 1 from On the Semantic Latent Space of Diffusion-Based Text-to ...

Figure 1 from Guided-TTS: A Diffusion Model for Text-to-Speech via ...

Table 1 from Realistic Speech-to-Face Generation with Speech ...

Figure 1 from Duplex Diffusion Models Improve Speech-to-Speech ...

Figure 1 from On the Semantic Latent Space of Diffusion-Based Text-to ...

Audio Diffusion Models Explained. How Text to Speech works | by Zaina ...
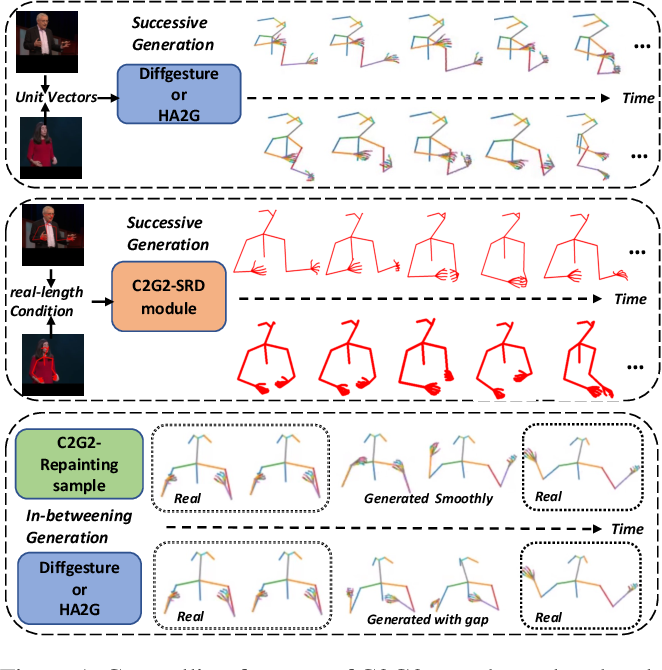
Figure 1 from C2G2: Controllable Co-speech Gesture Generation with ...

Figure 1 from Guided-TTS 2: A Diffusion Model for High-quality Adaptive ...

Figure 1 from Diffusion-Based Generative Speech Source Separation ...
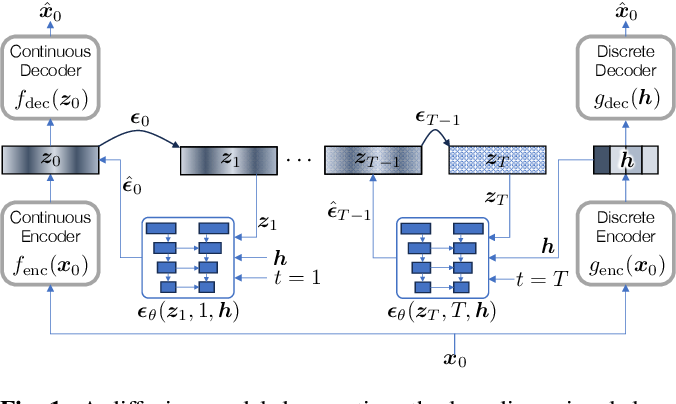
Figure 1 from Generative De-Quantization for Neural Speech Codec Via ...
Advertisement Space (336x280)

Figure 1 from Speech Signal Improvement Using Causal Generative ...

[2303.13336] A Survey on Audio Diffusion Models: Text To Speech ...

ZSVC: Zero-shot Style Voice Conversion with Latent Diffusion Models

Utilizing Latent Diffusion Model to Accelerate Sampling Speed and ...

Enhancing Paragraph Generation with a Latent Language Diffusion Model ...

Utilizing Latent Diffusion Model to Accelerate Sampling Speed and ...