
Figure 1 From Disentangled Speaker And Nuisance Attribute Embedding For

Figure 1 from Disentangled Speaker and Nuisance Attribute Embedding for ...

Figure 1 from Disentangled Speaker and Nuisance Attribute Embedding for ...

(PDF) Disentangled Speaker and Nuisance Attribute Embedding for Robust ...
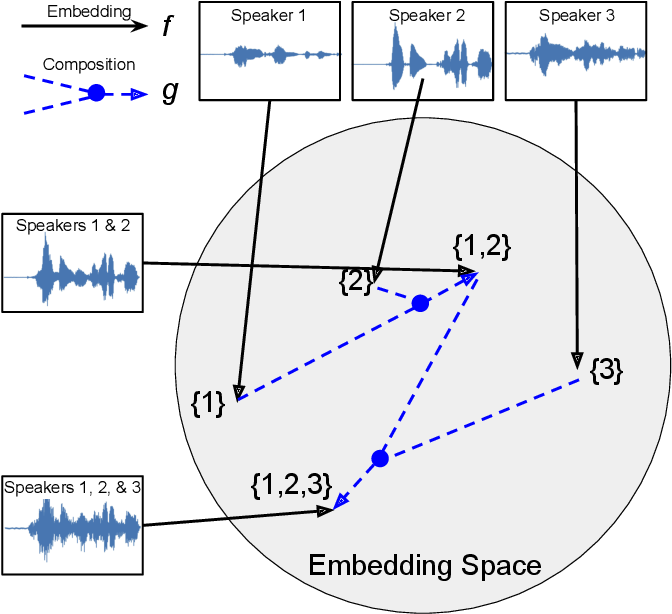
Figure 1 from Compositional Embedding Models for Speaker Identification ...
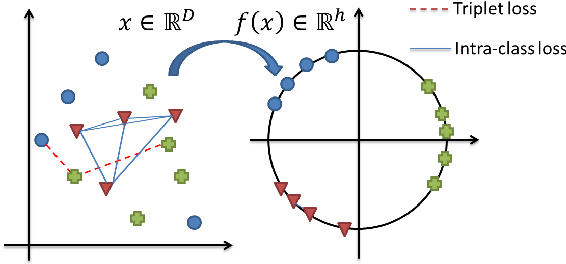
Figure 1 from Robust and Discriminative Speaker Embedding via Intra ...

Table 1 from Disentangled Speaker Embedding for Robust Speaker ...

Figure 1 from Joint Speech-Text Embeddings with Disentangled Speaker ...
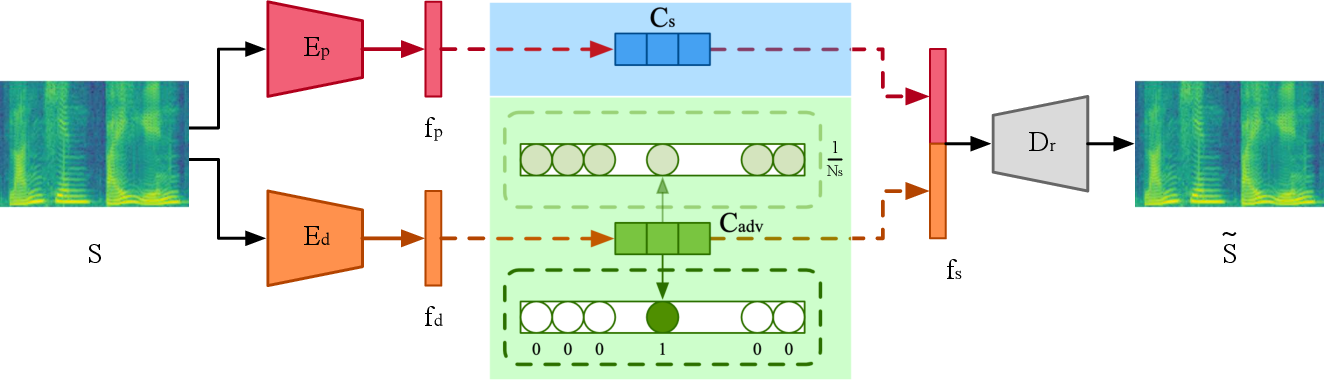
Figure 1 from Powerful Speaker Embedding Training Framework by ...

Figure 1 from Disentangled dimensionality reduction for noise-robust ...

Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
Advertisement Space (300x250)
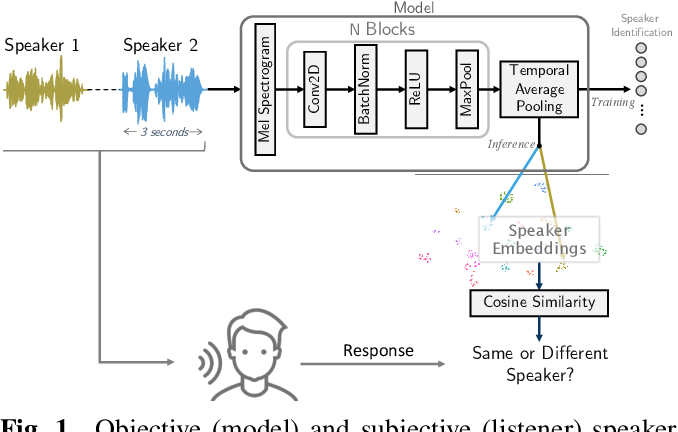
Figure 1 from Perceptual Analysis of Speaker Embeddings for Voice ...

Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
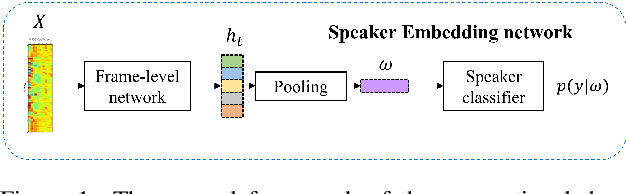
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from Vision-Guided Speaker Embedding Based Speech Separation ...
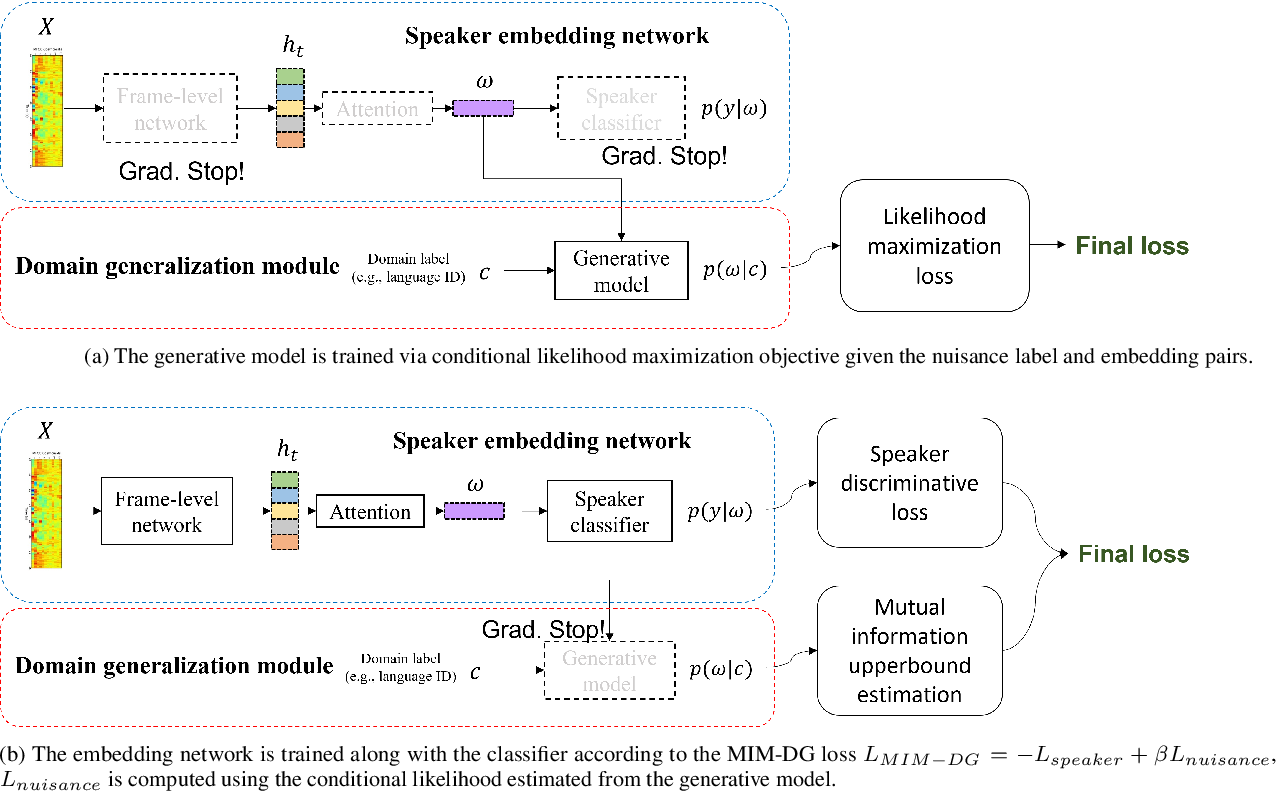
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...

Figure 1 from A Disentangled Recurrent Variational Autoencoder for ...

Figure 1 from Mutual Information-based Embedding Decoupling for ...

Figure 1 from Self-Supervised Disentangled Representation Learning for ...

Figure 1 from A Word-axis Speaker Embedding Trained with Multi-Speaker ...

Figure 1 from Disentangled Feature Learning for Real-Time Neural Speech ...
Advertisement Space (336x280)
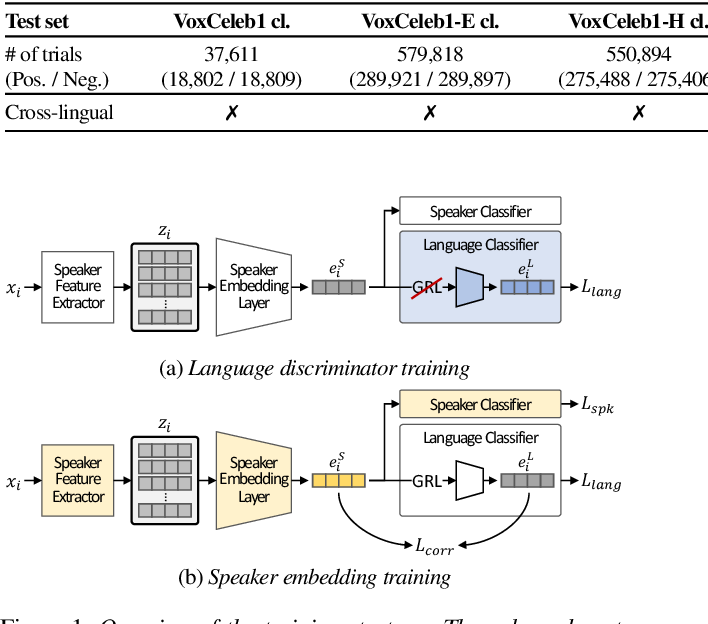
Figure 1 from Disentangled representation learning for multilingual ...
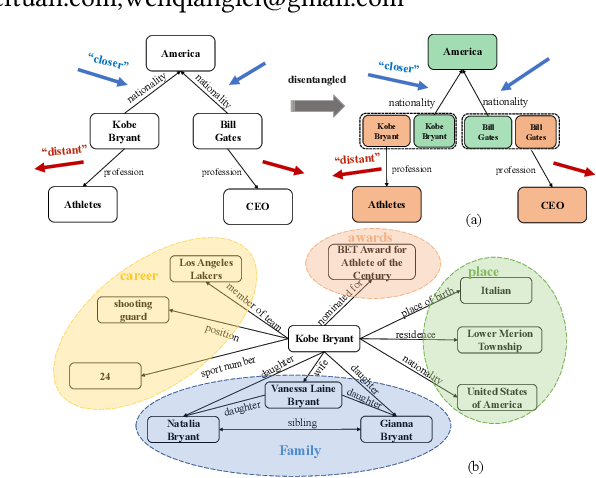
Figure 1 from DisenKGAT: Knowledge Graph Embedding with Disentangled ...

Figure 1 from Disentangled Prototypical Convolutional Network for Few ...

Figure 1 from Feature Disentangled for 3D Object Recognition | Semantic ...

Figure 1 from Channel Invariant Speaker Embedding Learning with Joint ...
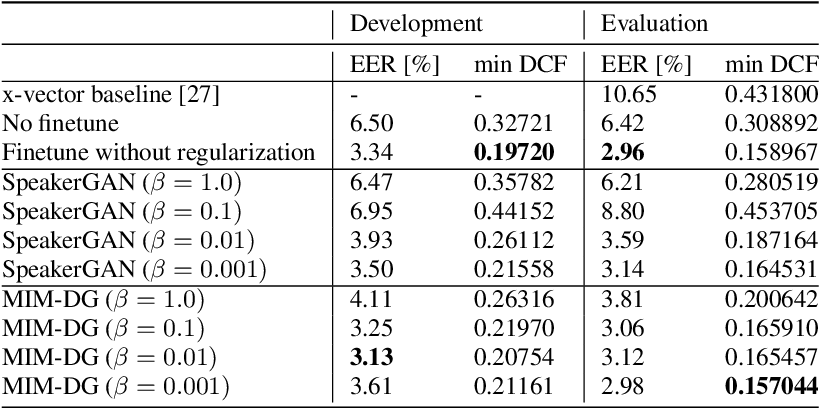
Figure 1 from Domain Generalized Speaker Embedding Learning via Mutual ...
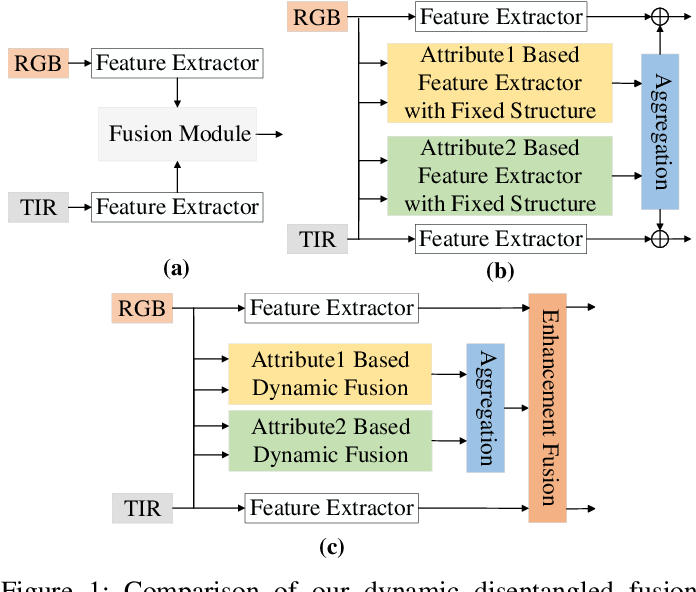
Figure 1 from Dynamic Disentangled Fusion Network for RGBT Tracking ...

[PDF] Disentangled Speaker Embedding for Robust Speaker Verification ...
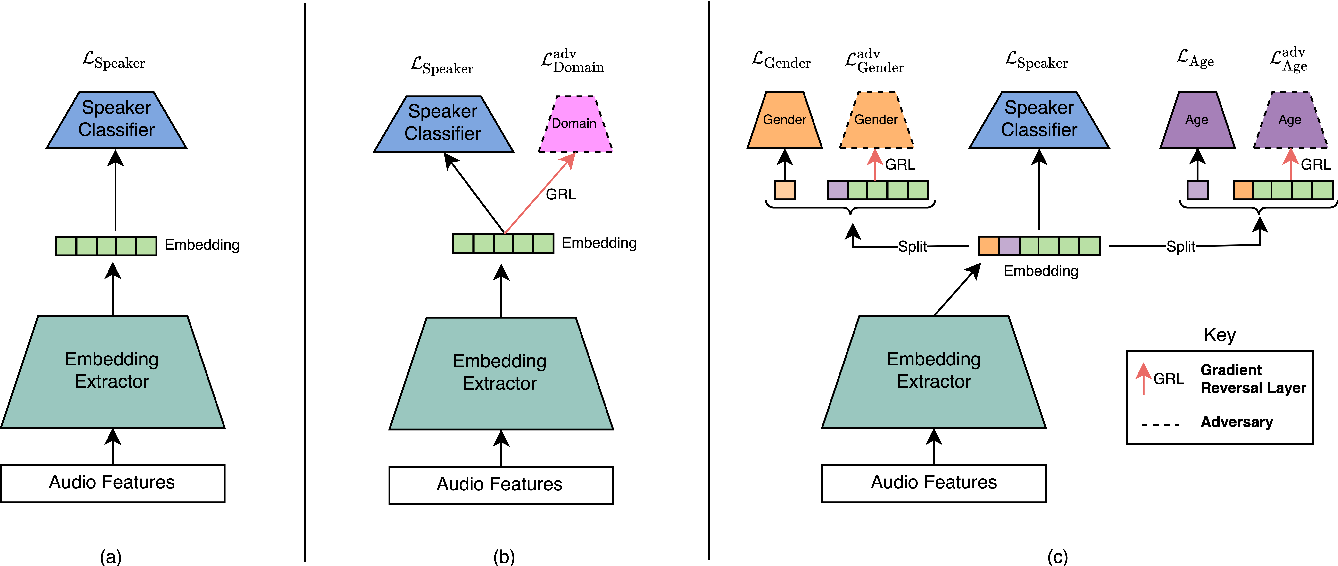
Figure 1 from Investigating the contribution of speaker attributes to ...
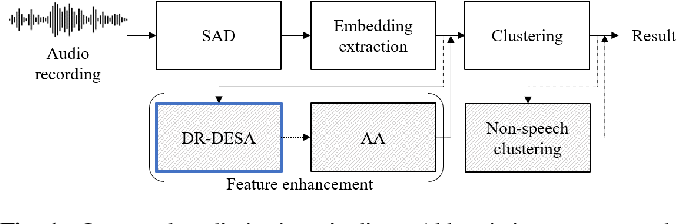
Figure 1 from Advancing the Dimensionality Reduction of Speaker ...
Advertisement Space (336x280)

Figure 2 from Joint Speech-Text Embeddings with Disentangled Speaker ...
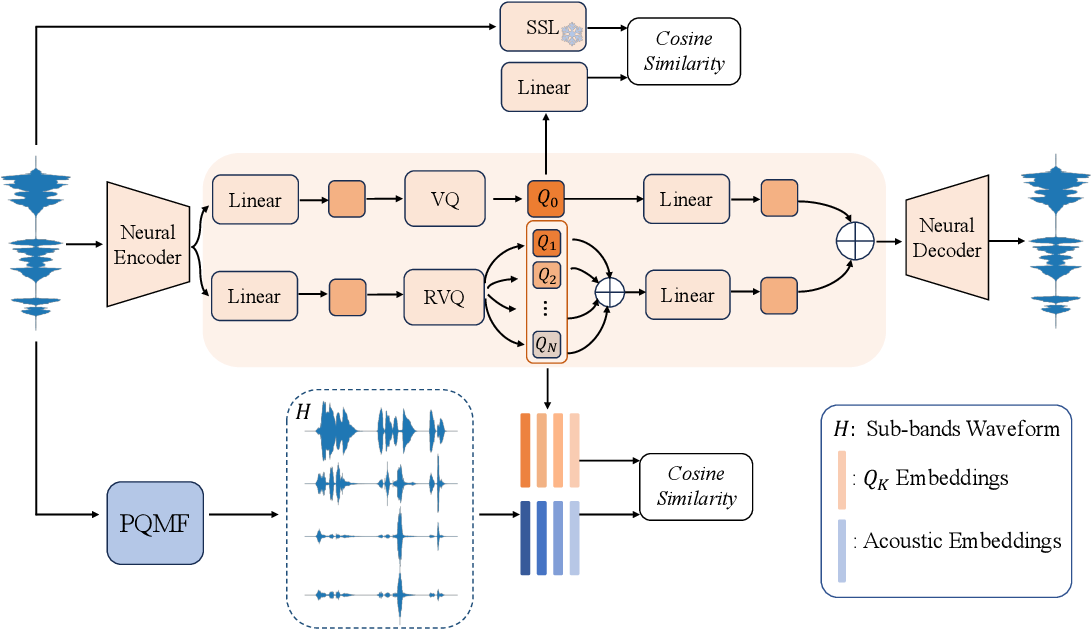
Figure 1 from MBCodec:Thorough disentangle for high-fidelity audio ...

Figure 1 from Improved Domain Generalization via Disentangled Multi ...

Figure 2 from Mutual Information-based Embedding Decoupling for ...

Figure 1 from Multi-Scale Speaker Embedding-Based Graph Attention ...

Figure 1 from Decomposition and Reorganization of Phonetic Information ...