
Figure 1 From Efficient Llm Inference Via Chunked Prefills Semantic
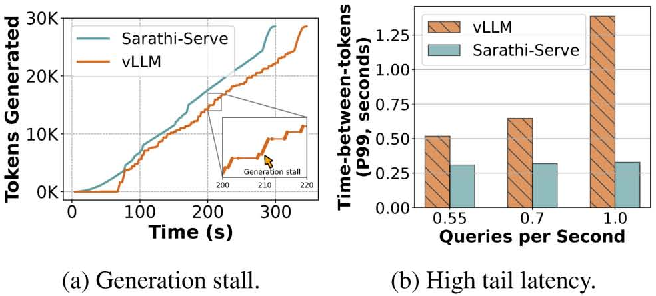
Figure 1 from Efficient LLM Inference via Chunked Prefills | Semantic ...
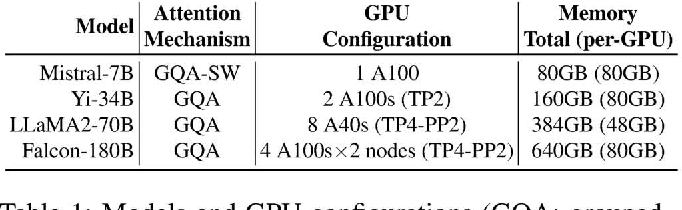
Table 1 from Efficient LLM Inference via Chunked Prefills | Semantic ...
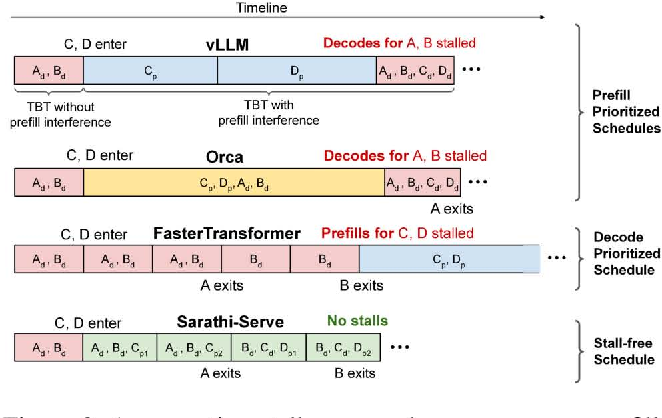
Figure 2 from Efficient LLM Inference via Chunked Prefills | Semantic ...
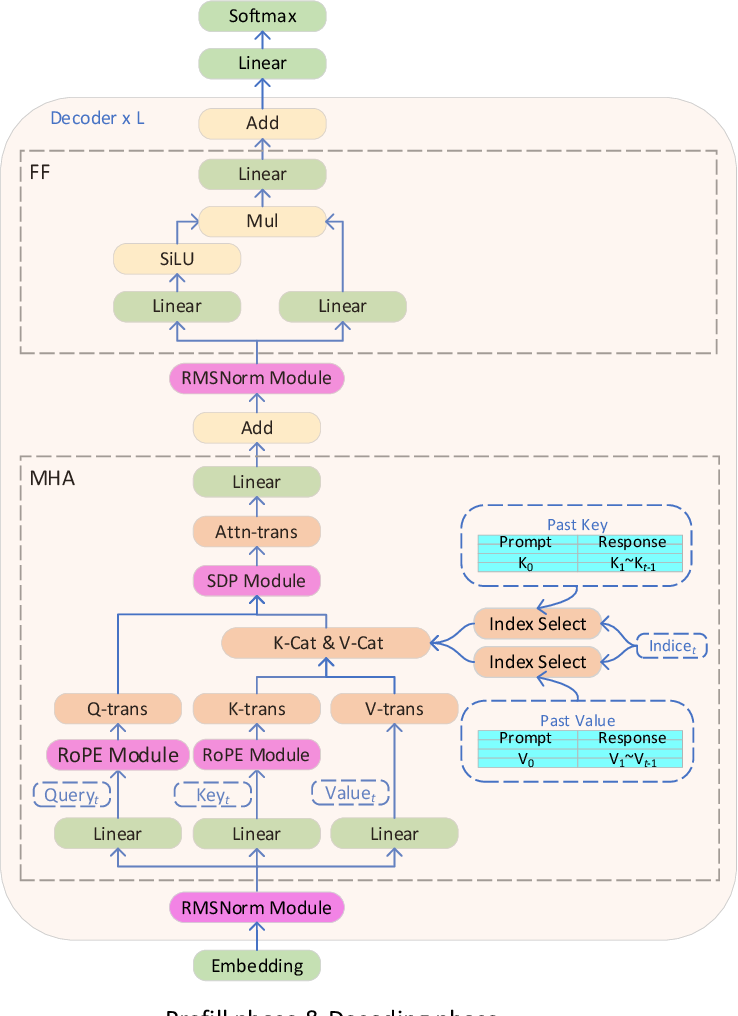
Figure 1 from Efficient LLM inference solution on Intel GPU | Semantic ...
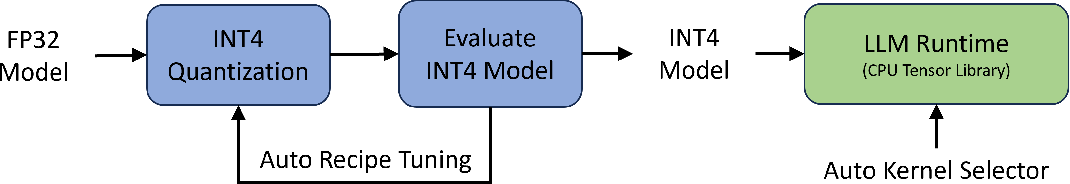
Figure 1 from Efficient LLM Inference on CPUs | Semantic Scholar

Figure 1 from A Survey of LLM Inference Systems | Semantic Scholar
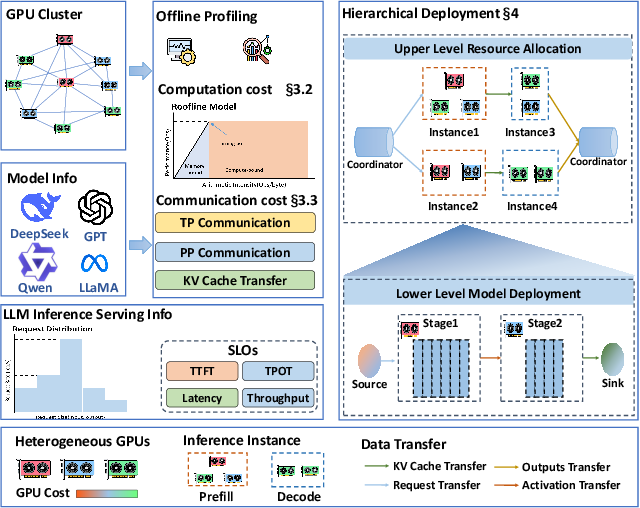
Figure 1 from SwiftServe: Efficient Disaggregated LLM Inference Serving ...
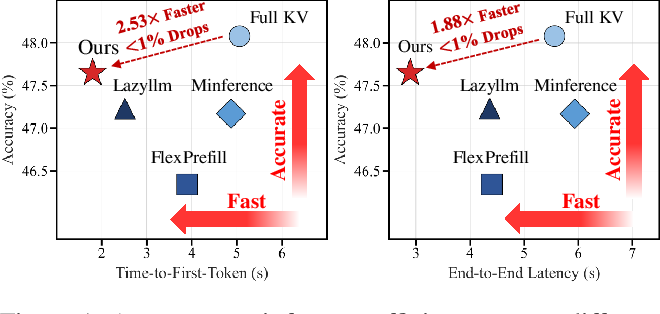
Figure 1 from SlimInfer: Accelerating Long-Context LLM Inference via ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...
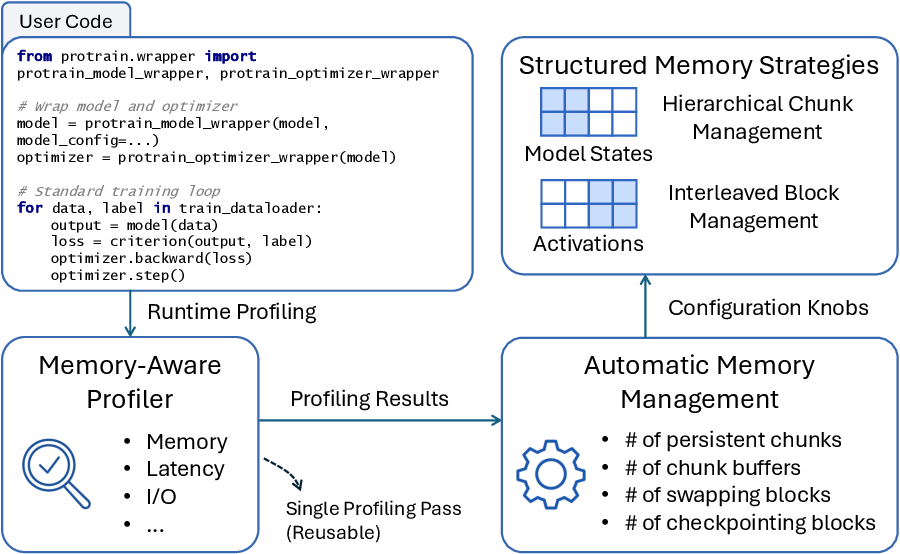
Figure 1 from ProTrain: Efficient LLM Training via Memory-Aware ...
Advertisement Space (300x250)
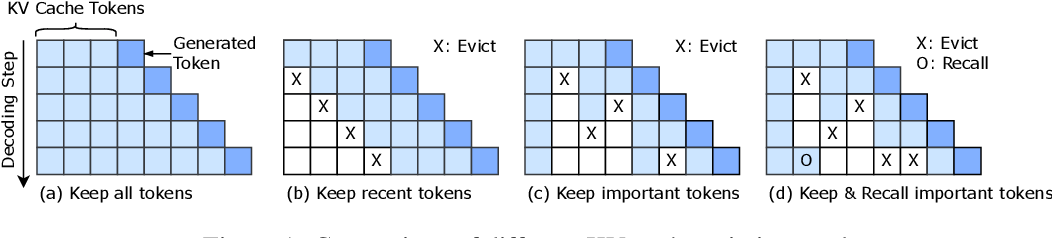
Figure 1 from ArkVale: Efficient Generative LLM Inference with ...

Figure 1 from Megalodon: Efficient LLM Pretraining and Inference with ...

Figure 1 from Accelerating LLM Inference via Dynamic KV Cache Placement ...
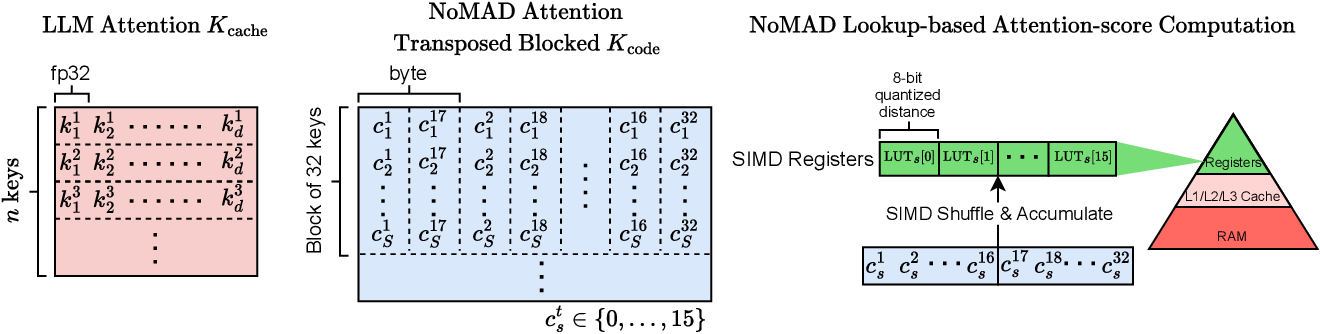
Figure 1 from NoMAD-Attention: Efficient LLM Inference on CPUs Through ...
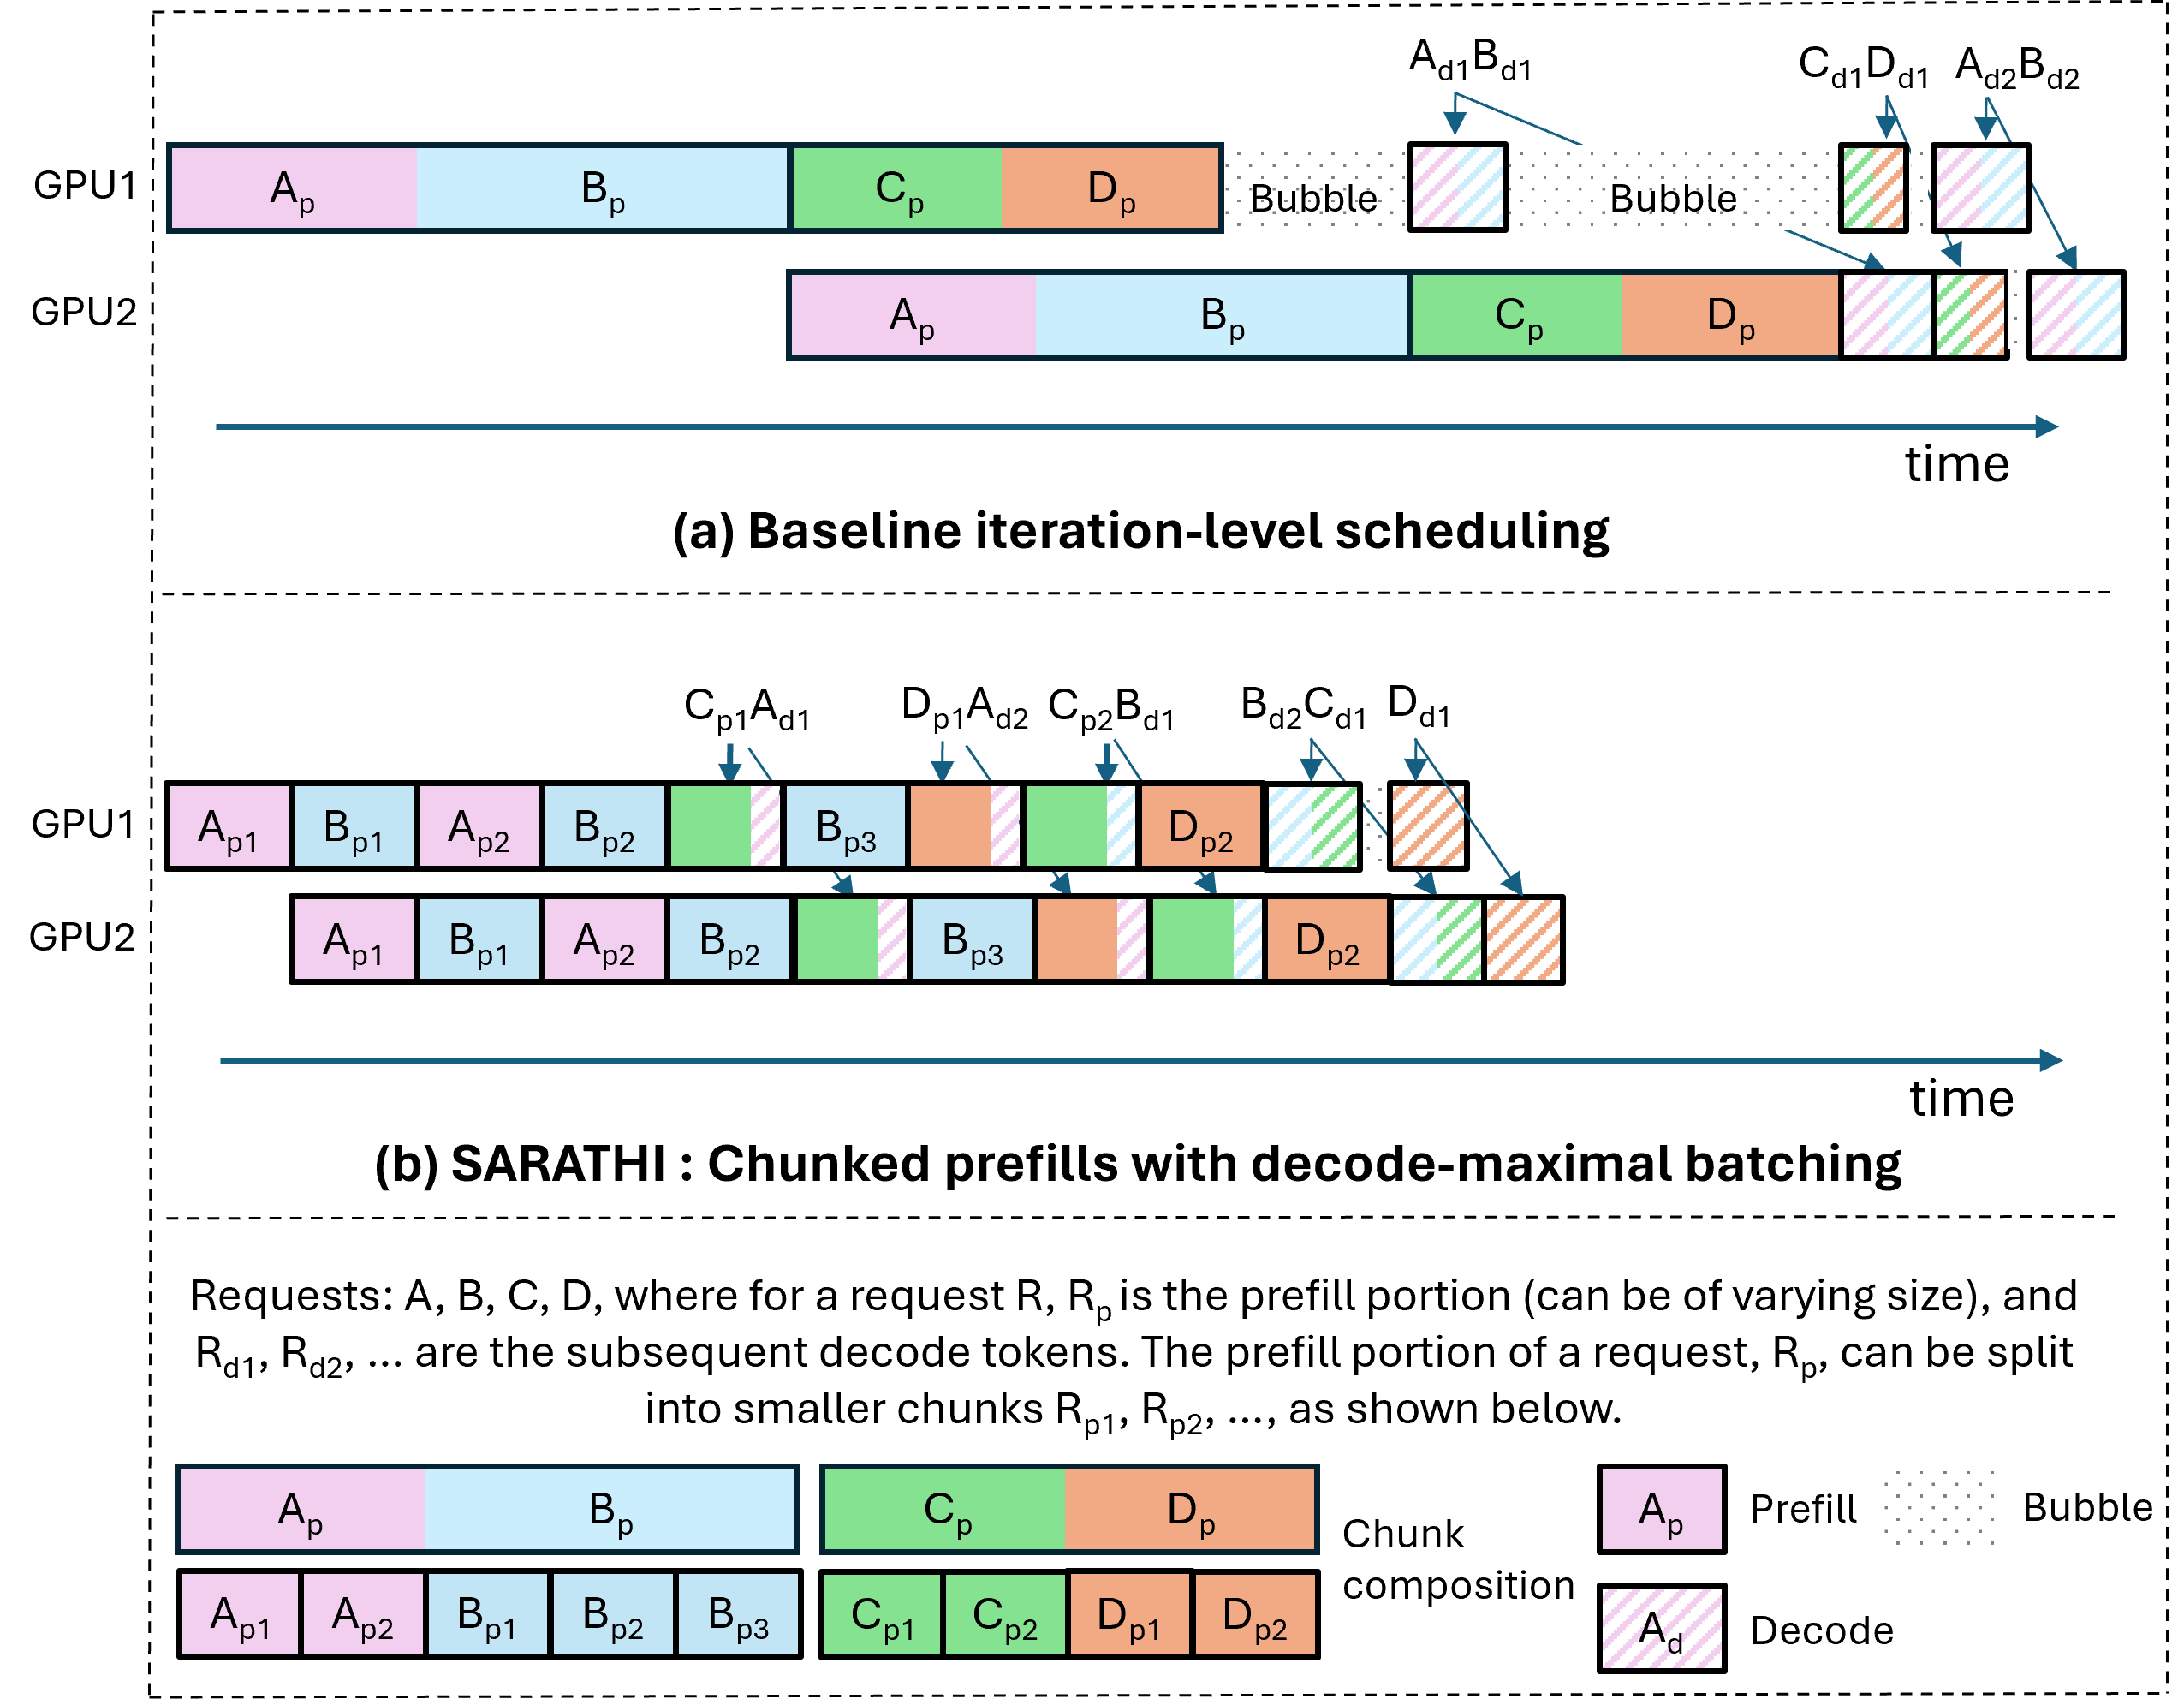
Sarathi-Serve: Chunked Prefills for Efficient LLM Inference | OSDI'24

Figure 1 from Progressive Mixed-Precision Decoding for Efficient LLM ...

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...

Figure 1 from SparQ Attention: Bandwidth-Efficient LLM Inference ...
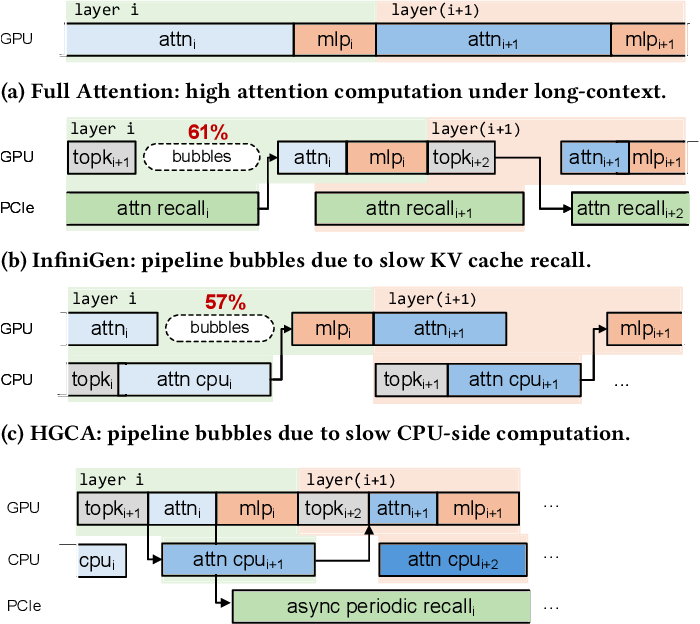
Figure 1 from ScoutAttention: Efficient KV Cache Offloading via Layer ...
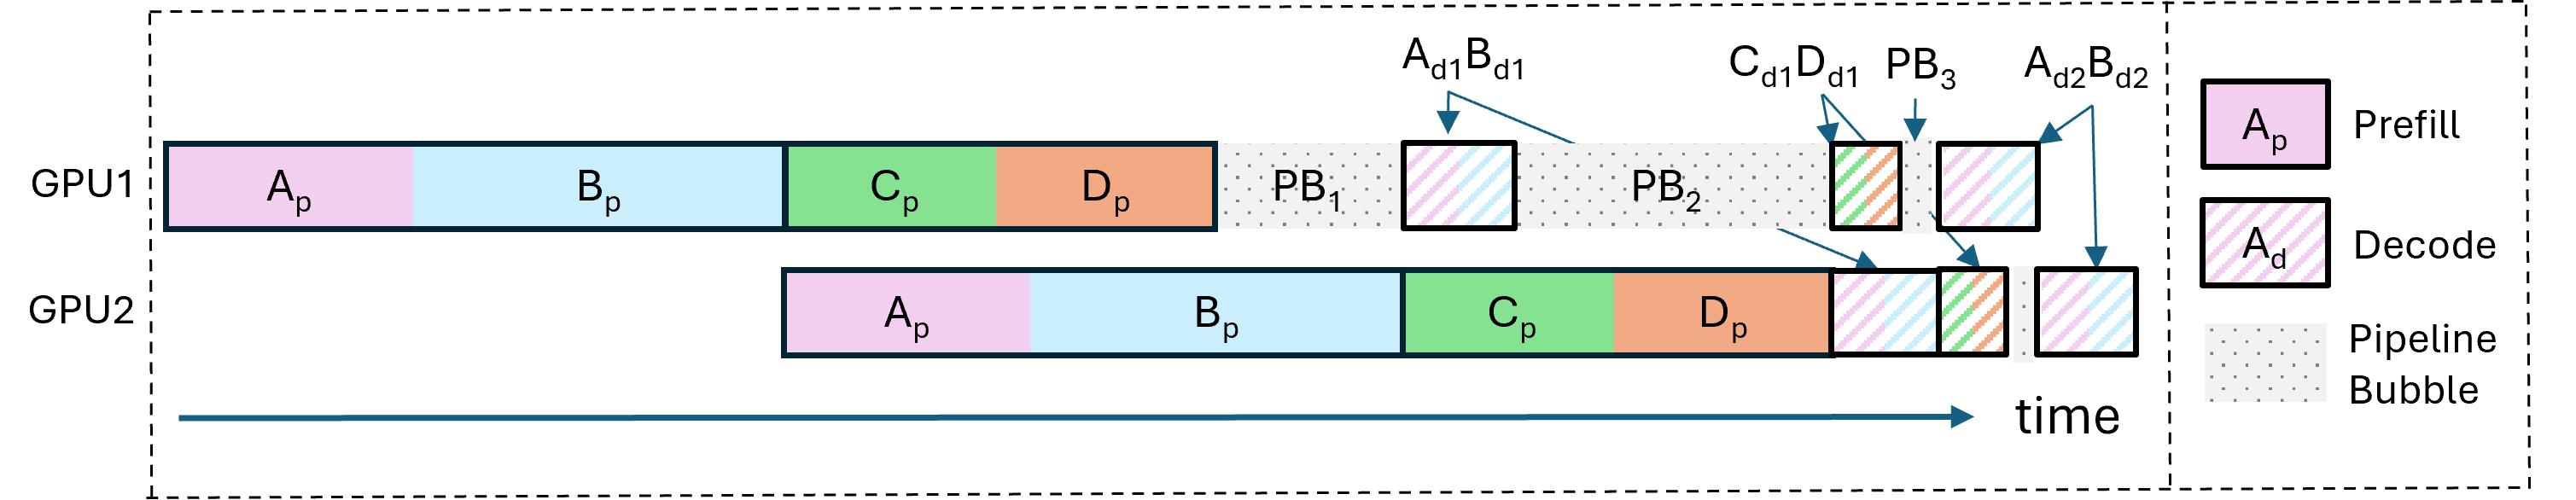
Sarathi-Serve: Chunked Prefills for Efficient LLM Inference | OSDI'24
Advertisement Space (336x280)
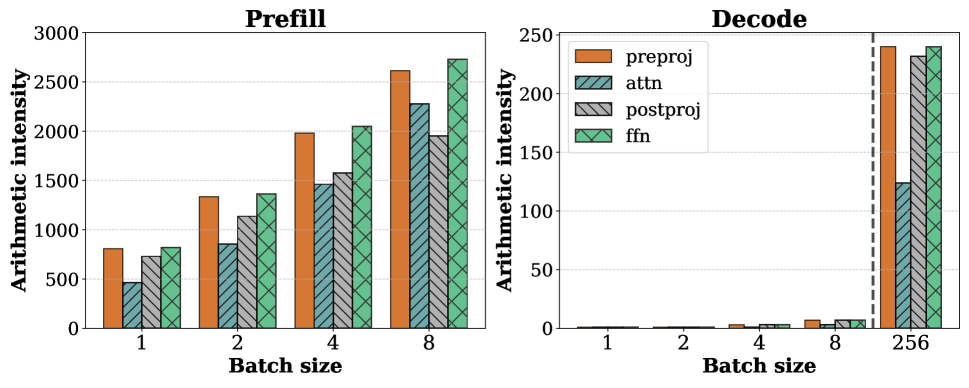
Sarathi-Serve: Chunked Prefills for Efficient LLM Inference | OSDI'24

Figure 1 from Medusa: Simple LLM Inference Acceleration Framework with ...

Figure 1 from User-LLM: Efficient LLM Contextualization with User ...
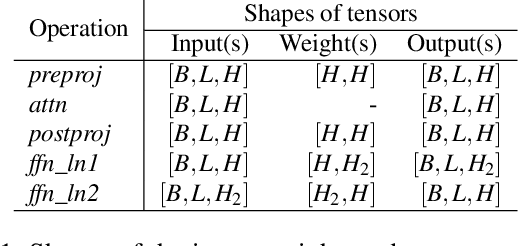
Table 1 from SARATHI: Efficient LLM Inference by Piggybacking Decodes ...

Figure 5 from A Dataflow Compiler for Efficient LLM Inference using ...

Figure 6 from A Dataflow Compiler for Efficient LLM Inference using ...

Figure 1 from Efficient LLM-Jailbreaking via Multimodal-LLM Jailbreak ...

Figure 1 from A Probabilistic Inference Scaling Theory for LLM Self ...
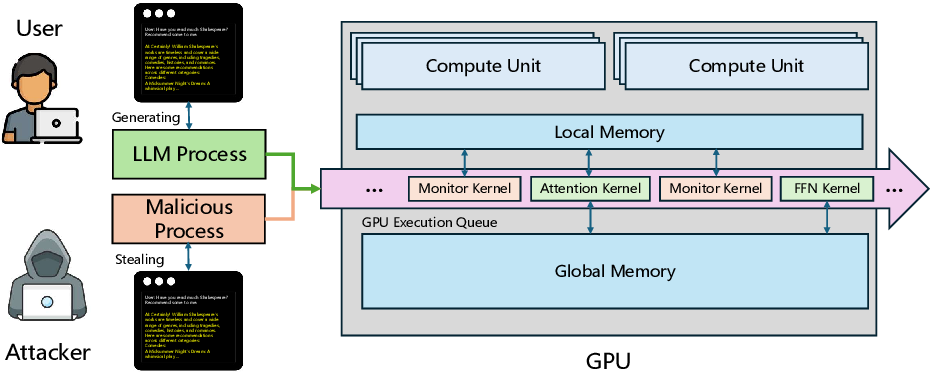
Figure 1 from A First Look At Efficient And Secure On-Device LLM ...
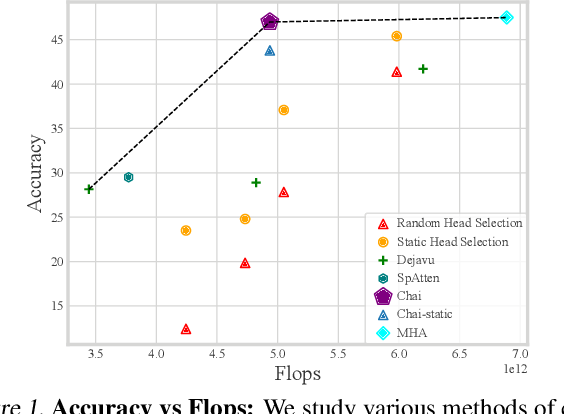
Figure 1 from CHAI: Clustered Head Attention for Efficient LLM ...
Advertisement Space (336x280)

Figure 2 from A Dataflow Compiler for Efficient LLM Inference using ...
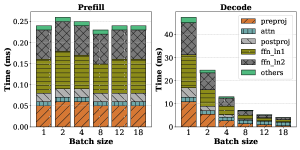
Sarathi-Serve: Chunked Prefills for Efficient LLM Inference | OSDI'24

Figure 1 from Boosting LLM via Learning from Data Iteratively and ...

Figure 1 from DSSD: Efficient Edge-Device LLM Deployment and ...
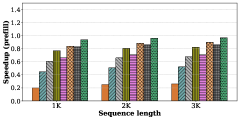
Sarathi-Serve: Chunked Prefills for Efficient LLM Inference | OSDI'24
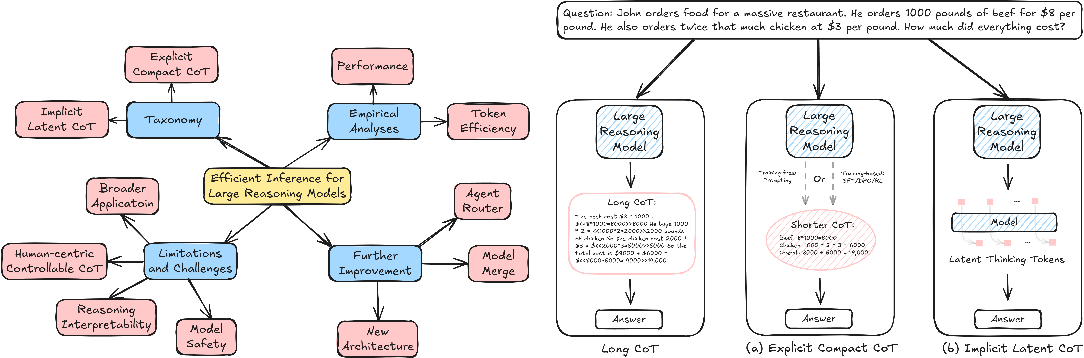
Figure 1 from Efficient Inference for Large Reasoning Models: A Survey ...