
Figure 1 From Efficient Llm Inference Solution On Intel Gpu Semantic
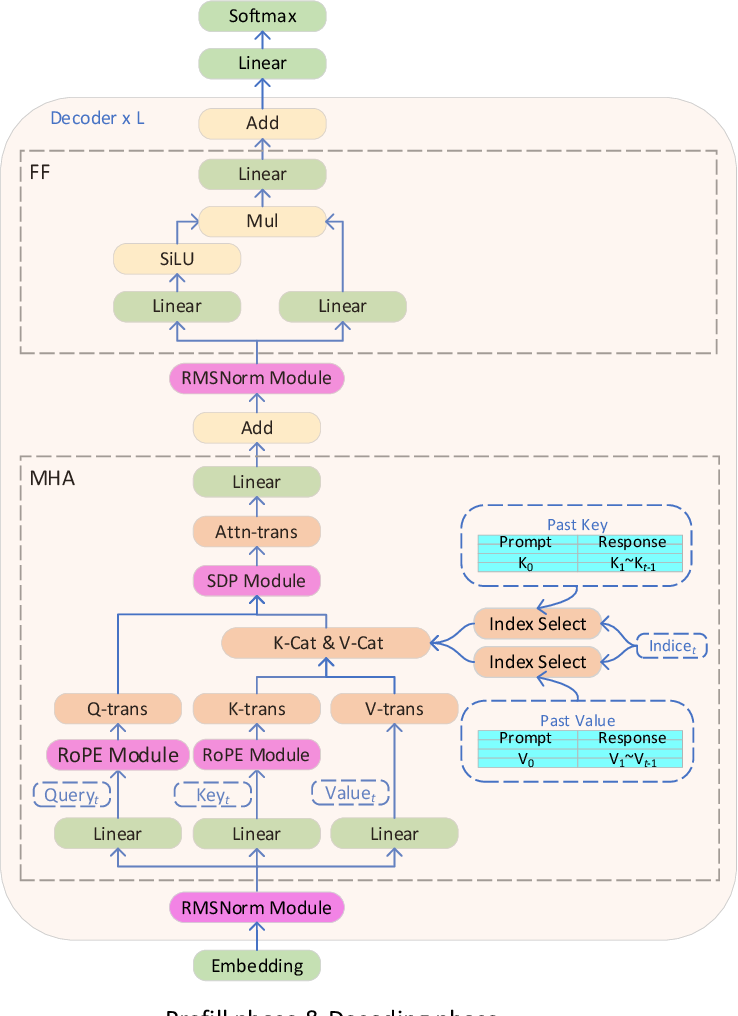
Figure 1 from Efficient LLM inference solution on Intel GPU | Semantic ...
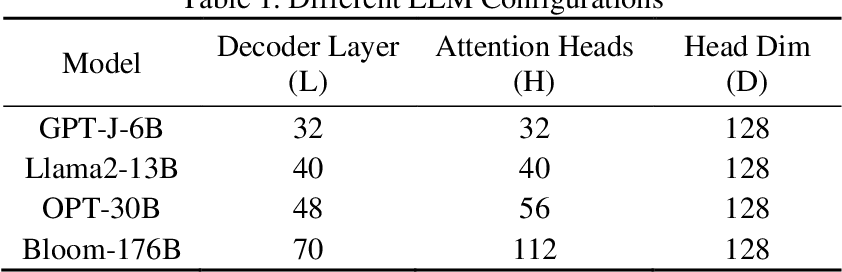
Table 1 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 3 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 2 from Efficient LLM inference solution on Intel GPU | Semantic ...

Figure 6 from Efficient LLM inference solution on Intel GPU | Semantic ...
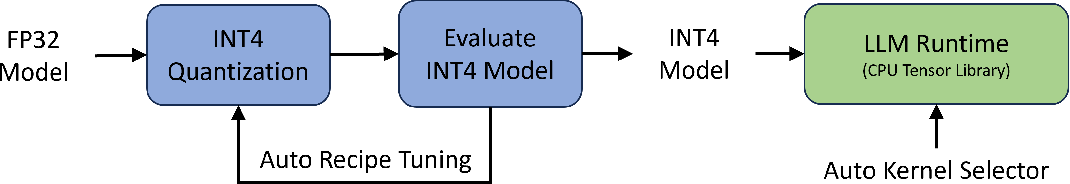
Figure 1 from Efficient LLM Inference on CPUs | Semantic Scholar
Paper page - Efficient LLM inference solution on Intel GPU
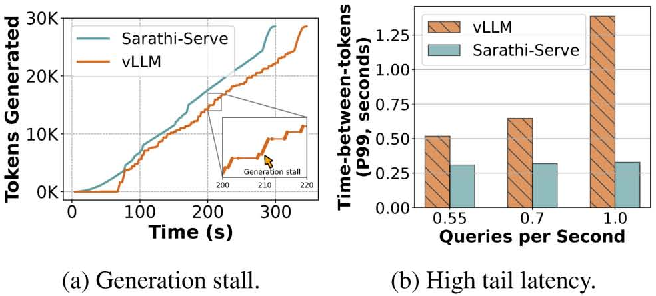
Figure 1 from Efficient LLM Inference via Chunked Prefills | Semantic ...

Intel presents Efficient LLM inference solution on Intel GPU paper page ...

Figure 1 from A Systematic Characterization of LLM Inference on GPUs ...
Advertisement Space (300x250)
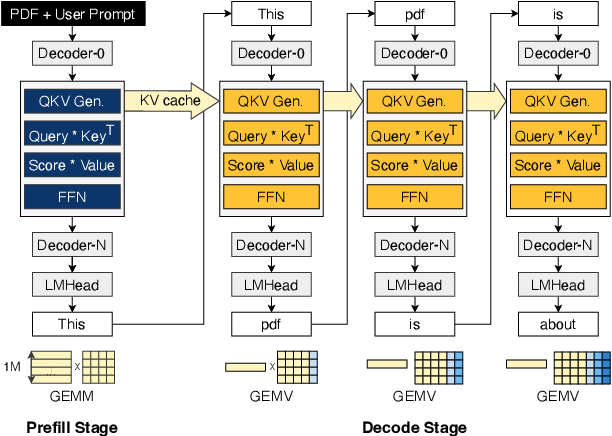
Figure 1 from Hybe: GPU-NPU Hybrid System for Efficient LLM Inference ...
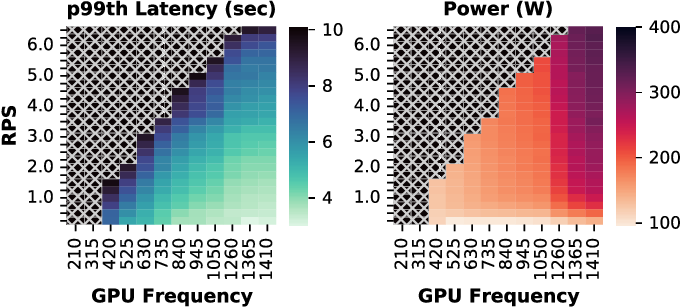
Figure 1 from SLO-Aware GPU DVFS for Energy-Efficient LLM Inference ...

Figure 1 from A Survey of LLM Inference Systems | Semantic Scholar
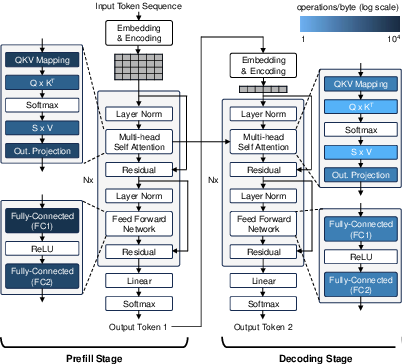
Figure 1 from LIA: A Single-GPU LLM Inference Acceleration with ...

Figure 1 from An Efficient Inference Frame for SMLM (Single-Molecule ...
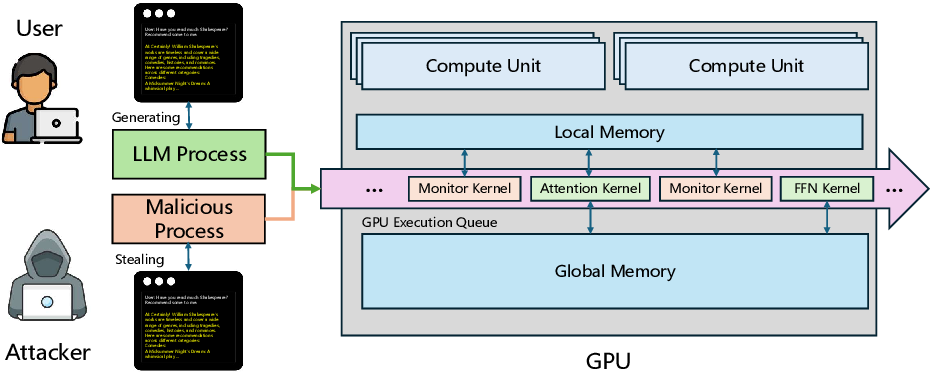
Figure 1 from A First Look At Efficient And Secure On-Device LLM ...

Figure 1 from SparQ Attention: Bandwidth-Efficient LLM Inference ...

Figure 1 from Efficient KV Cache Spillover Management on Memory ...

Demo | LLM Inference on Intel® Data Center GPU Flex Series | Intel ...

Figure 1 from Medusa: Simple LLM Inference Acceleration Framework with ...
Advertisement Space (336x280)

Figure 1 from User-LLM: Efficient LLM Contextualization with User ...

[논문 리뷰] Cronus: Efficient LLM inference on Heterogeneous GPU Clusters ...

Figure 1 from Progressive Mixed-Precision Decoding for Efficient LLM ...
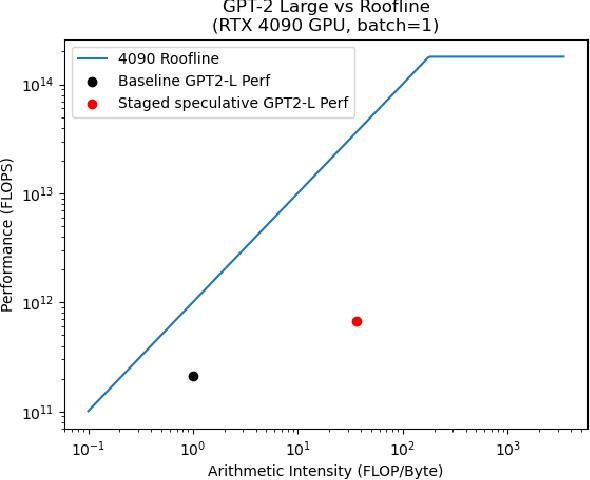
Figure 1 from Accelerating LLM Inference with Staged Speculative ...

Figure 1 from FastDecode: High-Throughput GPU-Efficient LLM Serving ...
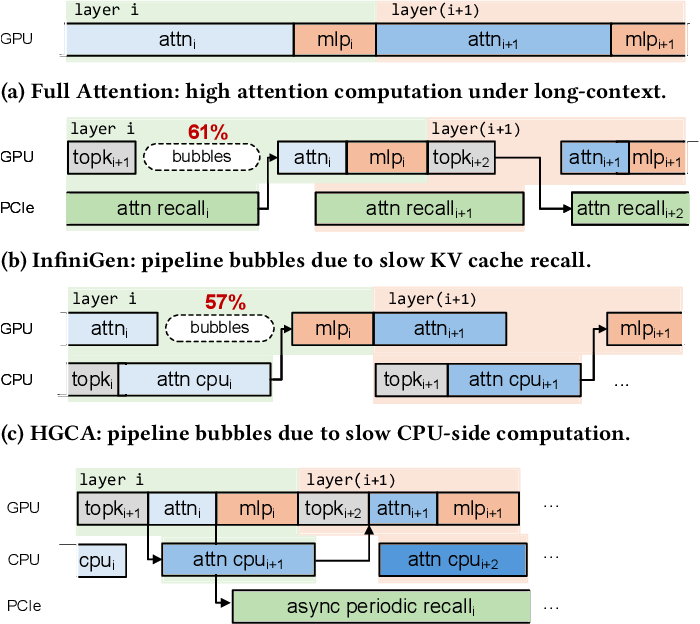
Figure 1 from ScoutAttention: Efficient KV Cache Offloading via Layer ...
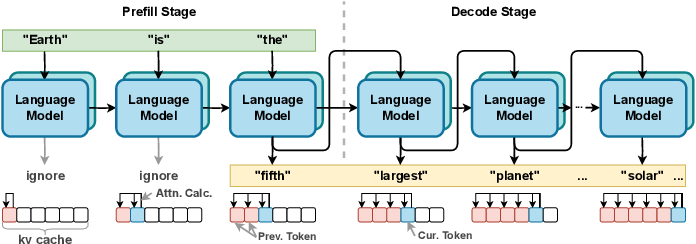
Figure 1 from LoopLynx: A Scalable Dataflow Architecture for Efficient ...

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...
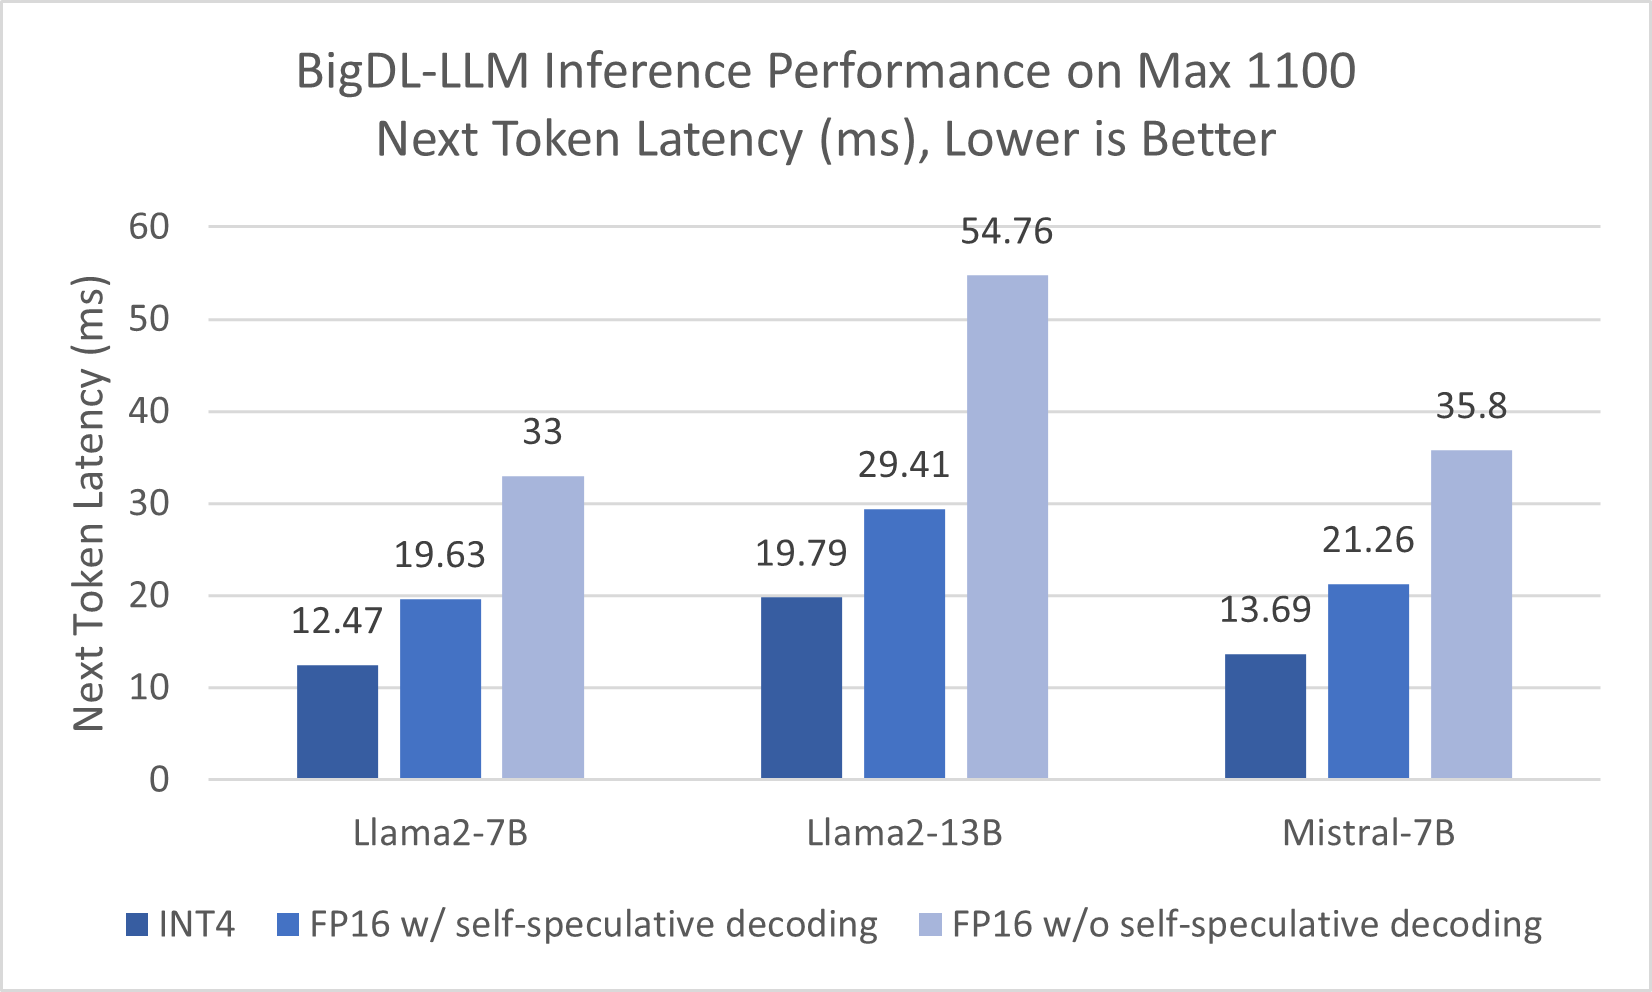
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM
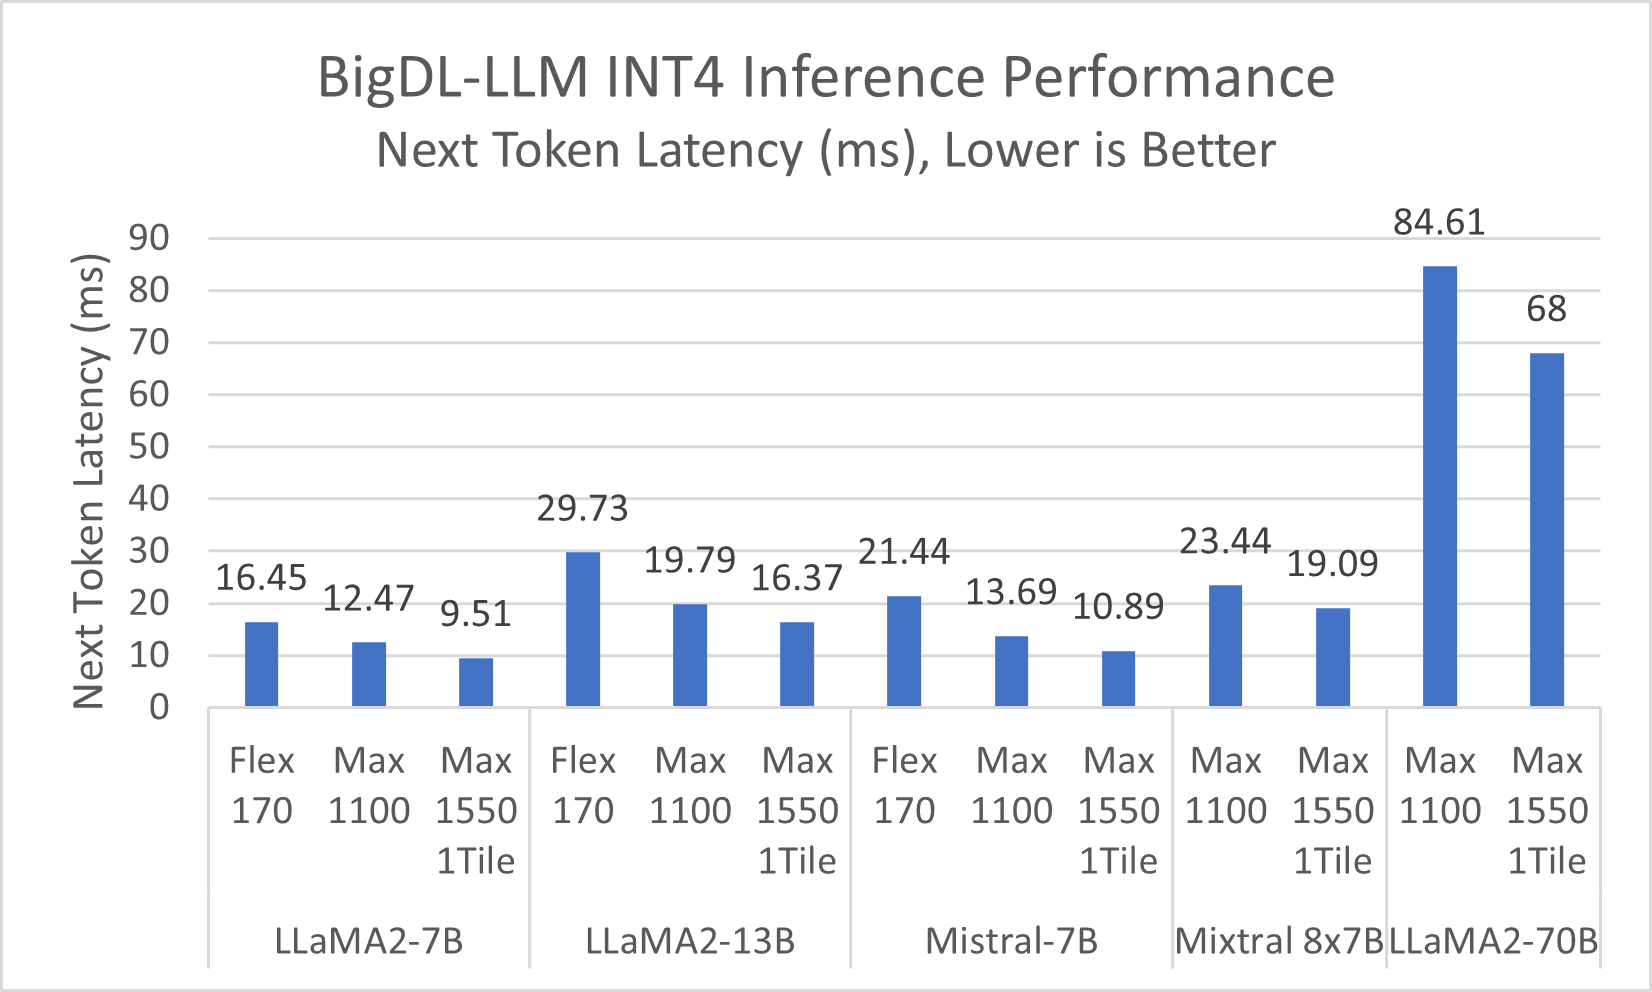
Accelerating LLM Inference on Intel Data Center GPUs using BigDL LLM
Advertisement Space (336x280)
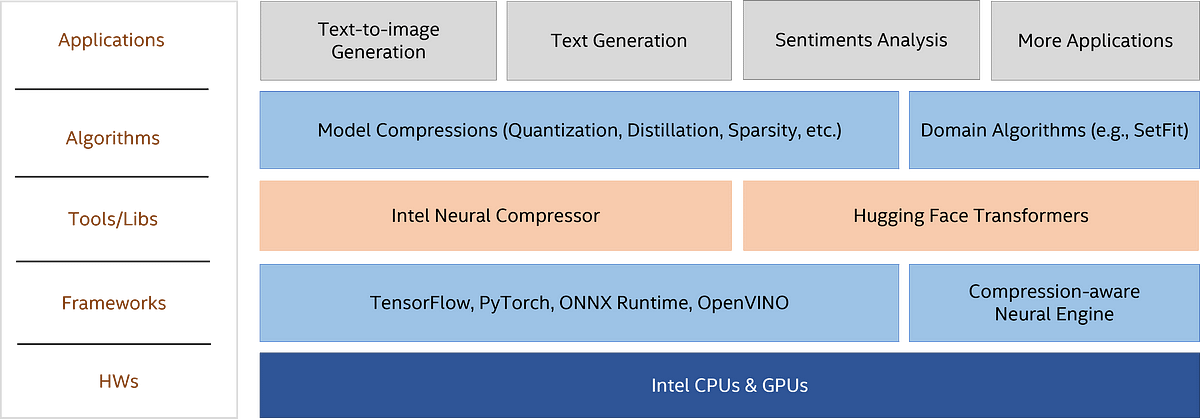
Highly-efficient LLM Inference on Intel Platforms | by Intel(R) Neural ...
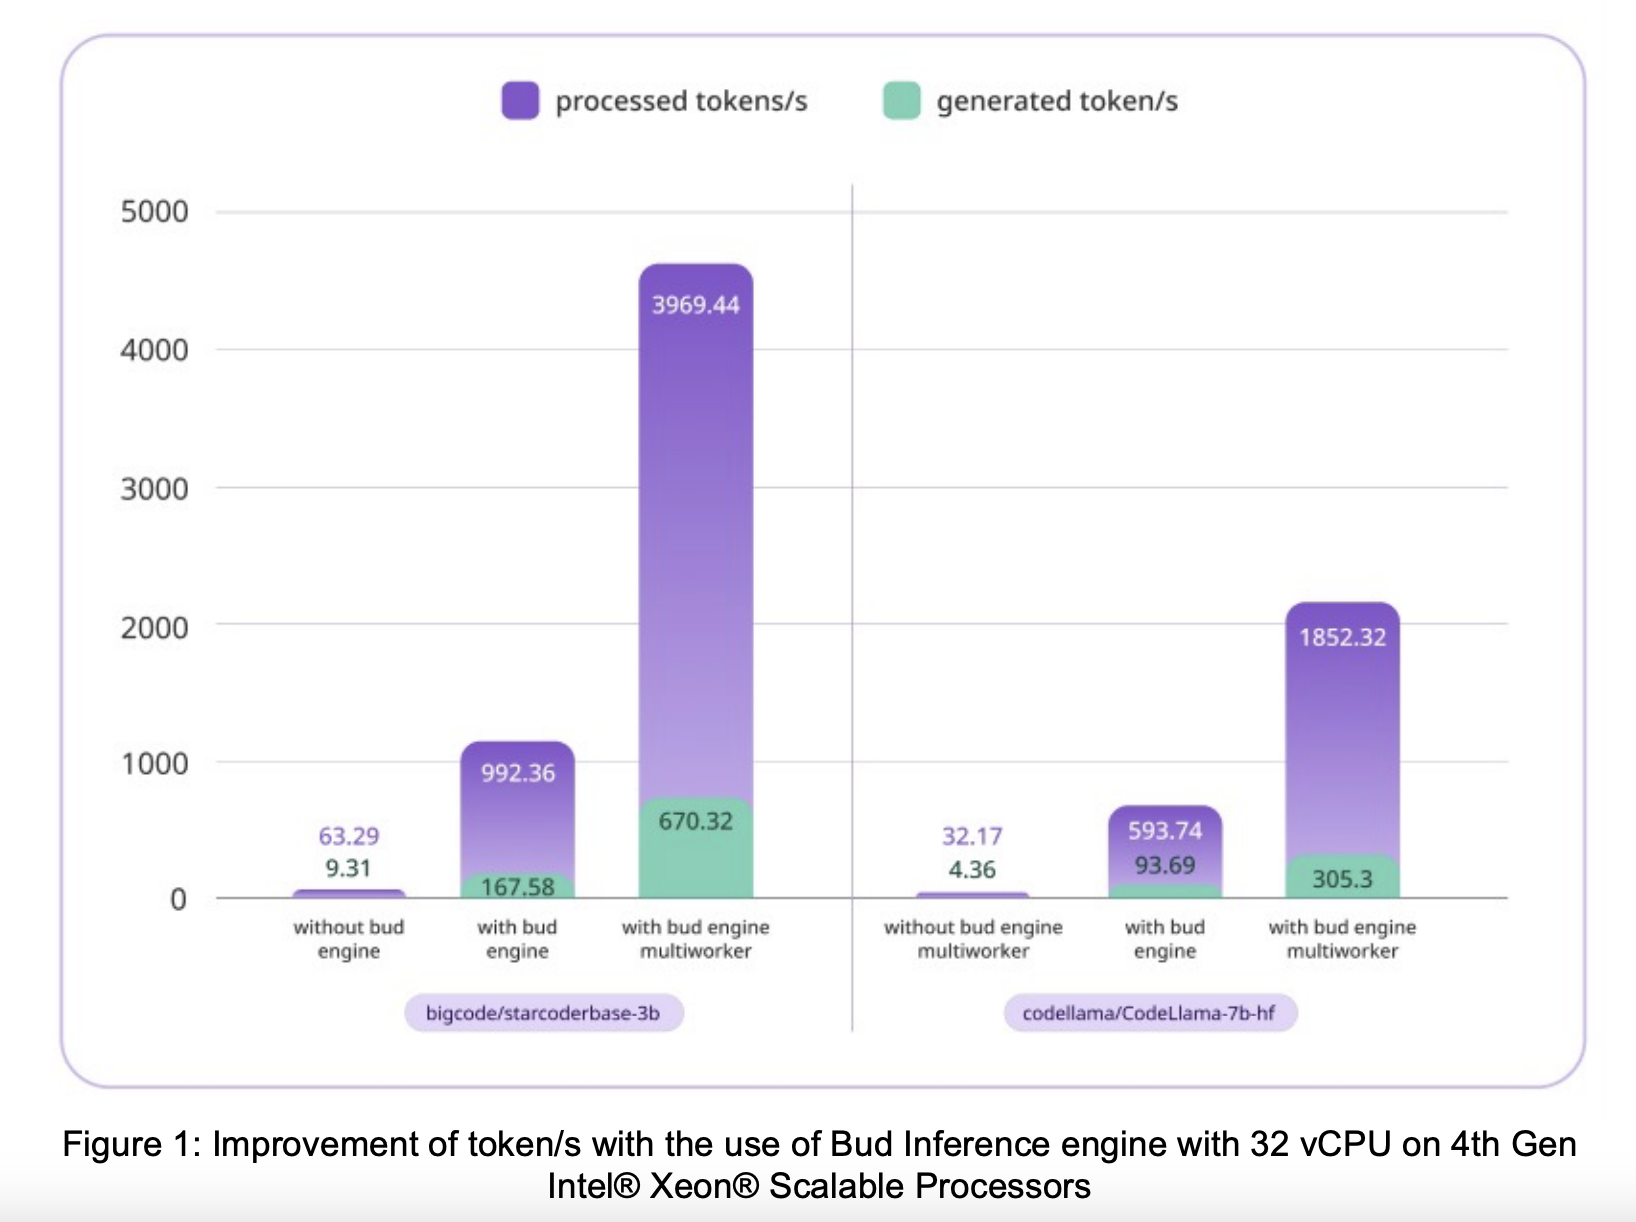
Enhancing LLM inference performance on Intel CPUs - BudEcosystem

SLO-aware GPU Frequency Scaling for Energy Efficient LLM Inference ...

Outshift | LLM inference optimization: An efficient GPU traffic routing ...
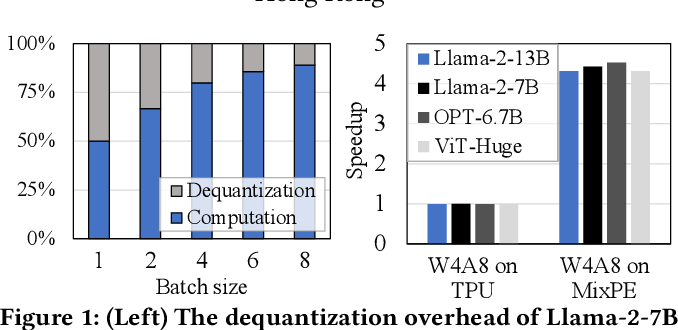
Figure 1 from MixPE: Quantization and Hardware Co-design for Efficient ...
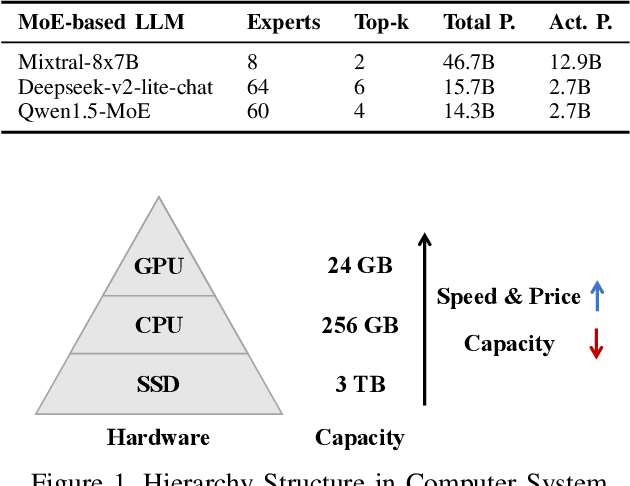
Figure 1 from DS-MoE: Dynamic Expert Scheduling for Efficient MoE-based ...