
Figure 1 From Finetuning Llms For Human Behavior Prediction In Social

Figure 1 from Finetuning LLMs for Human Behavior Prediction in Social ...

Paper page - Finetuning LLMs for Human Behavior Prediction in Social ...

Finetuning LLMs for Human Behavior Prediction in Social Science ...

Figure 1 from General-purpose LLMs as Models of Human Driver Behavior ...

Figure 1 from Instruction-tuning Aligns LLMs to the Human Brain ...

Figure 1 from The Challenge of Using LLMs to Simulate Human Behavior: A ...

Figure 1 from The Challenge of Using LLMs to Simulate Human Behavior: A ...

Figure 1 from Personalized Federated Fine-Tuning for LLMs via Data ...
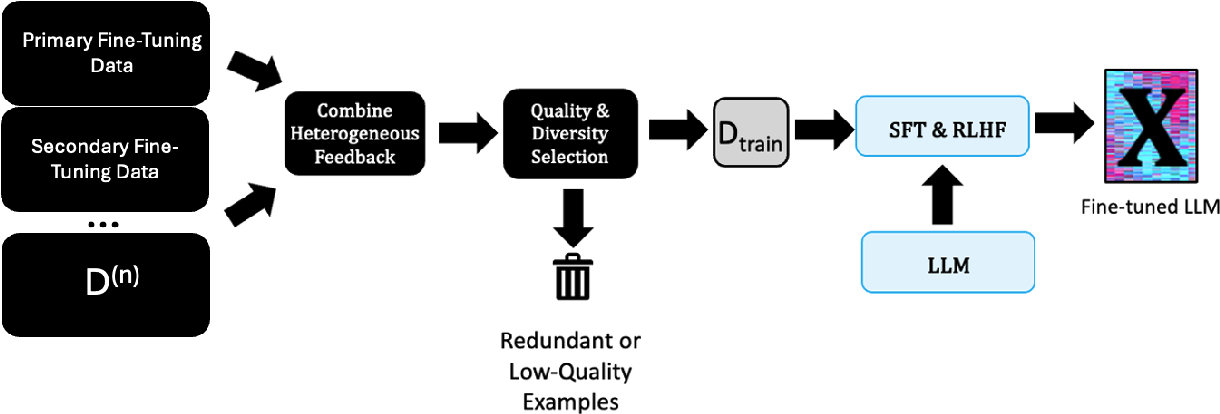
Figure 1 from A Framework for Fine-Tuning LLMs using Heterogeneous ...

Figure 3 from Instruction-tuning Aligns LLMs to the Human Brain ...
Advertisement Space (300x250)

LLM-Based Behavior Prediction for Social Media Users with Continuous ...

Figure 3 from The Challenge of Using LLMs to Simulate Human Behavior: A ...
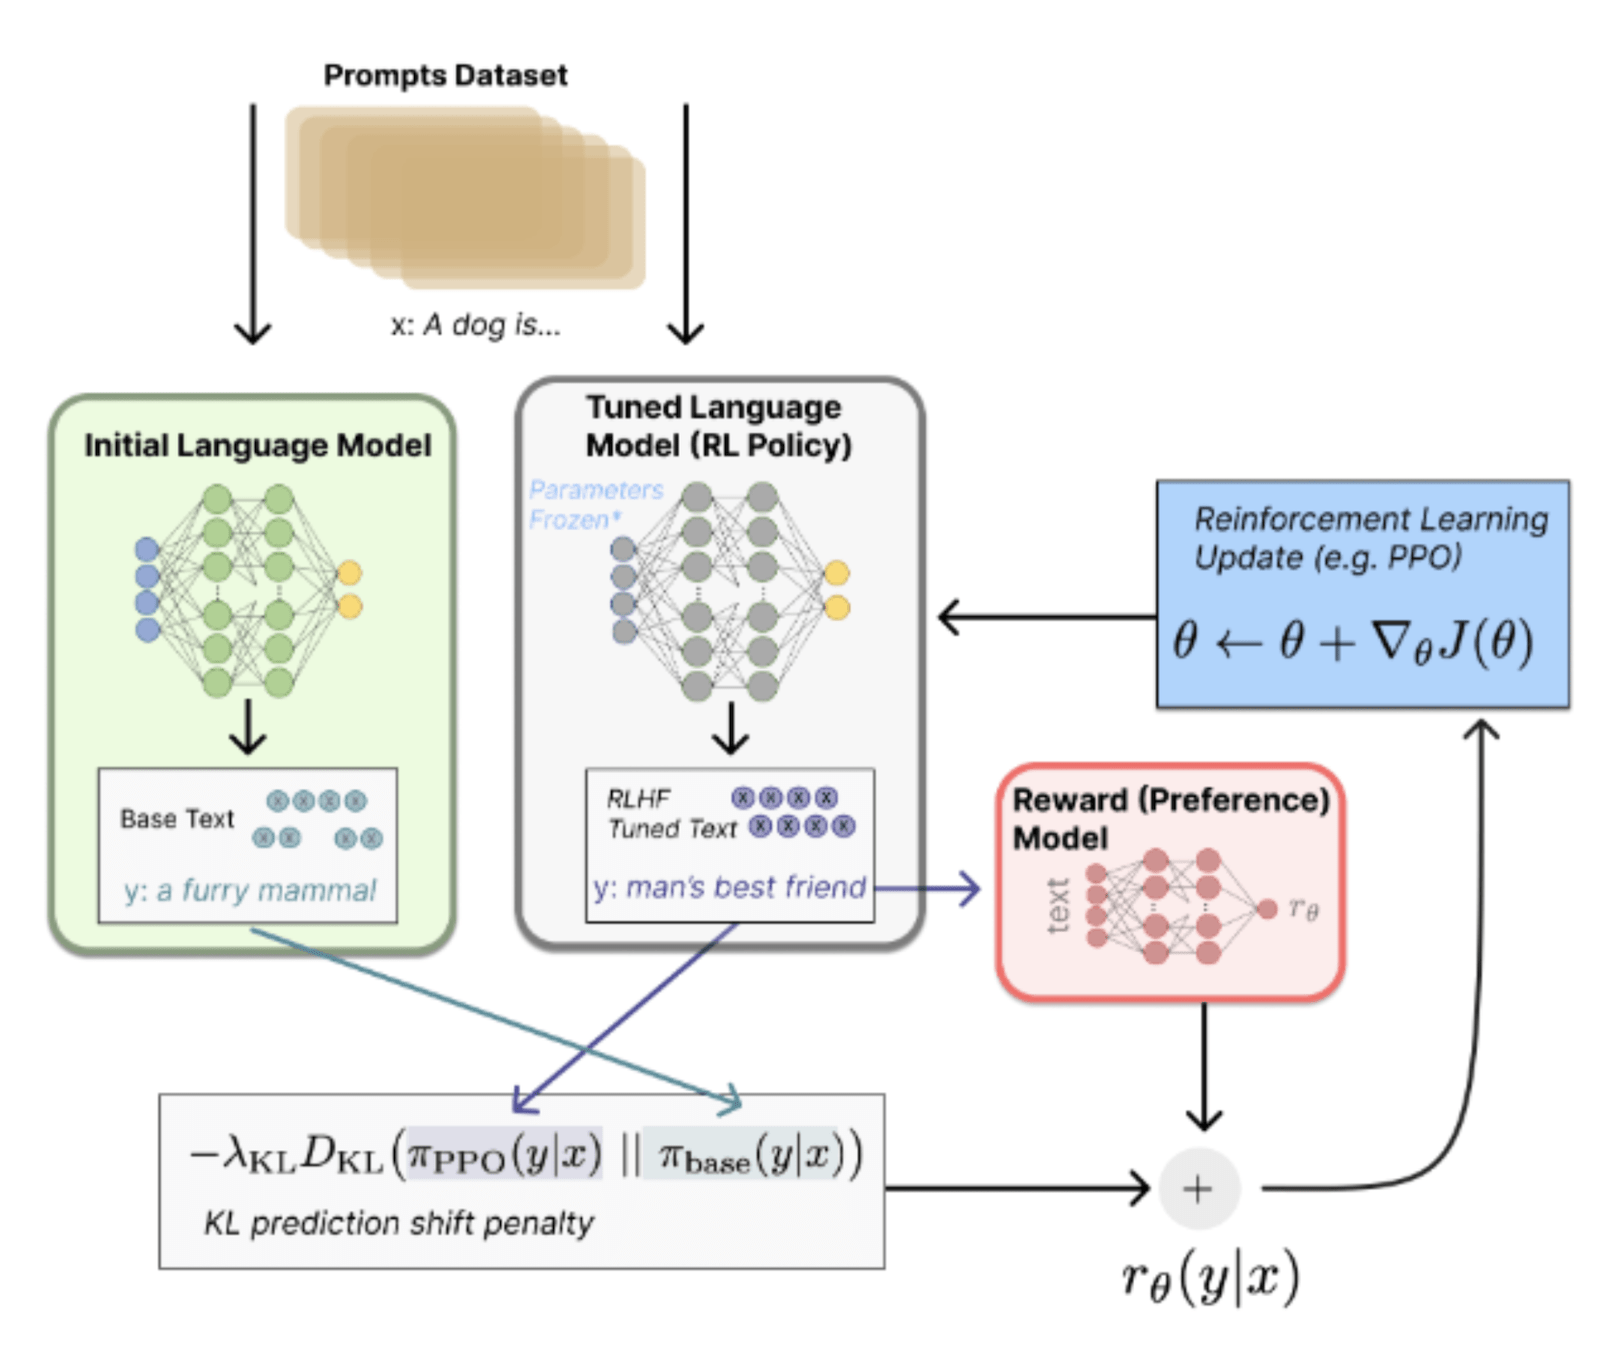
Reinforcement Learning from Human Feedback (RLHF) for LLMs - deepsense.ai

[논문 리뷰] Aligning Video Models with Human Social Judgments via Behavior ...
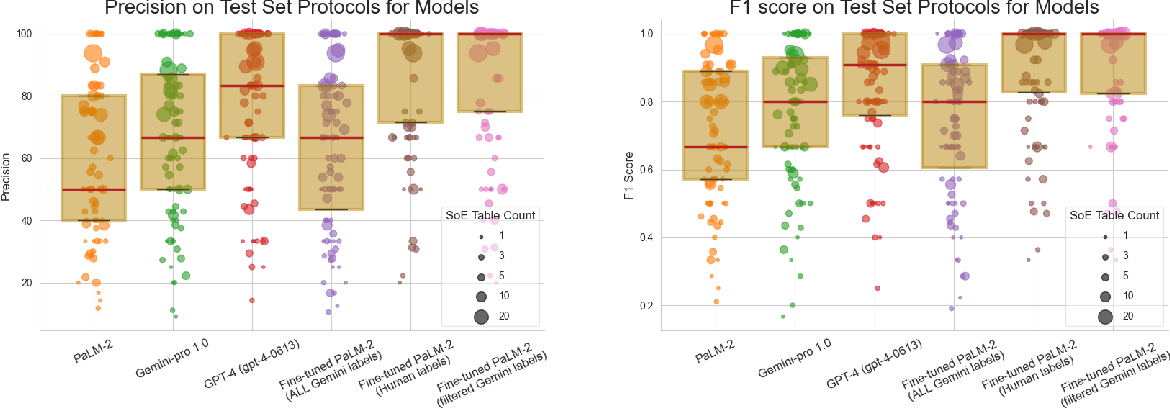
Figure 1 from Selective Fine-tuning on LLM-labeled Data May Reduce ...

Fine-tuning Open LLMs with Reinforcement Learning from Human Feedback ...
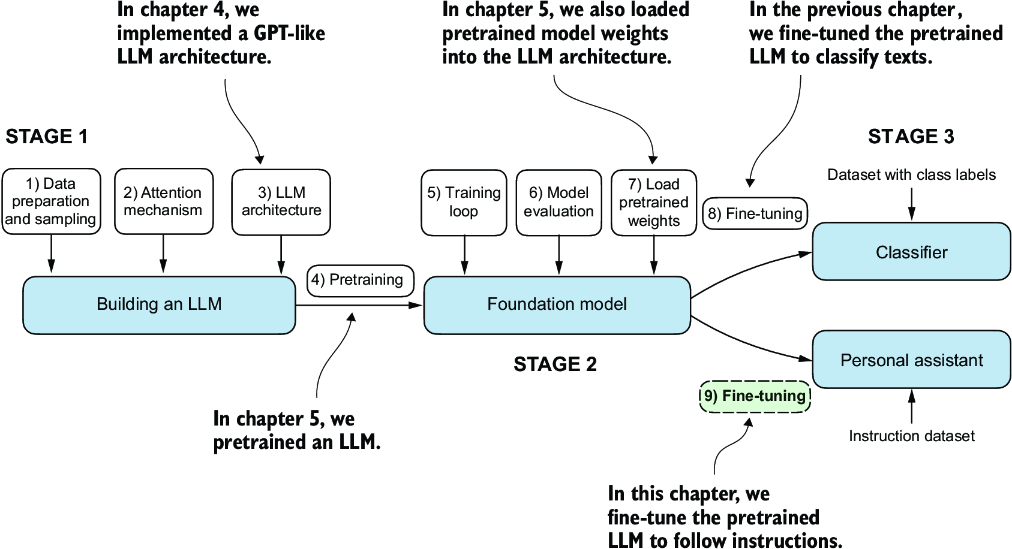
LLMs From Scratch - Chapter 7: Fine-tuning for Instruction Following ...

Use cases of llms in the social sci- ences and psychology
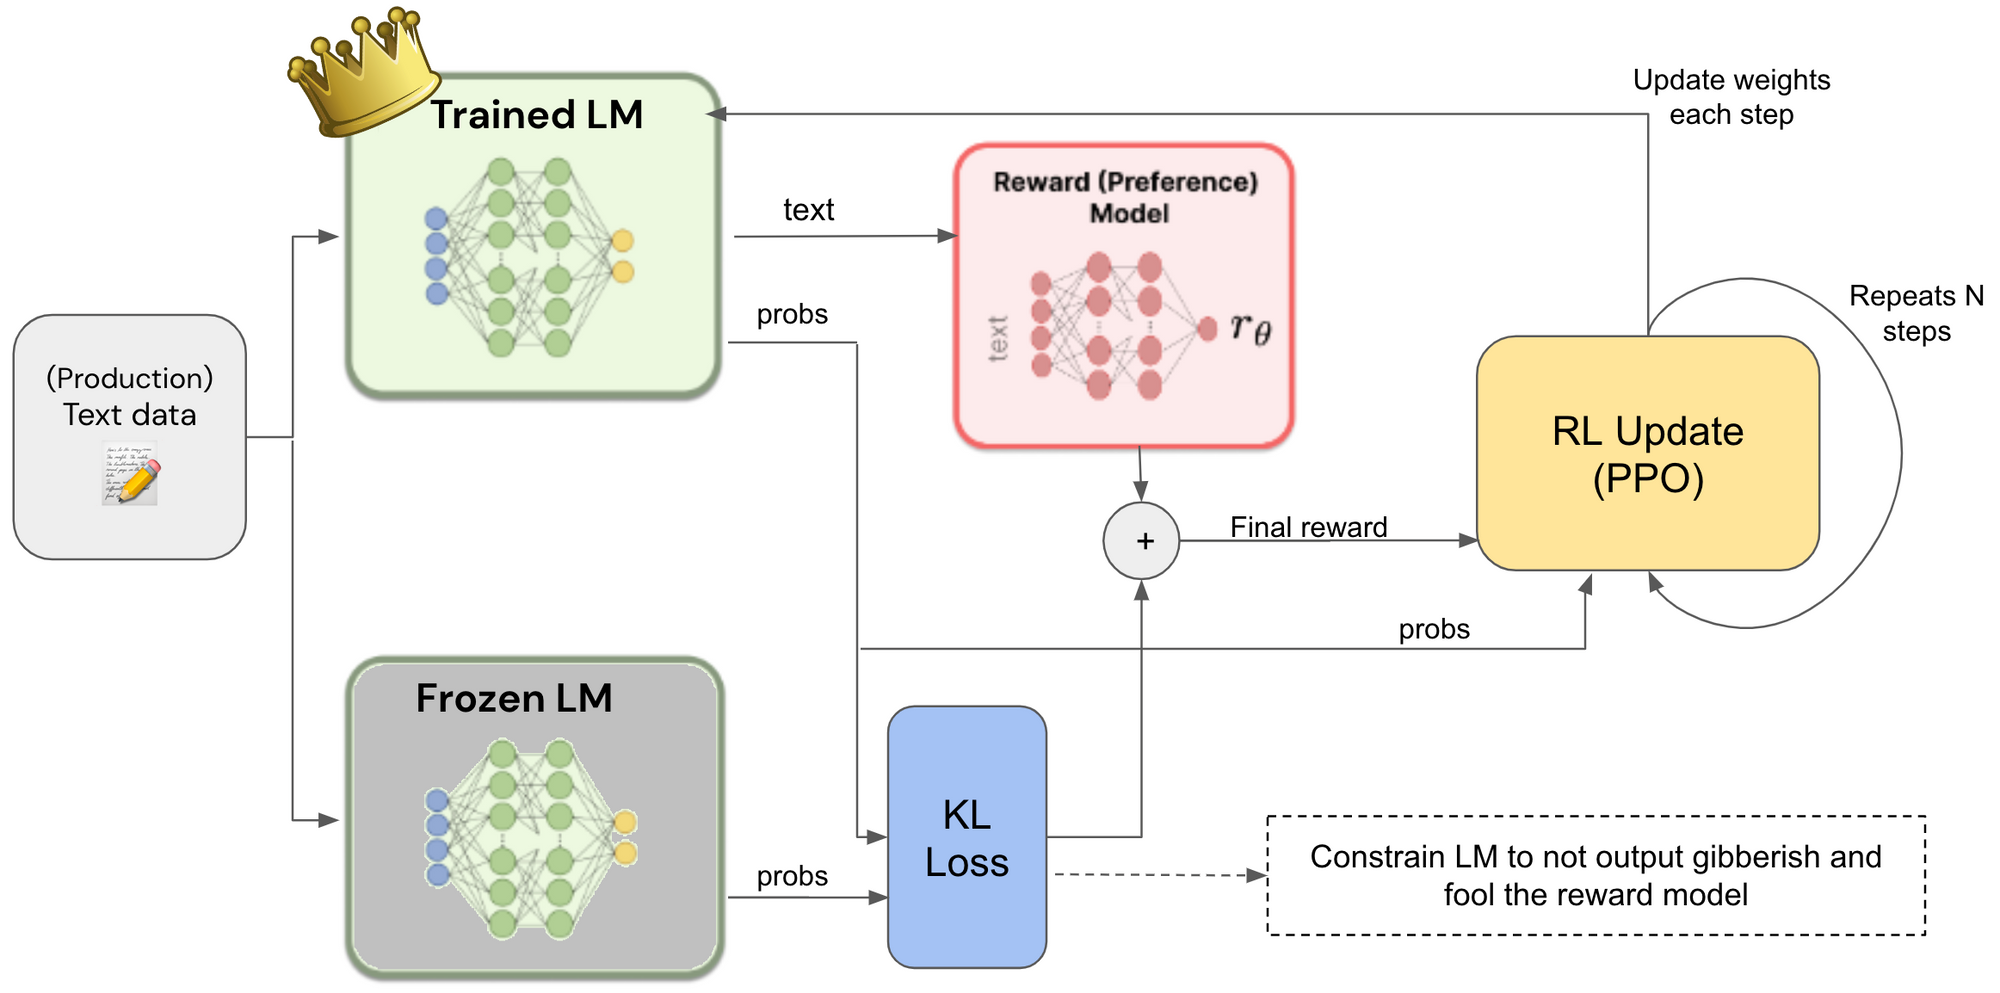
Reinforcement learning with human feedback (RLHF) for LLMs

TruthTensor: Evaluating LLMs Human Imitation through Prediction Market ...
Advertisement Space (336x280)

Fine-tuning Open LLMs with Reinforcement Learning from Human Feedback ...

LLMs for Social Simulation: Progress, Opportunities and Challenges ...

Teaching Values to Machines: Simulating Human-Like Behavior in LLMs

LLMs for Social Simulation: Progress, Opportunities and Challenges ...

Fine-tuning Open LLMs with Reinforcement Learning from Human Feedback ...

(PDF) Fine-tuning LLMs in behavioral psychology for scalable health ...
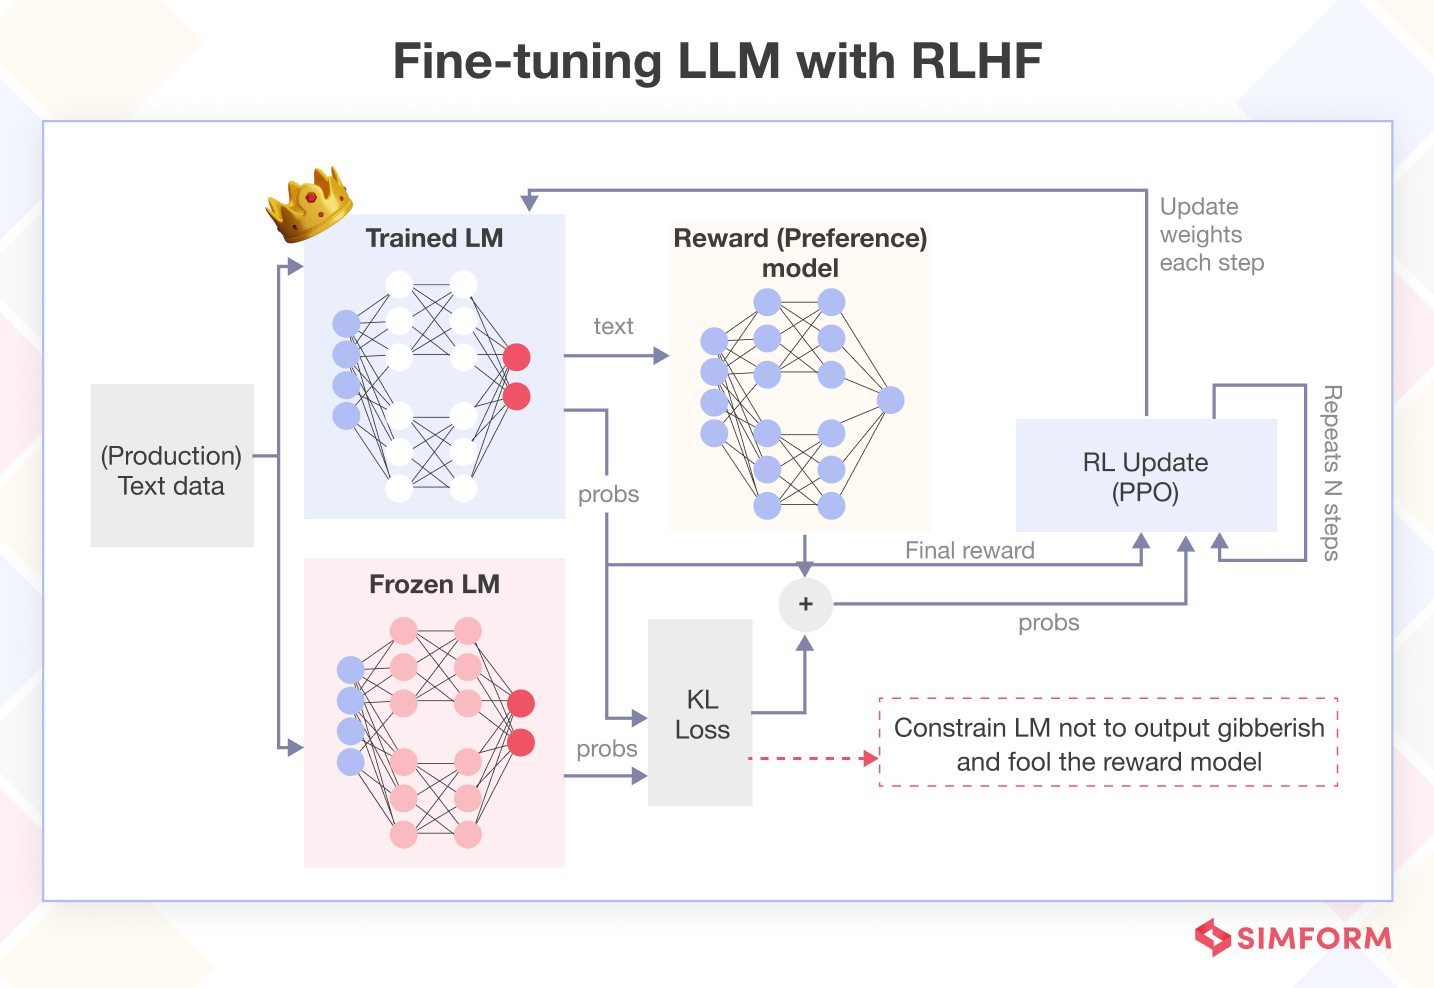
What is Reinforcement Learning from Human Feedback (RLHF)?
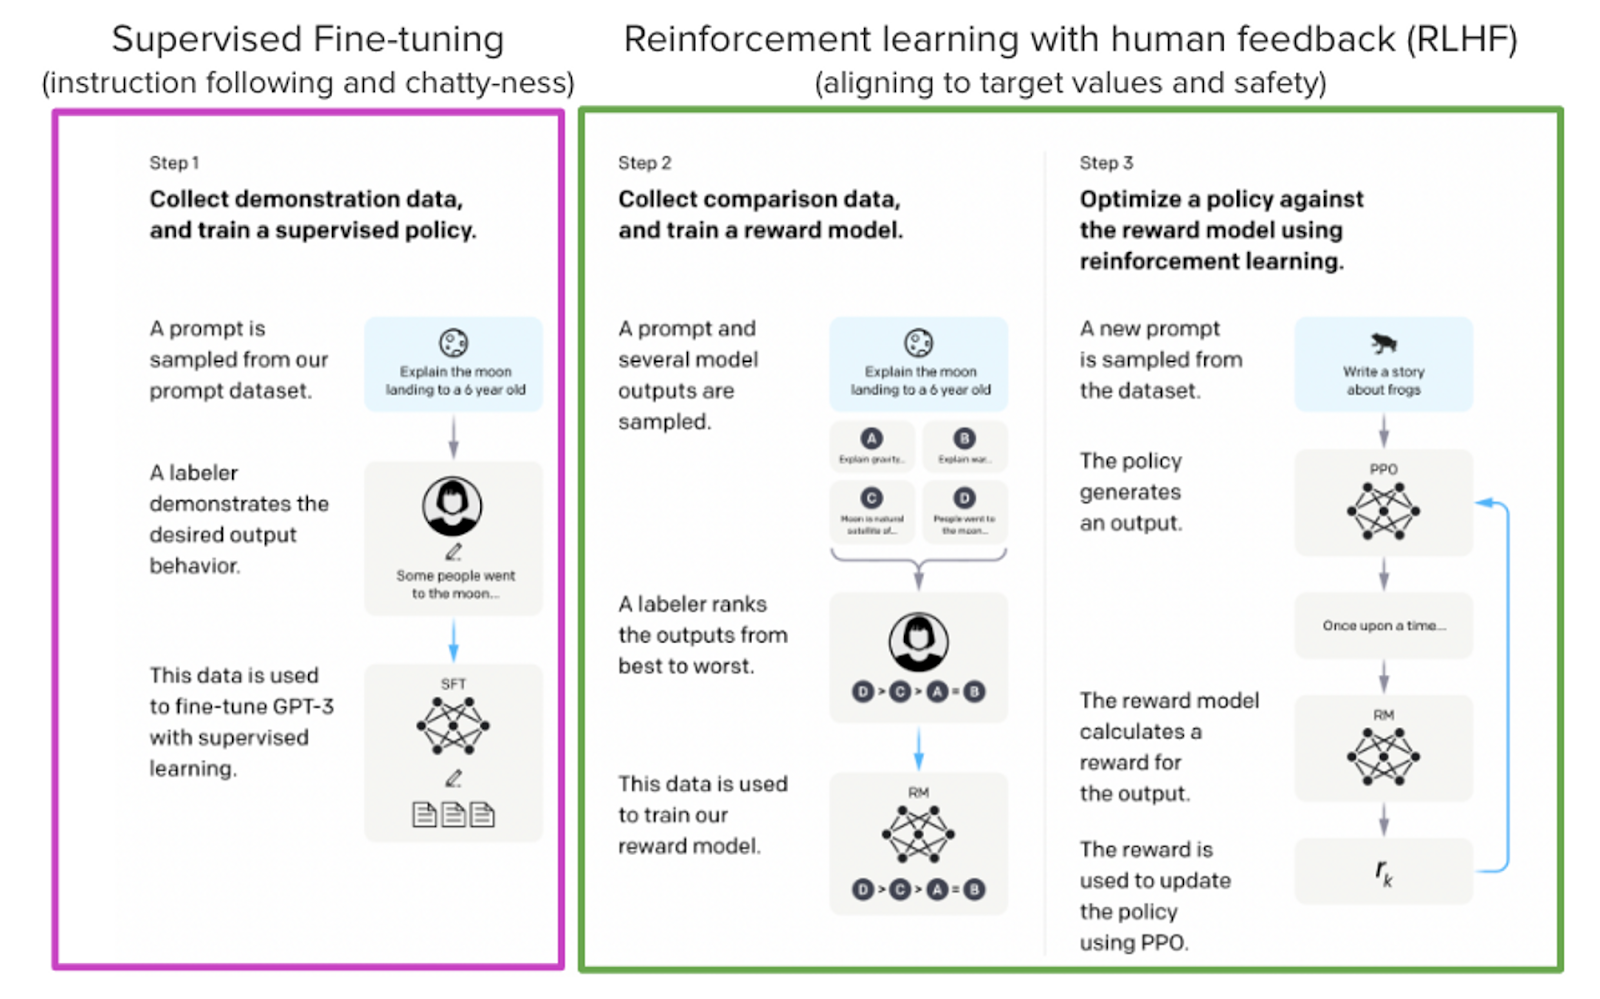
Finetune LLMs on your own consumer hardware using tools from PyTorch ...
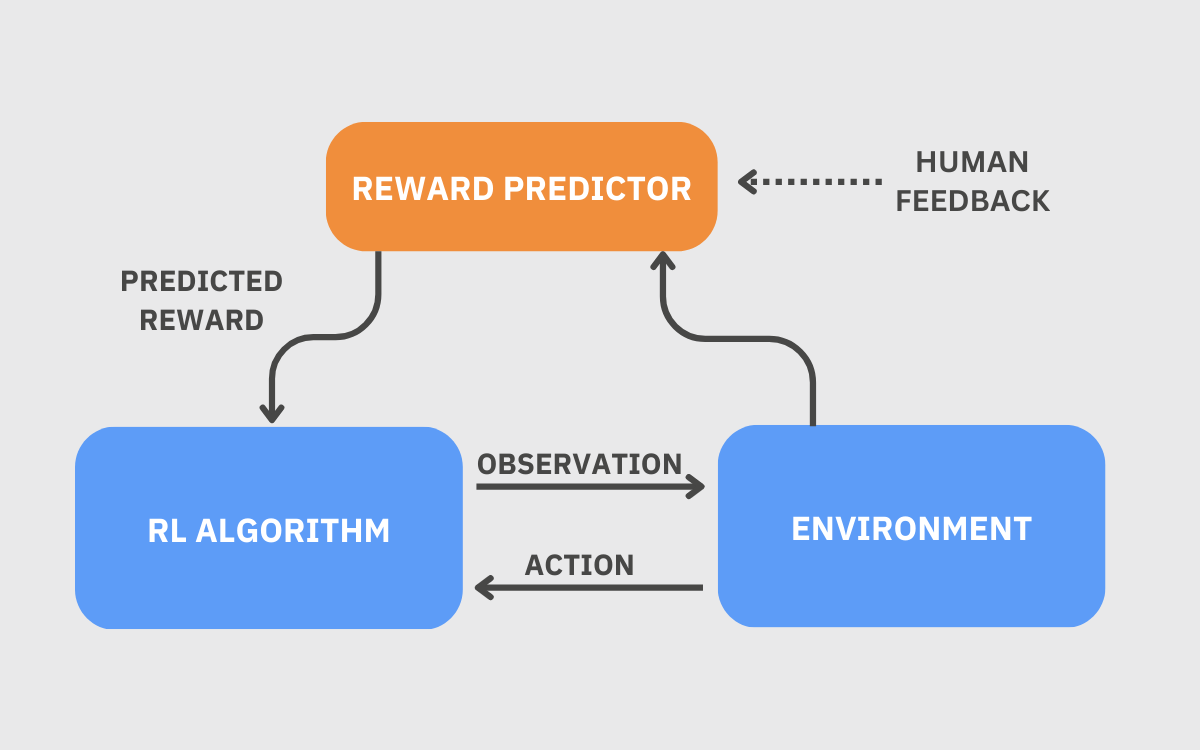
Using reinforcement learning from human feedback to fine-tune large ...

Finetuning LLMs Efficiently with Adapters
Advertisement Space (336x280)

[论文评述] Beyond Believability: Accurate Human Behavior Simulation with ...

Finetuning in large language models | ai-data-science
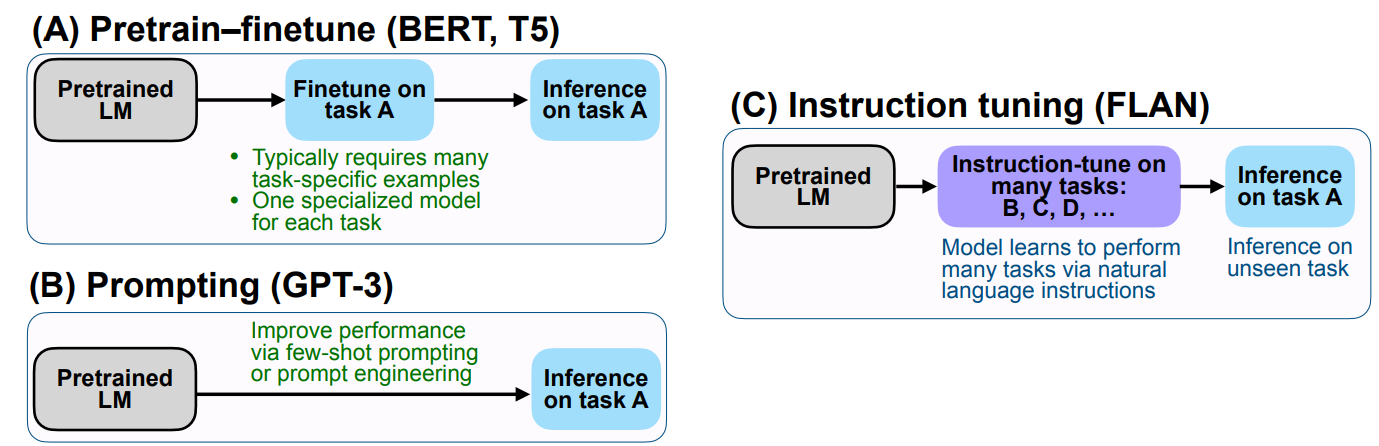
How to Fine-Tune LLMs in 2024
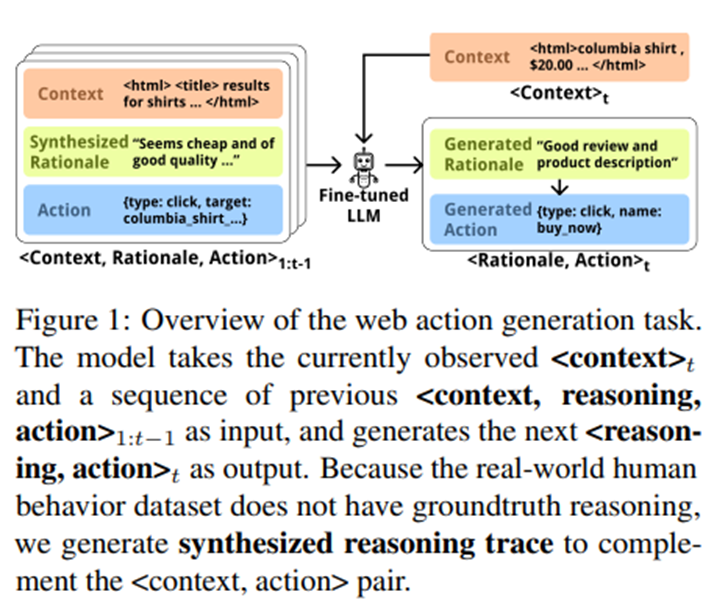
Beyond Believability: Accurate Human Behavior Simulation with Fine ...

Fine-tune LLMs with synthetic data for context-based Q&A using Amazon ...
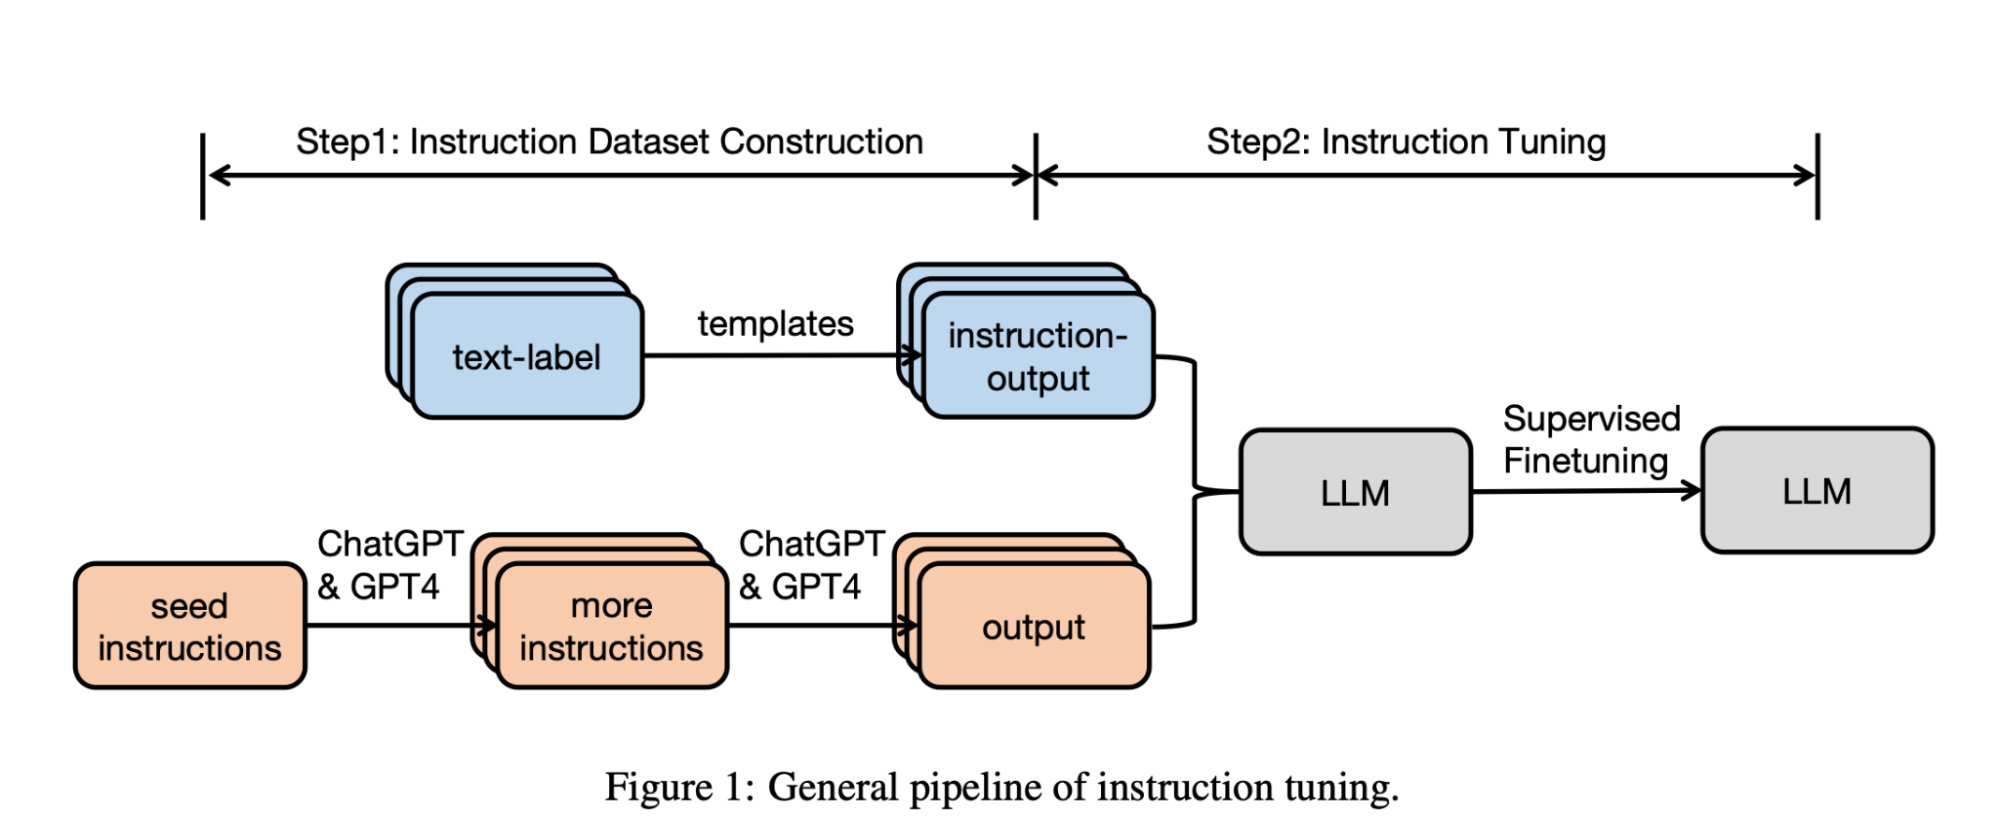
Optimizing LLMs From a Dataset Perspective | Sebastian Raschka, PhD